Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Phrase-level Self-Attention Networks for Univer...
Search
Sponsored
·
SiteGround - Reliable hosting with speed, security, and support you can count on.
→
katsutan
January 28, 2019
Technology
280
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Phrase-level Self-Attention Networks for Universal Sentence Encoding
文献紹介
長岡技術科学大学 勝田 哲弘
http://aclweb.org/anthology/D18-1408
katsutan
January 28, 2019
More Decks by katsutan
See All by katsutan
What does BERT learn about the structure of language?
katsutan
0
280
Simple and Effective Paraphrastic Similarity from Parallel Translations
katsutan
0
240
Simple task-specific bilingual word embeddings
katsutan
0
250
Retrofitting Contextualized Word Embeddings with Paraphrases
katsutan
0
300
Character Eyes: Seeing Language through Character-Level Taggers
katsutan
1
250
Improving Word Embeddings Using Kernel PCA
katsutan
0
250
Better Word Embeddings by Disentangling Contextual n-Gram Information
katsutan
0
370
Rotational Unit of Memory: A Novel Representation Unit for RNNs with Scalable Applications
katsutan
0
300
A robust self-learning method for fully unsupervised cross-lingual mappings of word embeddings
katsutan
0
320
Other Decks in Technology
See All in Technology
USB PDを使ってスマホを労わりたい
raspython3
0
180
Browser Spec: Testing Hotwire with Ruby
takahashim
1
120
Active Record Connection Adaptersにおける長年の課題に再び取り組む
yahonda
0
150
AI コーディングと人間の認知スループット / CTO Night & Day 2026 Morning Session / AI Coding and Human Cognitive Throughput
prog893
4
1.1k
初海外で注意すべきこと12選!!!安全快適なre:invent生活にするために
yuuuuuuu168
1
160
ブラウザとサーバーから考えるAI時代のフロントエンド監視
shogo4131
3
940
スキマバイトという雇用形態は存在しないので、雇用期間1日のアルバイト契約を事業者とワーカーが結ぶ手続きを支えるのがタイミーなんです
akitoshiga
0
200
無理せず続ける、子育てエンジニアの学び
codmoninc
PRO
0
870
⾮構造化データを価値に変える AI エージェント基盤とその組織
ivry_presentationmaterials
0
190
ソフトウェア ファクトリー - 再現性のあるソフトウェアの工場づくり / Software factory
iktakahiro
6
4.9k
今さら理解するウェブフォントver.2026
takanorip
3
770
自作バイナリを動かす「入口」8選
puhitaku
2
1.3k
Featured
See All Featured
How to Create Impact in a Changing Tech Landscape [PerfNow 2023]
tammyeverts
56
3.5k
Conquering PDFs: document understanding beyond plain text
inesmontani
PRO
4
3.2k
Sharpening the Axe: The Primacy of Toolmaking
bcantrill
46
3k
The #1 spot is gone: here's how to win anyway
tamaranovitovic
4
1.2k
The Limits of Empathy - UXLibs8
cassininazir
2
720
Navigating Weather and Climate Data
rabernat
0
560
The Curious Case for Waylosing
cassininazir
1
570
Large-scale JavaScript Application Architecture
addyosmani
516
110k
SEOcharity - Dark patterns in SEO and UX: How to avoid them and build a more ethical web
sarafernandez
0
300
Build The Right Thing And Hit Your Dates
maggiecrowley
39
3.5k
The State of eCommerce SEO: How to Win in Today's Products SERPs - #SEOweek
aleyda
2
12k
<Decoding/> the Language of Devs - We Love SEO 2024
nikkihalliwell
1
360
Transcript
Phrase-level Self-Attention Networks for Universal Sentence Encoding Wei Wu, Houfeng
Wang, Tianyu Liu, Shuming Ma Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing, pages 3729–3738 Brussels, Belgium, 2018. 文献紹介 長岡技術科学大学 勝田 哲弘
Abstract • Phrase-level SelfAttention Networks (PSAN)を提案 • フレーズで自己注意を行うため、メモリ消費が少ない • gated
memory updating mechanismでツリー構造を組み込 むことで階層的に単語表現を学習できる • 少ないメモリで様々なタスクでSotAを達成
Introduction 文のエンコーダにはRNNやCNNが用いられる • RNN:並列化できず、時間効率が悪い • CNN:パフォーマンスがRNNより悪い RNN/CNNを用いない Phrase-level SelfAttention Networks
(PSAN)を提案
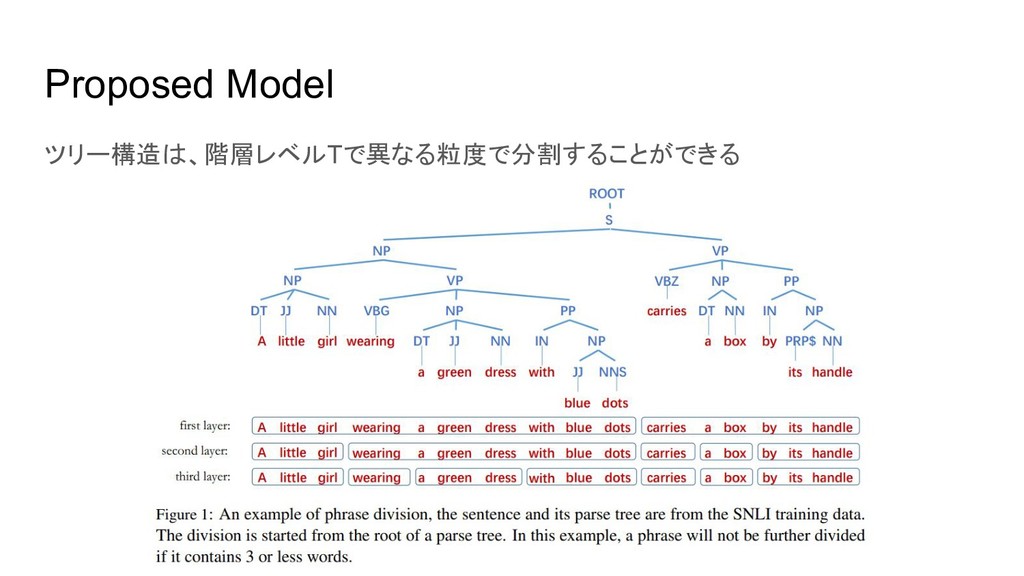
Proposed Model ツリー構造は、階層レベルTで異なる粒度で分割することができる
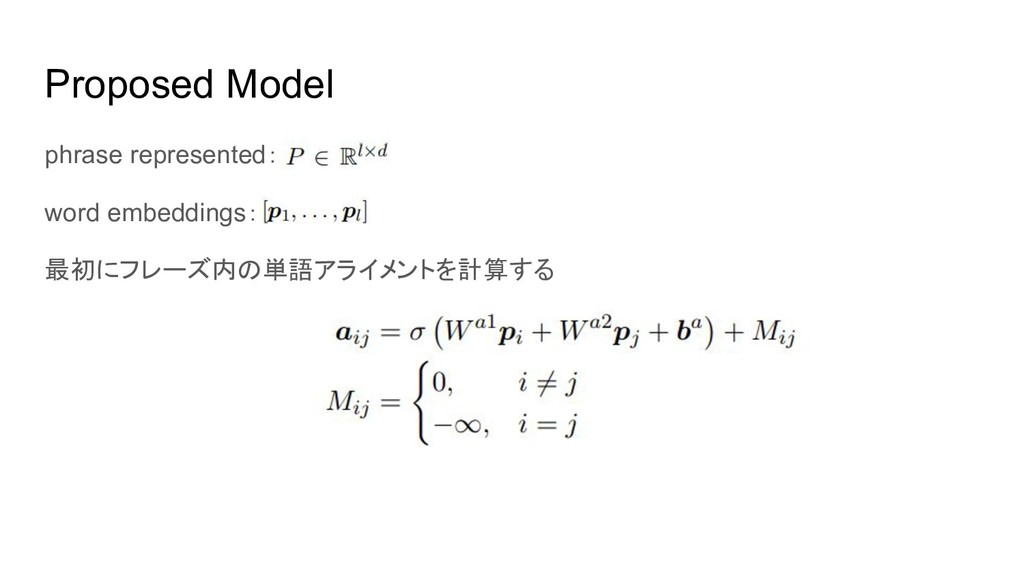
Proposed Model phrase represented: word embeddings: 最初にフレーズ内の単語アライメントを計算する
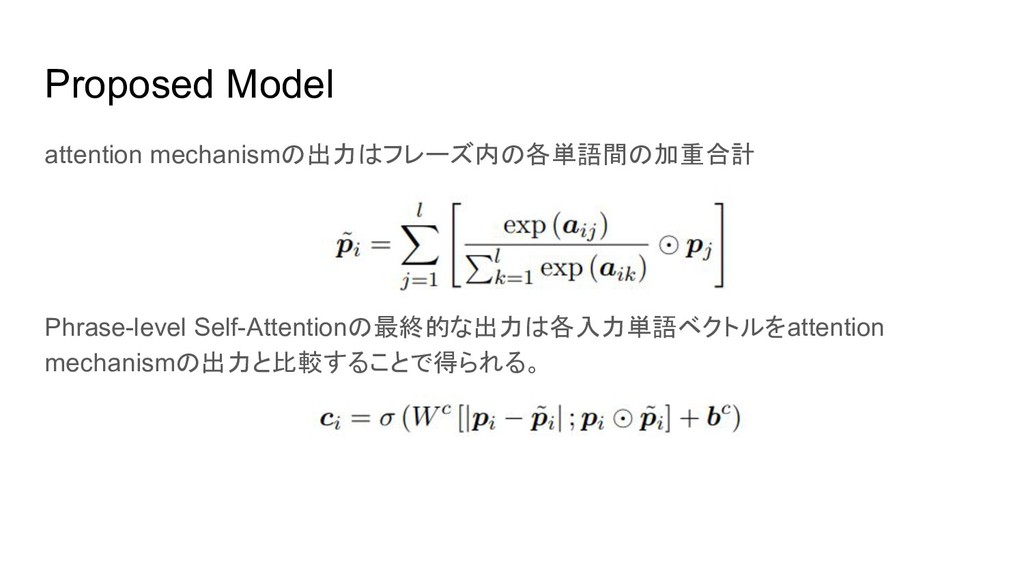
Proposed Model attention mechanismの出力はフレーズ内の各単語間の加重合計 Phrase-level Self-Attentionの最終的な出力は各入力単語ベクトルをattention mechanismの出力と比較することで得られる。
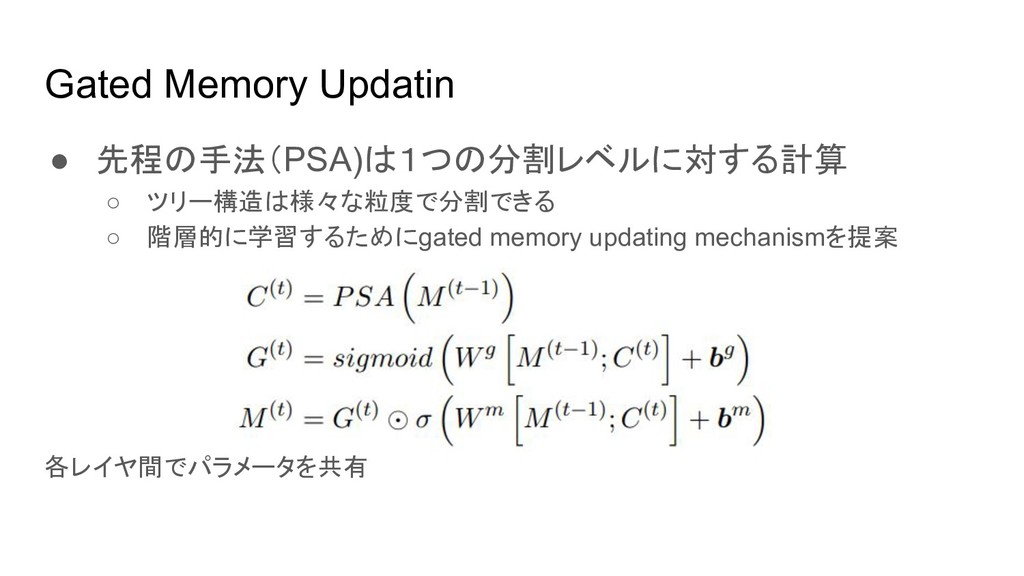
Gated Memory Updatin • 先程の手法(PSA)は1つの分割レベルに対する計算 ◦ ツリー構造は様々な粒度で分割できる ◦ 階層的に学習するためにgated memory
updating mechanismを提案 各レイヤ間でパラメータを共有
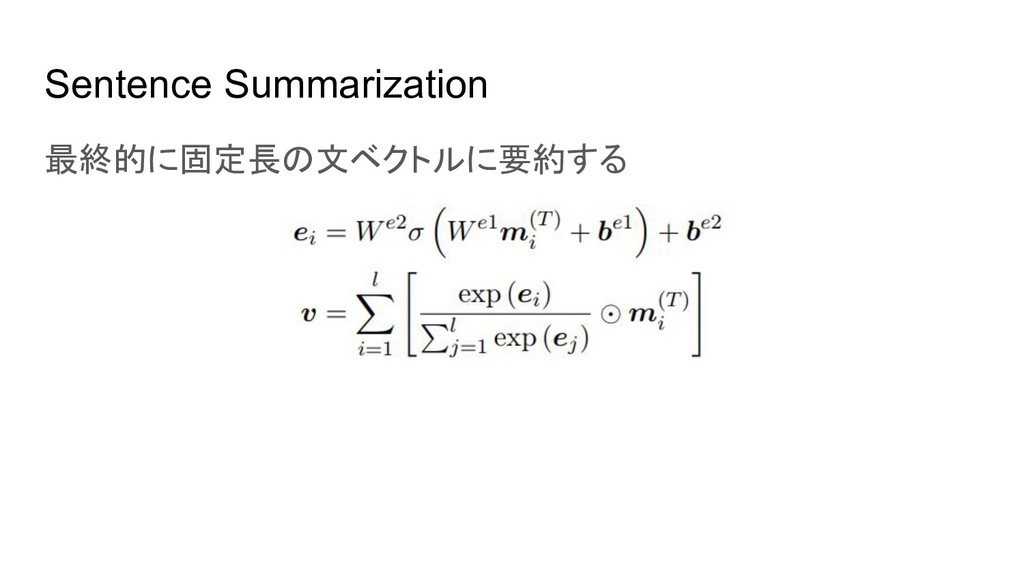
Sentence Summarization 最終的に固定長の文ベクトルに要約する
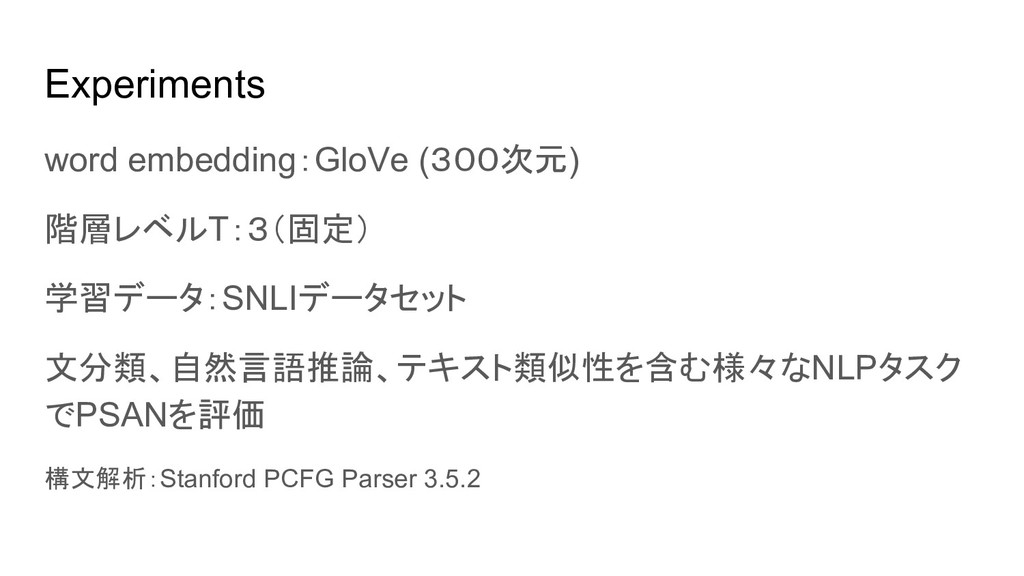
Experiments word embedding:GloVe (300次元) 階層レベルT:3(固定) 学習データ:SNLIデータセット 文分類、自然言語推論、テキスト類似性を含む様々なNLPタスク でPSANを評価 構文解析:Stanford PCFG
Parser 3.5.2
Training Setting Natural language inference(NLI)によってエンコーダを学習する 学習データ:Stanford Natural Language Inference (SNLI)
dataset • 549367/9842/9824 sentence pairs
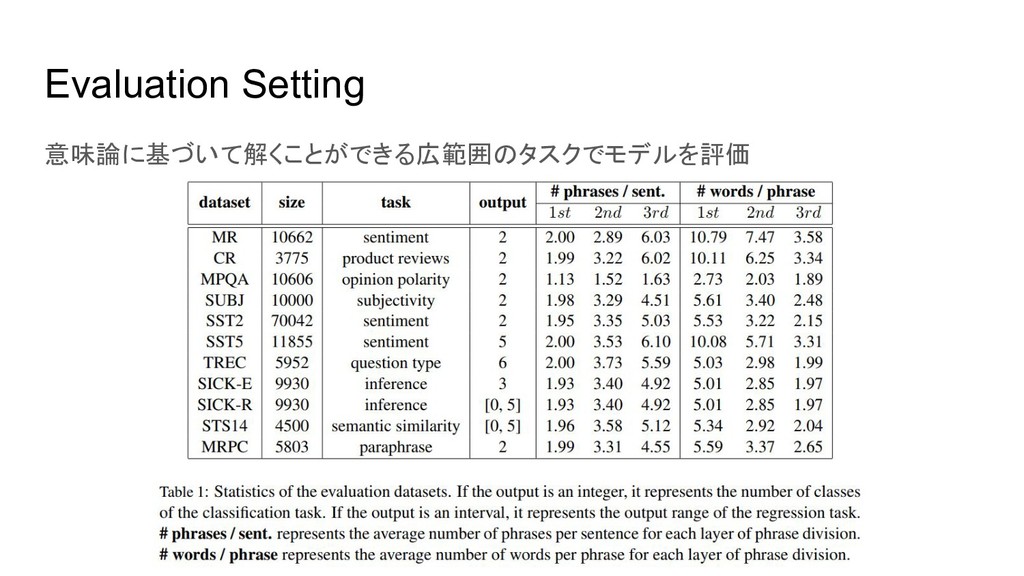
Evaluation Setting 意味論に基づいて解くことができる広範囲のタスクでモデルを評価
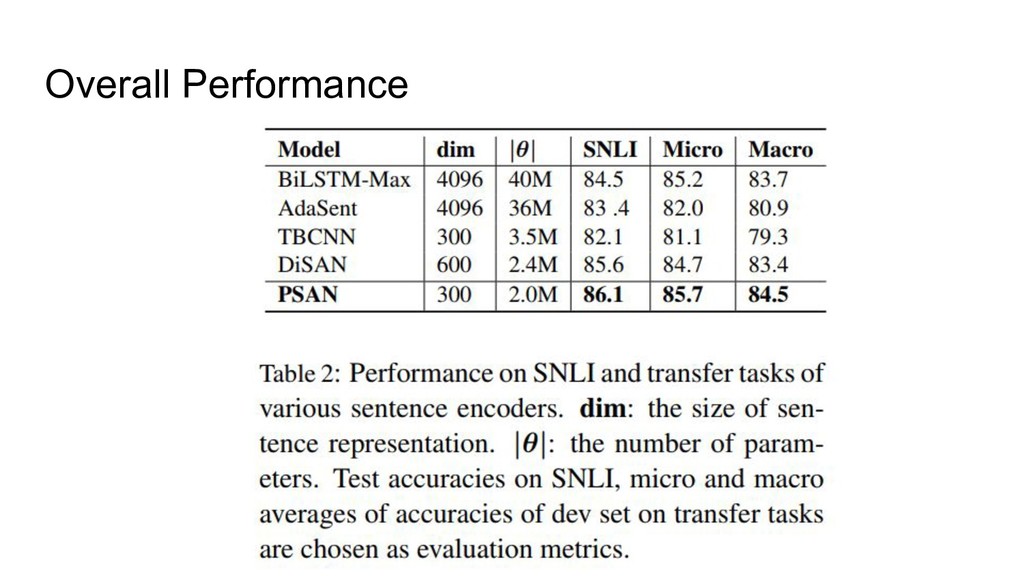
Overall Performance
Overall Performance
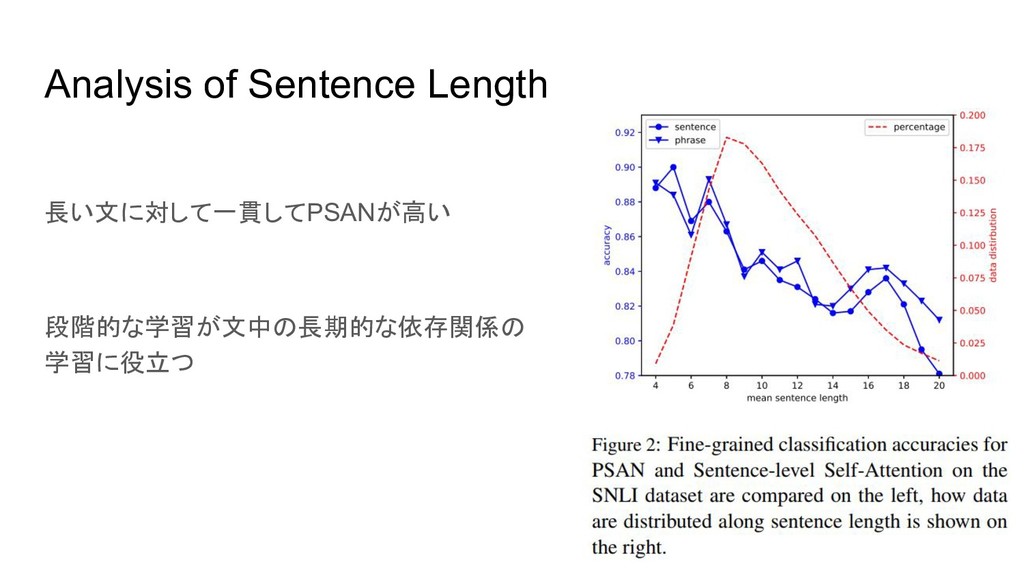
Analysis of Sentence Length 長い文に対して一貫してPSANが高い 段階的な学習が文中の長期的な依存関係の 学習に役立つ
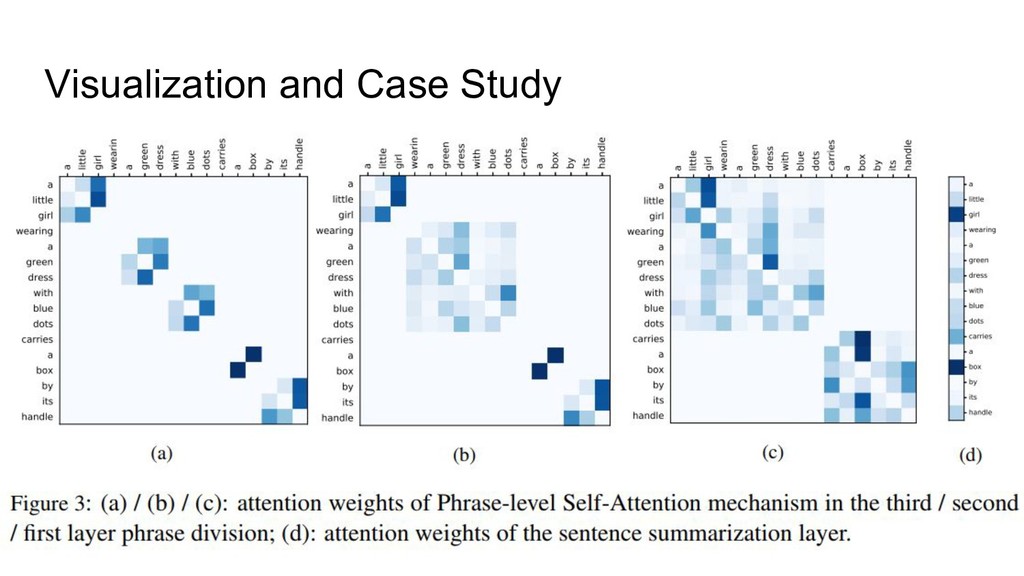
Visualization and Case Study
Conclusion • 構文情報を用いた文のエンコーダモデルを提案 ◦ 意味的、構文的に重要な単語間の相互作用に注目 • パラメータ数を減らし、メモリ消費を20%以上削減 • 様々なタスクで有効性が示された

 SiteGround - Reliable hosting with speed, security, and support you can count on.


 katsutan
 raspython3
 takahashim
 yahonda
 prog893
 yuuuuuuu168
 shogo4131
 akitoshiga
 codmoninc
 ivry_presentationmaterials
 iktakahiro
 takanorip
 puhitaku
 tammyeverts
 inesmontani
 bcantrill
 tamaranovitovic
 cassininazir
 rabernat
 addyosmani
 sarafernandez
 maggiecrowley
 aleyda
 nikkihalliwell