Share
Embed
Multilingual Part-of-Speech Tagging with Bidirectional Long Short-Term Memory Models and Auxiliary Loss
Barbara Plank, Anders Søgaard, and Yoav Goldberg
Proceedings of the 54th Annual Meeting of the
Association for Computational Linguistics
pages 412–418,
Berlin, Germany, August 7-12, 2016
Yemane
October 12, 2017
Transcript
20 slides
-
Multilingual Part-of-Speech Tagging with Bidirectional Long Short-Term Memory Models and
Auxiliary Loss Barbara Plank, Anders Søgaard, and Yoav Goldberg Proceedings of the 54th Annual Meeting of the Association for Computational Linguistics pages 412–418, Berlin, Germany, August 7-12, 2016 _________________________________________________ OCT 12, 2017 Nagaoka University of Technology Natural Language Processing Lab -
To evaluate the effect of Bi-directional long short-term memory
(bi-LSTM) neural networks across several languages, input representations, data size and label noise on part-of-speech (POS) tagging Motivation -
Introduction Bi-LSTMs LSTMs are recurrent neural networks (RNNs)
in which layers are designed to prevent vanishing gradients. Bidirectional LSTMs make a backward and forward pass through the sequence -
Introduction Constructed models • across 22 languages Compared
performance for different levels of representations • words, characters, and bytes Investigated the effect of training data and label noise compared to traditional POS taggers Proposed a novel approach • a bi-LSTM trained with auxiliary loss -
Tagging with bi-LSTMs Recurrent neural networks (RNNs) • allow
the computation of fixed-size vector representations for word sequences of arbitrary length. An RNN is a function • Input (x 1 ,...,x n ) → RNN → output (h n ) • h n depends on the entire sequence x 1 ,...,x n -
Tagging with bi-LSTMs Recurrent neural networks (RNNs) • allow
the computation of fixed-size vector representations for word sequences of arbitrary length. An RNN is a function • Input (x 1 ,...,x n ) → RNN → output (h n ) • h n depends on the entire sequence x 1 ,...,x n -
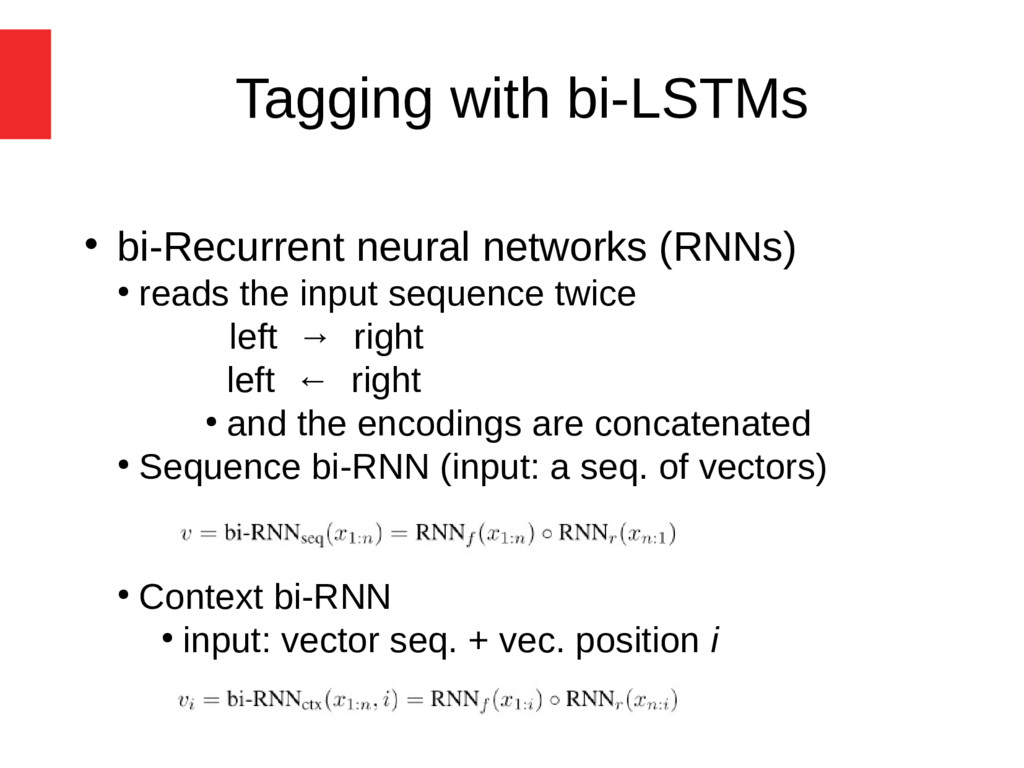
Tagging with bi-LSTMs bi-Recurrent neural networks (RNNs) • reads
the input sequence twice left → right left ← right • and the encodings are concatenated • Sequence bi-RNN (input: a seq. of vectors) • Context bi-RNN • input: vector seq. + vec. position i -
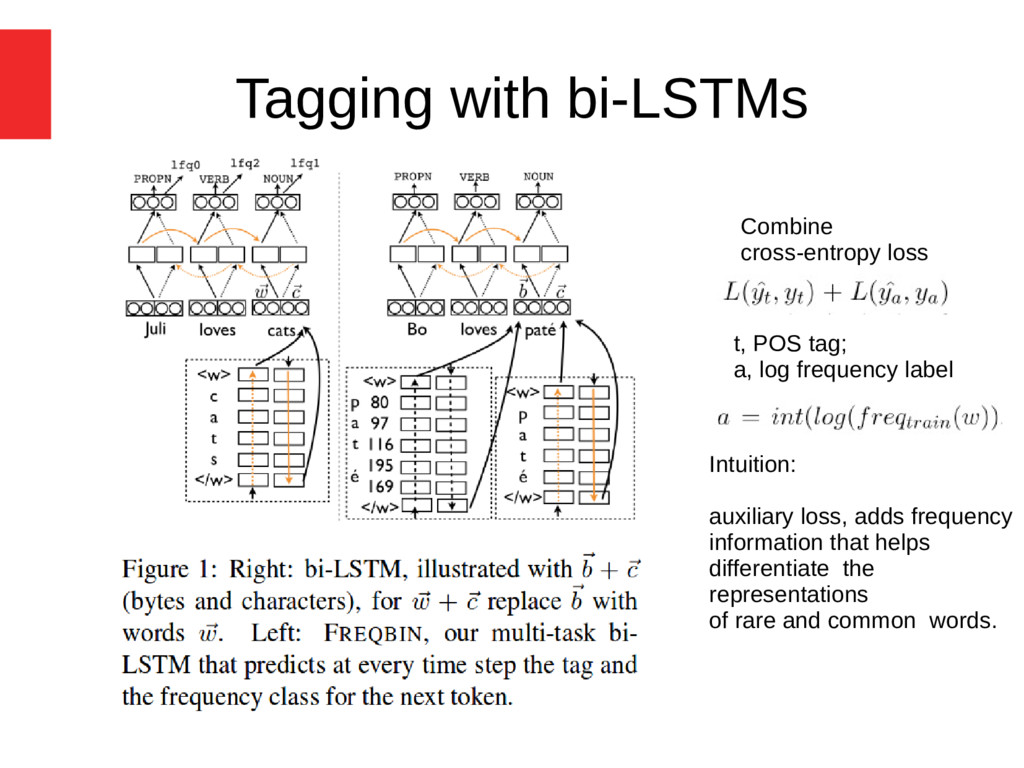
Tagging with bi-LSTMs Combine cross-entropy loss t, POS tag; a,
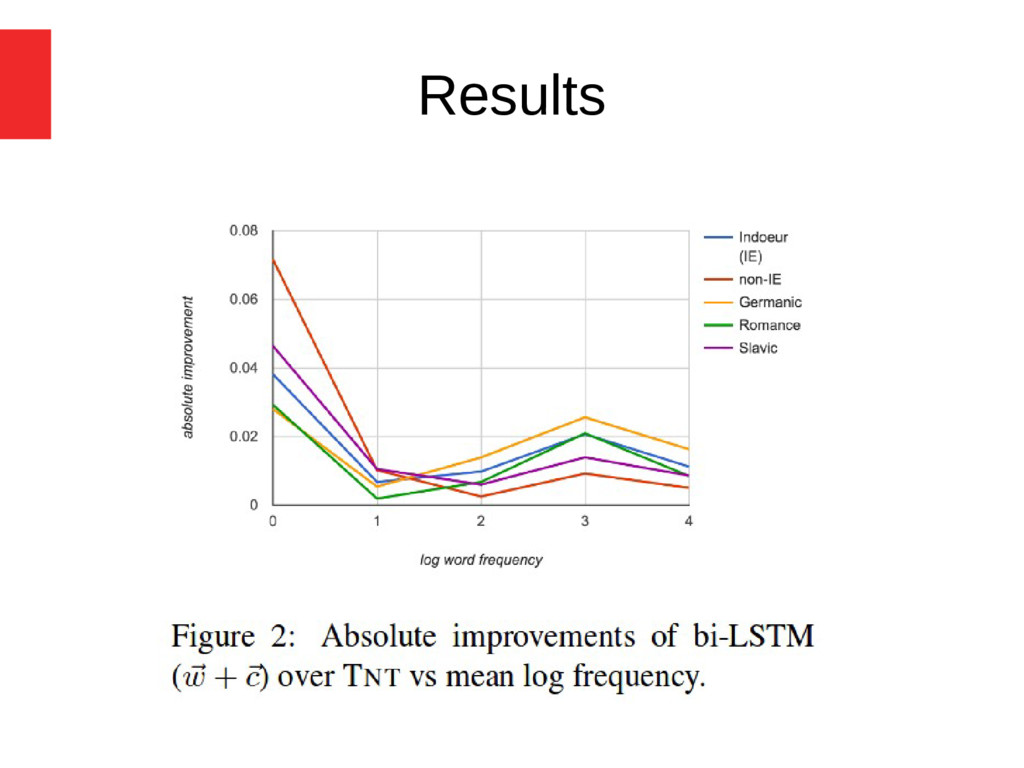
log frequency label Intuition: auxiliary loss, adds frequency information that helps differentiate the representations of rare and common words. -
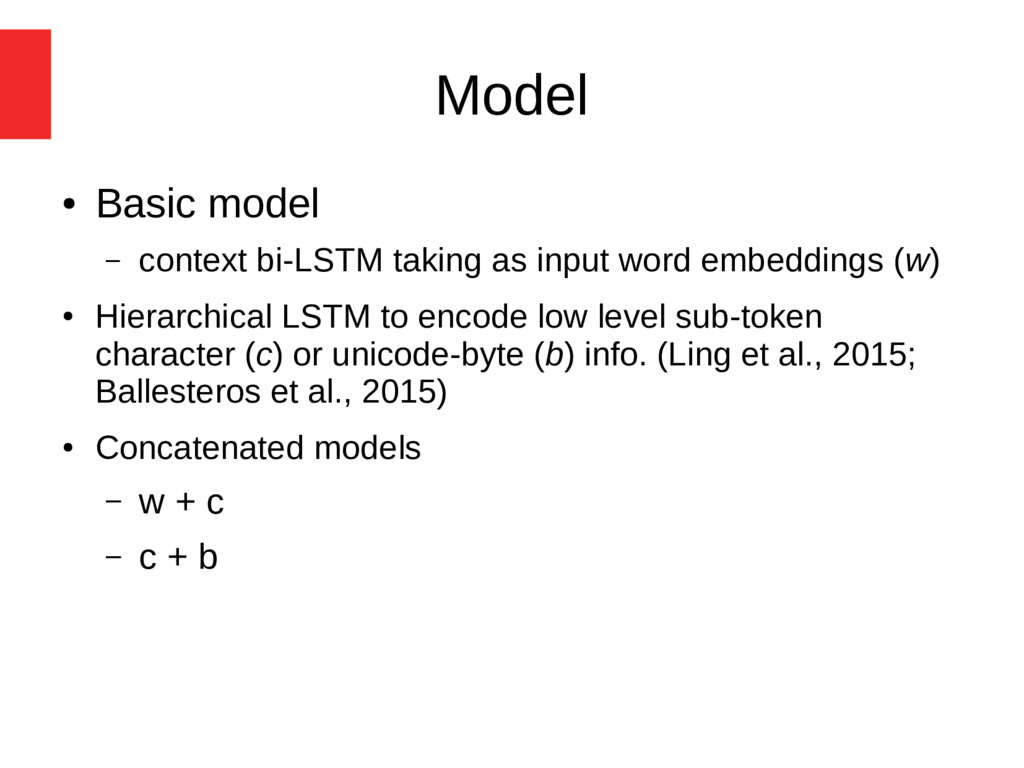
Model • Basic model – context bi-LSTM taking as input
word embeddings (w) • Hierarchical LSTM to encode low level sub-token character (c) or unicode-byte (b) info. (Ling et al., 2015; Ballesteros et al., 2015) • Concatenated models – w + c – c + b -
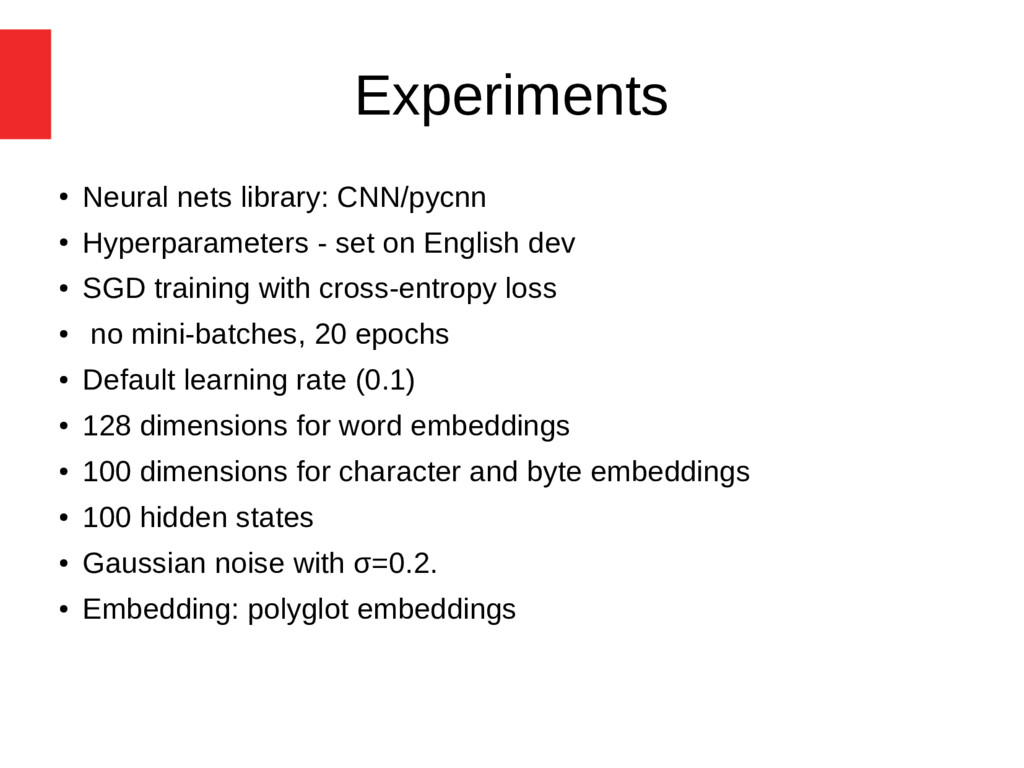
Experiments • Neural nets library: CNN/pycnn • Hyperparameters - set
on English dev • SGD training with cross-entropy loss • no mini-batches, 20 epochs • Default learning rate (0.1) • 128 dimensions for word embeddings • 100 dimensions for character and byte embeddings • 100 hidden states • Gaussian noise with σ=0.2. • Embedding: polyglot embeddings -
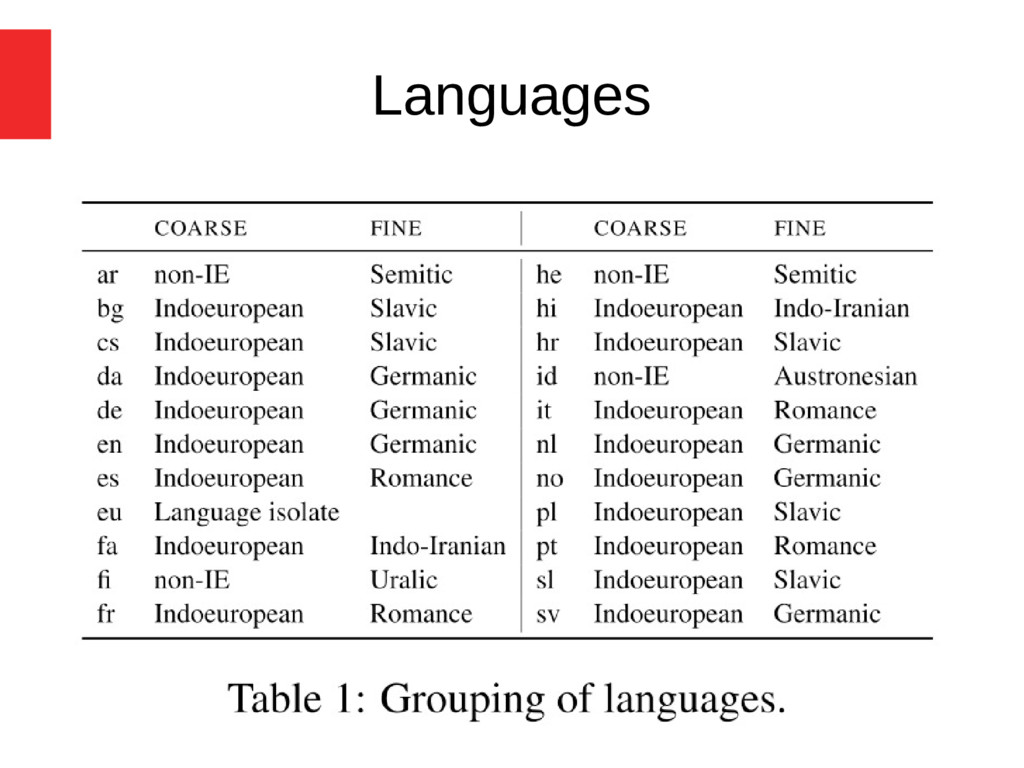
Datasets • 1) For the multilingual experiments, – Universal Dependencies
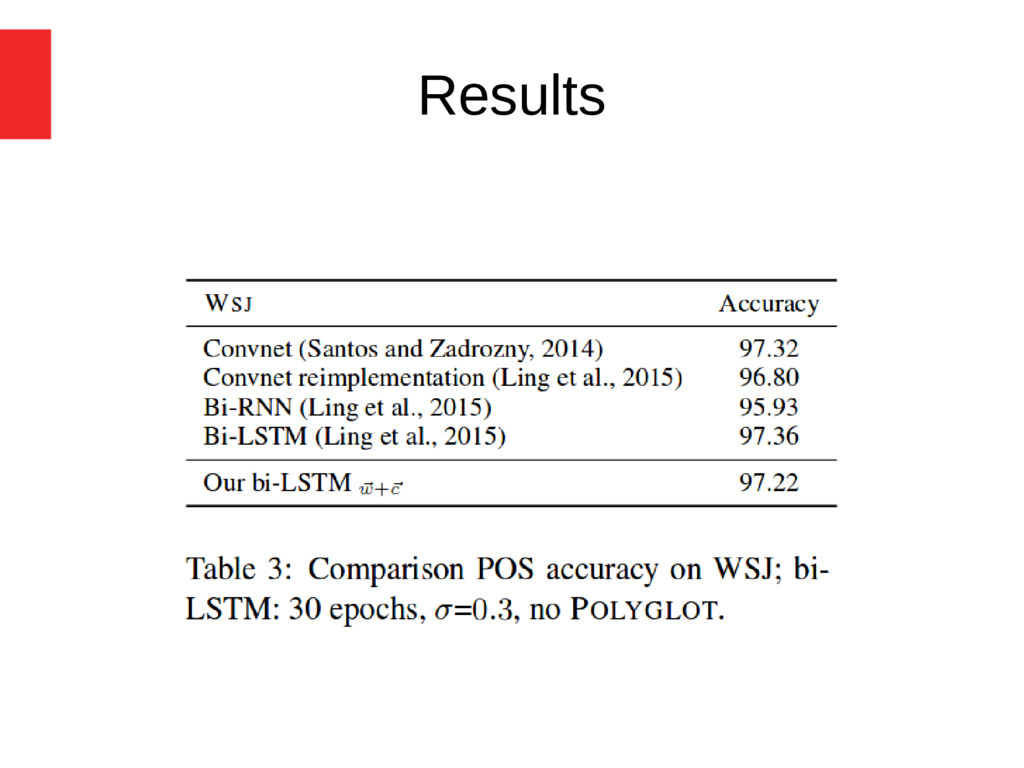
project v1.2 (Nivre et al., 2015) , 17 POS • For languages with token segmentation ambiguity – the provided gold segmentation. • At least 60k tokens and are distributed with words – 22 languages. • 2) WSJ (45 POS) using the standard splits (Collins, 2002; Manning, 2011) -
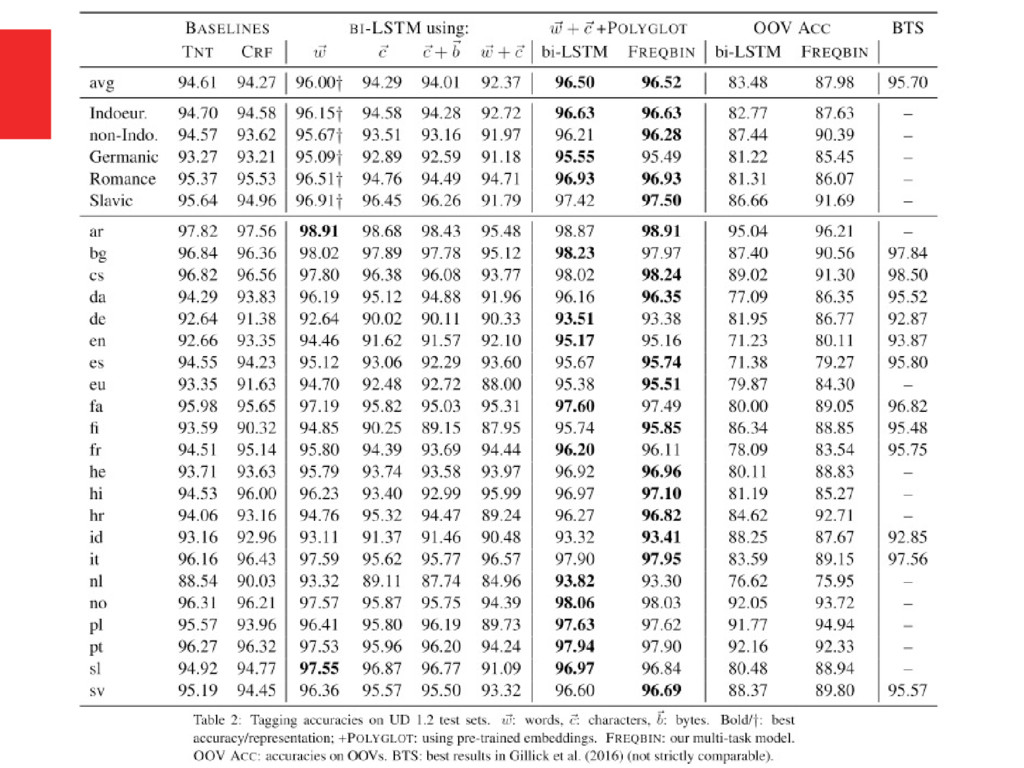
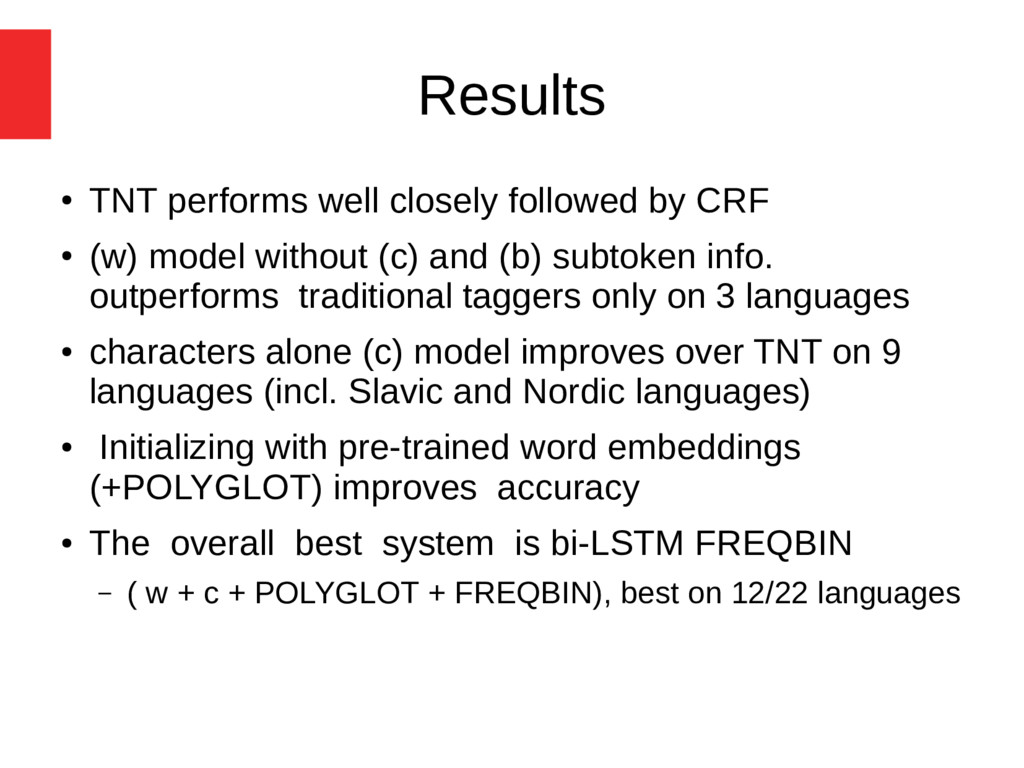
Results • TNT performs well closely followed by CRF •
(w) model without (c) and (b) subtoken info. outperforms traditional taggers only on 3 languages • characters alone (c) model improves over TNT on 9 languages (incl. Slavic and Nordic languages) • Initializing with pre-trained word embeddings (+POLYGLOT) improves accuracy • The overall best system is bi-LSTM FREQBIN – ( w + c + POLYGLOT + FREQBIN), best on 12/22 languages -
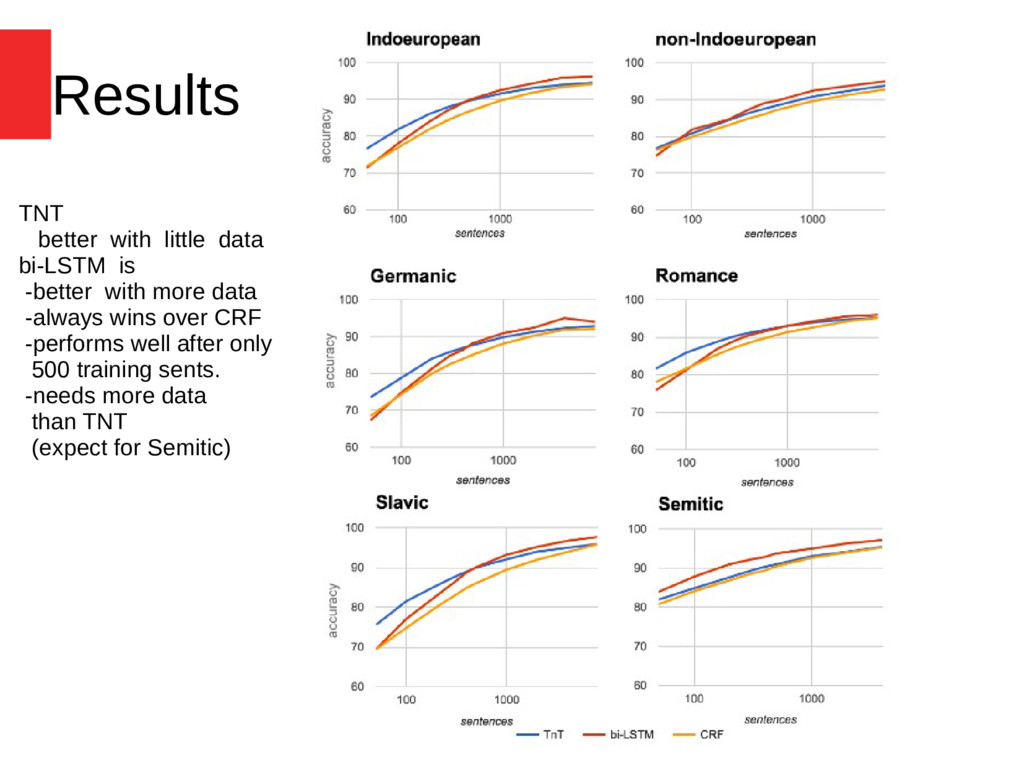
Results TNT better with little data bi-LSTM is -better with
more data -always wins over CRF -performs well after only 500 training sents. -needs more data than TNT (expect for Semitic) -
Results Label noise • investigated by artificially corrupting training labels
– at low noise rates • bi-LSTMs and TNT accuracies drop to a similar degree – at higher noise levels (more than 30% corrupted labels) • bi-LSTMs are less robust -
Conclusions • evaluated token and subtoken-level representations for bi-LSTM part-of-
speech tagging across 22 languages • proposed a model of bi-LSTM with auxiliary loss • The auxiliary loss is effective at improving the accuracy of rare words • Subtoken representations are necessary to obtain a state-of-the-art POS tagger • The best representation: Subtpken + word embeddings in a hierarchical network • The bi-LSTM tagger is as effective as the CRF and HMM taggers with already as little as 500 training sentences, • bi-LSTM tagger is less robust to label noise (at higher noise rates)