Share
Embed
Unsupervised morphological segmentation and clustering with document boundaries
Taesun Moon, Katrin Erk, and Jason Baldridge
Proceedings of the 2009 Conference on Empirical Methods in Natural Language Processing, pages 668–677, Singapore, 6-7 August 2009. (c) 2009 ACL and AFNLP
Yemane
October 18, 2016
Transcript
17 slides
-
Unsupervised morphological segmentation and clustering with document boundaries Taesun Moon,
Katrin Erk, and Jason Baldridge Proceedings of the 2009 Conference on Empirical Methods in Natural Language Processing, pages 668–677, Singapore, 6-7 August 2009. (c) 2009 ACL and AFNLP --------------------------------------------------------------- OCT 18, 2016 Nagaoka University of Technology Natural Language Processing Lab -
a simple method that does not require arbitrary parameter
tuning Use of document boundary to constraint generation of candidate stems, affixes and clustering morphological variants method that works for under-resourced languages (where data-driven tuning is unlikely because data are scarce) Motivation -
Introduction Unsupervised morphology acquisition attempts to learn the following
from text Segmentation of words Clustering of words Generation of OOV terms Approach (a) the filtering of affixes by significant co- occurrence (b) use of document boundaries when generating candidate stems and affixes and when clustering morphologically related words. -
Introduction Intuition - if two words in a single
document are very similar in terms of orthography, then the two words are likely to be related morphologically (term-document statistical correlation) Languages - English and Uspanteko (Mayan language of Guatemala) Result - better results compared to Linguistica and Morfessor -
Unsupervised morphology acquisition challenges distinguishing derivational from inflectional
morphology ambiguity in segmentation alit + meter, altitude evaluating clusters atheism, theism -
Model Goal – to generate conflation sets conflation
sets - word types that are related through either inflectional or derivational morphology (Schone and Jurafsky, 2000). -
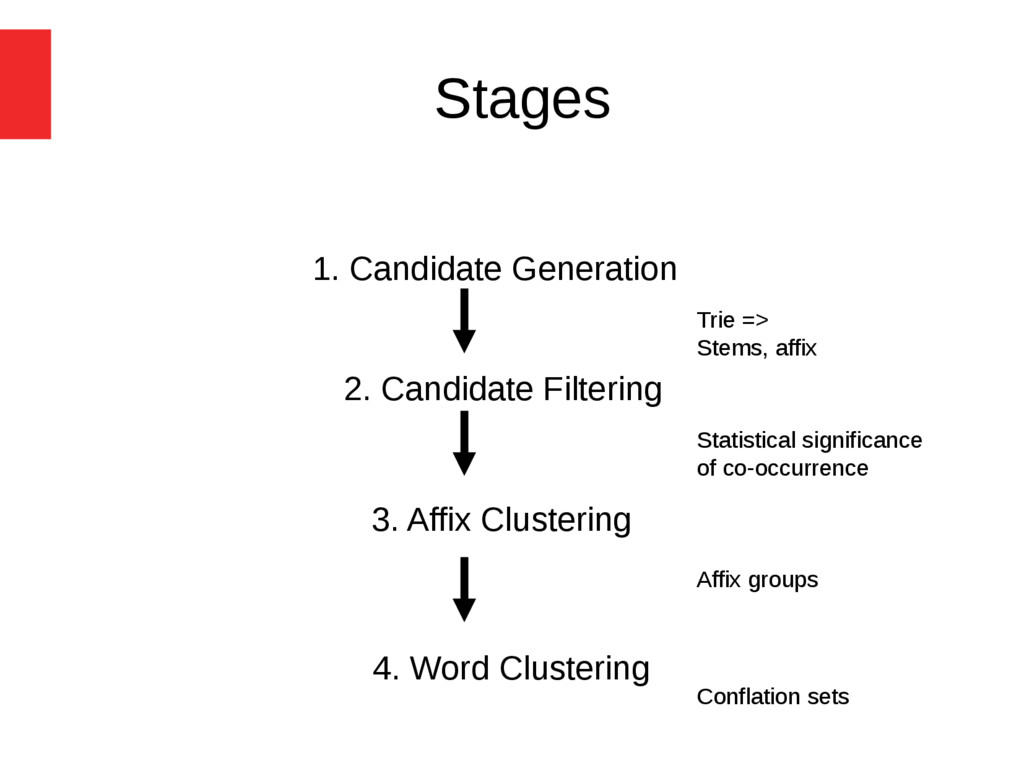
Stages 1. Candidate Generation 2. Candidate Filtering 3. Affix Clustering
4. Word Clustering Trie => Stems, affix Statistical significance of co-occurrence Affix groups Conflation sets -
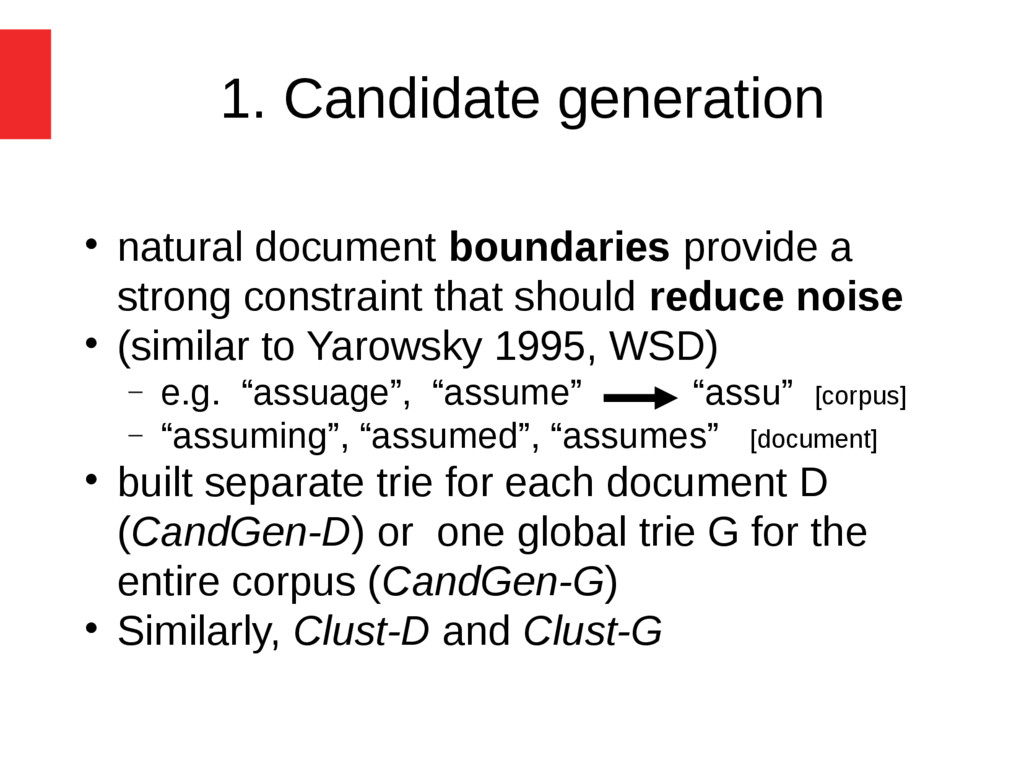
1. Candidate generation natural document boundaries provide a strong
constraint that should reduce noise (similar to Yarowsky 1995, WSD) e.g. “assuage”, “assume” “assu” [corpus] “assuming”, “assumed”, “assumes” [document] built separate trie for each document D (CandGen-D) or one global trie G for the entire corpus (CandGen-G) Similarly, Clust-D and Clust-G -
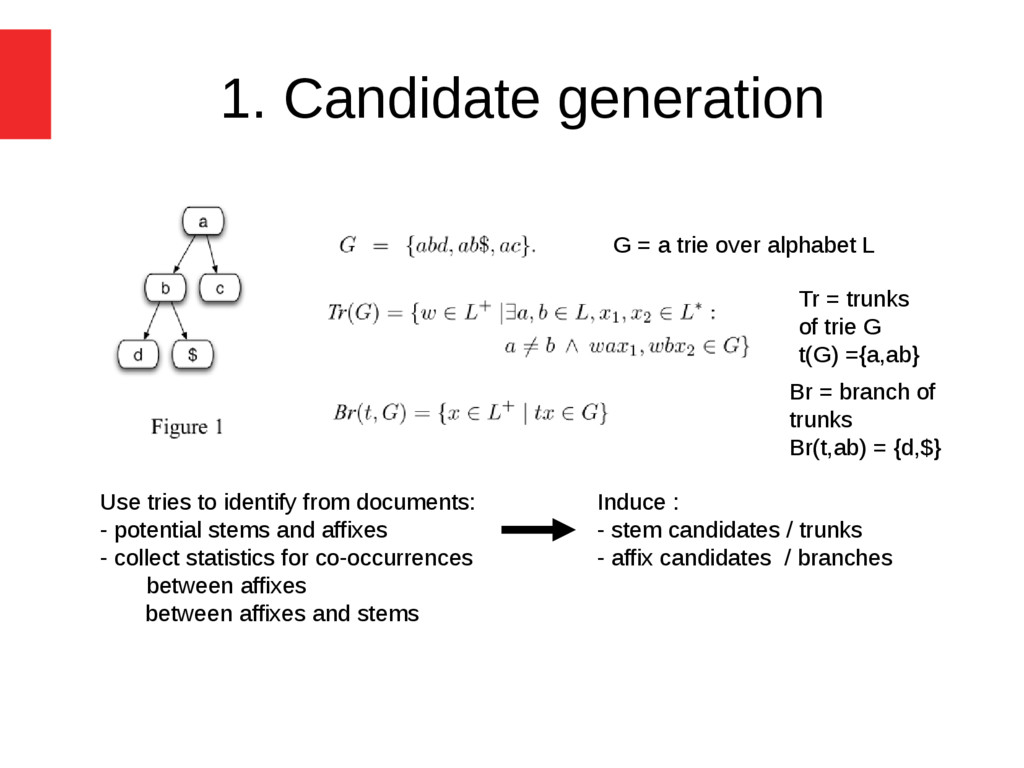
1. Candidate generation Use tries to identify from documents: -
potential stems and affixes - collect statistics for co-occurrences between affixes between affixes and stems G = a trie over alphabet L Tr = trunks of trie G t(G) ={a,ab} Br = branch of trunks Br(t,ab) = {d,$} Induce : - stem candidates / trunks - affix candidates / branches -
2. Candidate filtering Candidates generated based on substring matches
(stage-1) produce noise Statistical correlation between branches (affixes) b 1 and b 2 with X2 test pairwise comparison is used for filtering (rather than global inference) p < 0.05, X2 test significance Any affix candidates not statistically correlated with other affix in the set of affix candidates is discarded -
3. Affix clustering Input – set of significantly correlated
pairs of affixes Affix pairs are grouped into larger affix groups to improve generalization -
4. Word clustering form morphologically related groups, iff
(1) they occurred in the same trie G, (2) they have a trunk s in common that is a stem in Stem(G) (3) their affixes under stem s are members in a common valid affix cluster -
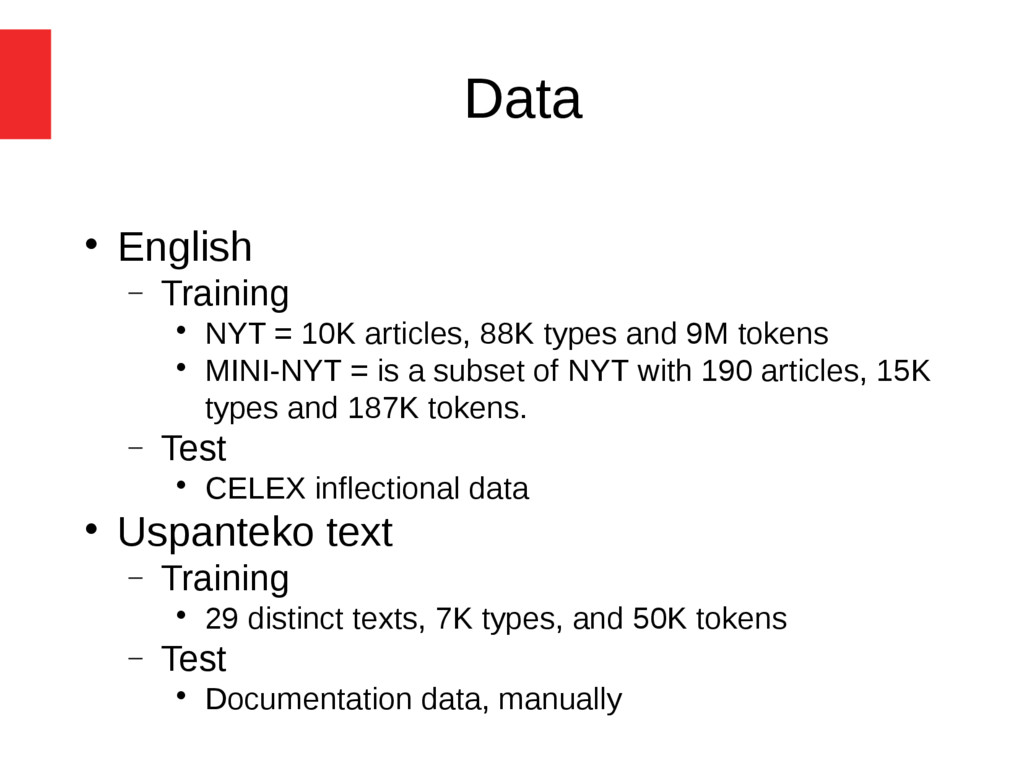
Data English Training NYT = 10K articles,
88K types and 9M tokens MINI-NYT = is a subset of NYT with 190 articles, 15K types and 187K tokens. Test CELEX inflectional data Uspanteko text Training 29 distinct texts, 7K types, and 50K tokens Test Documentation data, manually -
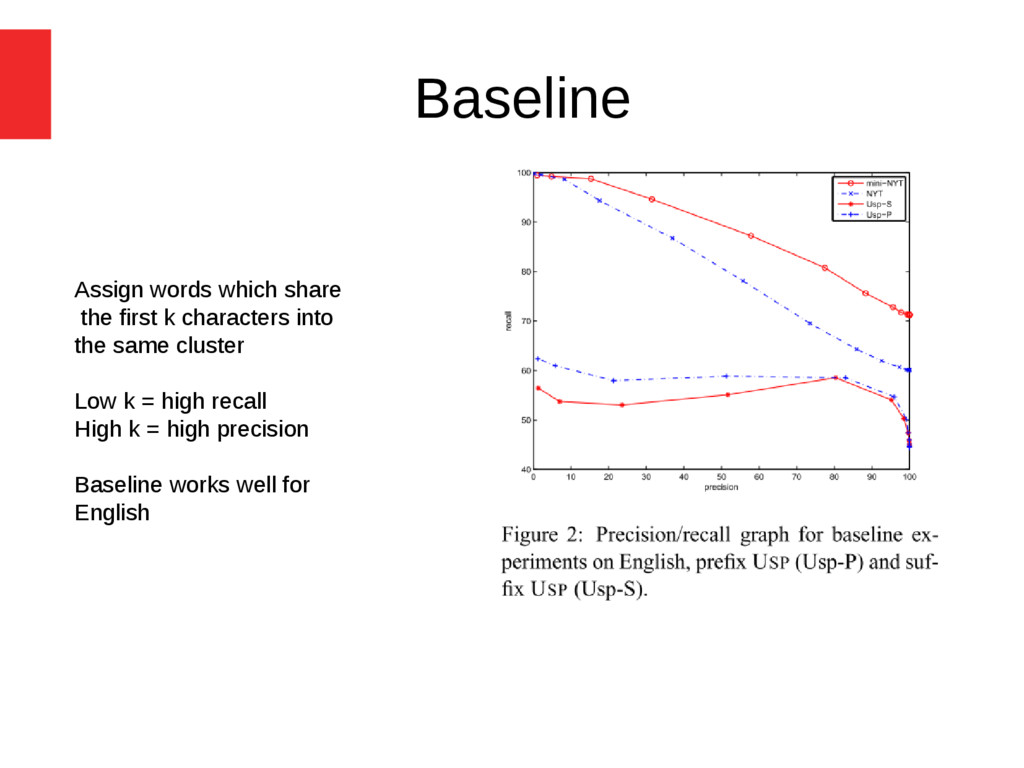
Baseline Assign words which share the first k characters into
the same cluster Low k = high recall High k = high precision Baseline works well for English -
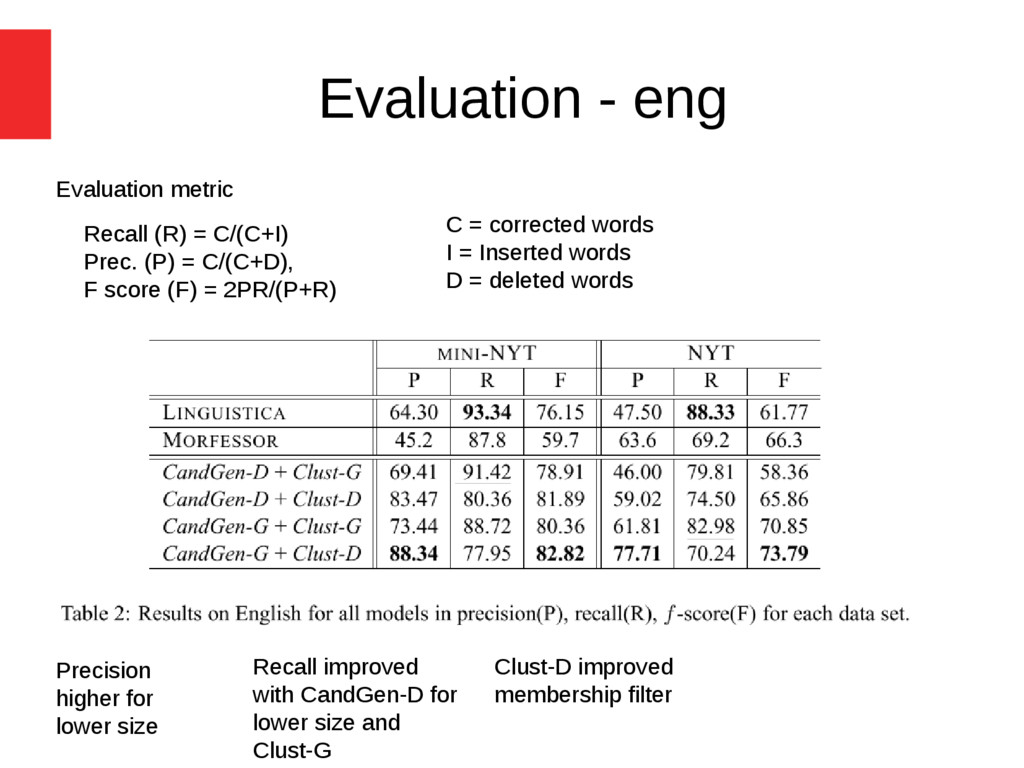
Evaluation - eng Evaluation metric C = corrected words I
= Inserted words D = deleted words Recall (R) = C/(C+I) Prec. (P) = C/(C+D), F score (F) = 2PR/(P+R) Precision higher for lower size Recall improved with CandGen-D for lower size and Clust-G Clust-D improved membership filter -
Conclusion unsupervised morphology acquisition is presented document boundaries
and correlation tests are used for filtering stems and affixes promising for under-resourced languages result shows good improvement over existing methods Future direction: textual distance to estimate likelihood of morphological relatedness