Share
Embed
Improving Statistical MT through Morphological Analysis
Sharon Goldwater, David McClosky
Brown University
Proceedings of Human Language Technology Conference and Conference on Empirical Methods in Natural Language
Processing (HLT/EMNLP), pages 676–683, Vancouver, October 2005. Association for Computational Linguistics
Yemane
April 27, 2016
Transcript
17 slides
-
Improving Statistical MT through Morphological Analysis April 27, 2016 Sharon
Goldwater, David McClosky Brown University Proceedings of Human Language Technology Conference and Conference on Empirical Methods in Natural Language Processing (HLT/EMNLP), pages 676–683, Vancouver, October 2005. Association for Computational Linguistics 1 -
Overview • Purpose • Improving MT between high-inflection and low-inflection
language • Source = Czech target = English • Method • Reduce data sparseness • make the Czech input data more English-like • Data • Prague Czech-English Dependency Treebank (PCEDT corpus) • Result • Improved machine translation performance (BLUE 0.27 0.333) 2 -
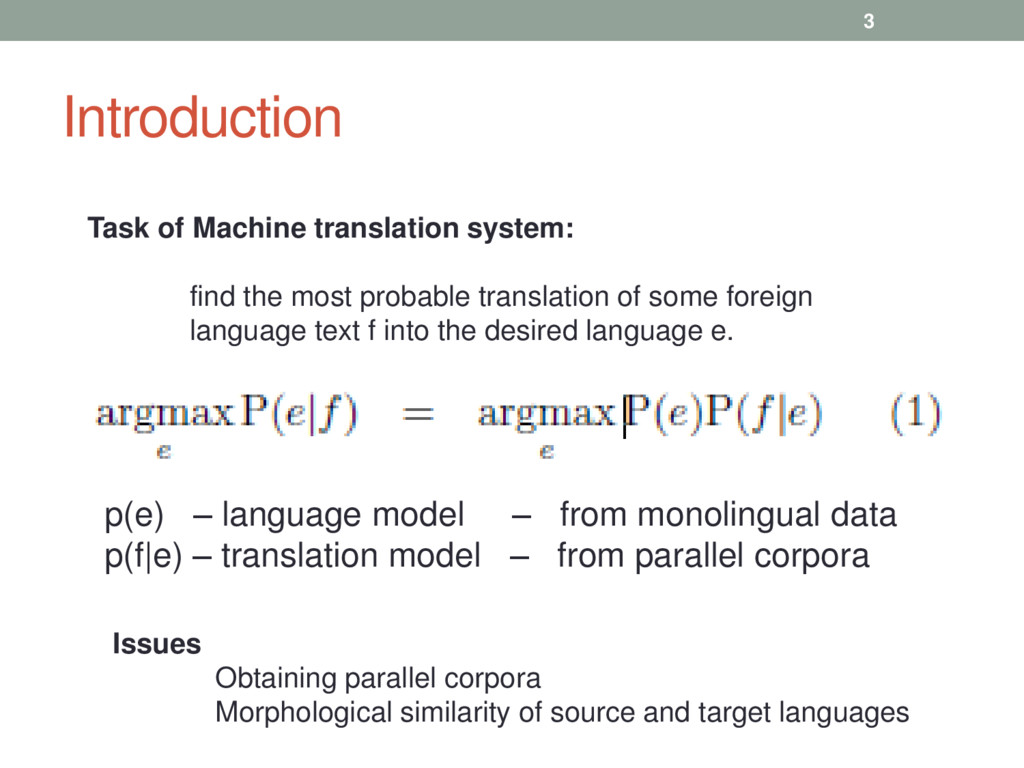
Introduction p(e) – language model – from monolingual data p(f|e)
– translation model – from parallel corpora Task of Machine translation system: find the most probable translation of some foreign language text f into the desired language e. Issues Obtaining parallel corpora Morphological similarity of source and target languages 3 -
Morphological correspondence • Czech and English Morphological corresponds is reflected
as follows • (1) Morphological distinctions exist in both languages • e.g. Verb past tense, noun plural • (2) Morphological variants in Czech are expressed by function words in English • e.g. Genitive case – of ; instrumental case – by, with • (3) Some Czech morphological distinctions are absent in English • e.g Gender in common nouns 4 -
Resource for Morphological information • Resource • Prague Czech-English Dependency
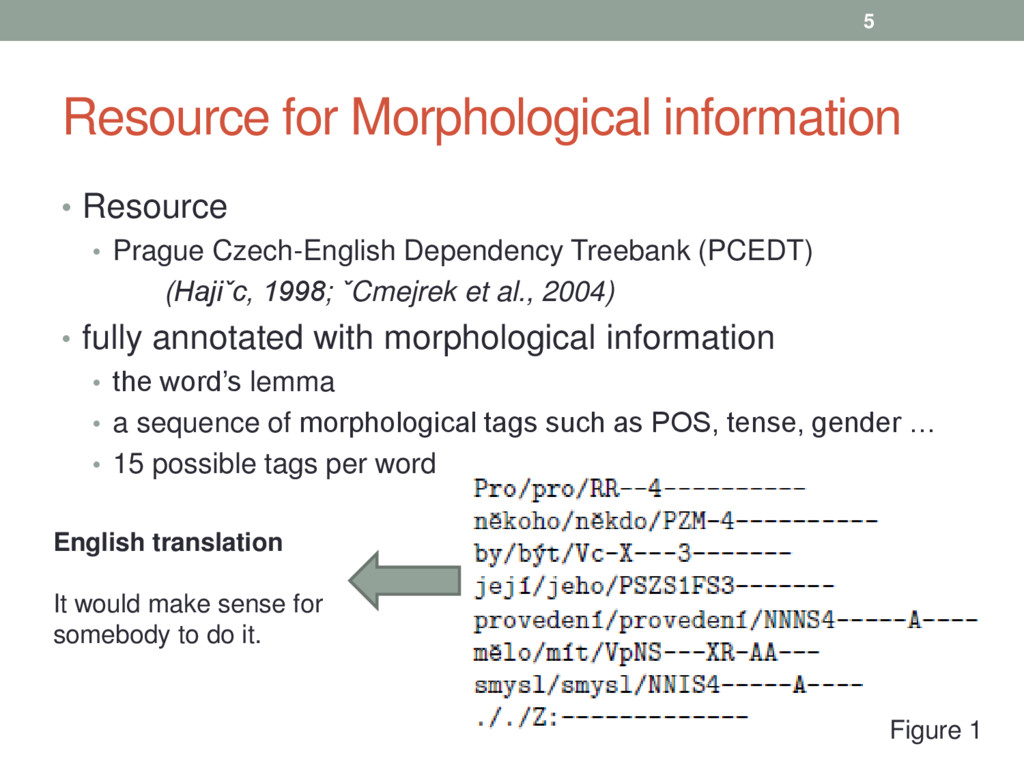
Treebank (PCEDT) (Hajiˇc, 1998; ˇCmejrek et al., 2004) • fully annotated with morphological information • the word’s lemma • a sequence of morphological tags such as POS, tense, gender … • 15 possible tags per word English translation It would make sense for somebody to do it. Figure 1 5 -
Methodology: Adjusting morphological variation • To create more English-like morphological
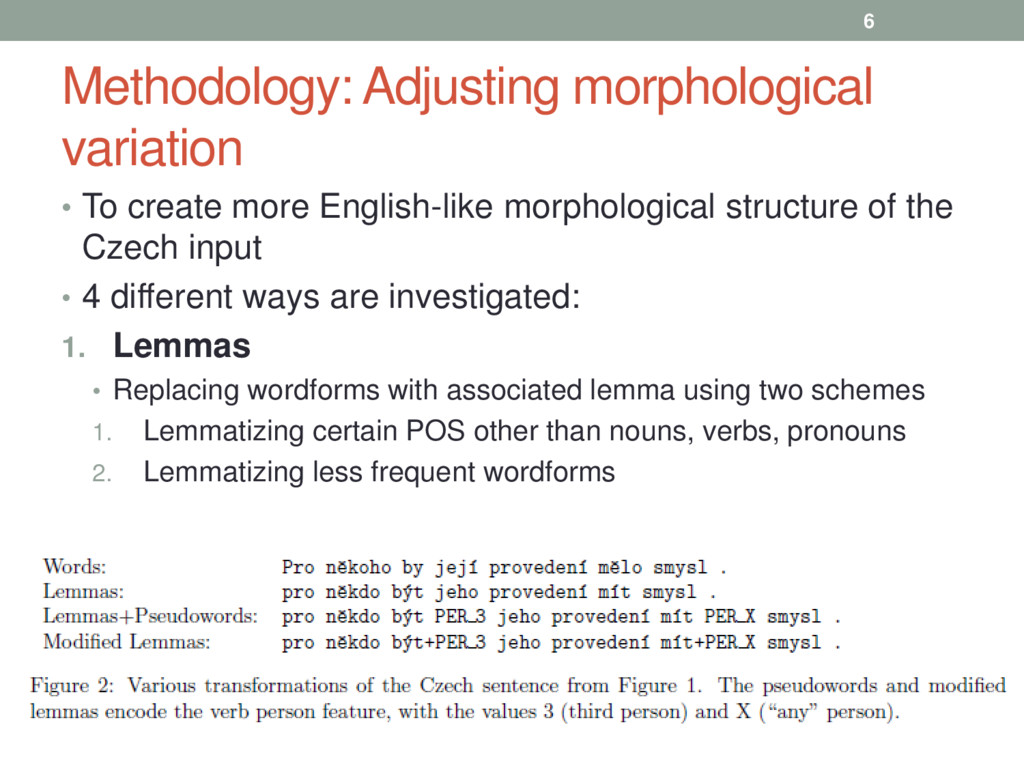
structure of the Czech input • 4 different ways are investigated: 1. Lemmas • Replacing wordforms with associated lemma using two schemes 1. Lemmatizing certain POS other than nouns, verbs, pronouns 2. Lemmatizing less frequent wordforms 6 -
Adjusting morphological variation (2) • 4 different ways 1. Lemmas
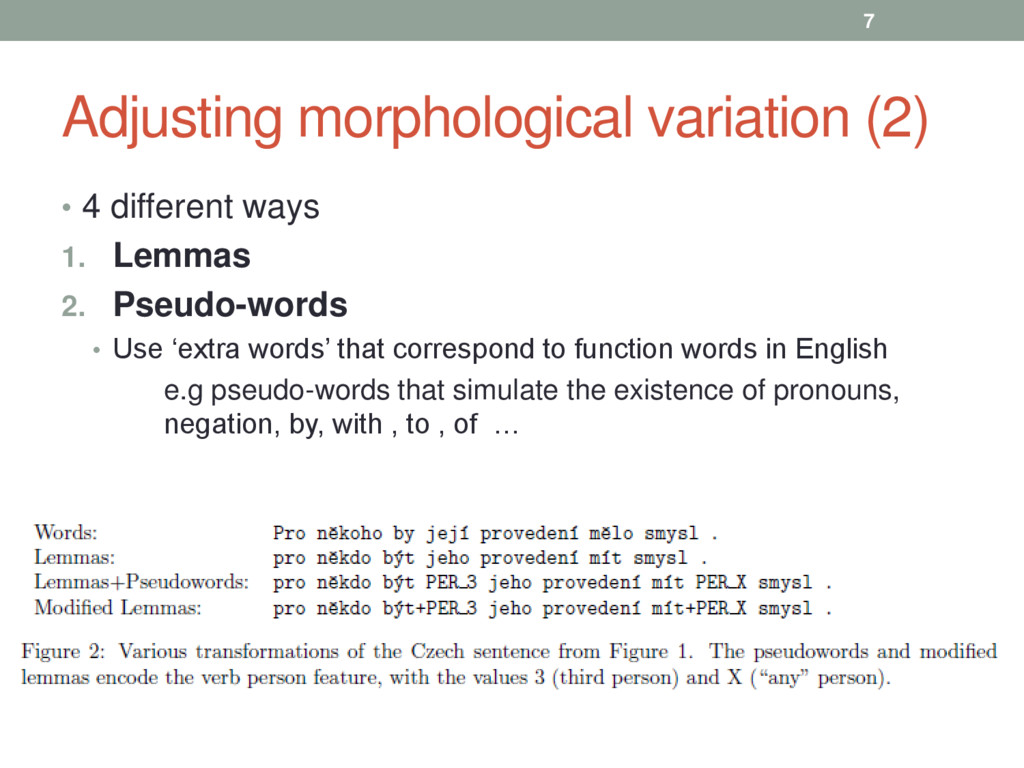
2. Pseudo-words • Use ‘extra words’ that correspond to function words in English e.g pseudo-words that simulate the existence of pronouns, negation, by, with , to , of … 7 -
Adjusting morphological variation (3) • 4 different ways 1. Lemmas
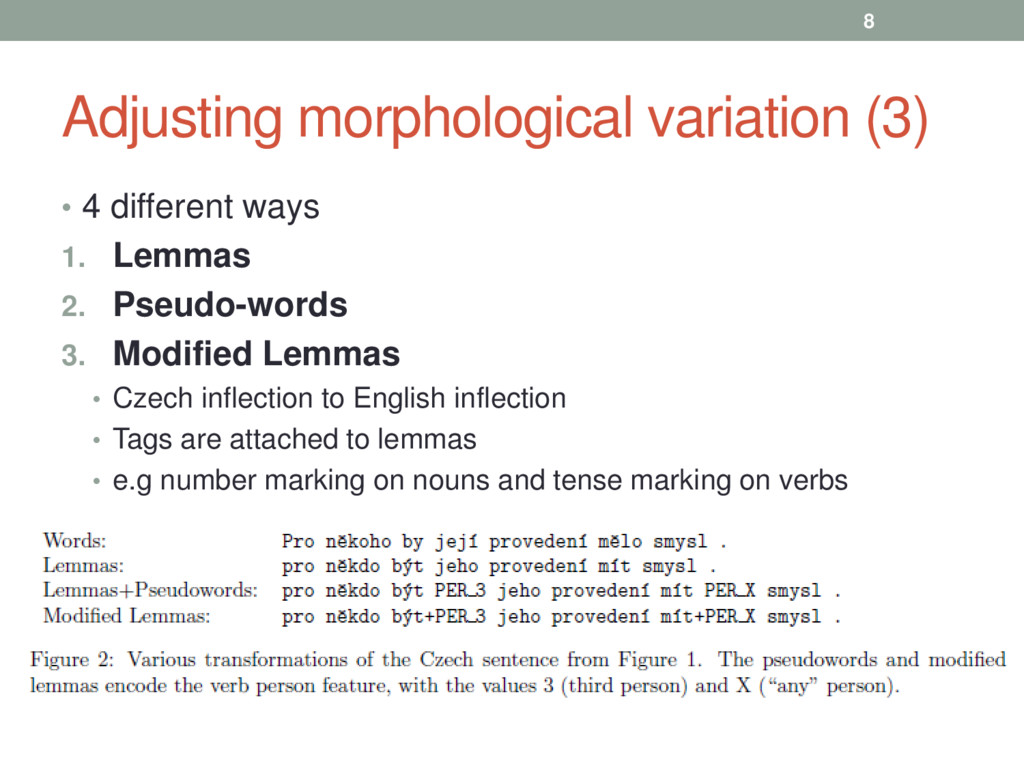
2. Pseudo-words 3. Modified Lemmas • Czech inflection to English inflection • Tags are attached to lemmas • e.g number marking on nouns and tense marking on verbs 8 -
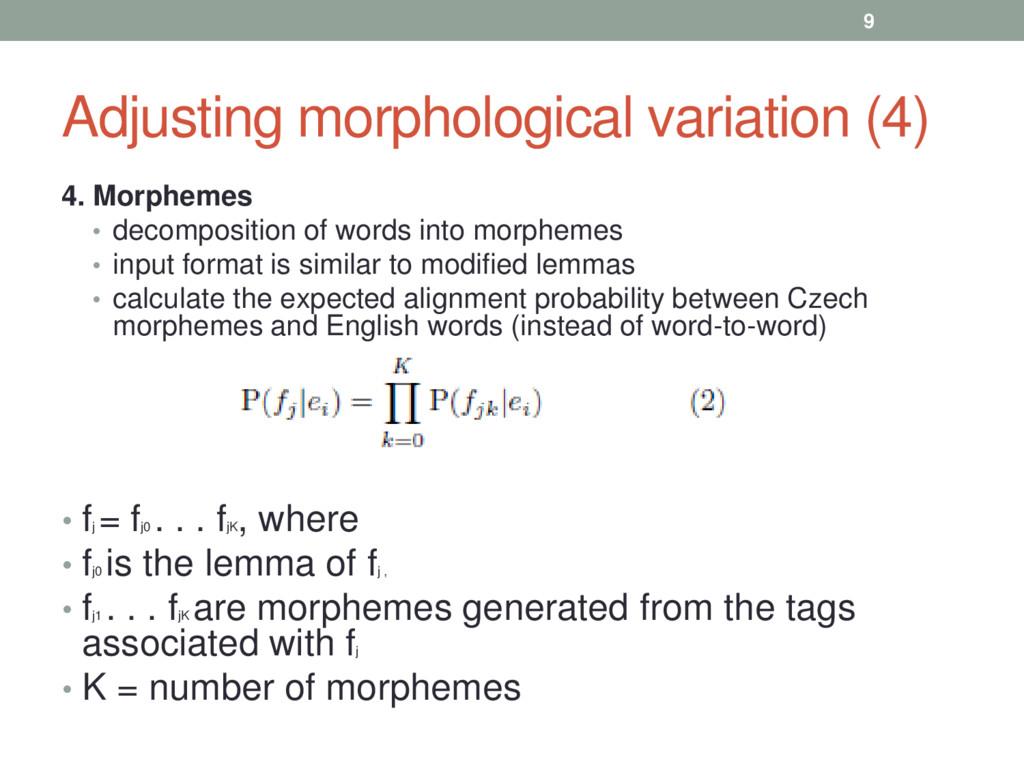
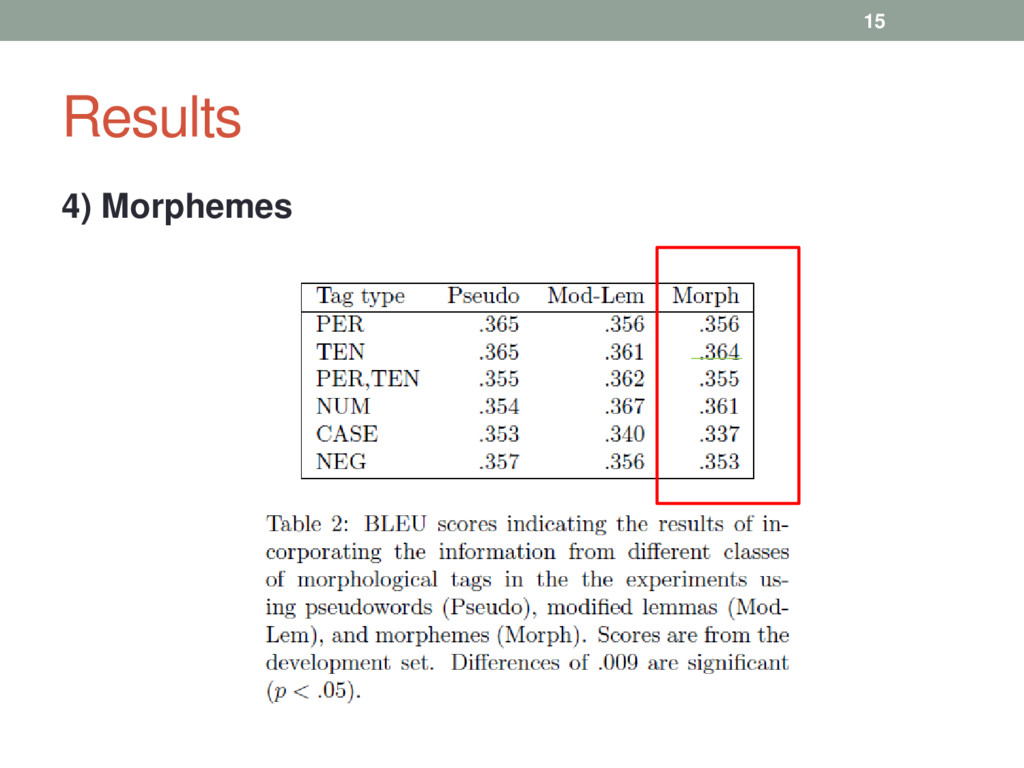
Adjusting morphological variation (4) 9 4. Morphemes • decomposition of
words into morphemes • input format is similar to modified lemmas • calculate the expected alignment probability between Czech morphemes and English words (instead of word-to-word) • fj = fj0 . . . fjK , where • fj0 is the lemma of fj , • fj1 . . . fjK are morphemes generated from the tags associated with fj • K = number of morphemes -
Experiments • Data is from the PCEDT corpus • Language
model • the English portion of PCEDT is the same as Penn WSJ corpus • trained with the Carnegie Mellon University (CMU) Statistical Language Modeling toolkit • Translation model • trained on GIZA++ • Decoder - ISI ReWrite Decoder • Training data – 50,000 sentences • Test and dev. data – 250 sentences • translated by 5 different translators for BLUE comparison • Baseline - word-to-word scores • .311 (development) and .270 (test) 10 -
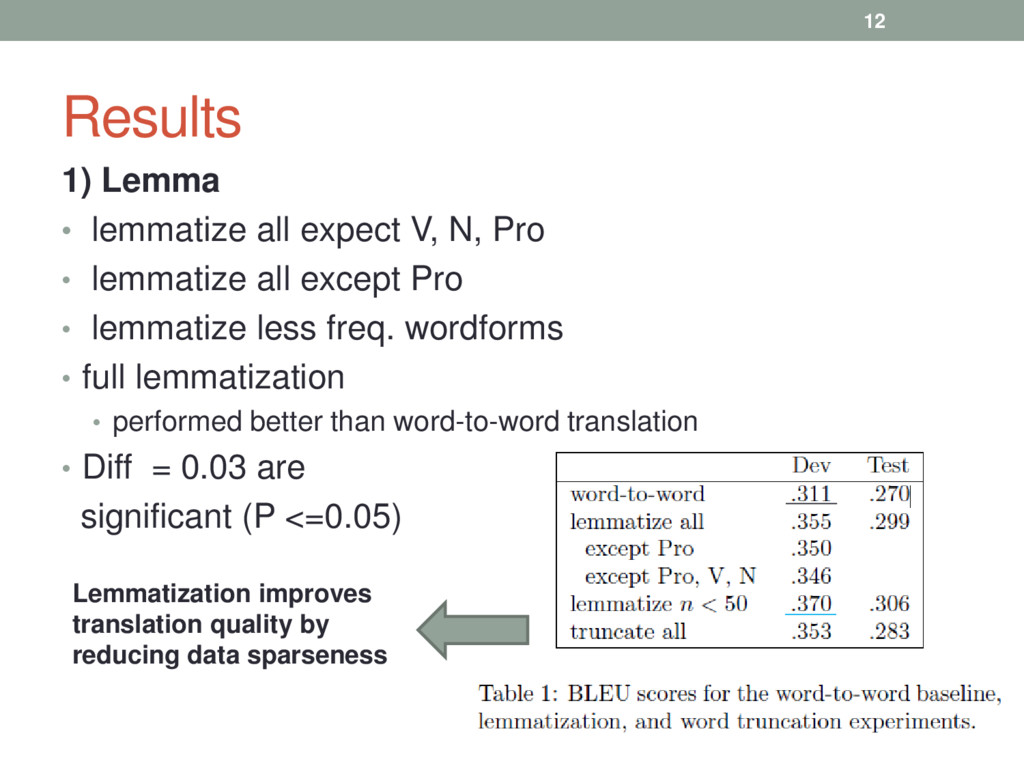
Results 1) Lemma • lemmatize all expect V, N, Pro
• lemmatize all except Pro • lemmatize less freq. wordforms • full lemmatization • performed better than word-to-word translation • Diff = 0.03 are significant (P <=0.05) 12 Lemmatization improves translation quality by reducing data sparseness -
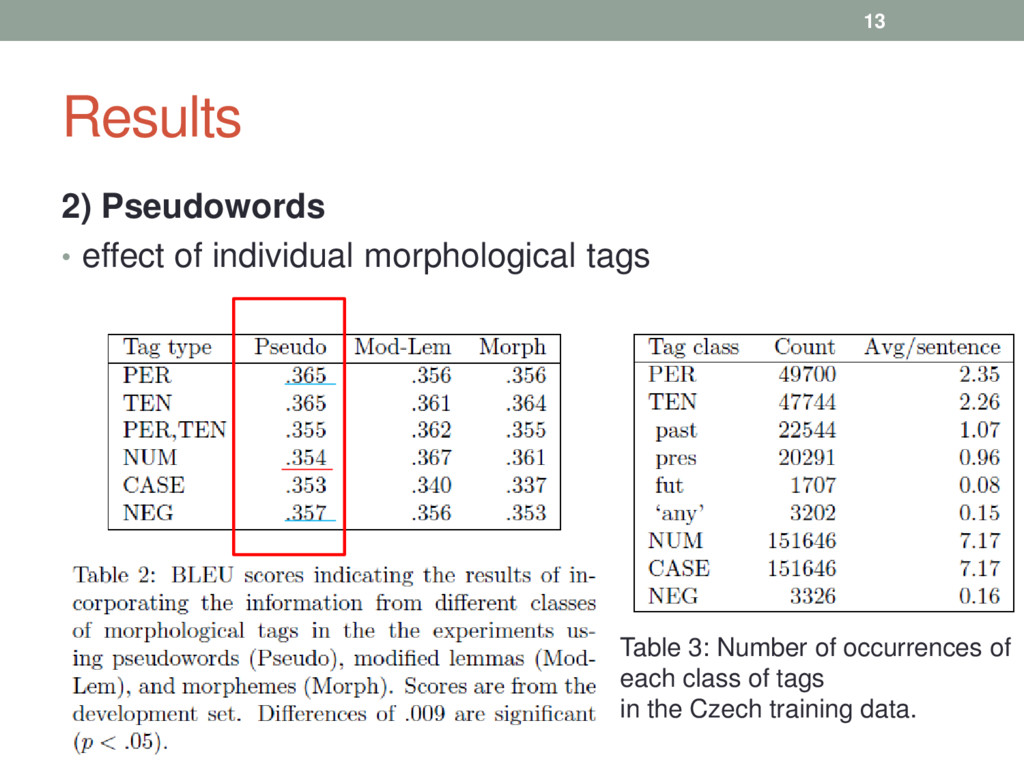
Results 2) Pseudowords • effect of individual morphological tags 13
Table 3: Number of occurrences of each class of tags in the Czech training data. -
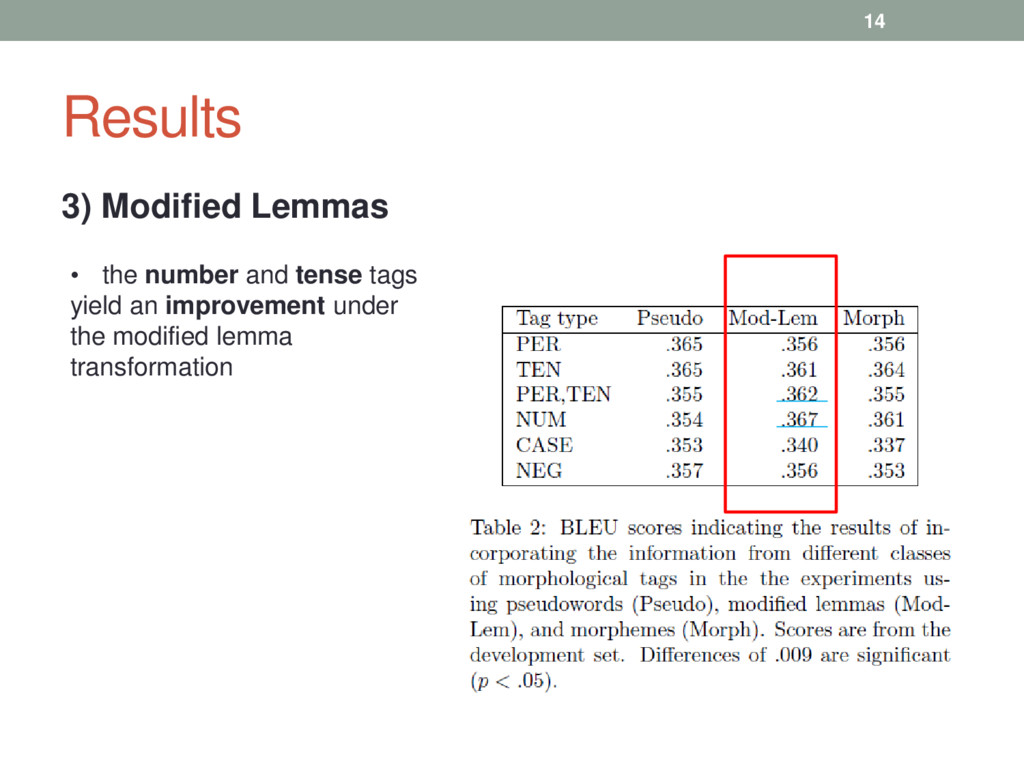
Results 3) Modified Lemmas 14 • the number and tense
tags yield an improvement under the modified lemma transformation -
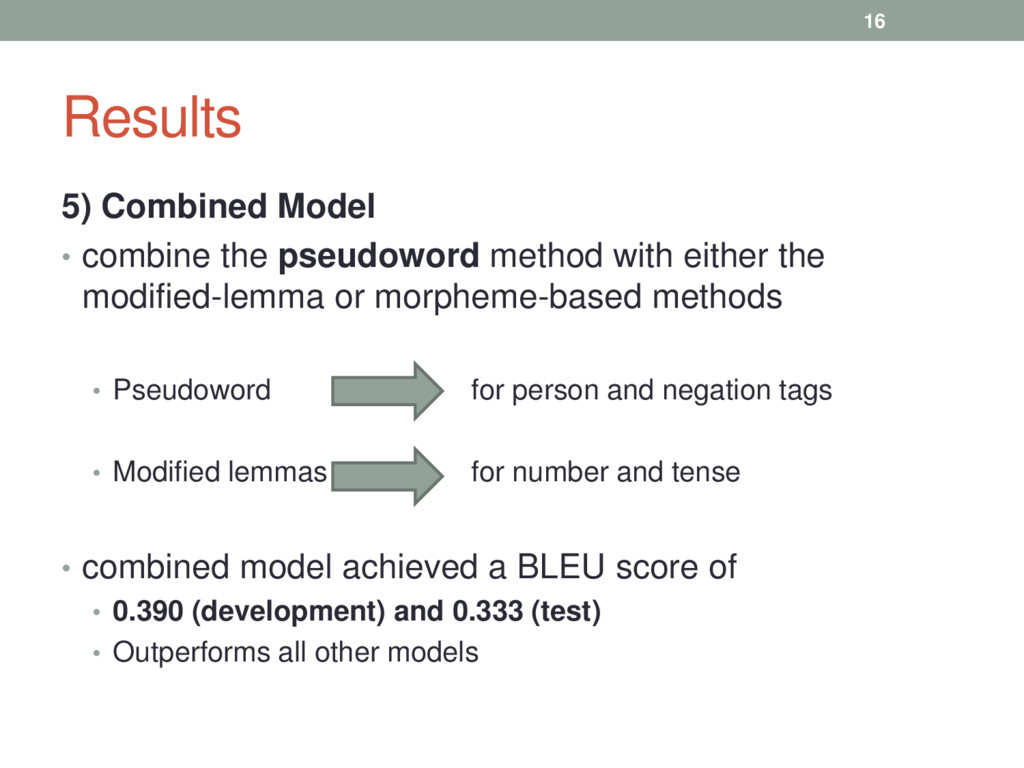
Results 5) Combined Model • combine the pseudoword method with
either the modified-lemma or morpheme-based methods • Pseudoword for person and negation tags • Modified lemmas for number and tense • combined model achieved a BLEU score of • 0.390 (development) and 0.333 (test) • Outperforms all other models 16 -
Conclusion • Showed that morphological analysis of highly inflected languages
can improve machine translation between high- inflection and low inflection languages • Simple lemmatization, • significantly reduces the sparse data problem • lemmatizing less frequent words improves performance • Showed correspondences that make the input data more English-like by introducing • discrete words • attachment to lemmas • combined models • Although the arrangements need to be determined for each language pair, the approach provided is beneficial for other languages also. 17