Share
Embed
20250411_PGStrom_with_Arrow.pdf
Apache Arrow Meet-up Tokyo 2025
https://red-data-tools.connpass.com/event/349680/

KaiGai Kohei
April 11, 2025
Transcript
23 slides
-
about Us... 20250411 - Apache Arrow MeetUp in Tokyo 2
Established: 4th-Jul-2017 Location: Tokyo / Japan Businesses: ✓ Development of high-performance data-processing software on top of heterogeneous architecture. ✓ Engineering service on GPU&DB area. We have developed the high-performance data processing software by the Heterogeneous Computing Technology for PostgreSQL Database. Who are you? KaiGai Kohei(海外 浩平) Chief Architect & CEO of HeteroDB,Inc Have contributed development of PostgreSQL and Linux kernel more than 10 years. (for security, database federation, custom-scan API, etc...) Primary developer of PG-Strom Award of genius programmer by METI/IPA (2006) PG-Strom -
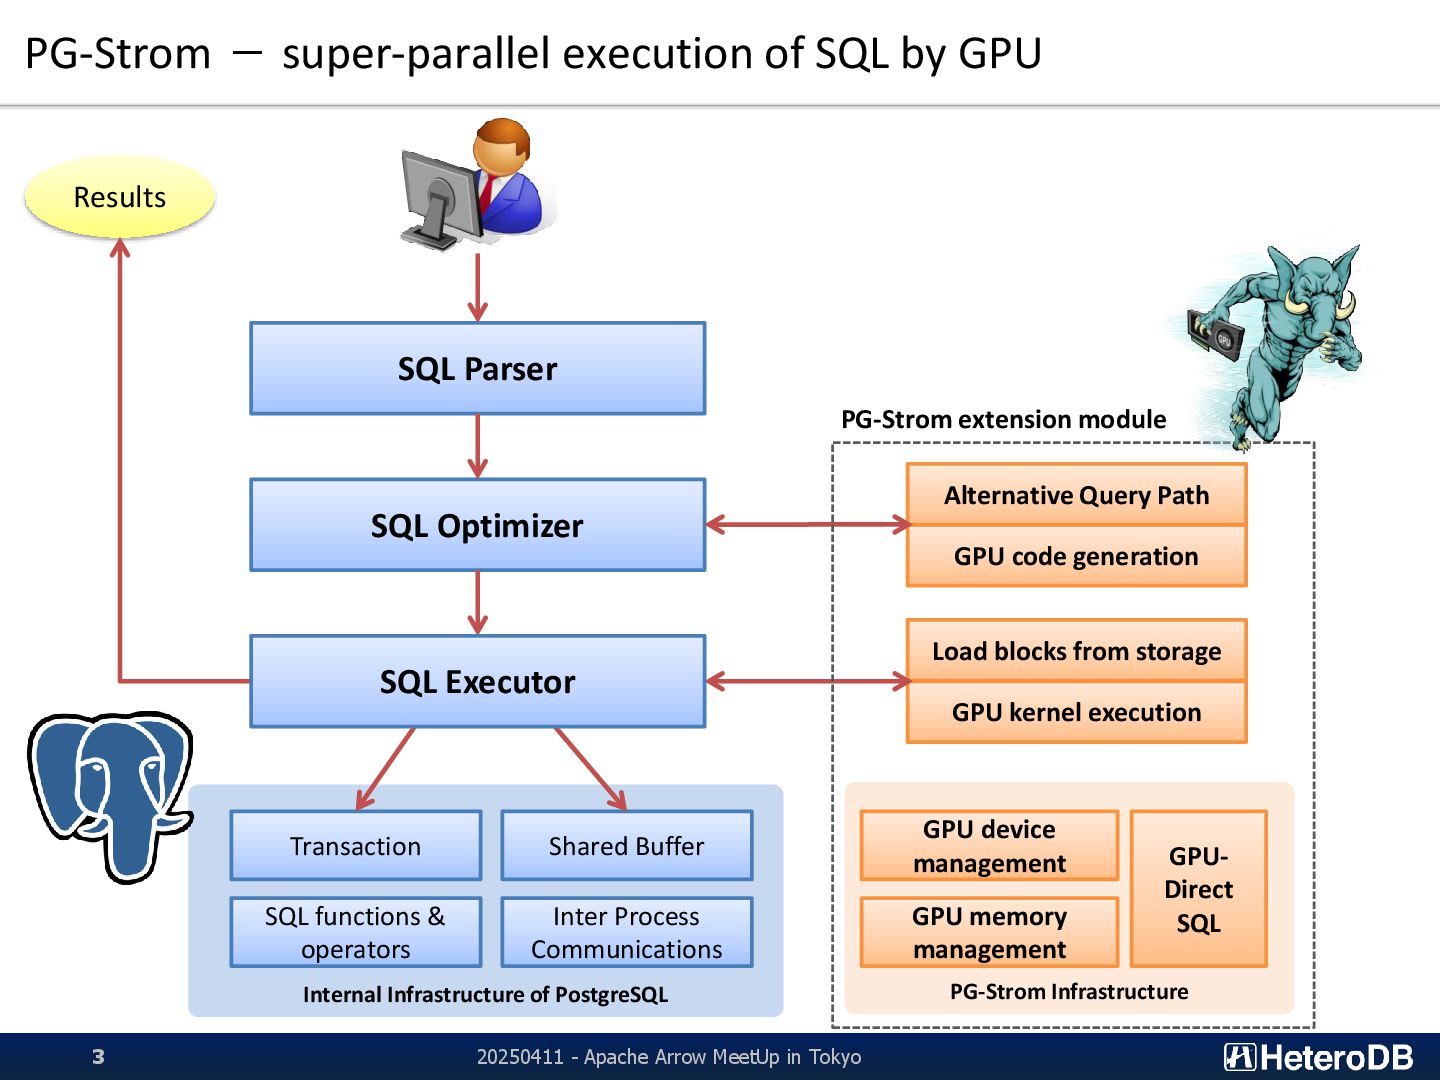
Internal Infrastructure of PostgreSQL PG-Strom - super-parallel execution of SQL
by GPU SQL Parser SQL Optimizer Transaction Shared Buffer SQL functions & operators Inter Process Communications Results GPU code generation Alternative Query Path PG-Strom Infrastructure GPU device management GPU memory management GPU- Direct SQL Load blocks from storage GPU kernel execution SQL Executor PG-Strom extension module 20250411 - Apache Arrow MeetUp in Tokyo 3 -
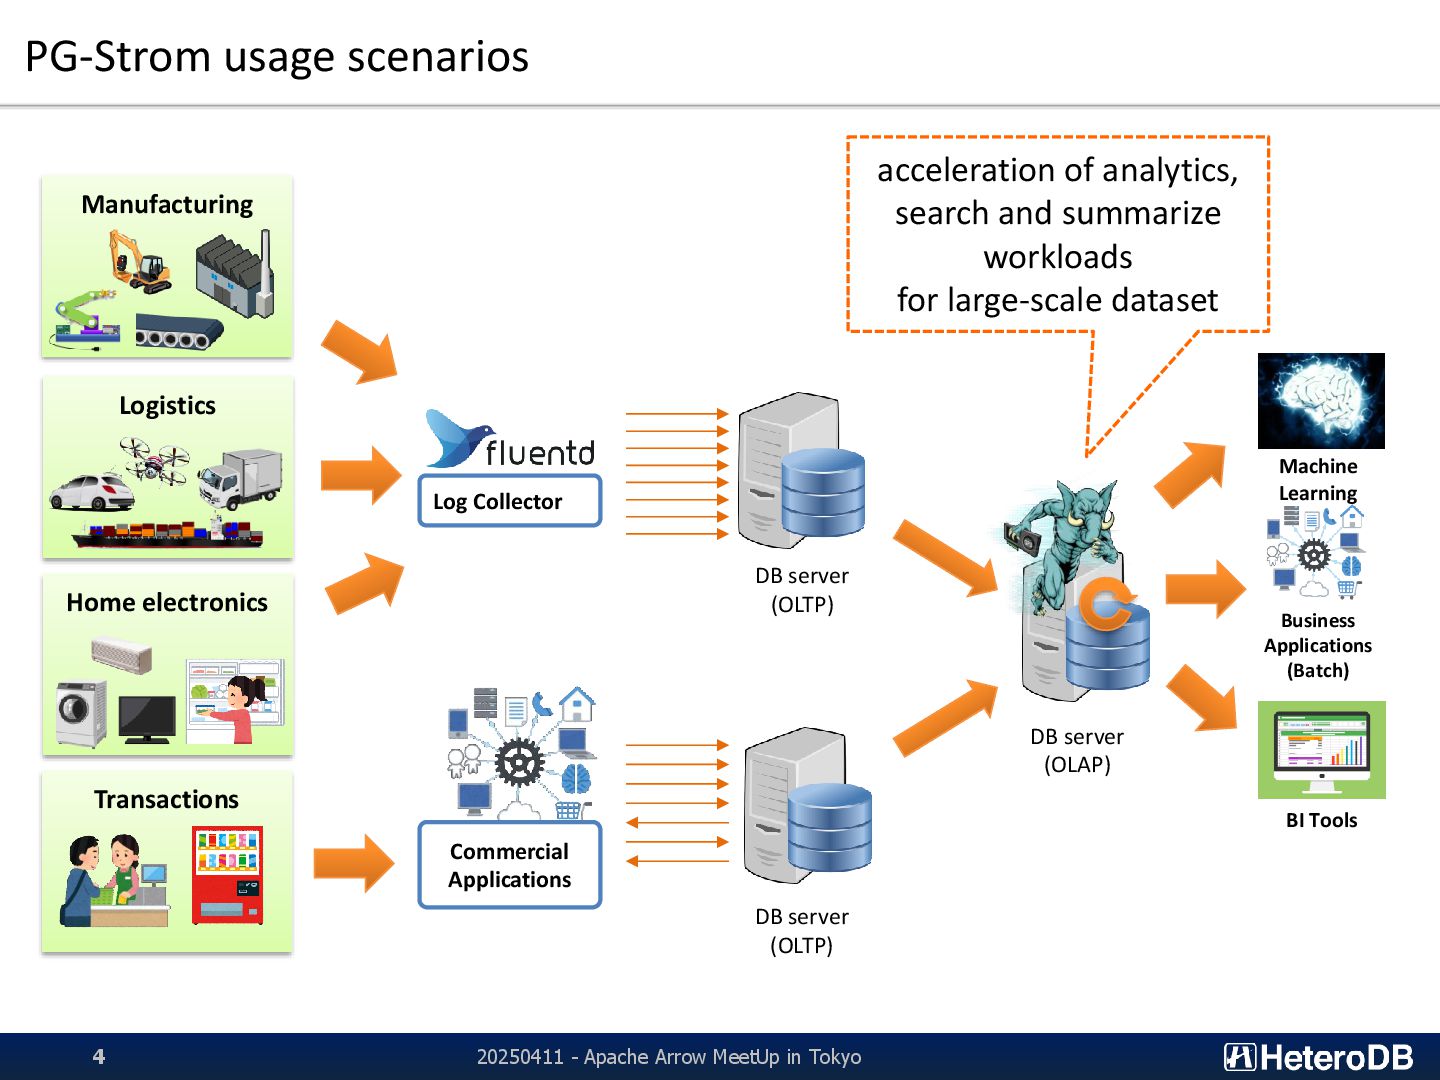
PG-Strom usage scenarios Logistics Manufacturing Transactions Home electronics Log Collector
Commercial Applications DB server (OLTP) DB server (OLTP) DB server (OLAP) BI Tools Business Applications (Batch) Machine Learning acceleration of analytics, search and summarize workloads for large-scale dataset 20250411 - Apache Arrow MeetUp in Tokyo 4 -
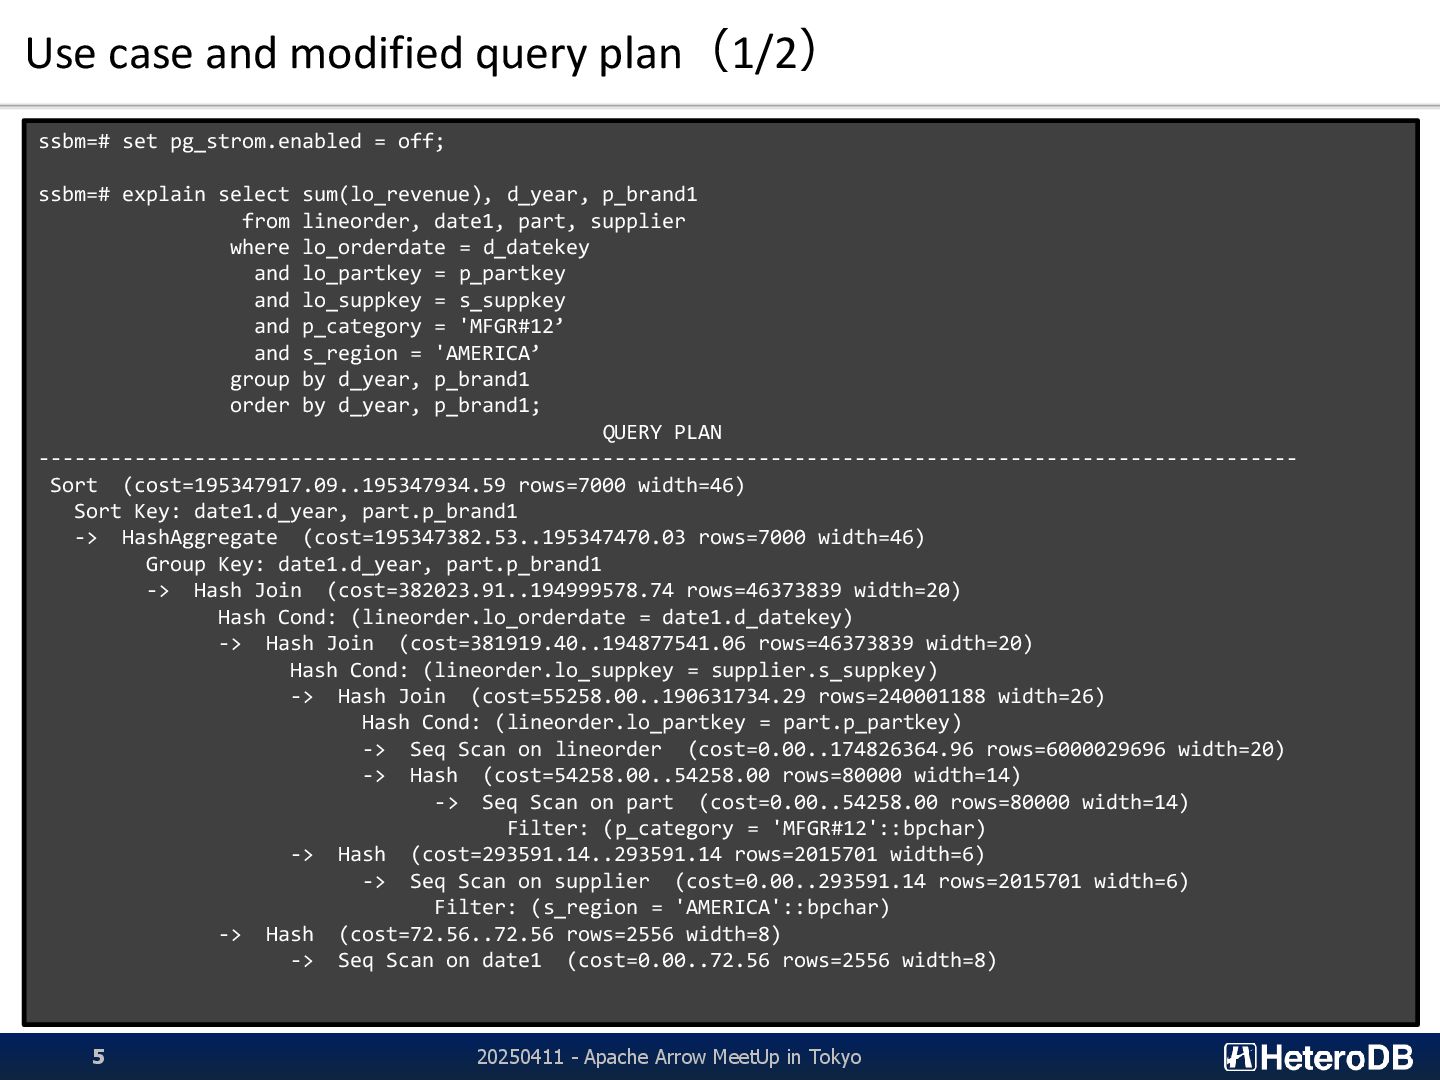
Use case and modified query plan(1/2) ssbm=# set pg_strom.enabled =
off; ssbm=# explain select sum(lo_revenue), d_year, p_brand1 from lineorder, date1, part, supplier where lo_orderdate = d_datekey and lo_partkey = p_partkey and lo_suppkey = s_suppkey and p_category = 'MFGR#12’ and s_region = 'AMERICA’ group by d_year, p_brand1 order by d_year, p_brand1; QUERY PLAN --------------------------------------------------------------------------------------------------------- Sort (cost=195347917.09..195347934.59 rows=7000 width=46) Sort Key: date1.d_year, part.p_brand1 -> HashAggregate (cost=195347382.53..195347470.03 rows=7000 width=46) Group Key: date1.d_year, part.p_brand1 -> Hash Join (cost=382023.91..194999578.74 rows=46373839 width=20) Hash Cond: (lineorder.lo_orderdate = date1.d_datekey) -> Hash Join (cost=381919.40..194877541.06 rows=46373839 width=20) Hash Cond: (lineorder.lo_suppkey = supplier.s_suppkey) -> Hash Join (cost=55258.00..190631734.29 rows=240001188 width=26) Hash Cond: (lineorder.lo_partkey = part.p_partkey) -> Seq Scan on lineorder (cost=0.00..174826364.96 rows=6000029696 width=20) -> Hash (cost=54258.00..54258.00 rows=80000 width=14) -> Seq Scan on part (cost=0.00..54258.00 rows=80000 width=14) Filter: (p_category = 'MFGR#12'::bpchar) -> Hash (cost=293591.14..293591.14 rows=2015701 width=6) -> Seq Scan on supplier (cost=0.00..293591.14 rows=2015701 width=6) Filter: (s_region = 'AMERICA'::bpchar) -> Hash (cost=72.56..72.56 rows=2556 width=8) -> Seq Scan on date1 (cost=0.00..72.56 rows=2556 width=8) 20250411 - Apache Arrow MeetUp in Tokyo 5 -
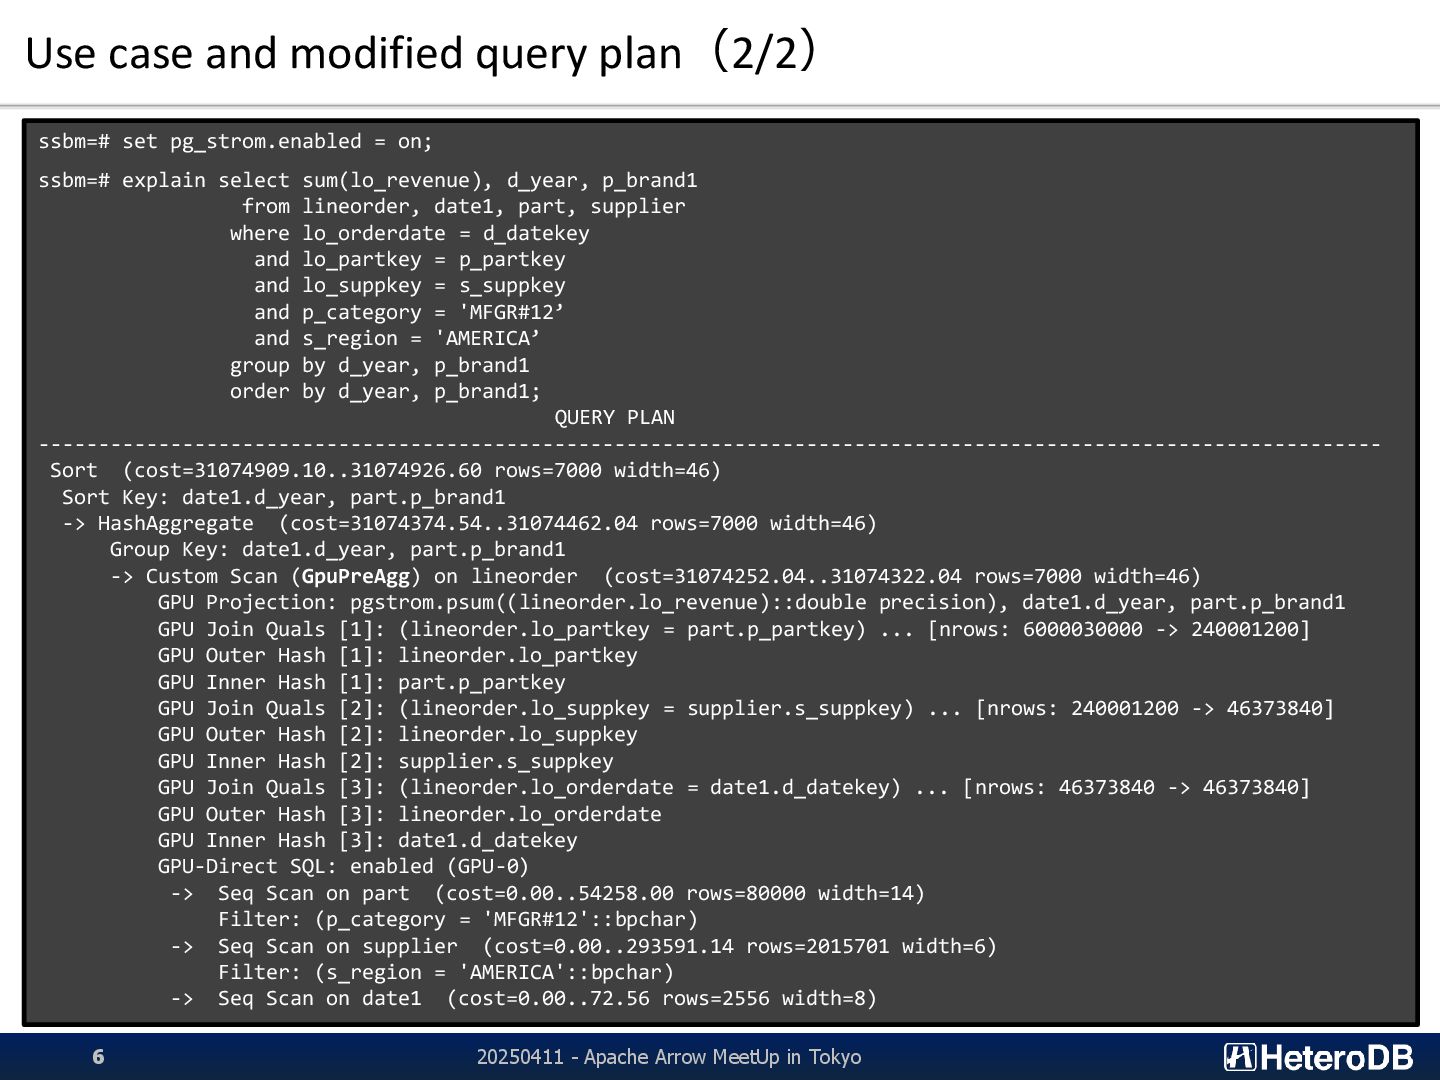
Use case and modified query plan(2/2) ssbm=# set pg_strom.enabled =
on; ssbm=# explain select sum(lo_revenue), d_year, p_brand1 from lineorder, date1, part, supplier where lo_orderdate = d_datekey and lo_partkey = p_partkey and lo_suppkey = s_suppkey and p_category = 'MFGR#12’ and s_region = 'AMERICA’ group by d_year, p_brand1 order by d_year, p_brand1; QUERY PLAN ---------------------------------------------------------------------------------------------------------------- Sort (cost=31074909.10..31074926.60 rows=7000 width=46) Sort Key: date1.d_year, part.p_brand1 -> HashAggregate (cost=31074374.54..31074462.04 rows=7000 width=46) Group Key: date1.d_year, part.p_brand1 -> Custom Scan (GpuPreAgg) on lineorder (cost=31074252.04..31074322.04 rows=7000 width=46) GPU Projection: pgstrom.psum((lineorder.lo_revenue)::double precision), date1.d_year, part.p_brand1 GPU Join Quals [1]: (lineorder.lo_partkey = part.p_partkey) ... [nrows: 6000030000 -> 240001200] GPU Outer Hash [1]: lineorder.lo_partkey GPU Inner Hash [1]: part.p_partkey GPU Join Quals [2]: (lineorder.lo_suppkey = supplier.s_suppkey) ... [nrows: 240001200 -> 46373840] GPU Outer Hash [2]: lineorder.lo_suppkey GPU Inner Hash [2]: supplier.s_suppkey GPU Join Quals [3]: (lineorder.lo_orderdate = date1.d_datekey) ... [nrows: 46373840 -> 46373840] GPU Outer Hash [3]: lineorder.lo_orderdate GPU Inner Hash [3]: date1.d_datekey GPU-Direct SQL: enabled (GPU-0) -> Seq Scan on part (cost=0.00..54258.00 rows=80000 width=14) Filter: (p_category = 'MFGR#12'::bpchar) -> Seq Scan on supplier (cost=0.00..293591.14 rows=2015701 width=6) Filter: (s_region = 'AMERICA'::bpchar) -> Seq Scan on date1 (cost=0.00..72.56 rows=2556 width=8) 20250411 - Apache Arrow MeetUp in Tokyo 6 -
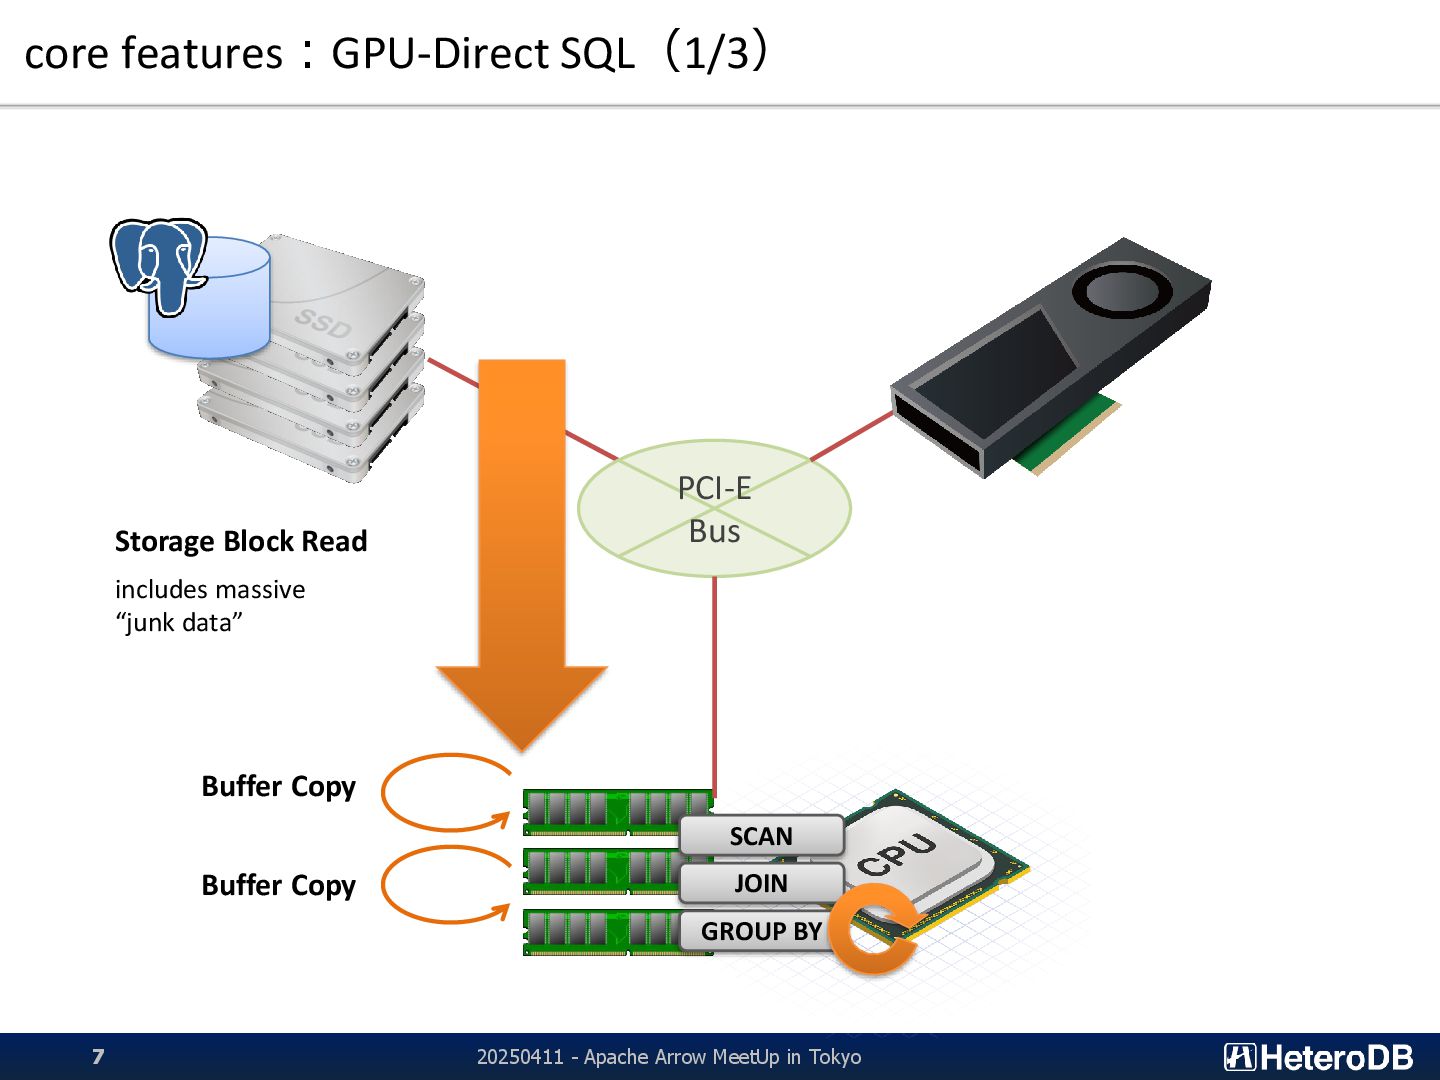
core features:GPU-Direct SQL(1/3) PCI-E Bus Buffer Copy Buffer Copy SCAN
JOIN GROUP BY Storage Block Read includes massive “junk data” 20250411 - Apache Arrow MeetUp in Tokyo 7 -
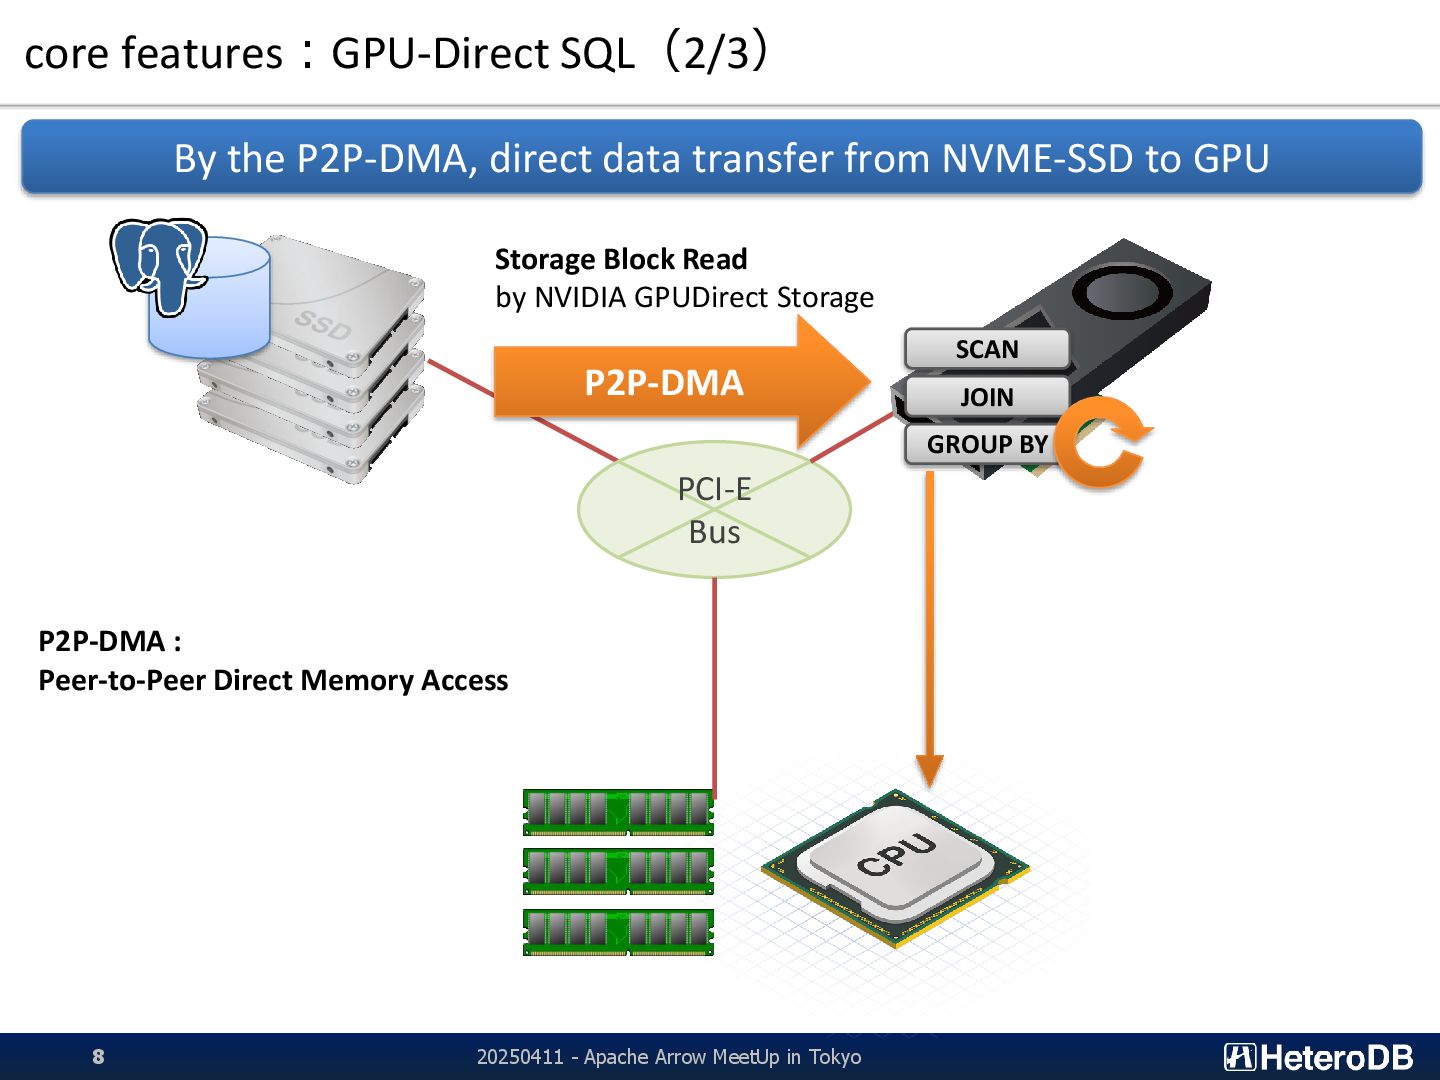
core features:GPU-Direct SQL(2/3) By the P2P-DMA, direct data transfer from
NVME-SSD to GPU PCI-E Bus SCAN JOIN GROUP BY Storage Block Read by NVIDIA GPUDirect Storage P2P-DMA P2P-DMA : Peer-to-Peer Direct Memory Access 20250411 - Apache Arrow MeetUp in Tokyo 8 -
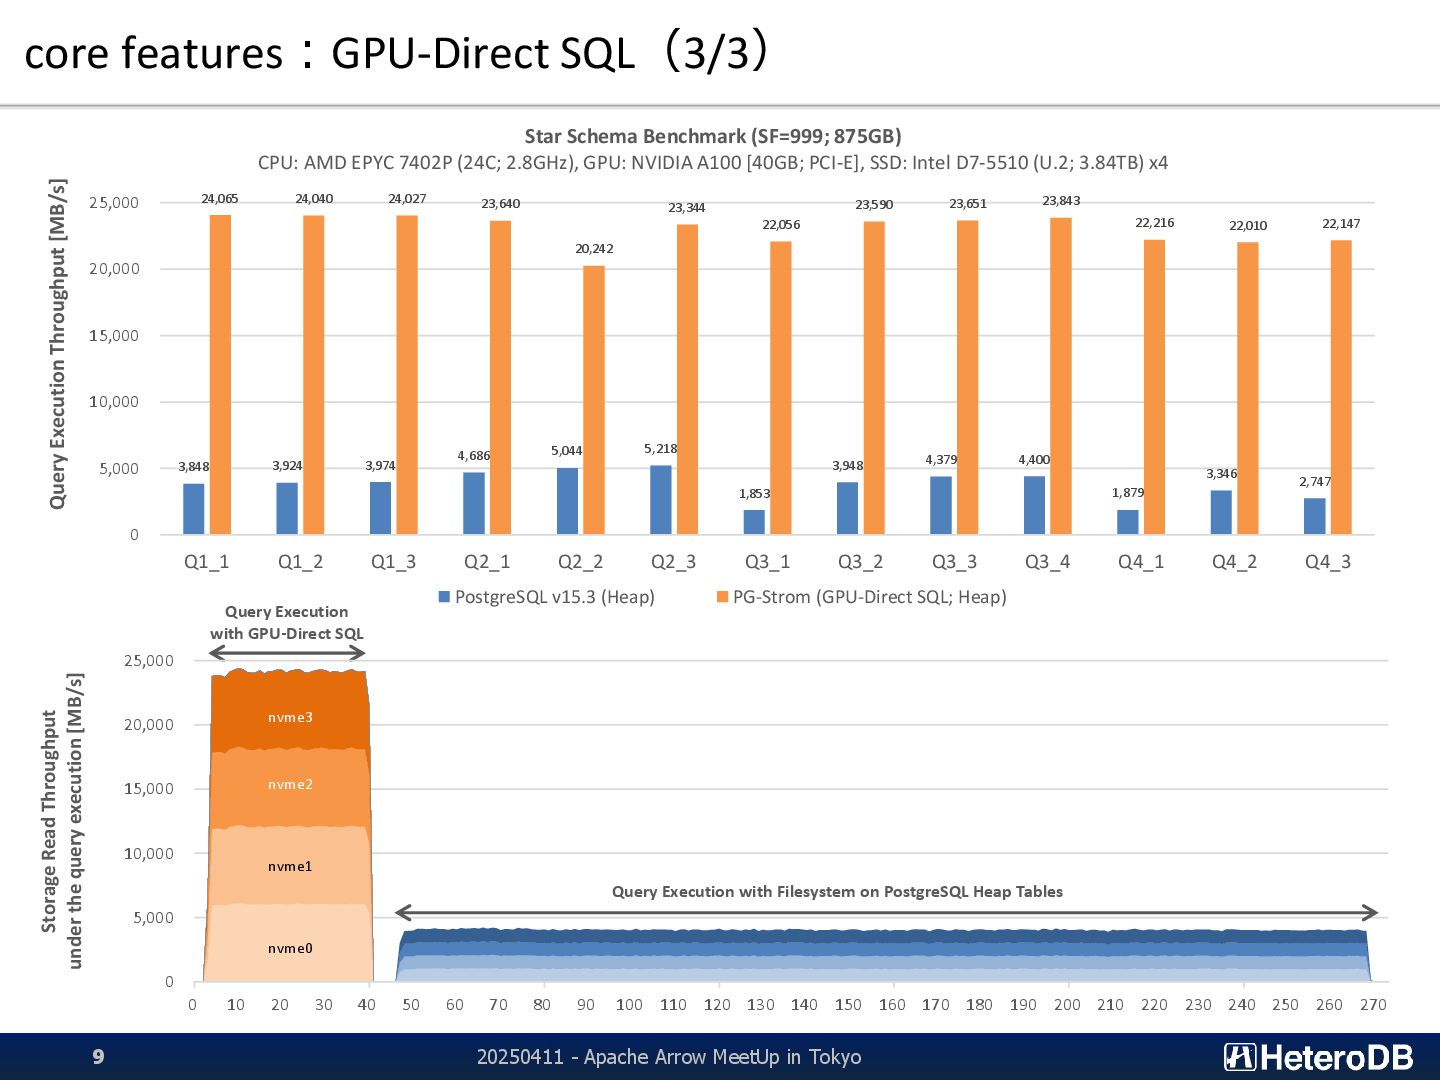
core features:GPU-Direct SQL(3/3) Query Execution with GPU-Direct SQL 20250411 -
Apache Arrow MeetUp in Tokyo 9 3,848 3,924 3,974 4,686 5,044 5,218 1,853 3,948 4,379 4,400 1,879 3,346 2,747 24,065 24,040 24,027 23,640 20,242 23,344 22,056 23,590 23,651 23,843 22,216 22,010 22,147 0 5,000 10,000 15,000 20,000 25,000 Q1_1 Q1_2 Q1_3 Q2_1 Q2_2 Q2_3 Q3_1 Q3_2 Q3_3 Q3_4 Q4_1 Q4_2 Q4_3 Query Execution Throughput [MB/s] Star Schema Benchmark (SF=999; 875GB) CPU: AMD EPYC 7402P (24C; 2.8GHz), GPU: NVIDIA A100 [40GB; PCI-E], SSD: Intel D7-5510 (U.2; 3.84TB) x4 PostgreSQL v15.3 (Heap) PG-Strom (GPU-Direct SQL; Heap) 0 5,000 10,000 15,000 20,000 25,000 0 10 20 30 40 50 60 70 80 90 100 110 120 130 140 150 160 170 180 190 200 210 220 230 240 250 260 270 Storage Read Throughput under the query execution [MB/s] nvme3 nvme2 nvme1 nvme0 Query Execution with Filesystem on PostgreSQL Heap Tables -
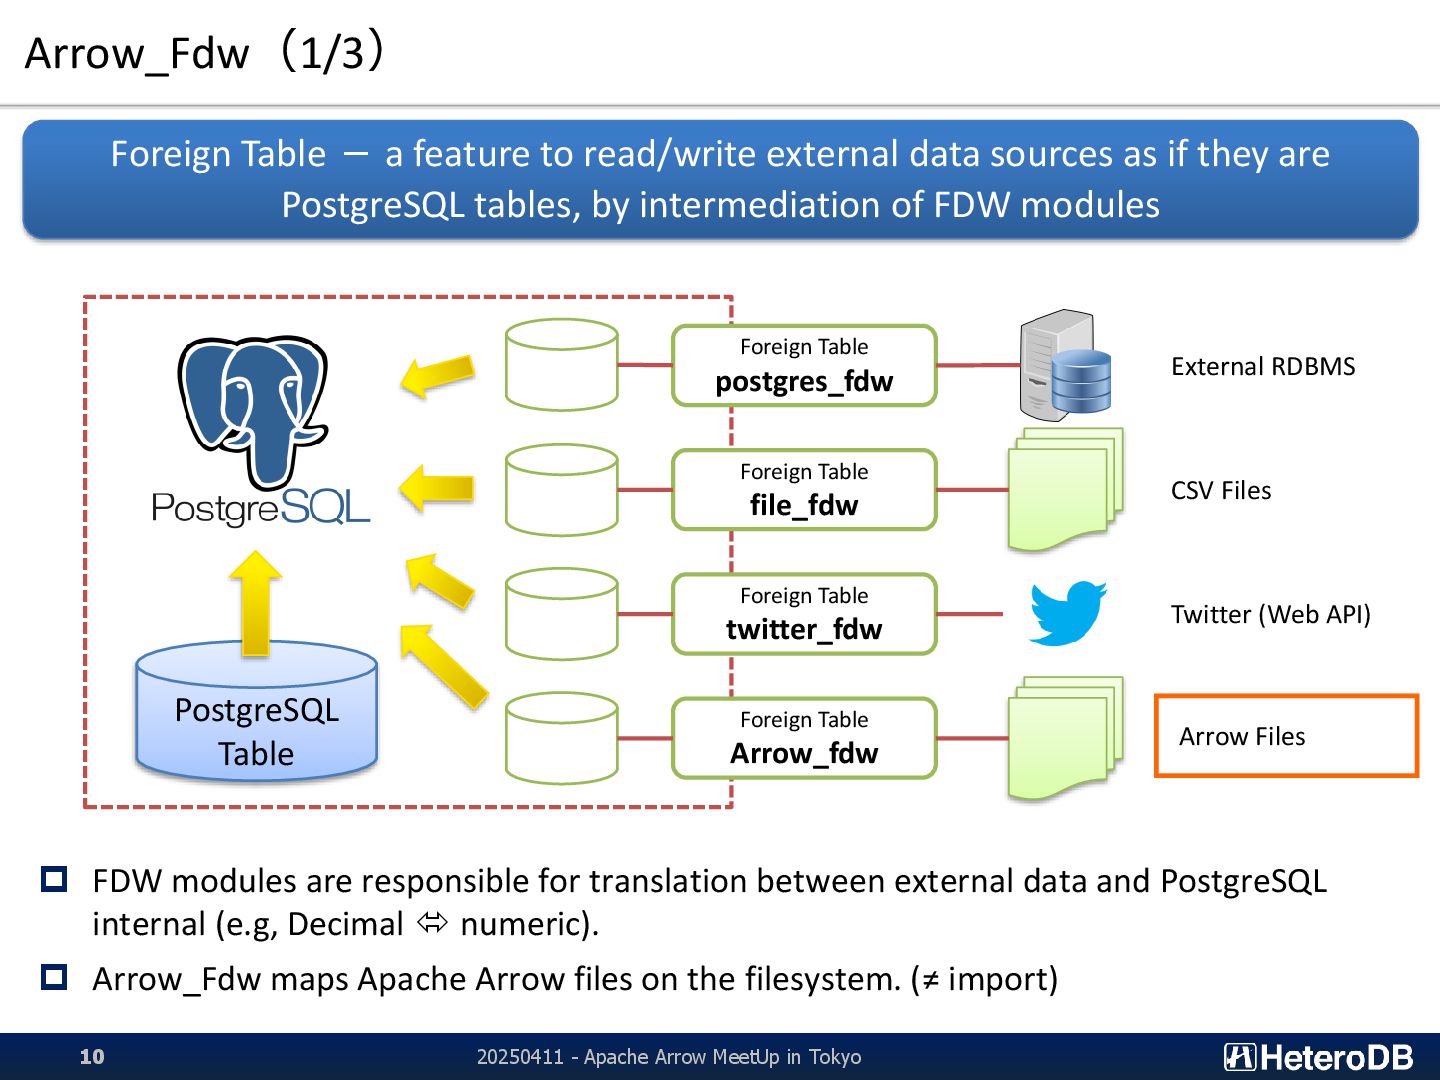
Arrow_Fdw(1/3) 20250411 - Apache Arrow MeetUp in Tokyo 10
FDW modules are responsible for translation between external data and PostgreSQL internal (e.g, Decimal numeric). Arrow_Fdw maps Apache Arrow files on the filesystem. (≠ import) Foreign Table - a feature to read/write external data sources as if they are PostgreSQL tables, by intermediation of FDW modules PostgreSQL Table Foreign Table postgres_fdw Foreign Table file_fdw Foreign Table twitter_fdw Foreign Table Arrow_fdw External RDBMS CSV Files Twitter (Web API) Arrow Files -
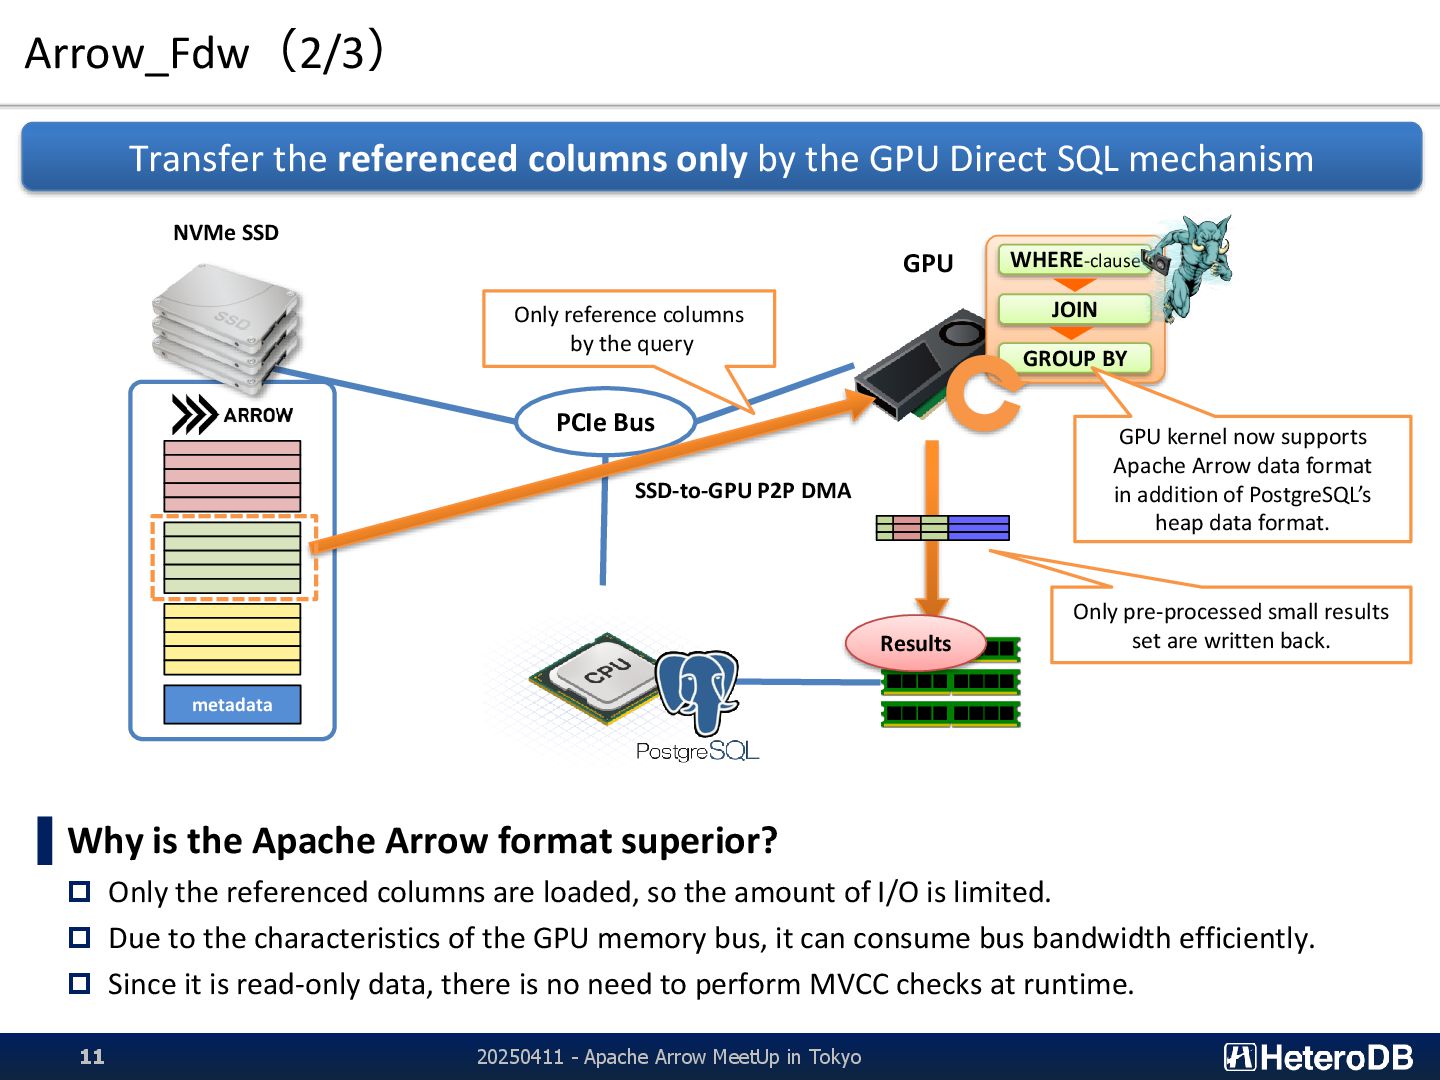
Arrow_Fdw(2/3) 20250411 - Apache Arrow MeetUp in Tokyo 11 ▌Why
is the Apache Arrow format superior? Only the referenced columns are loaded, so the amount of I/O is limited. Due to the characteristics of the GPU memory bus, it can consume bus bandwidth efficiently. Since it is read-only data, there is no need to perform MVCC checks at runtime. Transfer the referenced columns only by the GPU Direct SQL mechanism PCIe Bus NVMe SSD GPU SSD-to-GPU P2P DMA WHERE-clause JOIN GROUP BY Only reference columns by the query GPU kernel now supports Apache Arrow data format in addition of PostgreSQL’s heap data format. Only pre-processed small results set are written back. Results metadata -
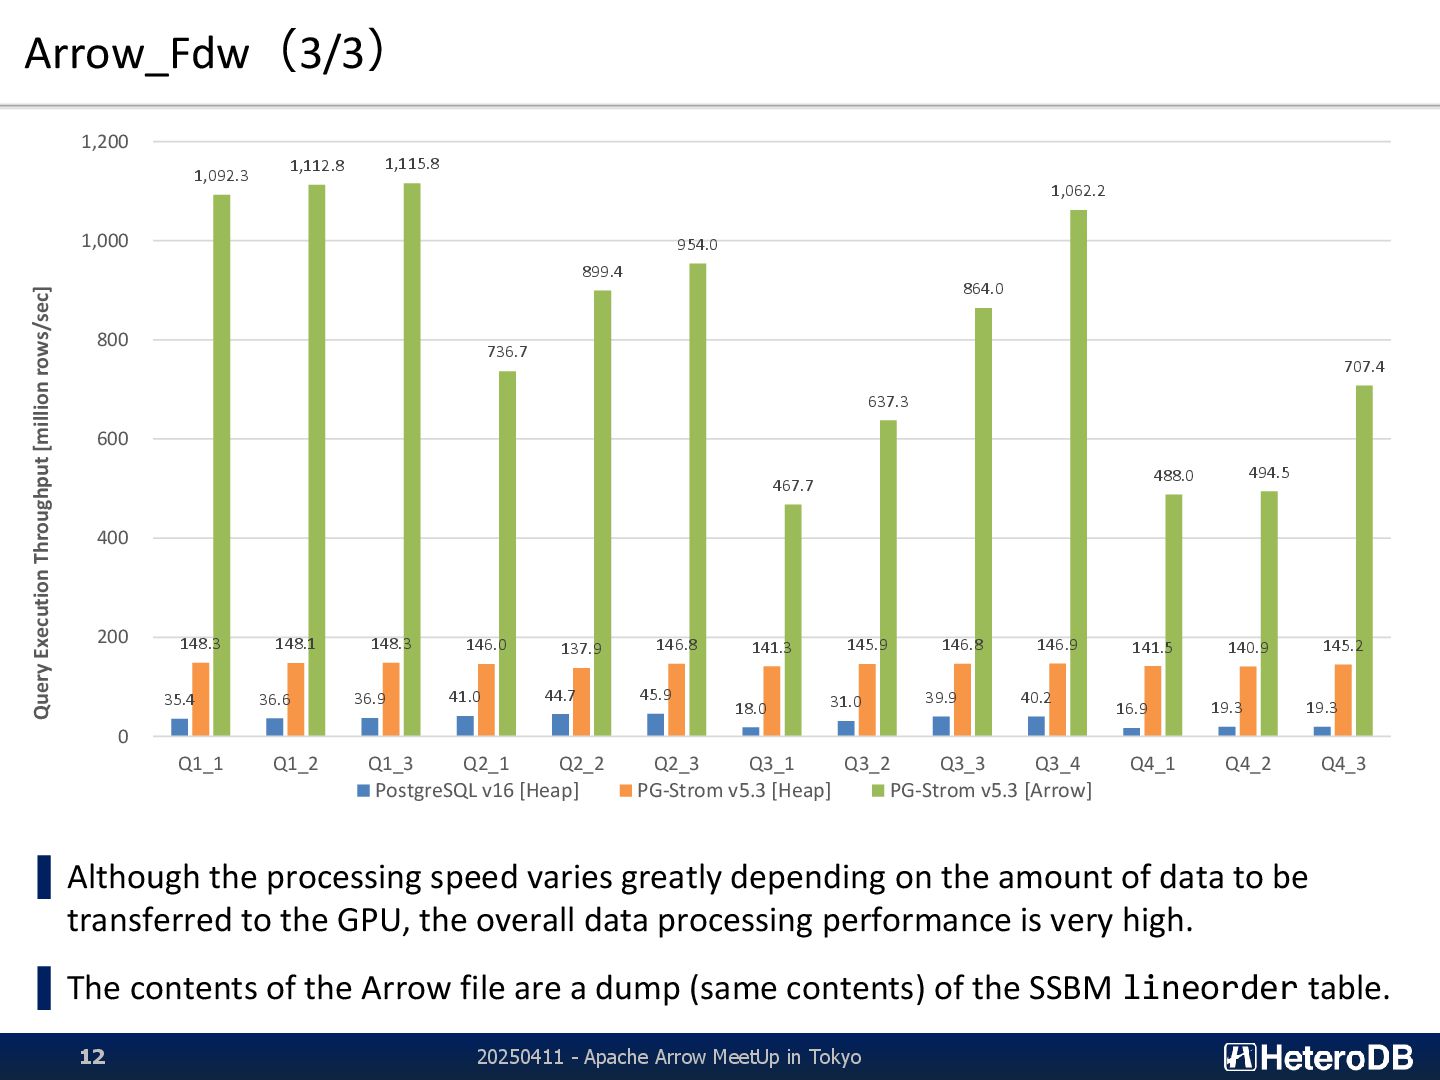
Arrow_Fdw(3/3) ▌Although the processing speed varies greatly depending on the
amount of data to be transferred to the GPU, the overall data processing performance is very high. ▌The contents of the Arrow file are a dump (same contents) of the SSBM lineorder table. 35.4 36.6 36.9 41.0 44.7 45.9 18.0 31.0 39.9 40.2 16.9 19.3 19.3 148.3 148.1 148.3 146.0 137.9 146.8 141.3 145.9 146.8 146.9 141.5 140.9 145.2 1,092.3 1,112.8 1,115.8 736.7 899.4 954.0 467.7 637.3 864.0 1,062.2 488.0 494.5 707.4 0 200 400 600 800 1,000 1,200 Q1_1 Q1_2 Q1_3 Q2_1 Q2_2 Q2_3 Q3_1 Q3_2 Q3_3 Q3_4 Q4_1 Q4_2 Q4_3 Query Execution Throughput [million rows/sec] PostgreSQL v16 [Heap] PG-Strom v5.3 [Heap] PG-Strom v5.3 [Arrow] 20250411 - Apache Arrow MeetUp in Tokyo 12 -
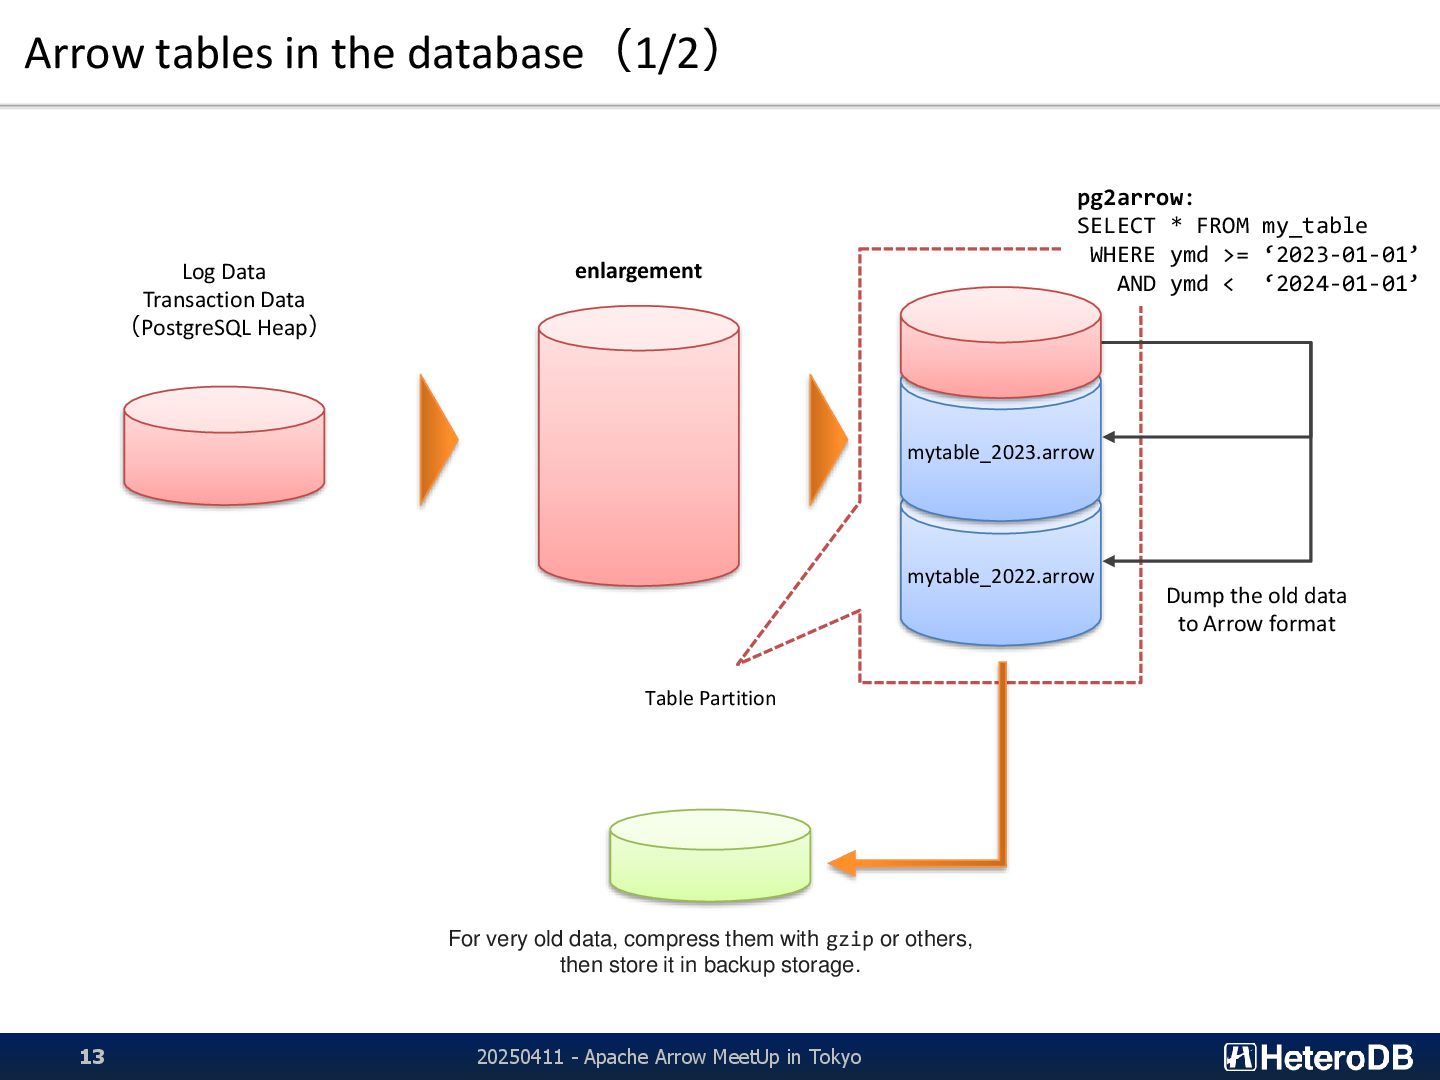
pg2arrow: SELECT * FROM my_table WHERE ymd >= ‘2023-01-01’ AND
ymd < ‘2024-01-01’ Arrow tables in the database(1/2) Log Data Transaction Data (PostgreSQL Heap) enlargement Dump the old data to Arrow format For very old data, compress them with gzip or others, then store it in backup storage. Table Partition mytable_2022.arrow mytable_2023.arrow 20250411 - Apache Arrow MeetUp in Tokyo 13 -
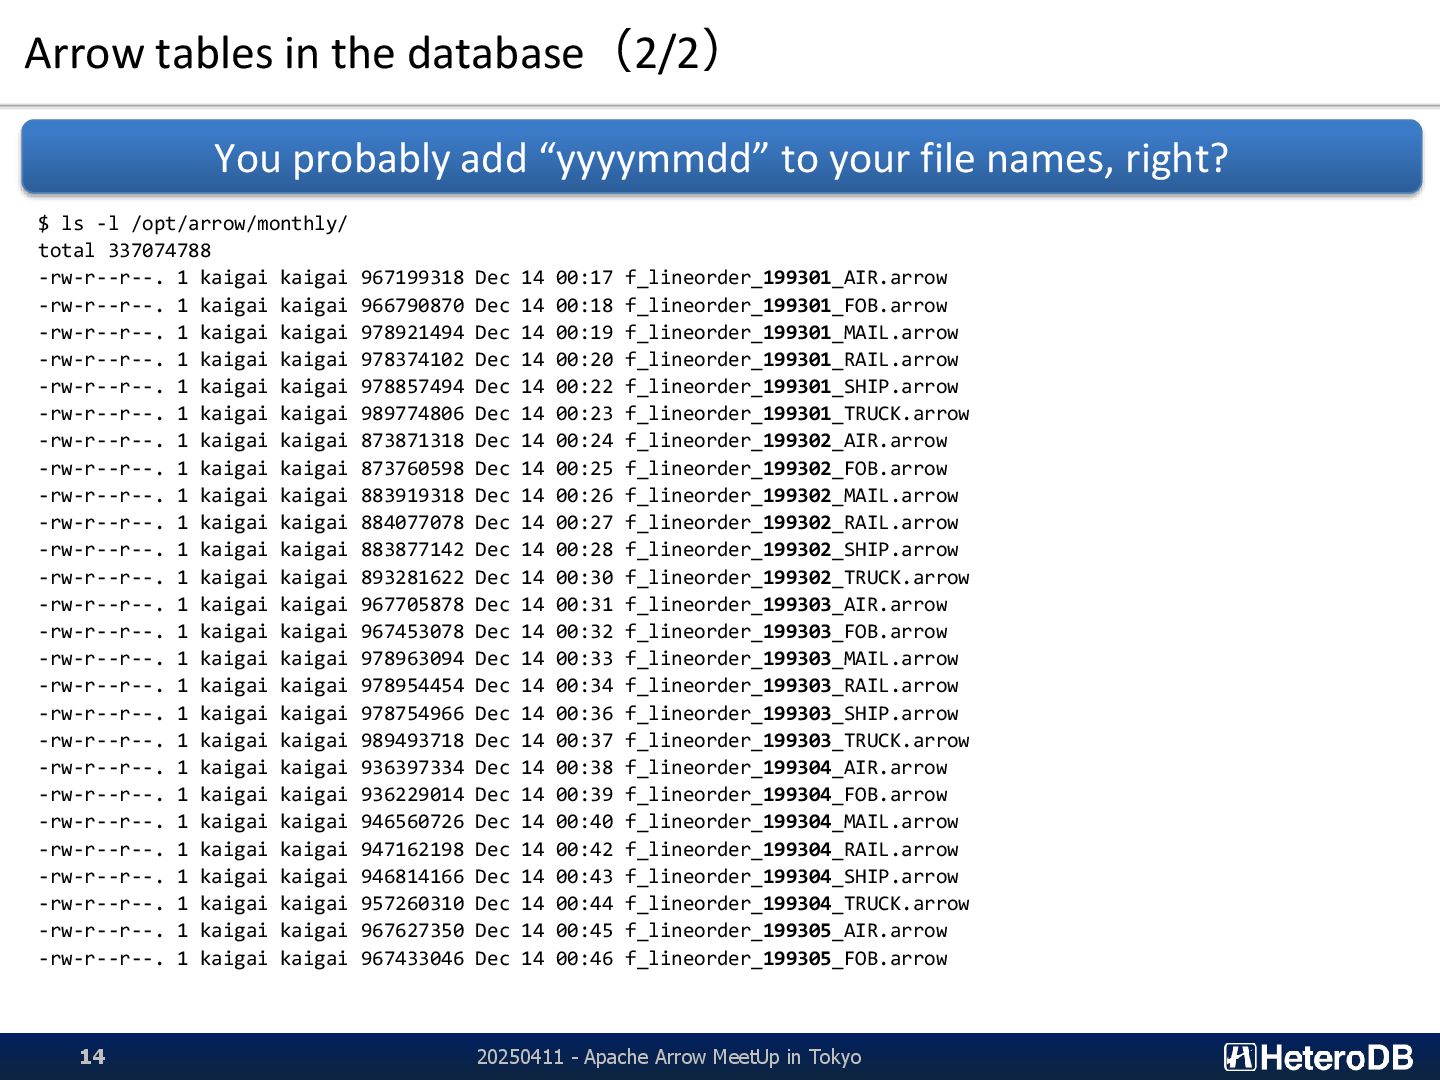
Arrow tables in the database(2/2) $ ls -l /opt/arrow/monthly/ total
337074788 -rw-r--r--. 1 kaigai kaigai 967199318 Dec 14 00:17 f_lineorder_199301_AIR.arrow -rw-r--r--. 1 kaigai kaigai 966790870 Dec 14 00:18 f_lineorder_199301_FOB.arrow -rw-r--r--. 1 kaigai kaigai 978921494 Dec 14 00:19 f_lineorder_199301_MAIL.arrow -rw-r--r--. 1 kaigai kaigai 978374102 Dec 14 00:20 f_lineorder_199301_RAIL.arrow -rw-r--r--. 1 kaigai kaigai 978857494 Dec 14 00:22 f_lineorder_199301_SHIP.arrow -rw-r--r--. 1 kaigai kaigai 989774806 Dec 14 00:23 f_lineorder_199301_TRUCK.arrow -rw-r--r--. 1 kaigai kaigai 873871318 Dec 14 00:24 f_lineorder_199302_AIR.arrow -rw-r--r--. 1 kaigai kaigai 873760598 Dec 14 00:25 f_lineorder_199302_FOB.arrow -rw-r--r--. 1 kaigai kaigai 883919318 Dec 14 00:26 f_lineorder_199302_MAIL.arrow -rw-r--r--. 1 kaigai kaigai 884077078 Dec 14 00:27 f_lineorder_199302_RAIL.arrow -rw-r--r--. 1 kaigai kaigai 883877142 Dec 14 00:28 f_lineorder_199302_SHIP.arrow -rw-r--r--. 1 kaigai kaigai 893281622 Dec 14 00:30 f_lineorder_199302_TRUCK.arrow -rw-r--r--. 1 kaigai kaigai 967705878 Dec 14 00:31 f_lineorder_199303_AIR.arrow -rw-r--r--. 1 kaigai kaigai 967453078 Dec 14 00:32 f_lineorder_199303_FOB.arrow -rw-r--r--. 1 kaigai kaigai 978963094 Dec 14 00:33 f_lineorder_199303_MAIL.arrow -rw-r--r--. 1 kaigai kaigai 978954454 Dec 14 00:34 f_lineorder_199303_RAIL.arrow -rw-r--r--. 1 kaigai kaigai 978754966 Dec 14 00:36 f_lineorder_199303_SHIP.arrow -rw-r--r--. 1 kaigai kaigai 989493718 Dec 14 00:37 f_lineorder_199303_TRUCK.arrow -rw-r--r--. 1 kaigai kaigai 936397334 Dec 14 00:38 f_lineorder_199304_AIR.arrow -rw-r--r--. 1 kaigai kaigai 936229014 Dec 14 00:39 f_lineorder_199304_FOB.arrow -rw-r--r--. 1 kaigai kaigai 946560726 Dec 14 00:40 f_lineorder_199304_MAIL.arrow -rw-r--r--. 1 kaigai kaigai 947162198 Dec 14 00:42 f_lineorder_199304_RAIL.arrow -rw-r--r--. 1 kaigai kaigai 946814166 Dec 14 00:43 f_lineorder_199304_SHIP.arrow -rw-r--r--. 1 kaigai kaigai 957260310 Dec 14 00:44 f_lineorder_199304_TRUCK.arrow -rw-r--r--. 1 kaigai kaigai 967627350 Dec 14 00:45 f_lineorder_199305_AIR.arrow -rw-r--r--. 1 kaigai kaigai 967433046 Dec 14 00:46 f_lineorder_199305_FOB.arrow You probably add “yyyymmdd” to your file names, right? 20250411 - Apache Arrow MeetUp in Tokyo 14 -
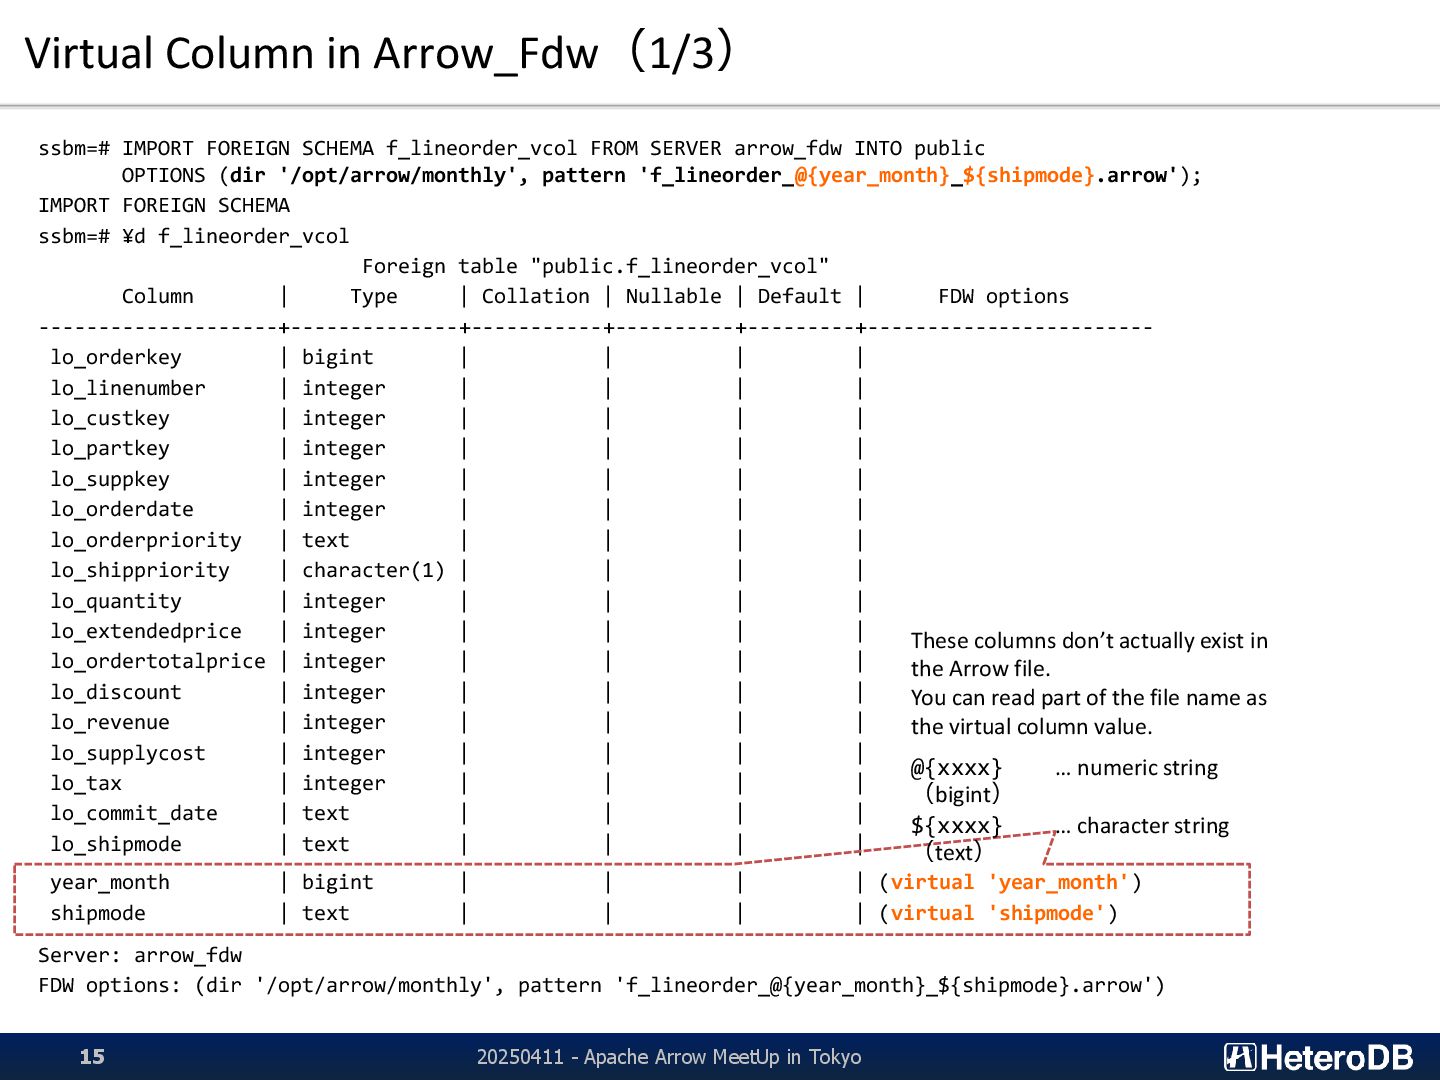
Virtual Column in Arrow_Fdw(1/3) ssbm=# IMPORT FOREIGN SCHEMA f_lineorder_vcol FROM
SERVER arrow_fdw INTO public OPTIONS (dir '/opt/arrow/monthly', pattern 'f_lineorder_@{year_month}_${shipmode}.arrow'); IMPORT FOREIGN SCHEMA ssbm=# ¥d f_lineorder_vcol Foreign table "public.f_lineorder_vcol" Column | Type | Collation | Nullable | Default | FDW options --------------------+--------------+-----------+----------+---------+------------------------ lo_orderkey | bigint | | | | lo_linenumber | integer | | | | lo_custkey | integer | | | | lo_partkey | integer | | | | lo_suppkey | integer | | | | lo_orderdate | integer | | | | lo_orderpriority | text | | | | lo_shippriority | character(1) | | | | lo_quantity | integer | | | | lo_extendedprice | integer | | | | lo_ordertotalprice | integer | | | | lo_discount | integer | | | | lo_revenue | integer | | | | lo_supplycost | integer | | | | lo_tax | integer | | | | lo_commit_date | text | | | | lo_shipmode | text | | | | year_month | bigint | | | | (virtual 'year_month') shipmode | text | | | | (virtual 'shipmode') Server: arrow_fdw FDW options: (dir '/opt/arrow/monthly', pattern 'f_lineorder_@{year_month}_${shipmode}.arrow') These columns don’t actually exist in the Arrow file. You can read part of the file name as the virtual column value. @{xxxx} … numeric string (bigint) ${xxxx} … character string (text) 20250411 - Apache Arrow MeetUp in Tokyo 15 -
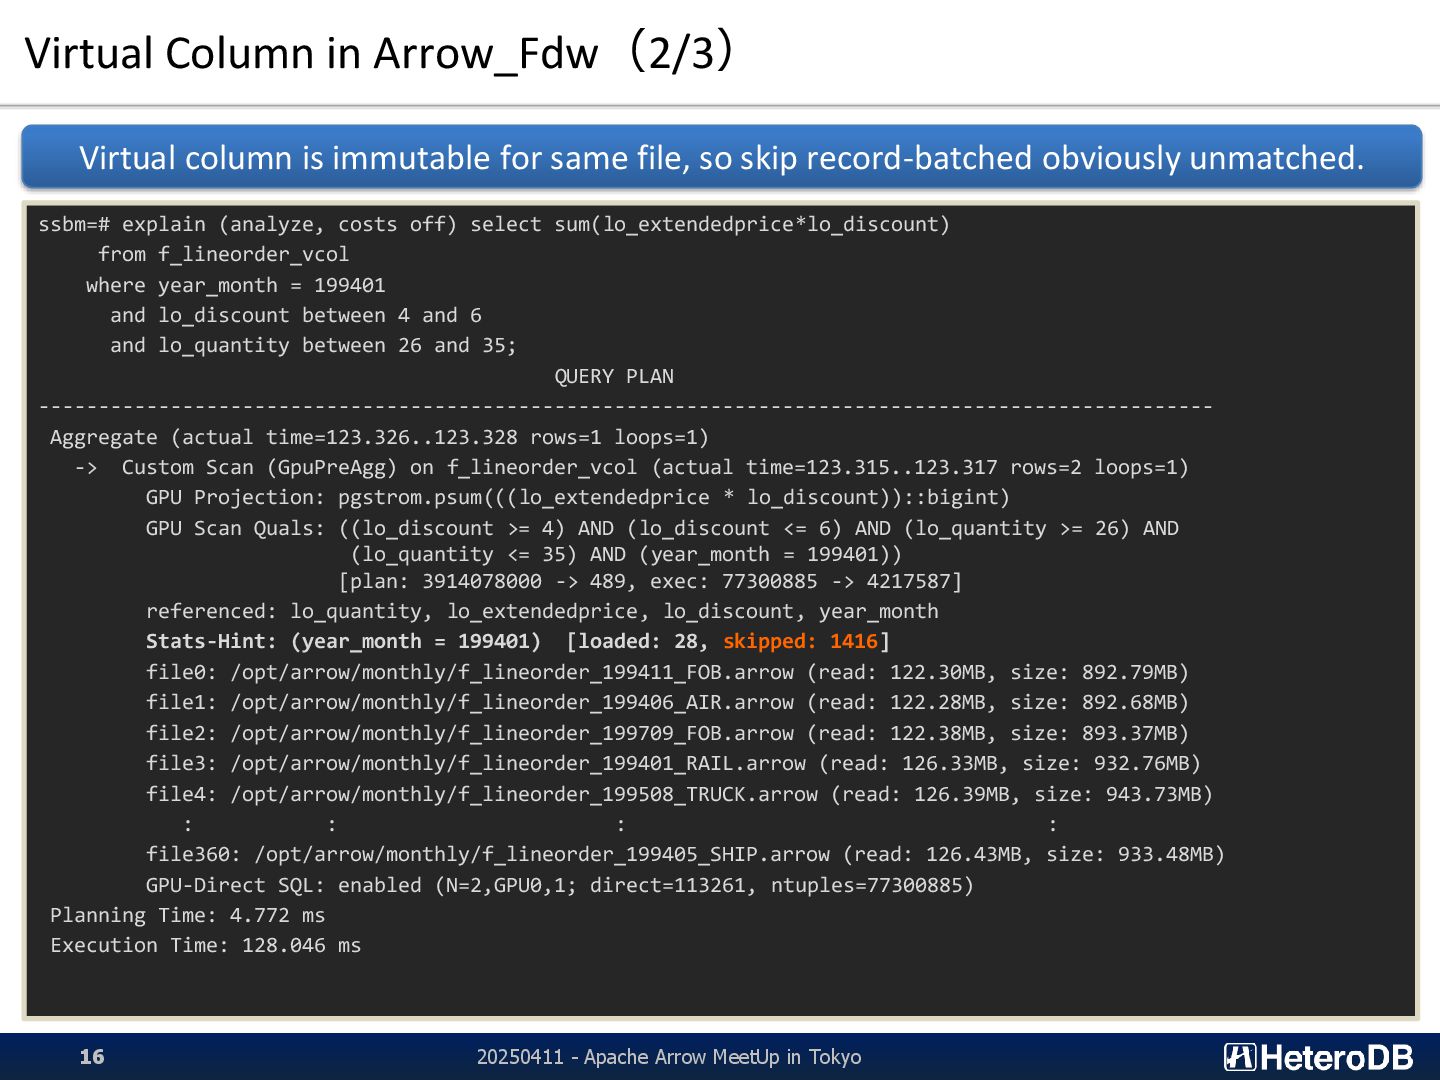
Virtual Column in Arrow_Fdw(2/3) ssbm=# explain (analyze, costs off) select
sum(lo_extendedprice*lo_discount) from f_lineorder_vcol where year_month = 199401 and lo_discount between 4 and 6 and lo_quantity between 26 and 35; QUERY PLAN -------------------------------------------------------------------------------------------------- Aggregate (actual time=123.326..123.328 rows=1 loops=1) -> Custom Scan (GpuPreAgg) on f_lineorder_vcol (actual time=123.315..123.317 rows=2 loops=1) GPU Projection: pgstrom.psum(((lo_extendedprice * lo_discount))::bigint) GPU Scan Quals: ((lo_discount >= 4) AND (lo_discount <= 6) AND (lo_quantity >= 26) AND (lo_quantity <= 35) AND (year_month = 199401)) [plan: 3914078000 -> 489, exec: 77300885 -> 4217587] referenced: lo_quantity, lo_extendedprice, lo_discount, year_month Stats-Hint: (year_month = 199401) [loaded: 28, skipped: 1416] file0: /opt/arrow/monthly/f_lineorder_199411_FOB.arrow (read: 122.30MB, size: 892.79MB) file1: /opt/arrow/monthly/f_lineorder_199406_AIR.arrow (read: 122.28MB, size: 892.68MB) file2: /opt/arrow/monthly/f_lineorder_199709_FOB.arrow (read: 122.38MB, size: 893.37MB) file3: /opt/arrow/monthly/f_lineorder_199401_RAIL.arrow (read: 126.33MB, size: 932.76MB) file4: /opt/arrow/monthly/f_lineorder_199508_TRUCK.arrow (read: 126.39MB, size: 943.73MB) : : : : file360: /opt/arrow/monthly/f_lineorder_199405_SHIP.arrow (read: 126.43MB, size: 933.48MB) GPU-Direct SQL: enabled (N=2,GPU0,1; direct=113261, ntuples=77300885) Planning Time: 4.772 ms Execution Time: 128.046 ms Virtual column is immutable for same file, so skip record-batched obviously unmatched. 20250411 - Apache Arrow MeetUp in Tokyo 16 -
Virtual Column in Arrow_Fdw(3/3) 20250411 - Apache Arrow MeetUp in
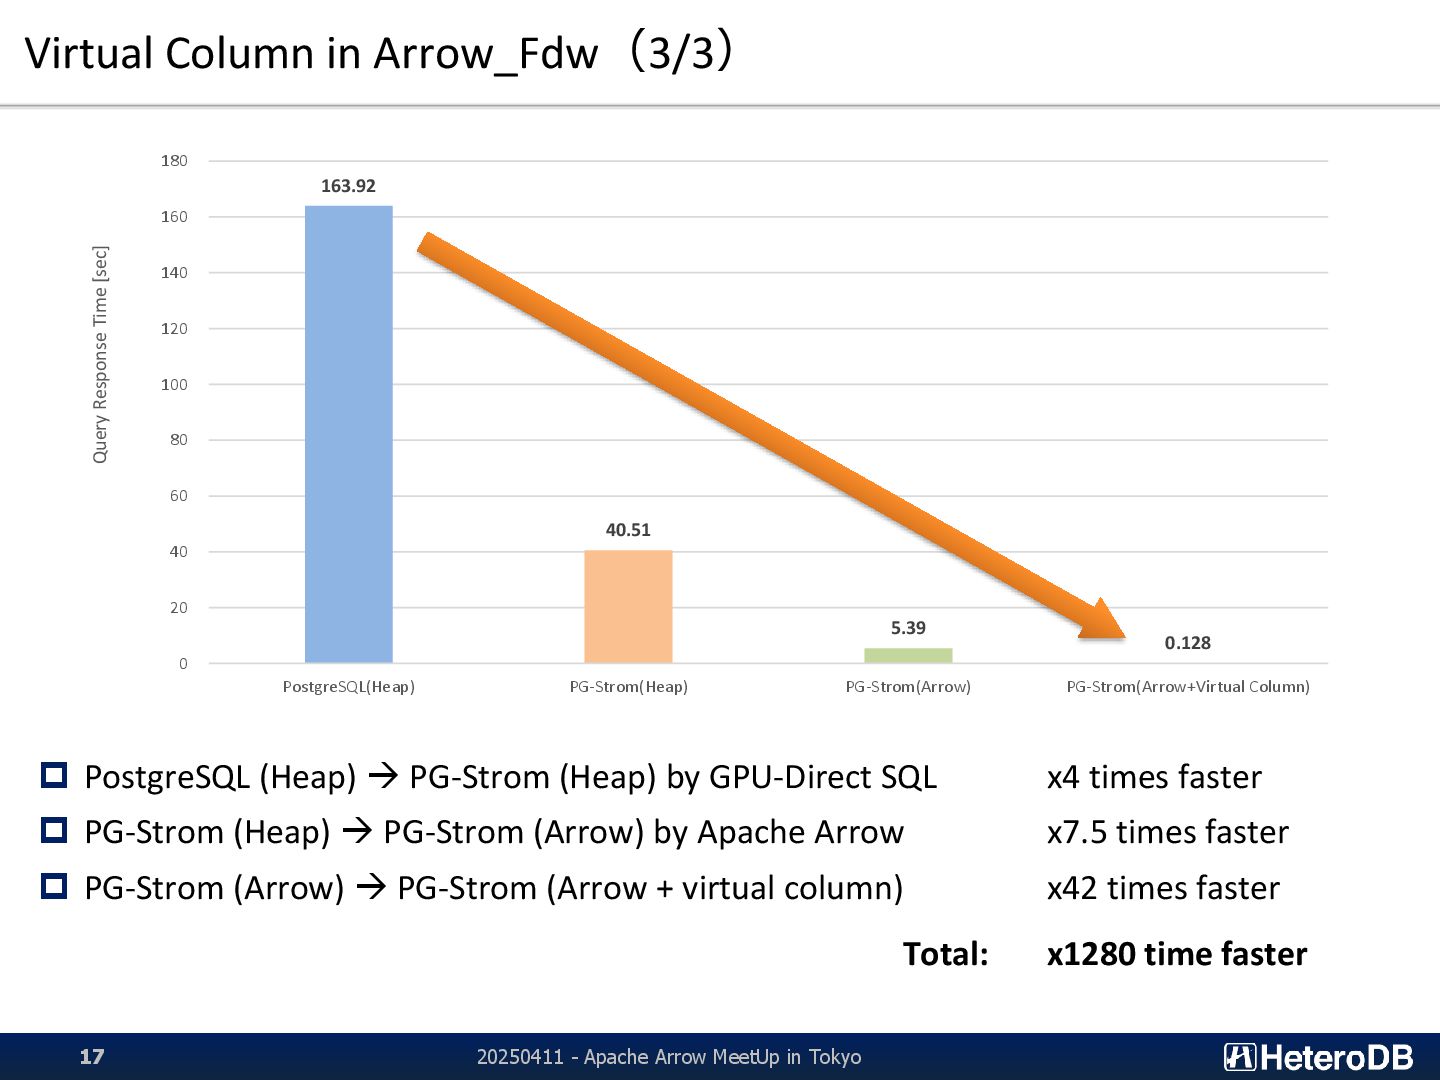
Tokyo 17 PostgreSQL (Heap) → PG-Strom (Heap) by GPU-Direct SQL x4 times faster PG-Strom (Heap) → PG-Strom (Arrow) by Apache Arrow x7.5 times faster PG-Strom (Arrow) → PG-Strom (Arrow + virtual column) x42 times faster Total: x1280 time faster 163.92 40.51 5.39 0.128 0 20 40 60 80 100 120 140 160 180 PostgreSQL(Heap) PG-Strom(Heap) PG-Strom(Arrow) PG-Strom(Arrow+Virtual Column) Query Response Time [sec] -
Apache Arrow converter tools in PG-Strom 20250411 - Apache Arrow
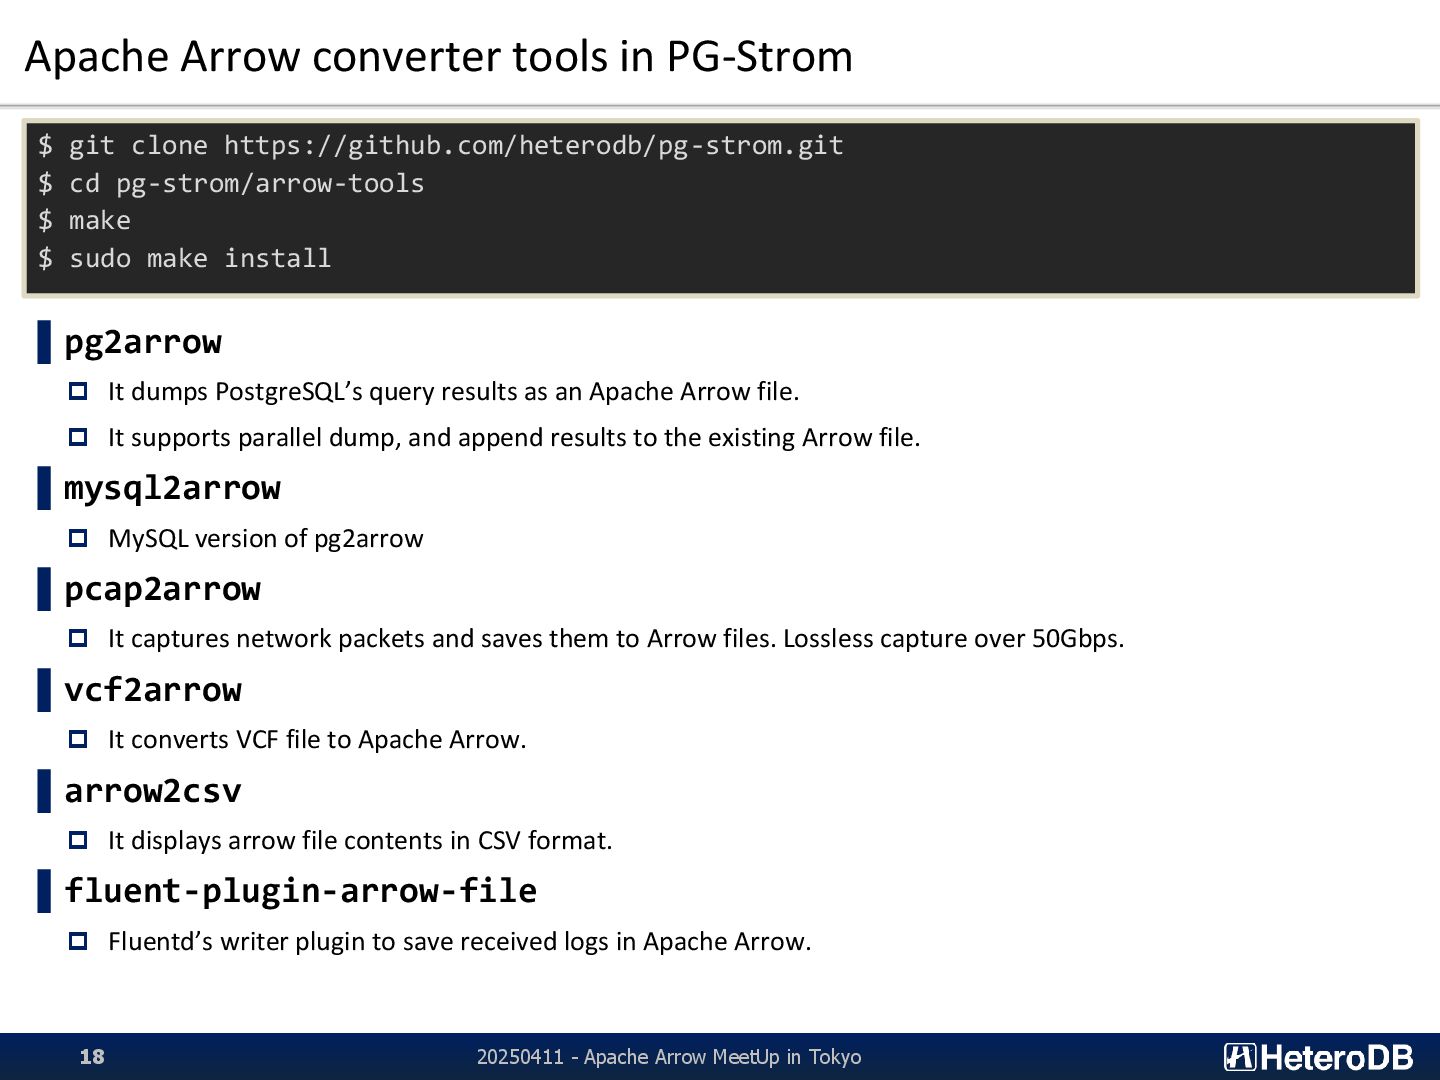
MeetUp in Tokyo 18 ▌pg2arrow It dumps PostgreSQL’s query results as an Apache Arrow file. It supports parallel dump, and append results to the existing Arrow file. ▌mysql2arrow MySQL version of pg2arrow ▌pcap2arrow It captures network packets and saves them to Arrow files. Lossless capture over 50Gbps. ▌vcf2arrow It converts VCF file to Apache Arrow. ▌arrow2csv It displays arrow file contents in CSV format. ▌fluent-plugin-arrow-file Fluentd’s writer plugin to save received logs in Apache Arrow. $ git clone https://github.com/heterodb/pg-strom.git $ cd pg-strom/arrow-tools $ make $ sudo make install -
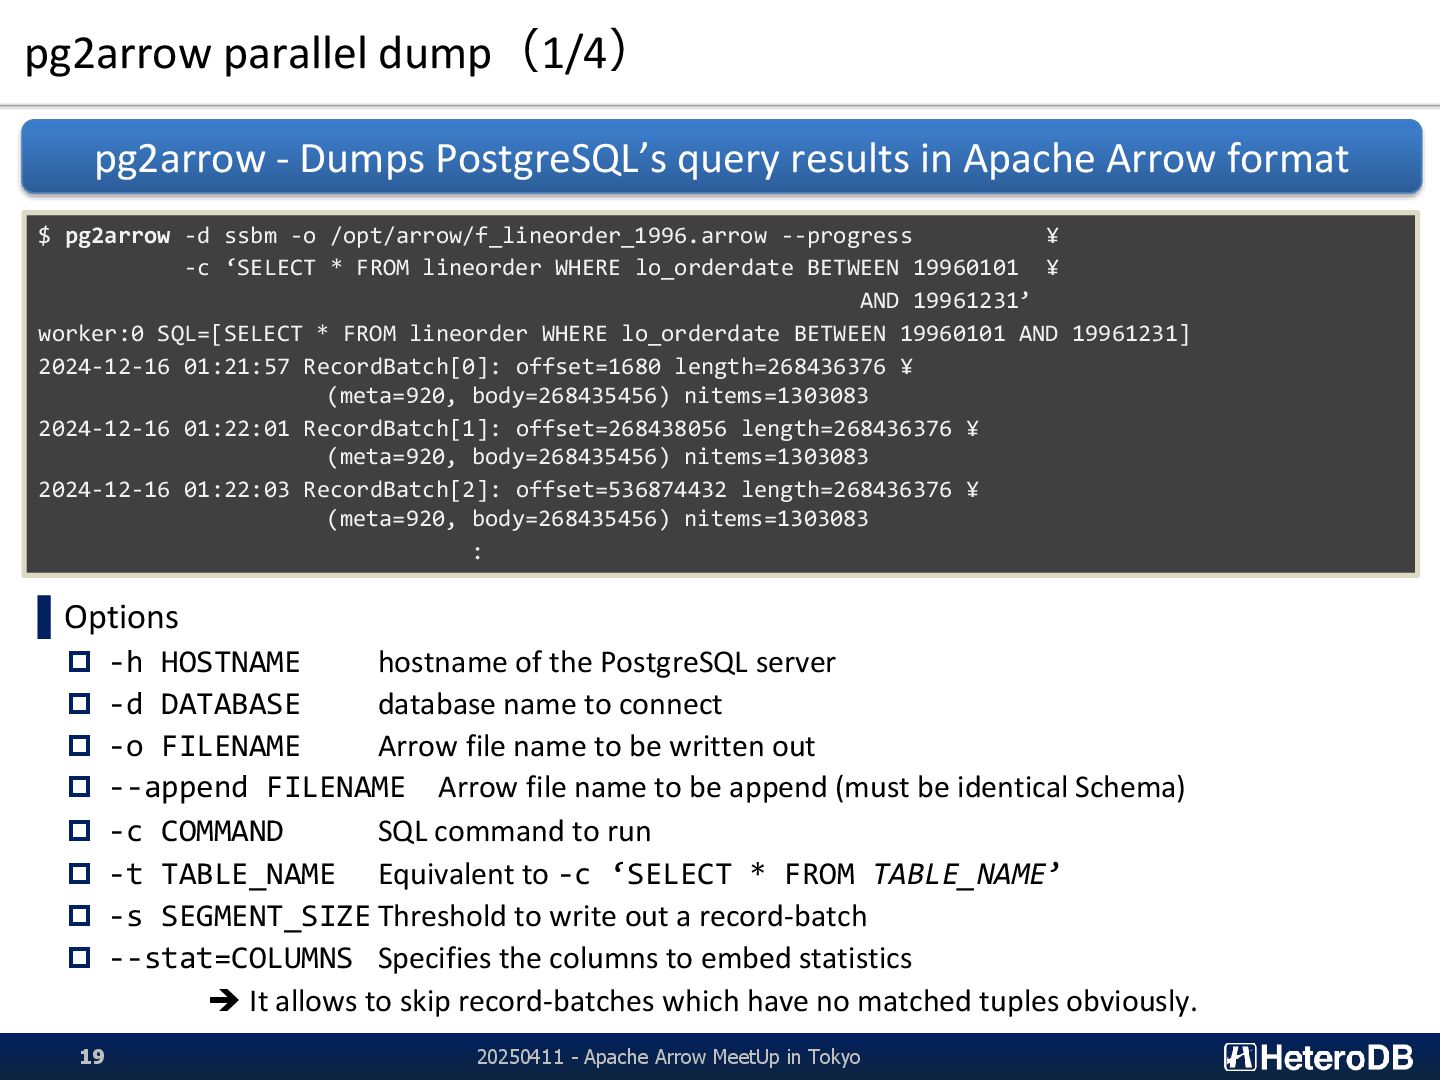
pg2arrow parallel dump(1/4) ▌Options -h HOSTNAME hostname of the
PostgreSQL server -d DATABASE database name to connect -o FILENAME Arrow file name to be written out --append FILENAME Arrow file name to be append (must be identical Schema) -c COMMAND SQL command to run -t TABLE_NAME Equivalent to -c ‘SELECT * FROM TABLE_NAME’ -s SEGMENT_SIZE Threshold to write out a record-batch --stat=COLUMNS Specifies the columns to embed statistics ➔ It allows to skip record-batches which have no matched tuples obviously. pg2arrow - Dumps PostgreSQL’s query results in Apache Arrow format $ pg2arrow -d ssbm -o /opt/arrow/f_lineorder_1996.arrow --progress ¥ -c ‘SELECT * FROM lineorder WHERE lo_orderdate BETWEEN 19960101 ¥ AND 19961231’ worker:0 SQL=[SELECT * FROM lineorder WHERE lo_orderdate BETWEEN 19960101 AND 19961231] 2024-12-16 01:21:57 RecordBatch[0]: offset=1680 length=268436376 ¥ (meta=920, body=268435456) nitems=1303083 2024-12-16 01:22:01 RecordBatch[1]: offset=268438056 length=268436376 ¥ (meta=920, body=268435456) nitems=1303083 2024-12-16 01:22:03 RecordBatch[2]: offset=536874432 length=268436376 ¥ (meta=920, body=268435456) nitems=1303083 : 20250411 - Apache Arrow MeetUp in Tokyo 19 -
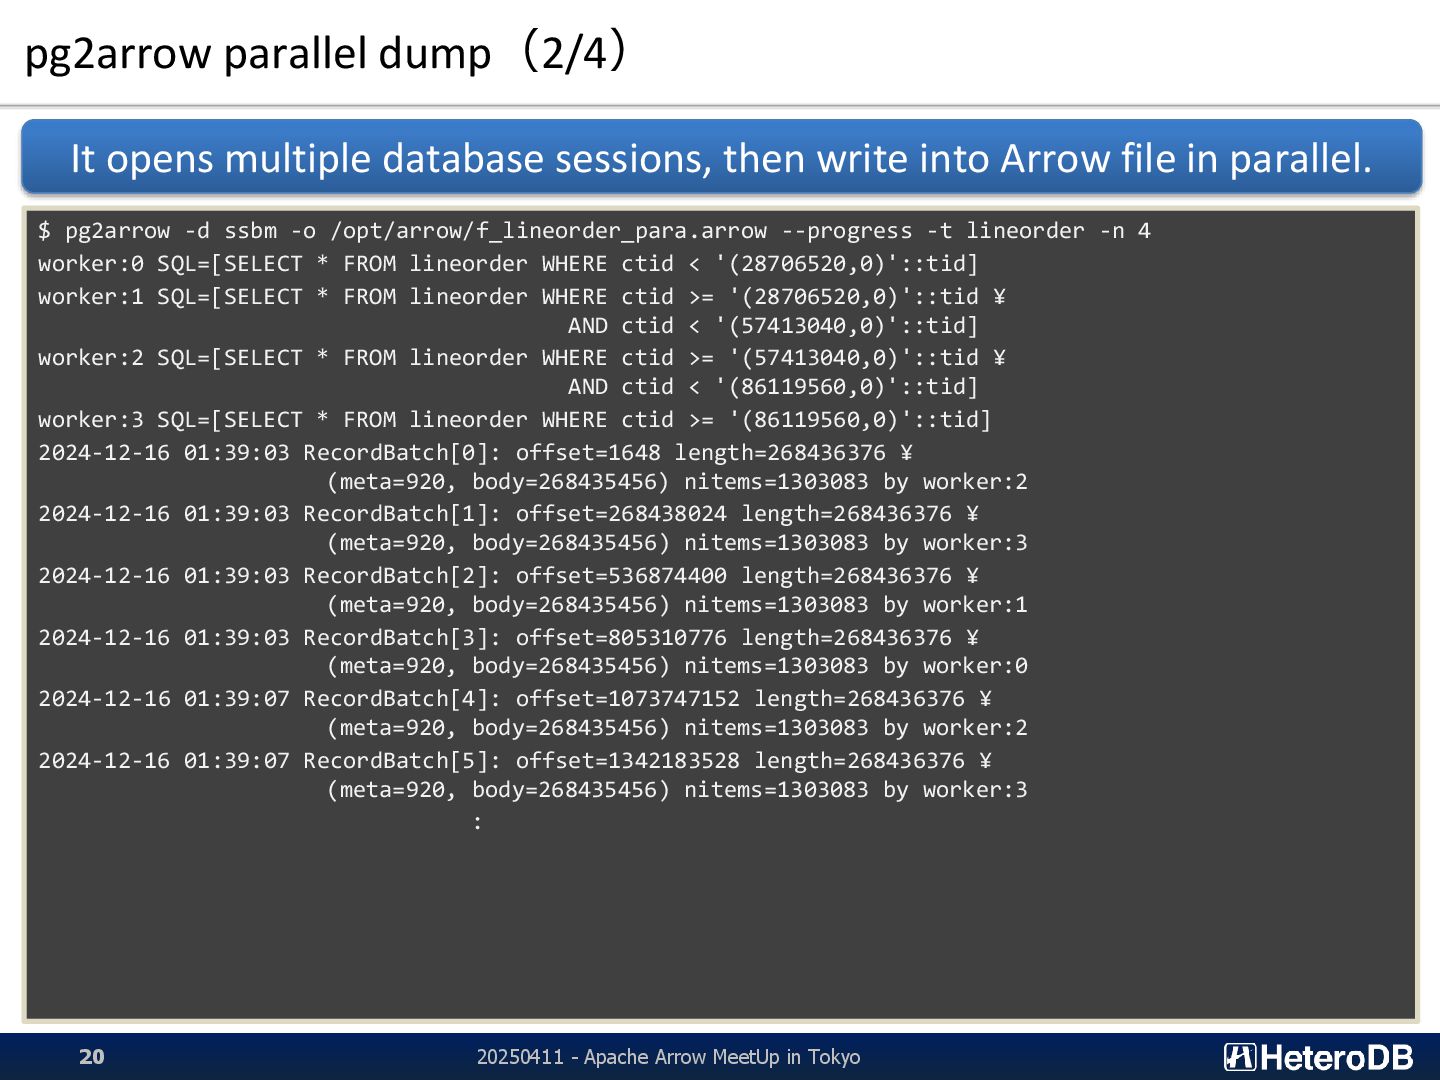
pg2arrow parallel dump(2/4) It opens multiple database sessions, then write
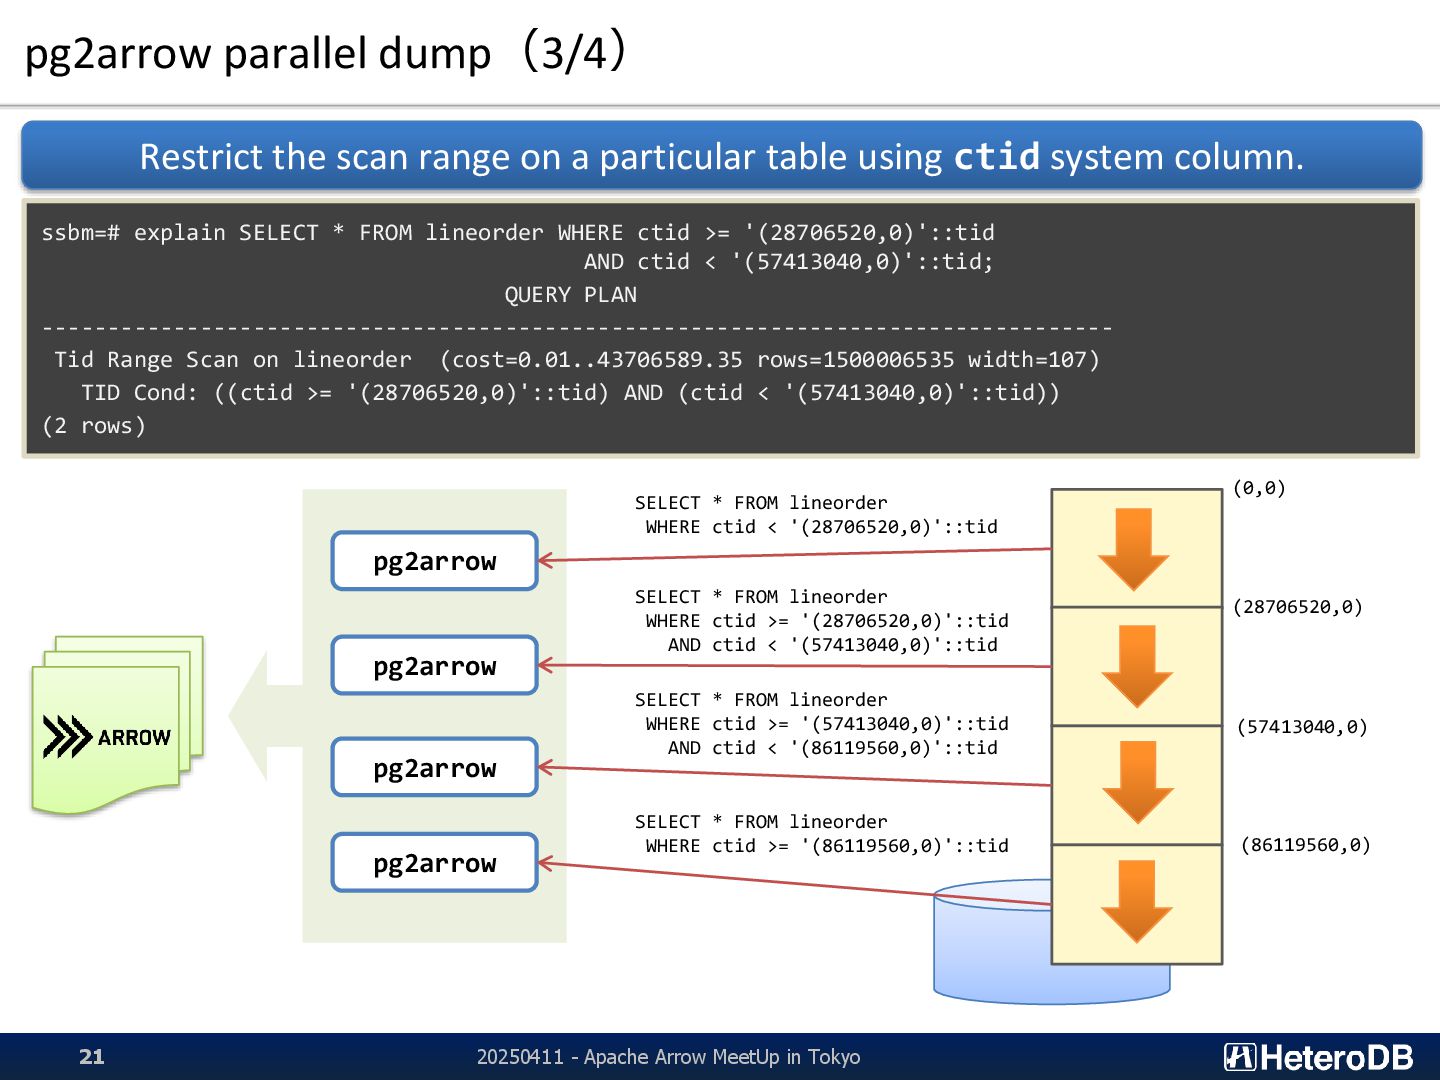
into Arrow file in parallel. $ pg2arrow -d ssbm -o /opt/arrow/f_lineorder_para.arrow --progress -t lineorder -n 4 worker:0 SQL=[SELECT * FROM lineorder WHERE ctid < '(28706520,0)'::tid] worker:1 SQL=[SELECT * FROM lineorder WHERE ctid >= '(28706520,0)'::tid ¥ AND ctid < '(57413040,0)'::tid] worker:2 SQL=[SELECT * FROM lineorder WHERE ctid >= '(57413040,0)'::tid ¥ AND ctid < '(86119560,0)'::tid] worker:3 SQL=[SELECT * FROM lineorder WHERE ctid >= '(86119560,0)'::tid] 2024-12-16 01:39:03 RecordBatch[0]: offset=1648 length=268436376 ¥ (meta=920, body=268435456) nitems=1303083 by worker:2 2024-12-16 01:39:03 RecordBatch[1]: offset=268438024 length=268436376 ¥ (meta=920, body=268435456) nitems=1303083 by worker:3 2024-12-16 01:39:03 RecordBatch[2]: offset=536874400 length=268436376 ¥ (meta=920, body=268435456) nitems=1303083 by worker:1 2024-12-16 01:39:03 RecordBatch[3]: offset=805310776 length=268436376 ¥ (meta=920, body=268435456) nitems=1303083 by worker:0 2024-12-16 01:39:07 RecordBatch[4]: offset=1073747152 length=268436376 ¥ (meta=920, body=268435456) nitems=1303083 by worker:2 2024-12-16 01:39:07 RecordBatch[5]: offset=1342183528 length=268436376 ¥ (meta=920, body=268435456) nitems=1303083 by worker:3 : 20250411 - Apache Arrow MeetUp in Tokyo 20 -
pg2arrow parallel dump(3/4) Restrict the scan range on a particular
table using ctid system column. ssbm=# explain SELECT * FROM lineorder WHERE ctid >= '(28706520,0)'::tid AND ctid < '(57413040,0)'::tid; QUERY PLAN --------------------------------------------------------------------------------- Tid Range Scan on lineorder (cost=0.01..43706589.35 rows=1500006535 width=107) TID Cond: ((ctid >= '(28706520,0)'::tid) AND (ctid < '(57413040,0)'::tid)) (2 rows) pg2arrow pg2arrow pg2arrow pg2arrow SELECT * FROM lineorder WHERE ctid < '(28706520,0)'::tid SELECT * FROM lineorder WHERE ctid >= '(28706520,0)'::tid AND ctid < '(57413040,0)'::tid SELECT * FROM lineorder WHERE ctid >= '(57413040,0)'::tid AND ctid < '(86119560,0)'::tid SELECT * FROM lineorder WHERE ctid >= '(86119560,0)'::tid (28706520,0) (0,0) (57413040,0) (86119560,0) 20250411 - Apache Arrow MeetUp in Tokyo 21 -
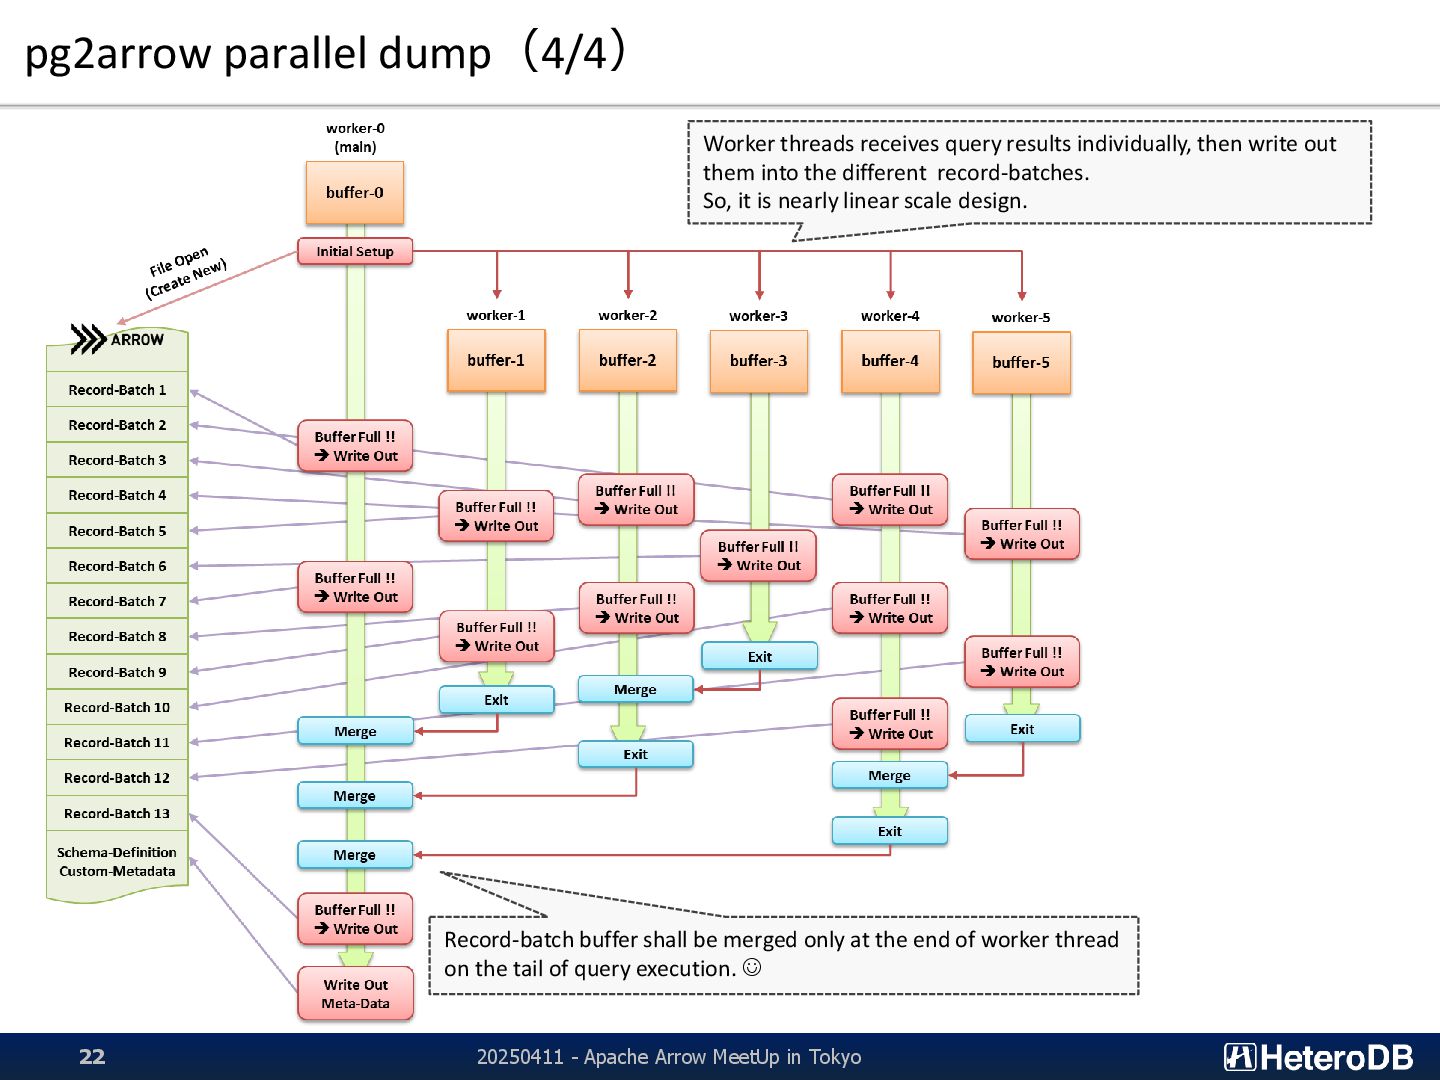
pg2arrow parallel dump(4/4) 20250411 - Apache Arrow MeetUp in Tokyo
22 Worker threads receives query results individually, then write out them into the different record-batches. So, it is nearly linear scale design. Record-batch buffer shall be merged only at the end of worker thread on the tail of query execution. ☺
 kaigai
 imuta
 kmiya84377
 bitkey
 puku0x
 munakata
 ykimi
 masasuzu
 yusuke427
 silmin_
 inesmontani
 takuyay0ne
 staka121
 mongodb
 orderedlist
 addyosmani
 baasie
 tonyrice
 mclloyd
 mkilby
 tenderlove
 katiecoart
 raygrieselhuber
 quramy