Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
[Journal club] Toeplitz Neural Network for Sequ...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Semantic Machine Intelligence Lab., Keio Univ.
PRO
December 21, 2023
Technology
1.2k
2
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
[Journal club] Toeplitz Neural Network for Sequence Modeling
慶應義塾⼤学 杉浦孔明研究室 M1 和田唯我 / Yuiga Wada
Semantic Machine Intelligence Lab., Keio Univ.
PRO
December 21, 2023
More Decks by Semantic Machine Intelligence Lab., Keio Univ.
See All by Semantic Machine Intelligence Lab., Keio Univ.
[RSJ26] Building a VLA Model Based on Self-Distilled Classification
keio_smilab
PRO
0
210
[RSJ26] AnoleVLA: Lightweight Vision-Language-Action Model with Deep State Space Models for Mobile Manipulation
keio_smilab
PRO
0
170
[RSJ26] NarrativeFlow: Flow-Based Vision-Language-Action Model Using Robot Velocity Fields
keio_smilab
PRO
0
240
[RSJ26] Flow as Flow: Modeling Robot Velocity Fields as Probability Velocity Fields
keio_smilab
PRO
1
240
[RSJ26] Hierarchy-Aware Multimodal Retrieval-Augmented Generation for Embodied Question Answering
keio_smilab
PRO
1
200
[MIRU26] Open-Vocabulary Intention-Guided Object Detection in Diverse Scenes
keio_smilab
PRO
0
230
[Journal club] Evo-1: Lightweight Vision-Language-Action Model with Preserved Semantic Alignment
keio_smilab
PRO
0
72
[MIRU26] To What Extent Does MLLM-as-a-Judge Exhibit Cross-Model Preference Bias?
keio_smilab
PRO
0
320
[Journal club] FlashVID: Efficient Video Large Language Models via Training-free Tree-based Spatiotemporal Token Merging
keio_smilab
PRO
0
52
Other Decks in Technology
See All in Technology
AIがコードを書く時代に、エンジニアは何で自分の価値を証明するのか / In an era where AI writes code how do engineers prove their value
carta_engineering
1
680
カンファレンスに参加した後の浮遊感とセルフケア
pauli
0
320
AgentCoreで実践するハーネスエンジニアリング
yakumo
1
290
Execution in the Kingdom of Agents: Reflections on Abstraction and Complexity
bcantrill
0
890
AI 時代の Azure エンジニアリング ~ 私たちは何を磨き、何を任せるのか ~
chack411
1
550
OpenSharing について熱く語る 〜AI アセットの共有について〜
kameitomohiro
0
240
契約書画像からの情報抽出に特化した視覚接地モデルを育てる話
sansantech
PRO
1
160
AI駆動開発、viviONの1年 ── うまくいったこと・いかなかったこと
vivion
0
280
Incremental HTTP
kazuho
5
2.1k
子育てエンジニアの可処分時間が減っても成長を諦めない戦い方
sudoakiy
5
4.3k
3つのアプローチで目指す チームを強くするAI駆動開発
thkt
0
140
SDDの運用にめげずに向き合った話
sansantech
PRO
1
140
Featured
See All Featured
Navigating Weather and Climate Data
rabernat
0
550
Effective software design: The role of men in debugging patriarchy in IT @ Voxxed Days AMS
baasie
1
550
Digital Ethics as a Driver of Design Innovation
axbom
PRO
1
450
Responsive Adventures: Dirty Tricks From The Dark Corners of Front-End
smashingmag
254
22k
ピンチをチャンスに:未来をつくるプロダクトロードマップ #pmconf2020
aki_iinuma
128
56k
The AI Revolution Will Not Be Monopolized: How open-source beats economies of scale, even for LLMs
inesmontani
PRO
3
3.8k
Information Architects: The Missing Link in Design Systems
soysaucechin
1
1.2k
Design in an AI World
tapps
1
350
Mobile First: as difficult as doing things right
swwweet
225
10k
XXLCSS - How to scale CSS and keep your sanity
sugarenia
250
1.3M
Amusing Abliteration
ianozsvald
1
330
Exploring anti-patterns in Rails
aemeredith
4
530
Transcript
Toeplitz Neural Network for Sequence Modeling Zhen Qin2, Xiaodong Han2,
Weixuan Sun3, Bowen He2, Dong Li1, Dongxu Li3, Yuchao Dai4, Lingpeng Kong5, Yiran Zhong1 (1Shanghai AI Laboratory, 2SenseTime Research, 3Australian National University, 4Northwestern Polytechnical University, 5The University of Hong Kong) 慶應義塾⼤学 杉浦孔明研究室 M1 和⽥唯我 Zhen Qin et al., “Toeplitz Neural Network for Sequence Modeling” in ICLR (2023) ICLR23 notable top 25%
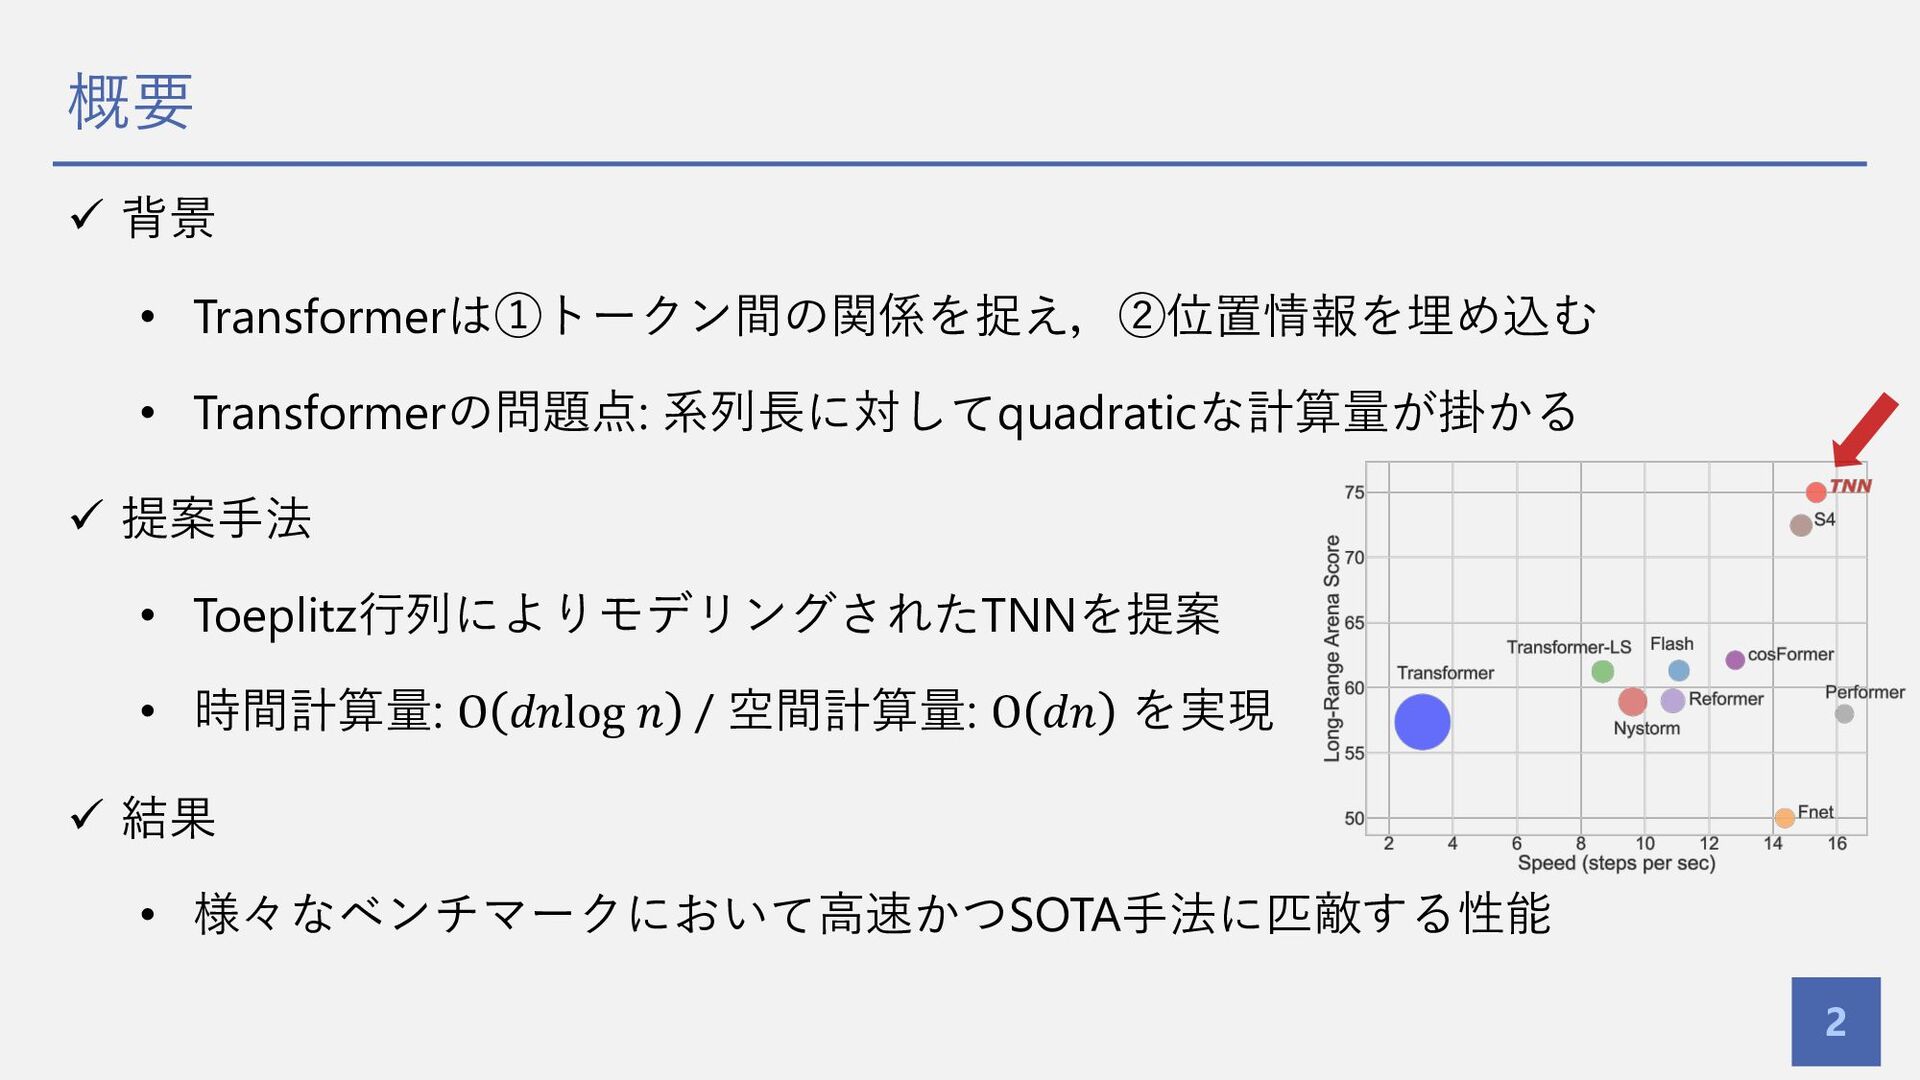
概要 2 ü 背景 • Transformerは①トークン間の関係を捉え,②位置情報を埋め込む • Transformerの問題点: 系列⻑に対してquadraticな計算量が掛かる ü
提案⼿法 • Toeplitz⾏列によりモデリングされたTNNを提案 • 時間計算量: O 𝑑𝑛log 𝑛 / 空間計算量: O 𝑑𝑛 を実現 ü 結果 • 様々なベンチマークにおいて⾼速かつSOTA⼿法に匹敵する性能
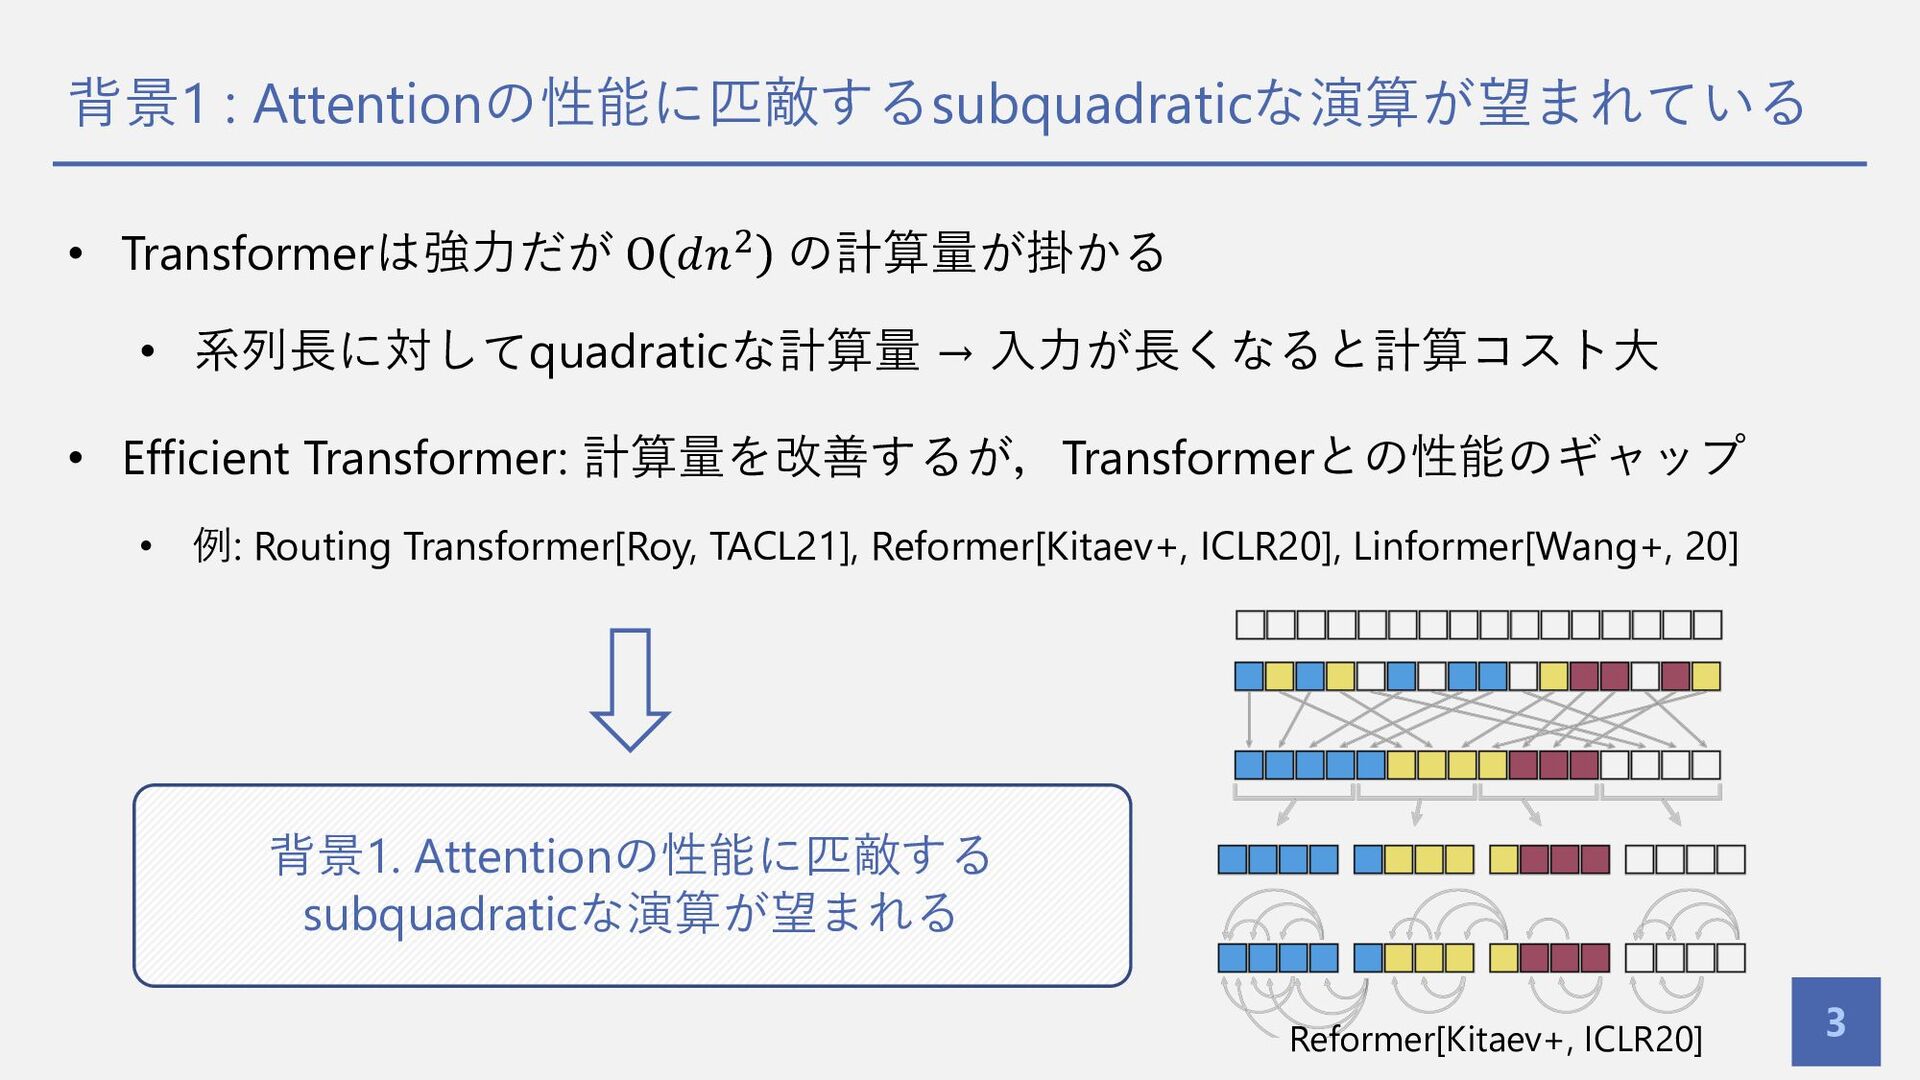
背景1 : Attentionの性能に匹敵するsubquadraticな演算が望まれている 3 • Transformerは強⼒だが O 𝑑𝑛! の計算量が掛かる •
系列⻑に対してquadraticな計算量 → ⼊⼒が⻑くなると計算コスト⼤ • Efficient Transformer: 計算量を改善するが,Transformerとの性能のギャップ • 例: Routing Transformer[Roy, TACL21], Reformer[Kitaev+, ICLR20], Linformer[Wang+, 20] 背景1. Attentionの性能に匹敵する subquadraticな演算が望まれる Reformer[Kitaev+, ICLR20]
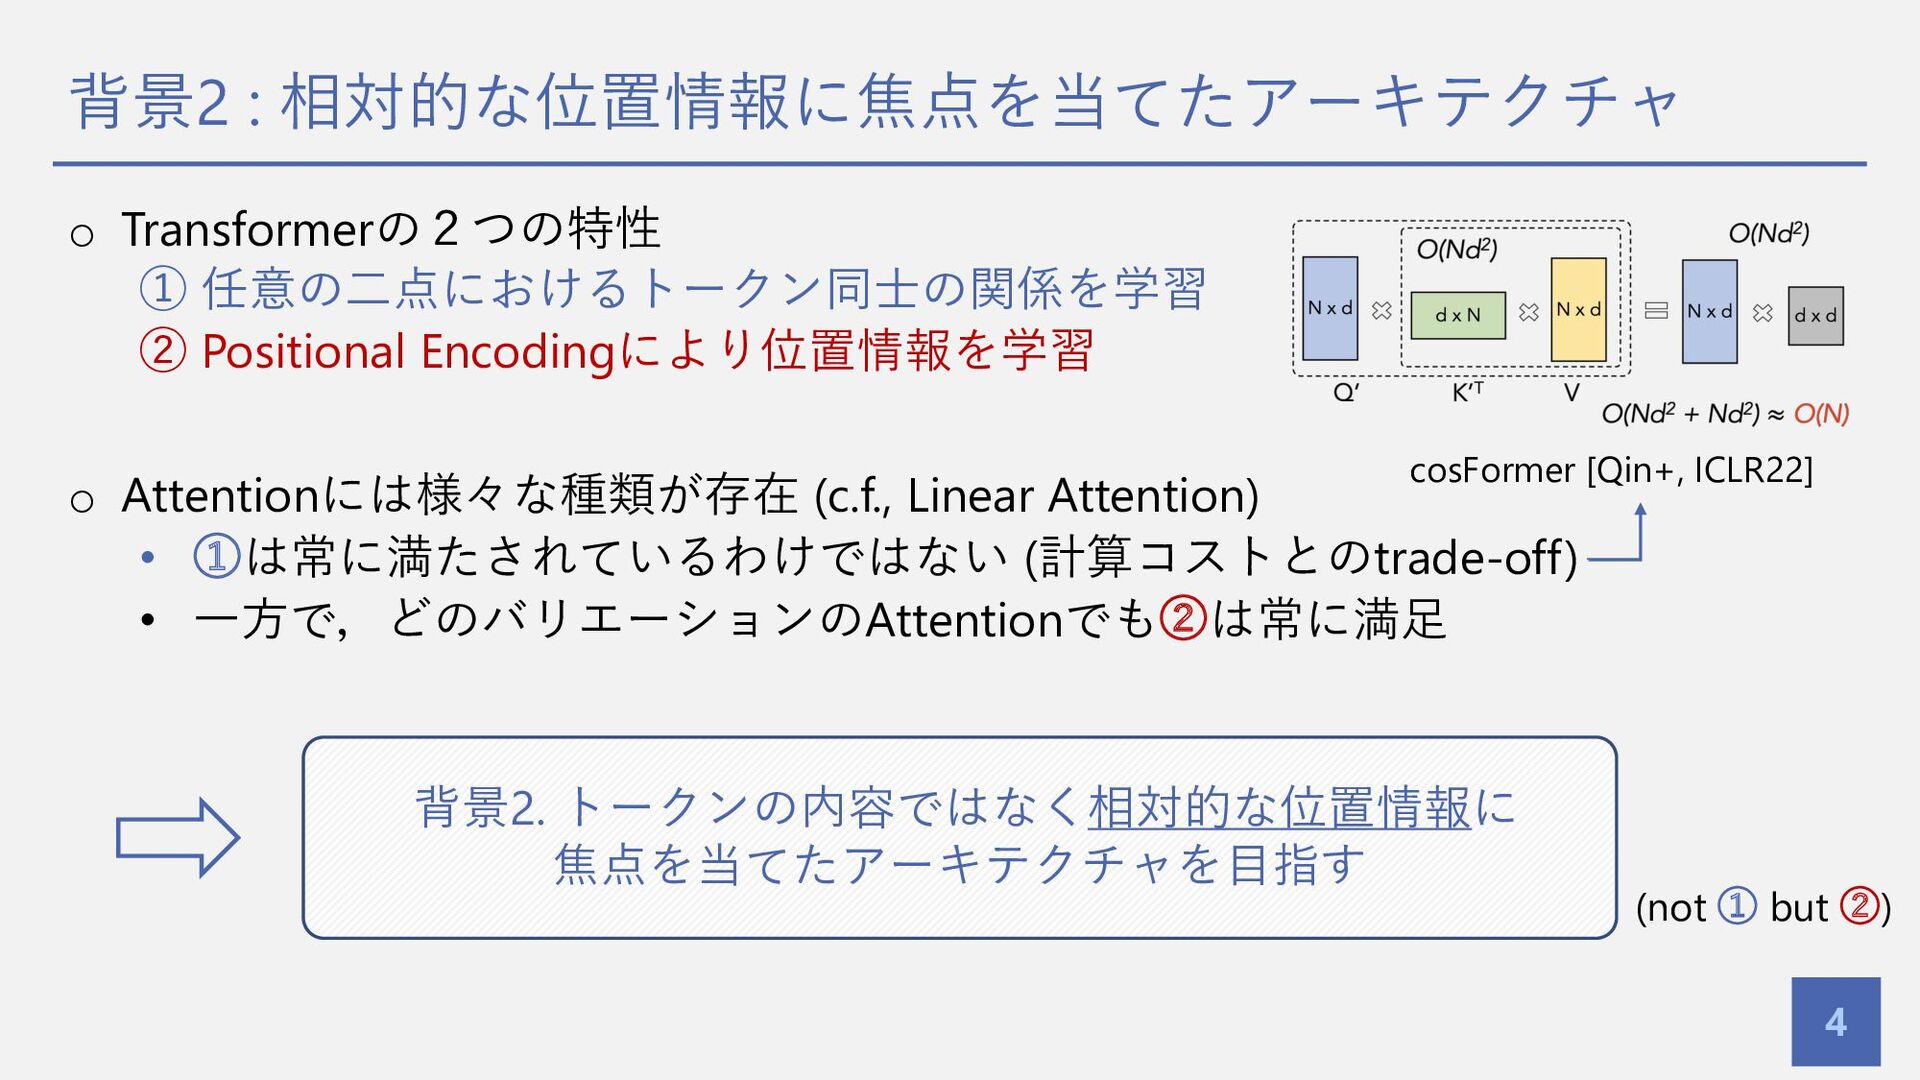
背景2 : 相対的な位置情報に焦点を当てたアーキテクチャ 4 o Transformerの2つの特性 ① 任意の⼆点におけるトークン同⼠の関係を学習 ② Positional
Encodingにより位置情報を学習 o Attentionには様々な種類が存在 (c.f., Linear Attention) • ①は常に満たされているわけではない (計算コストとのtrade-off) • ⼀⽅で,どのバリエーションのAttentionでも②は常に満⾜ 背景2. トークンの内容ではなく相対的な位置情報に 焦点を当てたアーキテクチャを⽬指す (not ① but ②) cosFormer [Qin+, ICLR22]
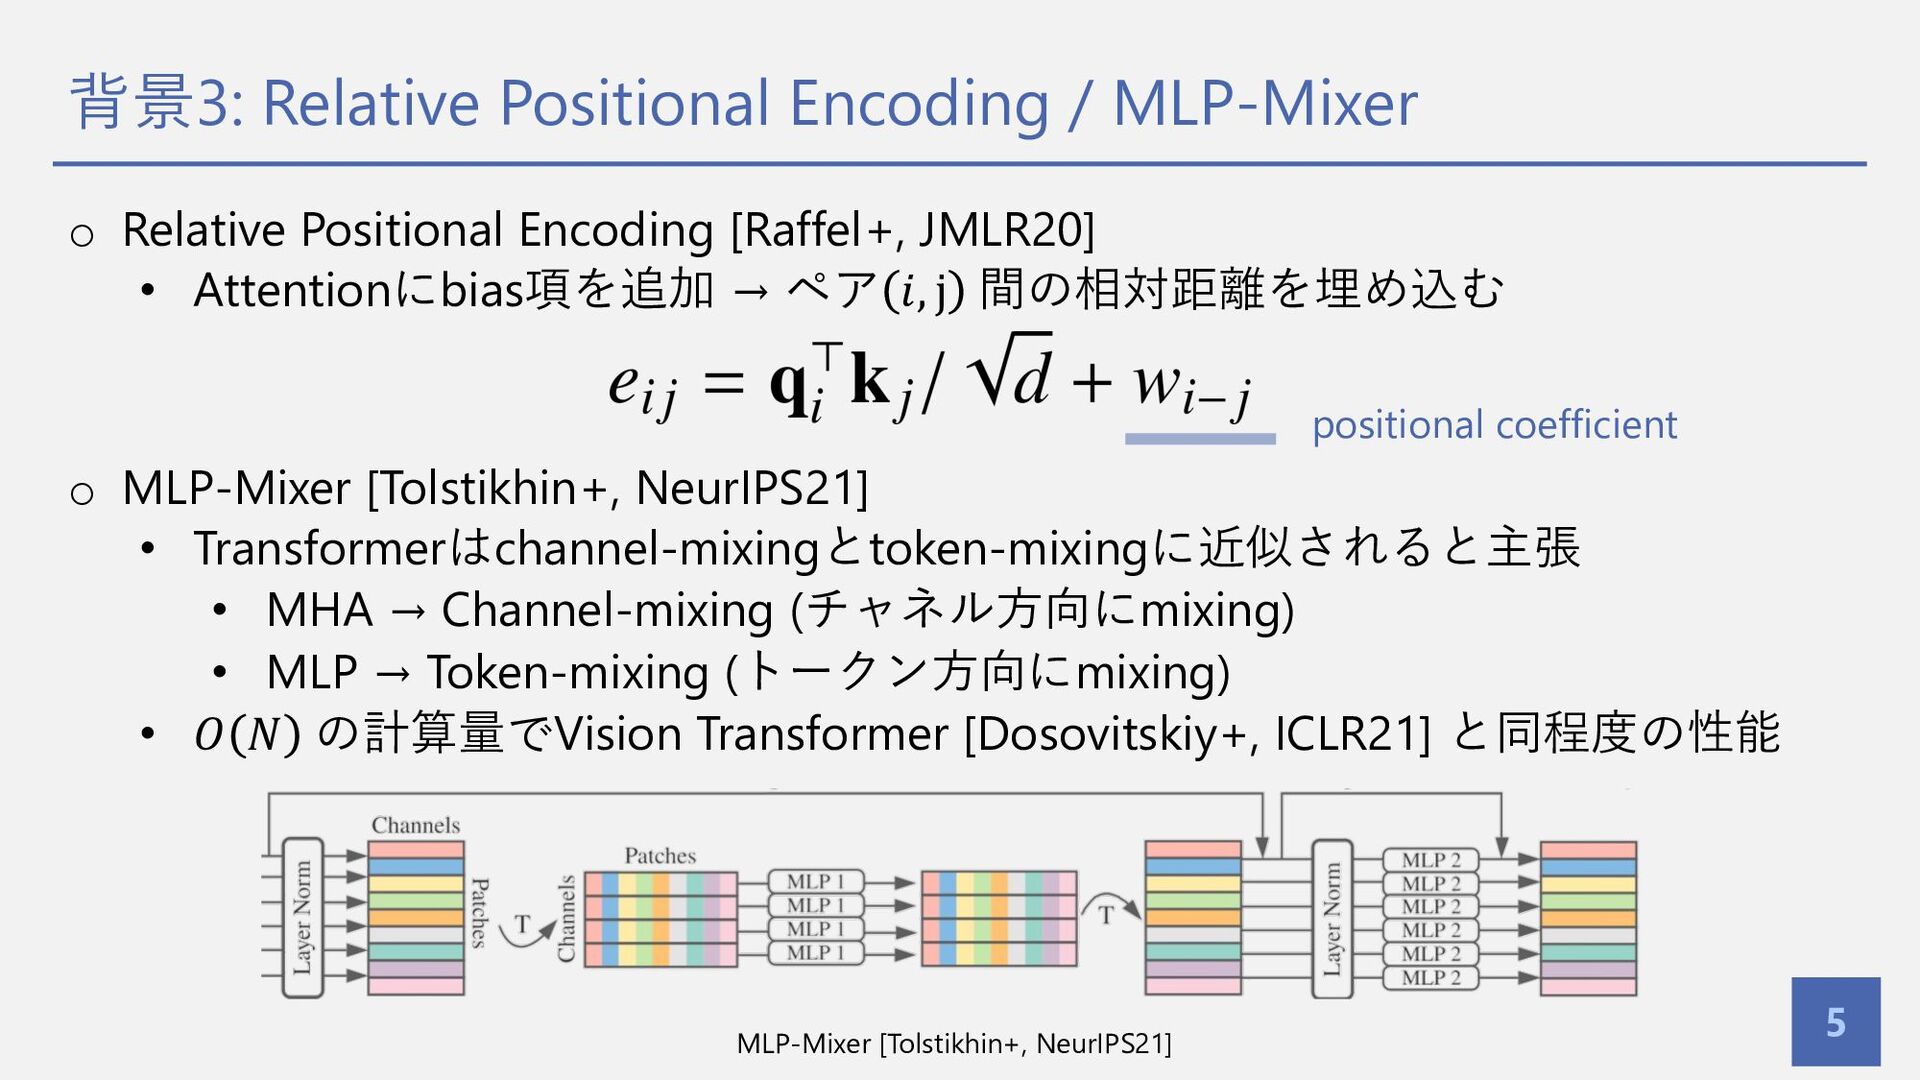
背景3: Relative Positional Encoding / MLP-Mixer 5 o Relative Positional
Encoding [Raffel+, JMLR20] • Attentionにbias項を追加 → ペア 𝑖, j 間の相対距離を埋め込む o MLP-Mixer [Tolstikhin+, NeurIPS21] • Transformerはchannel-mixingとtoken-mixingに近似されると主張 • MHA → Channel-mixing (チャネル⽅向にmixing) • MLP → Token-mixing (トークン⽅向にmixing) • 𝑂 𝑁 の計算量でVision Transformer [Dosovitskiy+, ICLR21] と同程度の性能 positional coefficient MLP-Mixer [Tolstikhin+, NeurIPS21]
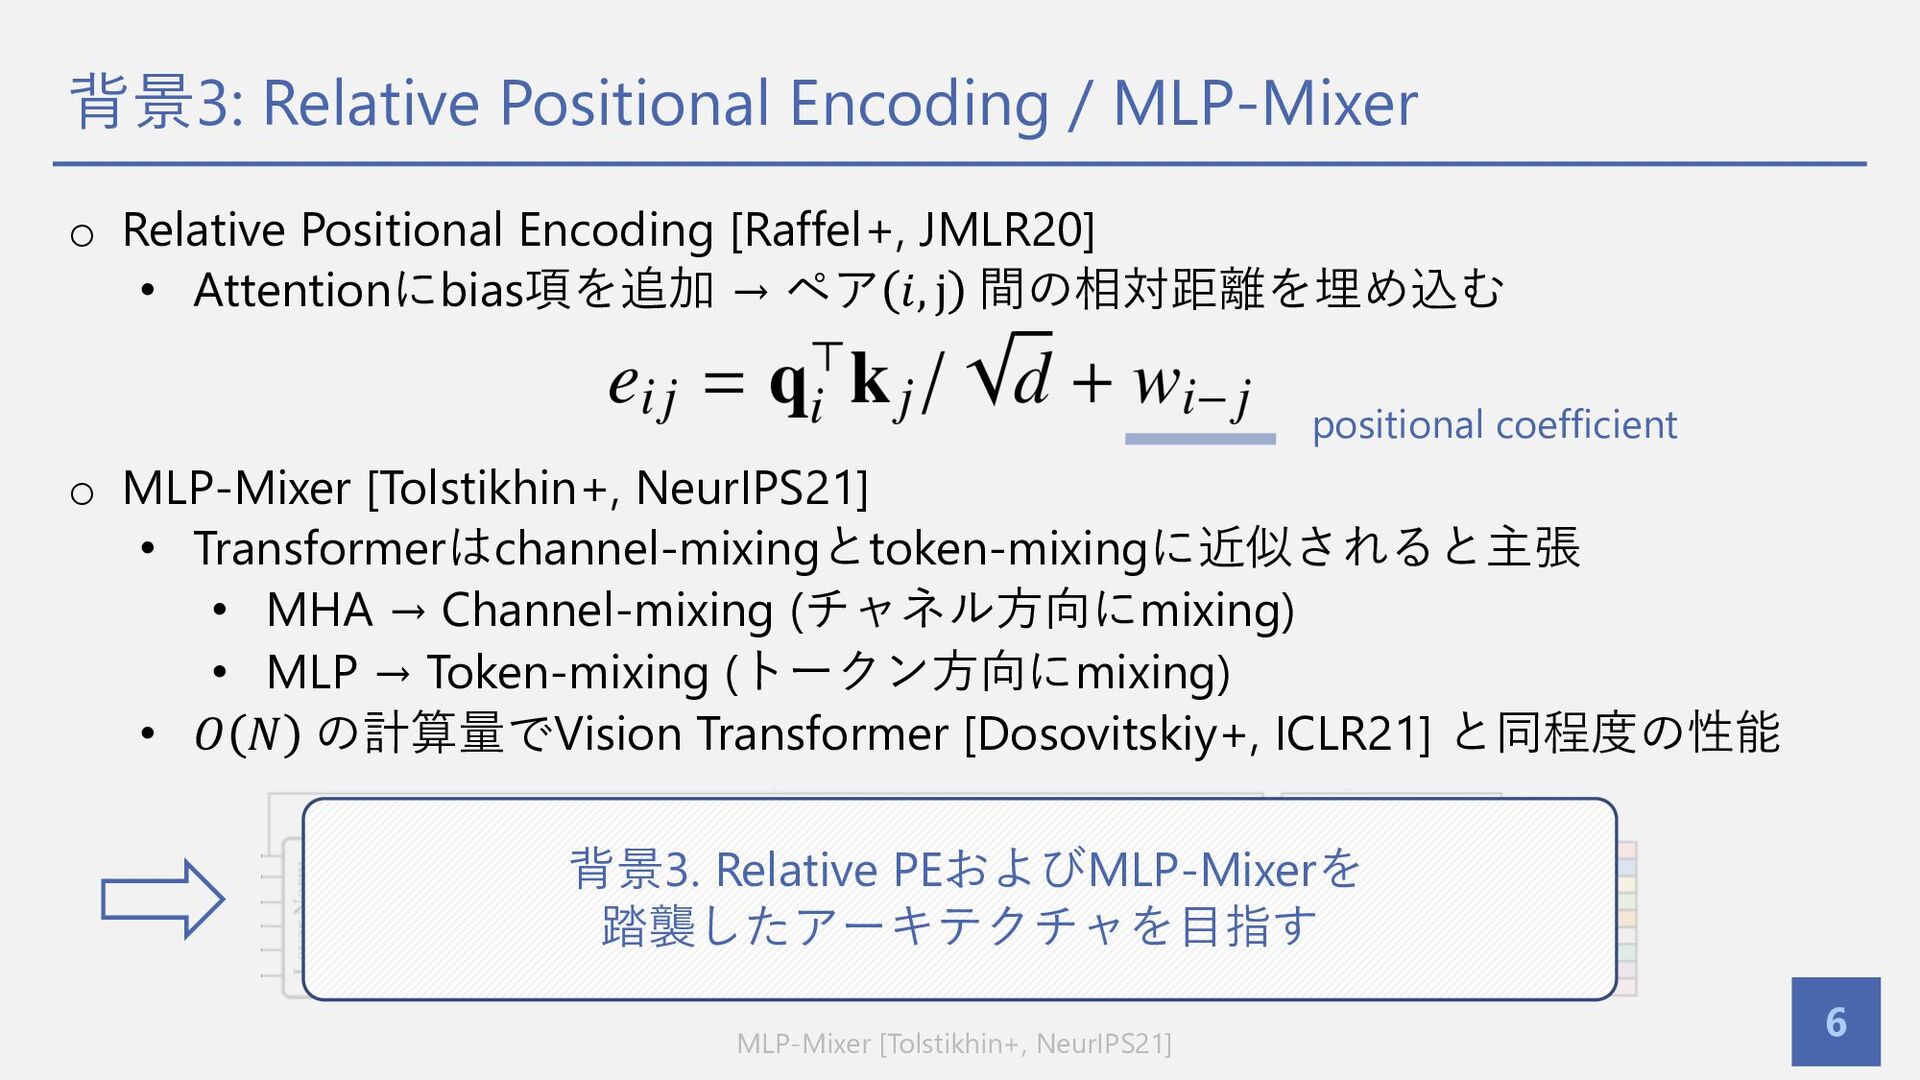
背景3: Relative Positional Encoding / MLP-Mixer 6 o Relative Positional
Encoding [Raffel+, JMLR20] • Attentionにbias項を追加 → ペア 𝑖, j 間の相対距離を埋め込む o MLP-Mixer [Tolstikhin+, NeurIPS21] • Transformerはchannel-mixingとtoken-mixingに近似されると主張 • MHA → Channel-mixing (チャネル⽅向にmixing) • MLP → Token-mixing (トークン⽅向にmixing) • 𝑂 𝑁 の計算量でVision Transformer [Dosovitskiy+, ICLR21] と同程度の性能 positional coefficient MLP-Mixer [Tolstikhin+, NeurIPS21] 背景3. Relative PEおよびMLP-Mixerを 踏襲したアーキテクチャを⽬指す
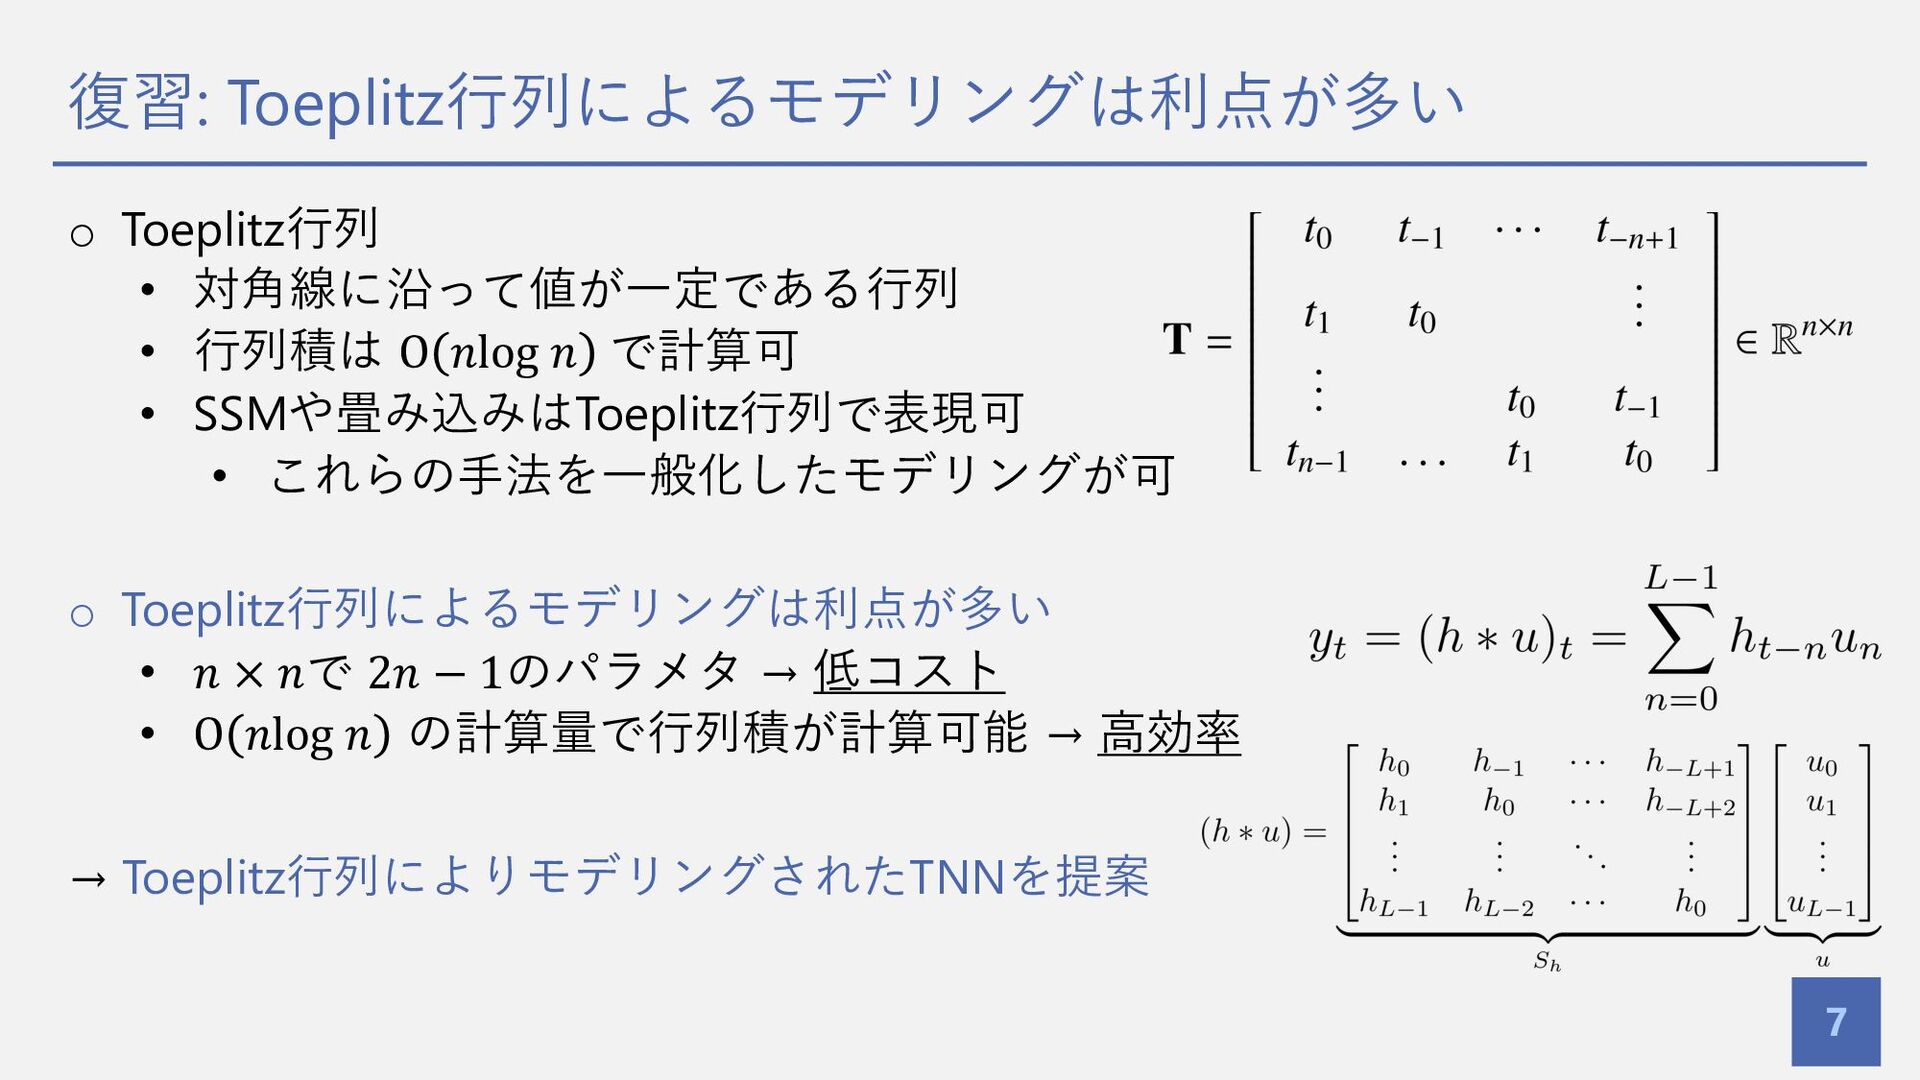
復習: Toeplitz⾏列によるモデリングは利点が多い 7 o Toeplitz⾏列 • 対⾓線に沿って値が⼀定である⾏列 • ⾏列積は O
𝑛log 𝑛 で計算可 • SSMや畳み込みはToeplitz⾏列で表現可 • これらの⼿法を⼀般化したモデリングが可 o Toeplitz⾏列によるモデリングは利点が多い • 𝑛 × 𝑛で 2𝑛 − 1のパラメタ → 低コスト • O 𝑛log 𝑛 の計算量で⾏列積が計算可能 → ⾼効率 → Toeplitz⾏列によりモデリングされたTNNを提案
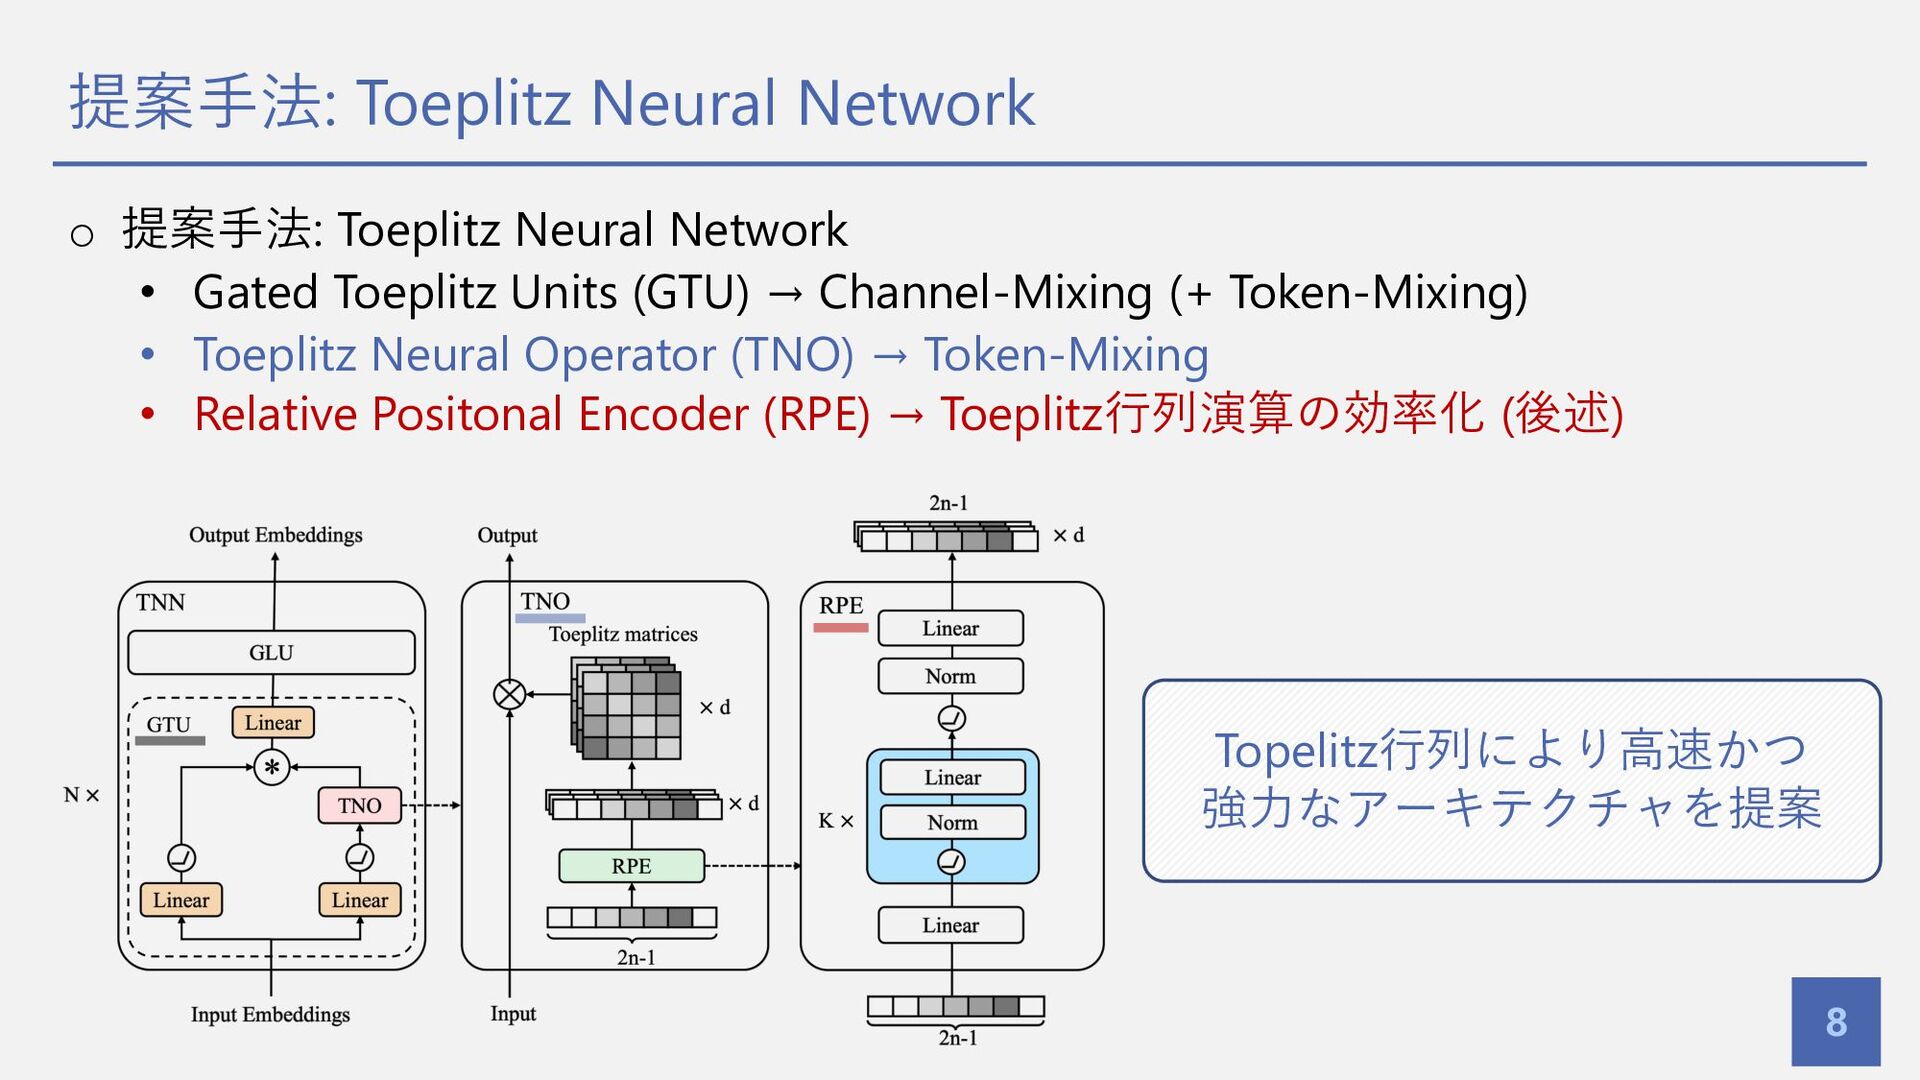
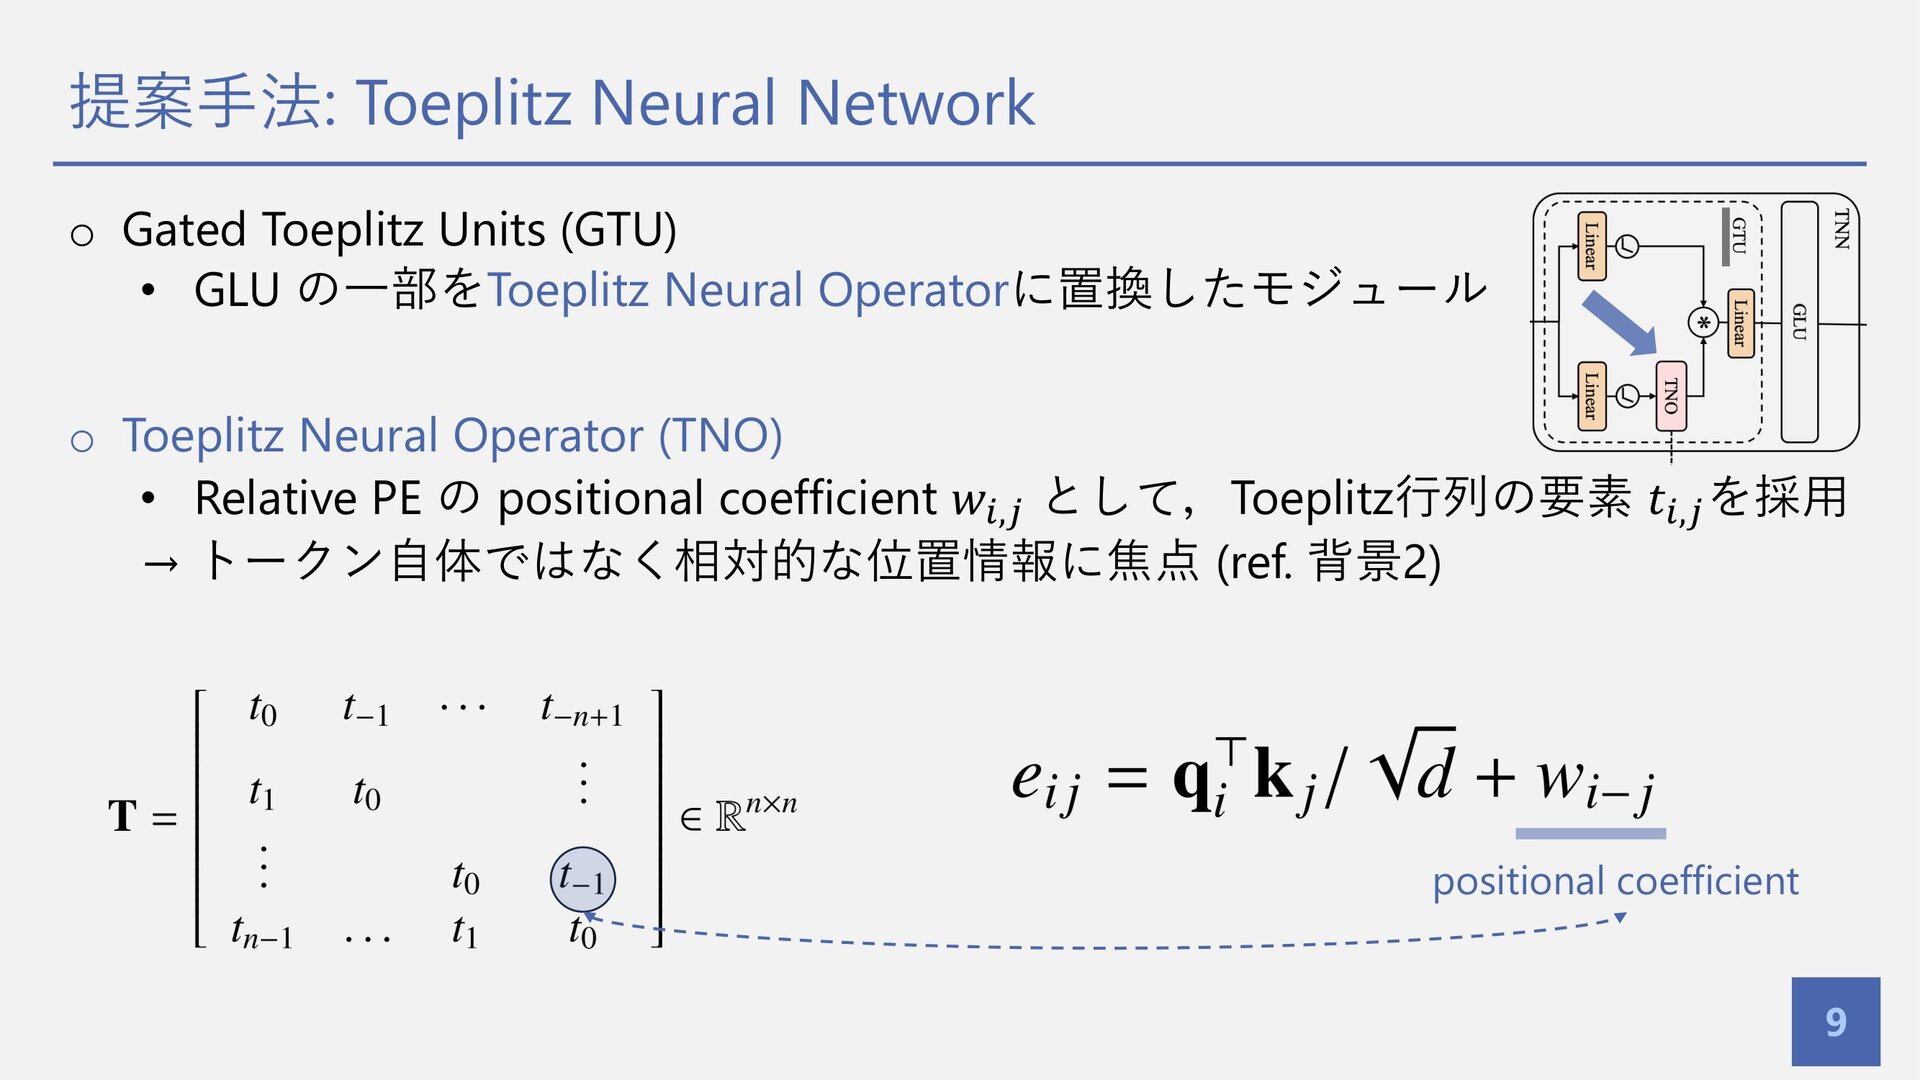
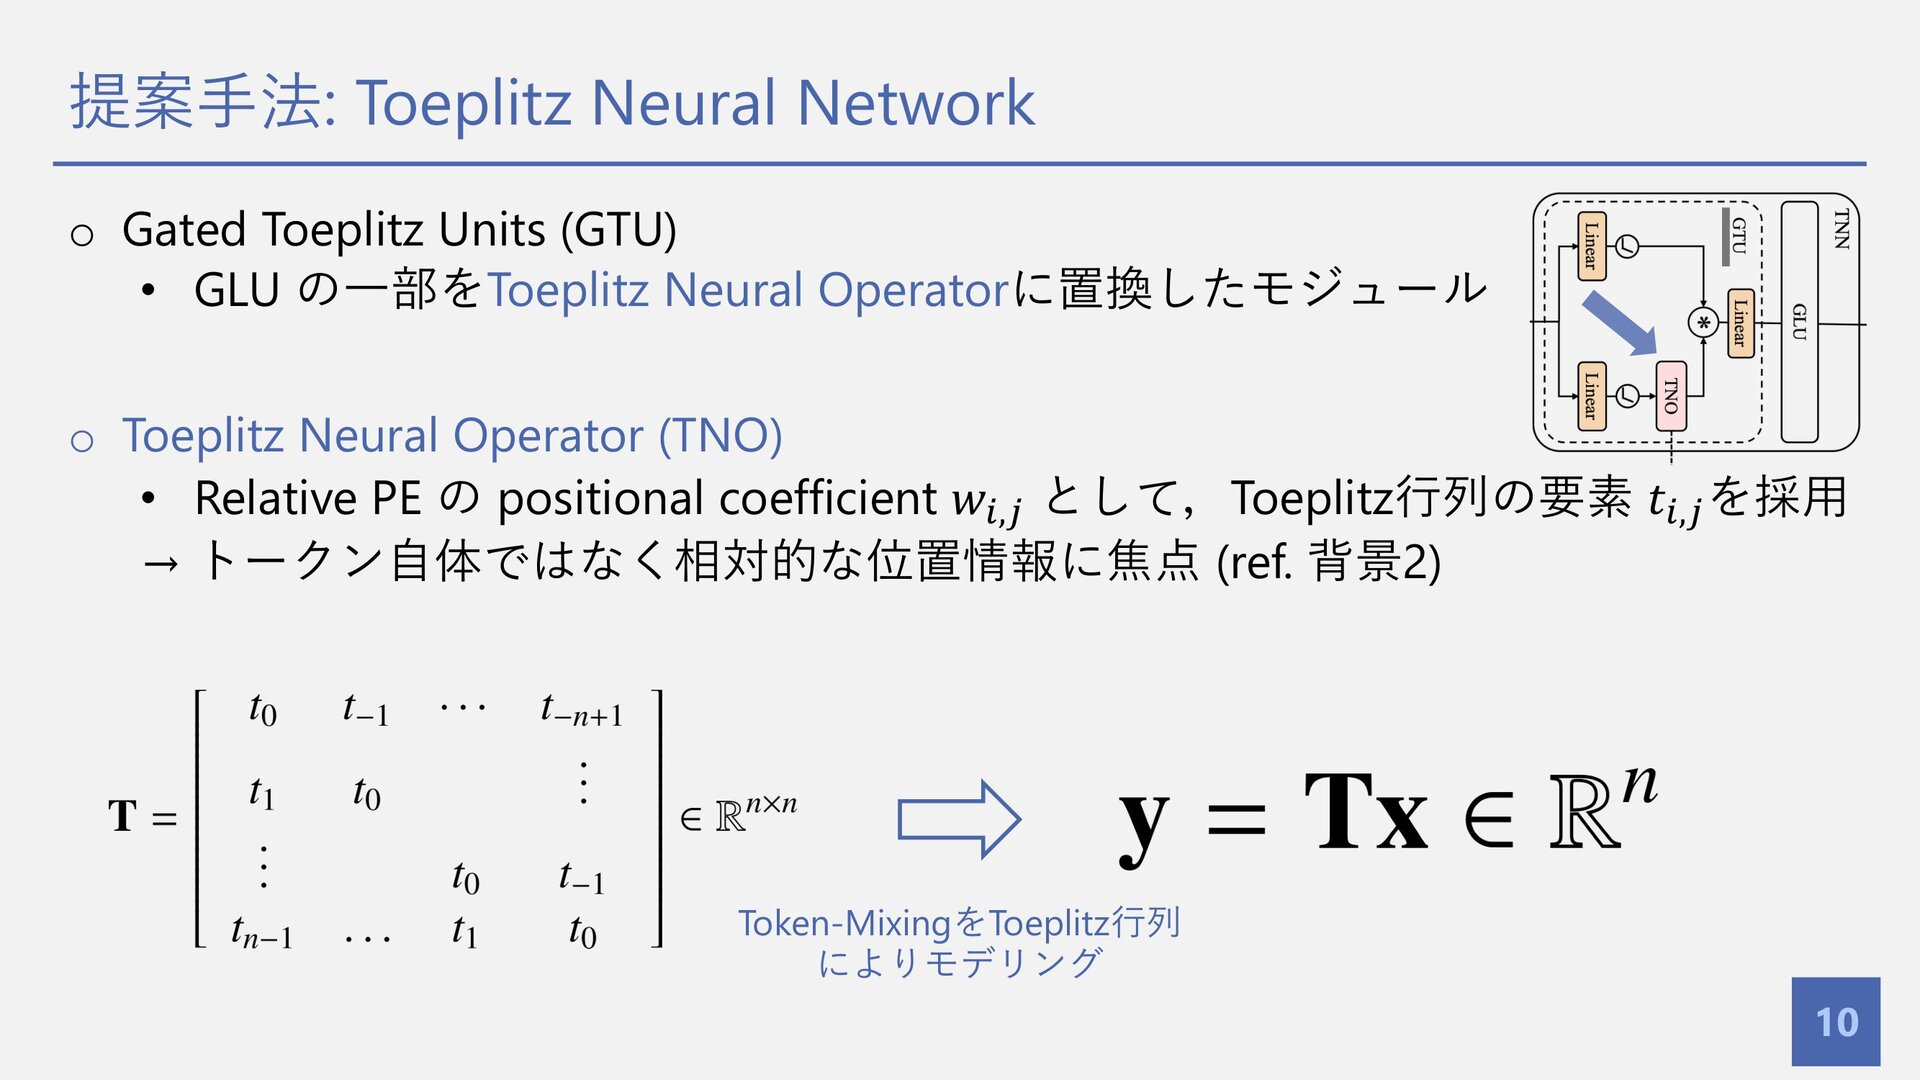
提案⼿法: Toeplitz Neural Network 8 o 提案⼿法: Toeplitz Neural Network
• Gated Toeplitz Units (GTU) → Channel-Mixing (+ Token-Mixing) • Toeplitz Neural Operator (TNO) → Token-Mixing • Relative Positonal Encoder (RPE) → Toeplitz⾏列演算の効率化 (後述) Topelitz⾏列により⾼速かつ 強⼒なアーキテクチャを提案
None
None
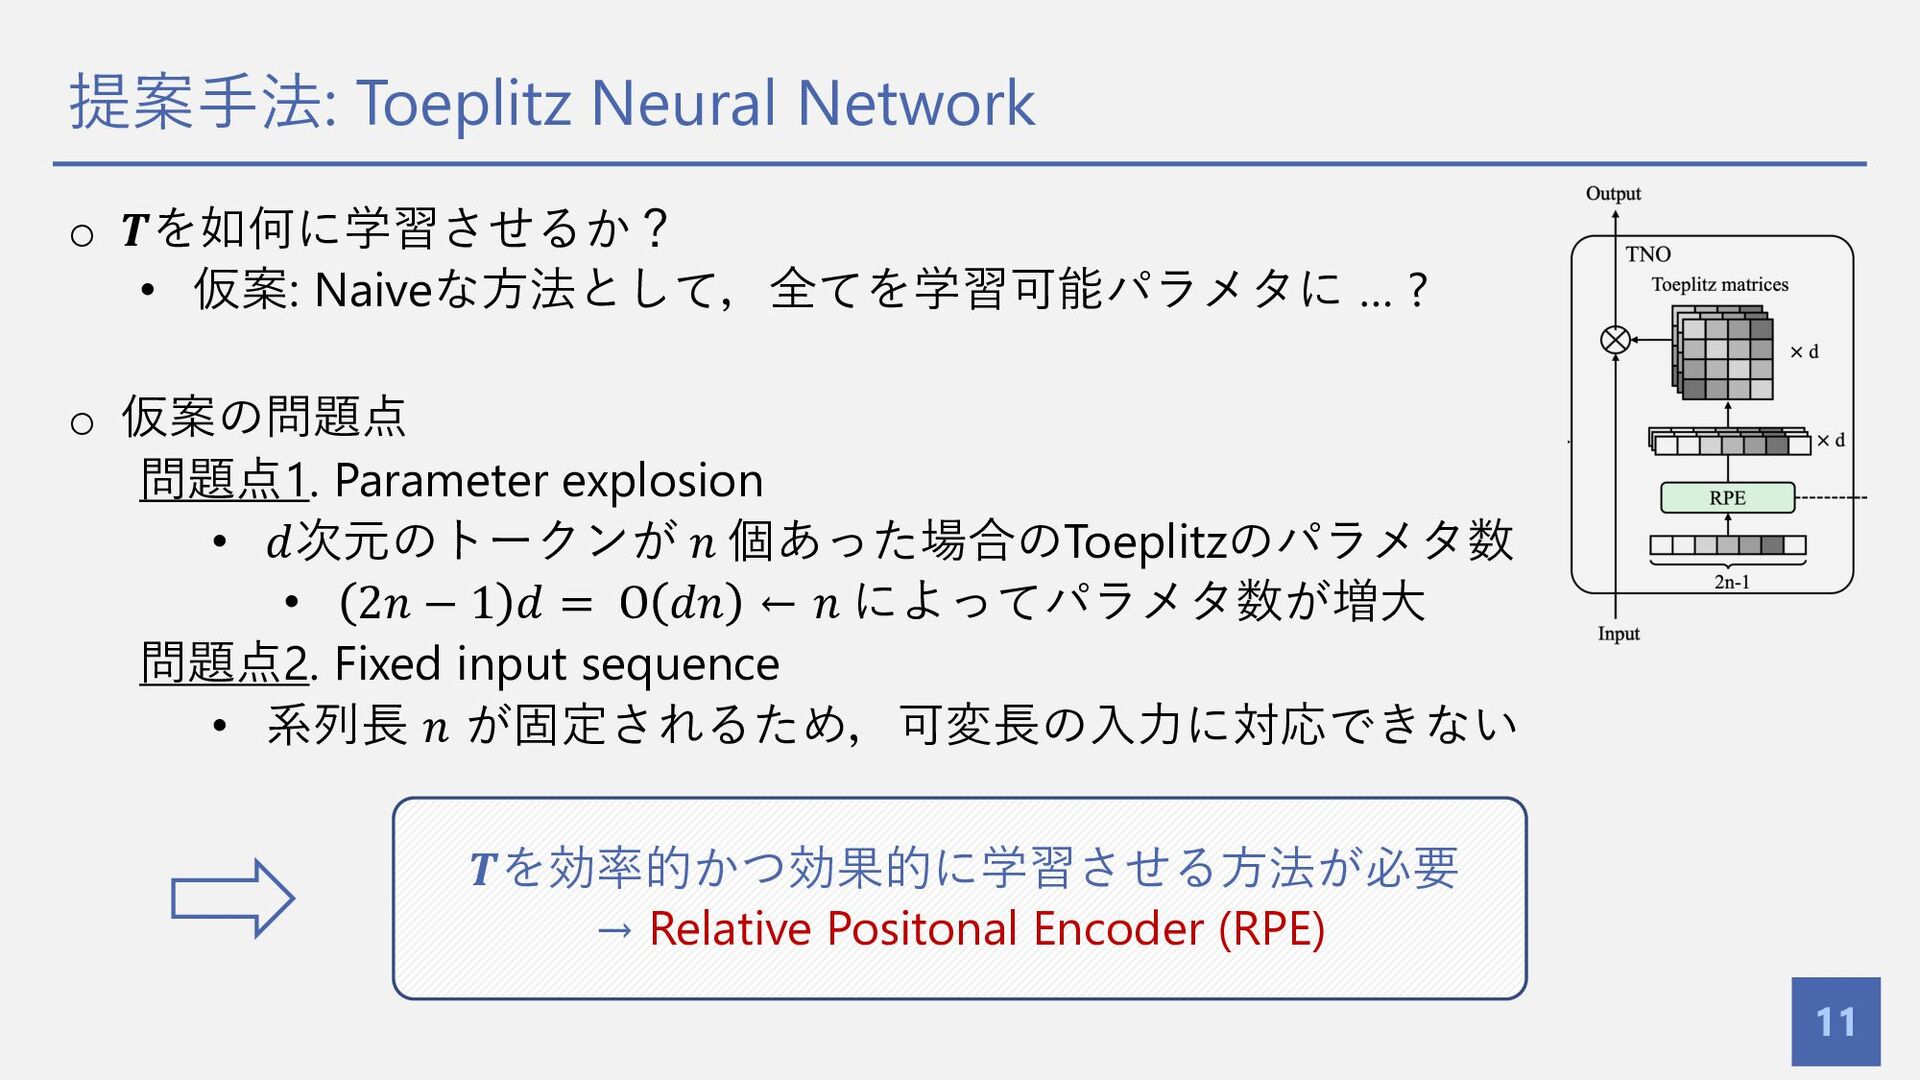
提案⼿法: Toeplitz Neural Network 11 o 𝑻を如何に学習させるか? • 仮案: Naiveな⽅法として,全てを学習可能パラメタに
… ? o 仮案の問題点 問題点1. Parameter explosion • 𝑑次元のトークンが 𝑛 個あった場合のToeplitzのパラメタ数 • 2𝑛 − 1 𝑑 = O 𝑑𝑛 ← 𝑛 によってパラメタ数が増⼤ 問題点2. Fixed input sequence • 系列⻑ 𝑛 が固定されるため,可変⻑の⼊⼒に対応できない 𝑻を効率的かつ効果的に学習させる⽅法が必要 → Relative Positonal Encoder (RPE)
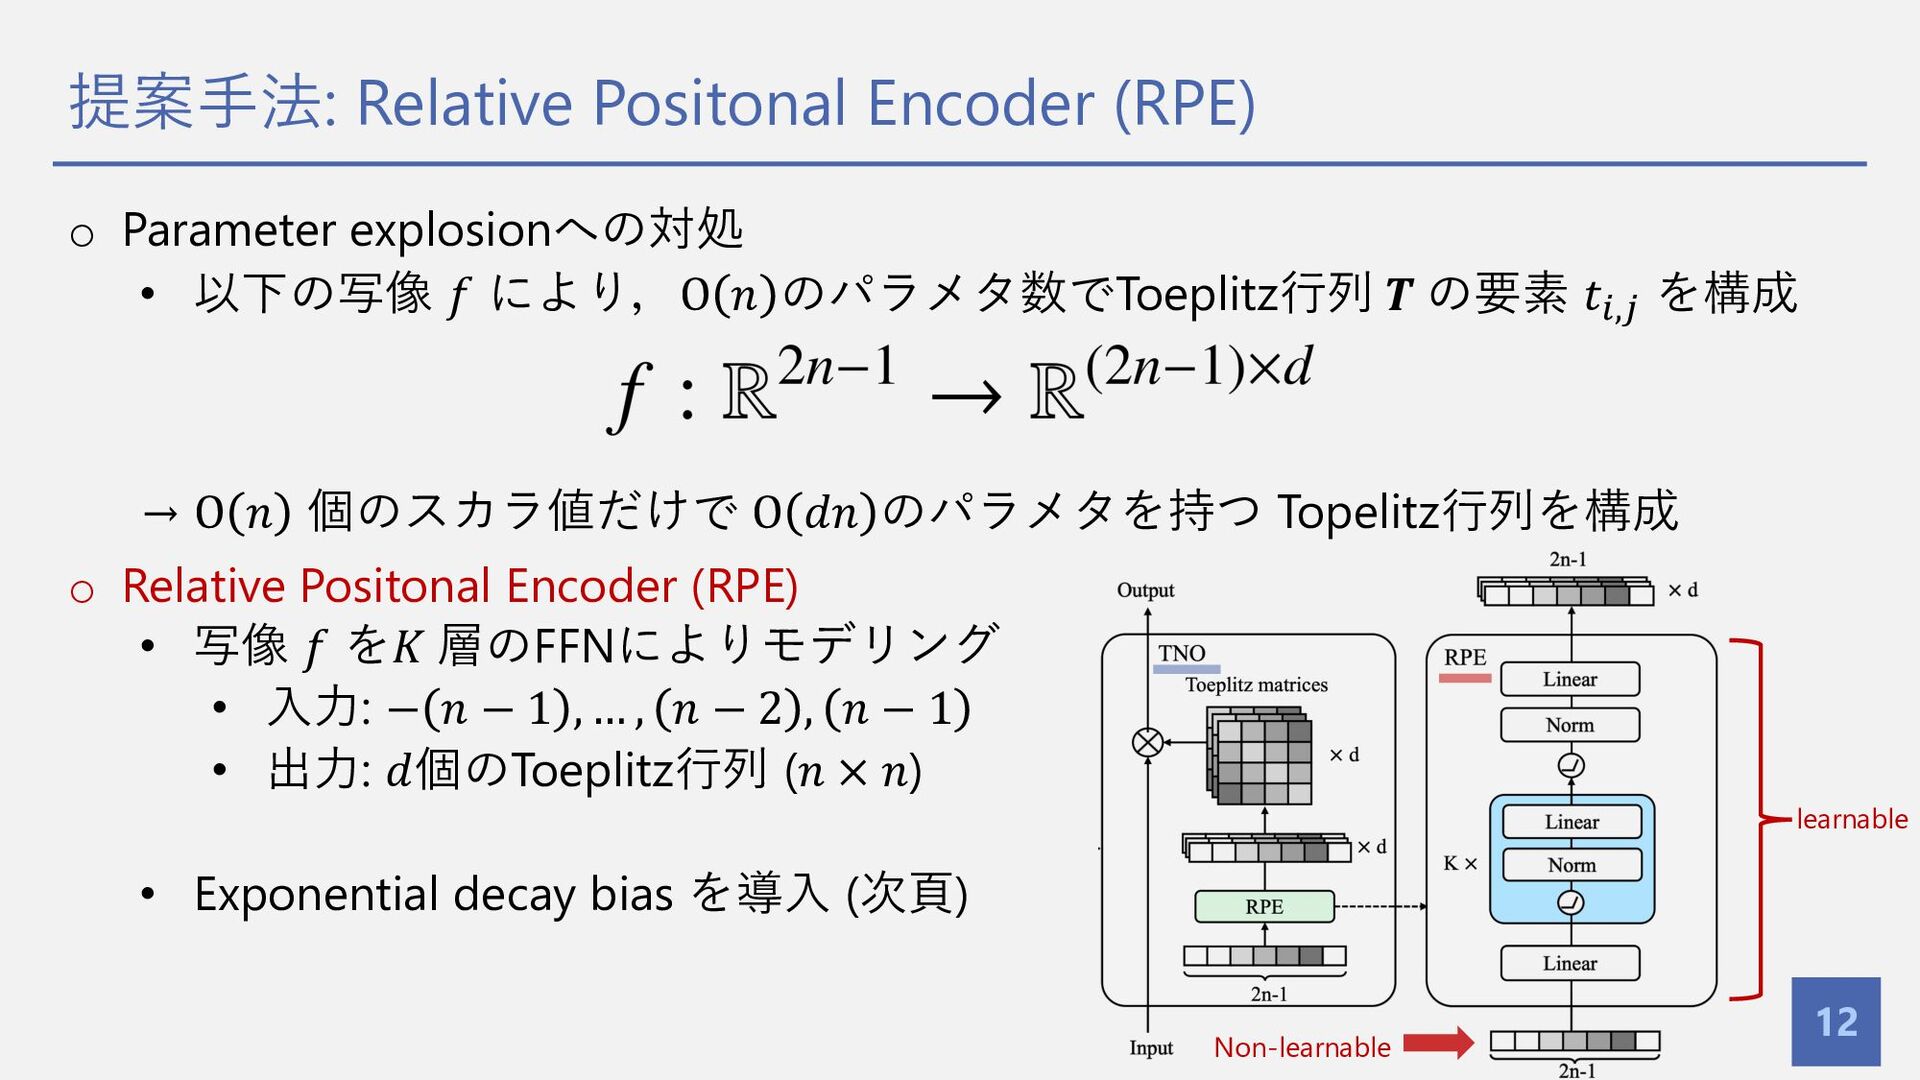
提案⼿法: Relative Positonal Encoder (RPE) 12 o Parameter explosionへの対処 •
以下の写像 𝑓 により,O 𝑛 のパラメタ数でToeplitz⾏列 𝑻 の要素 𝑡",$ を構成 → O 𝑛 個のスカラ値だけで O 𝑑𝑛 のパラメタを持つ Topelitz⾏列を構成 o Relative Positonal Encoder (RPE) • 写像 𝑓 を𝐾 層のFFNによりモデリング • ⼊⼒: − 𝑛 − 1 , … , 𝑛 − 2 , 𝑛 − 1 • 出⼒: 𝑑個のToeplitz⾏列 (𝑛 × 𝑛) • Exponential decay bias を導⼊ (次⾴) learnable Non-learnable
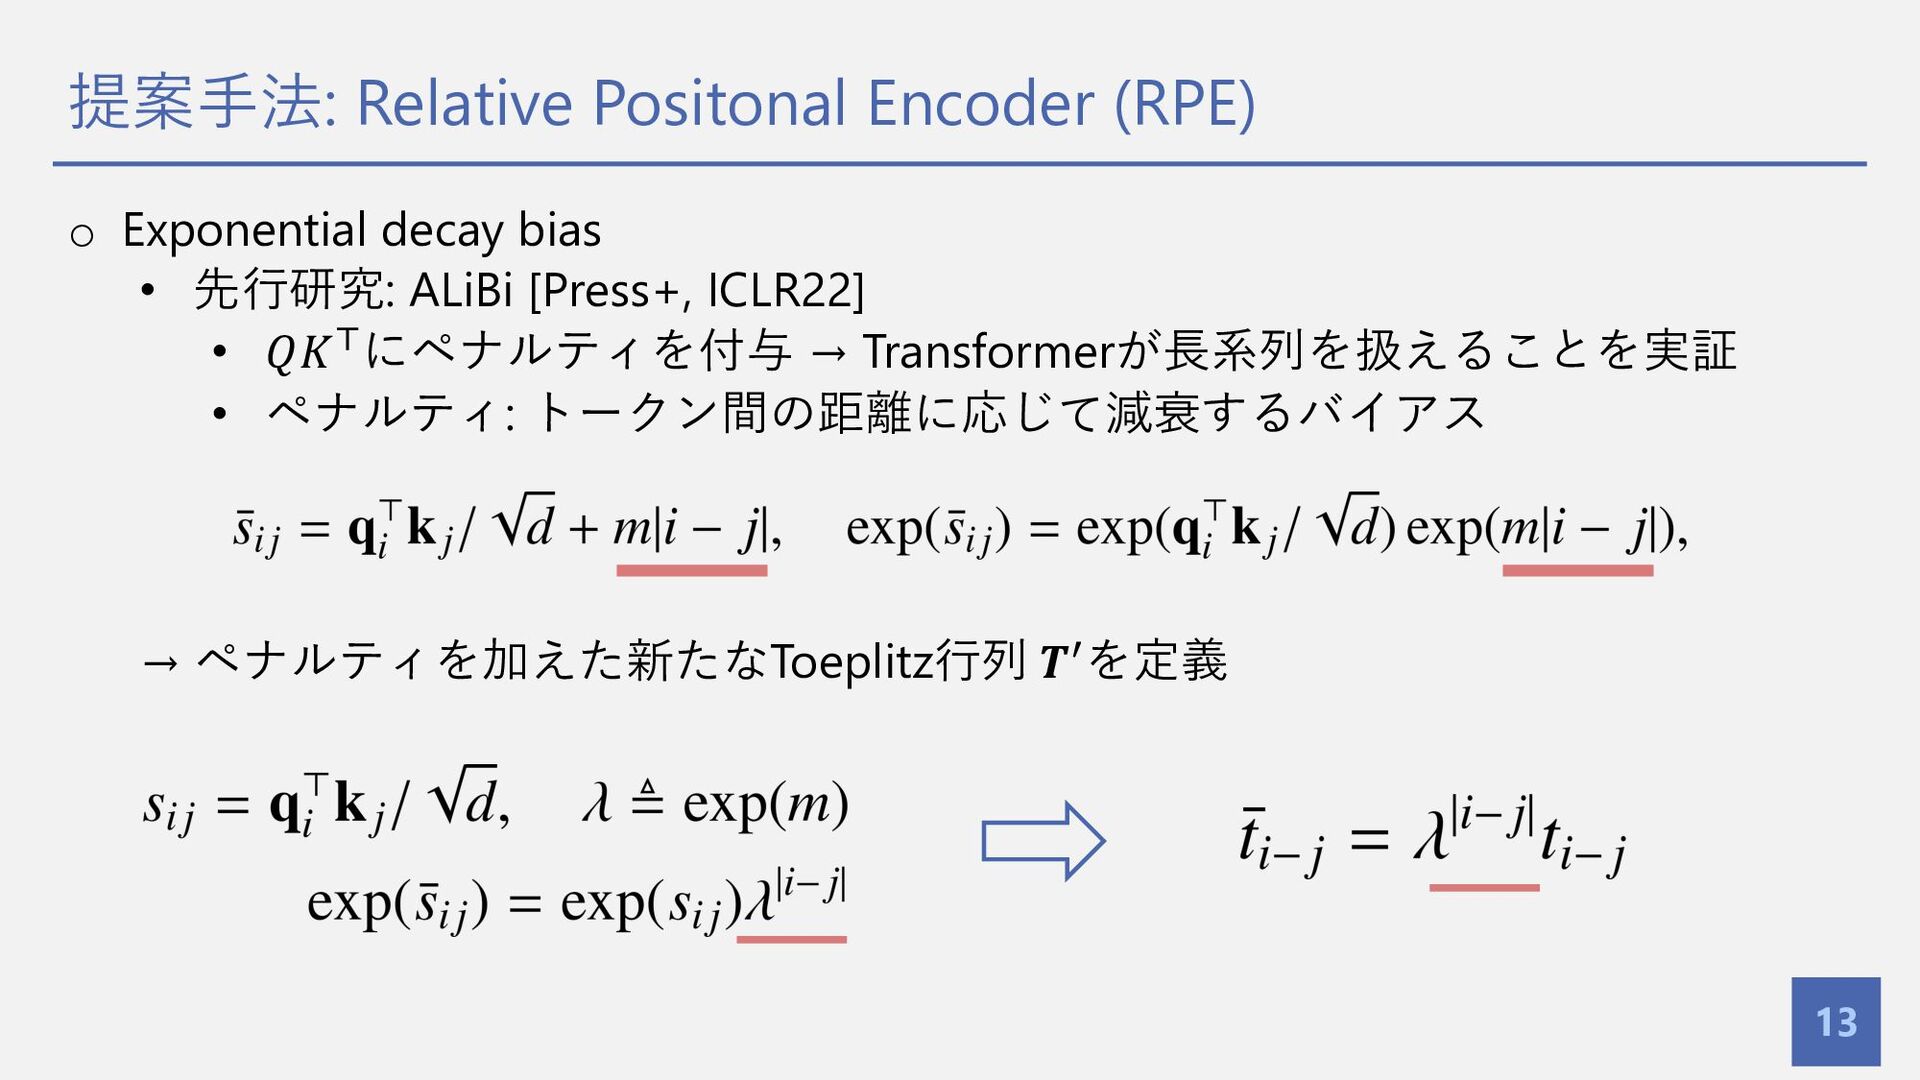
提案⼿法: Relative Positonal Encoder (RPE) 13 o Exponential decay bias
• 先⾏研究: ALiBi [Press+, ICLR22] • 𝑄𝐾%にペナルティを付与 → Transformerが⻑系列を扱えることを実証 • ペナルティ: トークン間の距離に応じて減衰するバイアス → ペナルティを加えた新たなToeplitz⾏列 𝑻&を定義
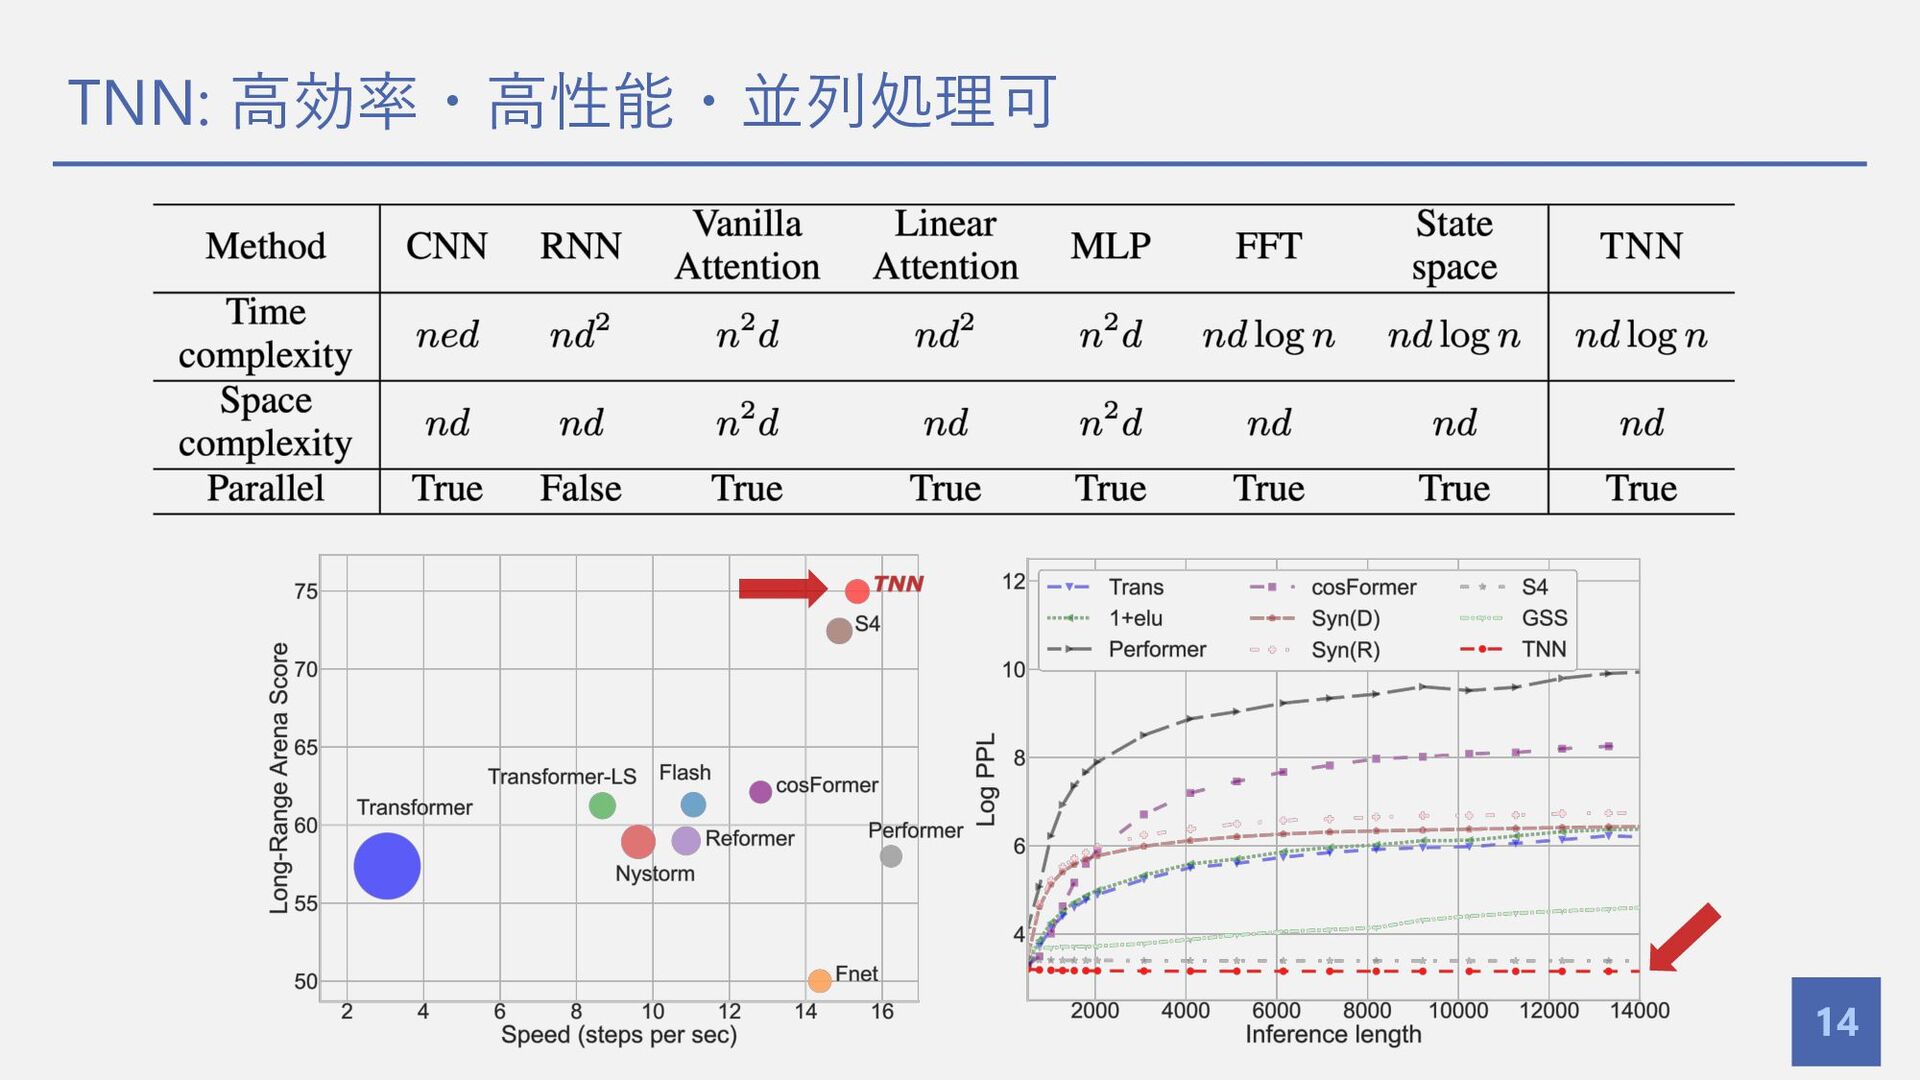
TNN: ⾼効率・⾼性能・並列処理可 14
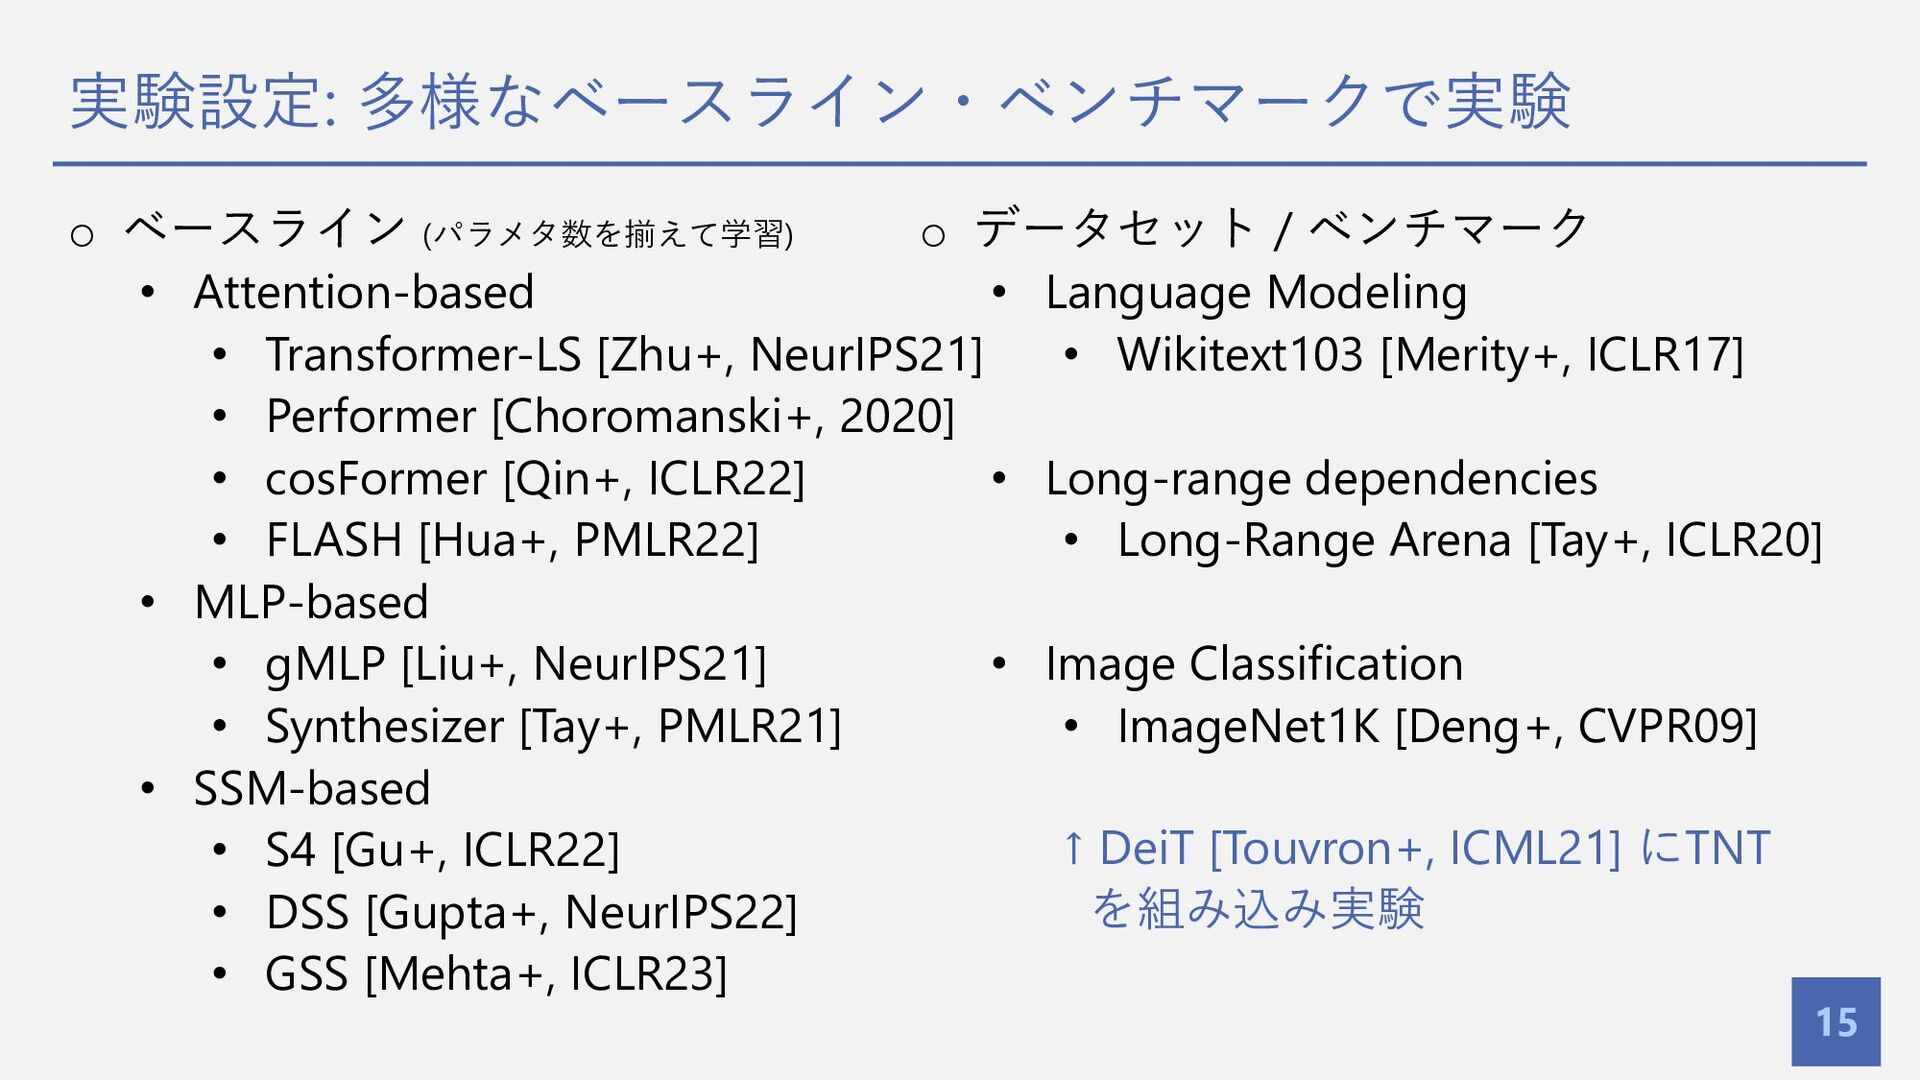
実験設定: 多様なベースライン・ベンチマークで実験 15 o ベースライン (パラメタ数を揃えて学習) • Attention-based • Transformer-LS
[Zhu+, NeurIPS21] • Performer [Choromanski+, 2020] • cosFormer [Qin+, ICLR22] • FLASH [Hua+, PMLR22] • MLP-based • gMLP [Liu+, NeurIPS21] • Synthesizer [Tay+, PMLR21] • SSM-based • S4 [Gu+, ICLR22] • DSS [Gupta+, NeurIPS22] • GSS [Mehta+, ICLR23] o データセット / ベンチマーク • Language Modeling • Wikitext103 [Merity+, ICLR17] • Long-range dependencies • Long-Range Arena [Tay+, ICLR20] • Image Classification • ImageNet1K [Deng+, CVPR09] ↑ DeiT [Touvron+, ICML21] にTNT を組み込み実験
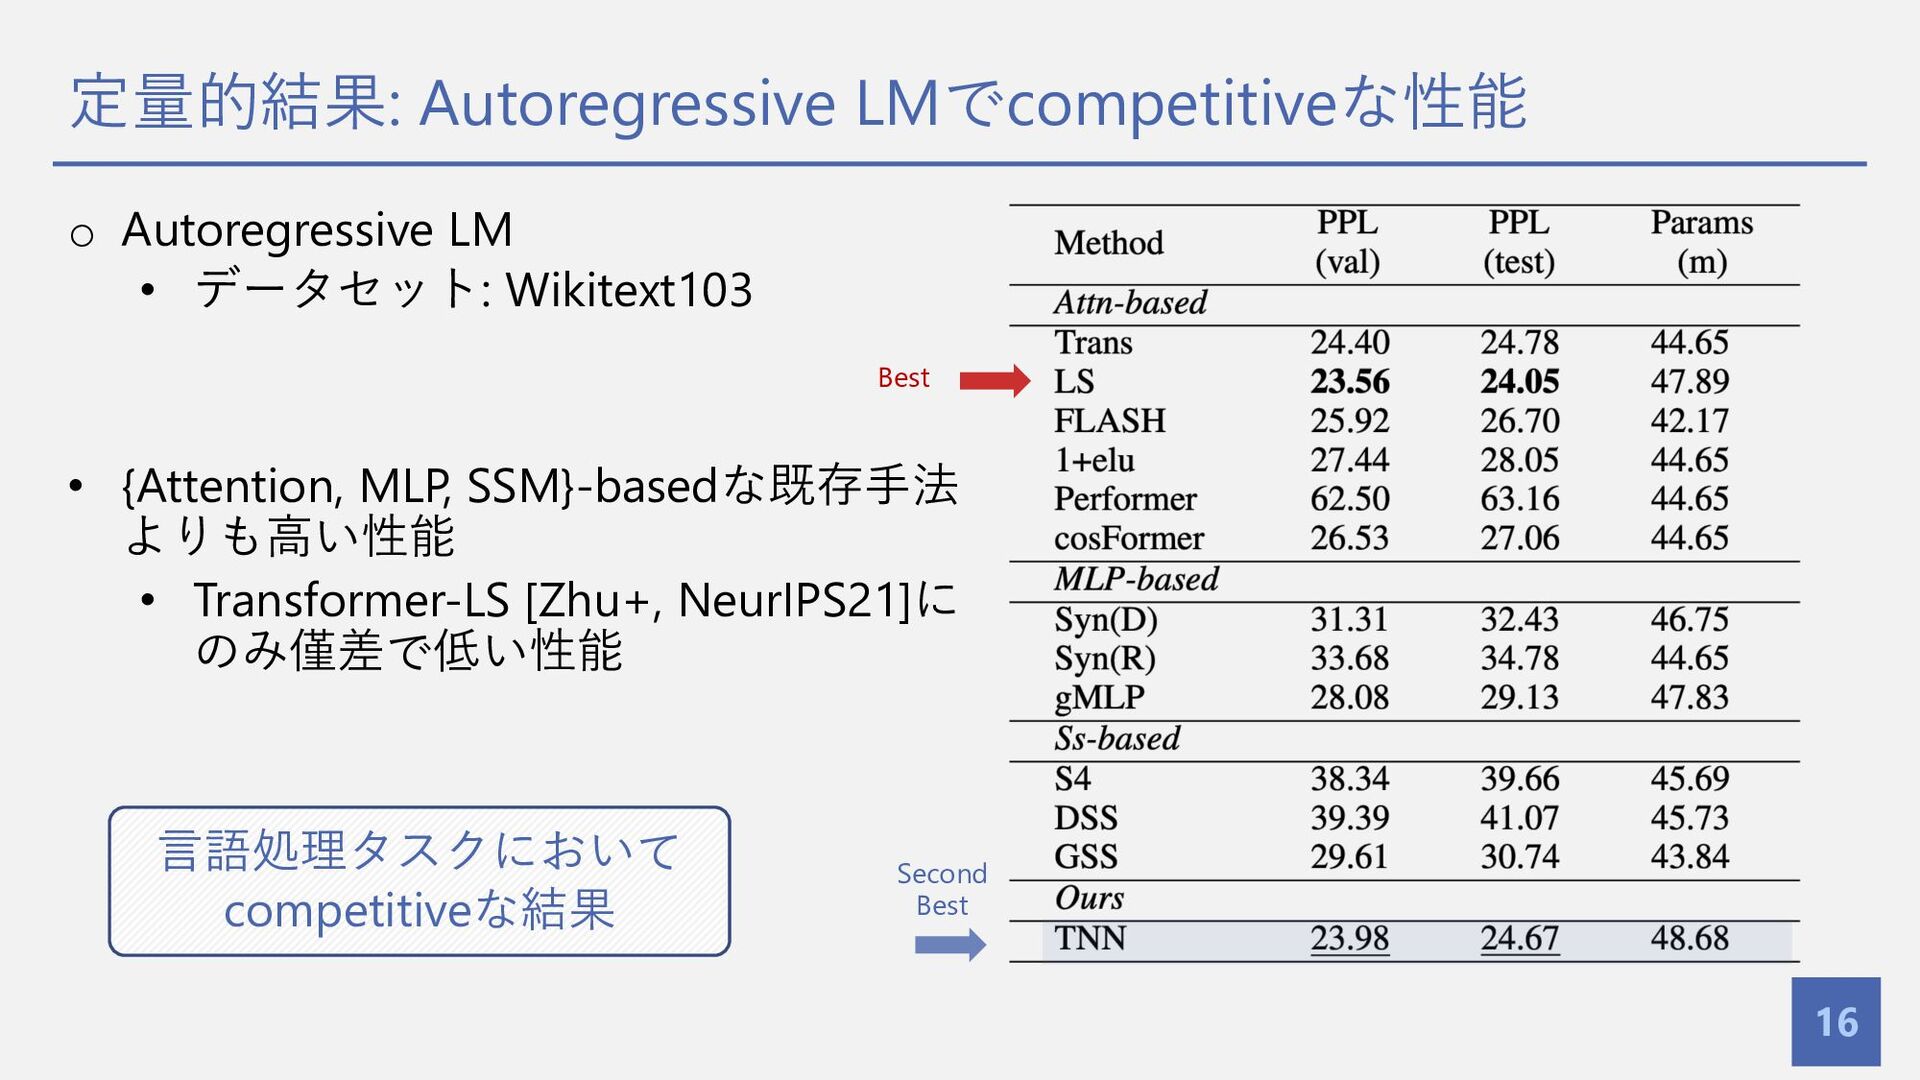
定量的結果: Autoregressive LMでcompetitiveな性能 16 o Autoregressive LM • データセット: Wikitext103
• {Attention, MLP, SSM}-basedな既存⼿法 よりも⾼い性能 • Transformer-LS [Zhu+, NeurIPS21]に のみ僅差で低い性能 Best Second Best ⾔語処理タスクにおいて competitiveな結果
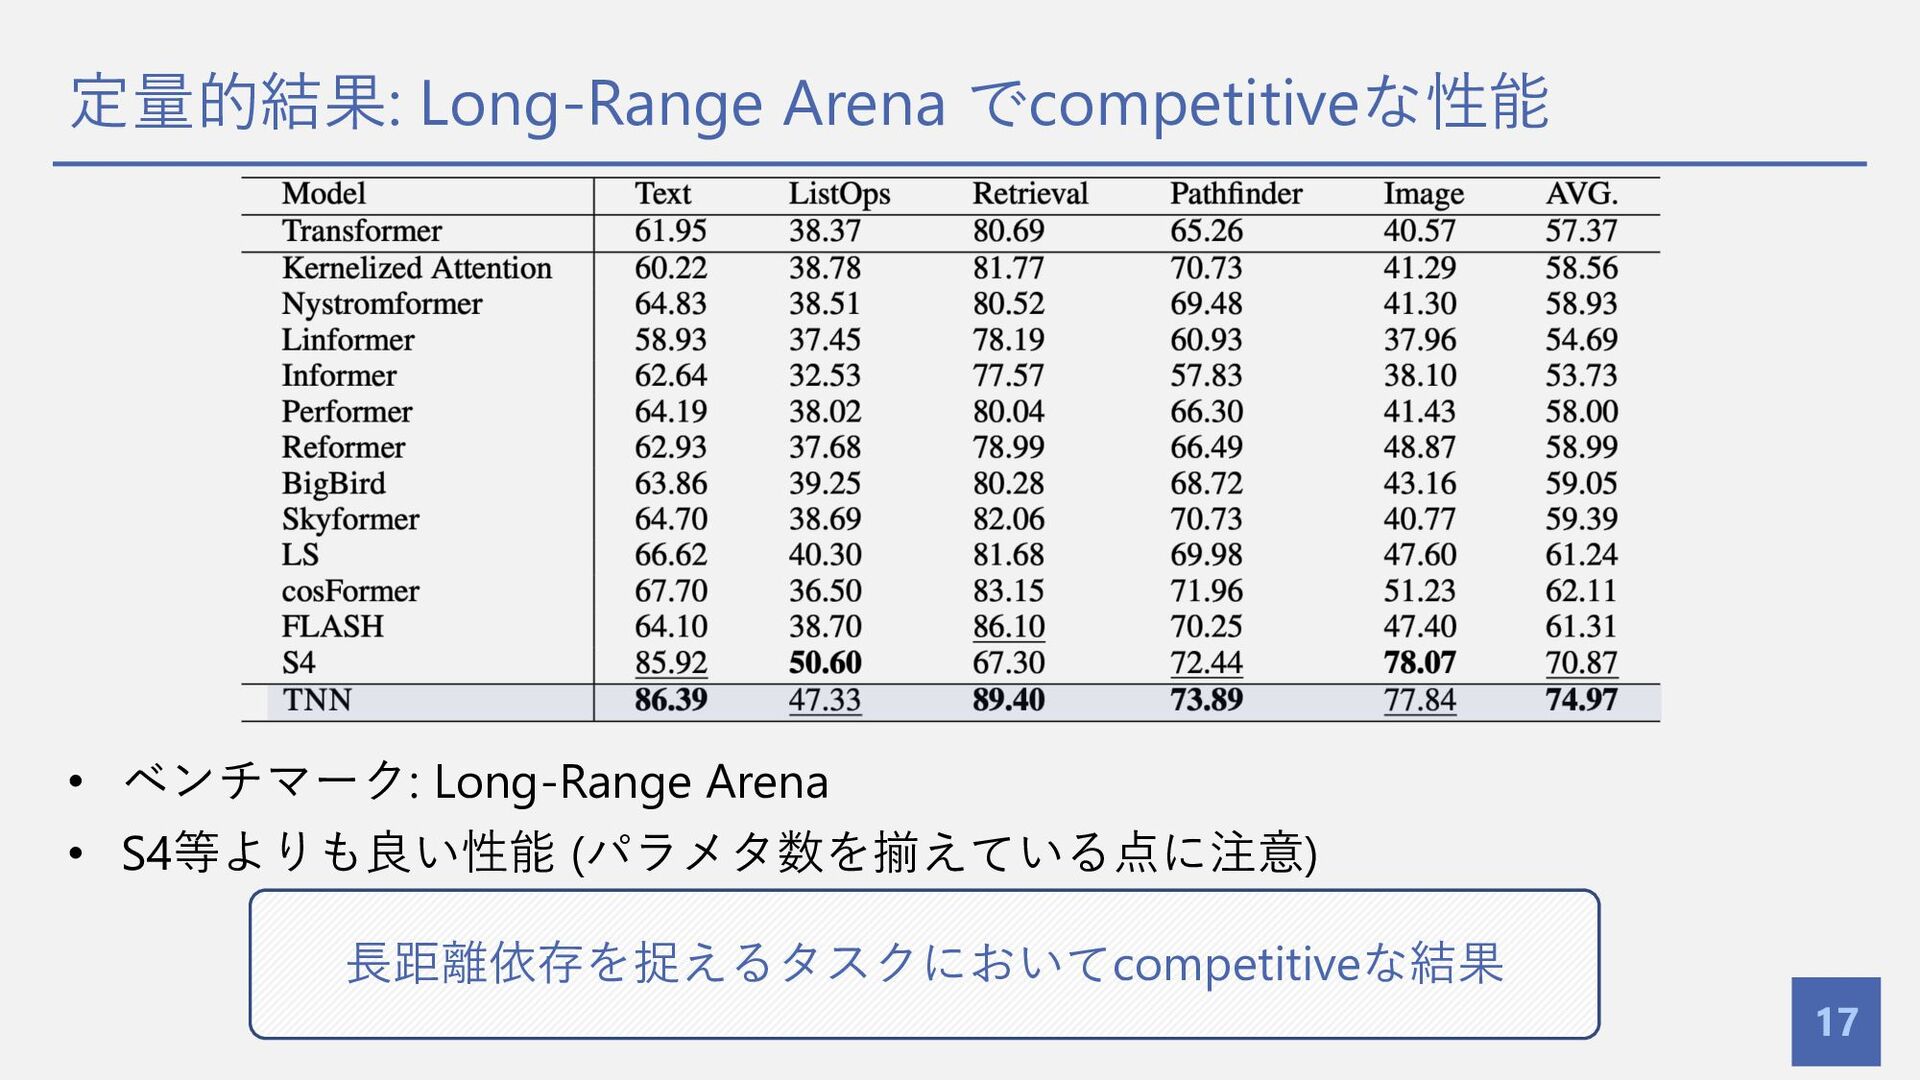
定量的結果: Long-Range Arena でcompetitiveな性能 17 • ベンチマーク: Long-Range Arena •
S4等よりも良い性能 (パラメタ数を揃えている点に注意) ⻑距離依存を捉えるタスクにおいてcompetitiveな結果
Ablation Study: RPEの有効性を確認 18 o RPEの⼊⼒は最良か? • NeRF [Mildenhall+, ECCV20]の指摘
• ⾼次元空間への写像が重要である と指摘 →PEにsin / cosが有効であると主張 → 実際は,ほとんど性能には寄与しないことを確認 ⇒ ⼊⼒ − 𝑛 − 1 , … , 𝑛 − 2 , 𝑛 − 1 が最良 o RPEは有効か? → RPEがないことで性能が極端に低下 RPEの有効性を確認
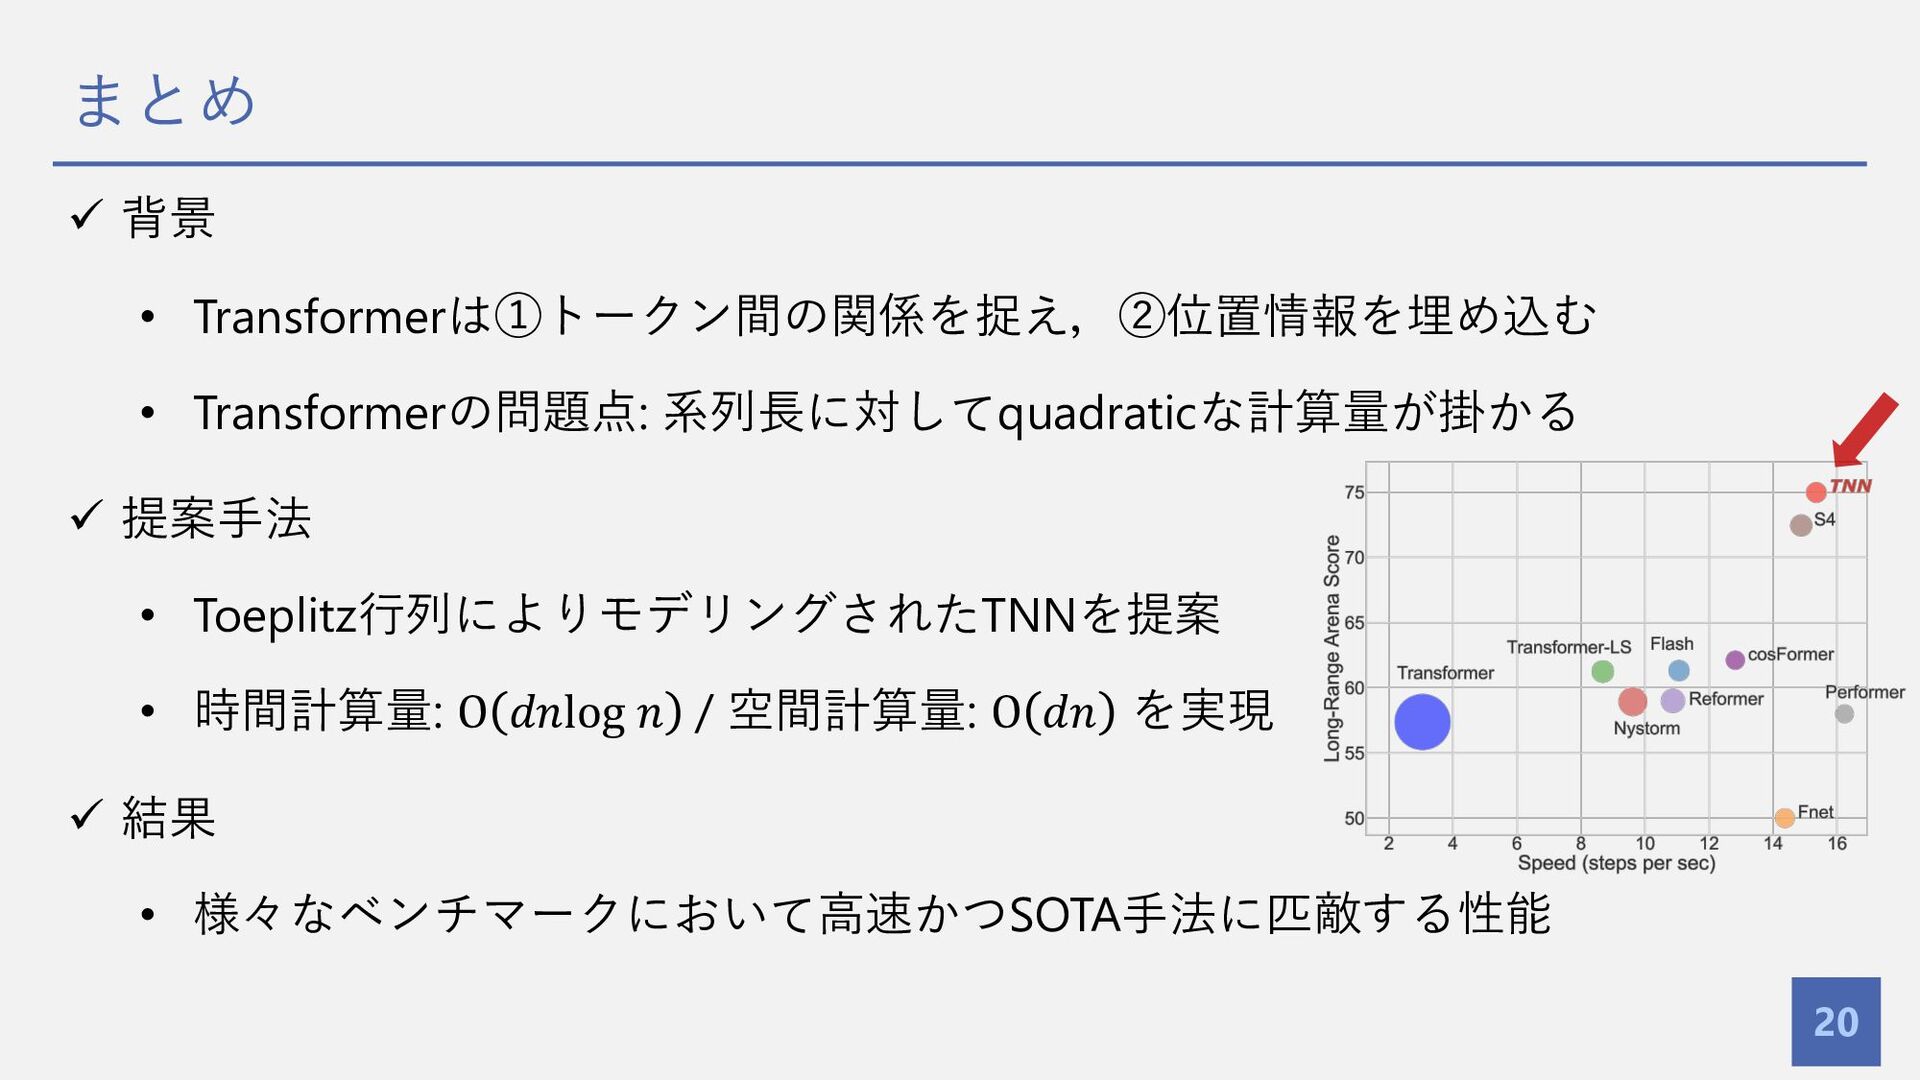
まとめ 20 ü 背景 • Transformerは①トークン間の関係を捉え,②位置情報を埋め込む • Transformerの問題点: 系列⻑に対してquadraticな計算量が掛かる ü
提案⼿法 • Toeplitz⾏列によりモデリングされたTNNを提案 • 時間計算量: O 𝑑𝑛log 𝑛 / 空間計算量: O 𝑑𝑛 を実現 ü 結果 • 様々なベンチマークにおいて⾼速かつSOTA⼿法に匹敵する性能


 keio_smilab
 carta_engineering
 pauli
 yakumo
 bcantrill
 chack411
 kameitomohiro
 sansantech
 vivion
 kazuho
 sudoakiy
 thkt
 rabernat
 baasie
 axbom
 smashingmag
 aki_iinuma
 inesmontani
 soysaucechin
 tapps
 swwweet
 sugarenia
 ianozsvald
 aemeredith