Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
AIで最適化を解けるか?
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
MIKIO KUBO
March 31, 2026
Research
170
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
AIで最適化を解けるか?
LLMや深層強化学習で組合せ最適化を解くためのアプローチと比較
MIKIO KUBO
March 31, 2026
More Decks by MIKIO KUBO
See All by MIKIO KUBO
人工知能の歴史: チューリングからエージェントスキルに至る道程}
mickey_kubo
0
160
AlgorithAlgorihms for Decision Making
mickey_kubo
0
170
エージェントスキル:自律型AIが変える最適化とサプライチェーンの未来
mickey_kubo
0
250
エージェントスキルによる最適化
mickey_kubo
2
240
Agent Skills 完全ガイド
mickey_kubo
0
230
Skill Creatorの技術設計と動作原理
mickey_kubo
0
240
AI+SCM
mickey_kubo
0
130
エージェンティック・サプライチェーン」の概念と、製造業におけるその革新的な役割について解説
mickey_kubo
0
130
MOAI Solutionの紹介 -電力最適化を中心として-
mickey_kubo
0
150
Other Decks in Research
See All in Research
ros2-perf-multihost: Automated Coordination Framework for Objective Architecture Evaluation in Distributed Systems
takasehideki
0
130
Evaluating LLM Reliability Across Facts, Evidence, and Cultures
yukiar
0
200
第64回CV・PRML勉強会 論文紹介:Linguistic Priors for Visual Decoupling: Towards Symmetric Vision-Brain Alignment
sokikatayama
0
240
[IR Reading 2026春 論文紹介] LLM-based Listwise Reranking under the Effect of Positional Bias (ECIR 2026) /IR-Reading-2026-Spring
koheishinden
PRO
0
450
LA-Bench 2025:実験指示から 実行可能手順を生成するためのデータセット/LA-Bench 2025: A Dataset for Generating Executable Experimental Procedures from Experimental Instructions
stktu
0
190
【Zozo Research 技術共有会】三次元領域の現在と展望
mickey_0226
3
670
[SNLP2026] Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach
wataruuuuu
0
330
Fukui Shibiten 39 - AI Art
butchi
0
260
VRID: View-Invariant Representation through Dual-Axis Transformation for Cross-iew Pose Estimation
satai
3
110
ros2-perf-multihost: 分散システムにおける客観的なアーキテクチャ評価フレームワーク
takasehideki
0
280
The story of RefactoringMiner. Slow research, long-term impact
tsantalis
0
180
Source Code Diff Revolution
tsantalis
0
180
Featured
See All Featured
Side Projects
sachag
456
43k
Thoughts on Productivity
jonyablonski
76
5.4k
brightonSEO & MeasureFest 2025 - Winning Strategies for Black Friday CRO & PPC - Christian Goodrich
cargoodrich
3
860
Performance Is Good for Brains [We Love Speed 2024]
tammyeverts
12
1.9k
Making the Leap to Tech Lead
cromwellryan
135
10k
Unsuck your backbone
ammeep
672
58k
YesSQL, Process and Tooling at Scale
rocio
174
15k
The Spectacular Lies of Maps
axbom
PRO
1
1.1k
The innovator’s Mindset - Leading Through an Era of Exponential Change - McGill University 2025
jdejongh
PRO
1
350
Building a Modern Day E-commerce SEO Strategy
aleyda
45
9.2k
Effective software design: The role of men in debugging patriarchy in IT @ Voxxed Days AMS
baasie
1
550
The Web Performance Landscape in 2024 [PerfNow 2024]
tammyeverts
12
1.3k
Transcript
AIで最適化を解けるか? MOAI Lab.
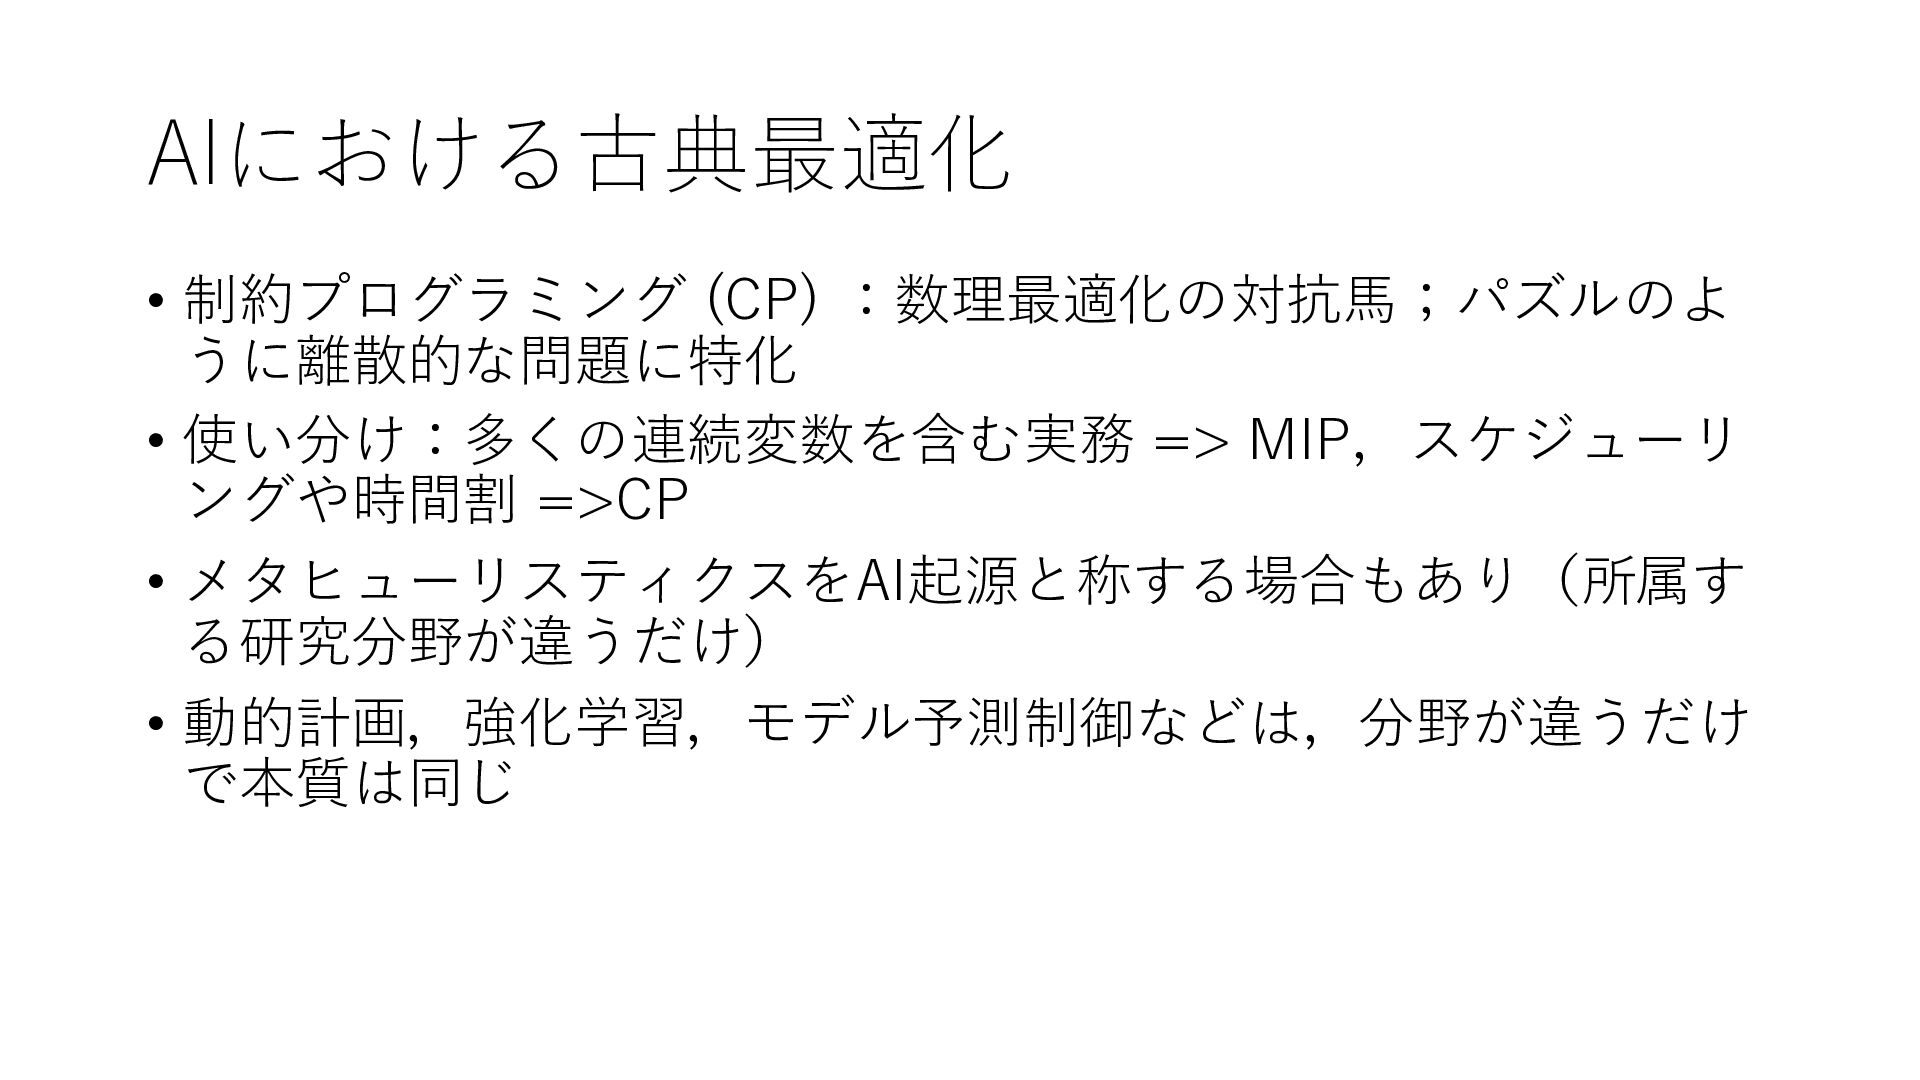
AIにおける古典最適化 • 制約プログラミング (CP) :数理最適化の対抗馬;パズルのよ うに離散的な問題に特化 • 使い分け:多くの連続変数を含む実務 => MIP,スケジューリ
ングや時間割 =>CP • メタヒューリスティクスをAI起源と称する場合もあり(所属す る研究分野が違うだけ) • 動的計画,強化学習,モデル予測制御などは,分野が違うだけ で本質は同じ
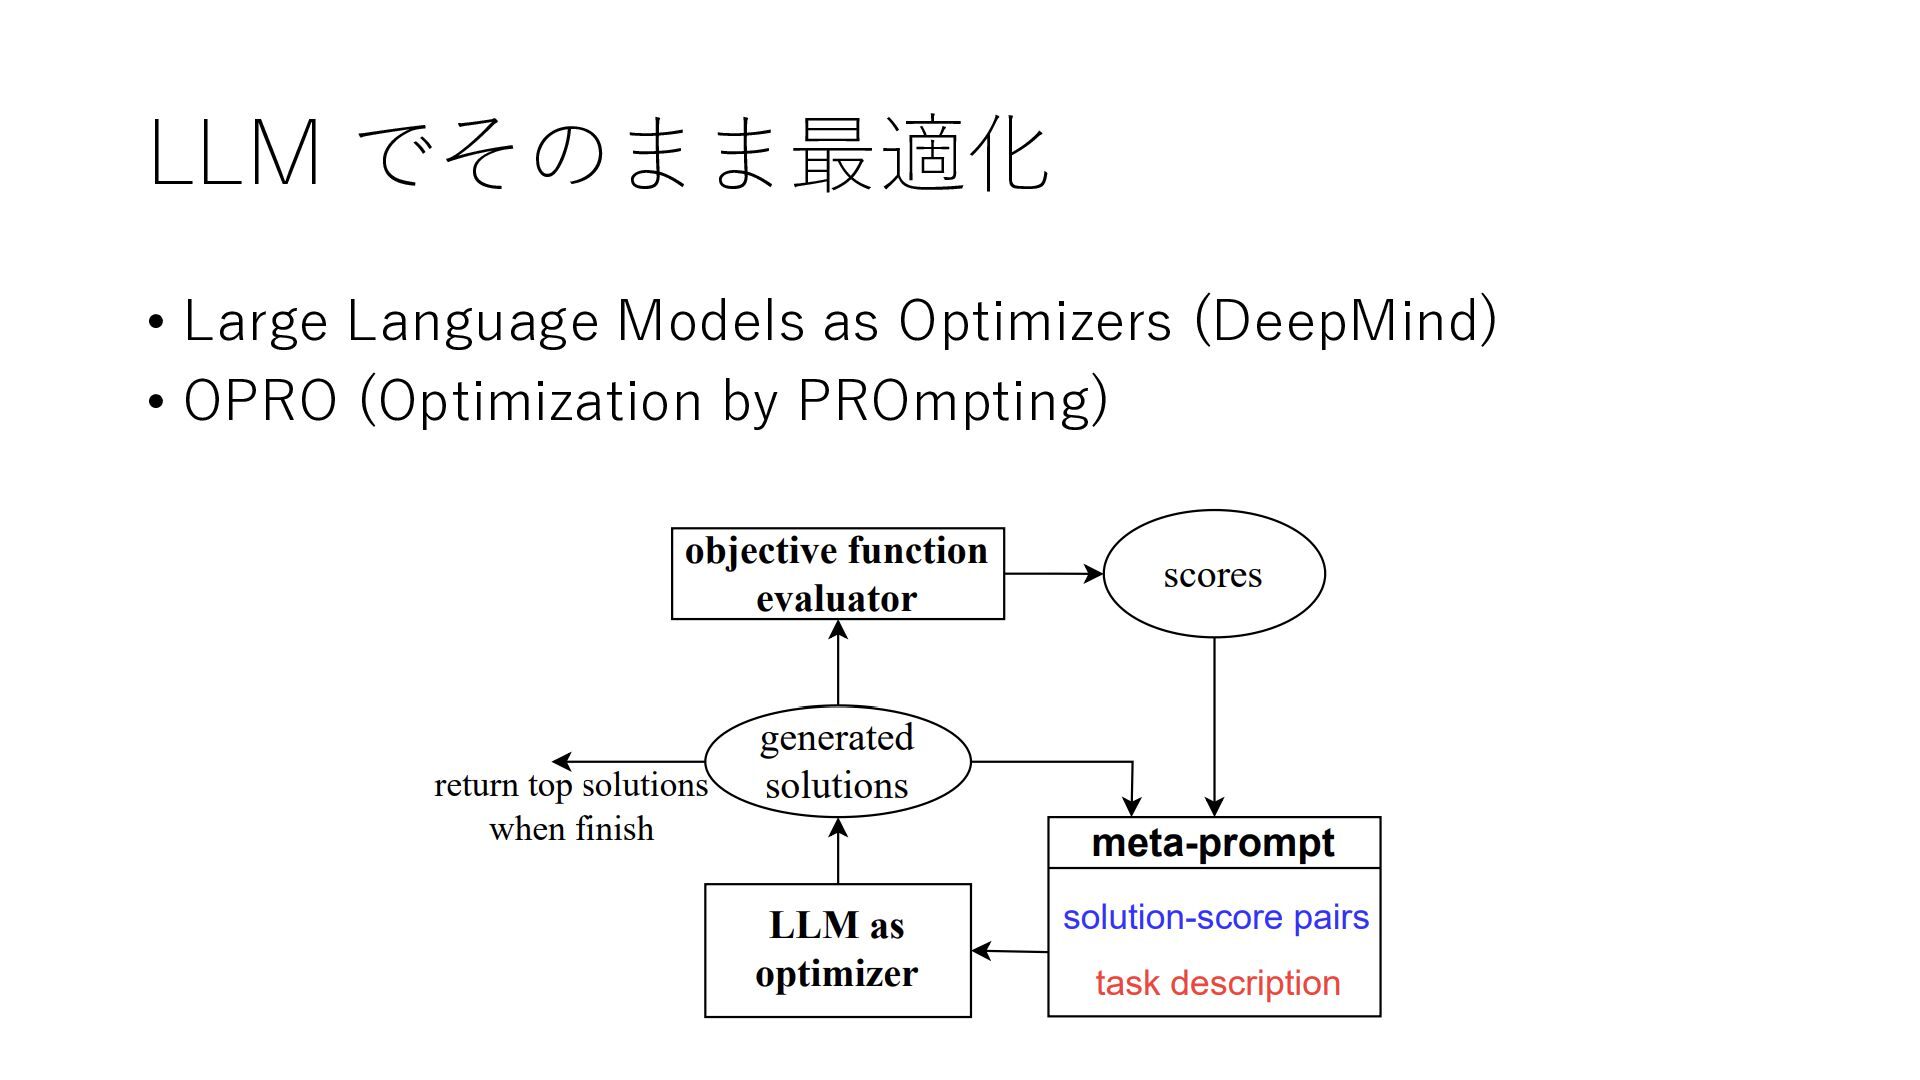
LLM でそのまま最適化 • Large Language Models as Optimizers (DeepMind) •
OPRO (Optimization by PROmpting)
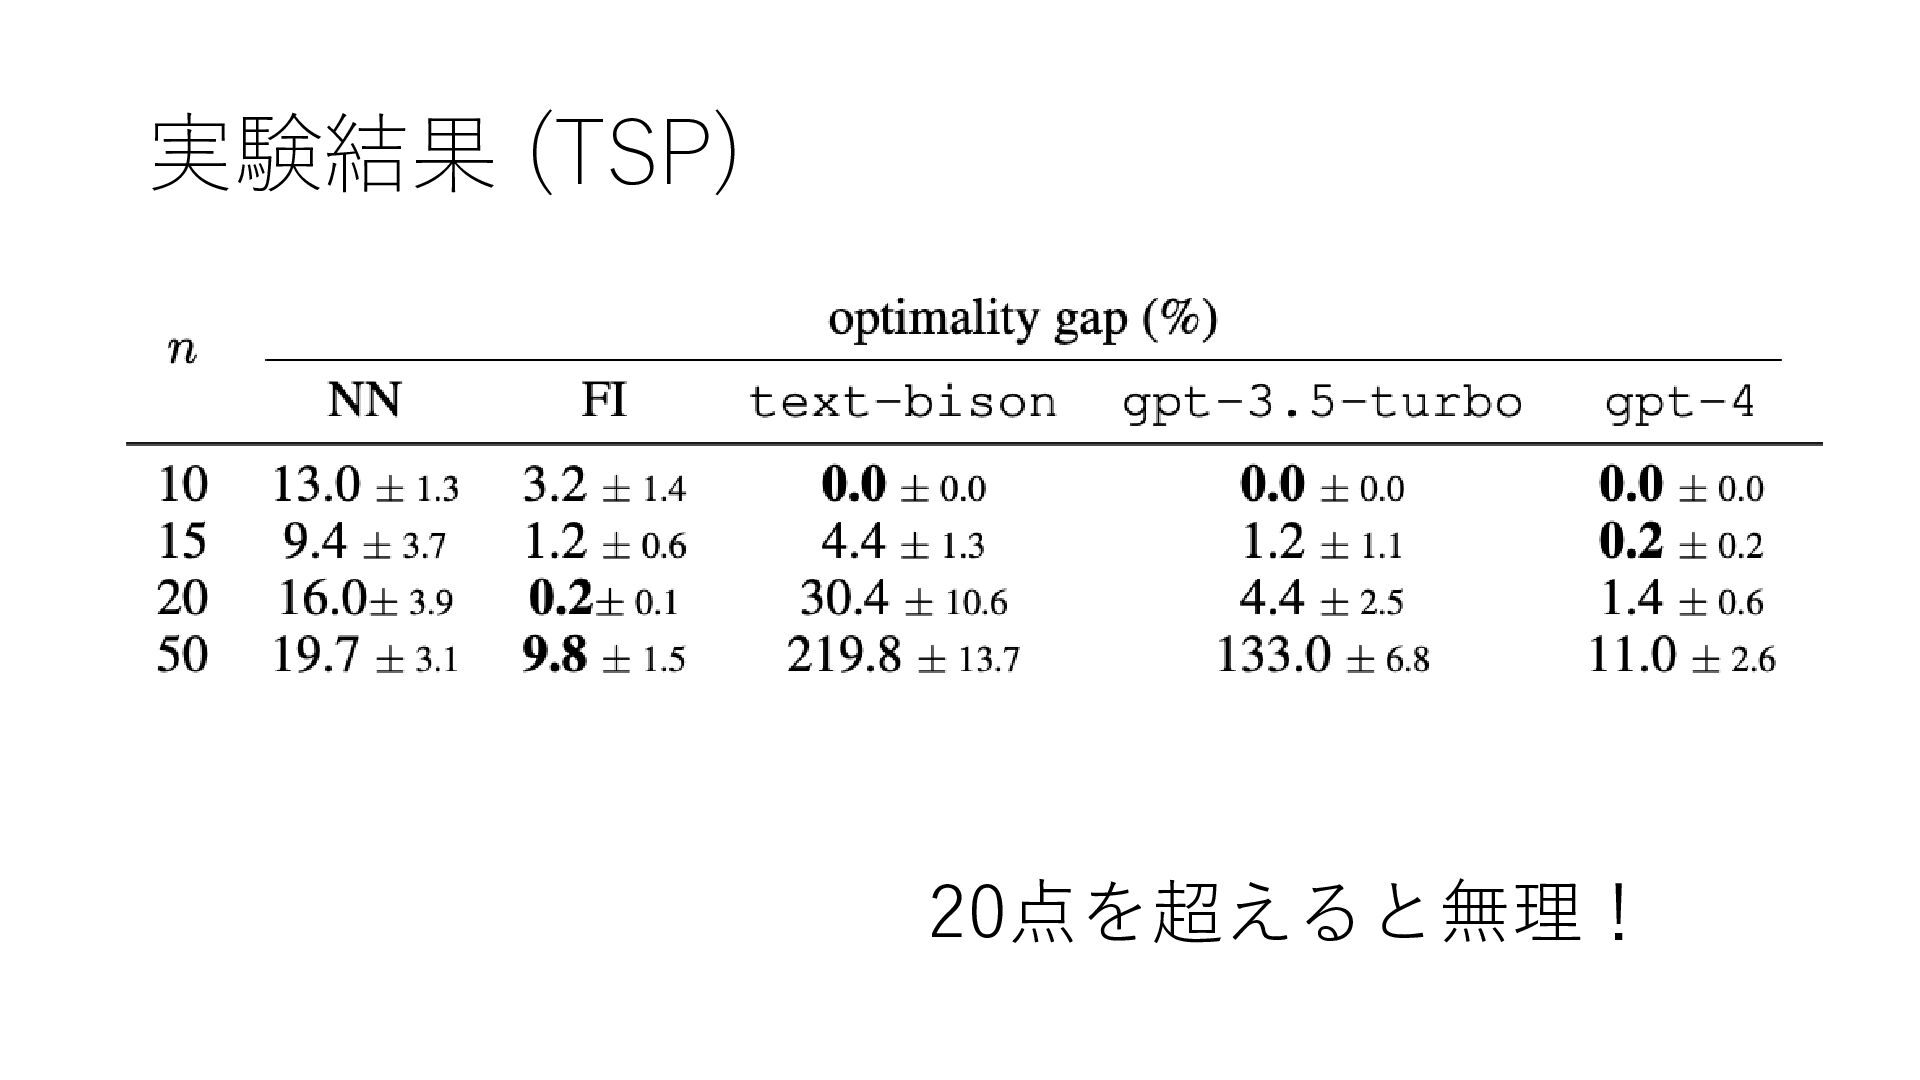
実験結果 (TSP) 20点を超えると無理!
深層強化学習 • AlphaZero (DeepMind) が有名 • Neural Combinatorial Optimizationという名前でたくさんある •
グラフをGNNやtransformerでエンコーディング,次の点への推移を当 てるデコーダーで近似解 • 一様ユークリッドのランダム問題例での実験が多い • 小さな問題例での実験が多い • 比較対象がLKHなどのSOTA解法でなく,NNやFIなどが多い • 提案手法はGPU,比較対象はCPUが多い • SOTA解法の計算時間がおかしい(提案手法の時間にあわせてある)
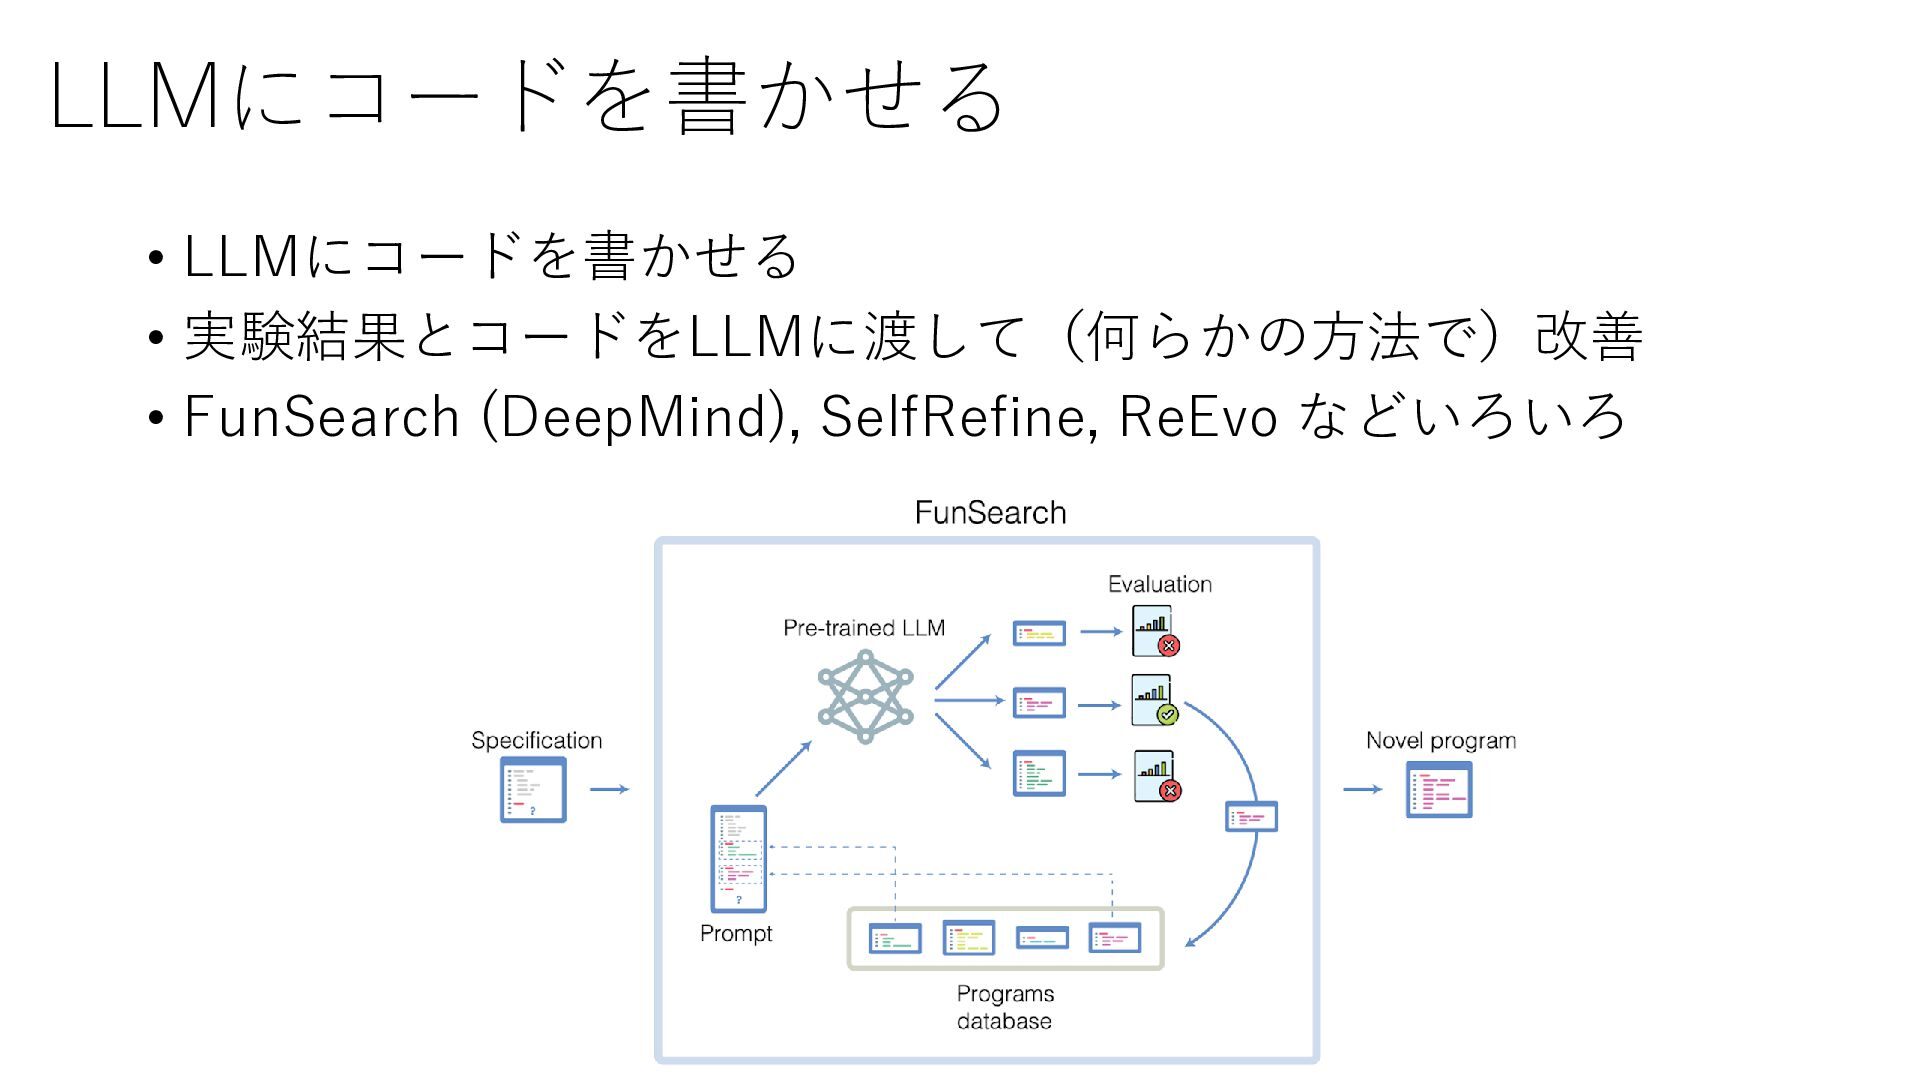
LLMにコードを書かせる • LLMにコードを書かせる • 実験結果とコードをLLMに渡して(何らかの方法で)改善 • FunSearch (DeepMind), SelfRefine, ReEvo
などいろいろ
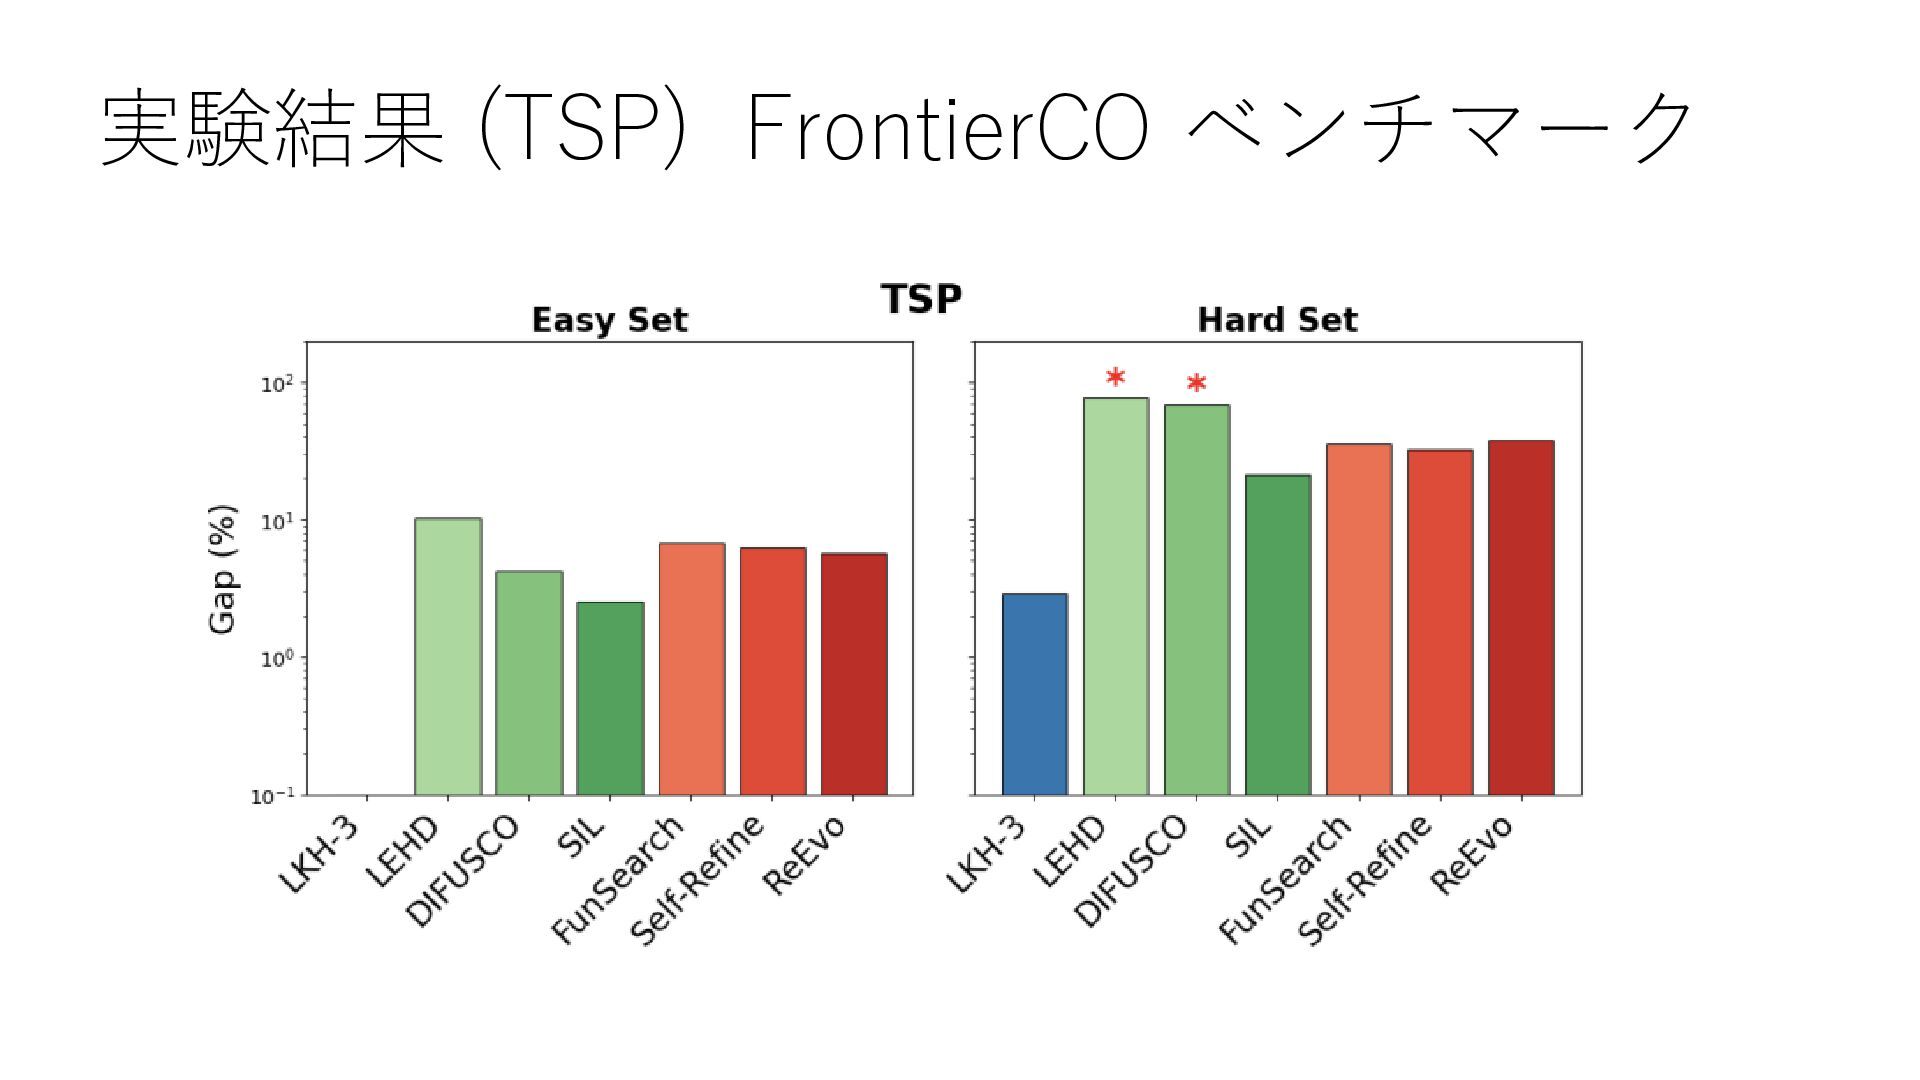
実験結果 (TSP) FrontierCO ベンチマーク
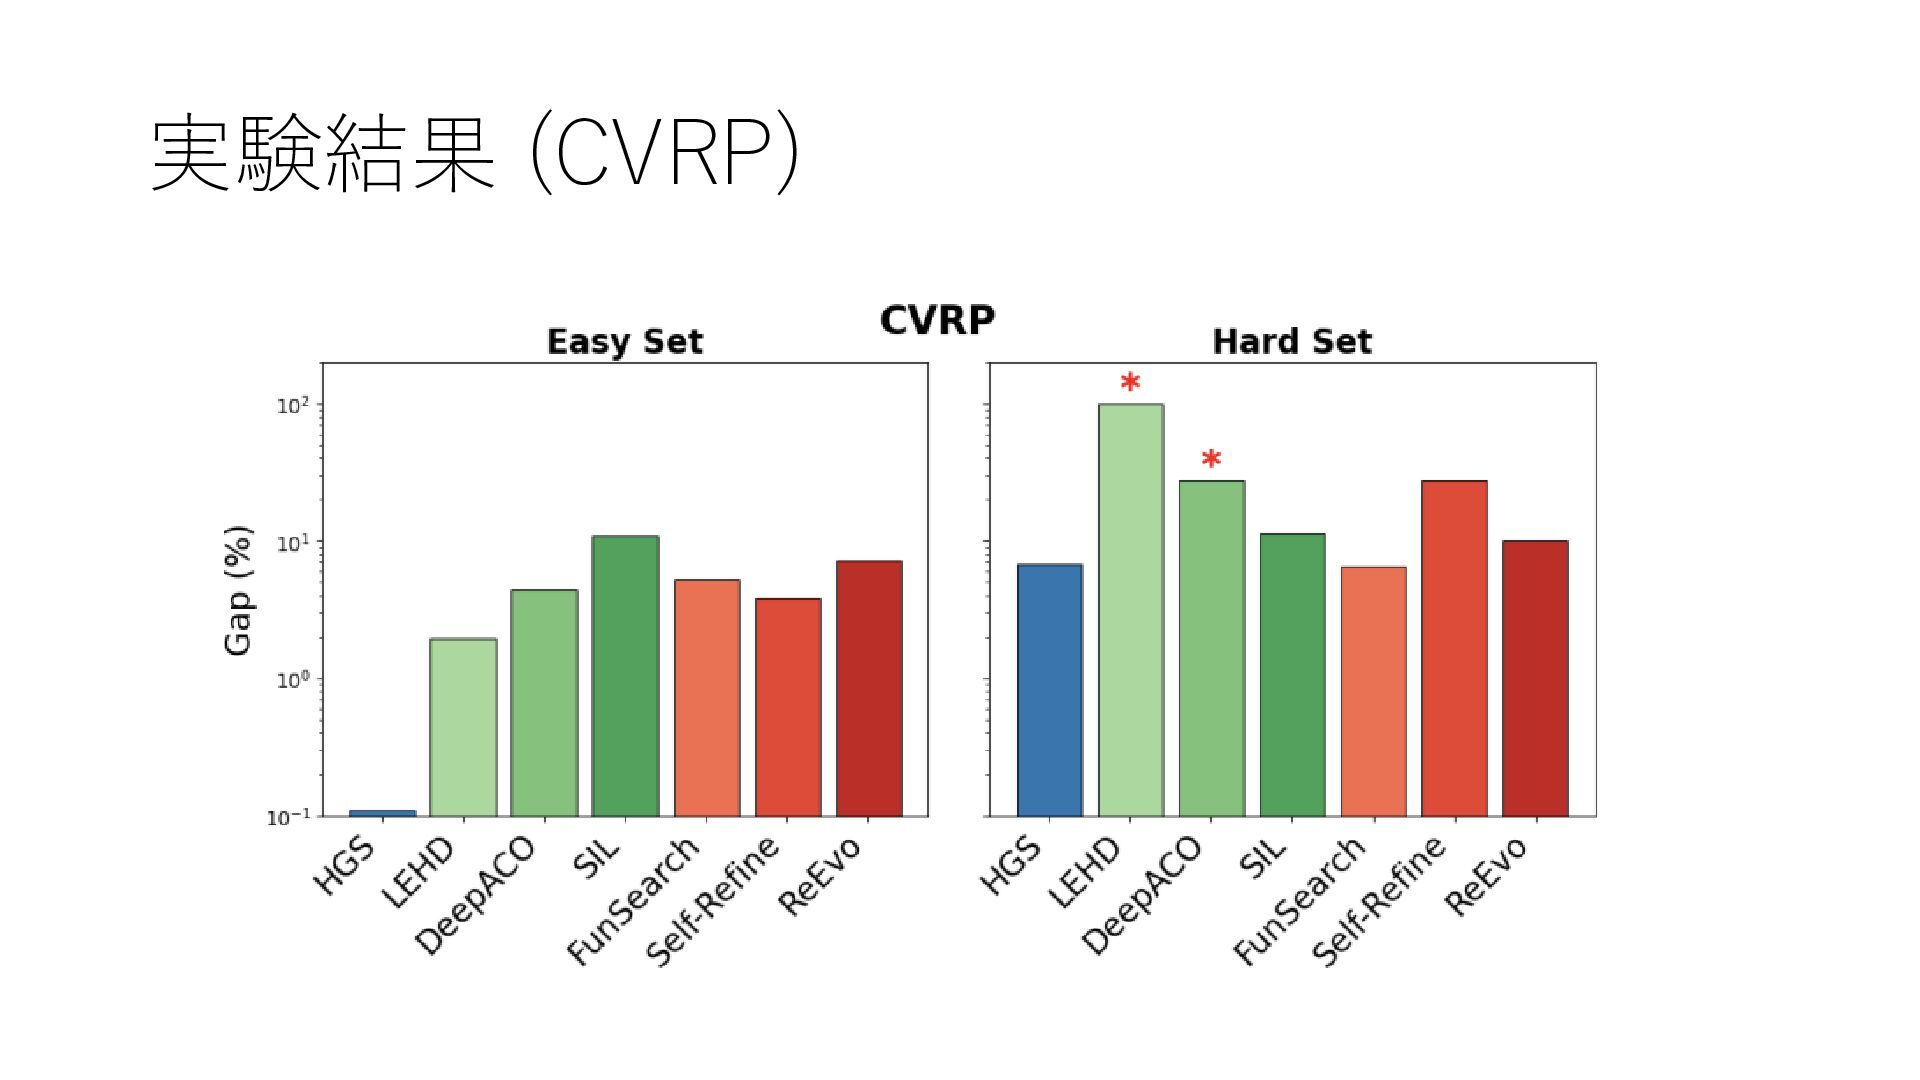
実験結果 (CVRP)
まとめ • AI は制約プログラミング (CP) だけではなくなってきている • 深層強化学習やLLMベースの研究は,実験が不十分 • 実験的解析の長い研究(1980-)を踏まえて再評価すべき
• 今のところ SOTA 解法にはかなわない • 自然言語からモデル抽出や,既存解法とLLMのハイブリッドが 正しい未来 • 過去の問題例が豊富にあれば,SOTA解法をさらに改善可能 (MOAIアプローチ)


 mickey_kubo
 takasehideki
 yukiar
 sokikatayama
 koheishinden
 stktu
 mickey_0226
 wataruuuuu
 butchi
 satai
 tsantalis
 sachag
 jonyablonski
 cargoodrich
 tammyeverts
 cromwellryan
 ammeep
 rocio
 axbom
 jdejongh
 aleyda
 baasie