Share
Embed
Fearless Deployment
Presented at 2016/06/28 at OpenCommerceConf.org, by Sean Schofield and Richard Lister (Spree Commerce).
Ric Lister
June 28, 2016
Transcript
36 slides
-
Background • Open Source • Consulting company • VC Backed
• Acquired by First Data in 2015 -
What are we afraid of? 1. The “Real World” 2.
Instability 3. Going Slow -
The “Real World” • Differences between staging and production •
Volume of data • Nature of data • Missing configuration -
Instability • Deployments cause most of the problems that impact
customers • Code being deployed as well as the deployment itself • Risk increases over time • External sources of instability -
Going slow • Speed of development ◦ We don’t want
stability at the expense of speed ◦ Whatever solution we come up with it will just slow us down • Intervals between deployments ◦ The longer we go between deploys, the more worried we are about the next one ◦ Migrations are more likely to fail ◦ We’re only making the problem worse by delaying our deployments -
Embracing the “Real World” • Two things keep us separated
from the “Real World” ◦ Application behavior ◦ User behavior • Let’s figure out a way to eliminate those differences • No more surprises when we deploy! -
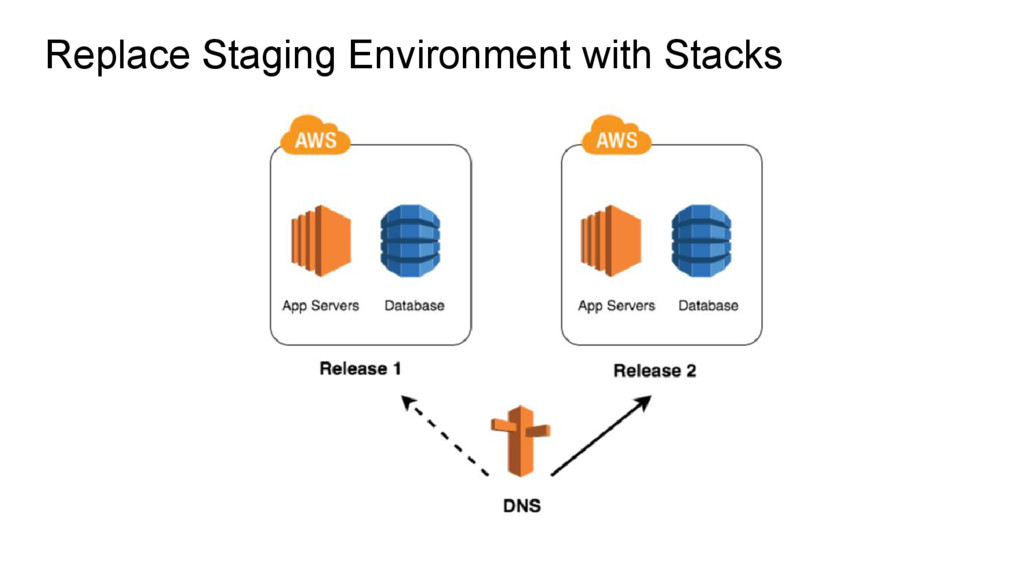
Use the stacks to go live • Each release is
done as a self-contained “stack” • No more staging environment • No more RAILS_ENV • Think release candidate for your infrastructure • No more surprises based on real world data -
Stop separating the test data • DynamoDB is designed for
massive amounts of data • Test data and live customer data can peacefully co-exist • Use a test attribute to identify our test records • Everything lives together in a single database! -
Stop using ActiveRecord • Learned things the hard way with
Spree • Really slow when doing a lot of writes • Use Plain Old Ruby Objects (PORO) instead • All of our tables have the same structure ◦ store_id ◦ object_id ◦ object_value -
Protect the real world data • No database write access
for developers • Only the store owner change their own data • No super admin • Impossible for developers to change data while testing • Ensure no real world side effects whenever we write data -
Complete copy of the database • Every stack has a
complete database copy • Migrations are performed at the same time as copy • Shoryuken workers for multi-threaded processing • We can copy 500,000 records in under ten minutes -
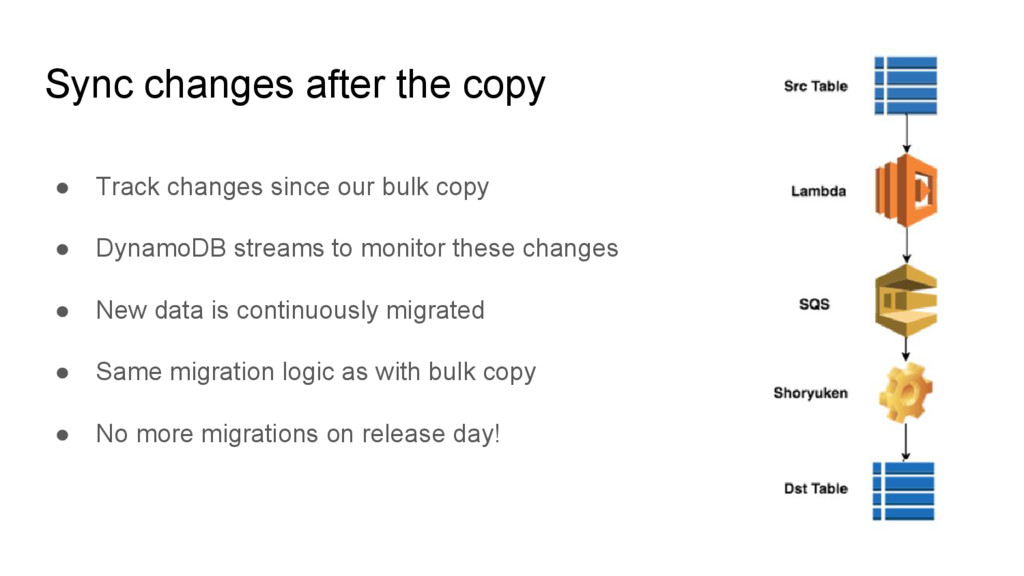
Sync changes after the copy • Track changes since our
bulk copy • DynamoDB streams to monitor these changes • New data is continuously migrated • Same migration logic as with bulk copy • No more migrations on release day! -
Ops Code as First Class Citizen • Infrastructure must be
change-controlled and repeatable • Operations source-code is in same git repo as application code • Every release is tracked as a single SHA in Github • Check out a SHA to get a fully self-contained ops+app setup • We use AWS Cloudformation templates to describe all resources -
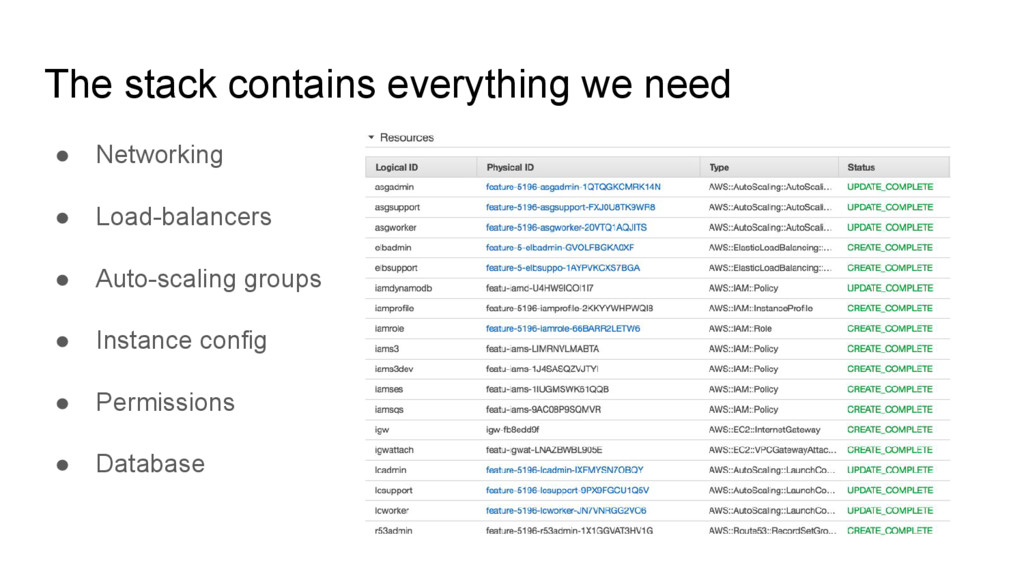
The stack contains everything we need • Networking • Load-balancers
• Auto-scaling groups • Instance config • Permissions • Database -
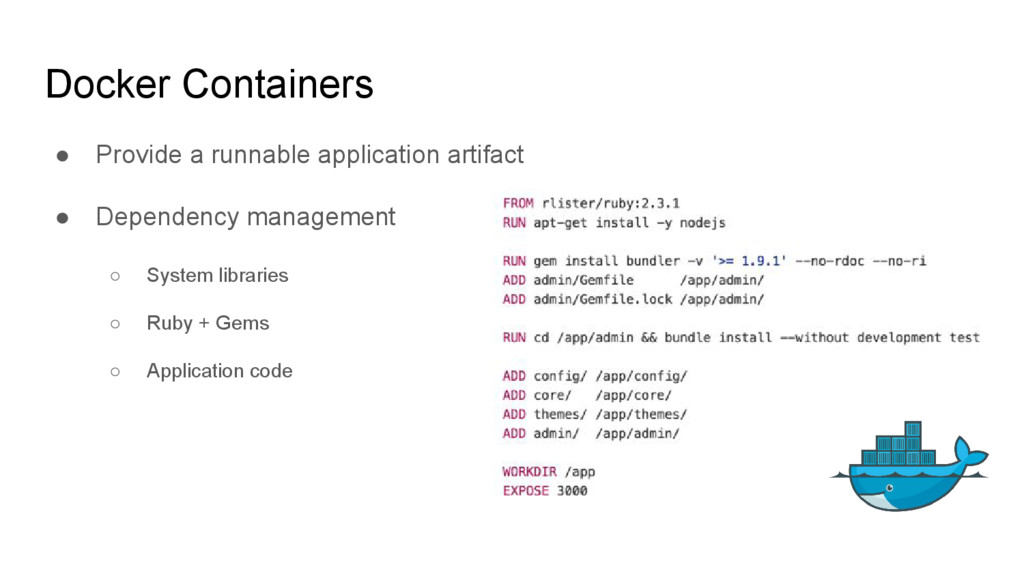
Docker Containers • Provide a runnable application artifact • Dependency
management ◦ System libraries ◦ Ruby + Gems ◦ Application code -
Docker Decouples Application from OS • Protect against changes in
the underlying OS, which just provides: ◦ Kernel ◦ Docker daemon ◦ Systemd, to start containers • We are safer making OS updates ◦ Updates to system libraries do not affect application -
Amazon Machine Image • AMI provides a runnable server artifact
◦ We get the same artifact every time • What if Docker repository goes down? ◦ Create AMI with packer and bake in all docker images ◦ We’re happy to trade AMI build time for stability • What if Github or rubygems are down? ◦ Instance needs no external information to start app -
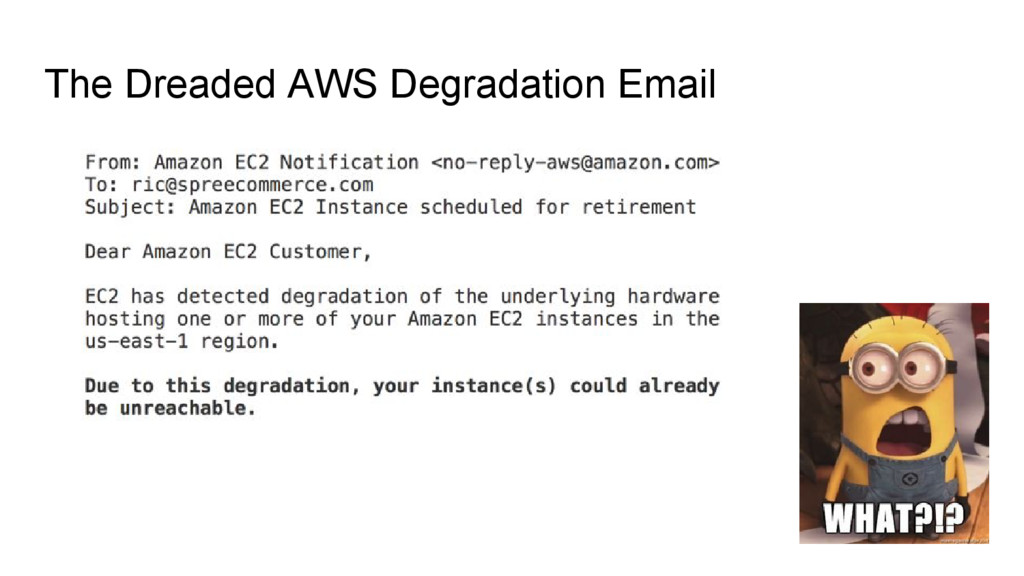
Auto Scaling • Stop caring about individual instances • Autoscaling
replaces failed instances • We trust replacement because we do it all the time • Copy easily with changing load -
Release Procedure • Tag branch in git • Build docker
container • Build AMI • Create stack • Copy data from production • Sync new data from production • Test, test, test • Update DNS • Delete old stack -
Immutable once we go live • New releases require a
new stack • Emergency hotfixes require a new AMI • Instances are replaced, not modified • Once deployed nothing can be changed • There is no SSH -
Continuous Deployment for Developers • We deploy many times a
day - just not to production ◦ Devs get a stack for each feature branch, with a full copy of production data ◦ Go crazy, break things, it will be entirely deleted when done • Docker lets us build image fast ◦ We don’t want to wait for a brand new AMI with each commit ◦ Write Dockerfile to use caching in a smart way • Dev stacks can be deployed by just replacing docker image -
Argus for Fast Docker Builds • Enqueue docker builds using
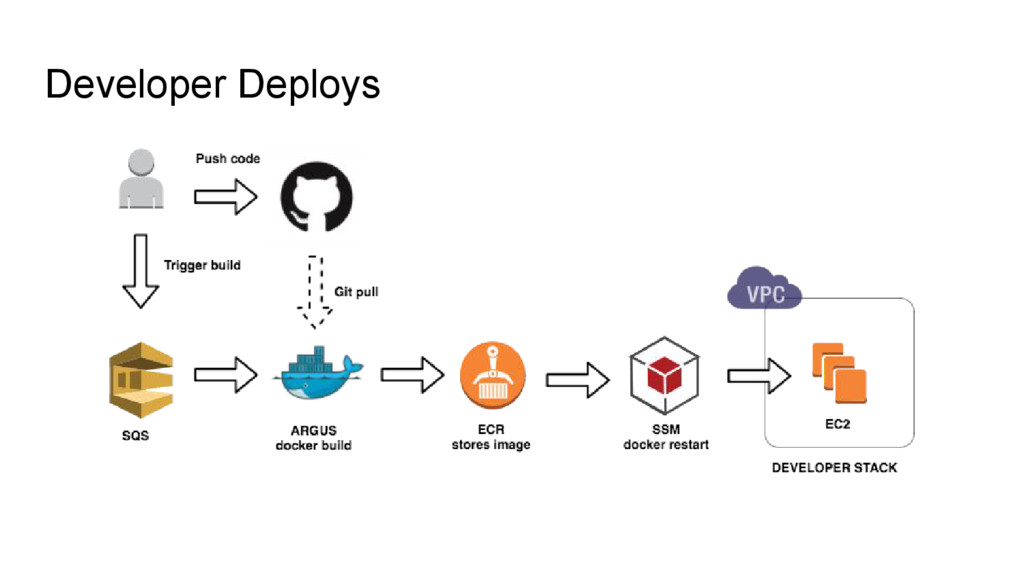
SQS • Distributed workers for fast builds • Workers pre-pull existing image layers • This means all workers can use docker cache • Pushes image to AWS EC2 Container Registry github.com/rlister/argus -
Developer Deploys Are Fast • If the bundle is cached,
docker build takes about 15 seconds • AWS SSM Run Command runs a canned script • Simply pulls latest docker image and restarts container • Access is controlled with IAM • Logs are in logstash -
Summary • All infrastructure and code is in the stack
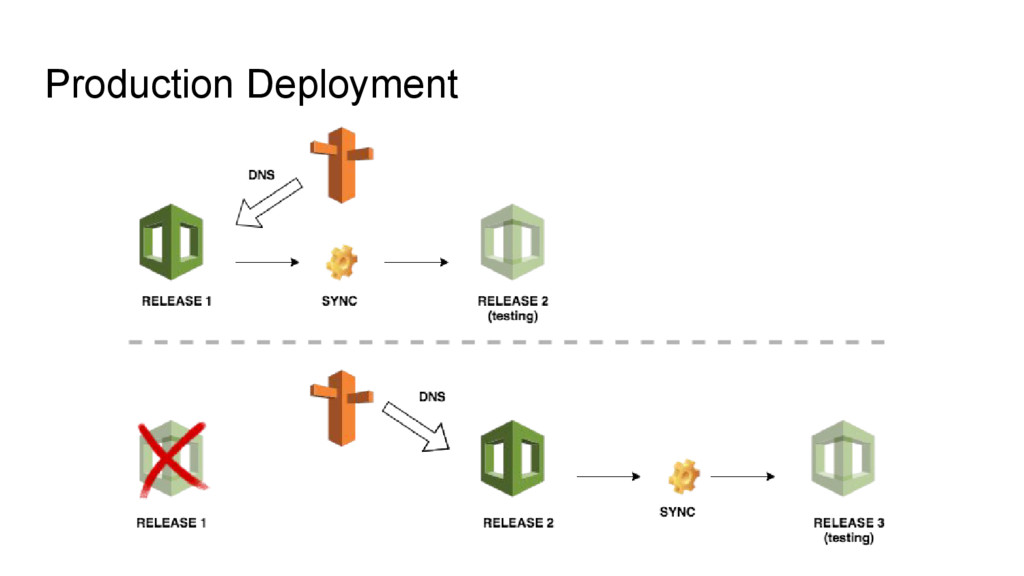
• The stack is immutable • We use stacks instead of a having a special staging environment • We use a complete copy of real world data in our stacks • We’re constantly deploying - just not to production • Production deploys are just updating the DNS to the new stack -
Resources • github.com/solnic/virtus - Ruby library for PORO • github.com/phstc/shoryuken
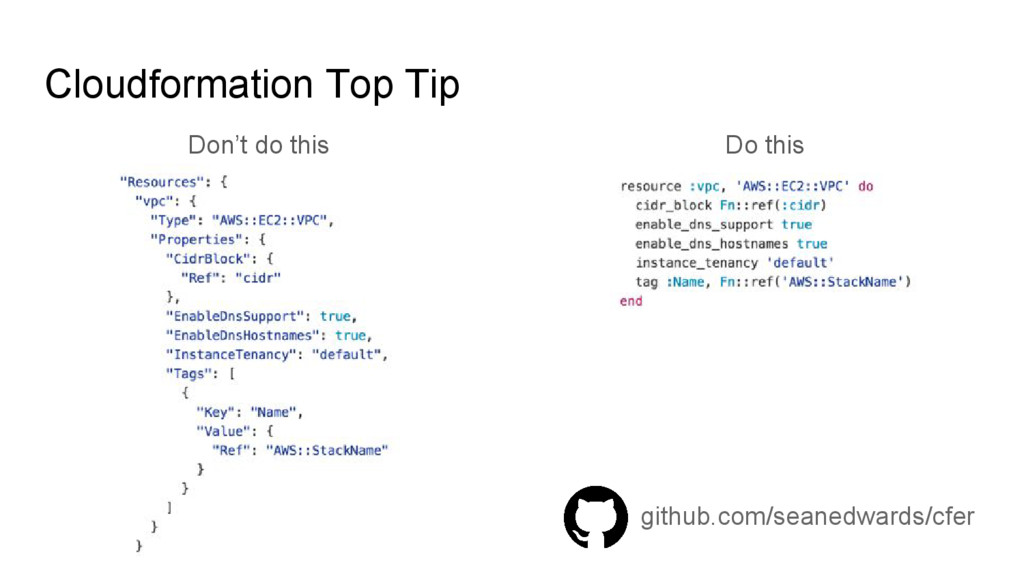
- asynchronous Ruby workers with SQS • github.com/rlister/argus - fast Docker build and push to ECR • github.com/rlister/awful - Ruby library for common stack operations • github.com/seanedwards/cfer - Ruby DSL for Cloudformation templates • 12factor.net - guidelines for stateless software as a service