Share
Embed
Transcript
27 slides
-
목차 목차 1. Problem Definition 1. Metric Learning 2. Previous
Approaches 2. The Proposed Method 1. Contributions 2. Symmetrical Synthesis 3. Results and Discussion 1. Experimental Setting 2. Experimental Results -
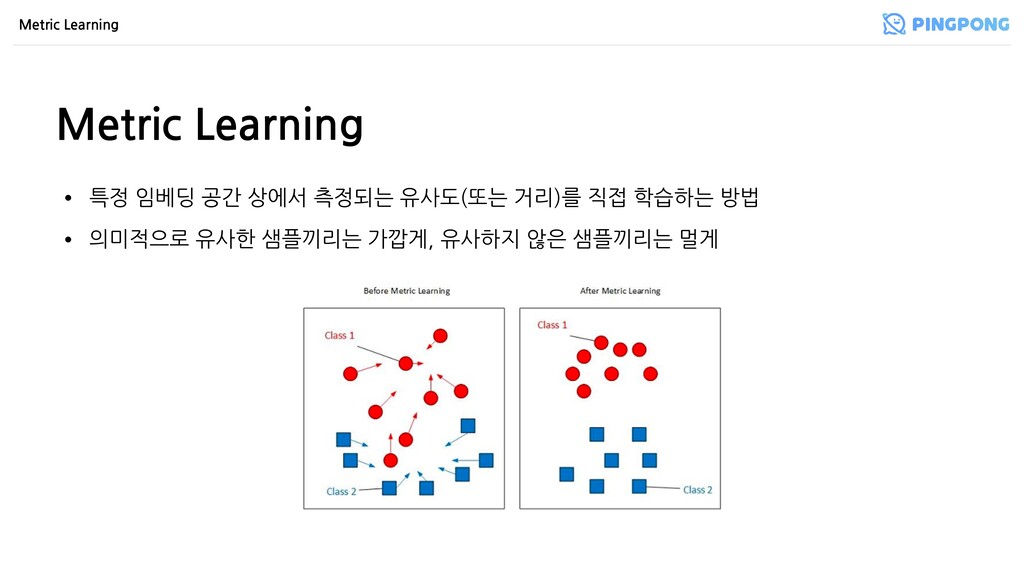
Metric Learning Metric Learning • 특정 임베딩 공간 상에서 측정되는
유사도(또는 거리)를 직접 학습하는 방법 • 의미적으로 유사한 샘플끼리는 가깝게, 유사하지 않은 샘플끼리는 멀게 -
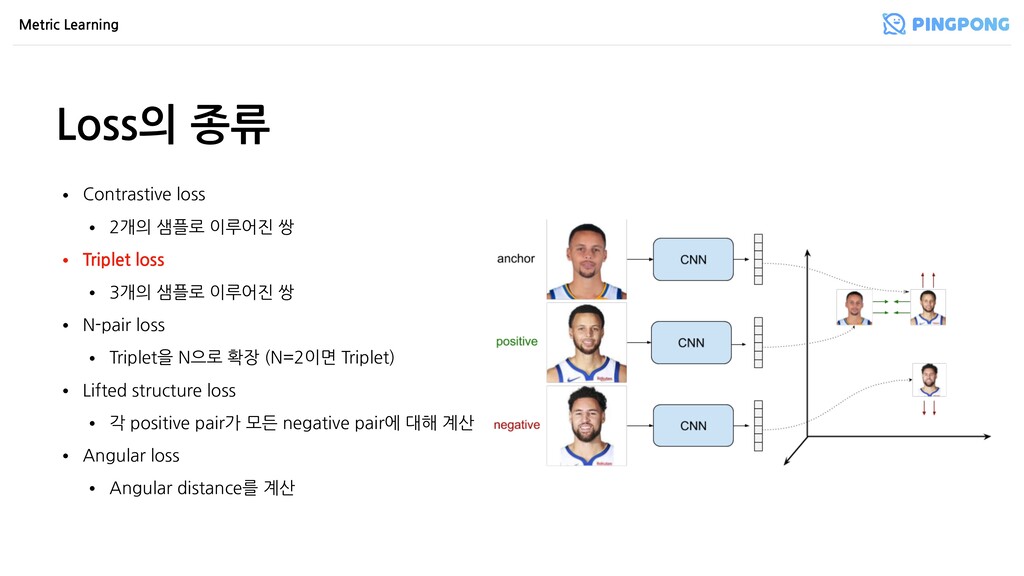
Loss의 종류 Metric Learning • Contrastive loss • 2개의 샘플로
이루어진 쌍 • Triplet loss • 3개의 샘플로 이루어진 쌍 • N-pair loss • Triplet을 N으로 확장 (N=2이면 Triplet) • Lifted structure loss • 각 positive pair가 모든 negative pair에 대해 계산 • Angular loss • Angular distance를 계산 -
Hard Negative Pair Mining Previous Approaches • Offline • 이전에
학습된 모델이 고른 hard negative에 대해 iterative fine-tune • Online • 배치 별로 가장 어려운(hardest) P-N pair 선택 • Semi-hard • 너무 어려우면 오히려 noise가 될 수 있으니 적당히 어려운 걸 고르자 문제: 선택된 소수의 샘플만 고려하므로 bias가 생길 가능성 -
Hard Sample Generation Previous Approaches • 많은 수의 easy negatives를
이용해 hard negative를 직접 생성 • Deep adversarial metric learning (DAML) • GAN을 사용해 hard negative, hard triplet 생성 • Hardness-aware deep metric learning (HDML) • AE 사용해 P-P or N-N 샘플 만들고 난이도 조절 가능 문제: 추가적인 네트워크 구조 필요 → 학습 시간↑, GAN은 학습도 어려움 -
Contributions Contributions • Main idea: 대수적 계산만으로 hard negative 샘플을
만들자! - 장점 1. Hyperparameter-free 2. Plug-and-play 기존 네트워크 구조를 바꿀 필요가 없기 때문 3. 학습 속도와 학습 난이도에 영향 X -
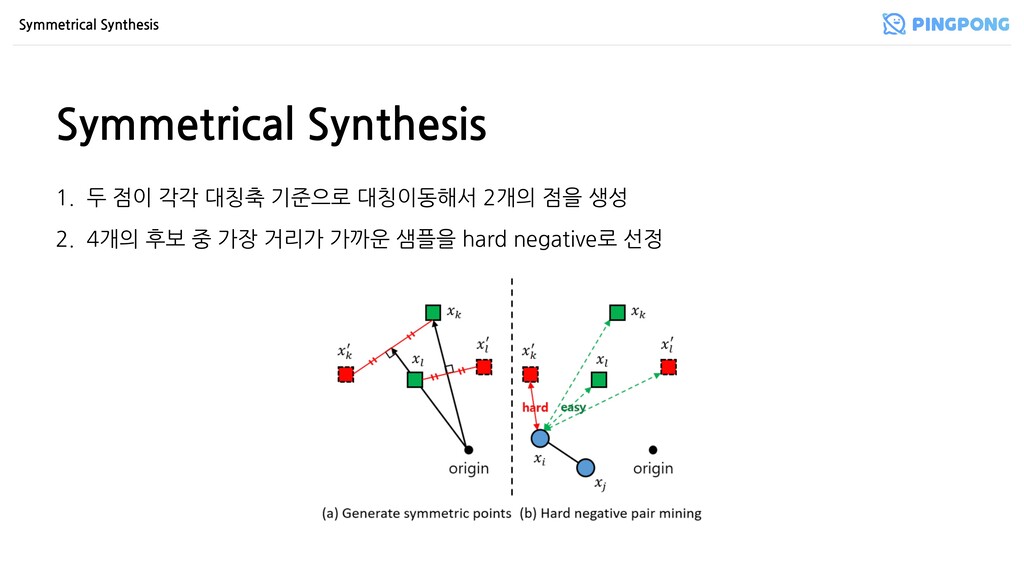
Symmetrical Synthesis Symmetrical Synthesis 1. 두 점이 각각 대칭축 기준으로
대칭이동해서 2개의 점을 생성 2. 4개의 후보 중 가장 거리가 가까운 샘플을 hard negative로 선정 -
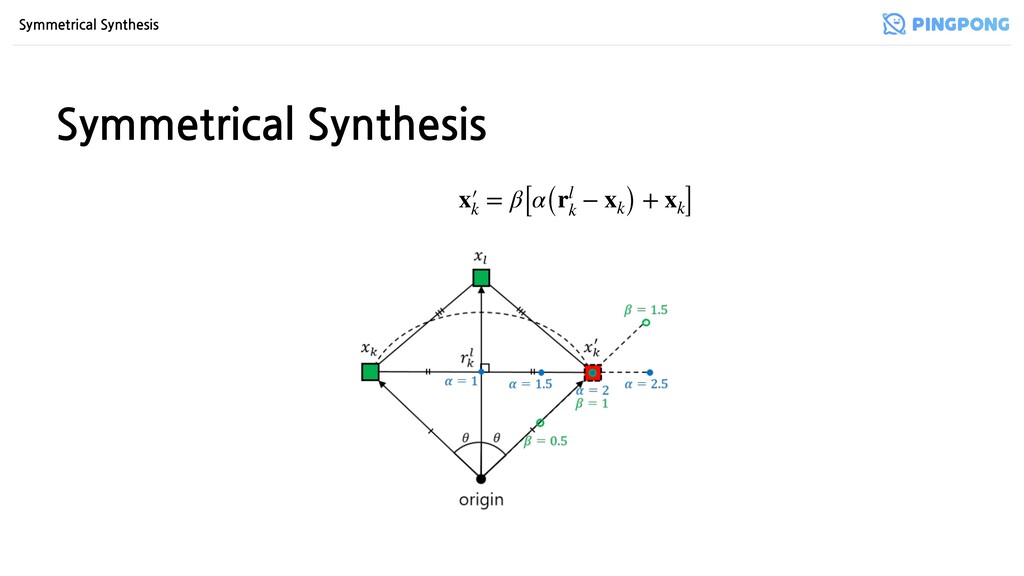
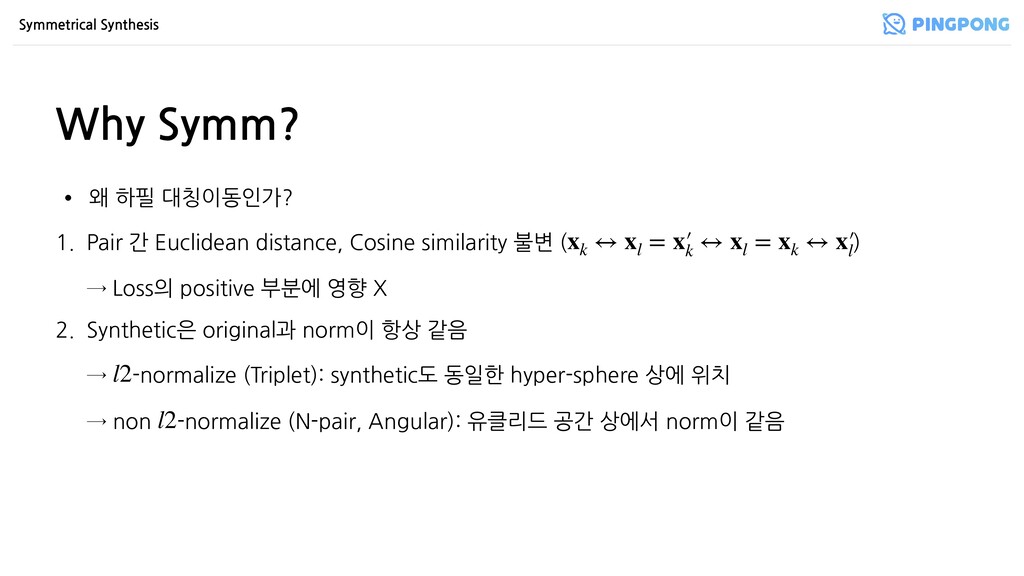
Why Symm? Symmetrical Synthesis • 왜 하필 대칭이동인가? 1. Pair
간 Euclidean distance, Cosine similarity 불변 ( ) → Loss의 positive 부분에 영향 X 2. Synthetic은 original과 norm이 항상 같음 → -normalize (Triplet): synthetic도 동일한 hyper-sphere 상에 위치 → non -normalize (N-pair, Angular): 유클리드 공간 상에서 norm이 같음 xk ↔ xl = x′ k ↔ xl = xk ↔ x′ l l2 l2 -
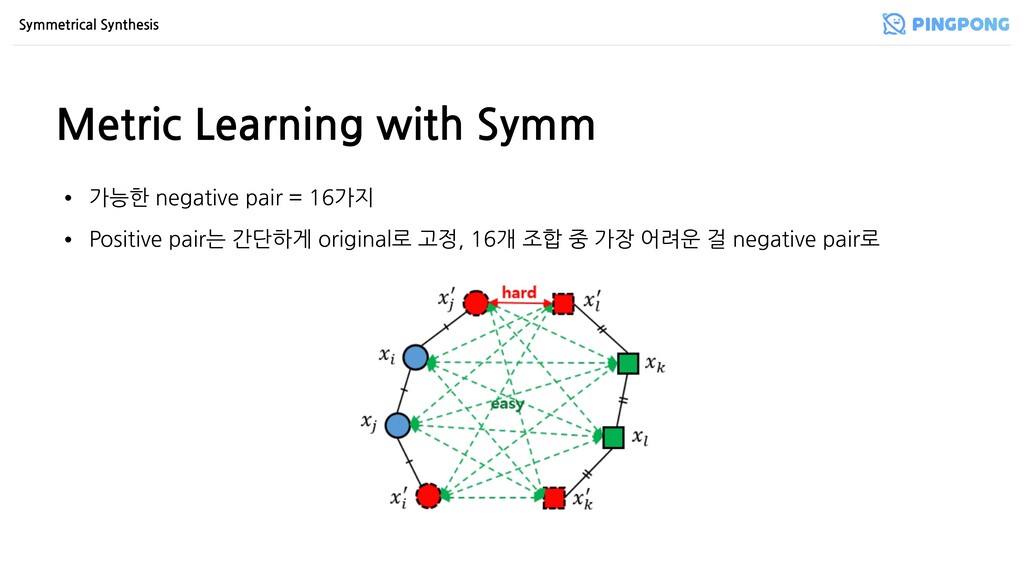
Metric Learning with Symm Symmetrical Synthesis • 가능한 negative pair
= 16가지 • Positive pair는 간단하게 original로 고정, 16개 조합 중 가장 어려운 걸 negative pair로 -
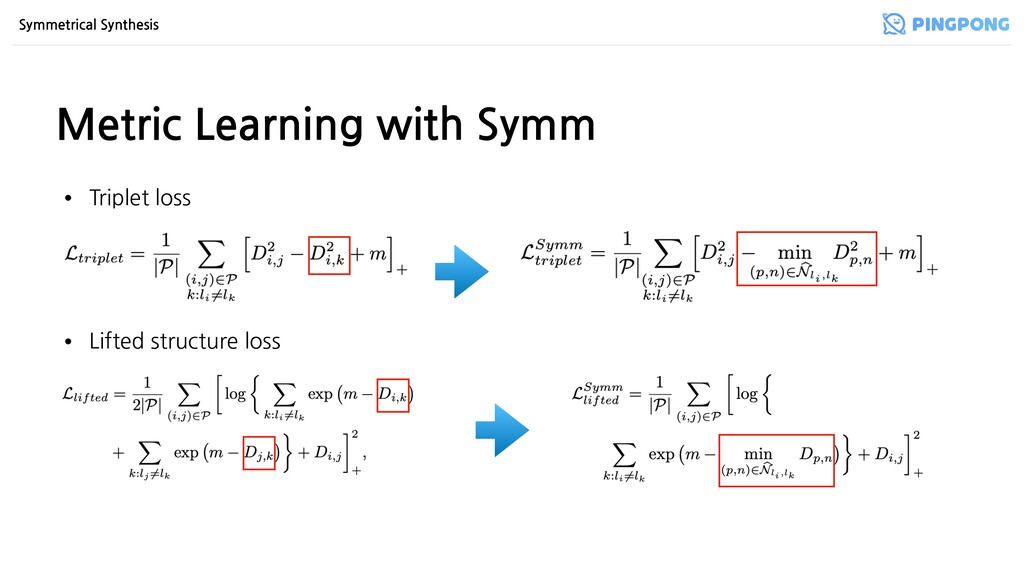
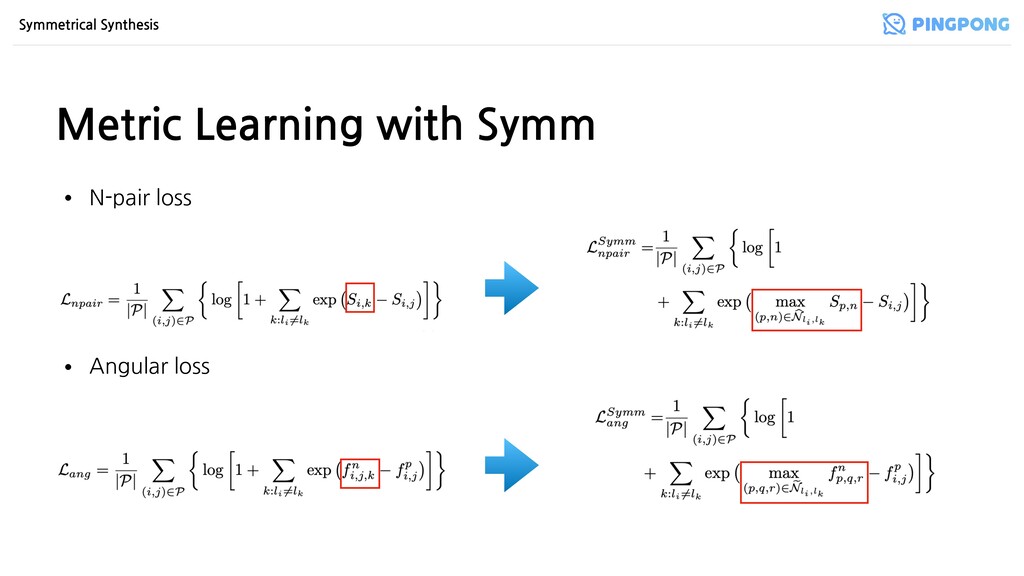
Metric Learning with Symm Symmetrical Synthesis • Triplet loss •
Lifted structure loss -
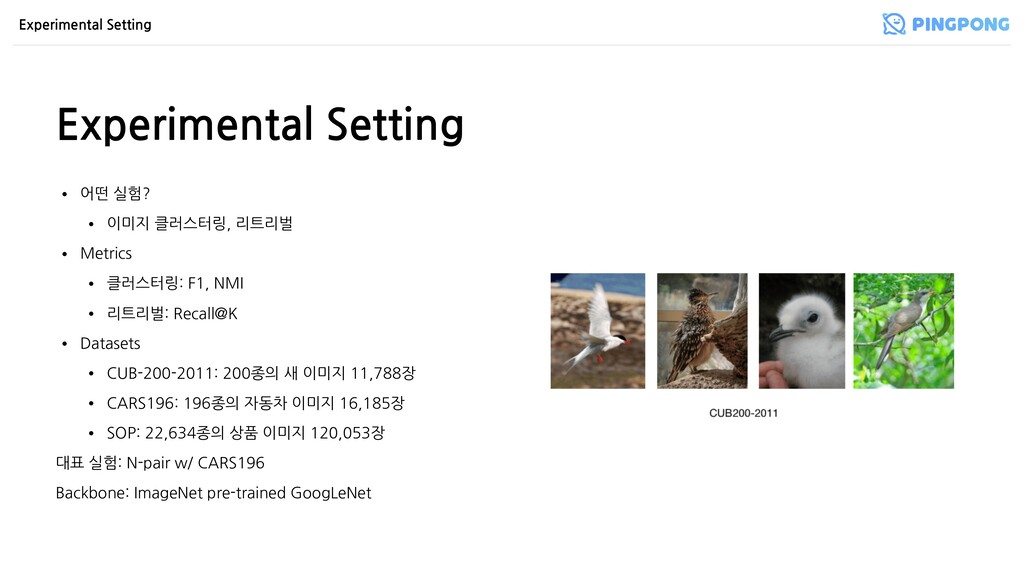
Experimental Setting Experimental Setting • 어떤 실험? • 이미지 클러스터링,
리트리벌 • Metrics • 클러스터링: F1, NMI • 리트리벌: Recall@K • Datasets • CUB-200-2011: 200종의 새 이미지 11,788장 • CARS196: 196종의 자동차 이미지 16,185장 • SOP: 22,634종의 상품 이미지 120,053장 대표 실험: N-pair w/ CARS196 Backbone: ImageNet pre-trained GoogLeNet -
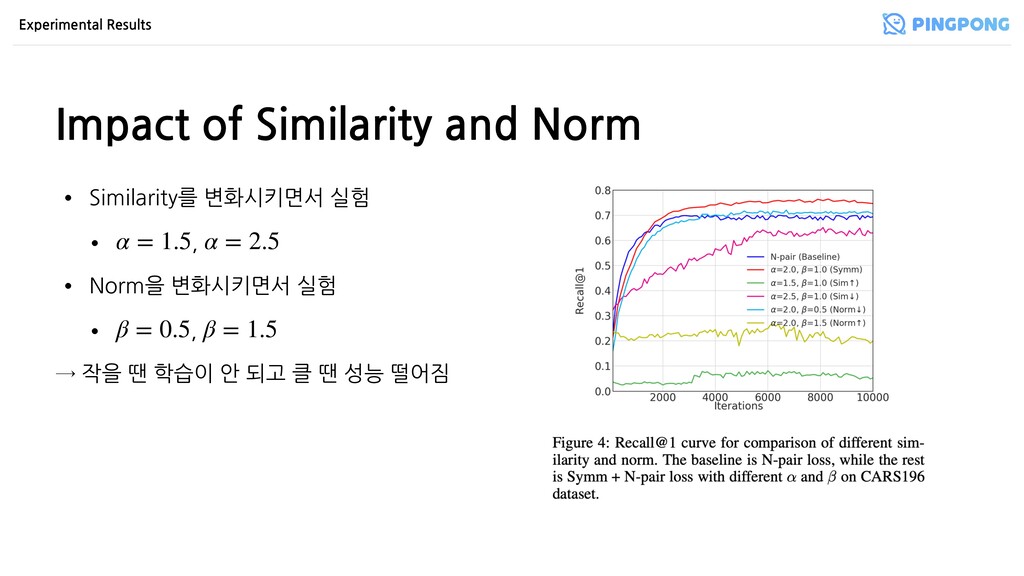
Impact of Similarity and Norm Experimental Results • Similarity를 변화시키면서
실험 • , • Norm을 변화시키면서 실험 • , → 작을 땐 학습이 안 되고 클 땐 성능 떨어짐 α = 1.5 α = 2.5 β = 0.5 β = 1.5 -
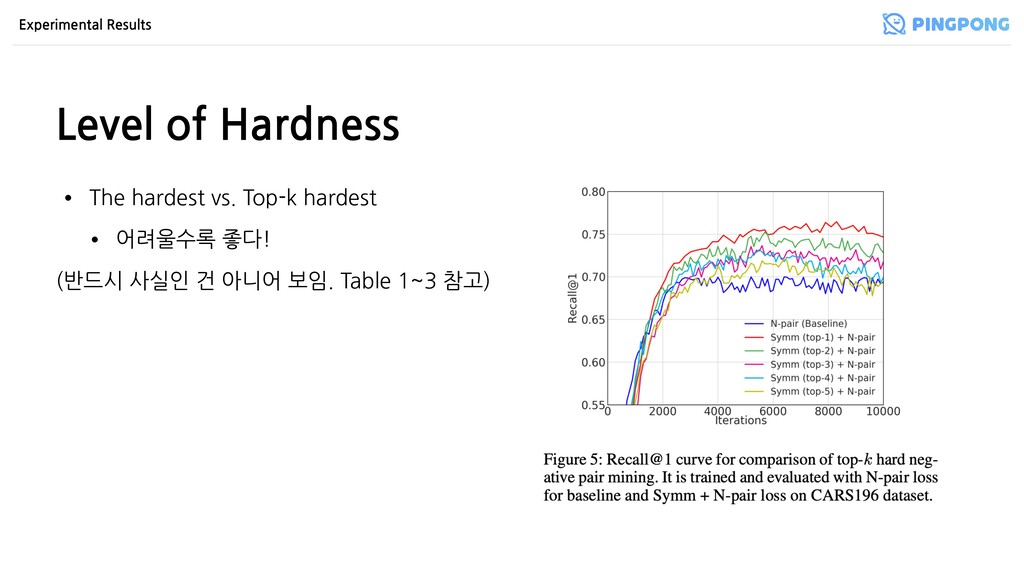
Level of Hardness Experimental Results • The hardest vs. Top-k
hardest • 어려울수록 좋다! (반드시 사실인 건 아니어 보임. Table 1~3 참고) -
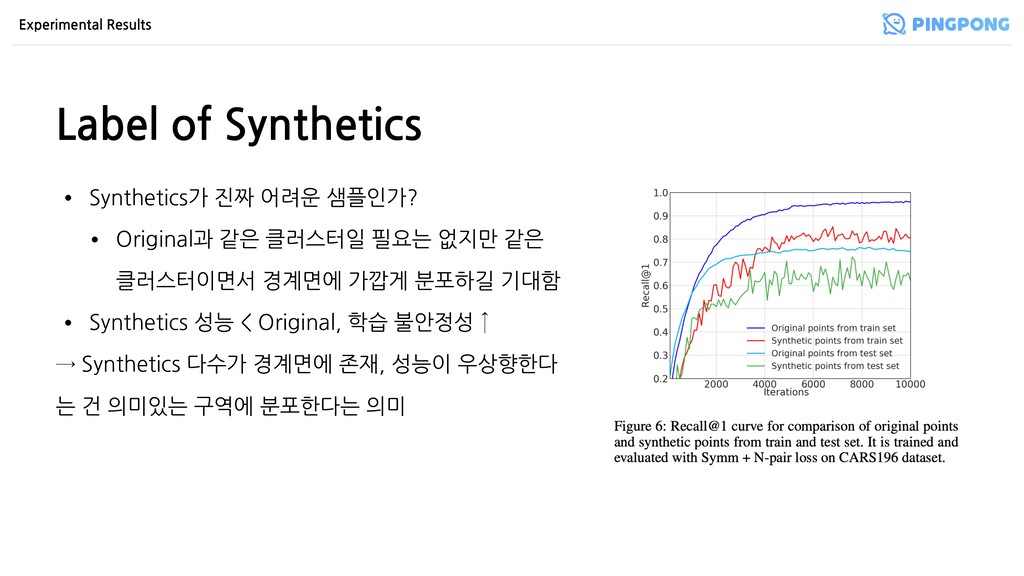
Label of Synthetics Experimental Results • Synthetics가 진짜 어려운 샘플인가?
• Original과 같은 클러스터일 필요는 없지만 같은 클러스터이면서 경계면에 가깝게 분포하길 기대함 • Synthetics 성능 < Original, 학습 불안정성 ↑ → Synthetics 다수가 경계면에 존재, 성능이 우상향한다 는 건 의미있는 구역에 분포한다는 의미 -
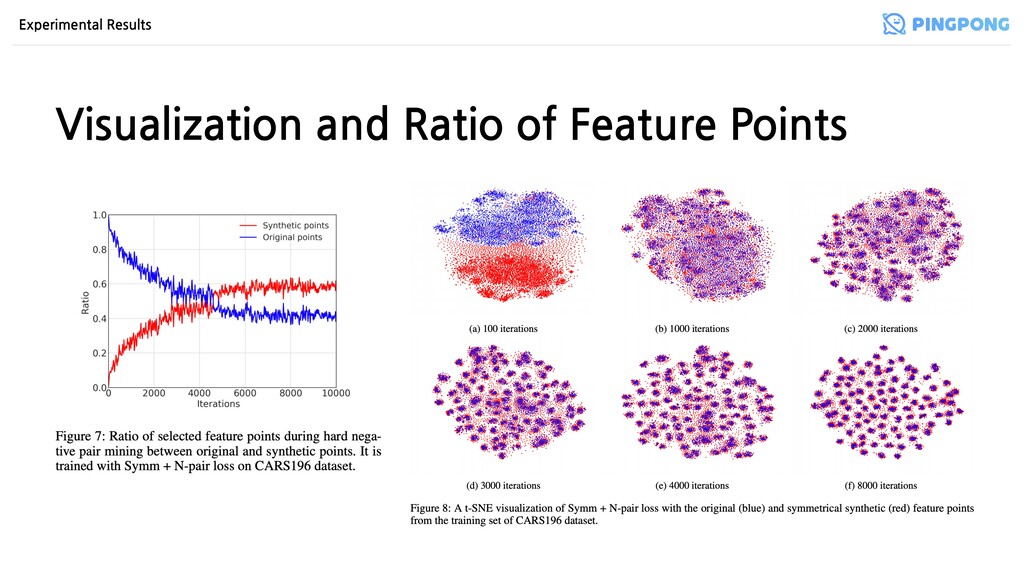
Visualization and Ratio of Feature Points Experimental Results • 학습이
진행될수록 생성된 샘플이 negative sample로 선택되는 비율 • 학습 과정 시각화 by t-SNE → 처음에는 같은 클래스 샘플끼리 가깝지 않으니 의미 없는 synthetics가 만들어지다가 점점 클러 스터 경계면에 분포하도록 만들어지면서 hard negative의 역할을 함 -
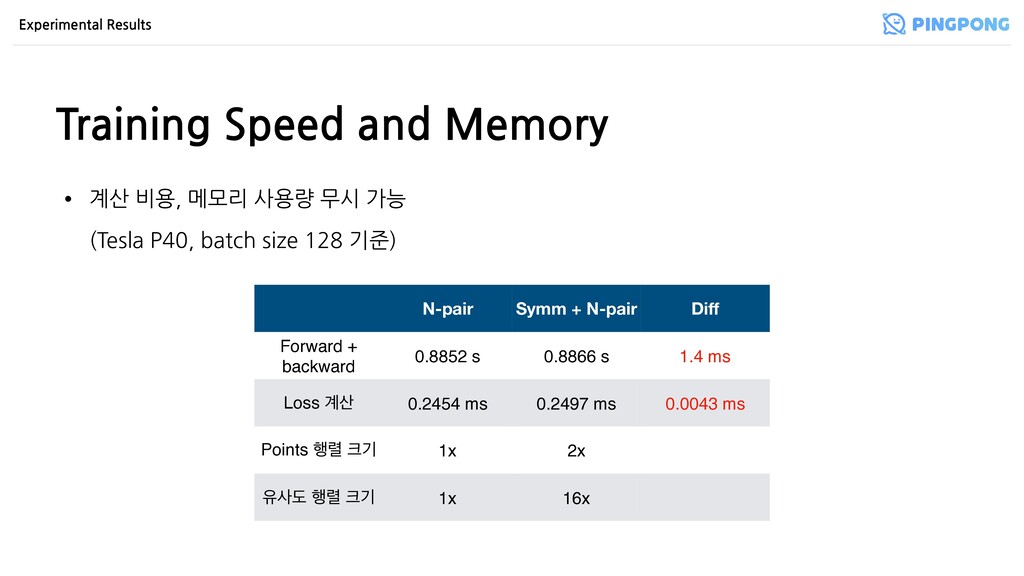
Training Speed and Memory Experimental Results • 계산 비용, 메모리
사용량 무시 가능 (Tesla P40, batch size 128 기준) N-pair Symm + N-pair Diff Forward + backward 0.8852 s 0.8866 s 1.4 ms Loss ҅ 0.2454 ms 0.2497 ms 0.0043 ms Points ೯۳ ӝ 1x 2x ਬࢎب ೯۳ ӝ 1x 16x -
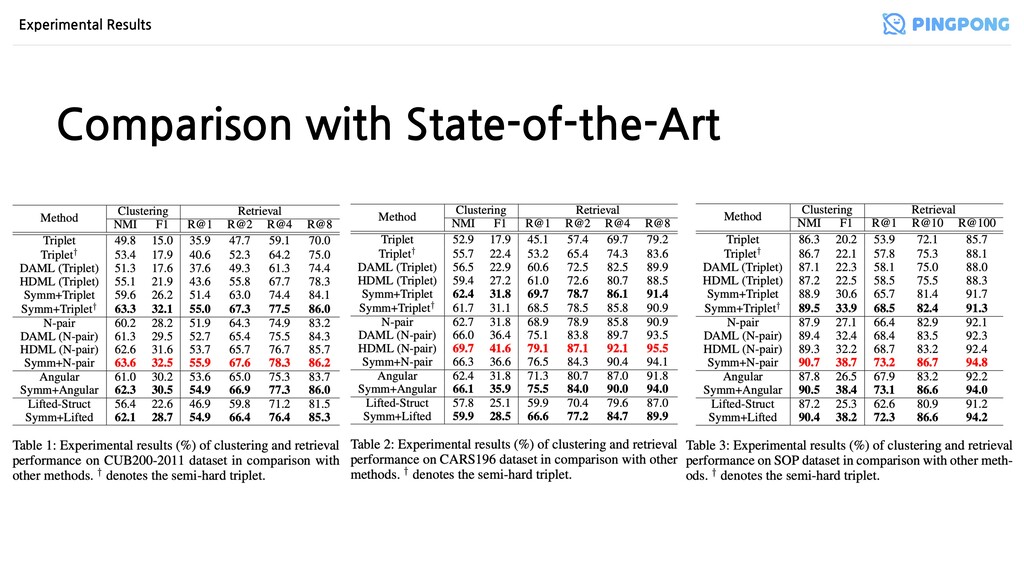
Comparison with State-of-the-Art Experimental Results • 거의 모든 loss와 dataset에서
더 좋은 성능 → Euclidean + normalization을 하는 loss (triplet, lifted structure)와 Cos-sim + non- 인 loss (N-pair, angular)에 모두 적용 가능 • 다른 sample generation 방식(DAML, HDML)은 큰 데이터셋(SOP)에서 성능 향상폭 ↓ → 반면 Symm은 데이터셋 크기에 상관 없이 성능 향상폭 ↑ (심지어 CARS196에서 HDML이 이긴 것도 공정한 비교를 위해 하이퍼파라미터 튜닝을 안 했기 때문) l2 l2 -
감사합니다✌ 추가 질문 또는 궁금한 점이 있다면 언제든 아래 연락처로
연락 주세요! 장성보 (ML Research Scientist, Pingpong) [email protected]