Share
Embed
Transcript
51 slides
-
Handling Large Data with Python Jill Cates Senior Data Scientist
at Shopify PyCon Italia | May 2024 -
What kind of data? In scope for this presentation Data
can come in many different forms: • Tabular (dataframes) • Images • N-dimensional arrays • Time-series data • Audio and video • Graphical structures -
What kind of data? An example of a tabular dataframe
member_id name age height 1 Joe 47 194 2 Cindy 32 168 3 Roman 11 161 4 Lucy 26 173 Rows = samples Columns = attributes / features -
Data have two possible states In motion ETL pipelines Batch
or streaming processed Examples: Apache Spark, Flink, Beam What kind of data? At rest Lives in data warehouse or static iles (e.g., csv, tsv, excel, etc.) Exploratory data analysis -
Data have two possible states In motion ETL pipelines Batch
or streaming processed Examples: Apache Spark, Flink, Beam What kind of data? At rest Lives in data warehouse or static iles (e.g., csv, tsv, excel, etc.) Exploratory data analysis -
Data operations can happen on two types of systems Single
Node Data exploration and ML modelling Less overhead What kind of system? Ideal for running tasks in parallel High overhead Distributed -
Data operations can happen on two types of systems Single
Node Data exploration and ML modelling Less overhead What kind of system? Ideal for running tasks in parallel High overhead Distributed -
Python packages for large data Polars • Pandas • Polars
• DuckDB • Vaex • Dask • Modin -
Pandas v1 • Created in 2008 by Wes McKinney •
Built around “data frames” and “series” data structures • Represented as NumPy arrays behind the scenes pandas.DataFrame pandas.Series Overview -
• Great option for manipulating and analyzing relatively small datasets
! Rule of thumb: have 5 to 10 times as much RAM as the size of your dataset • Very strong community, works well with many other libraries (e.g., seaborn, matplotlib, scikit-learn) Pandas v1 Overview -
1) Only load the columns that you care about 2)
Specify column data types when loading data 3) Down-cast integers and loats 4) Filter irst before merging or aggregating 5) Avoid for loops at all costs 6) Serialize your data Optimization Tips Pandas v1 -
1) Reduce memory by only loading the columns that you
care about Reduces dataframe size by 75% " Original size: 203.8+ MB Optimization Tips Pandas v1 -
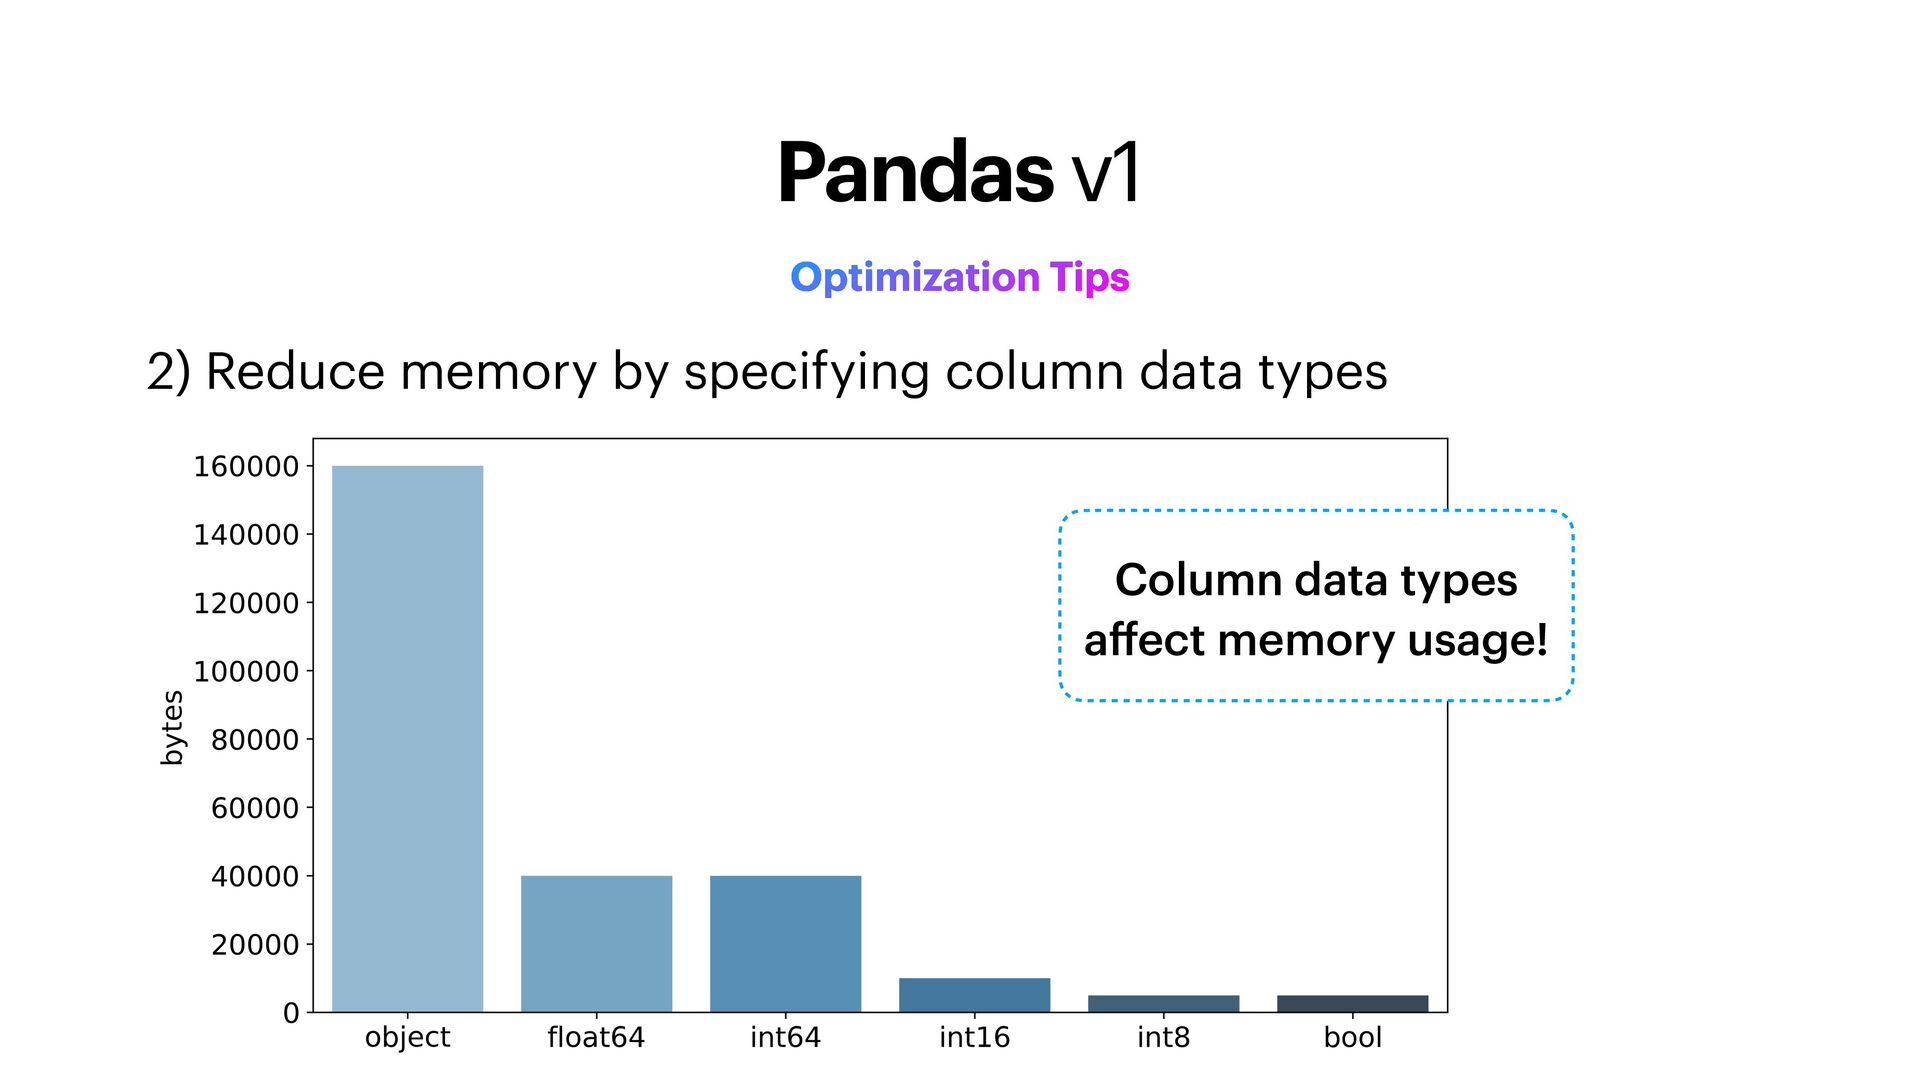
2) Reduce memory by specifying column data types Optimization Tips
Pandas v1 Column data types affect memory usage! -
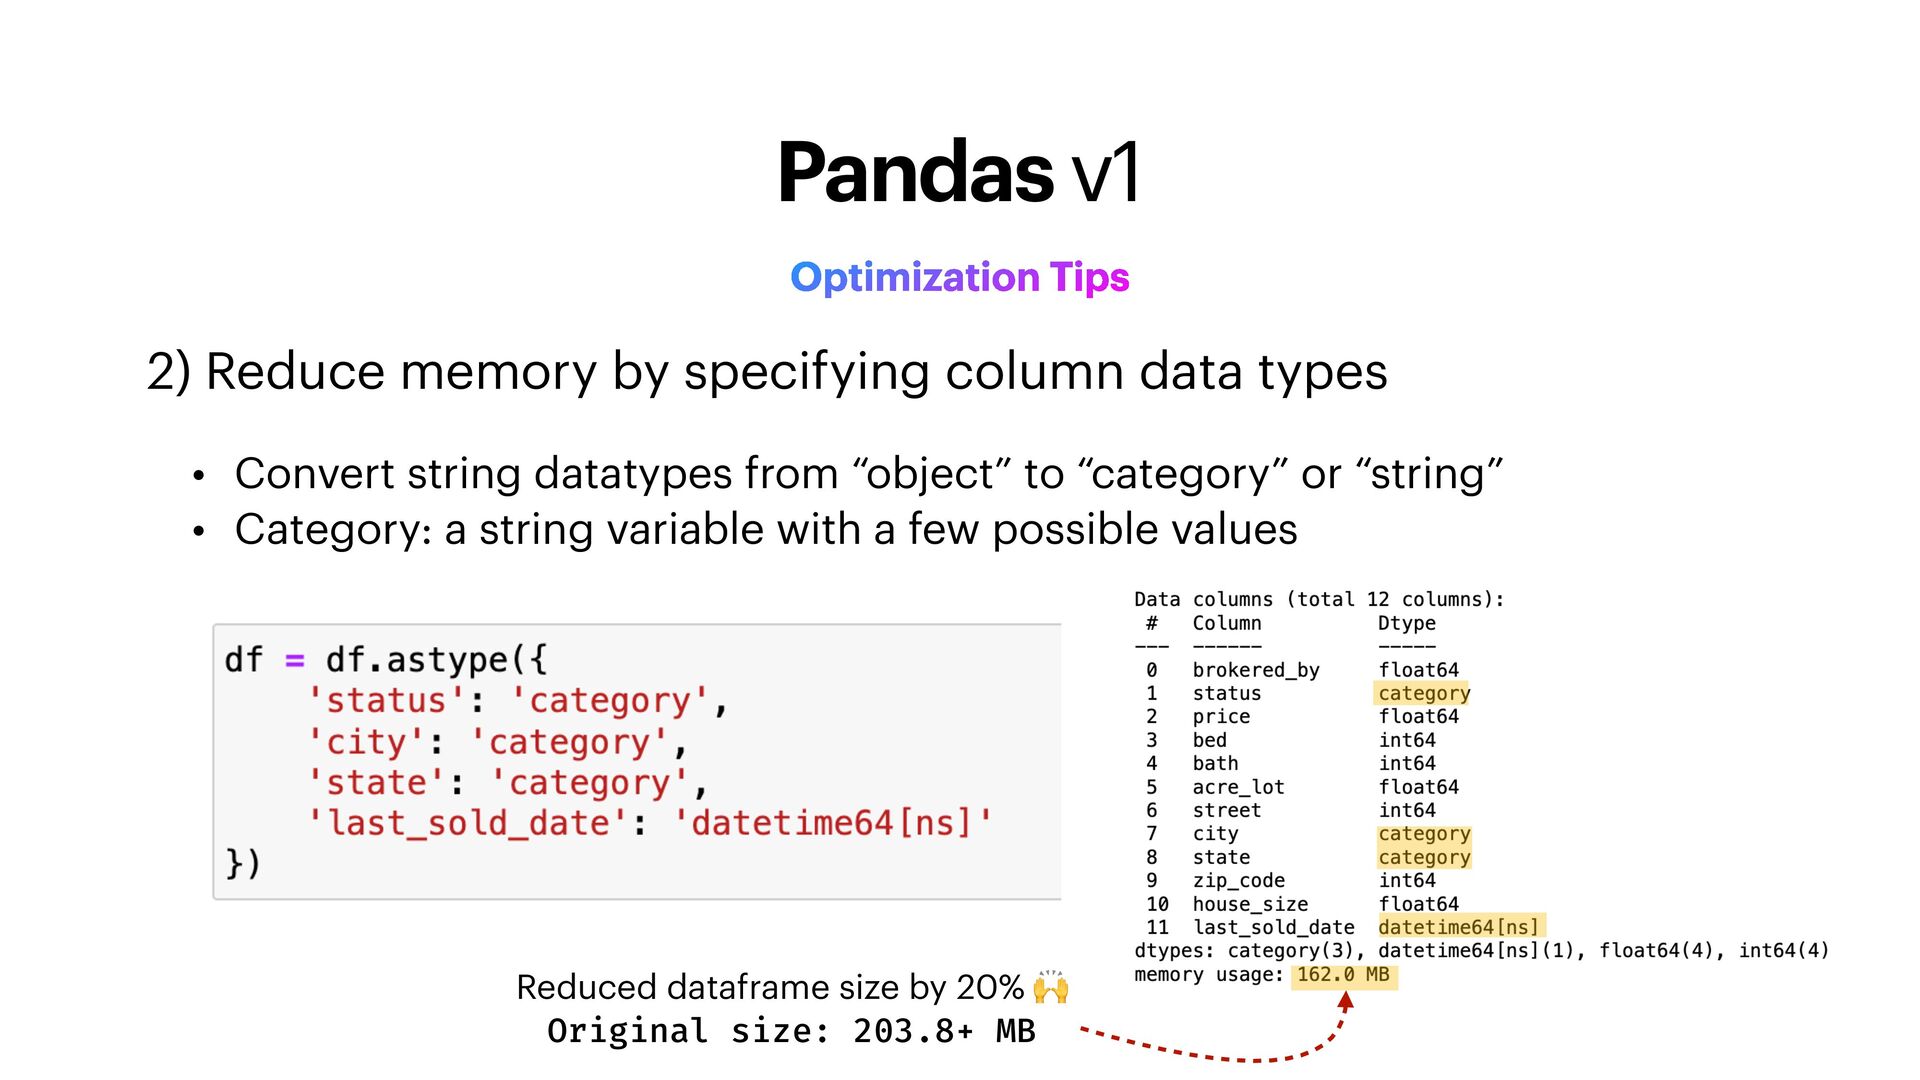
2) Reduce memory by specifying column data types Optimization Tips
Pandas v1 • Convert string datatypes from “object” to “category” or “string” • Category: a string variable with a few possible values Reduced dataframe size by 20% # Original size: 203.8+ MB -
3) Reduce memory by down-casting integers and loats Optimization Tips
Pandas v1 Reduces size by 40% (Original size 203MB) Takes up less space than loat64 and int64 -
3) Reduce memory by down-casting integers and loats Optimization Tips
min max int8 -128 127 int16 -32768 32767 int32 -2147483648 2147483647 int64 -9223372036854775808 9223372036854775807 min max loat32 -6.5504E+04 6.5504E+04 loat64 -1.7976E+308 1.7976E+308 np.finfo(np.float64) np.iinfo(np.int64) Pandas v1 -
4) Filter irst before merging or aggregating Optimization Tips Aggregate
irst, ilter last 123 ms $ Filter irst, aggregate last 58.3 ms % Pandas v1 2.1x speed up! -
5) Avoid for loops at all costs Optimization Tips Pandas
v1 & for index, row in df.iterrows(): ' 6) Serialize your data Alternative ile formats to csv include: • Feather —> df.to_feather() • Parquet —> df.to_parquet() • Pickle —> df.to_pickle() • Hdf5 —> df.to_hdf() Use vectorized operations instead! -
• Released in April 2023 " • Supports Apache Arrow
backend - very e icient! • Better support for strings • Better support for missing values • Zero-copy data access • E icient data transfer between different systems The Apache Arrow Revolution Pandas >= v2.0 -
The Apache Arrow Revolution PyArrow backend outperforms NumPy backend Operation
NumPy Backend PyArrow Backend Speed Up Read parquet ile 141 ms 87 ms 1.6x Calculate mean ( loat64) 3.56 ms 1.73 ms 2.1x Endswith (string) 471 ms 14.1 ms 31.6x Aggregated count 97.2 ms 39.5 ms 2.5x Aggregated mean 102 ms 70 ms 1.5x First three rows from Pandas 2.0 and the Arrow Revolution by Marc Garcia Pandas >= v2.0 -
• Created in 2020 by Ritchie Vink • Built around
“data frames” and “series” (same as Pandas) • Uses Apache Arrow in the backend • Written in Rust • Supports multi-threading • Supports lazy evaluation and query optimization • Streaming API allows for out-of-core processing Polars Overview -
Polars Supports string datatypes! No more “objects” Syntax is very
similar to PySpark -
Polars Eager vs Lazy Evaluation Eager Evaluation Lazy Evaluation Code
is evaluated as soon as you run the code Each line of code is added to a query plan rather than being evaluated straight away -
Polars Eager vs Lazy Evaluation Eager Evaluation Lazy Evaluation Code
is evaluated as soon as you run the code Each line of code is added to a query plan rather than being evaluated straight away -
Polars Lazy Evaluation • Polars LazyFrames get evaluated lazily •
collect() materializes the LazyFrame into a DataFrame • Query is optimized behind the scenes • e.g. iltering before aggregating • Dataframes can be converted to LazyFrames by calling the LazyFrame class: pl.LazyFrame(df) Eager vs Lazy Evaluation -
Polars Lazy Evaluation + Streaming • Executes query in batches
instead of all at once • Streaming is supported for several operations: • filter, slice, head • with_columns • group_by • join • unique • sort • explode, melt • ❗ Still in active development Streaming API -
DuckDB • In-process online analytical processing (OLAP) database • Created
in 2019 by Mühleisen and Raasveldt • Written in C++ and has client APIs in several languages • Uses a columnar-vectorized SQL query processing engine • Query optimization behind the scenes • Interoperable with Apache Arrow Overview -
DuckDB • Great option for SQL enthusiasts! Overview General-Purpose DataTypes
Float —> double String —> varchar -
DuckDB Overview Output • Uses PostgreSQL syntax Symbolic representation of
the SQL query Does not store any data -
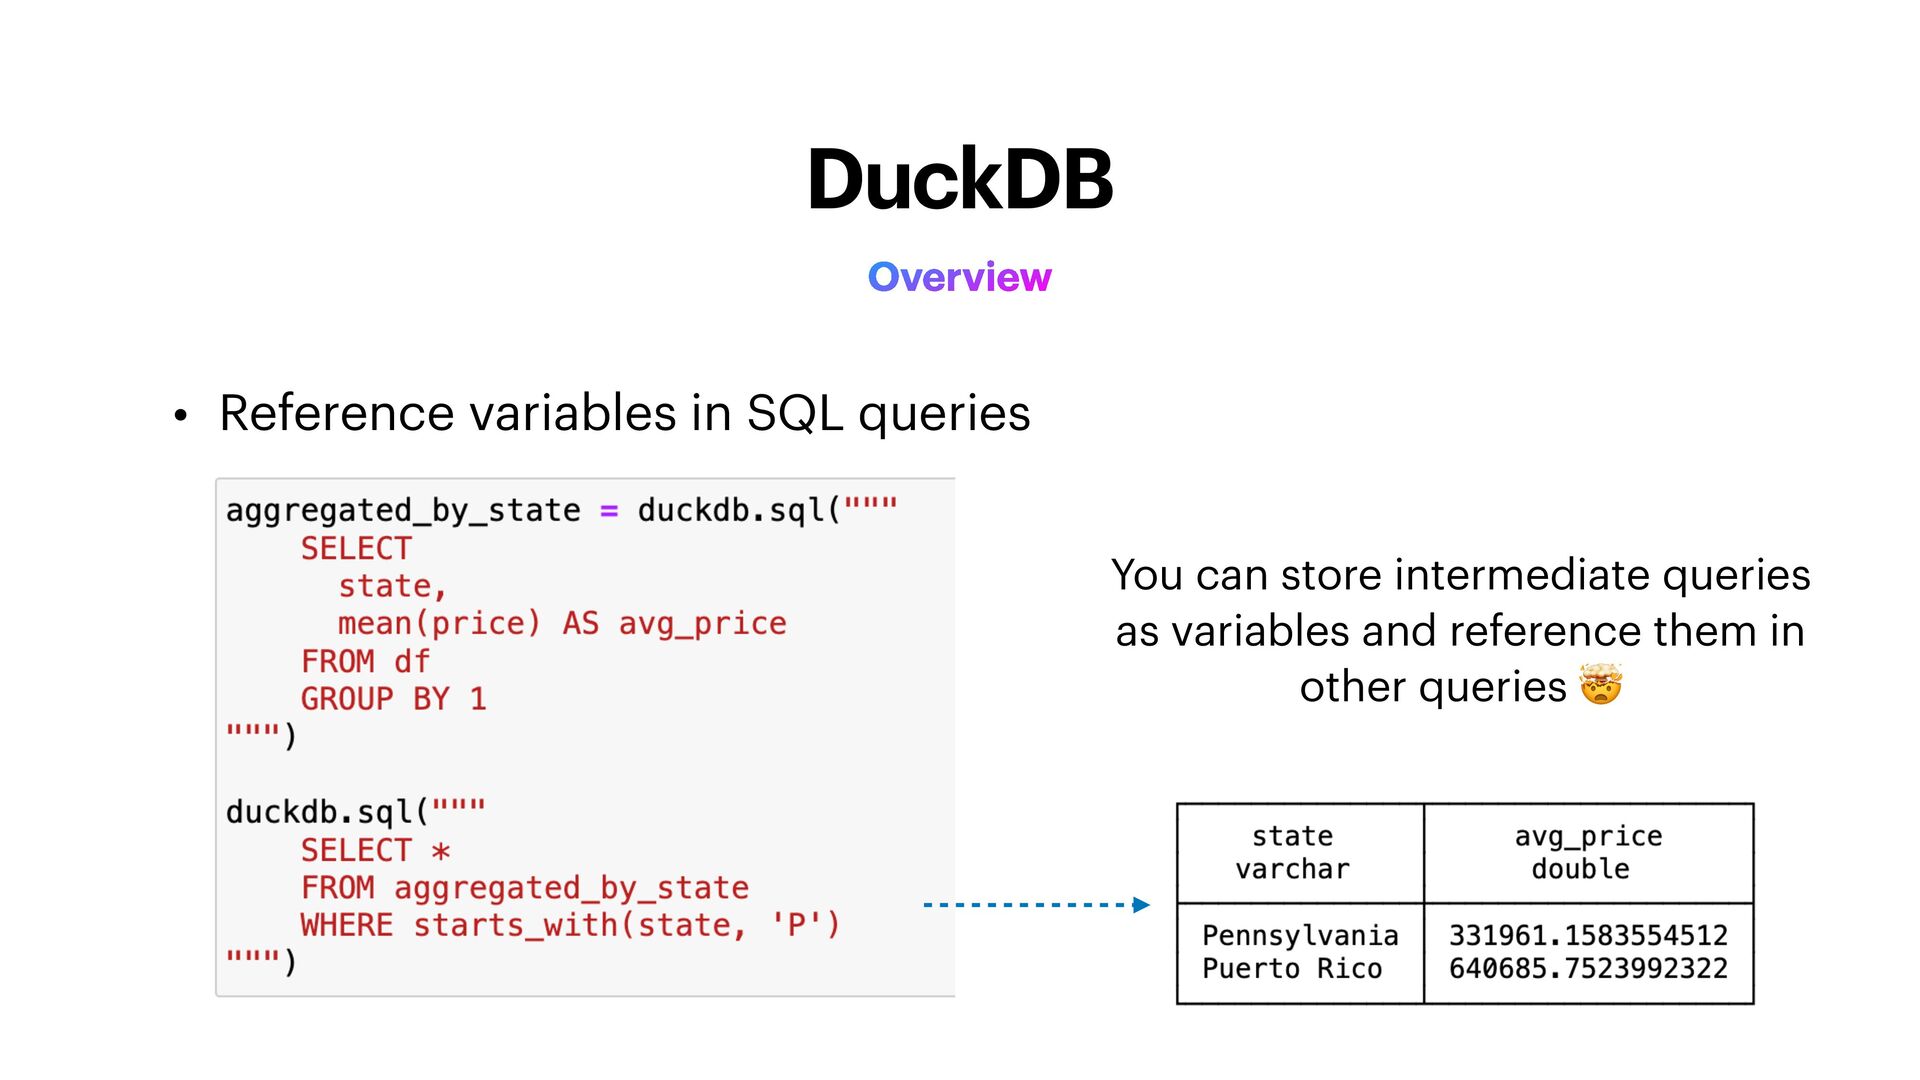
DuckDB Overview You can store intermediate queries as variables and
reference them in other queries ) • Reference variables in SQL queries -
DuckDB Overview • Calling Python functions inside a SQL query
Register Python user-de ined function (UDF) Call the Python UDF directly inside the SQL query -
Side-by-Side Comparison Pandas v2 Polars DuckDb *Data was queried on
May 15, 2024 Downloads by Continent -
Side-by-Side Comparison Pandas v2 Polars DuckDb Year of irst release
2008 2020 2019 Latest version* (as of May 2024) 2.2.2 0.20.27 0.10.3 Downloads last month 215.6M 6.9M 3.5M Total number of stars 42.1K 26.6K 17.2K Merged PRs last month 273 255 175 Total number of contributors 3.2K 407 316 *Data was queried on May 15, 2024 -
Side-by-Side Comparison Pandas v2 Polars DuckDb System type Single node
Single node Single node Syntax Python Python SQL Lazy evaluation ❌ ✅ ✅ Query optimization ❌ ✅ ✅ Supports multi-threading ❌ ✅ ✅ Interoperable with PyArrow ✅ ✅ ✅ -
Benchmarking (from the Polars website) TCP-H benchmark results Benchmarking is
an art and a science. Proceed with caution! -
Benchmarking Benchmarking is an art and a science. Proceed with
caution! My very uno icial benchmark test 3.5GB data local Pandas v2 Polars DuckDb DuckDb (without materializing to Arrow object) Aggregated count 1.18 s 487 ms 770 ms 149 µs Aggregated mean 44.7 s 499 ms 767 ms 148 µs -
Summary • Each package has its advantages and disadvantages -
Pandas v1 and v2 - Polars - DuckDB • Things to consider when making a decision: - Size of data - Learning curve and amount of spare time to learn a new syntax - Knowledge base of contributors and peer reviewers • My recommendation: try them all! Which package is best? -
Recommended Resources • Pandas Docs | Polars Docs | DuckDB
Docs • pandas 2.0 and the Arrow revolution (part I) by Marc Garcias • Apache Arrow and the “10 Things I Hate About pandas” by Wes McKinney • DuckDB: Bringing analytical SQL directly to your Python shell (PyData Presentation) by Pedro Holanda • Comprehensive Guide To Optimize Your Pandas Code by Eyal Trabelsi • Pandas 2.0 and its Ecosystem (Arrow, Polars, DuckDB) by Simon Späti