Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Language Model Based Grammatical Error Correcti...
Search
Sponsored
·
Ship Features Fearlessly
Turn features on and off without deploys. Used by thousands of Ruby developers.
→
youichiro
July 25, 2018
Technology
200
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Language Model Based Grammatical Error Correction without Annotated Training Data
長岡技術科学大学
自然言語処理研究室
文献紹介(2018-07-25)
youichiro
July 25, 2018
More Decks by youichiro
See All by youichiro
日本語文法誤り訂正における誤り傾向を考慮した擬似誤り生成
youichiro
0
1.7k
分類モデルを用いた日本語学習者の格助詞誤り訂正
youichiro
0
160
Multi-Agent Dual Learning
youichiro
1
210
Automated Essay Scoring with Discourse-Aware Neural Models
youichiro
0
160
Context is Key- Grammatical Error Detection with Contextual Word Representations
youichiro
1
180
勉強勉強会
youichiro
0
110
Confusionset-guided Pointer Networks for Chinese Spelling Check
youichiro
0
230
A Neural Grammatical Error Correction System Built On Better Pre-training and Sequential Transfer Learning
youichiro
0
210
An Empirical Study of Incorporating Pseudo Data into Grammatical Error Correction
youichiro
0
250
Other Decks in Technology
See All in Technology
AI駆動開発の時代になったのでトヨタ生産方式から見直す
terurou
7
6k
その Valkey 使いこなしていますか?
onk
PRO
5
1.5k
WasmをRustにする
sansantech
PRO
0
250
「Docker Desktop不要の時代」は 来たのか?
ueponx
0
770
Conditional PED-ANOVA: Hyperparameter Importance in Hierarchical & Dynamic Search Spaces
pfn
PRO
0
130
V8のArray.prototype.flatを最大約20倍速くするまでと、巨大OSSへの大規模コミットの道のり
riyaamemiya
0
290
M5Stackで作る BLEマウス GPSログの世界
tomokusaba
0
420
Optunaの最新リリースv5.0について
pfn
PRO
0
120
AIにシークレットを見せない、WSL2で安全な開発環境
yazm
0
300
PHPカンファレンス関西の招待状 / Invitation to PHP Conference Kansai
ykanoh
0
110
フロントエンドカンファレンス関西2026 - 速すぎるUIに、待ち時間を
teamlab
PRO
0
130
Tofu-Controller lightning talk @ Containerday 2026
gionn
0
110
Featured
See All Featured
世界の人気アプリ100個を分析して見えたペイウォール設計の心得
akihiro_kokubo
PRO
74
43k
Leveraging LLMs for student feedback in introductory data science courses - posit::conf(2025)
minecr
1
440
Evolution of real-time – Irina Nazarova, EuRuKo, 2024
irinanazarova
9
1.6k
Mobile First: as difficult as doing things right
swwweet
225
10k
Cheating the UX When There Is Nothing More to Optimize - PixelPioneers
stephaniewalter
287
14k
How to make the Groovebox
asonas
2
2.5k
HTML-Aware ERB: The Path to Reactive Rendering @ RubyCon 2026, Rimini, Italy
marcoroth
5
820
SEO Brein meetup: CTRL+C is not how to scale international SEO
lindahogenes
2
2.9k
Visual Storytelling: How to be a Superhuman Communicator
reverentgeek
2
710
SEOcharity - Dark patterns in SEO and UX: How to avoid them and build a more ethical web
sarafernandez
0
300
New Earth Scene 8
popppiees
4
2.7k
The MySQL Ecosystem @ GitHub 2015
samlambert
251
13k
Transcript
Language Model Based Grammatical Error Correction without Annotated Training Data
Christopher Bryant and Ted Briscoe Proceedings of the Thirteenth Workshop on Innovative Use of NLP for Building Educational Applications, pages 247–253, 2018 ⽂献紹介(2018-07-25) ⻑岡技術科学⼤学 ⾃然⾔語処理研究室 ⼩川 耀⼀朗 1
Abstract l ⾔語モデルを⽤いた⽂法誤り訂正アプローチ l シンプルかつ少量のアノテーションデータしか⽤いない⾔ 語モデルアプローチが、⼤量のアノテーションデータで訓 練されたモデルと競争できる性能を⽰した 2
Introduction l CoNNL-2014 shared taskではTop3のチーム全てがSMTあ るいはclassifier-baseのシステムを⽤いた l これ以降、SMTやSMTとclassifierの混同、NMTのアプロー チにフォーカスした研究が進んでいる l
⾔語モデルを⽤いた⼿法に関する研究は⼤きく停滞した Ø GECにおける⾔語モデルアプローチを再調査する 3
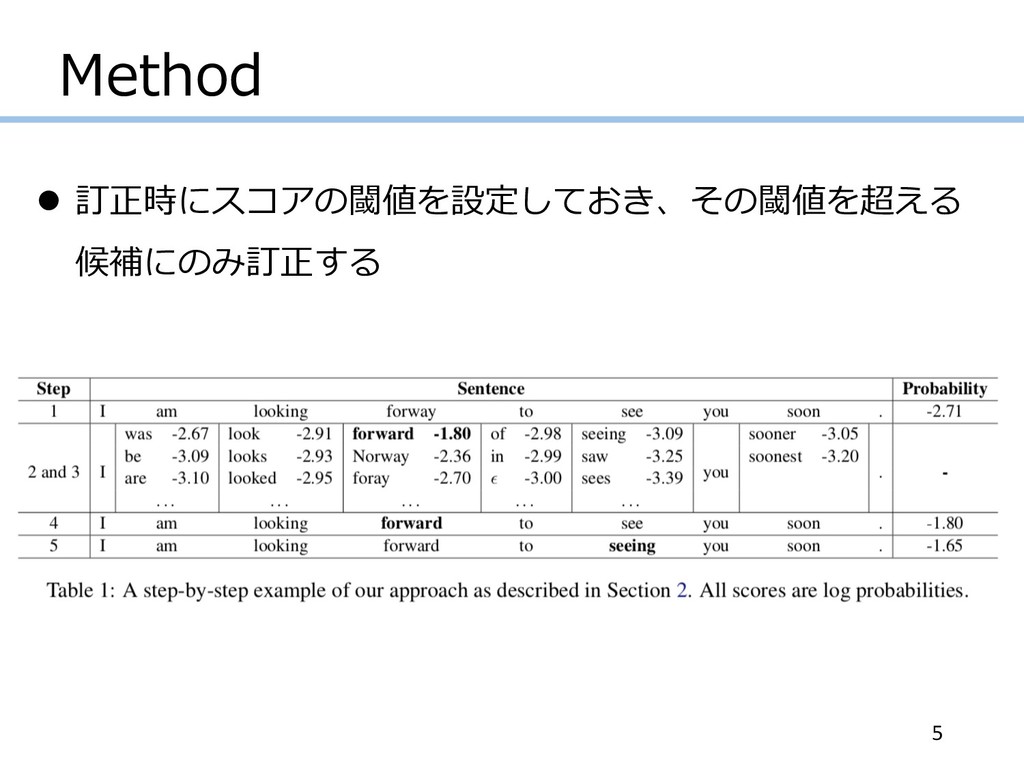
Method l ⾔語モデル確率の低い⽂は、⾔語モデル確率の⾼い⽂よ りも⽂法誤りを含んでいるであろうというアイデア 1. ⼊⼒⽂の⾔語モデルスコアを計算する 2. ⽂中の各単語において、訂正候補セットを作る 3. 各単語における各訂正候補で置換した⽂を⽣成し、
再び⽂のスコアを計算する 4. 訂正候補の中から、スコアが閾値よりもが⾼くなる 1⽂を選ぶ 5. ステップ1~4を繰り返す 4
Method l 訂正時にスコアの閾値を設定しておき、その閾値を超える 候補にのみ訂正する 5
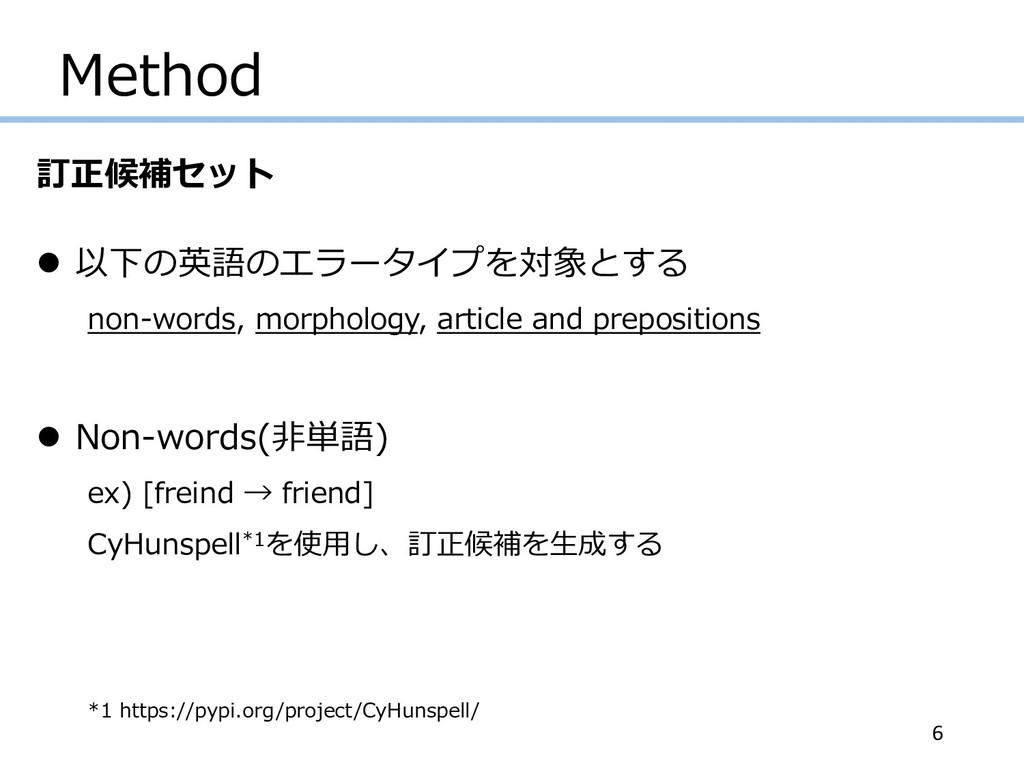
Method 訂正候補セット l 以下の英語のエラータイプを対象とする non-words, morphology, article and prepositions l
Non-words(⾮単語) ex) [freind → friend] CyHunspell*1を使⽤し、訂正候補を⽣成する *1 https://pypi.org/project/CyHunspell/ 6
Method 訂正候補セット l Morphology(語形) - noun number: [cat → cats]
- verb tense: [eat → ate] - adjective form: [big → bigger] など Automatically Generated Inflection Database(AGID)*2から、訂正 候補を⽣成する l Articles and Prepositions(冠詞と前置詞) article: {φ, a, an, the} preposition: {φ, about, at, by, for, from, in, of, on, to, with} *2 http://wordlist.aspell.net/other/ 7
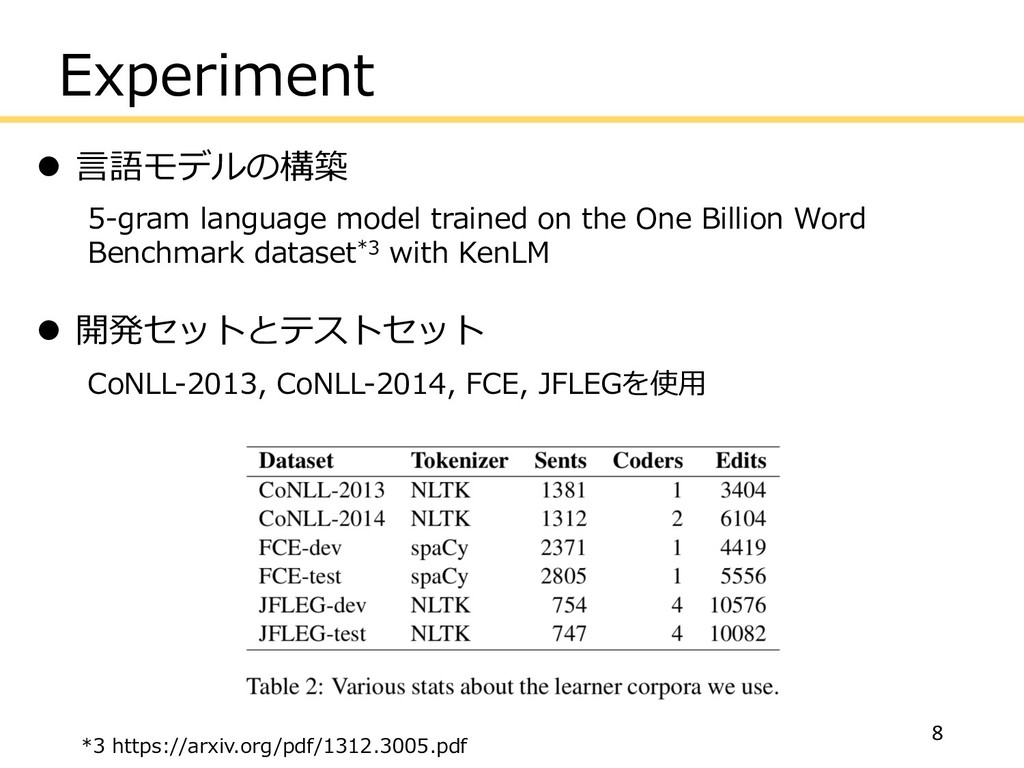
Experiment l ⾔語モデルの構築 5-gram language model trained on the One
Billion Word Benchmark dataset*3 with KenLM l 開発セットとテストセット CoNLL-2013, CoNLL-2014, FCE, JFLEGを使⽤ 8 *3 https://arxiv.org/pdf/1312.3005.pdf
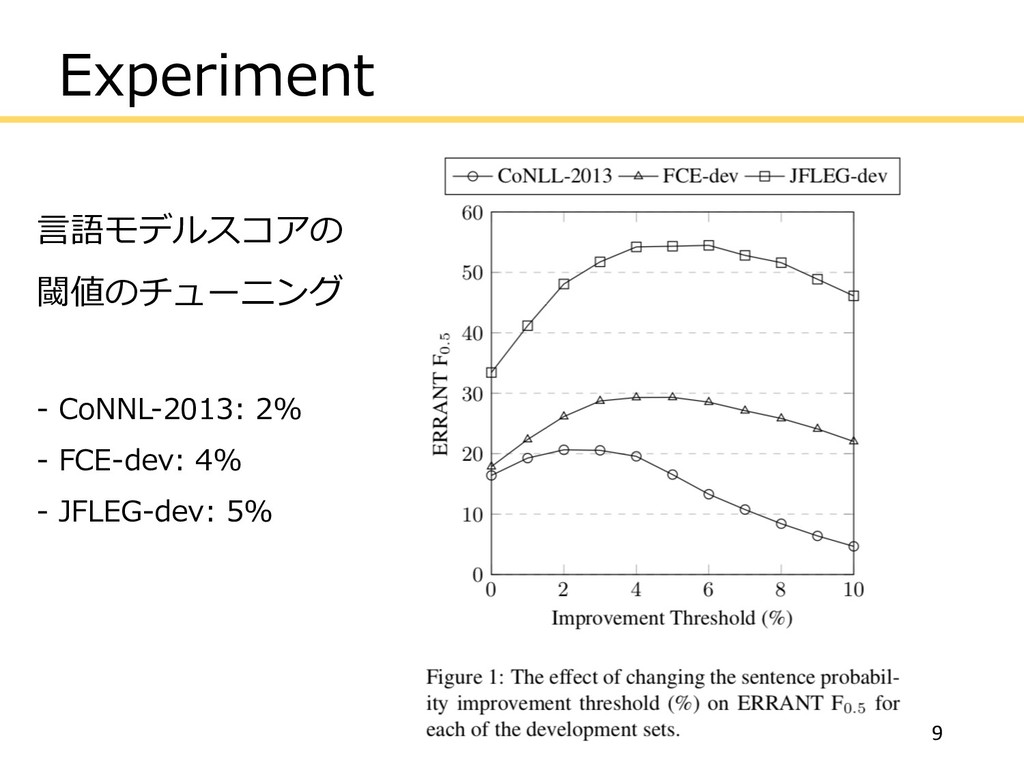
Experiment ⾔語モデルスコアの 閾値のチューニング - CoNNL-2013: 2% - FCE-dev: 4% -
JFLEG-dev: 5% 9
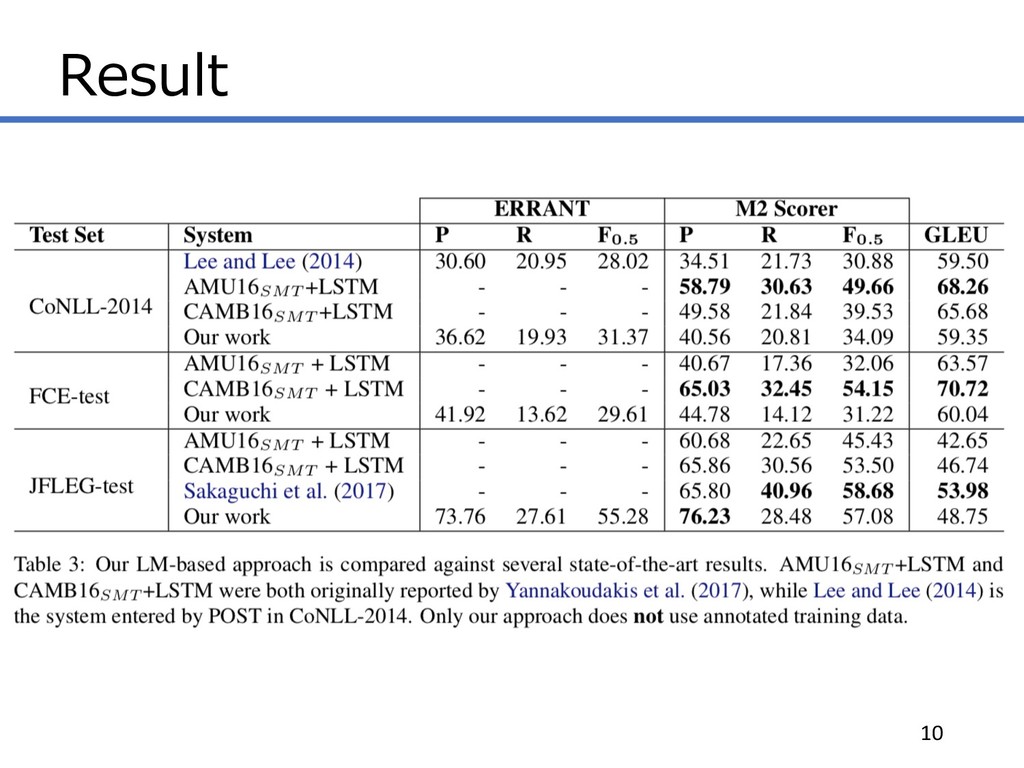
Result 10
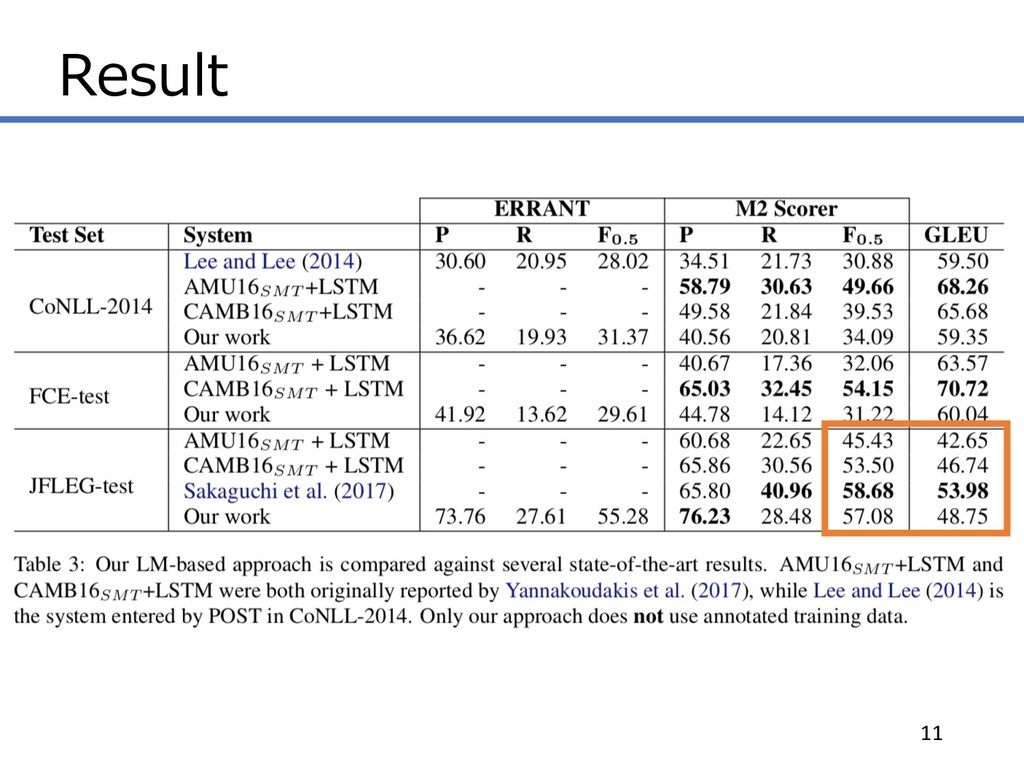
Result 11
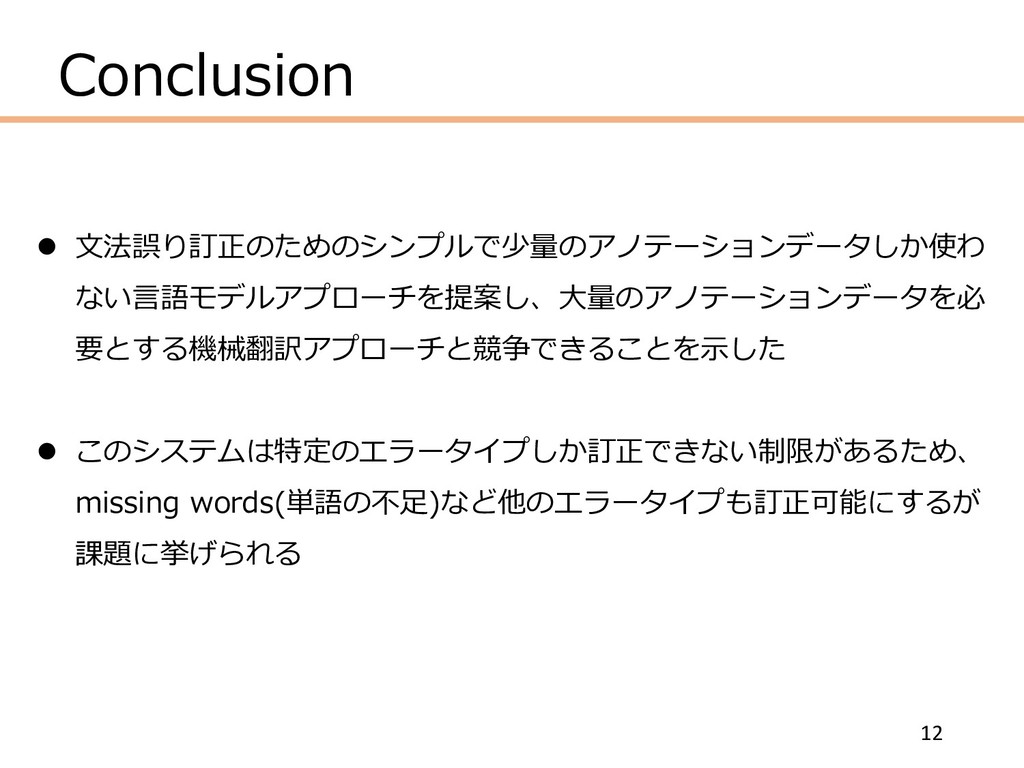
Conclusion 12 l ⽂法誤り訂正のためのシンプルで少量のアノテーションデータしか使わ ない⾔語モデルアプローチを提案し、⼤量のアノテーションデータを必 要とする機械翻訳アプローチと競争できることを⽰した l このシステムは特定のエラータイプしか訂正できない制限があるため、 missing words(単語の不⾜)など他のエラータイプも訂正可能にするが
課題に挙げられる


 youichiro
 terurou
 onk
 sansantech
 ueponx
 pfn
 riyaamemiya
 tomokusaba
 yazm
 ykanoh
 teamlab
 gionn
 akihiro_kokubo
 minecr
 irinanazarova
 swwweet
 stephaniewalter
 asonas
 marcoroth
 lindahogenes
 reverentgeek
 sarafernandez
 popppiees
 samlambert