Share
Embed
A Computational Model of Control Allocation Based on the Expected Value of Control (ICPS 2019)
Sebastian Musslick
March 09, 2019
Transcript
61 slides
-
Sebastian Musslick Princeton Neuroscience Institute, Princeton University ICPS 2019 Symposium
- Neural Mechanisms of Effort Mobilization and Cognitive Control -
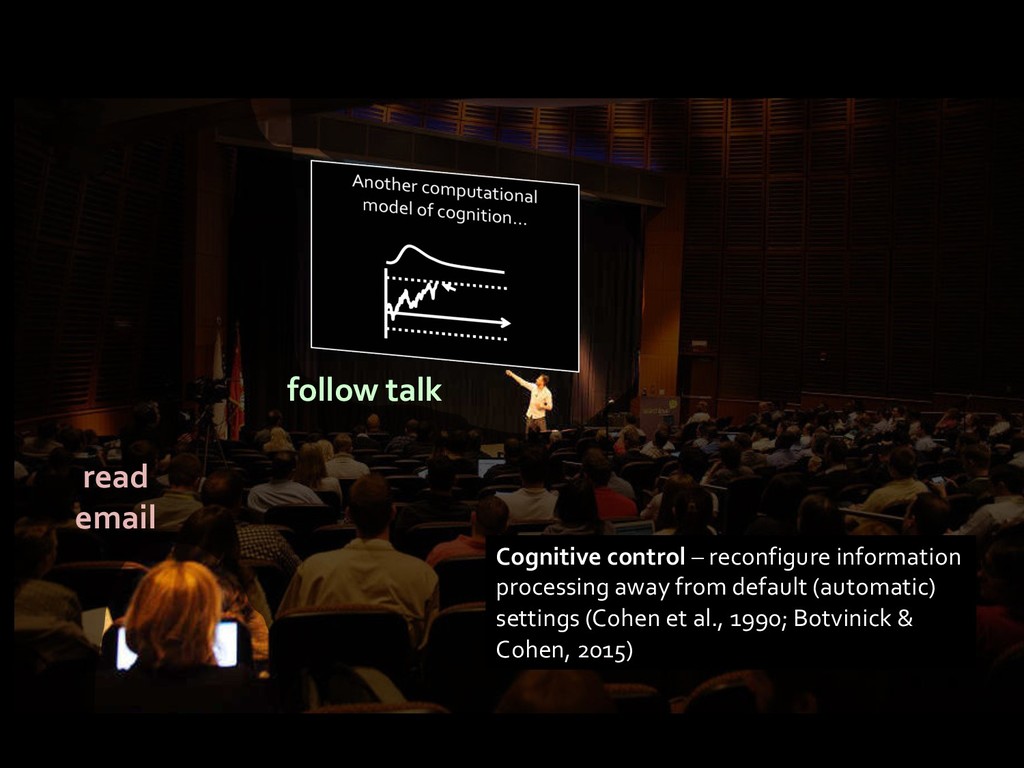
Cognitive control – reconfigure information processing away from default (automatic)
settings (Cohen et al., 1990; Botvinick & Cohen, 2015) read email follow talk -
A Computational Model of Control Allocation Based on the Expected
Value of Control A. The Theory B. The Model C. Simulations & Predictions D. Estimating Mental Effort from Behavior -
A Computational Model of Control Allocation Based on the Expected
Value of Control A. The Theory B. The Model C. Simulations & Predictions D. Estimating Mental Effort from Behavior -
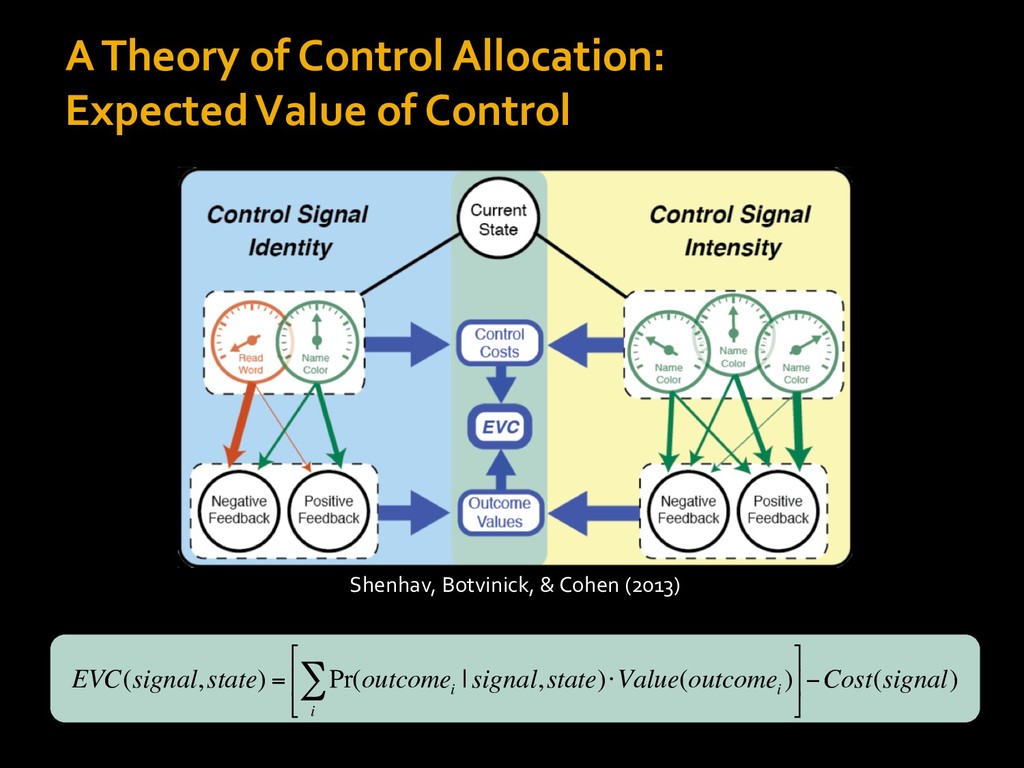
A Theory of Control Allocation: Expected Value of Control GREEN
EVC(signal,state) = Pr(outcome i i ∑ | signal,state)⋅Value(outcome i ) # $ % & ' (−Cost(signal) Shenhav, Botvinick, & Cohen (2013) -
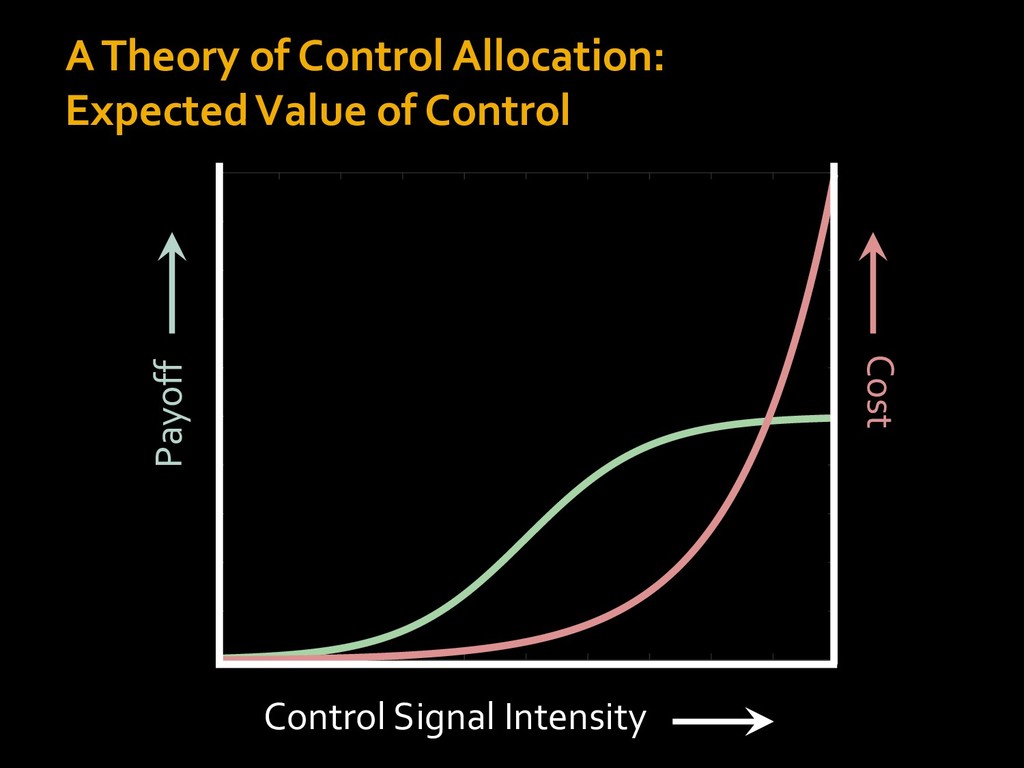
A Theory of Control Allocation: Expected Value of Control Control
Signal Intensity -
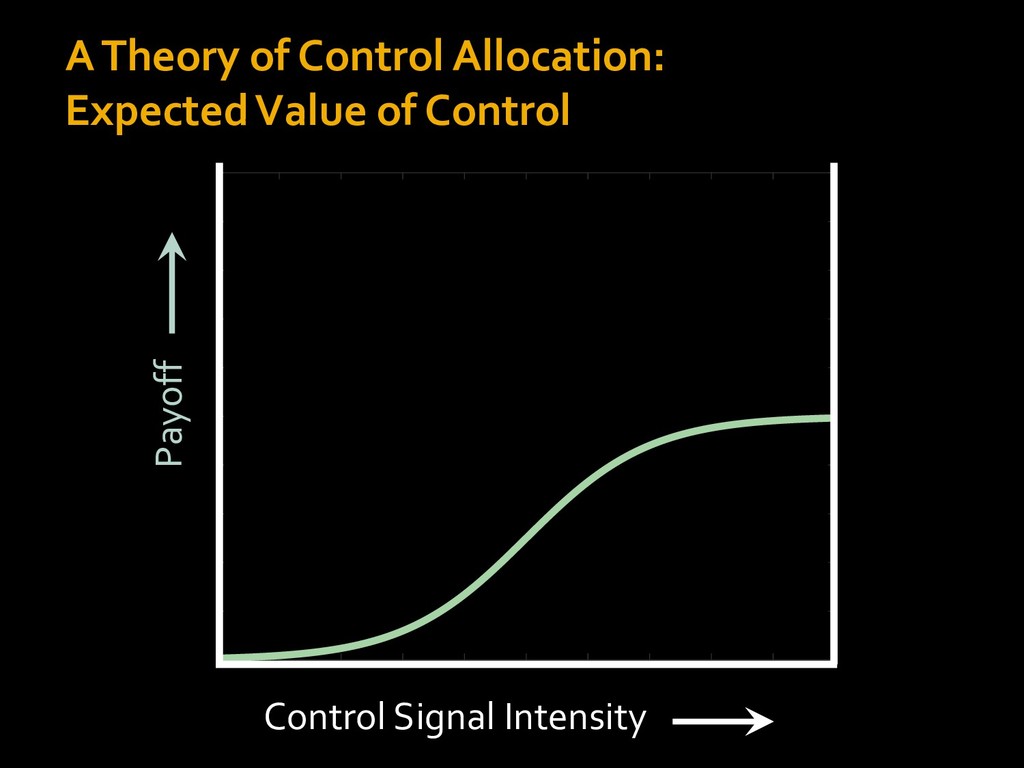
A Theory of Control Allocation: Expected Value of Control Control
Signal Intensity Payoff -
A Theory of Control Allocation: Expected Value of Control Control
Signal Intensity Payoff Cost -
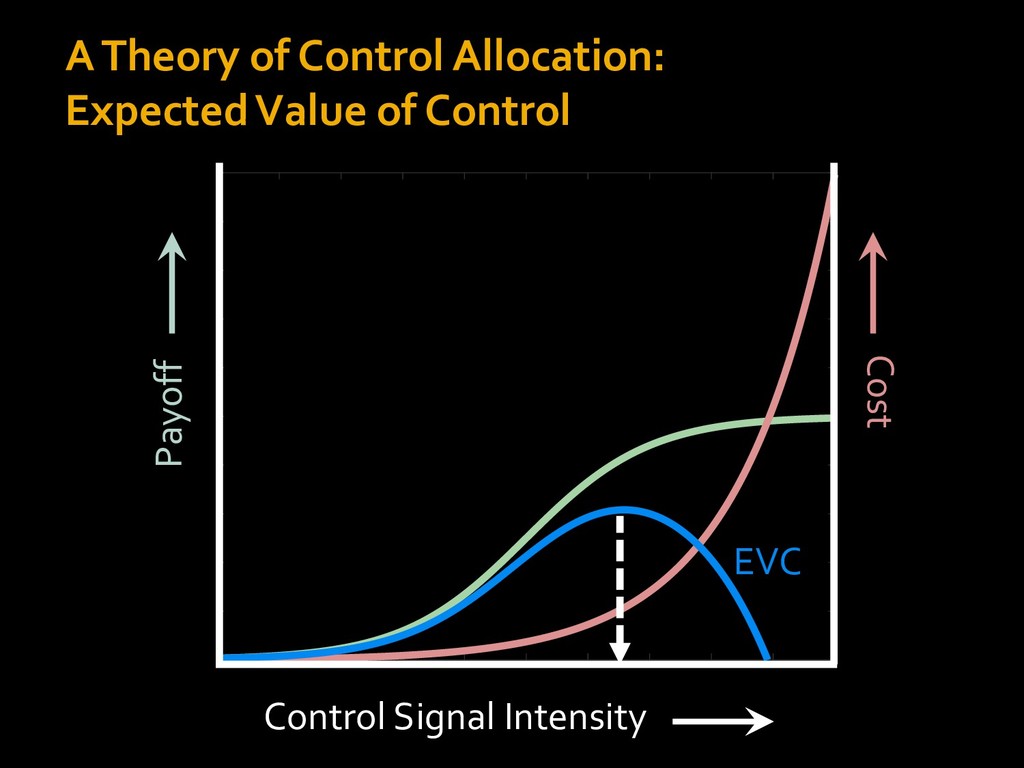
A Theory of Control Allocation: Expected Value of Control Control
Signal Intensity Payoff Cost EVC -
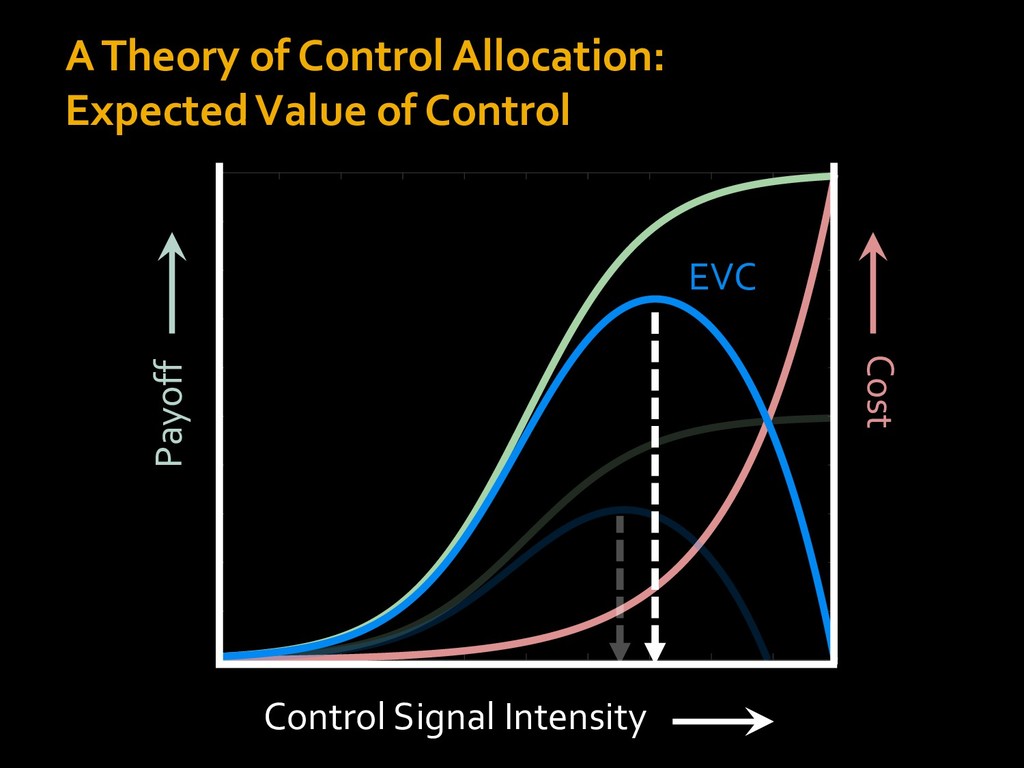
A Theory of Control Allocation: Expected Value of Control Control
Signal Intensity Payoff Cost EVC -
A Computational Model of Control Allocation Based on the Expected
Value of Control A. The Theory B. The Model C. Simulations & Predictions D. Estimating Mental Effort from Behavior -
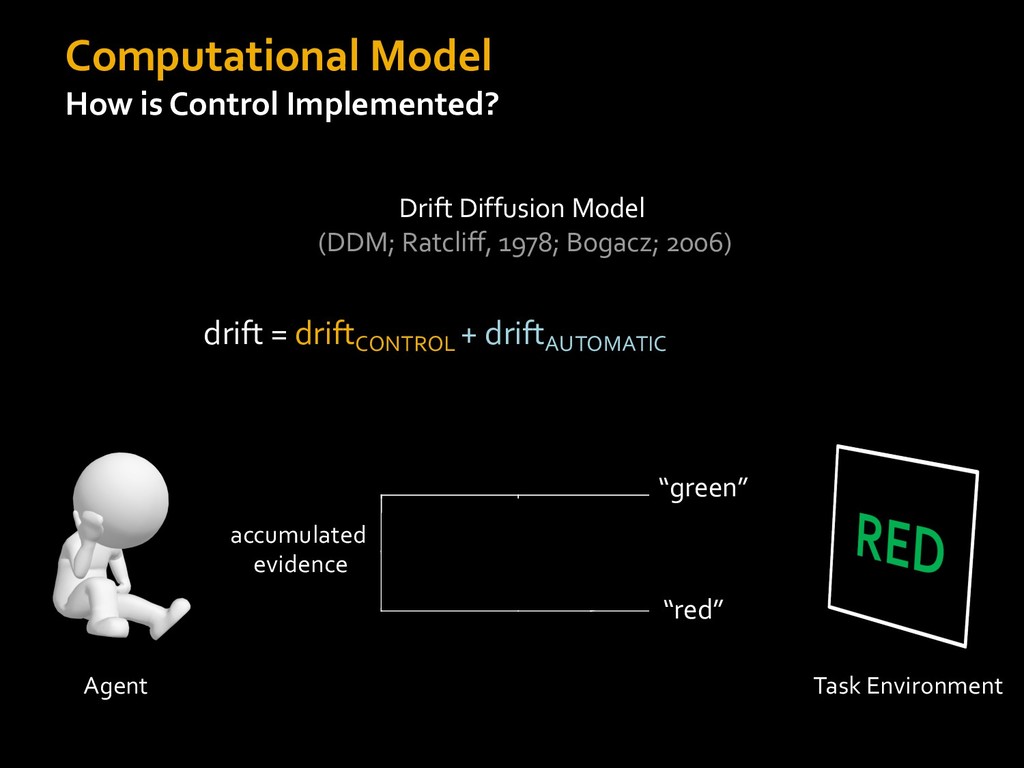
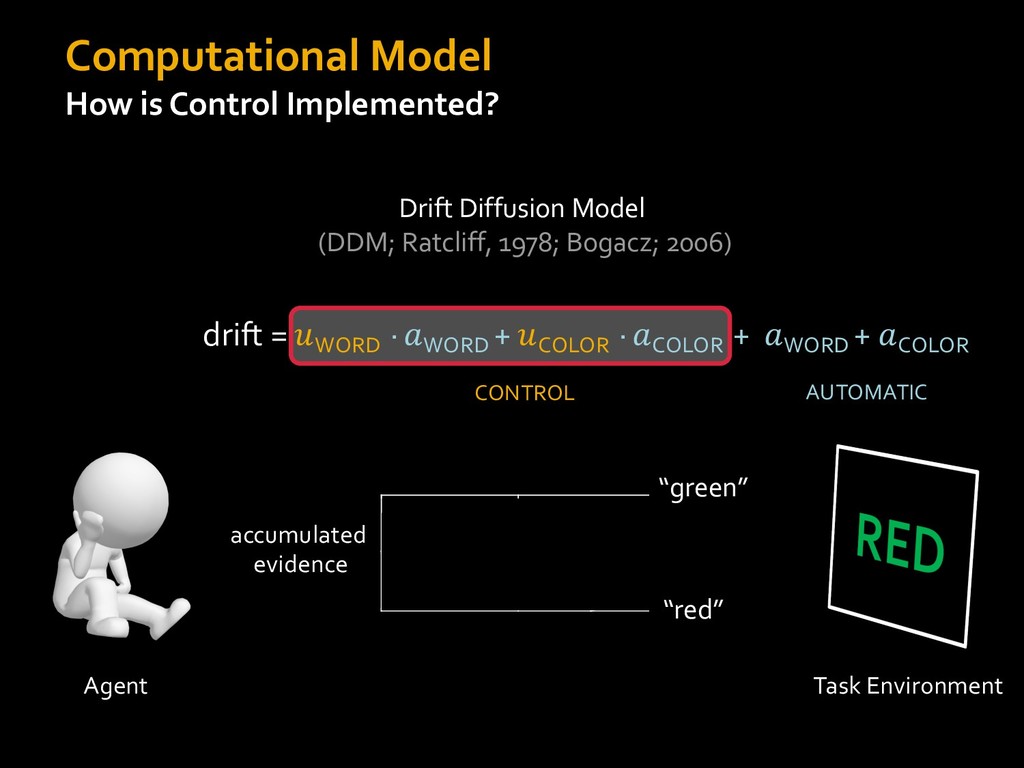
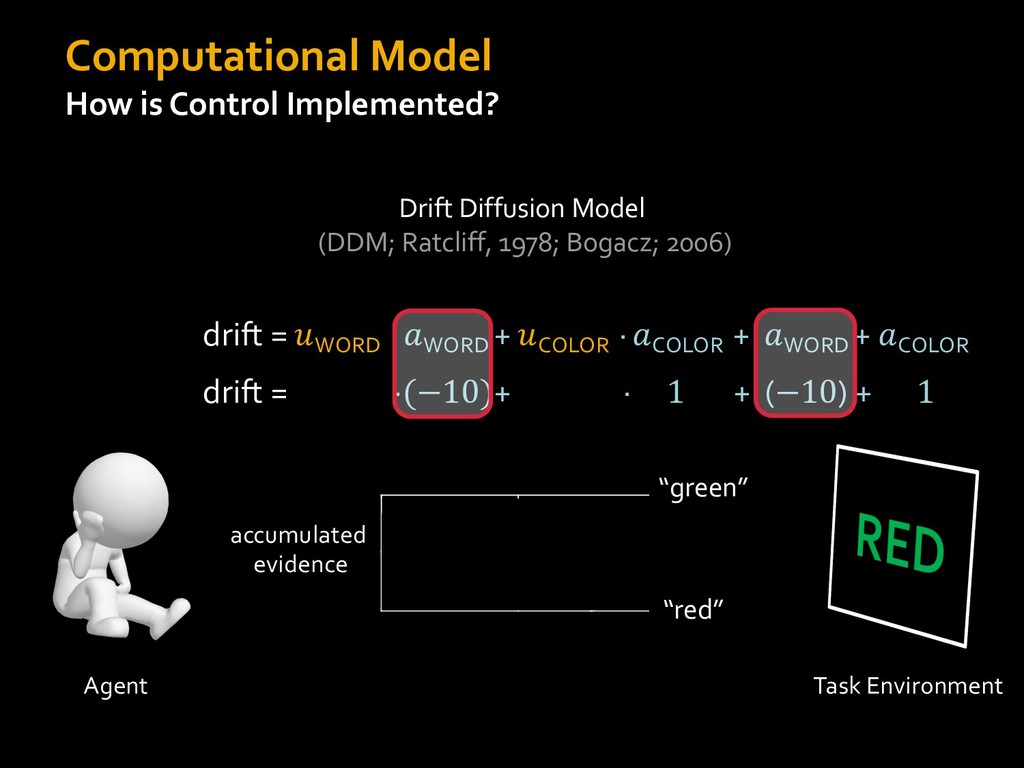
Computational Model How is Control Implemented? Agent Task Environment Drift
Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence drift = driftCONTROL + driftAUTOMATIC -
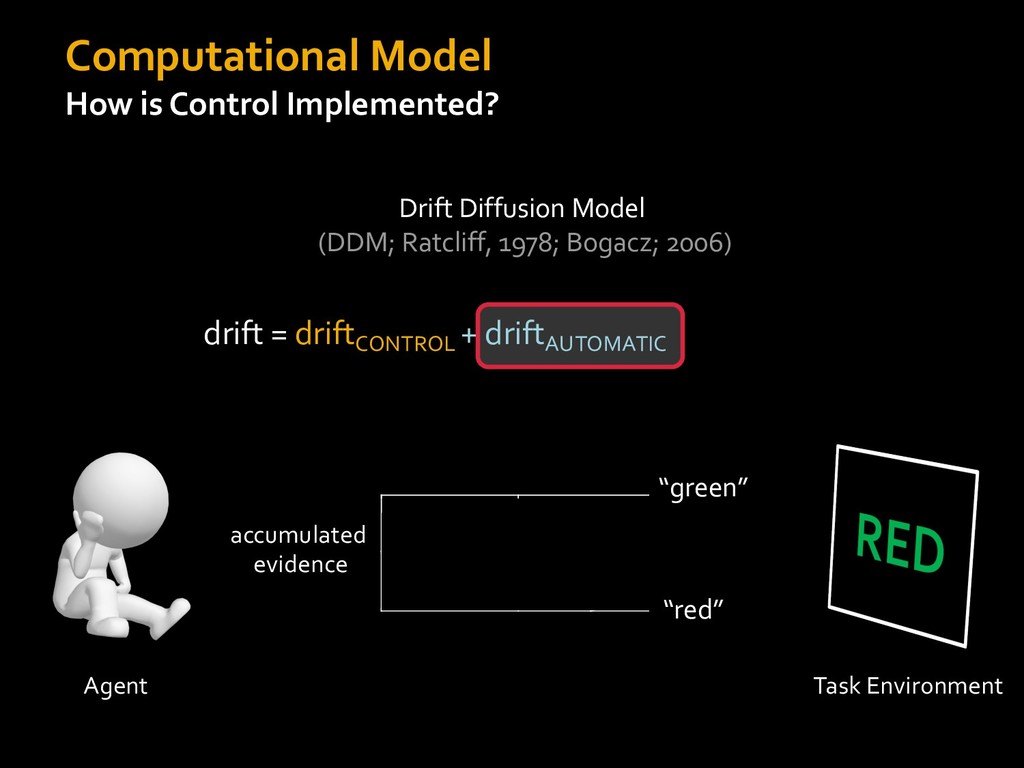
Computational Model How is Control Implemented? Agent Task Environment Drift
Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence drift = driftCONTROL + driftAUTOMATIC -
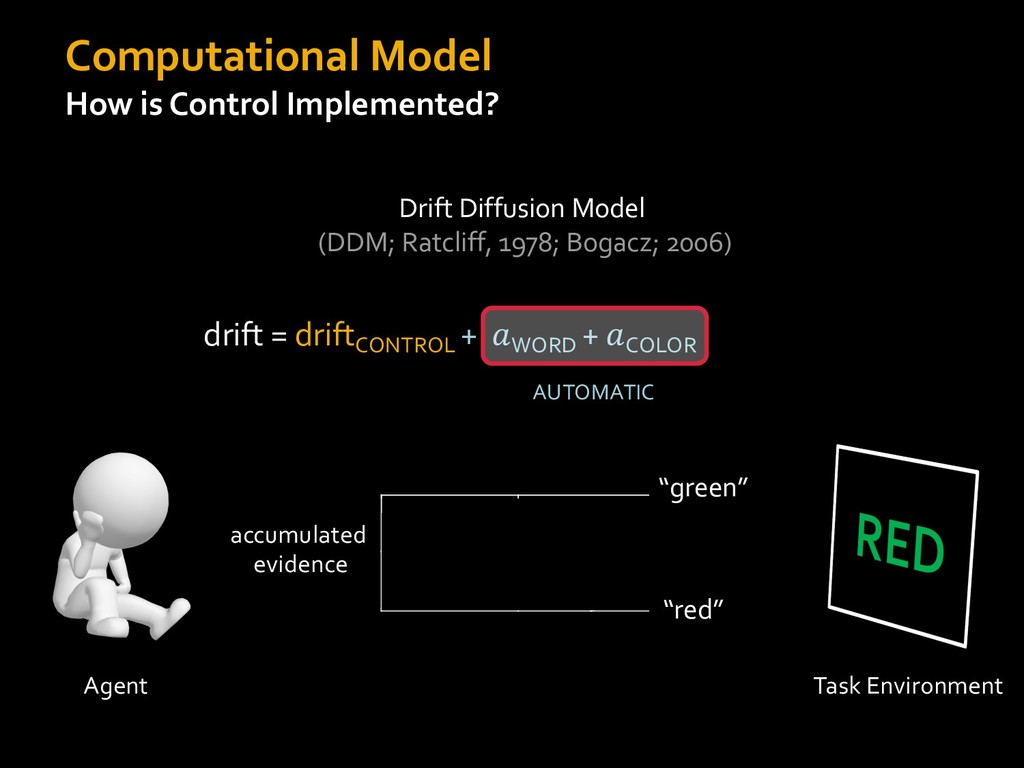
Computational Model How is Control Implemented? Agent Task Environment Drift
Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence AUTOMATIC drift = driftCONTROL + ! WORD + ! COLOR -
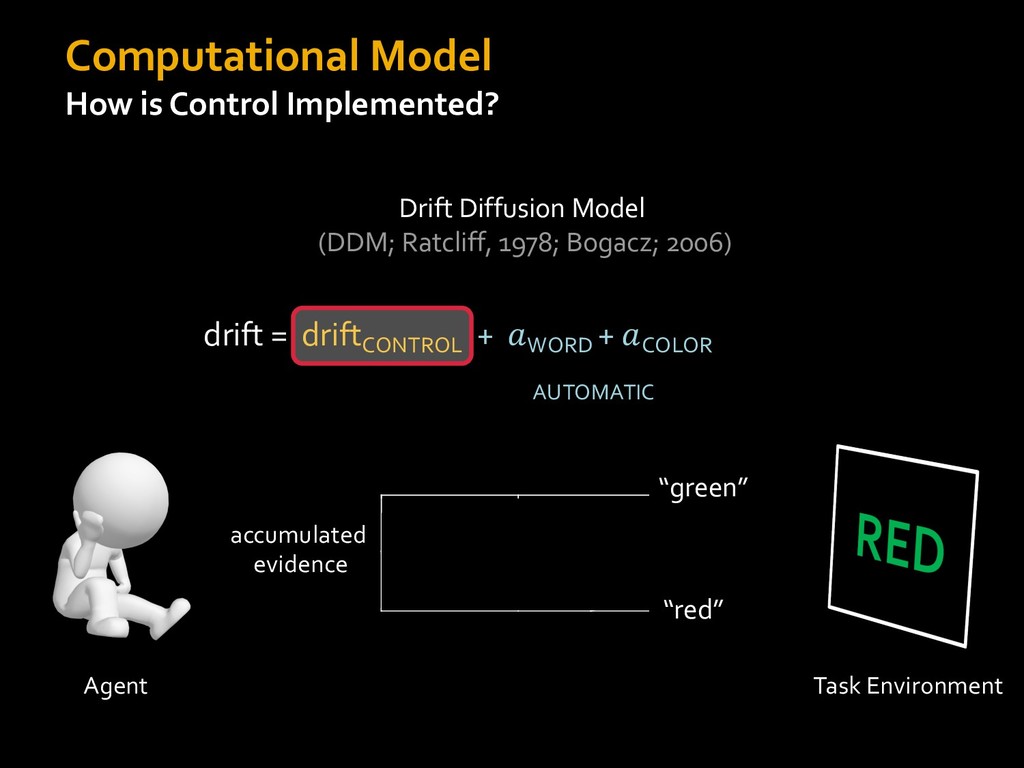
Computational Model How is Control Implemented? Agent Task Environment Drift
Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence AUTOMATIC drift = driftCONTROL + ! WORD + ! COLOR -
Computational Model How is Control Implemented? Agent Task Environment Drift
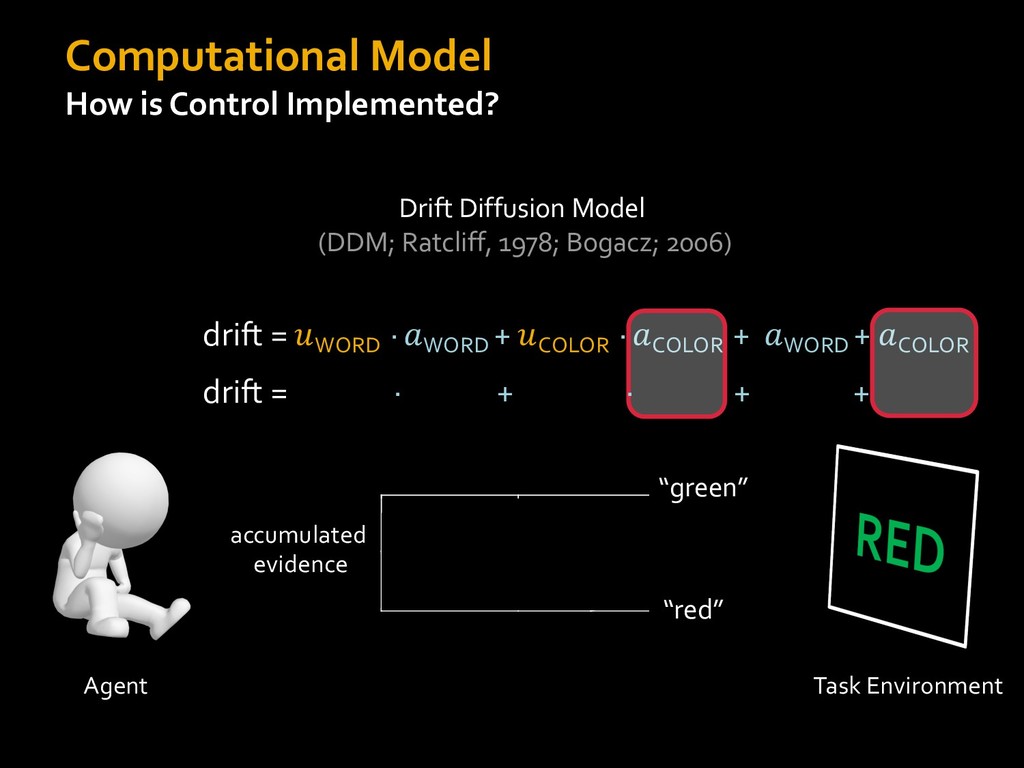
Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence AUTOMATIC drift = ! WORD ·" WORD + ! COLOR ·" COLOR + " WORD + " COLOR CONTROL -
Computational Model How is Control Implemented? Agent Task Environment Drift
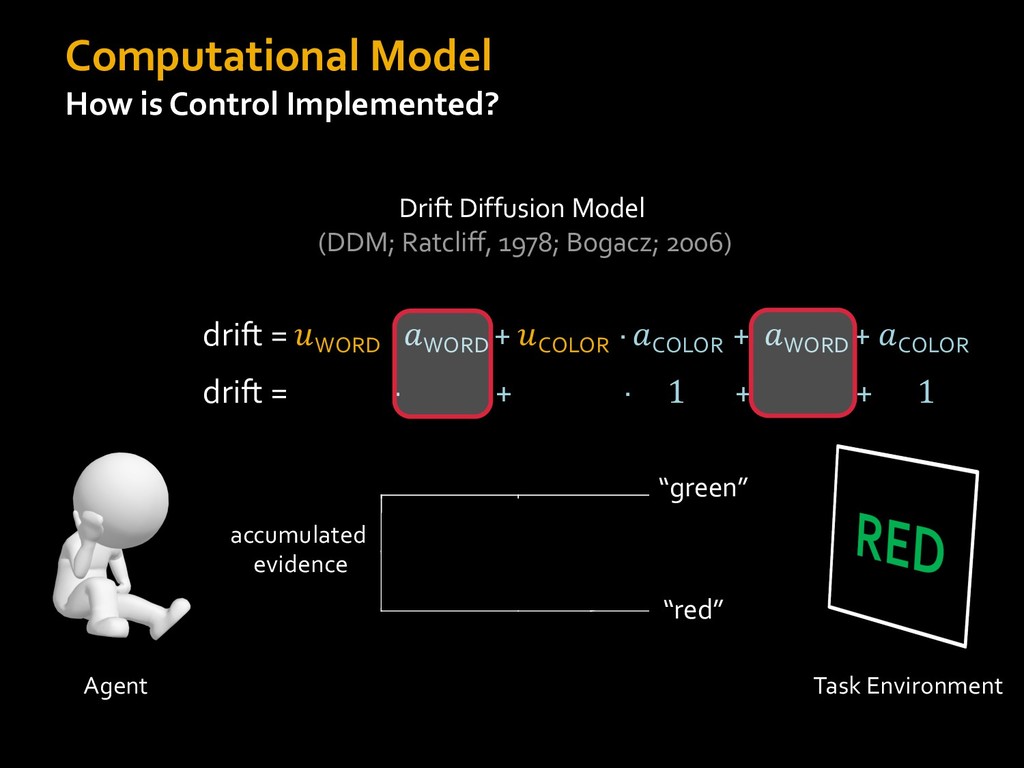
Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence drift = ! WORD ·" WORD + ! COLOR ·" COLOR + " WORD + " COLOR drift = · + · + + -
drift = ! WORD ·" WORD + ! COLOR ·"
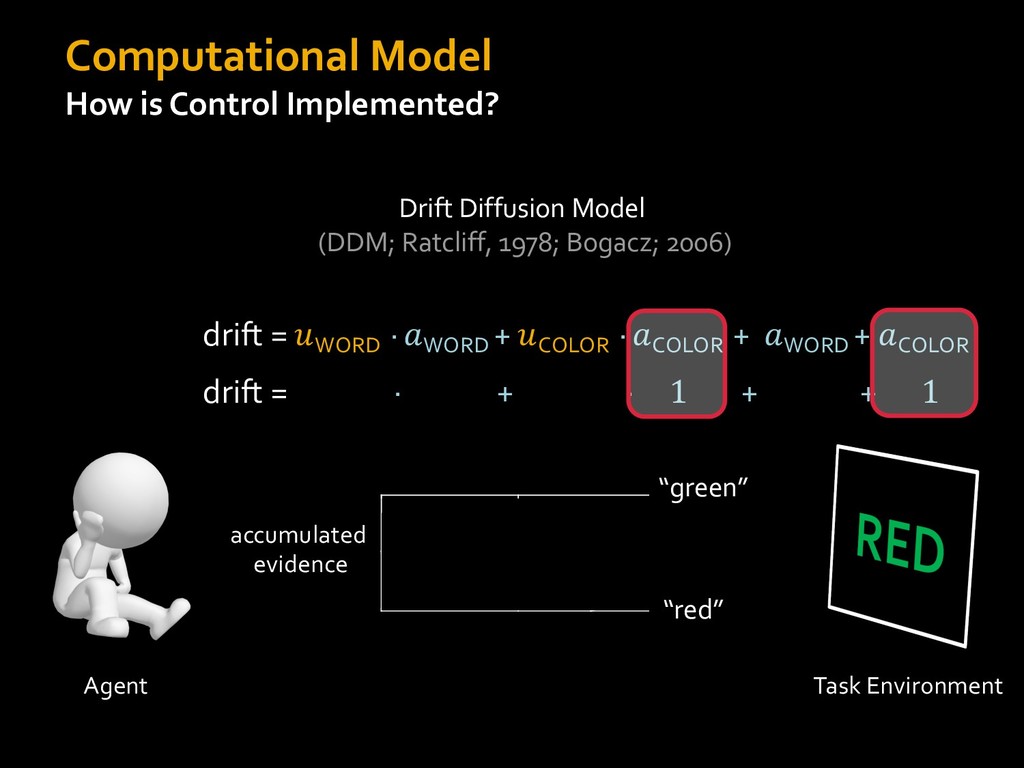
COLOR + " WORD + " COLOR drift = · + · 1 + + 1 Computational Model How is Control Implemented? Agent Task Environment Drift Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence -
drift = ! WORD ·" WORD + ! COLOR ·"
COLOR + " WORD + " COLOR drift = · + · 1 + + 1 Computational Model How is Control Implemented? Agent Task Environment Drift Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence -
drift = ! WORD ·" WORD + ! COLOR ·"
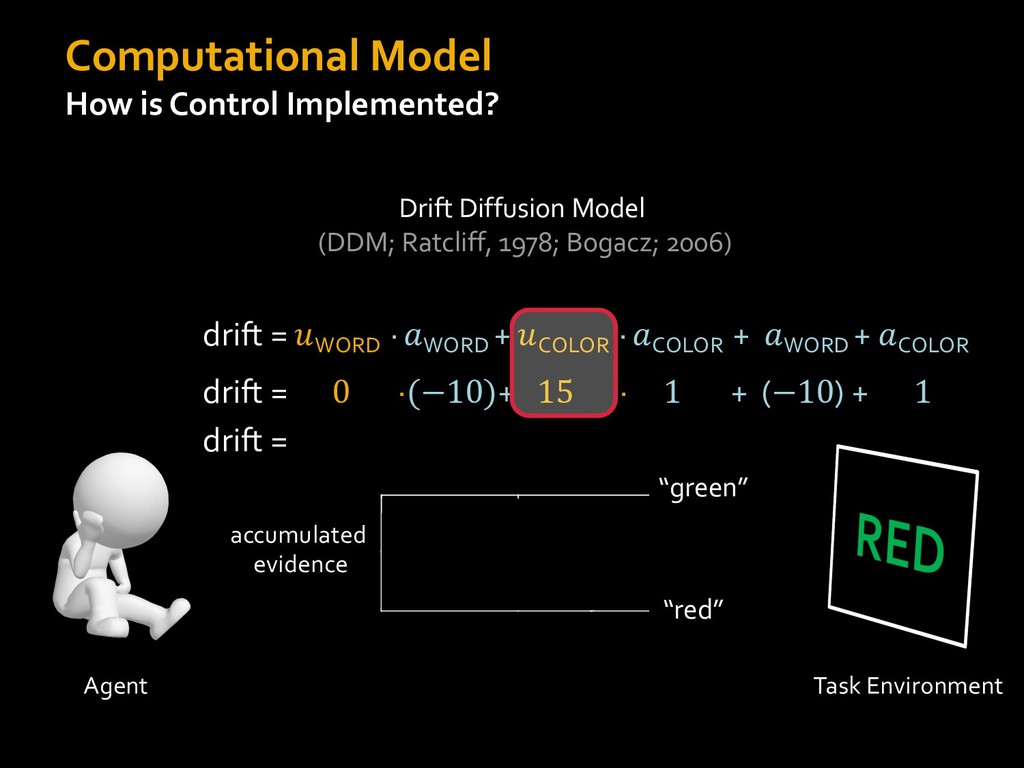
COLOR + " WORD + " COLOR drift = ·(−10)+ · 1 + (−10) + 1 Computational Model How is Control Implemented? Agent Task Environment Drift Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence -
drift = ! WORD ·" WORD + ! COLOR ·"
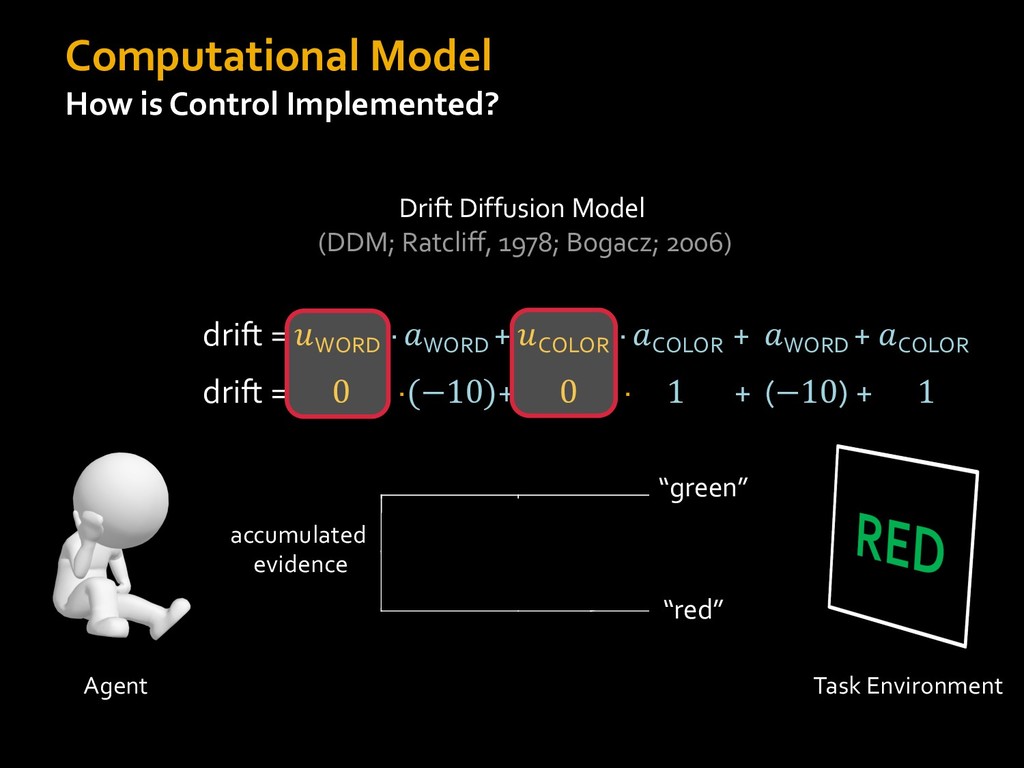
COLOR + " WORD + " COLOR drift = 0 ·(−10)+ 0 · 1 + (−10) + 1 Computational Model How is Control Implemented? Agent Task Environment Drift Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence -
drift = ! WORD ·" WORD + ! COLOR ·"
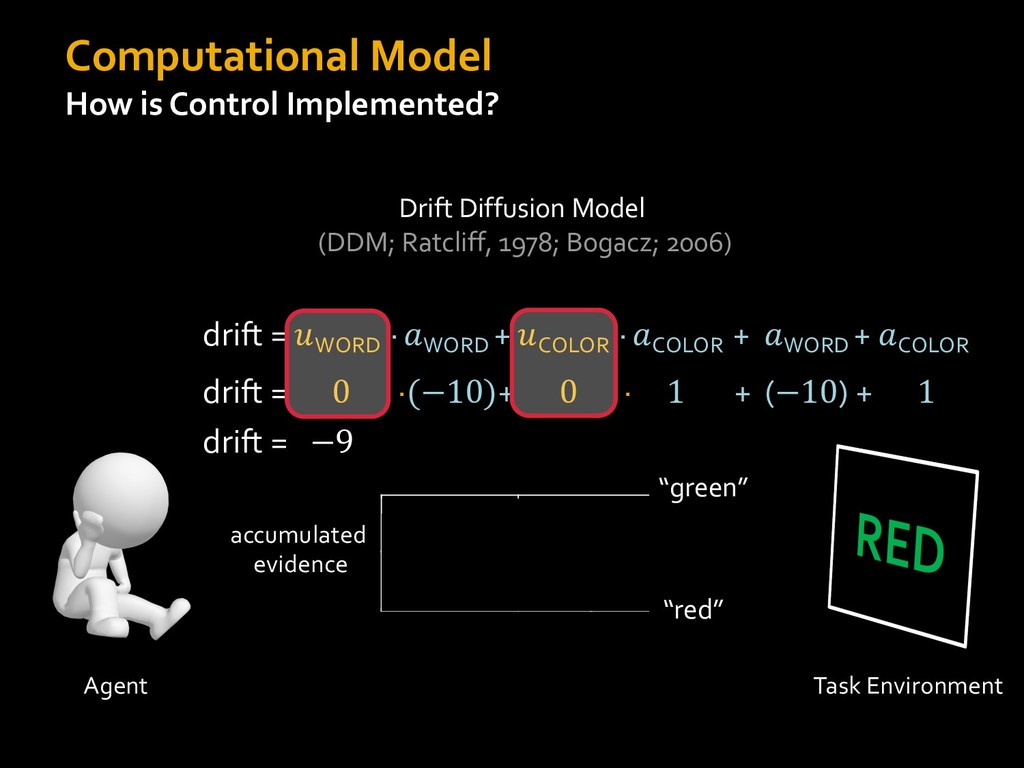
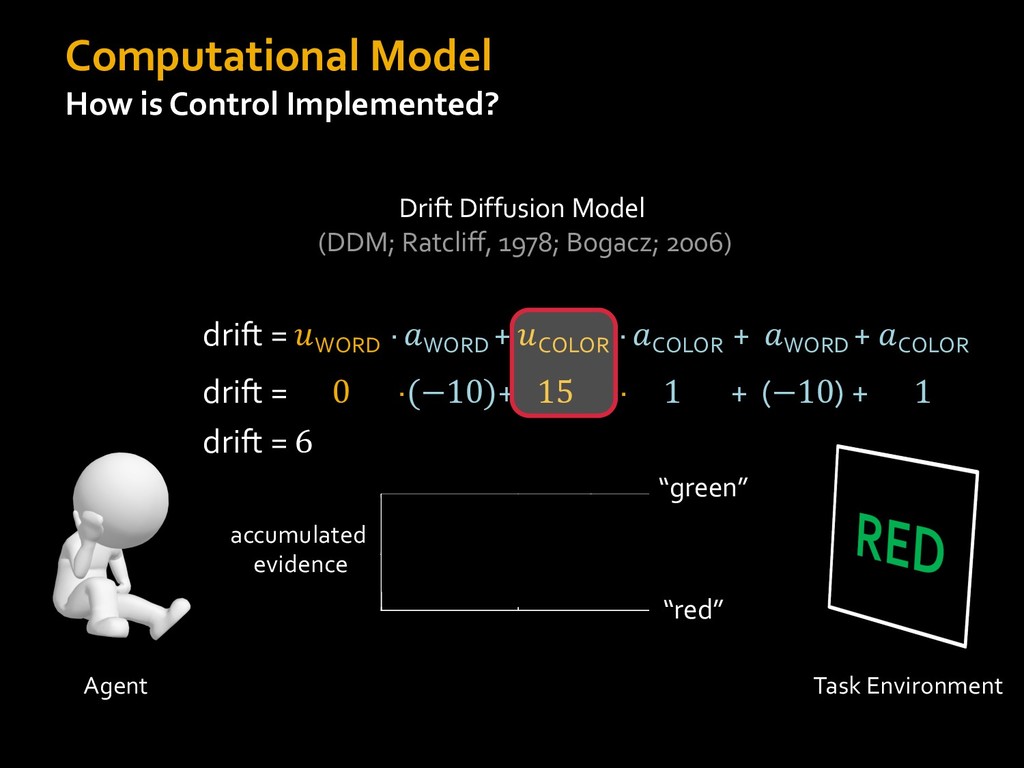
COLOR + " WORD + " COLOR drift = 0 ·(−10)+ 0 · 1 + (−10) + 1 Computational Model How is Control Implemented? Agent Task Environment Drift Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence drift = −9 t 0 -
drift = ! WORD ·" WORD + ! COLOR ·"
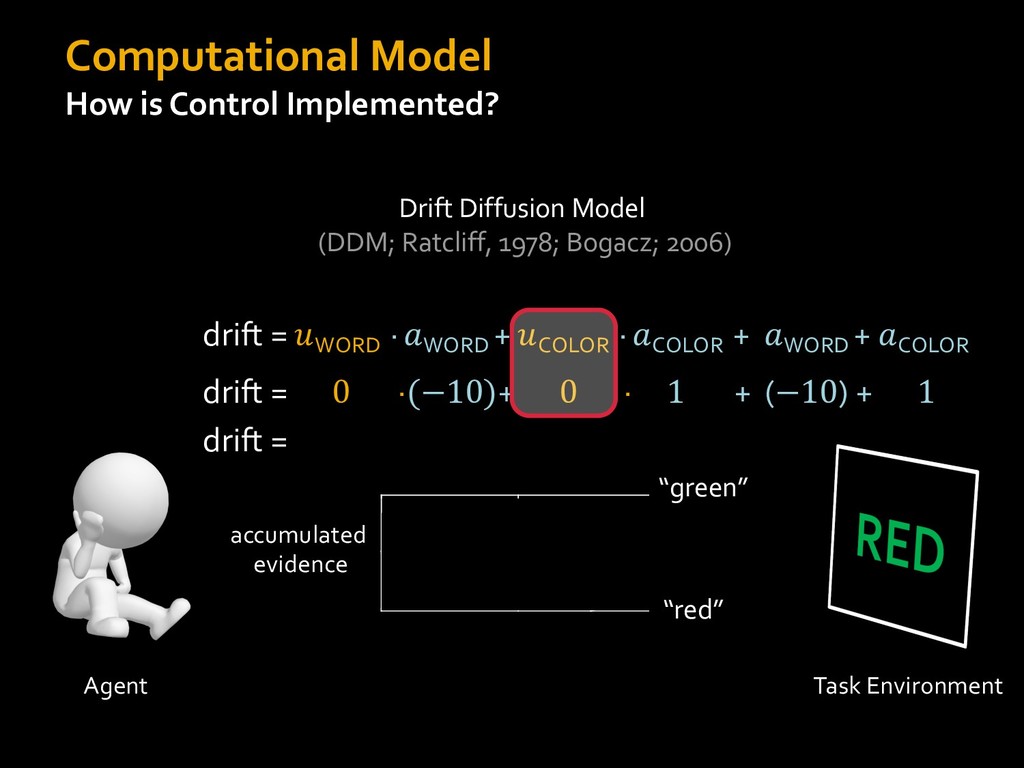
COLOR + " WORD + " COLOR drift = 0 ·(−10)+ 0 · 1 + (−10) + 1 Computational Model How is Control Implemented? Agent Task Environment Drift Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence drift = -
drift = ! WORD ·" WORD + ! COLOR ·"
COLOR + " WORD + " COLOR drift = 0 ·(−10)+ 15 · 1 + (−10) + 1 Computational Model How is Control Implemented? Agent Task Environment Drift Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence drift = -
drift = ! WORD ·" WORD + ! COLOR ·"
COLOR + " WORD + " COLOR drift = 0 ·(−10)+ 15 · 1 + (−10) + 1 Computational Model How is Control Implemented? Agent Task Environment Drift Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence drift = 6 -
drift = ! WORD ·" WORD + ! COLOR ·"
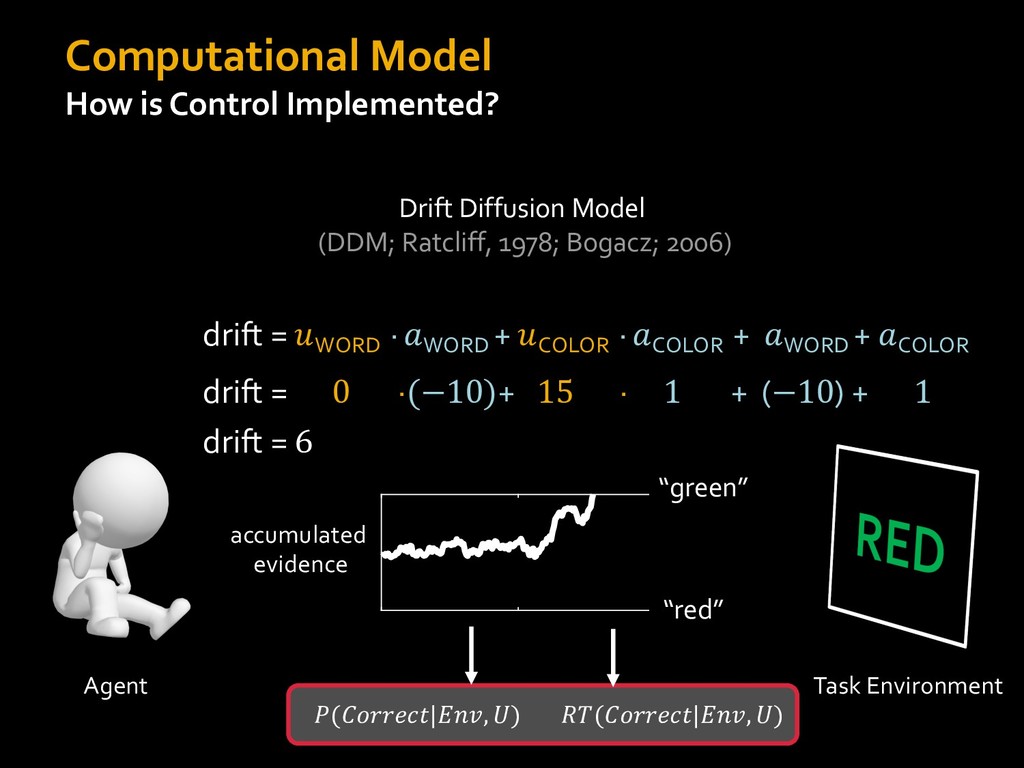
COLOR + " WORD + " COLOR Computational Model How is Control Implemented? Agent Task Environment Drift Diffusion Model (DDM; Ratcliff, 1978; Bogacz; 2006) t 0 “red” “green” accumulated evidence #(%&''()*|,-., 0) 23(%&''()*|,-., 0) drift = 0 ·(−10)+ 15 · 1 + (−10) + 1 drift = 6 -
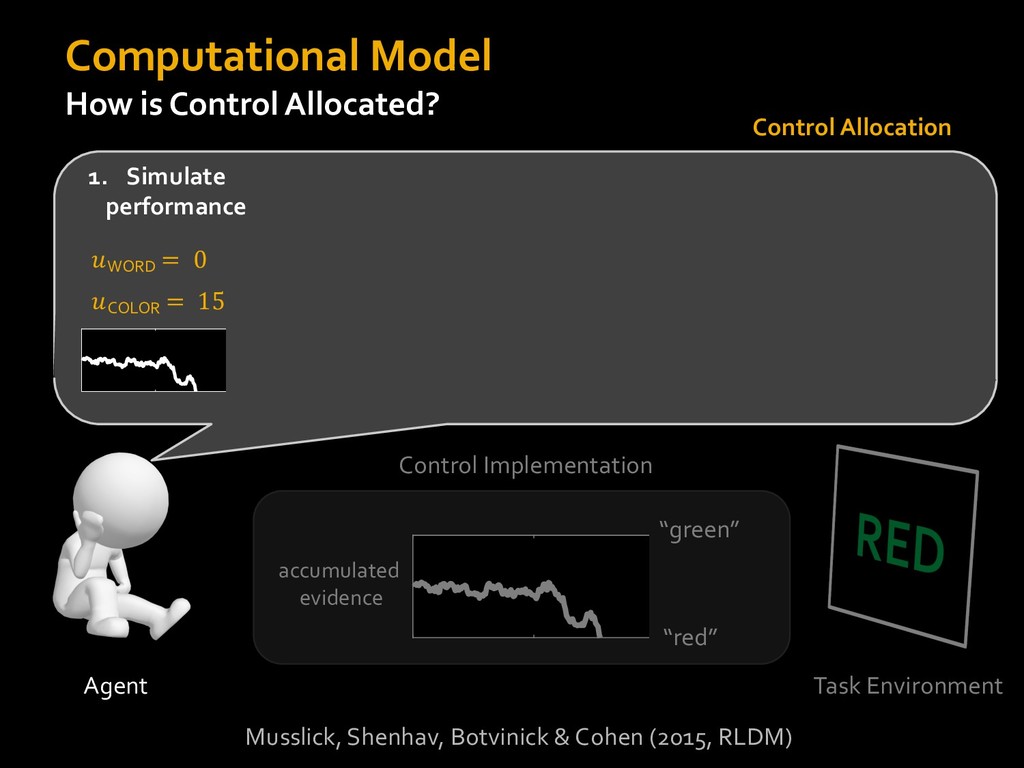
Computational Model How is Control Allocated? Agent Task Environment t
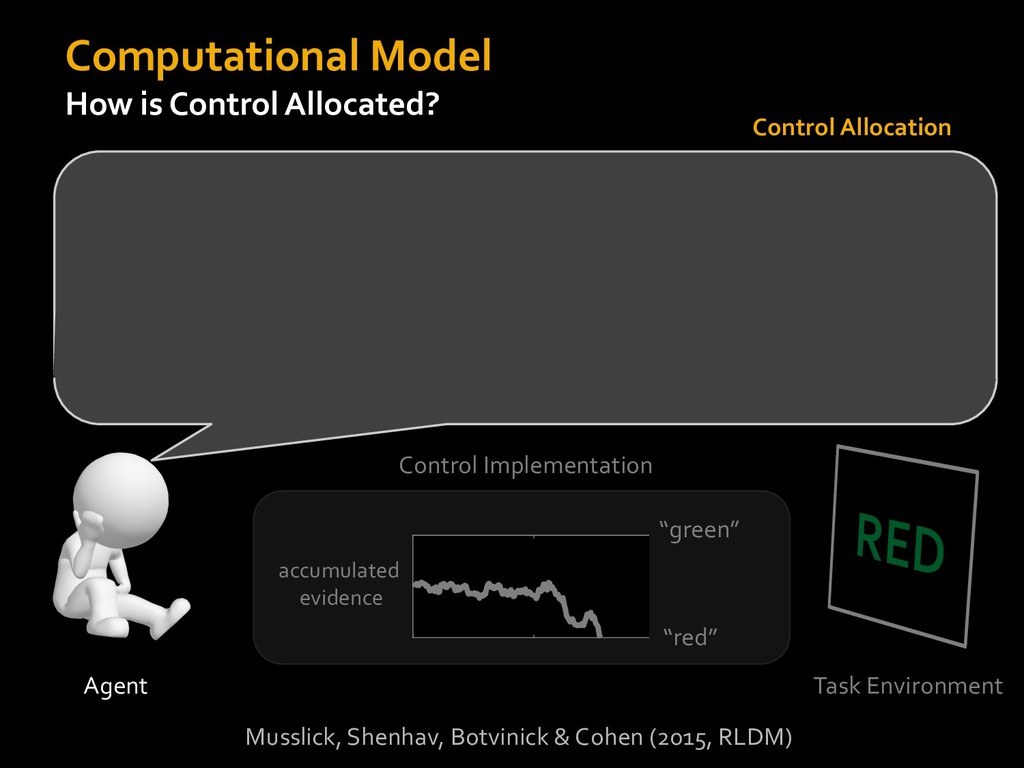
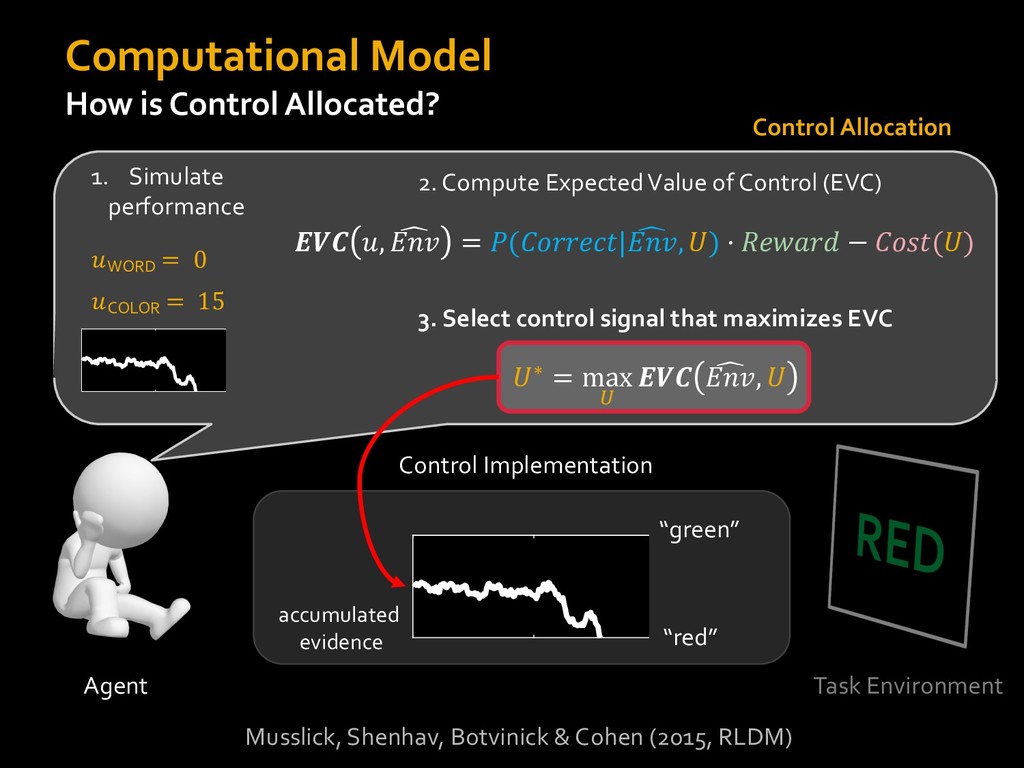
0 “red” “green” accumulated evidence Control Implementation Musslick, Shenhav, Botvinick & Cohen (2015, RLDM) Control Allocation -
Computational Model How is Control Allocated? Agent Task Environment t
0 “red” “green” accumulated evidence Control Implementation Musslick, Shenhav, Botvinick & Cohen (2015, RLDM) ! WORD = 0 ! COLOR = 15 t 0 1. Simulate performance Control Allocation -
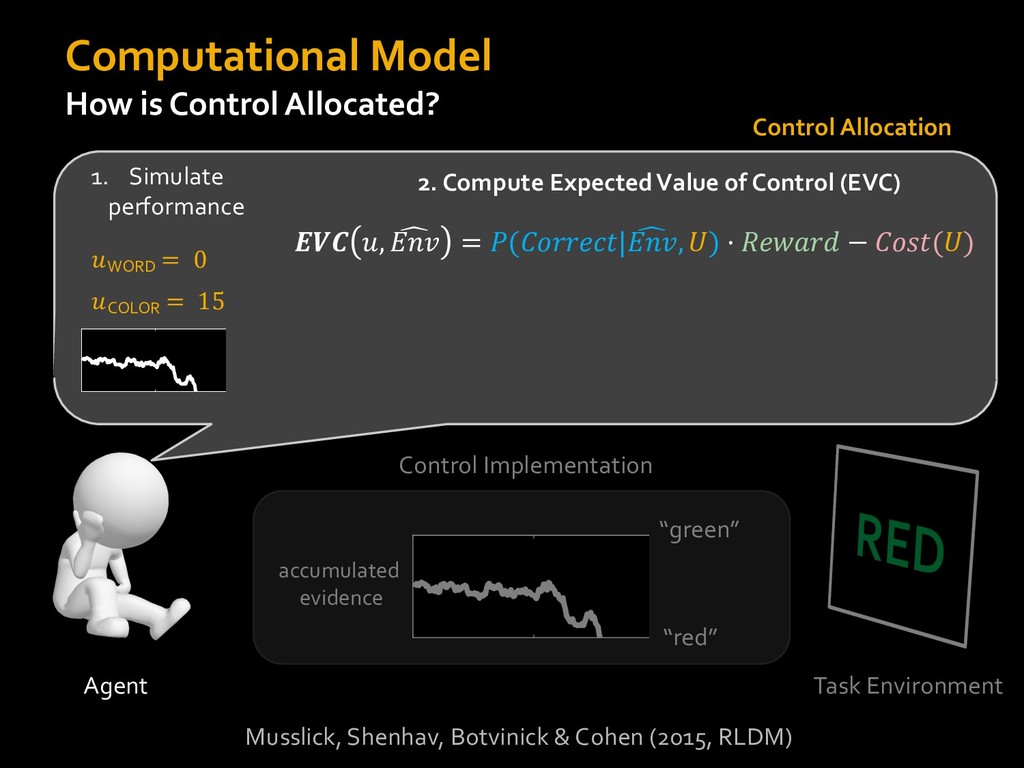
Computational Model How is Control Allocated? Agent Task Environment t
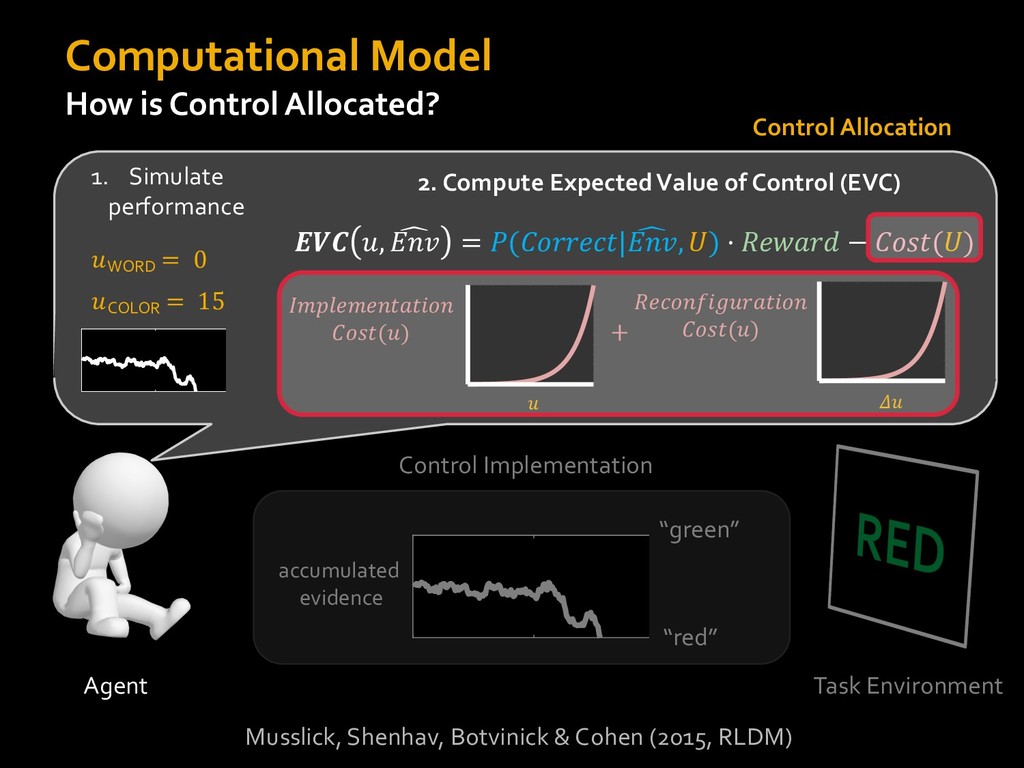
0 “red” “green” accumulated evidence Control Implementation Musslick, Shenhav, Botvinick & Cohen (2015, RLDM) ! WORD = 0 ! COLOR = 15 t 0 2. Compute Expected Value of Control (EVC) 1. Simulate performance &'( !, * +,- = .(0122345| * +,-, 7) · :3;<2= − 01?5(7) Control Allocation -
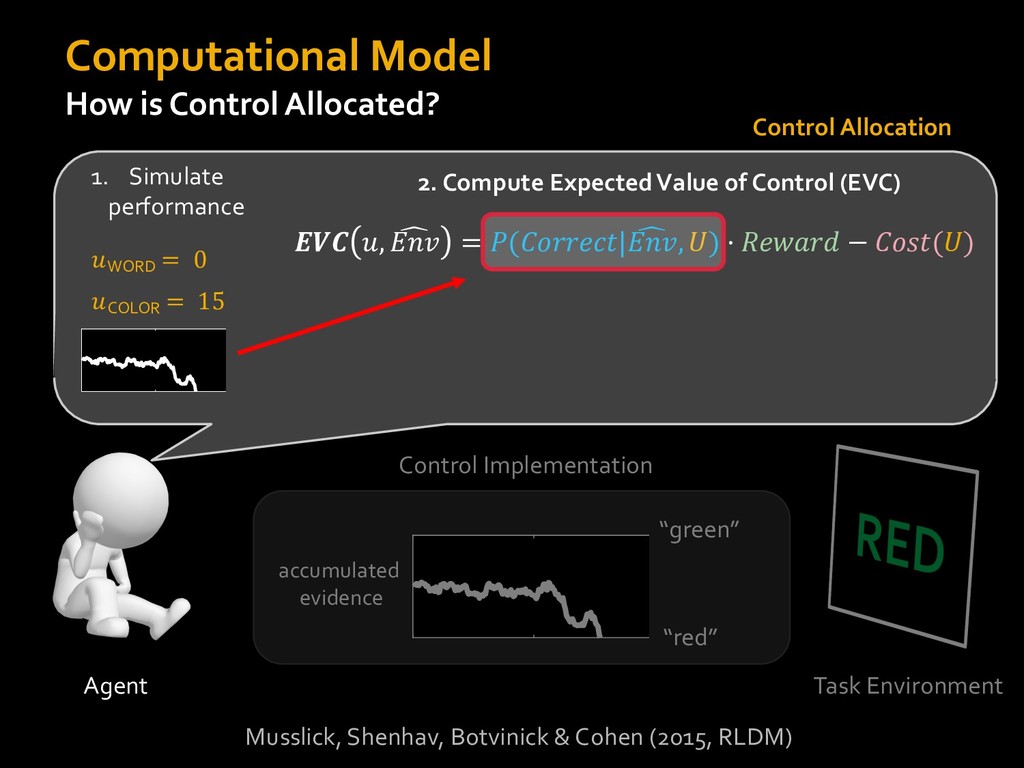
Computational Model How is Control Allocated? Agent Task Environment t
0 “red” “green” accumulated evidence Control Implementation Musslick, Shenhav, Botvinick & Cohen (2015, RLDM) ! WORD = 0 ! COLOR = 15 t 0 2. Compute Expected Value of Control (EVC) 1. Simulate performance &'( !, * +,- = .(0122345| * +,-, 7) · :3;<2= − 01?5(7) Control Allocation -
Computational Model How is Control Allocated? Agent Task Environment t
0 “red” “green” accumulated evidence Control Implementation Musslick, Shenhav, Botvinick & Cohen (2015, RLDM) ! WORD = 0 ! COLOR = 15 t 0 2. Compute Expected Value of Control (EVC) 1. Simulate performance Control Allocation &'( !, * +,- = .(0122345| * +,-, 7) · :3;<2= − 01?5(7) -
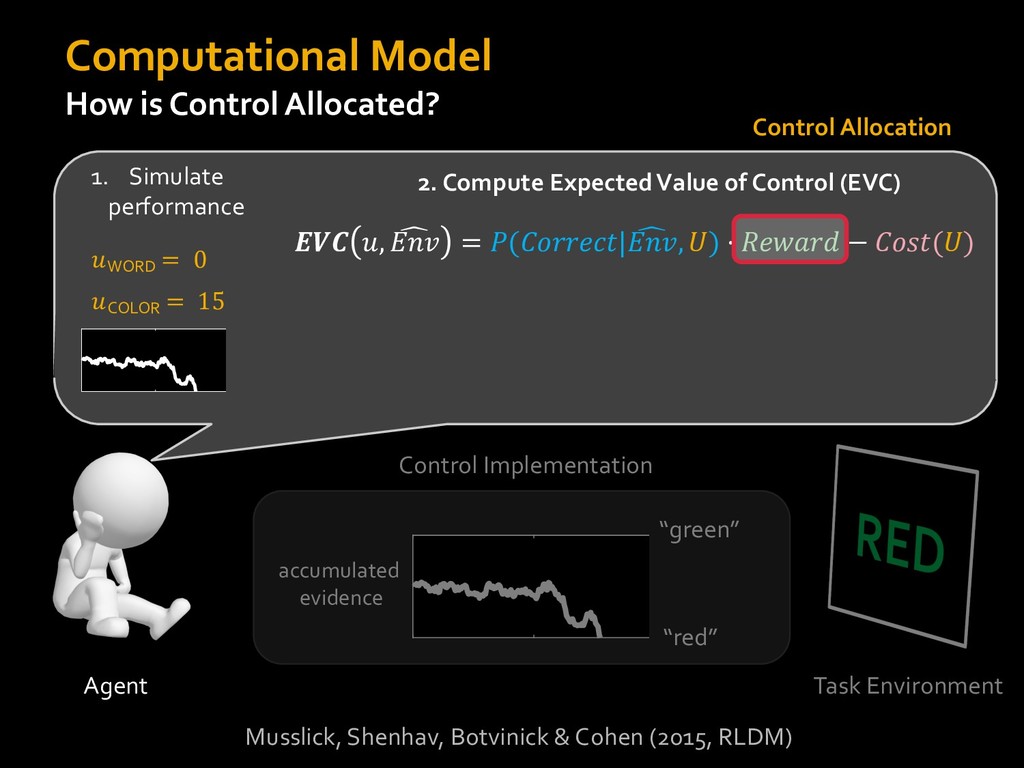
Computational Model How is Control Allocated? Agent Task Environment t
0 “red” “green” accumulated evidence Control Implementation Musslick, Shenhav, Botvinick & Cohen (2015, RLDM) !WORD = 0 !COLOR = 15 t 0 2. Compute Expected Value of Control (EVC) 1. Simulate performance Control Allocation &'()*'*+,-,./+ 0/1,(!) ! 4*5/+6.7!8-,./+ 0/1,(!) 9! + ;<= !, ? @+A = B(0/88*5,| ? @+A, D) · 4*F-8G − 0/1,(D) -
Computational Model How is Control Allocated? Agent Task Environment t
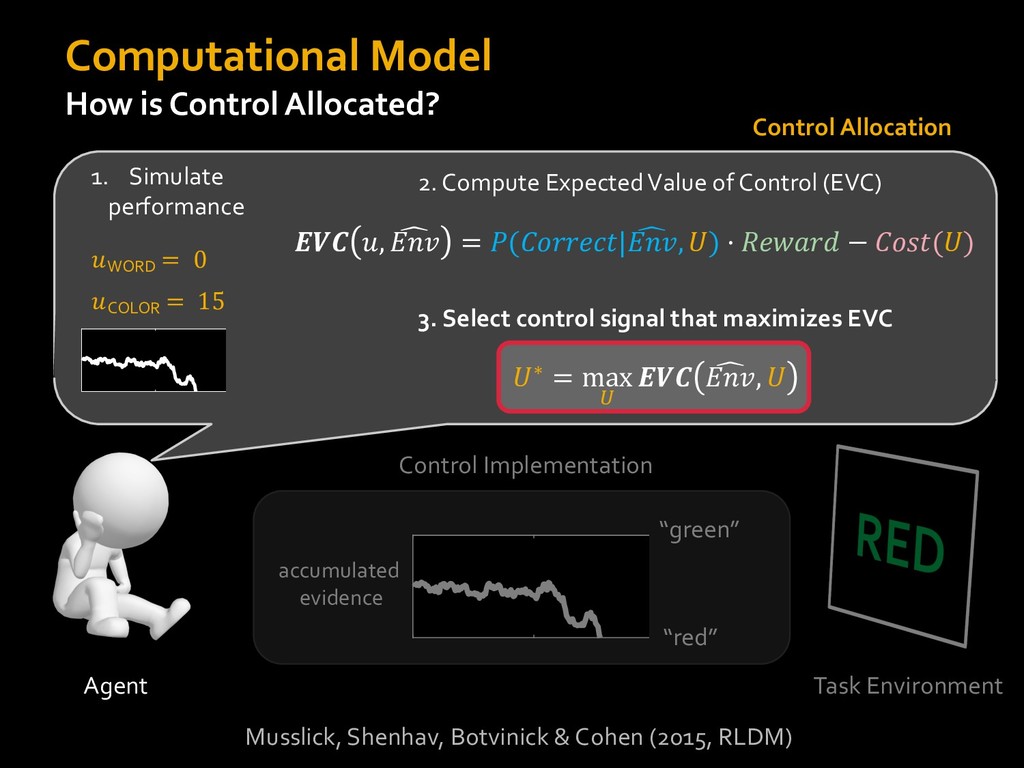
0 “red” “green” accumulated evidence Control Implementation Musslick, Shenhav, Botvinick & Cohen (2015, RLDM) ! WORD = 0 ! COLOR = 15 t 0 2. Compute Expected Value of Control (EVC) 1. Simulate performance Control Allocation &'( !, * +,- = .(0122345| * +,-, 7) · :3;<2= − 01?5(7) 3. Select control signal that maximizes EVC 7∗ = max D &'( * +,-, 7 -
Computational Model How is Control Allocated? Agent Task Environment t
0 “red” “green” accumulated evidence Control Implementation Musslick, Shenhav, Botvinick & Cohen (2015, RLDM) ! WORD = 0 ! COLOR = 15 t 0 2. Compute Expected Value of Control (EVC) 1. Simulate performance Control Allocation &'( !, * +,- = .(0122345| * +,-, 7) · :3;<2= − 01?5(7) 3. Select control signal that maximizes EVC 7∗ = max D &'( * +,-, 7 -
A Computational Model of Control Allocation Based on the Expected
Value of Control A. The Theory B. The Model C. Simulations & Predictions D. Estimating Mental Effort from Behavior -
Cognitive Control Phenomena Basic Phenomena Incongruency Costs (Stroop, 1935) Switch
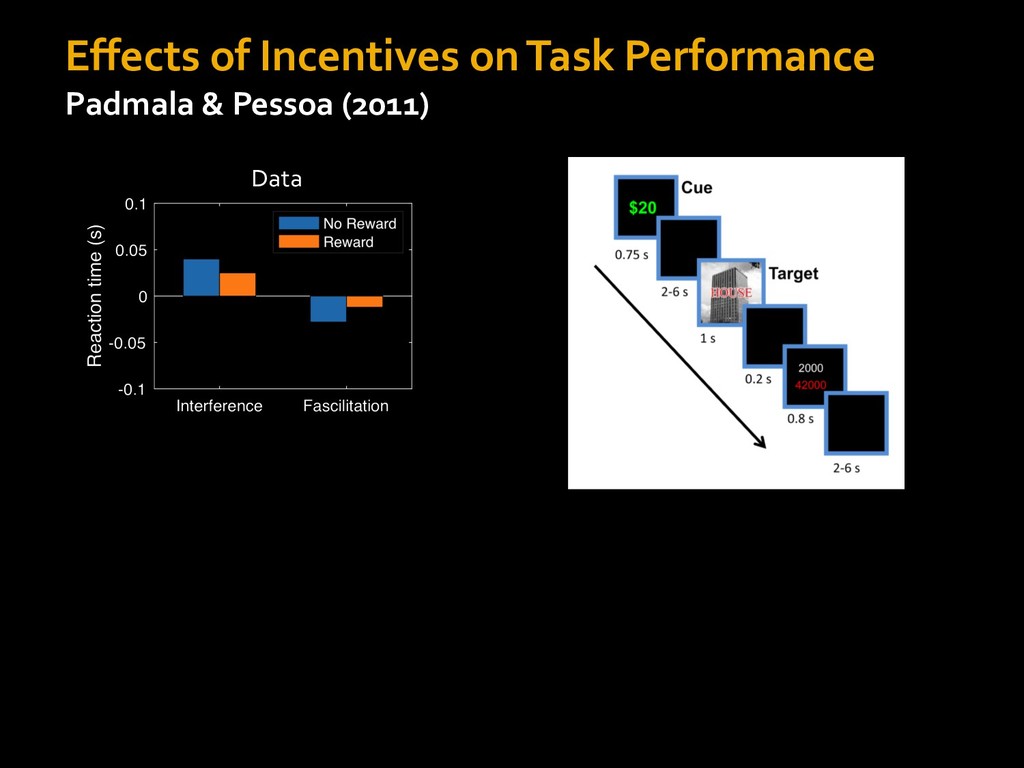
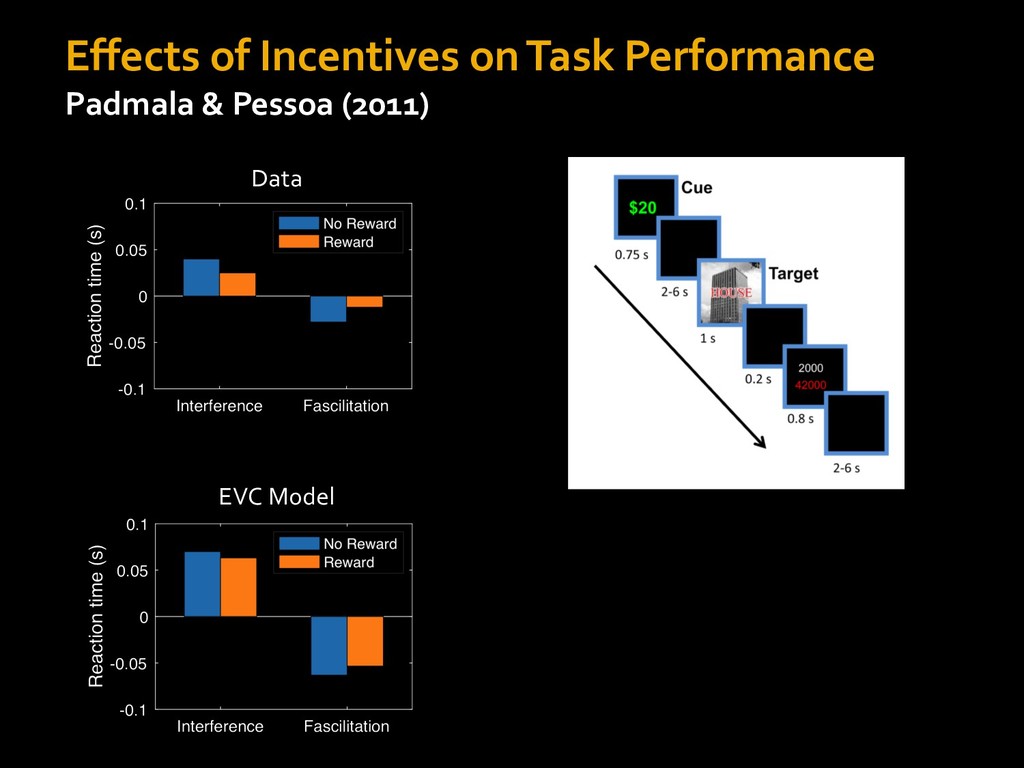
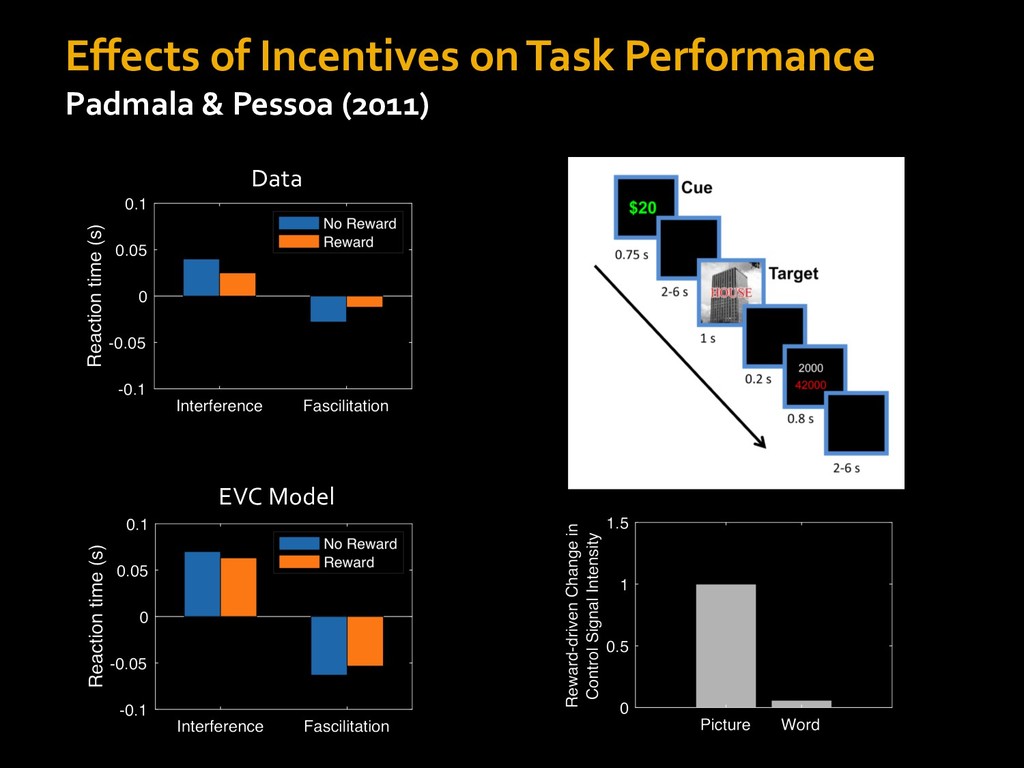
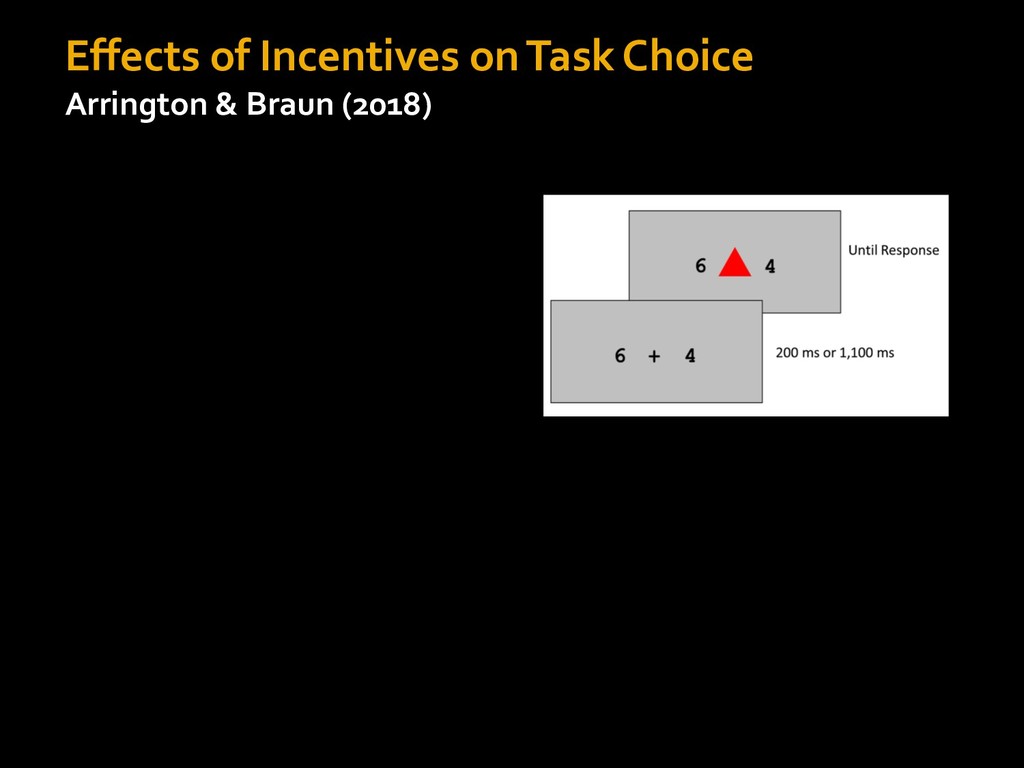
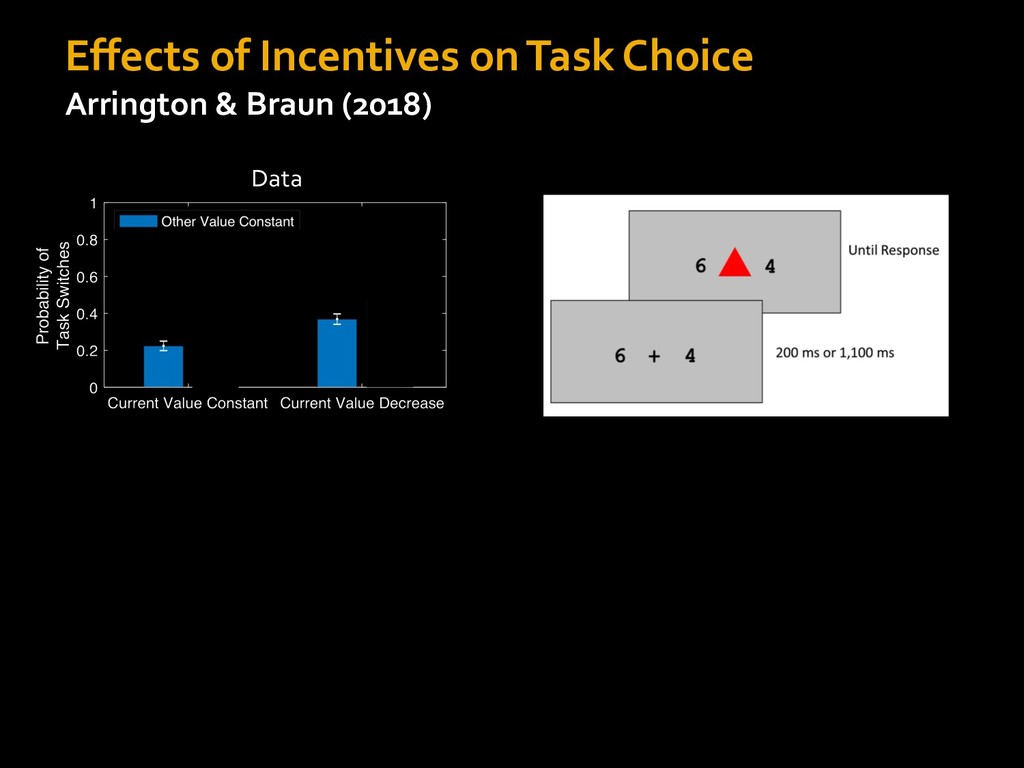
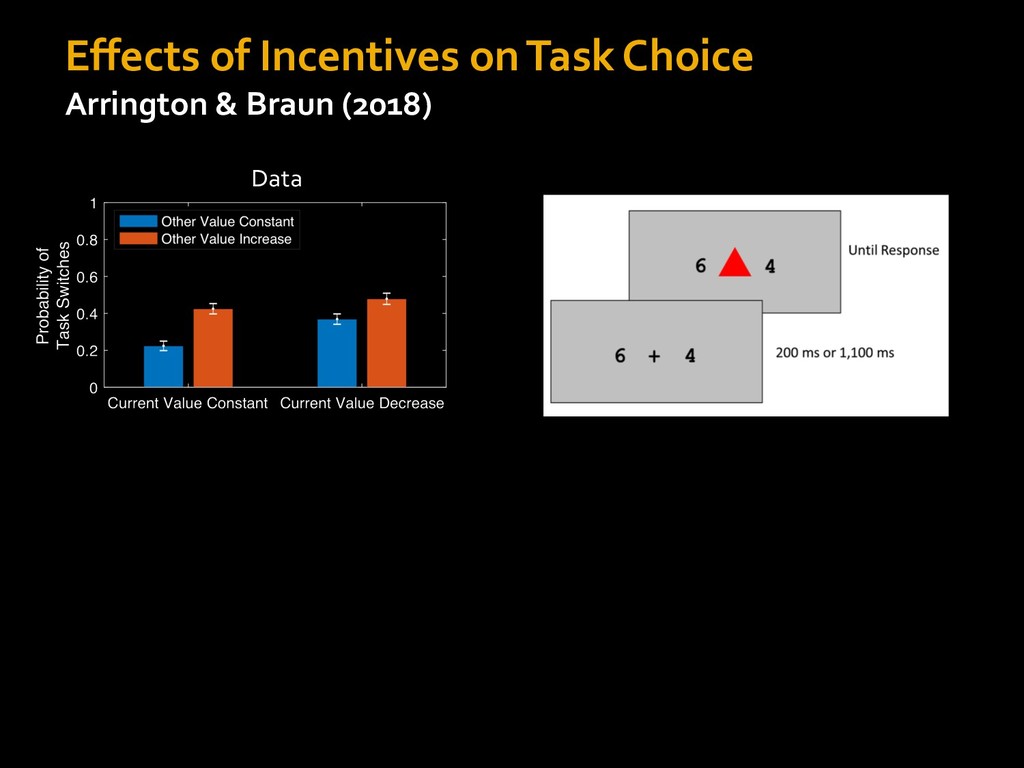
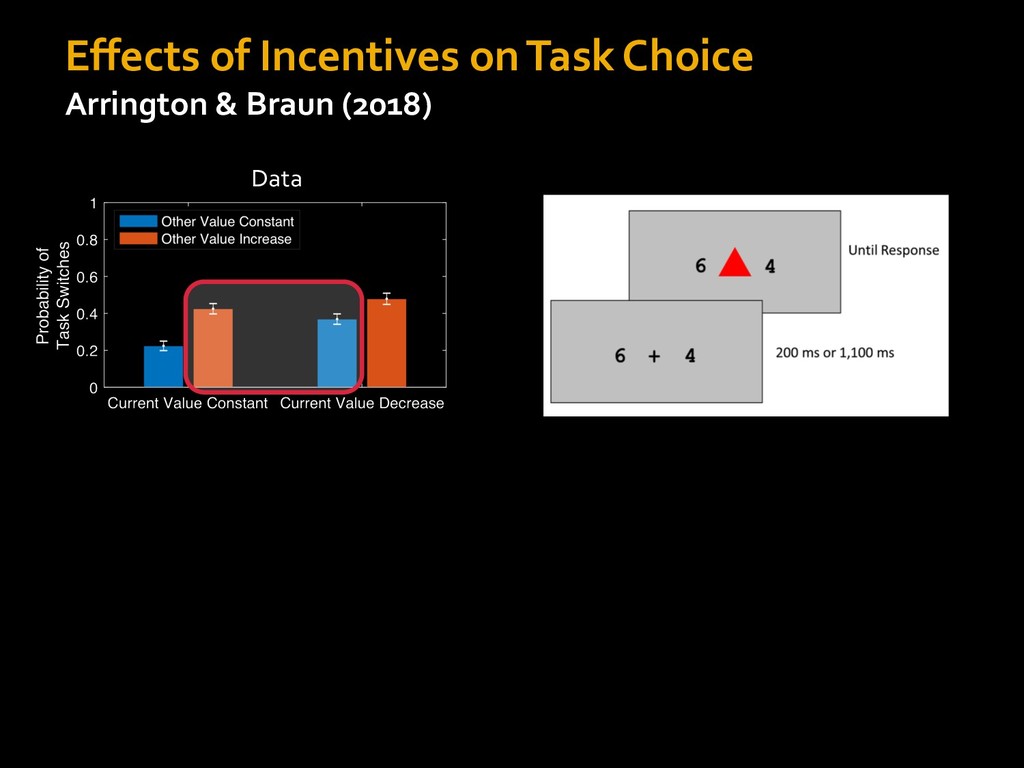
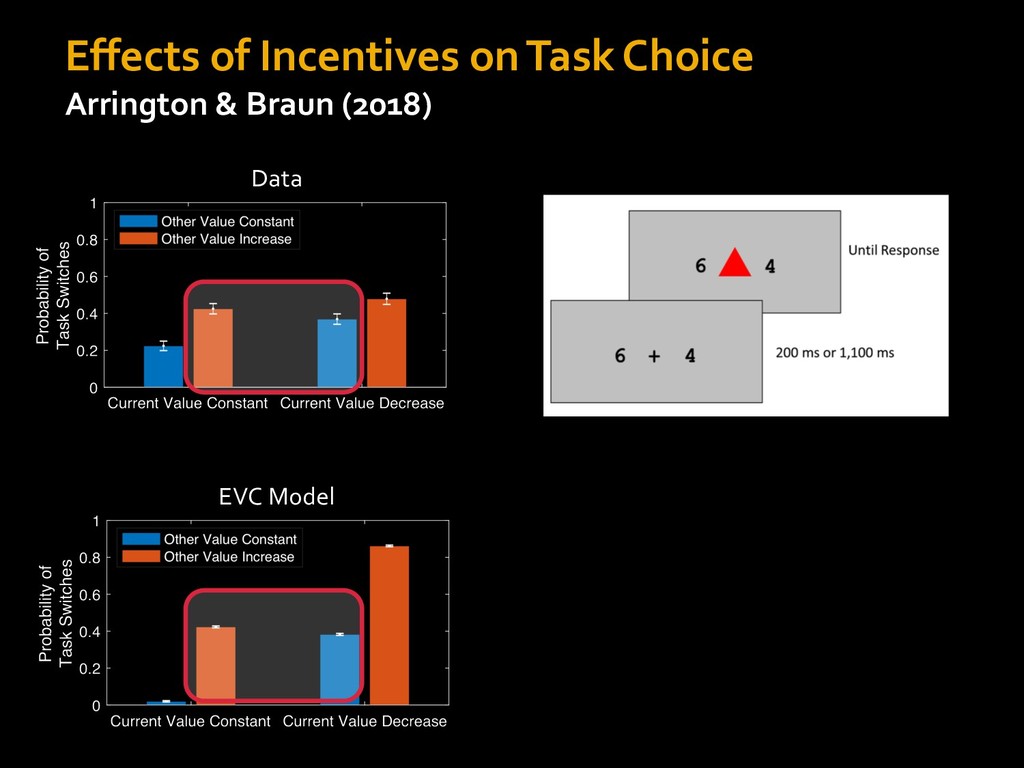
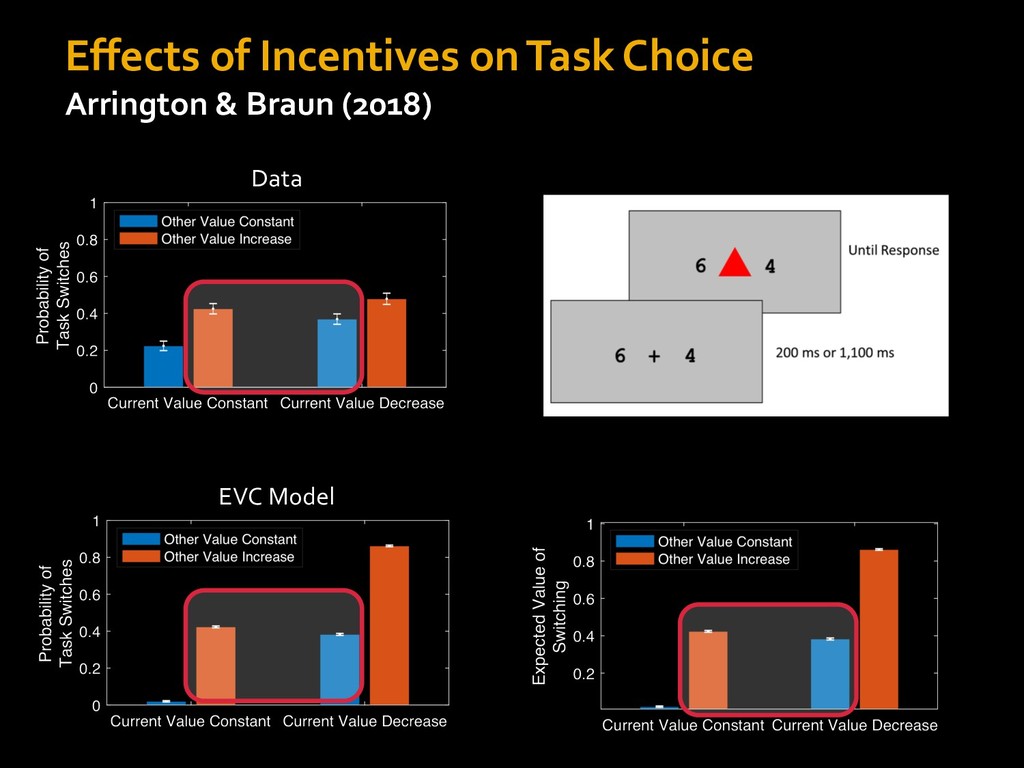
Costs (Allport, 1994) Effects of Incentives on Task Performance Distractor Interference/Facilitation (Padmala & Pessoa) Reward & Switch Costs (Umemoto & Holroyd, 2015) Effects of Incentives on Task Choice Demand Avoidance (Kool et al., 2010) Cognitive Effort Discounting (Westbrook & Braver, 2015) Reward and Voluntary Task Switching (Arrington & Braun, 2017) Adaptation to Task Difficulty Congruency Sequence Effect (Gratton, 1992) Proportion Congruency Effect (Logan & Zbrodoff, 1979) Non-Monotonicity in Task Engagement (Gilzenrat, 2010) Stability-Flexibility Tradeoff (Goschke, 2000) -
Cognitive Control Phenomena Basic Phenomena Incongruency Costs (Stroop, 1935) Switch
Costs (Allport, 1994) Effects of Incentives on Task Performance Distractor Interference/Facilitation (Padmala & Pessoa) Reward & Switch Costs (Umemoto & Holroyd, 2015) Effects of Incentives on Task Choice Demand Avoidance (Kool et al., 2010) Cognitive Effort Discounting (Westbrook & Braver, 2015) Reward and Voluntary Task Switching (Arrington & Braun, 2017) Adaptation to Task Difficulty Congruency Sequence Effect (Gratton, 1992) Proportion Congruency Effect (Logan & Zbrodoff, 1979) Non-Monotonicity in Task Engagement (Gilzenrat, 2010) Stability-Flexibility Tradeoff (Goschke, 2000) -
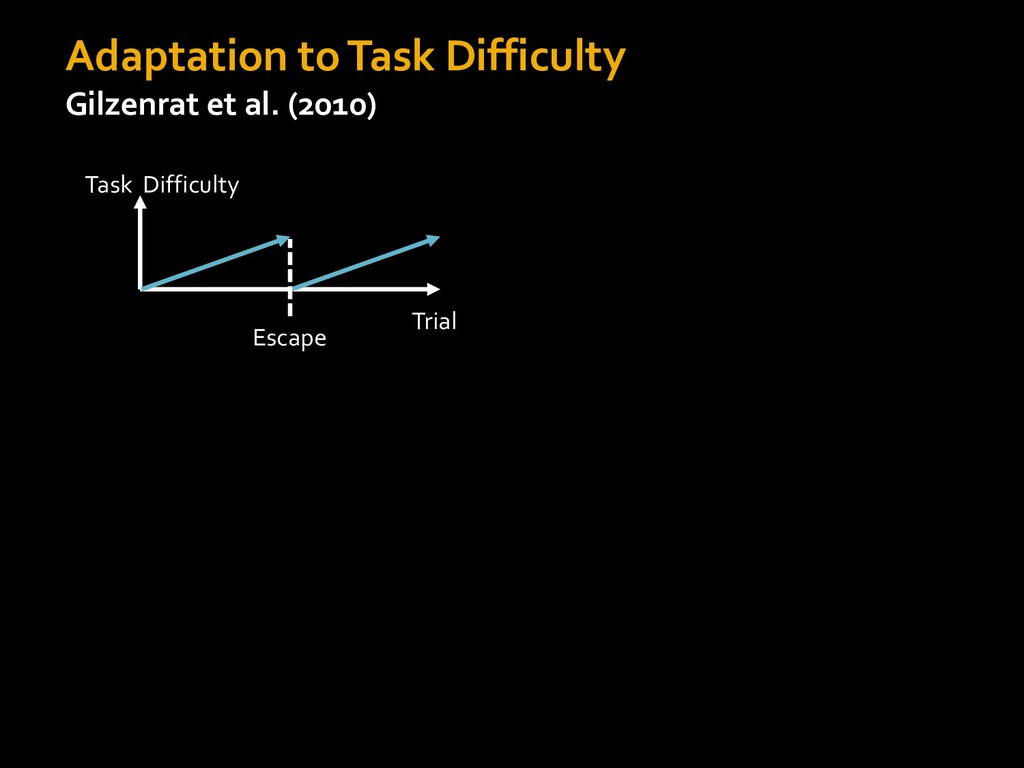
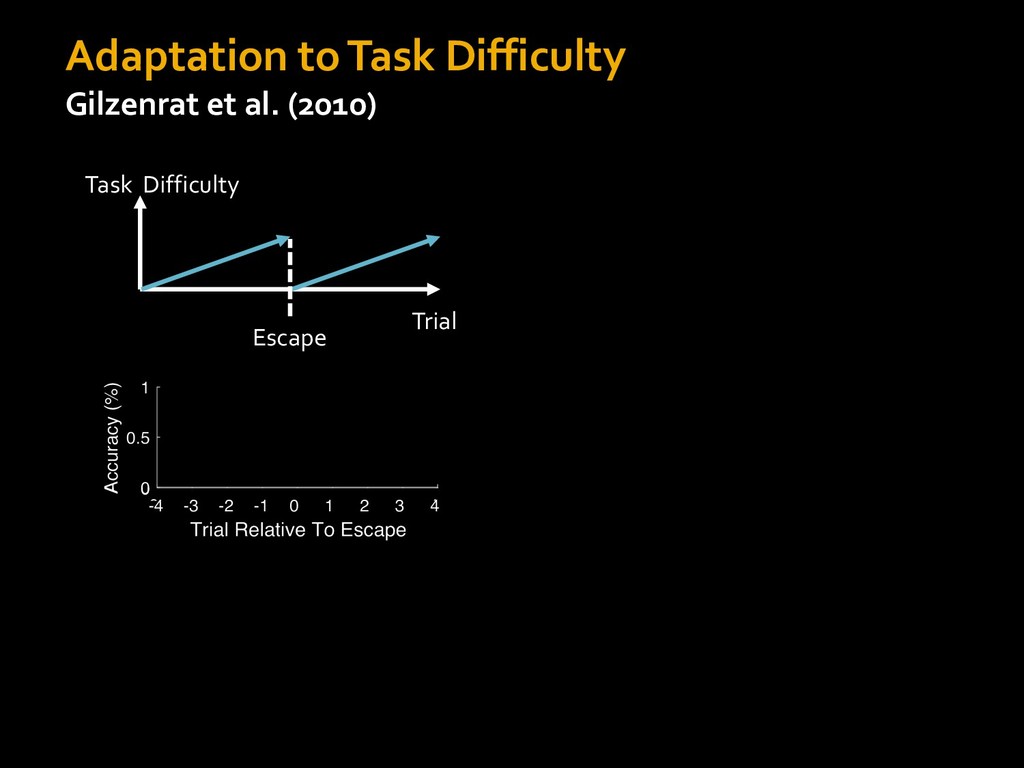
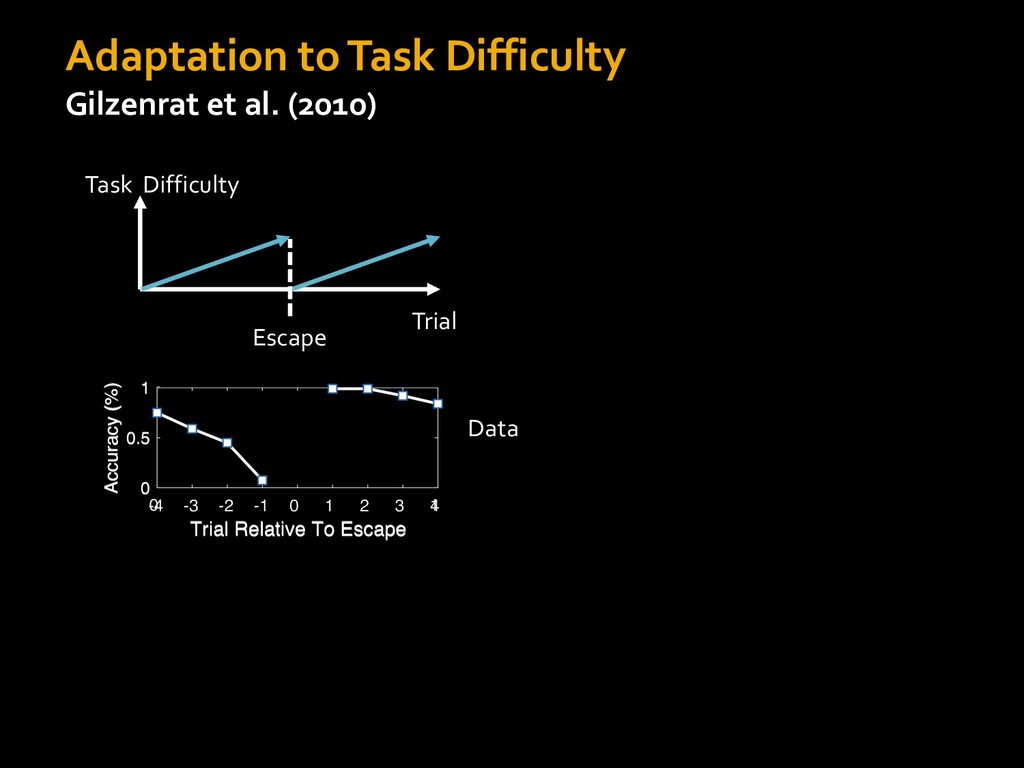
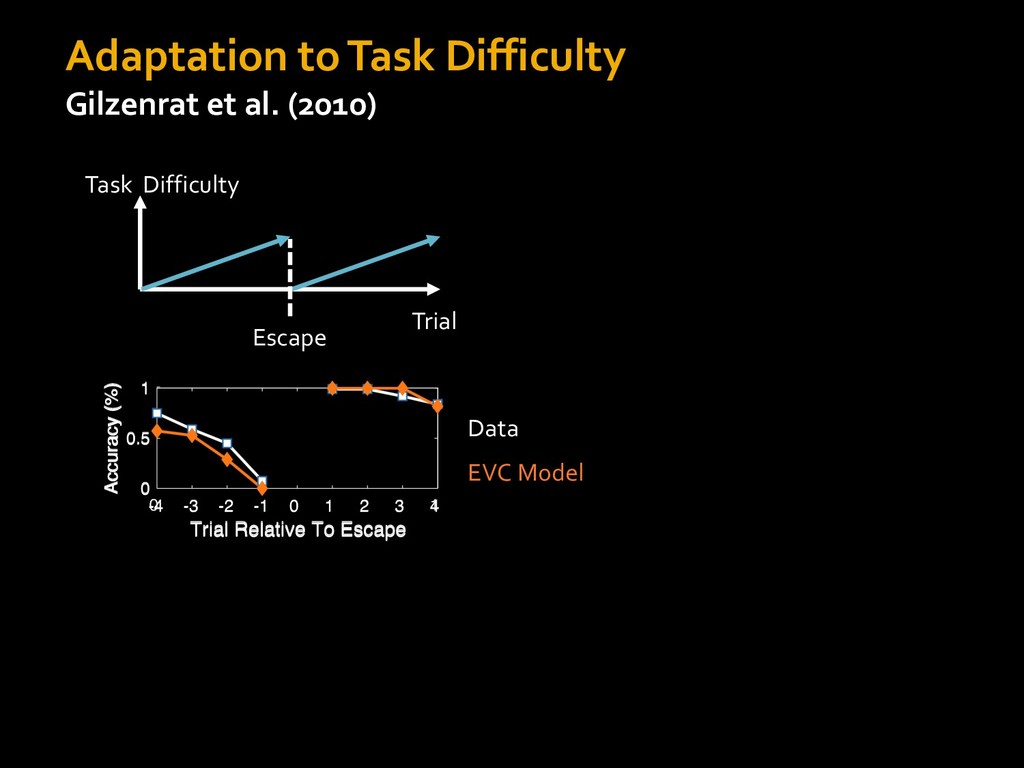
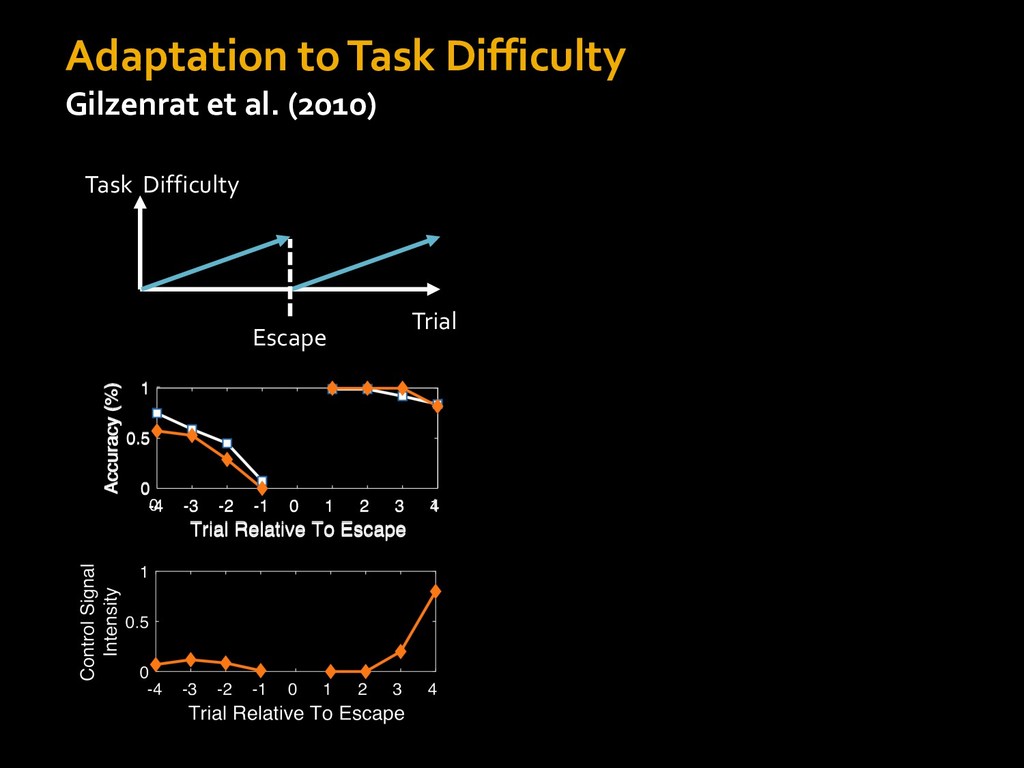
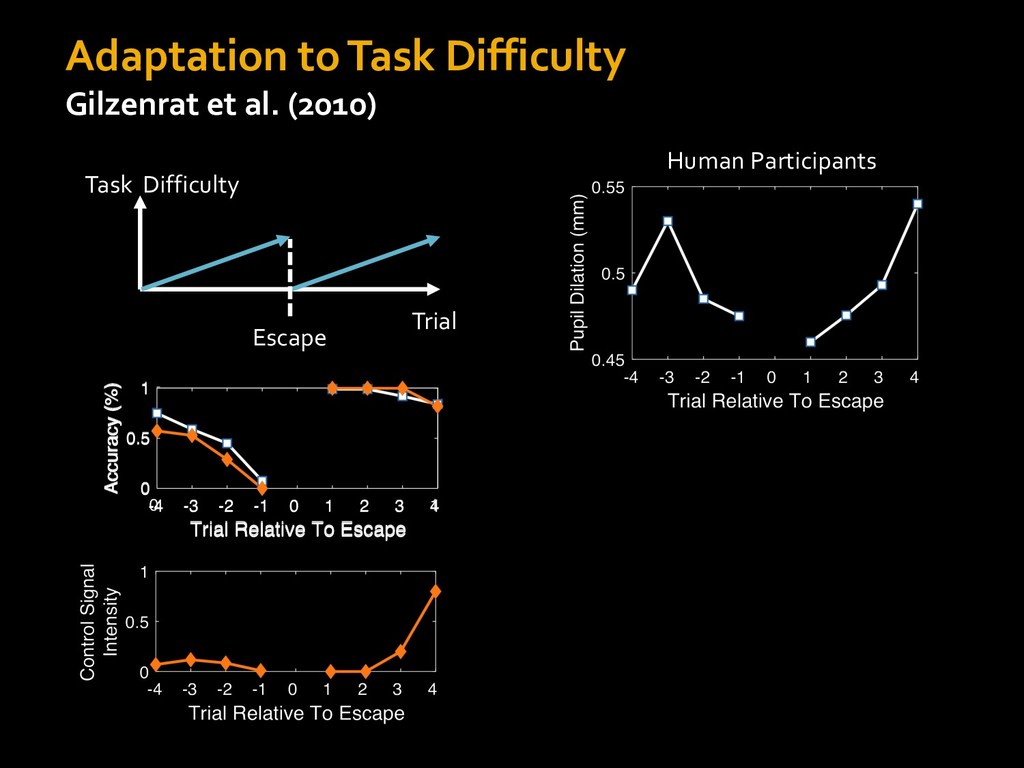
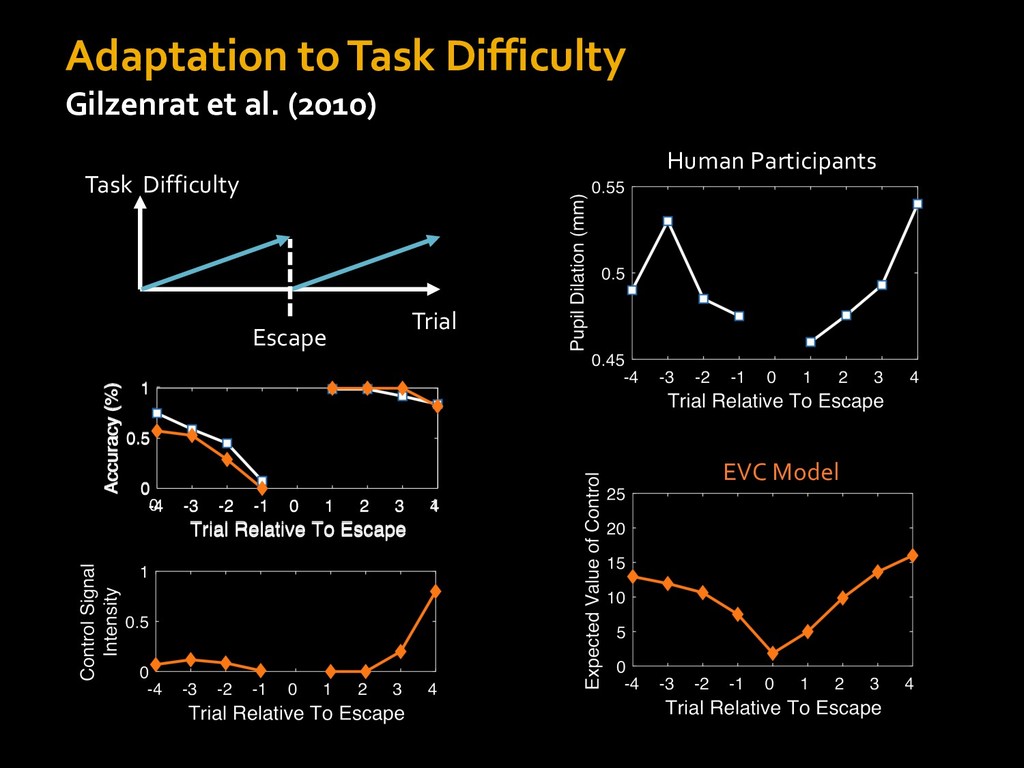
Adaptation to Task Difficulty Gilzenrat et al. (2010) Task Difficulty
Trial Escape Data -
Adaptation to Task Difficulty Gilzenrat et al. (2010) Task Difficulty
Trial Escape Data EVC Model -
Adaptation to Task Difficulty Gilzenrat et al. (2010) Task Difficulty
Trial Escape Human Participants -
Adaptation to Task Difficulty Gilzenrat et al. (2010) Task Difficulty
Trial Escape EVC Model Human Participants -
A Computational Model of Control Allocation Based on the Expected
Value of Control A. The Theory B. The Model C. Simulations & Predictions D. Estimating Mental Effort from Behavior -
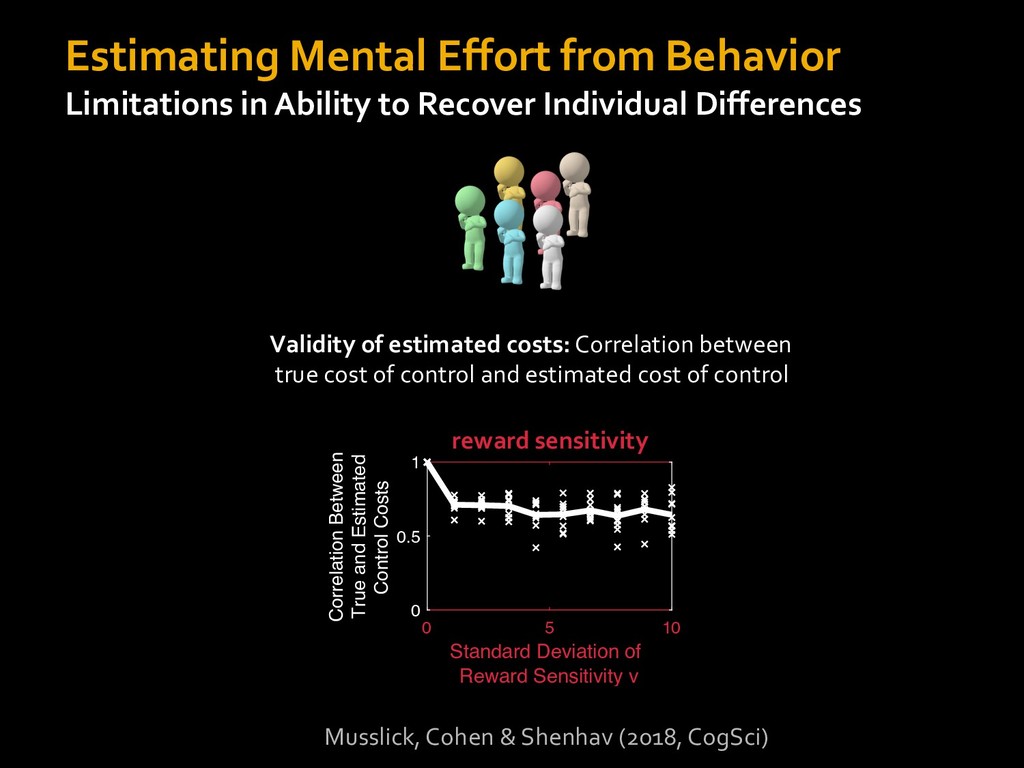
Estimating Mental Effort from Behavior Limitations in Ability to Recover
Individual Differences Validity of estimated costs: Correlation between true cost of control and estimated cost of control 0 5 10 Standard Deviation of Reward Sensitivity v 0 0.5 1 Correlation Between True and Estimated Control Costs reward sensitivity Musslick, Cohen & Shenhav (2018, CogSci) -
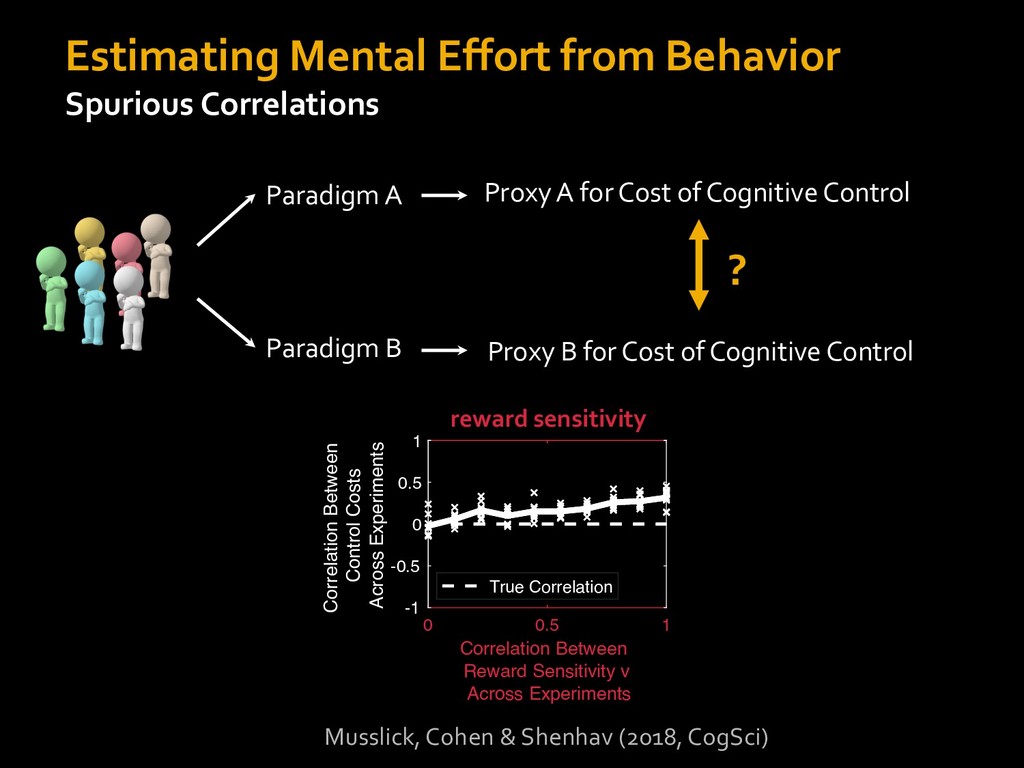
Estimating Mental Effort from Behavior Spurious Correlations Paradigm A Paradigm
B Proxy A for Cost of Cognitive Control Proxy B for Cost of Cognitive Control ? 0 0.5 1 Correlation Between Reward Sensitivity v Across Experiments -1 -0.5 0 0.5 1 Correlation Between Control Costs Across Experiments True Correlation reward sensitivity Musslick, Cohen & Shenhav (2018, CogSci) -
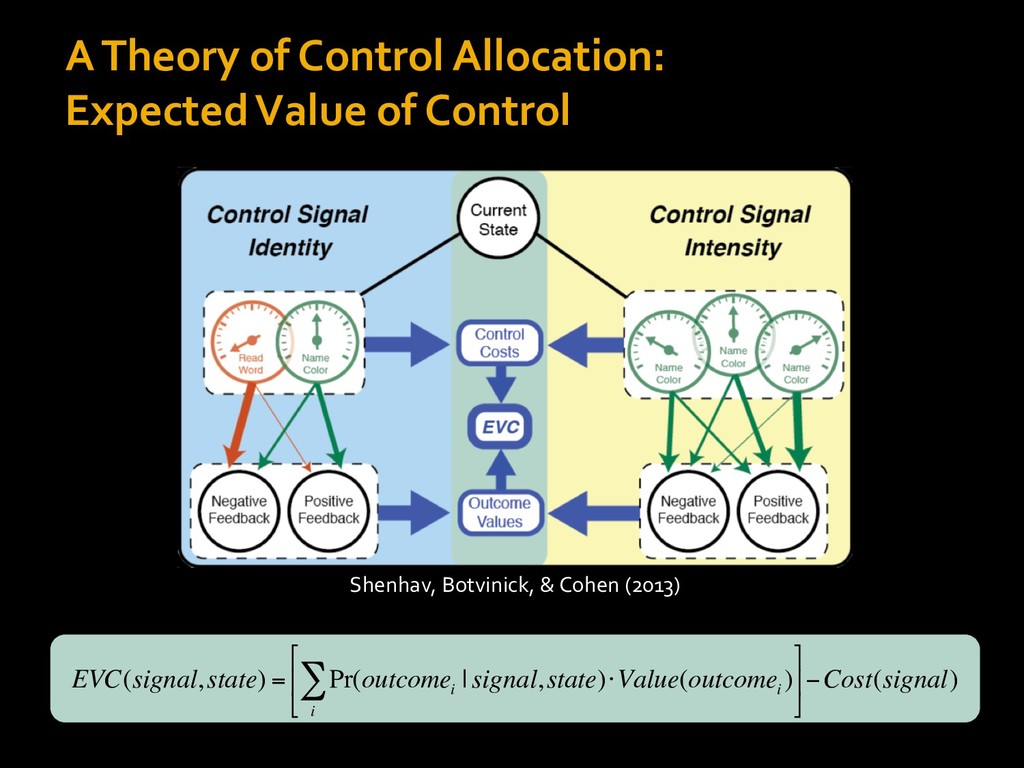
A Theory of Control Allocation: Expected Value of Control GREEN
EVC(signal,state) = Pr(outcome i i ∑ | signal,state)⋅Value(outcome i ) # $ % & ' (−Cost(signal) Shenhav, Botvinick, & Cohen (2013)