Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
(CVPR2024) Eyes Wide Shut? Exploring the Visua...
Search
Kazuya Nishimura
April 23, 2025
Research
10
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
(CVPR2024) Eyes Wide Shut? Exploring the Visual Shortcomings of Multimodal LLMs
Kazuya Nishimura
April 23, 2025
More Decks by Kazuya Nishimura
See All by Kazuya Nishimura
Paper reading party (ICCV 2023): End-to-End Semi-Supervised Object Detection with Soft Teacher
naivete5656
0
11
(CVPR2022) Integrative Few-Shot Learning for Classification and Segmentation
naivete5656
0
15
(ECCV2024) Multistain Pretraining for Slide Representation Learning in Pathology
naivete5656
0
10
(CVPR2024) Modeling Dense Multimodal Interactions Between Biological Pathways and Histology for Survival Prediction
naivete5656
0
10
(Neurips 2024) HEST-1k: A Dataset for Spatial Transcriptomics and Histology Image Analysis
naivete5656
0
13
Deep generative modeling for single-cell transcriptomics
naivete5656
0
5
Other Decks in Research
See All in Research
PHTalks Bengaluru - SSRF When All Else Fails
dk999
0
1.2k
Santé et fertilité des sols : ce que nous disent les pratiques dans les systèmes de polyculture-élevage
institutdelelevage
PRO
0
130
ハードウェア研究で国際トップ会議を目指す!IROS 2027での論文採択を目指して
ayatokanada
7
4.1k
IA for theory
gpeyre
1
500
進化?迷走?CasualConc ファミリーアプリの現在地 @ 英語コーパス学会 2026
casualconc
0
150
湯村研究室の紹介2026 / yumulab2026
yumulab
0
150
COMETAを用いたデータ民主化運動の歴史
sazimai
0
290
2025年度秋葉原ウォーカブルプロジェクト調査報告 「アキバらしいウォーカブル」とは何か
izumiyama_lab
1
250
山中市政の総括:相反する二つの顔
sishi
0
220
研究室単位での自律的 IPv6接続性確立に向けたAS共同運用モデルの提案と実証
reokashiwa
PRO
0
230
山中市政が招いた組織崩壊:よこはま安心ボックスを例に
sishi
0
350
Bilan travail en élevage : première restitution des enquêtes 2025-2026
institutdelelevage
PRO
0
240
Featured
See All Featured
Digital Projects Gone Horribly Wrong (And the UX Pros Who Still Save the Day) - Dean Schuster
uxyall
1
3.4k
Jess Joyce - The Pitfalls of Following Frameworks
techseoconnect
PRO
1
450
Tell your own story through comics
letsgokoyo
1
1.1k
The Success of Rails: Ensuring Growth for the Next 100 Years
eileencodes
47
8.4k
SEO for Brand Visibility & Recognition
aleyda
0
4.8k
WENDY [Excerpt]
tessaabrams
14
40k
Pawsitive SEO: Lessons from My Dog (and Many Mistakes) on Thriving as a Consultant in the Age of AI
davidcarrasco
0
260
Believing is Seeing
oripsolob
1
250
How to optimise 3,500 product descriptions for ecommerce in one day using ChatGPT
katarinadahlin
PRO
3
3.9k
Bioeconomy Workshop: Dr. Julius Ecuru, Opportunities for a Bioeconomy in West Africa
akademiya2063
PRO
1
410
How Fast Is Fast Enough? [PerfNow 2025]
tammyeverts
3
940
Faster Mobile Websites
deanohume
310
32k
Transcript
Eyes Wide Shut? Exploring the Visual Shortcomings of Multimodal LLMs
Kazuya Nishimura
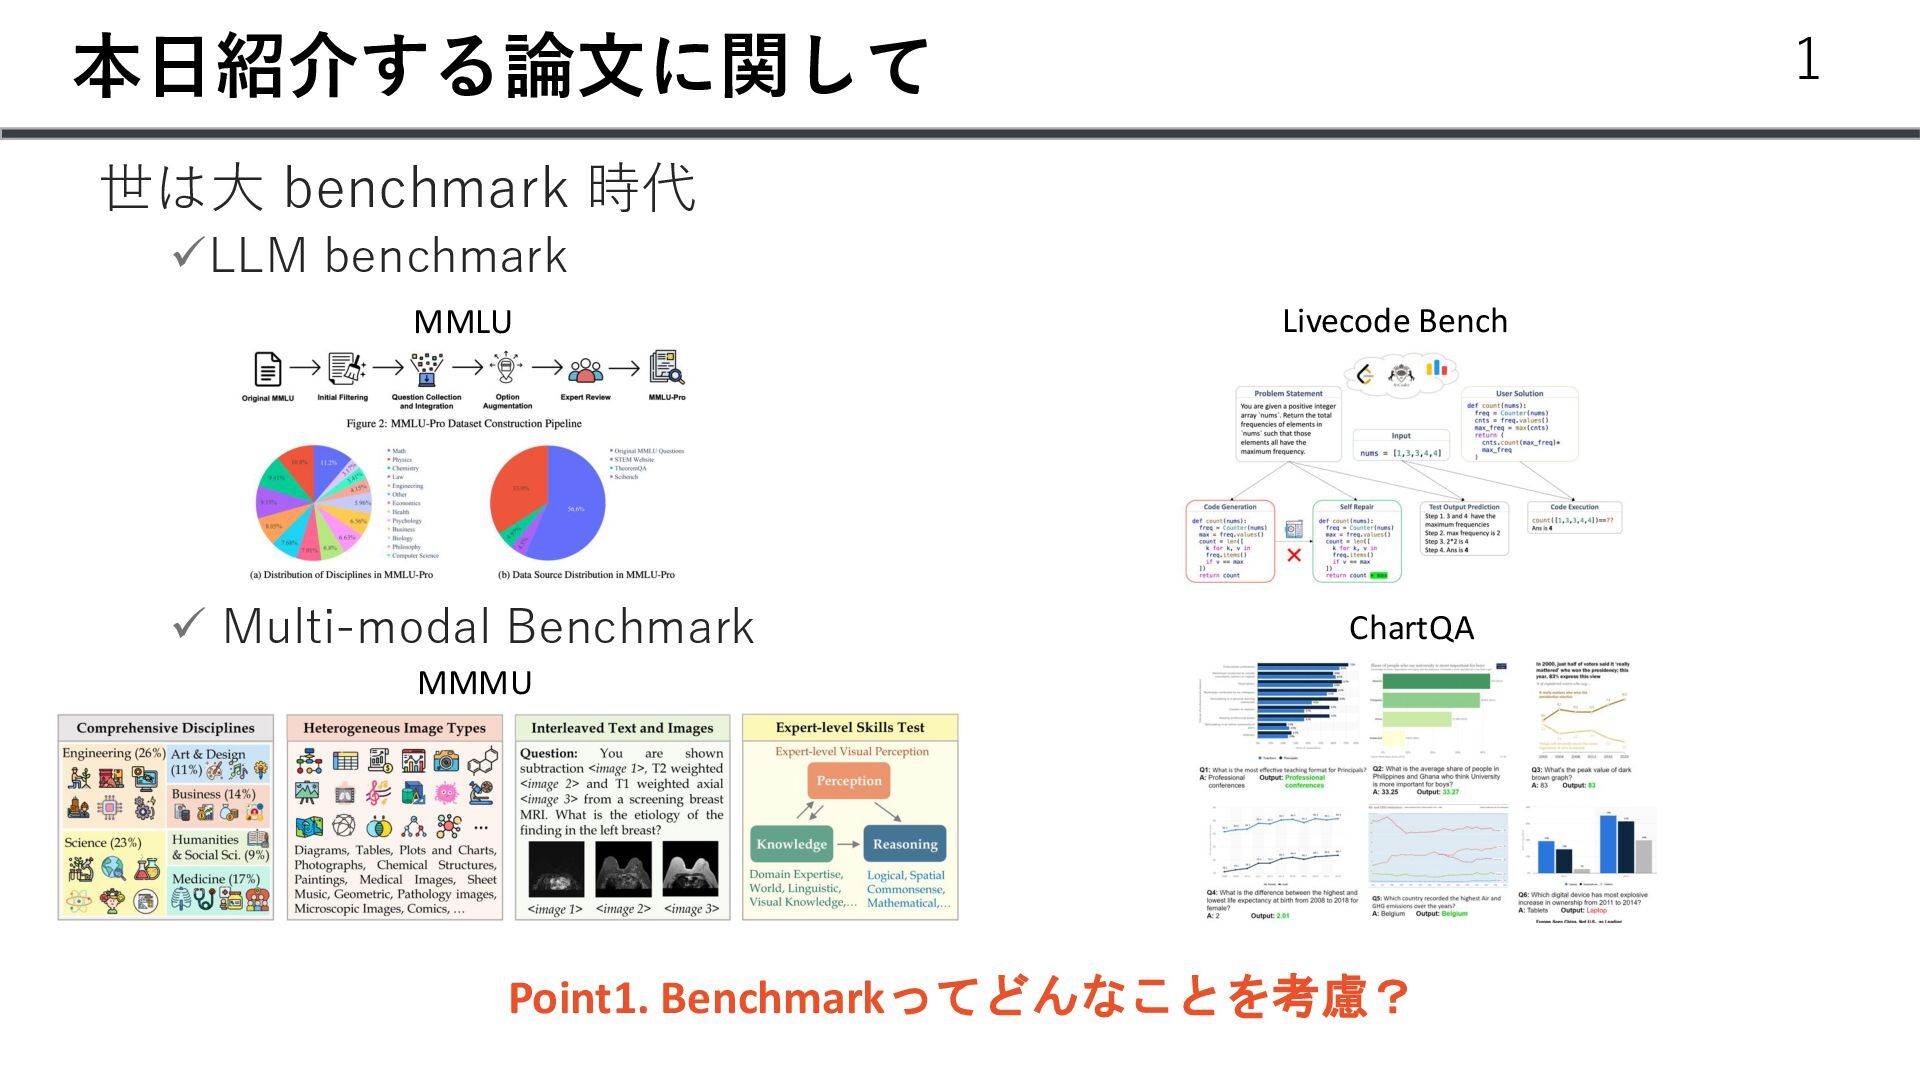
本日紹介する論文に関して 世は大 benchmark 時代 ✓LLM benchmark ✓ Multi-modal Benchmark 1
MMMU ChartQA MMLU Livecode Bench Point1. Benchmarkってどんなことを考慮?
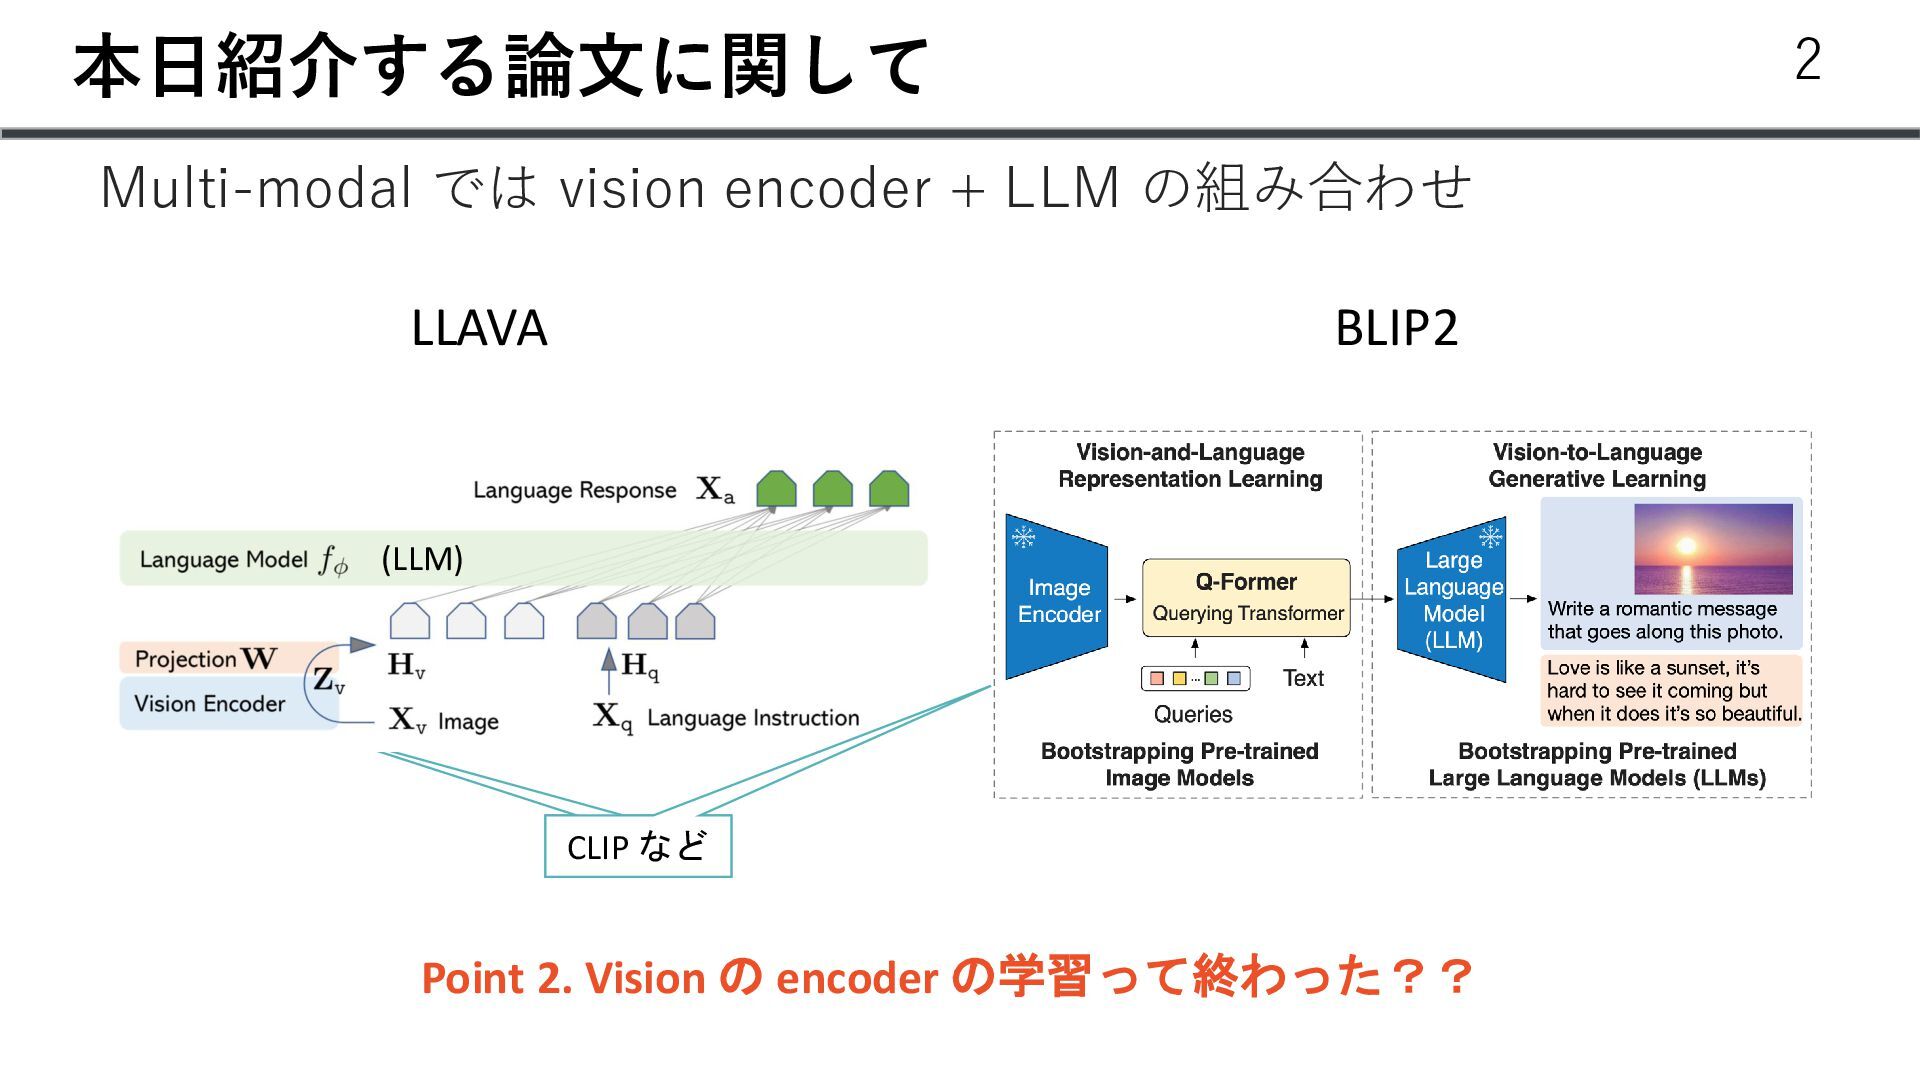
本日紹介する論文に関して Multi-modal では vision encoder + LLM の組み合わせ 2 CLIP
など LLAVA CLIP など (LLM) BLIP2 Point 2. Vision の encoder の学習って終わった??
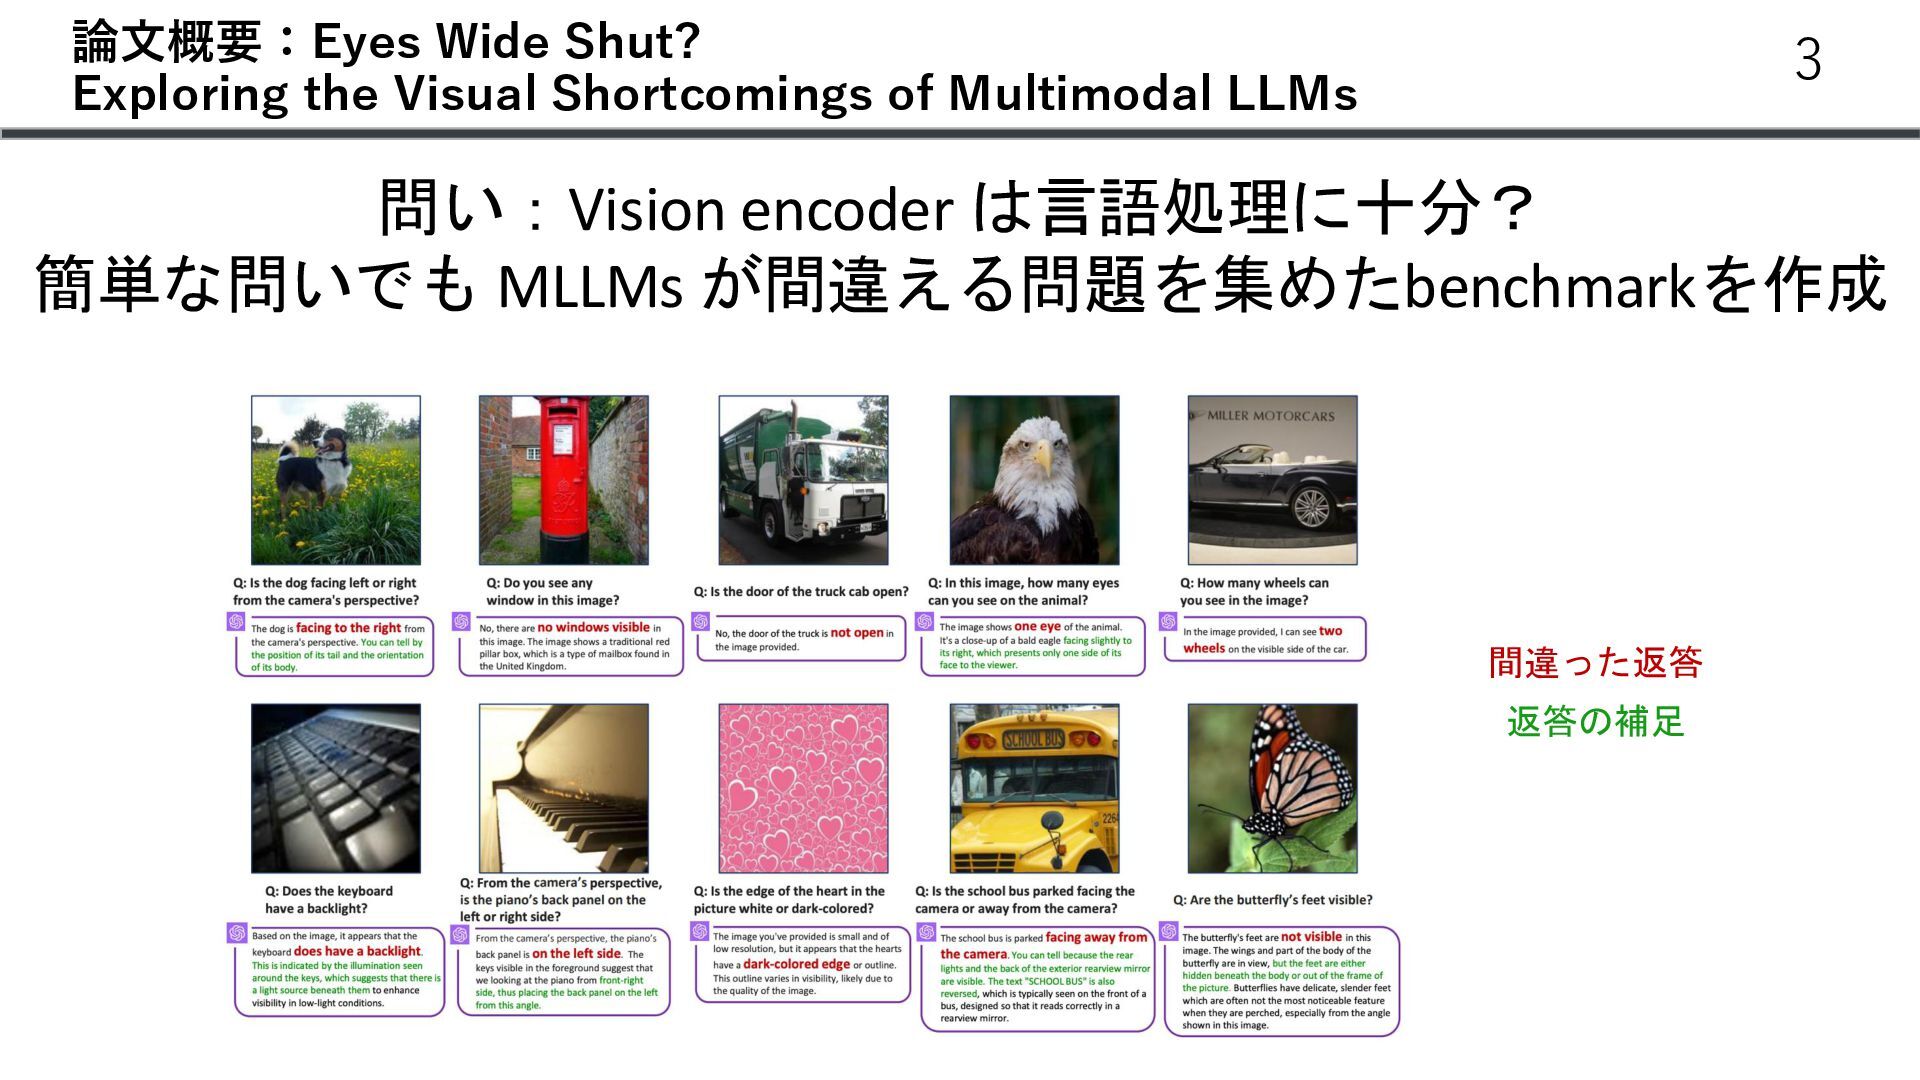
論文概要:Eyes Wide Shut? Exploring the Visual Shortcomings of Multimodal LLMs
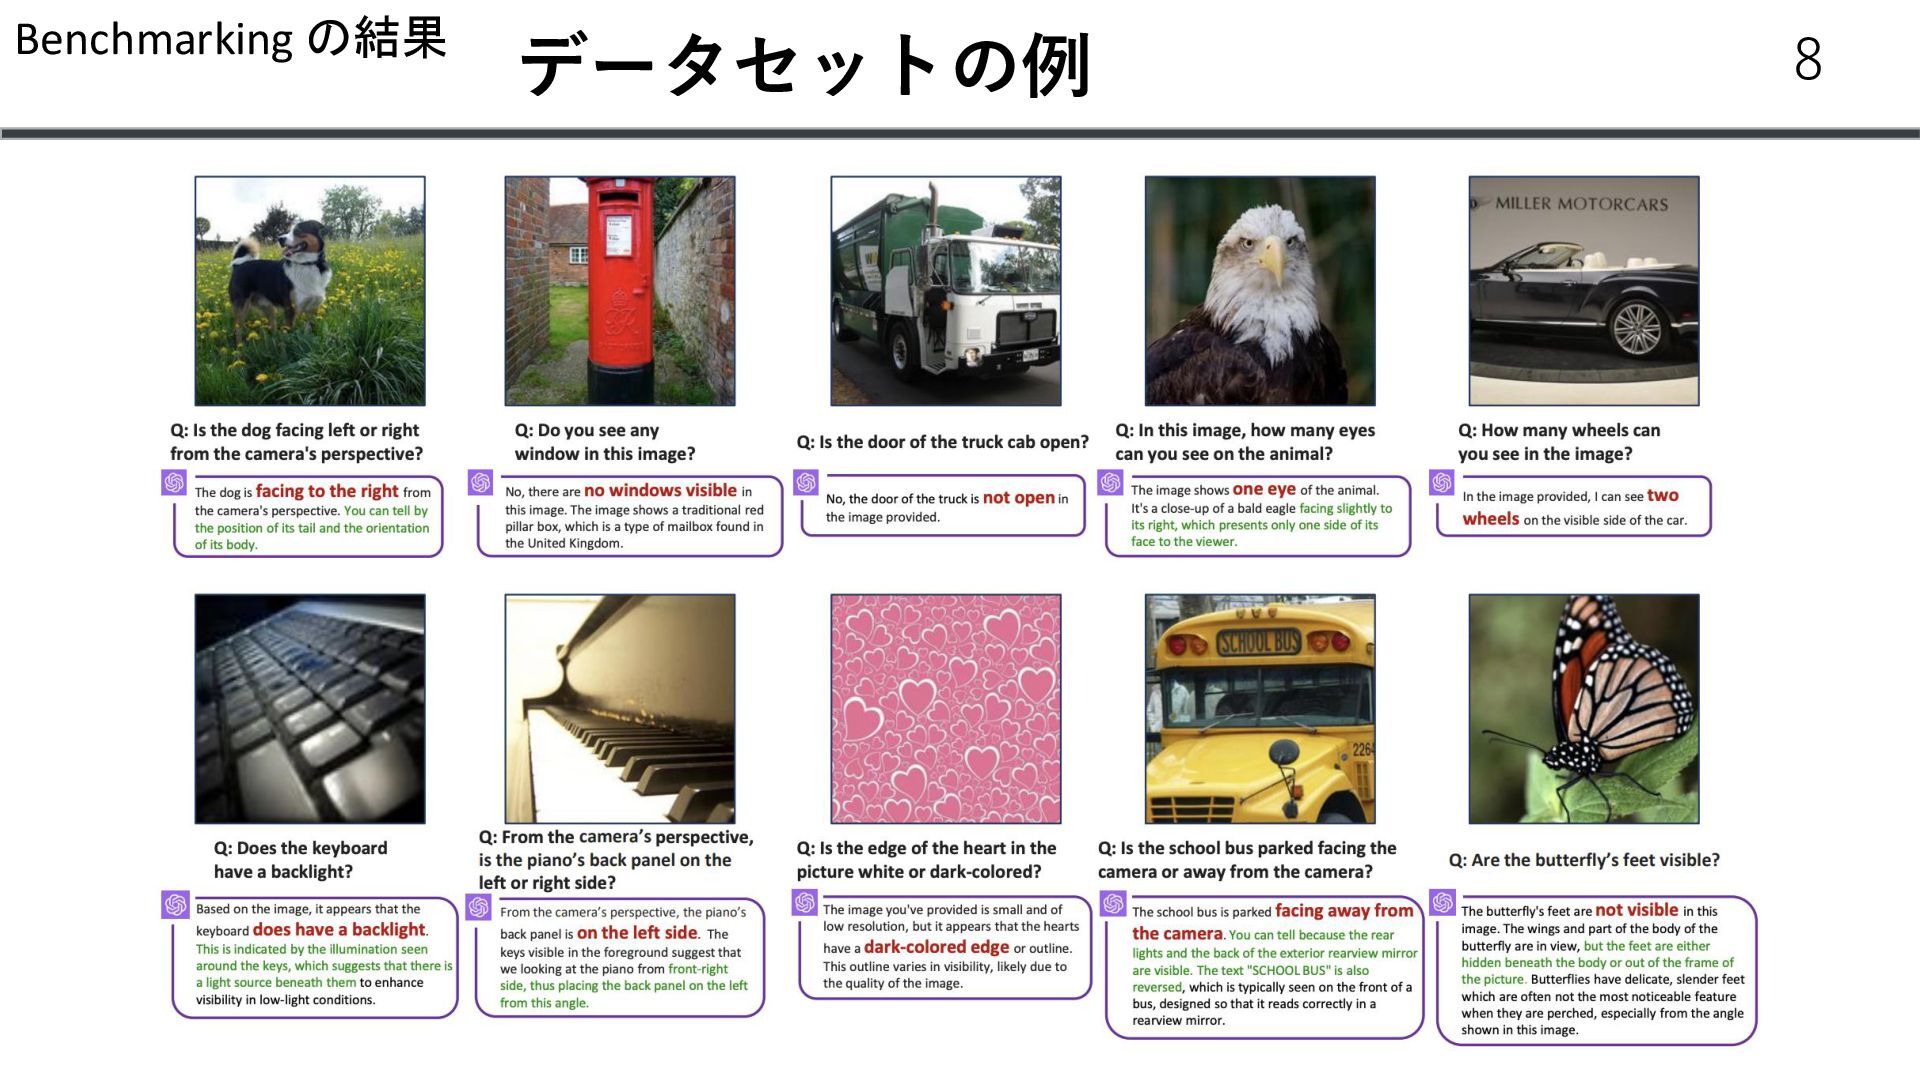
3 問い:Vision encoder は言語処理に十分? 簡単な問いでも MLLMs が間違える問題を集めたbenchmarkを作成 間違った返答 返答の補足
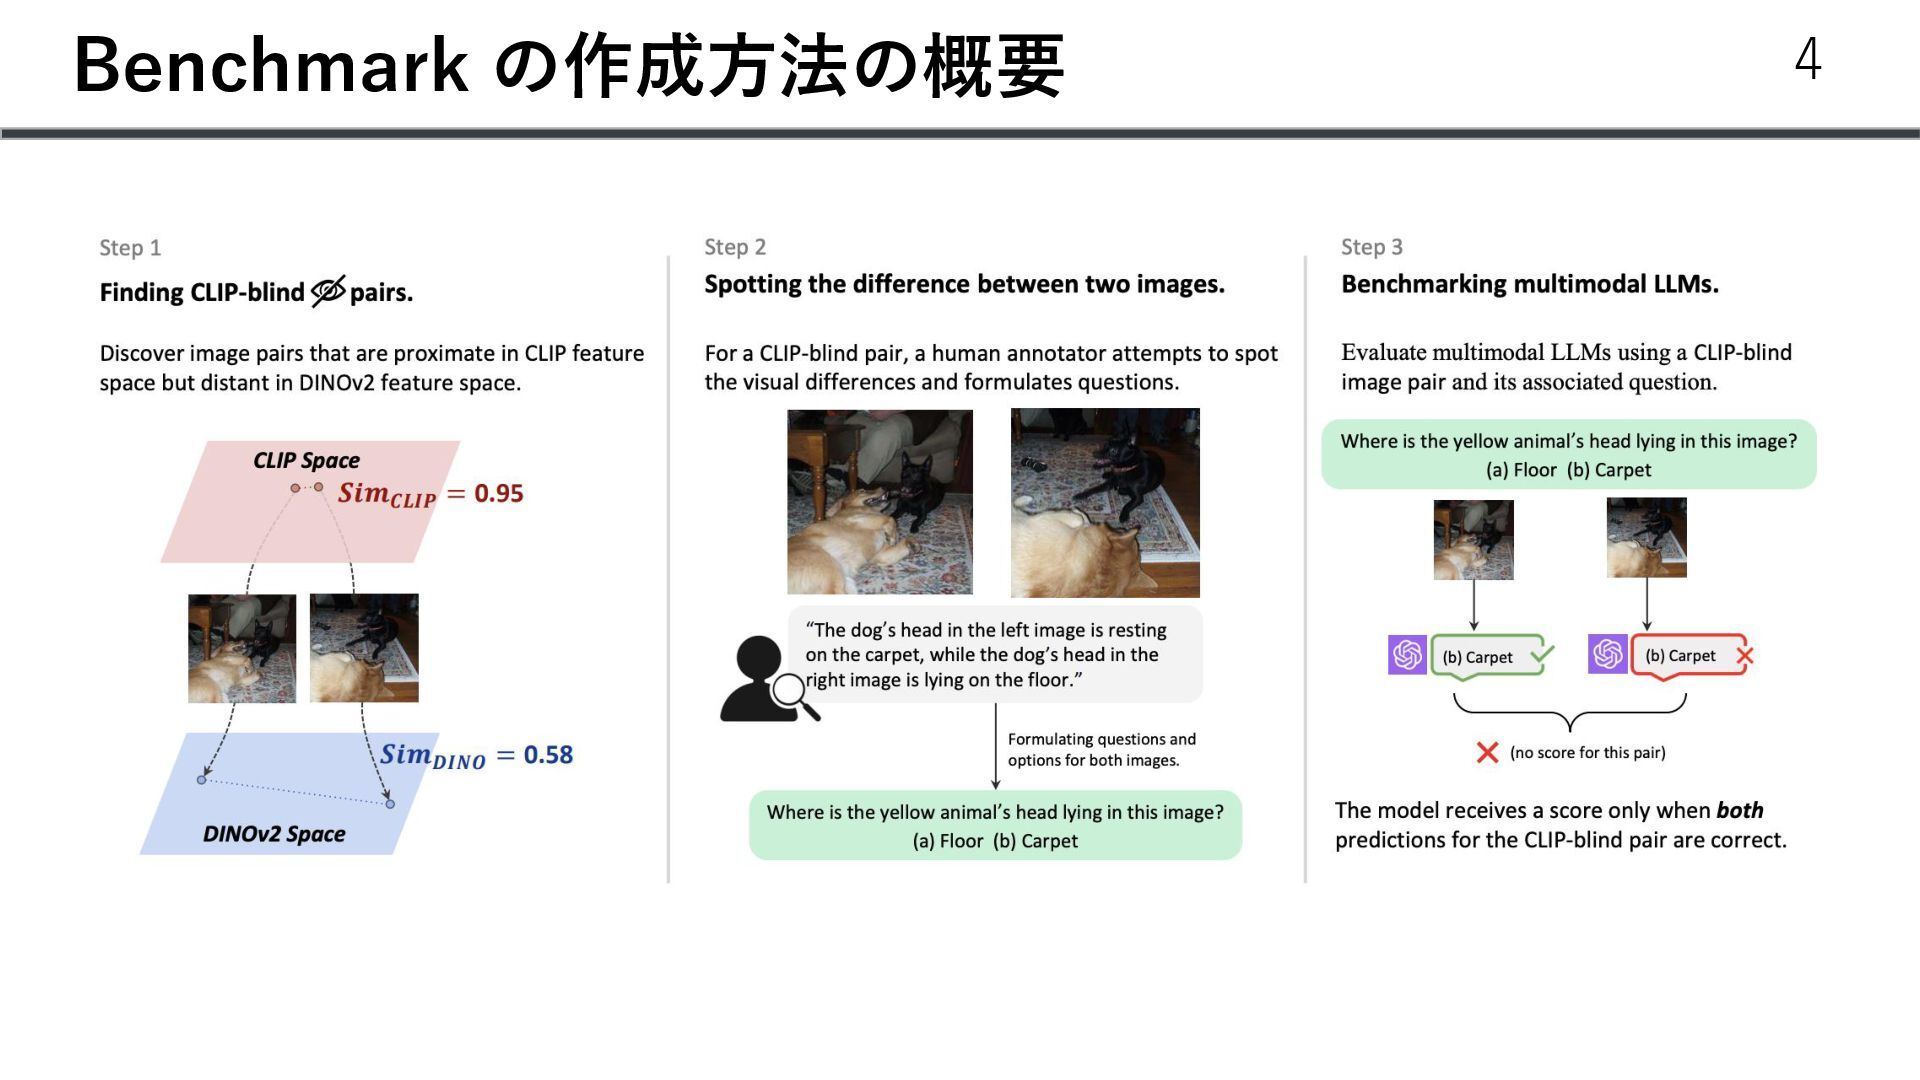
Benchmark の作成方法の概要 4
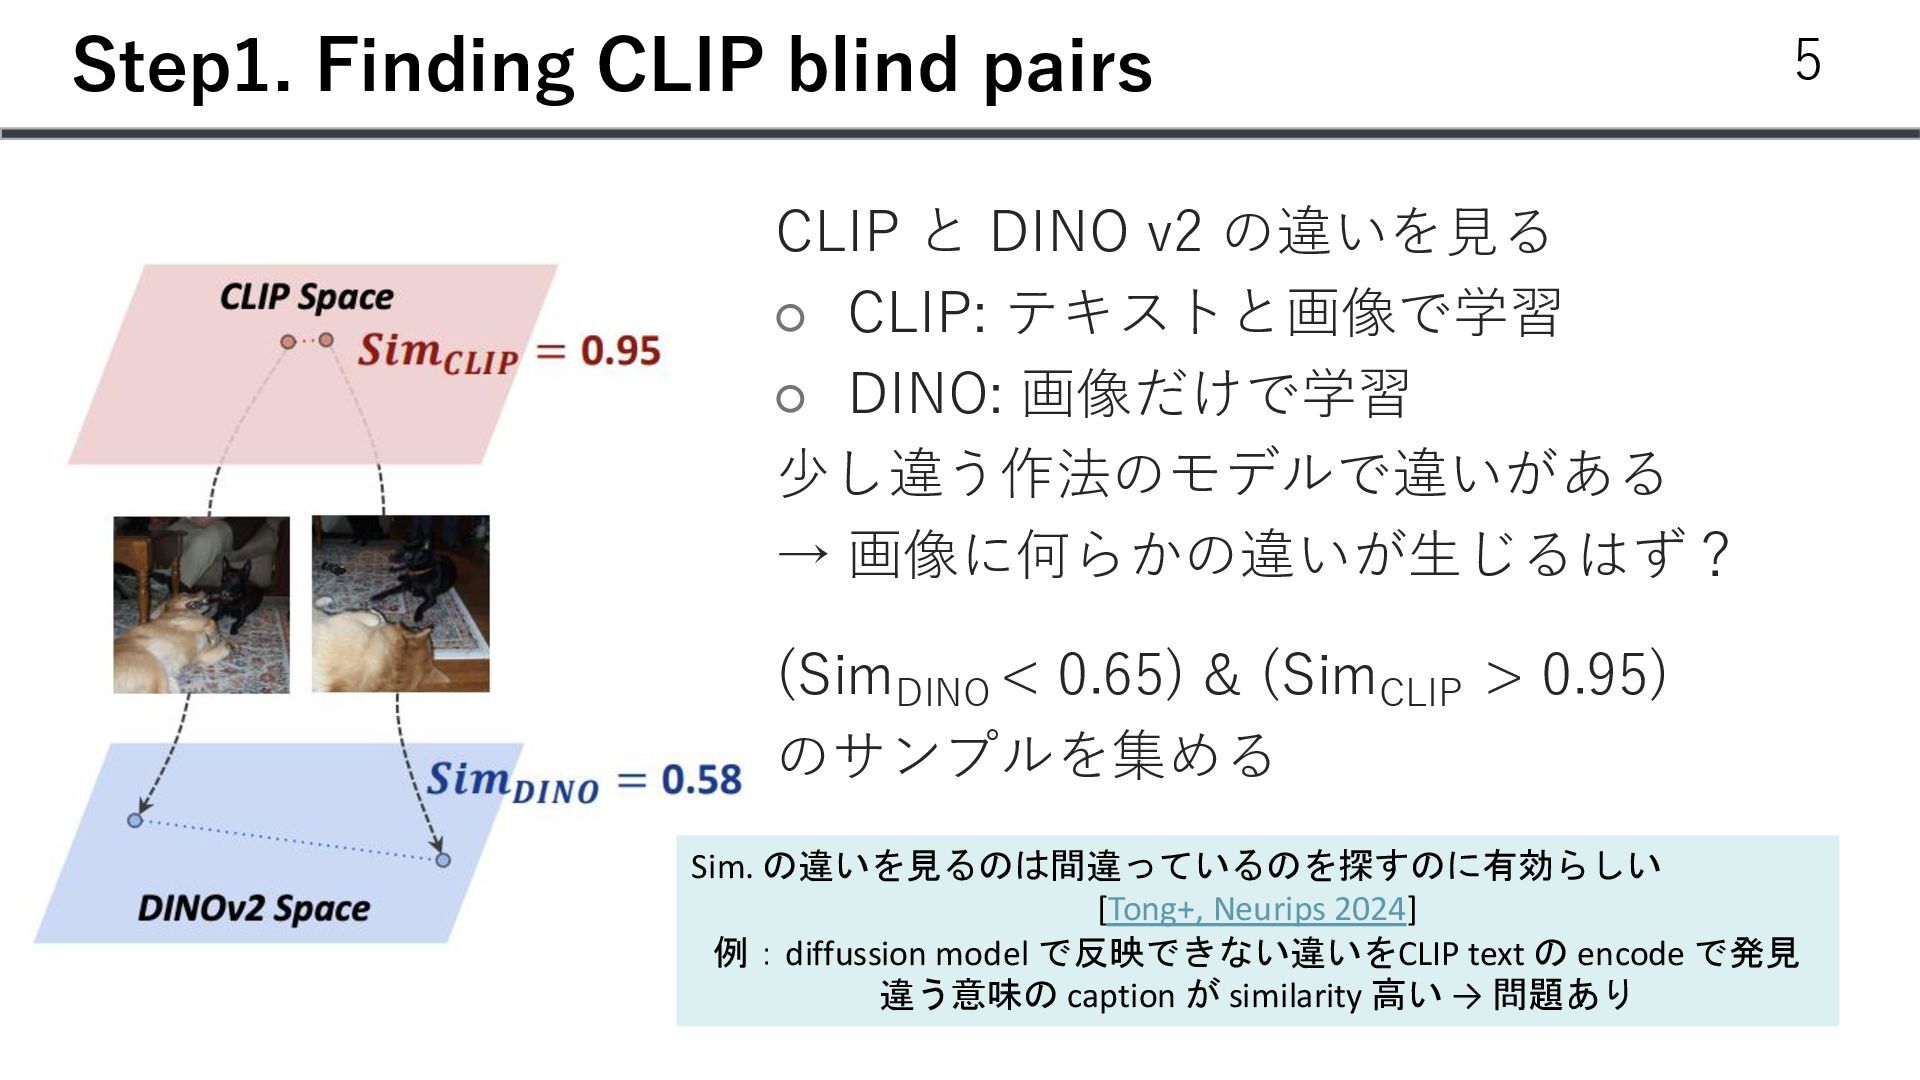
Step1. Finding CLIP blind pairs CLIP と DINO v2 の違いを見る
◦ CLIP: テキストと画像で学習 ◦ DINO: 画像だけで学習 少し違う作法のモデルで違いがある → 画像に何らかの違いが生じるはず? (Sim DINO < 0.65) & (Sim CLIP > 0.95) のサンプルを集める 5 Sim. の違いを見るのは間違っているのを探すのに有効らしい [Tong+, Neurips 2024] 例:diffussion model で反映できない違いをCLIP text の encode で発見 違う意味の caption が similarity 高い → 問題あり
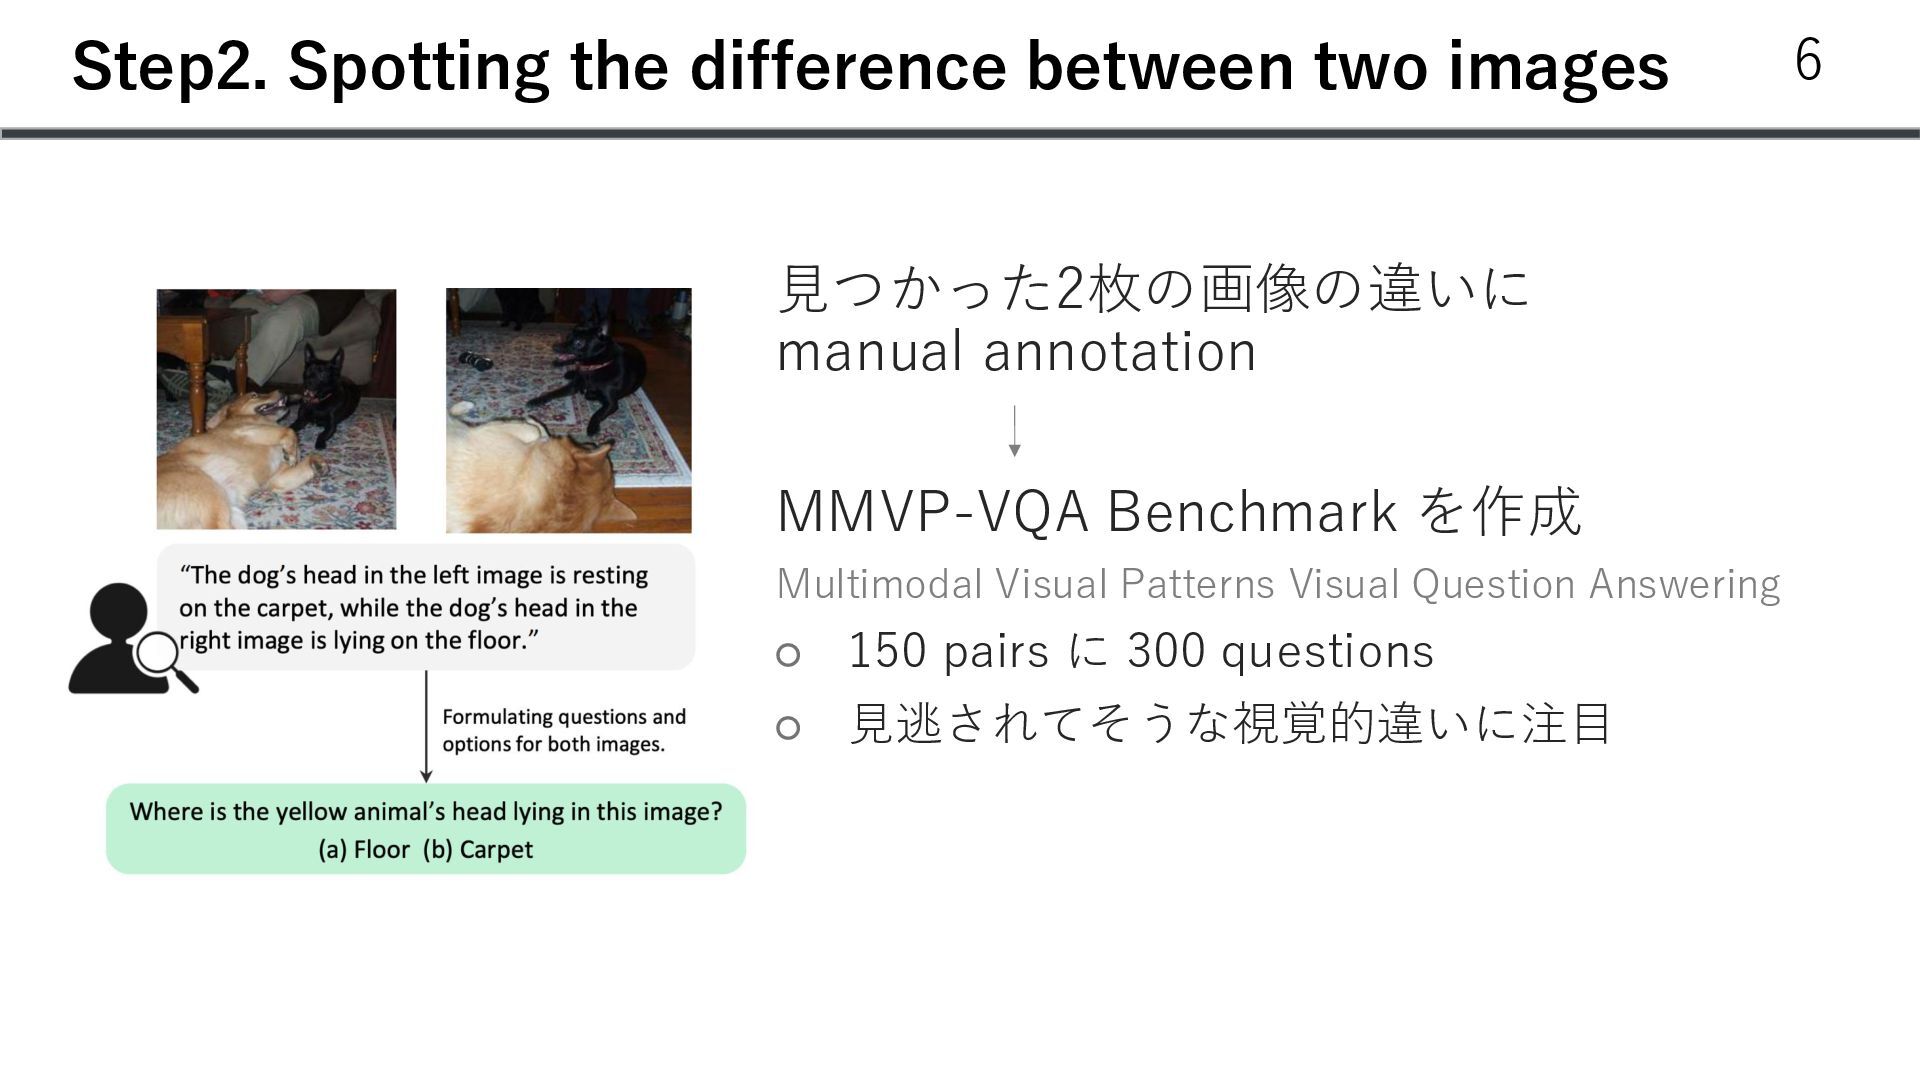
Step2. Spotting the difference between two images 見つかった2枚の画像の違いに manual annotation
MMVP-VQA Benchmark を作成 Multimodal Visual Patterns Visual Question Answering ◦ 150 pairs に 300 questions ◦ 見逃されてそうな視覚的違いに注目 6
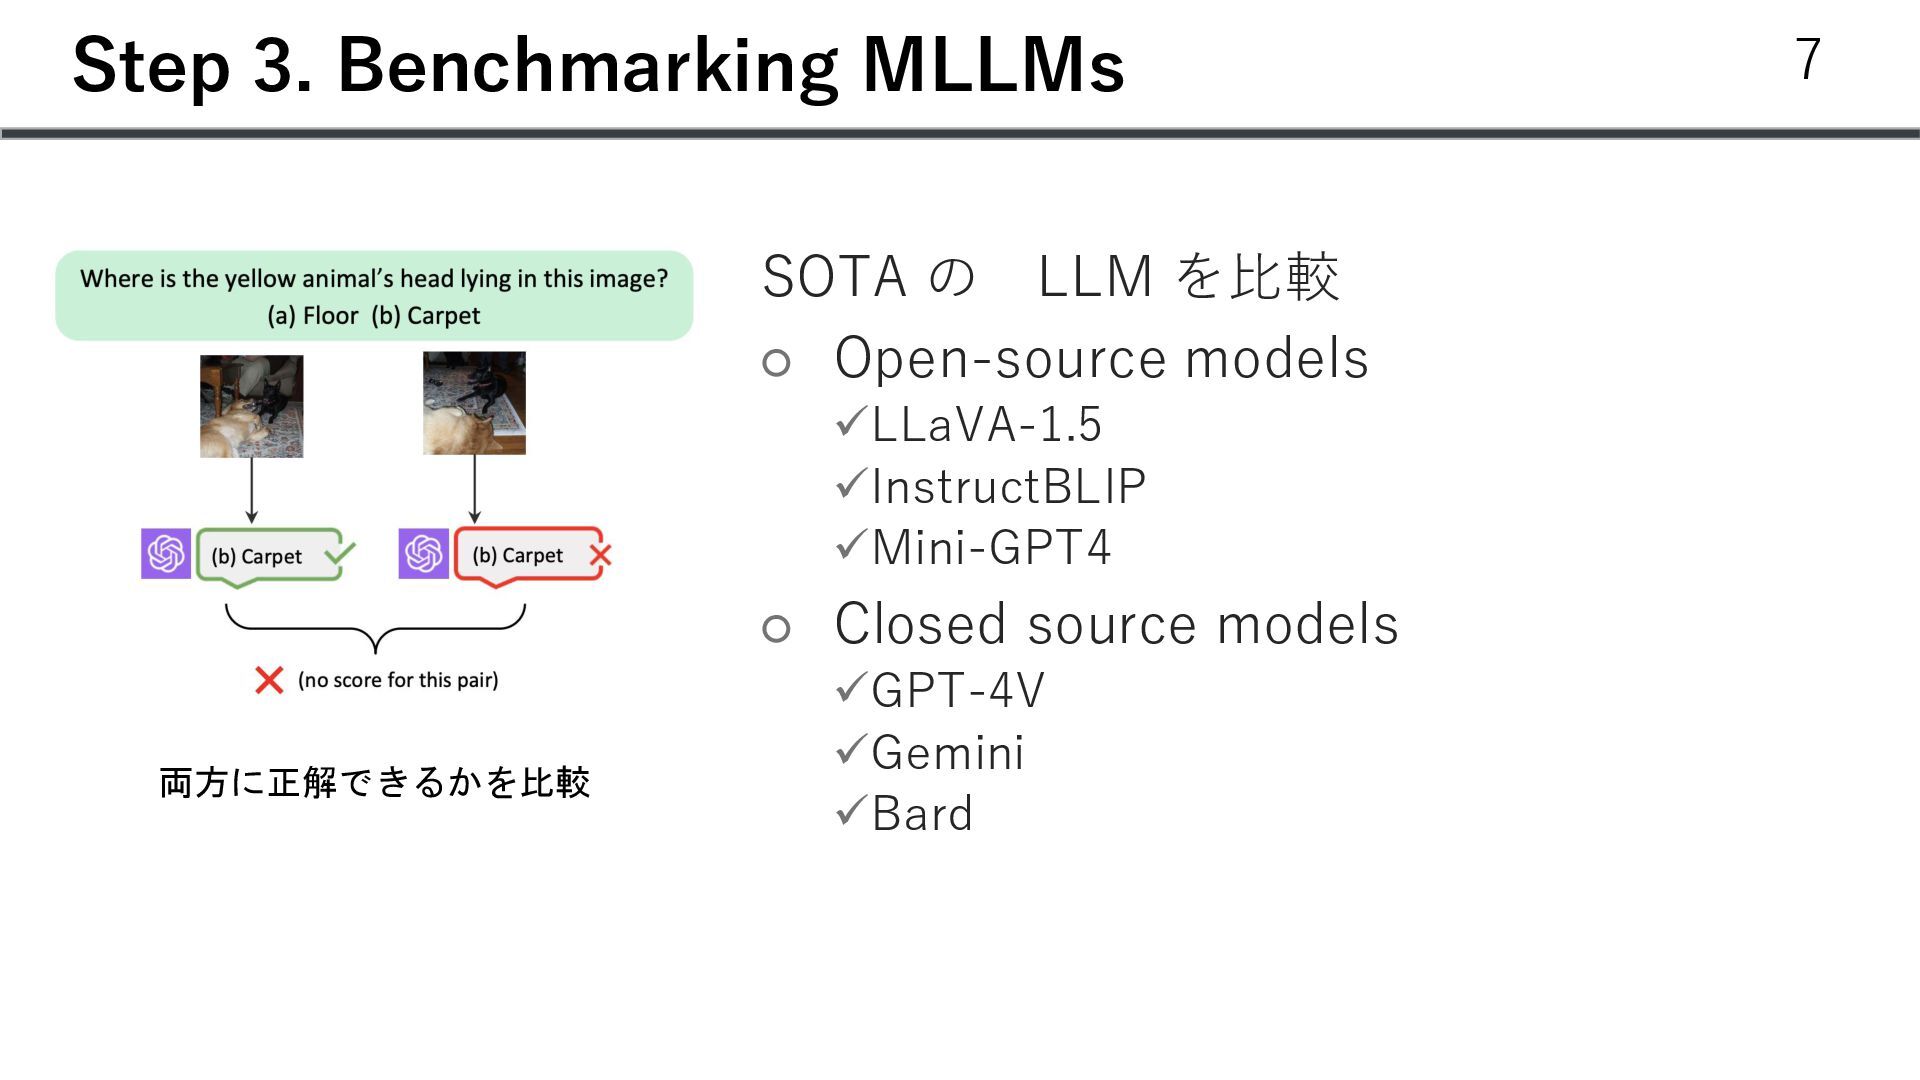
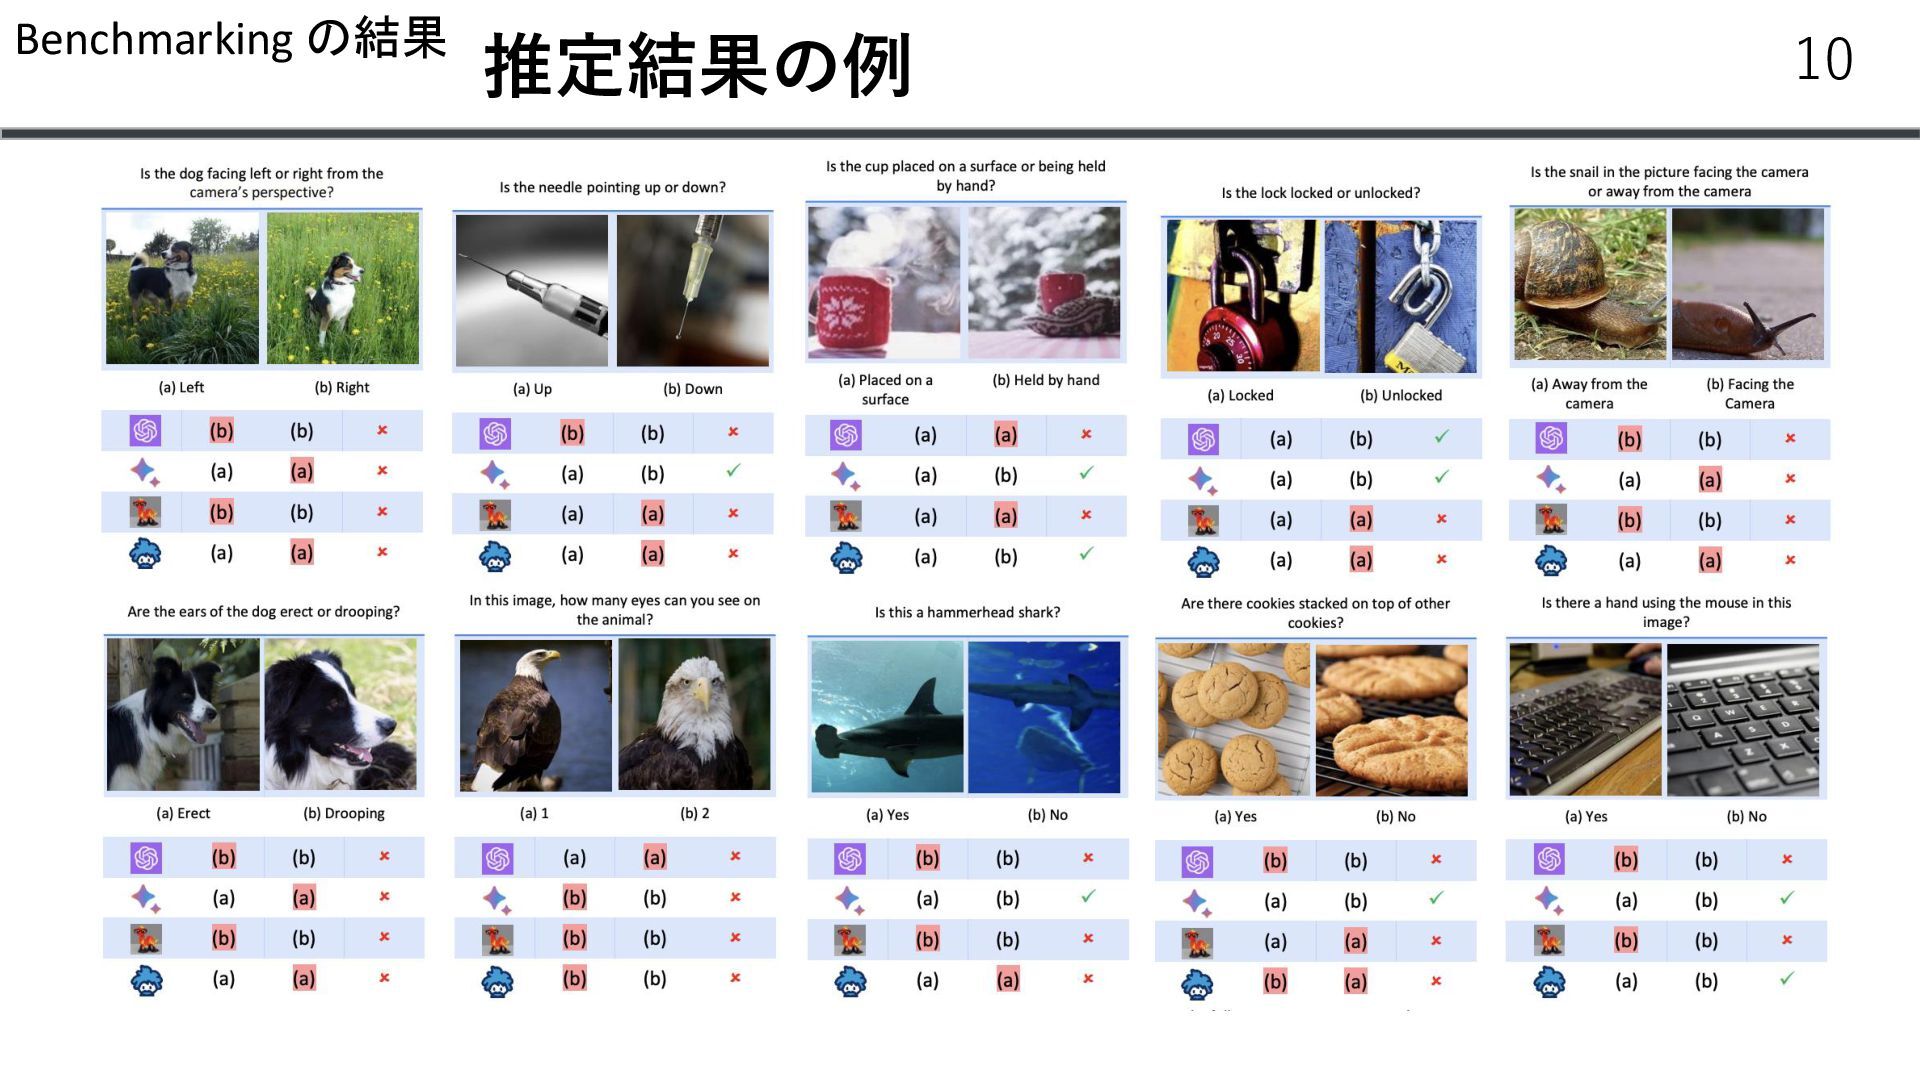
Step 3. Benchmarking MLLMs 7 両方に正解できるかを比較 SOTA の LLM を比較
◦ Open-source models ✓LLaVA-1.5 ✓InstructBLIP ✓Mini-GPT4 ◦ Closed source models ✓GPT-4V ✓Gemini ✓Bard
データセットの例 8 Benchmarking の結果
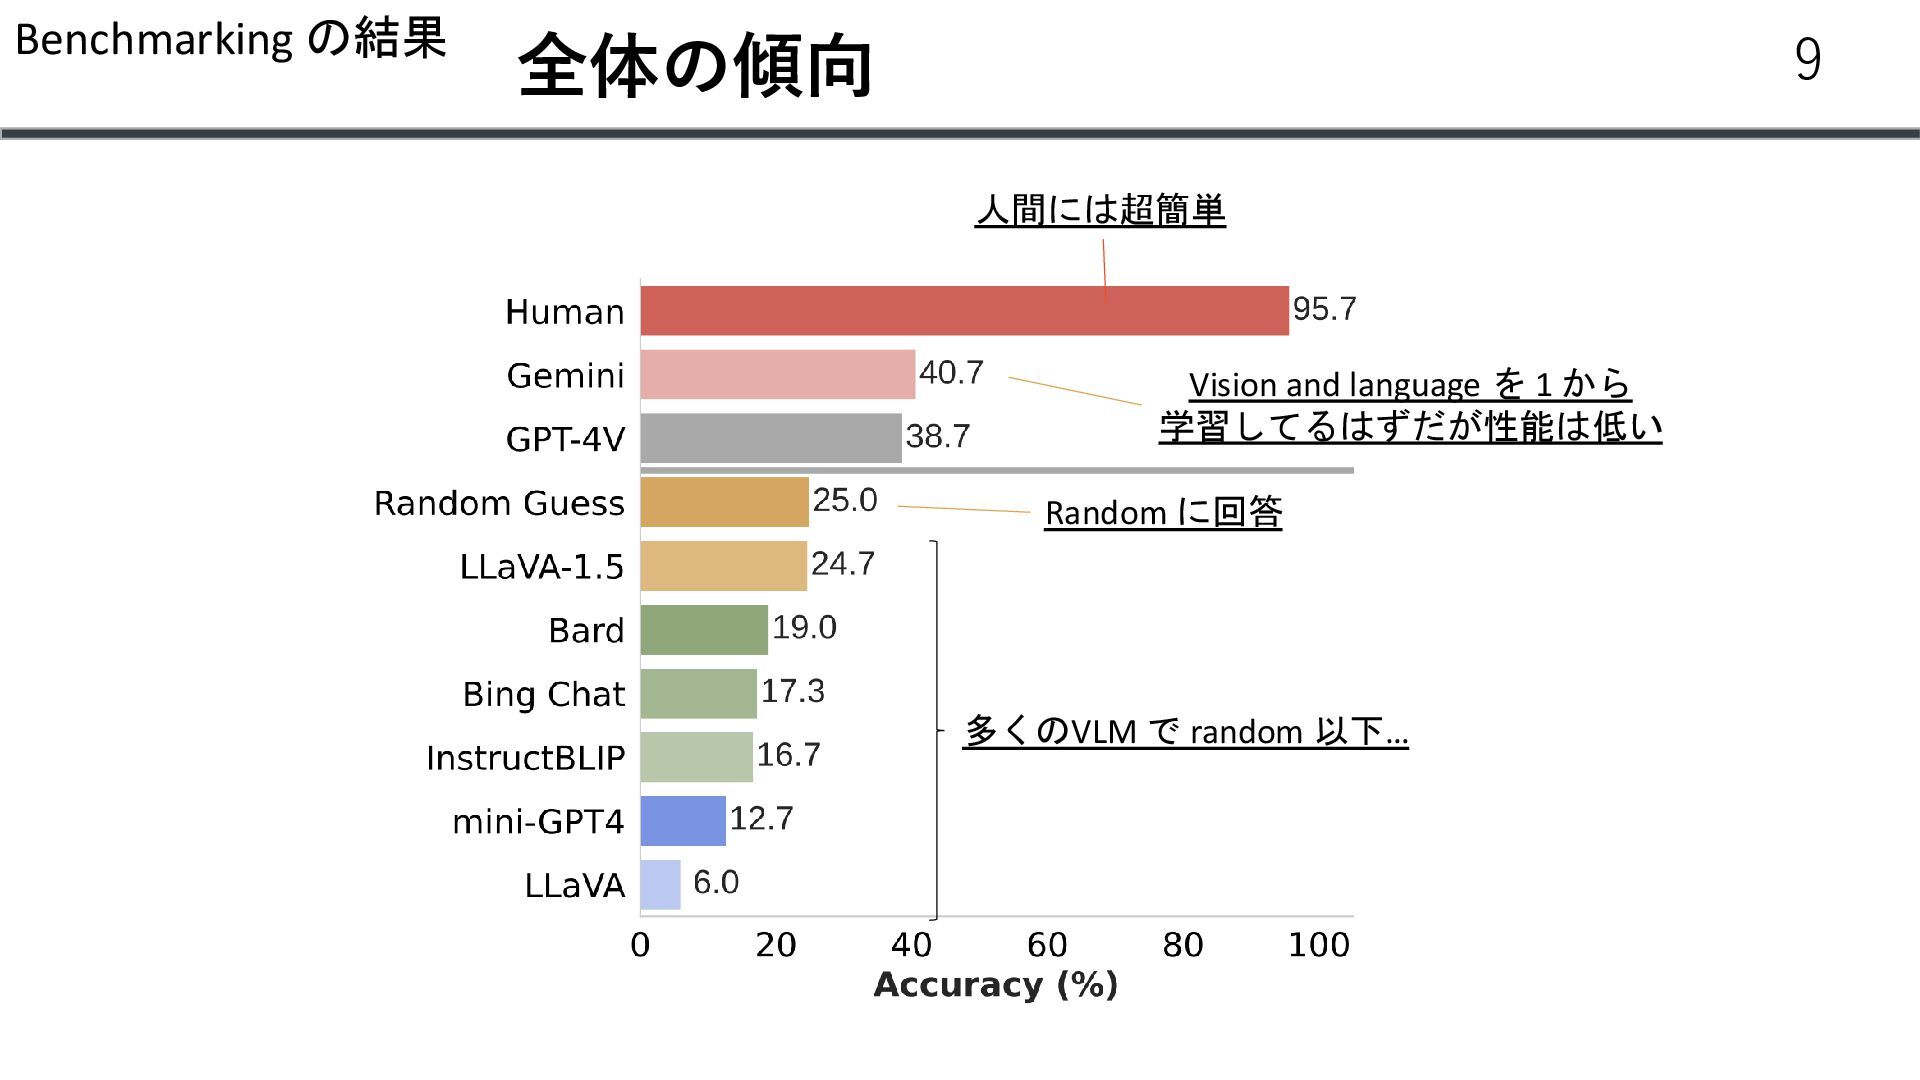
全体の傾向 9 人間には超簡単 Random に回答 Vision and language を 1
から 学習してるはずだが性能は低い Benchmarking の結果 多くのVLM で random 以下…
推定結果の例 10 Benchmarking の結果
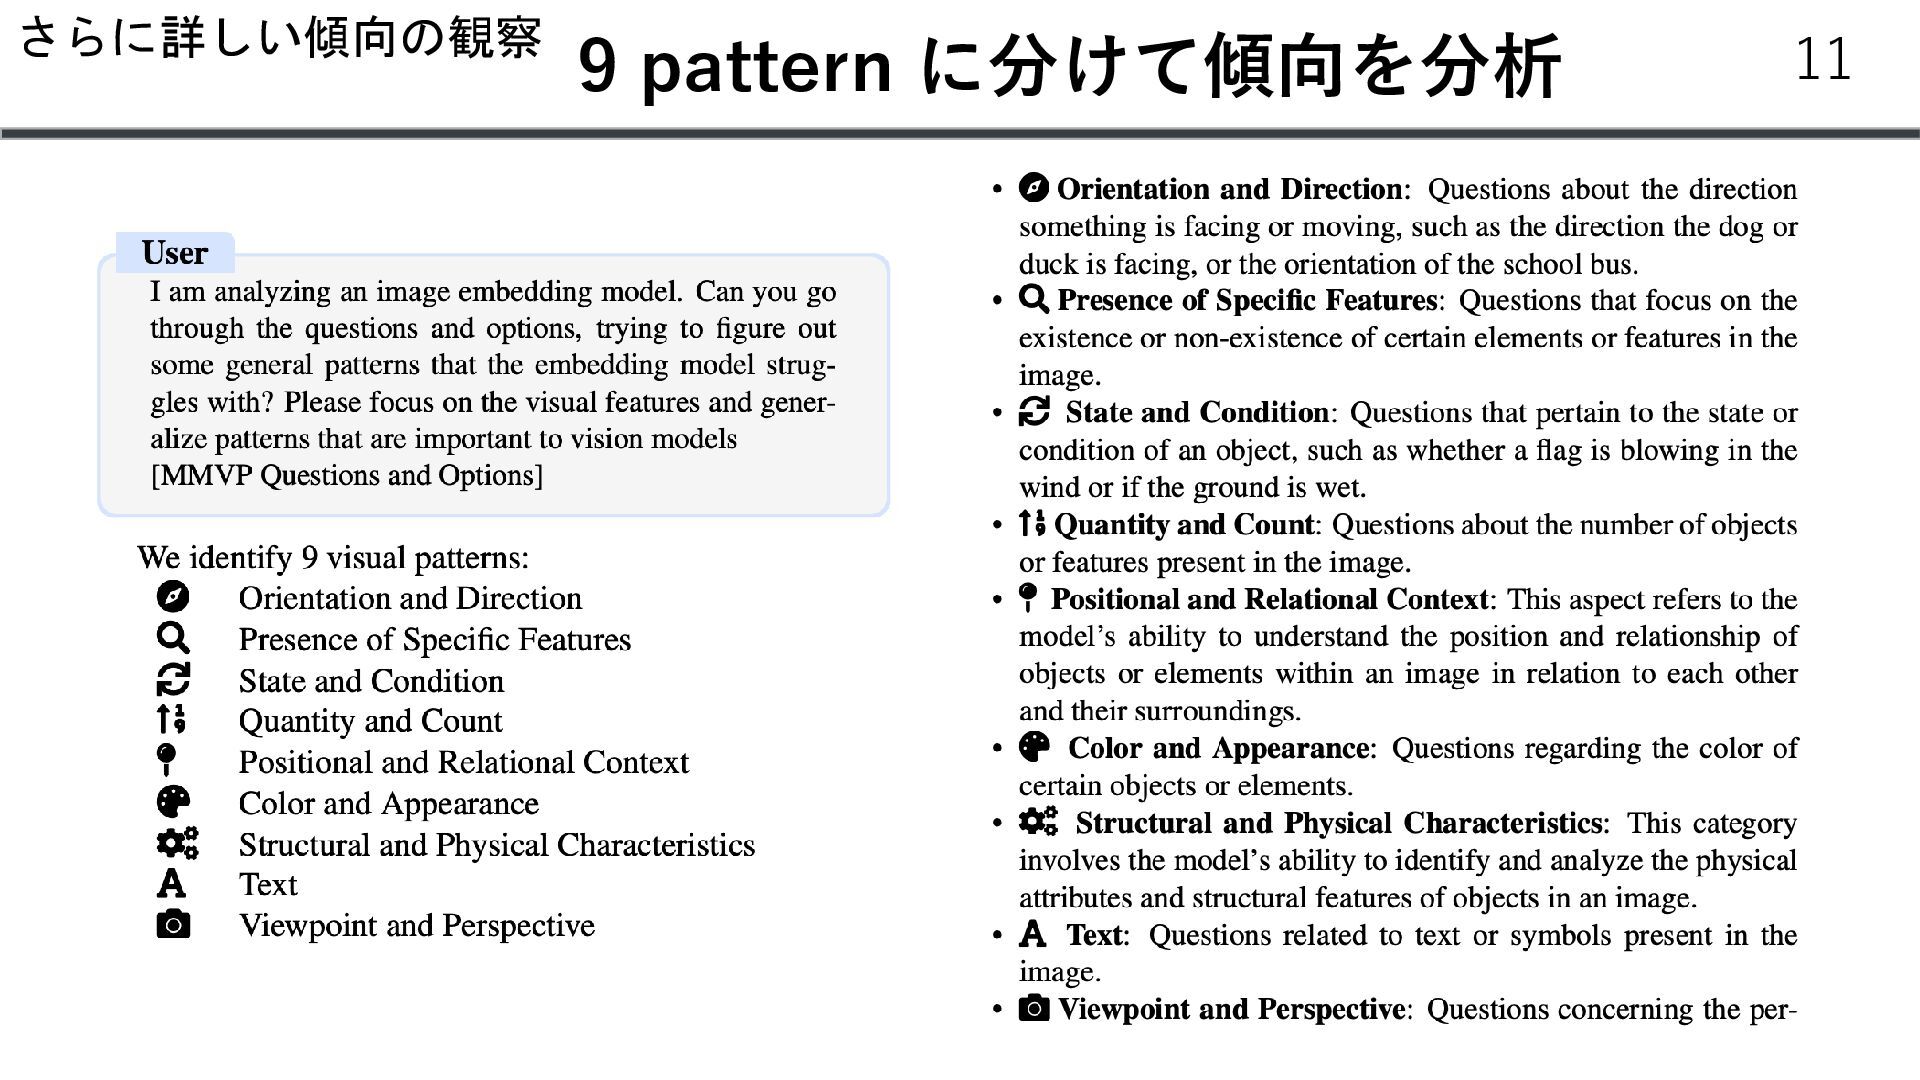
9 pattern に分けて傾向を分析 11 さらに詳しい傾向の観察
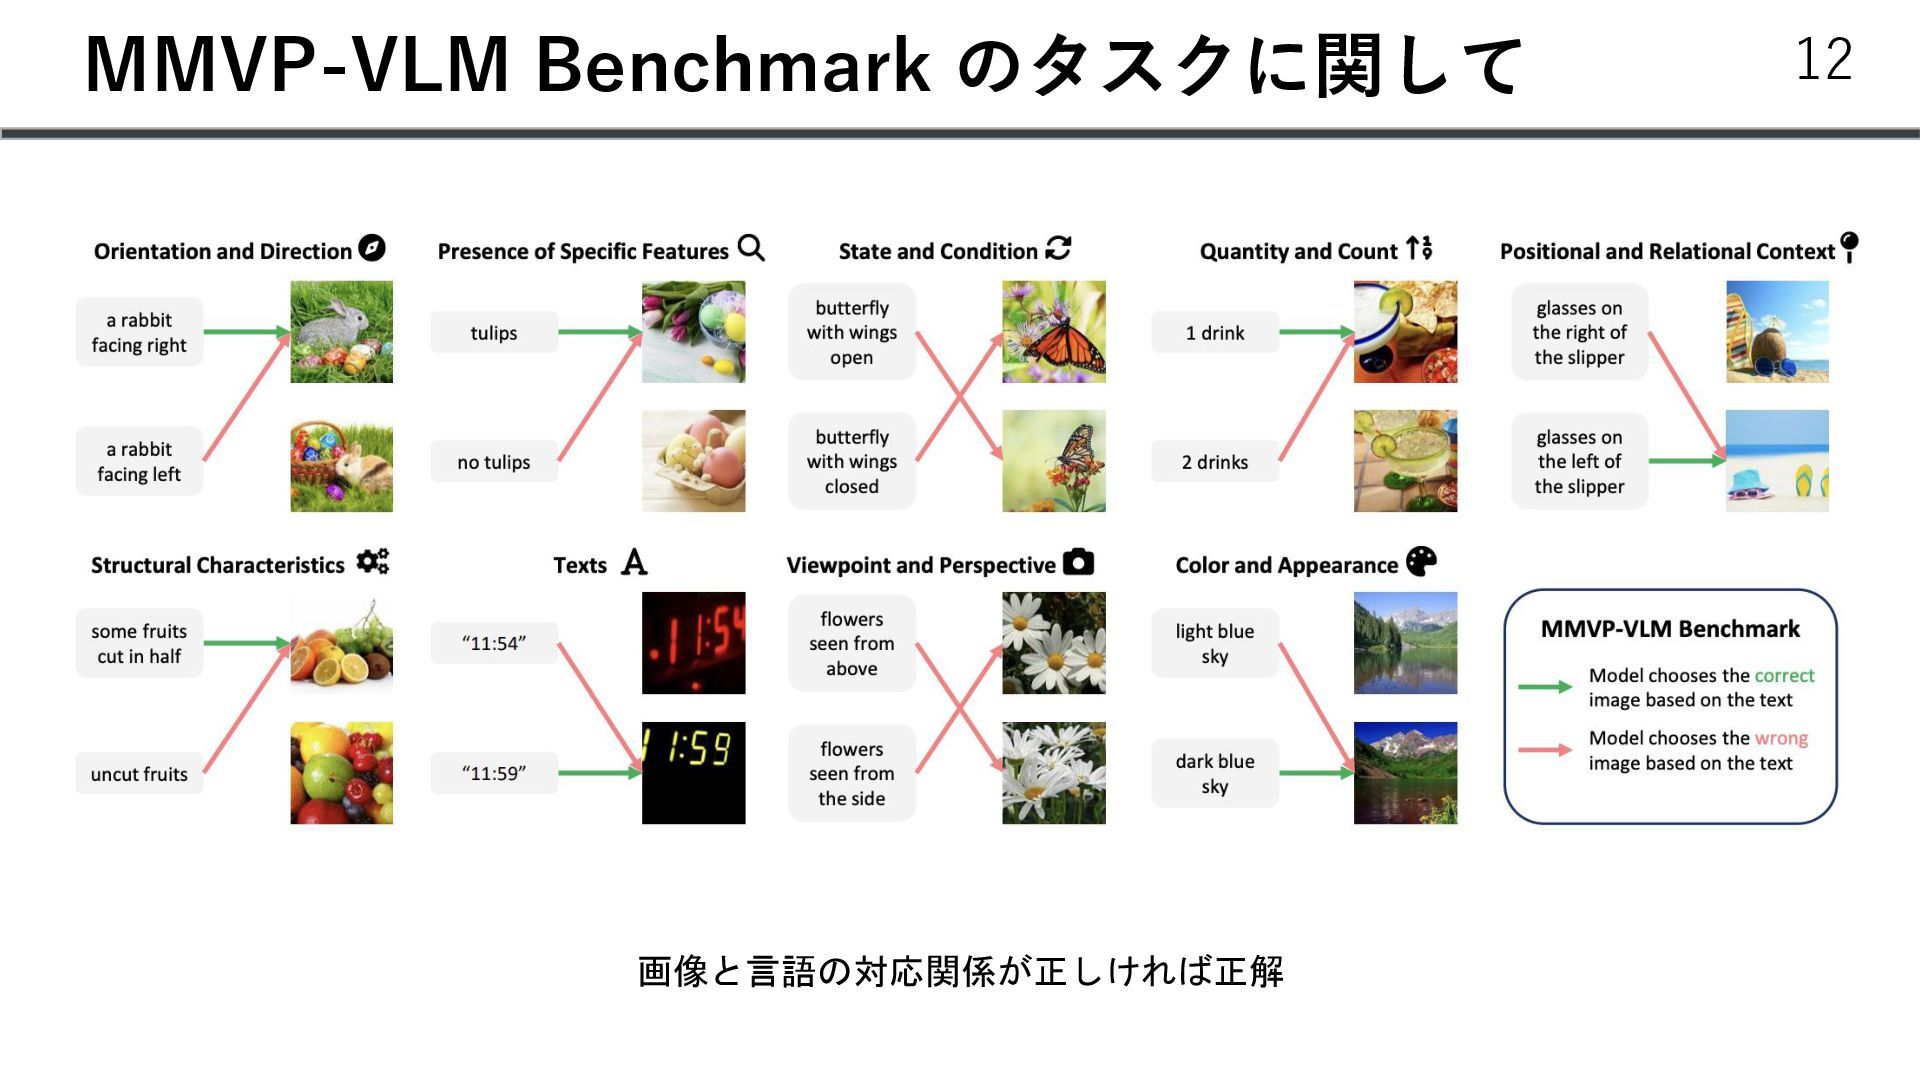
MMVP-VLM Benchmark のタスクに関して 12 画像と言語の対応関係が正しければ正解
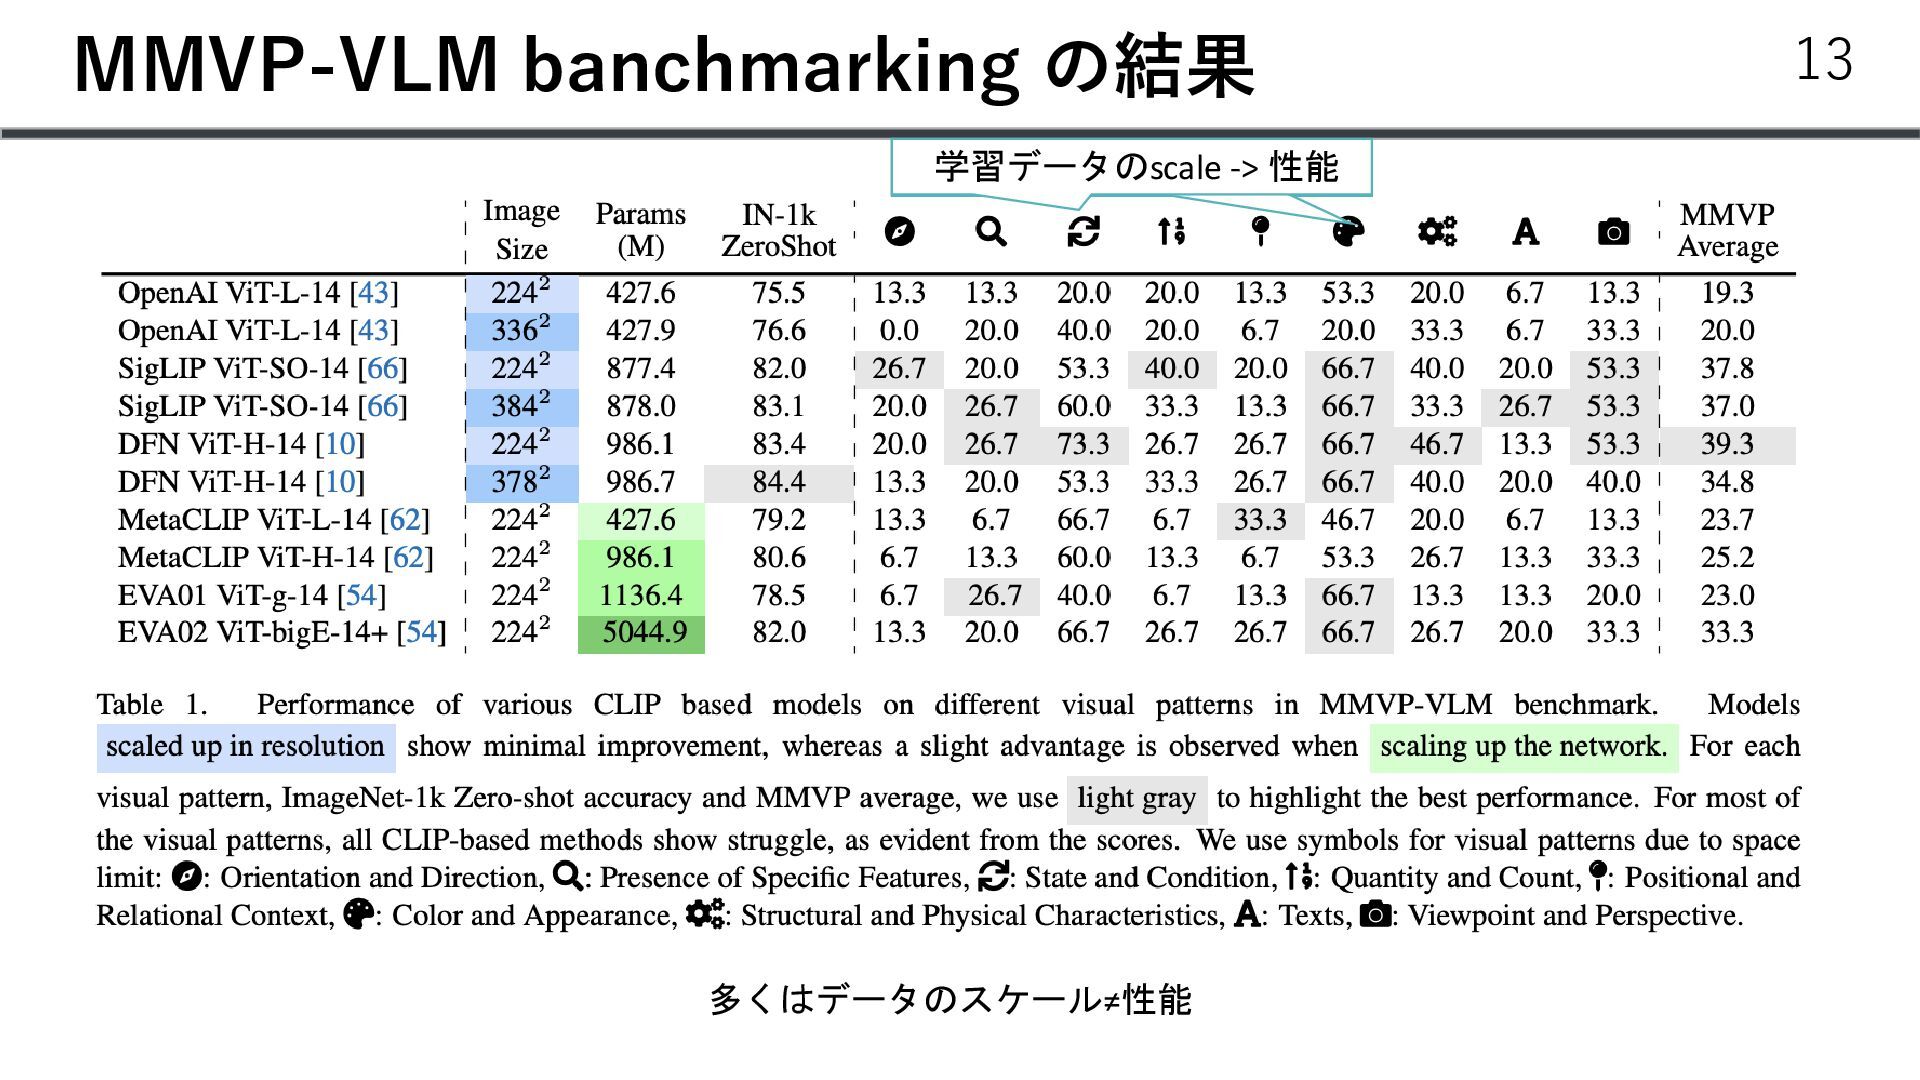
MMVP-VLM banchmarking の結果 13 学習データのscale -> 性能 多くはデータのスケール≠性能
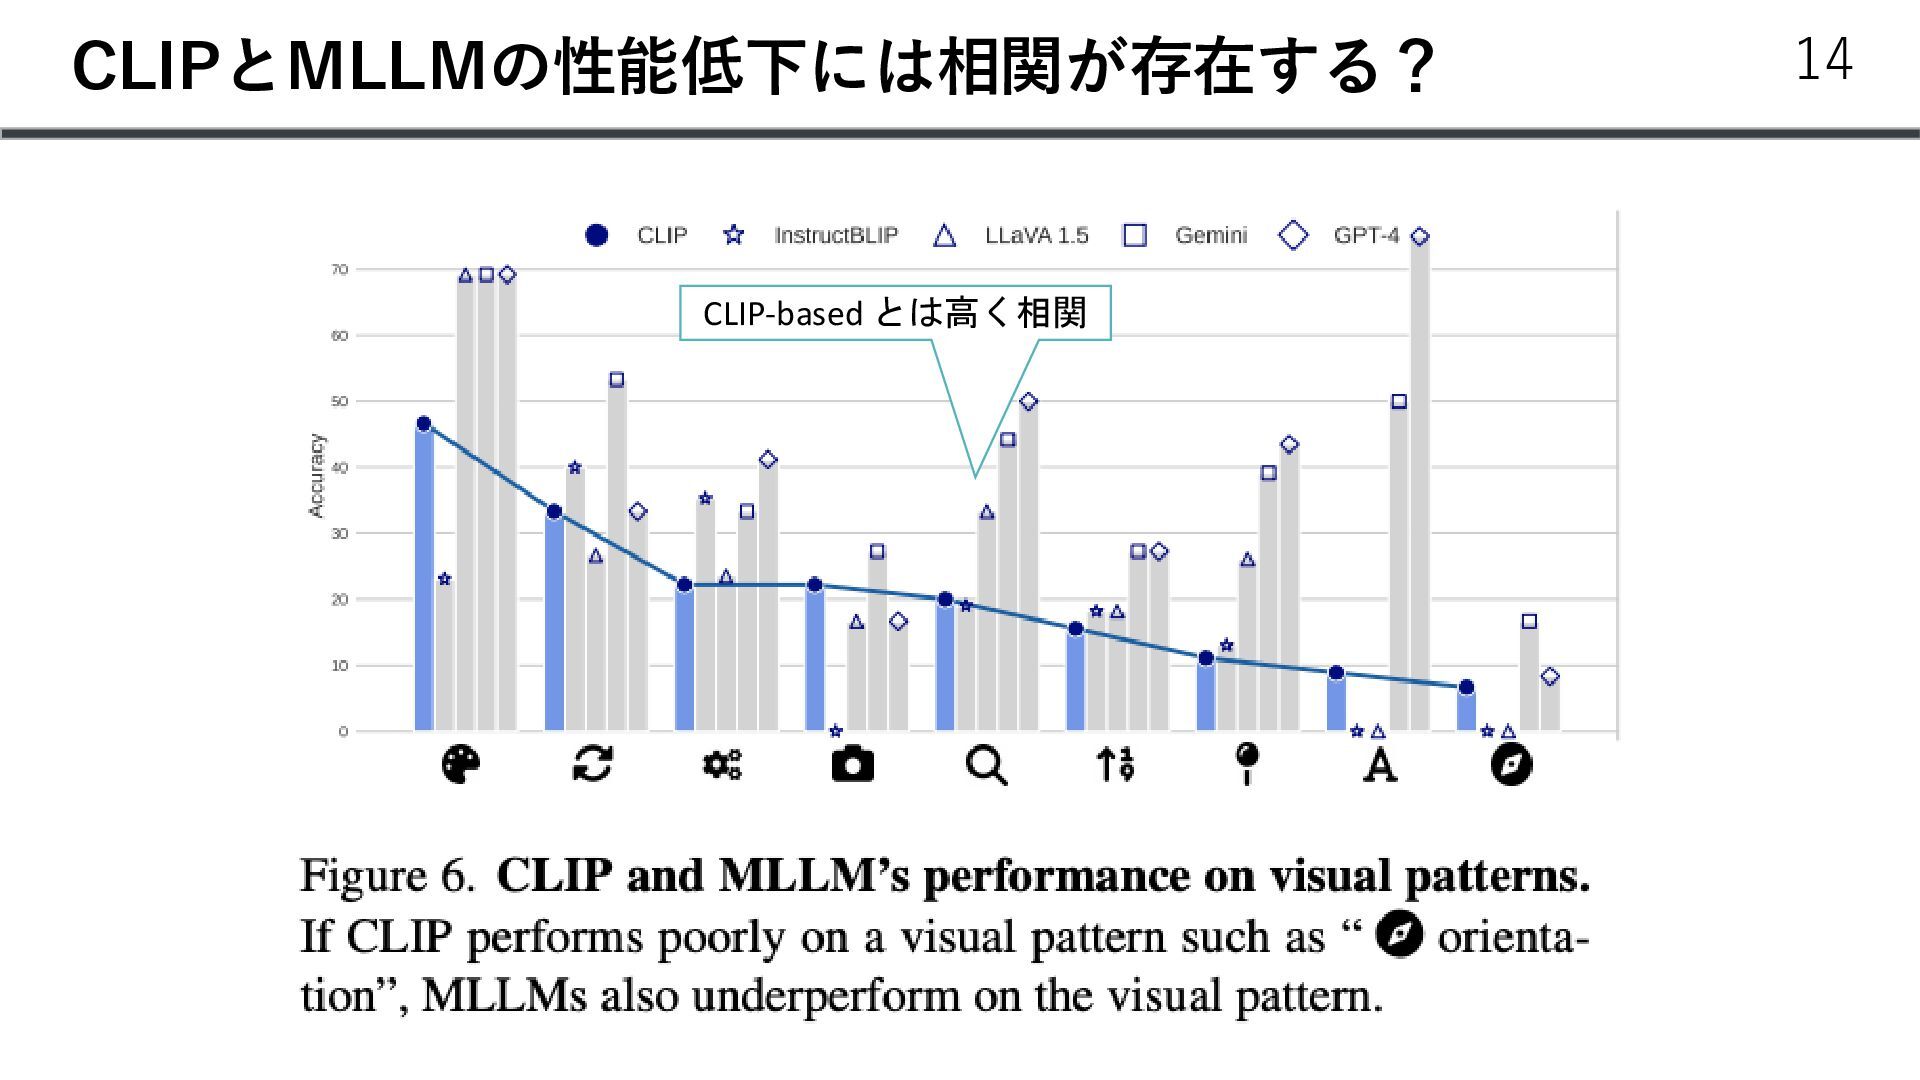
CLIPとMLLMの性能低下には相関が存在する? 14 CLIP-based とは高く相関
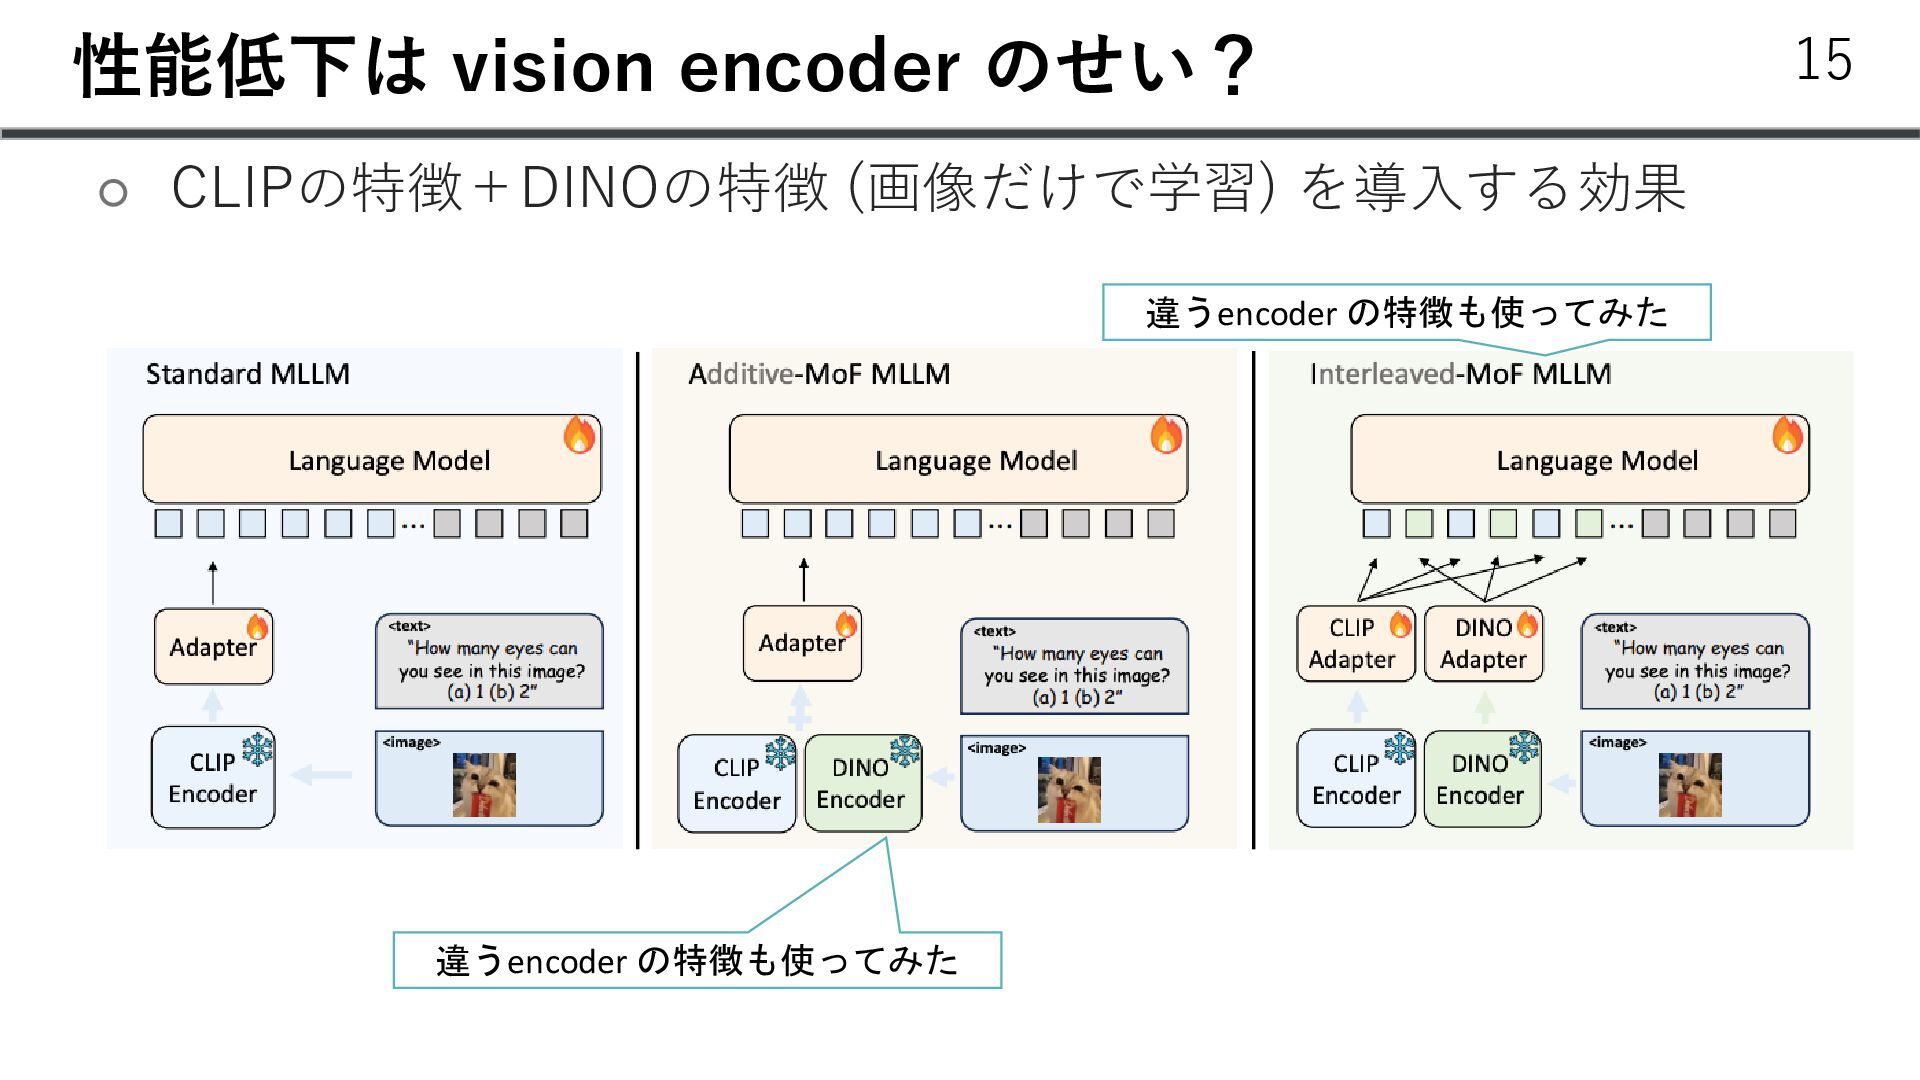
性能低下は vision encoder のせい? ◦ CLIPの特徴+DINOの特徴 (画像だけで学習) を導入する効果 15 違うencoder
の特徴も使ってみた 違うencoder の特徴も使ってみた
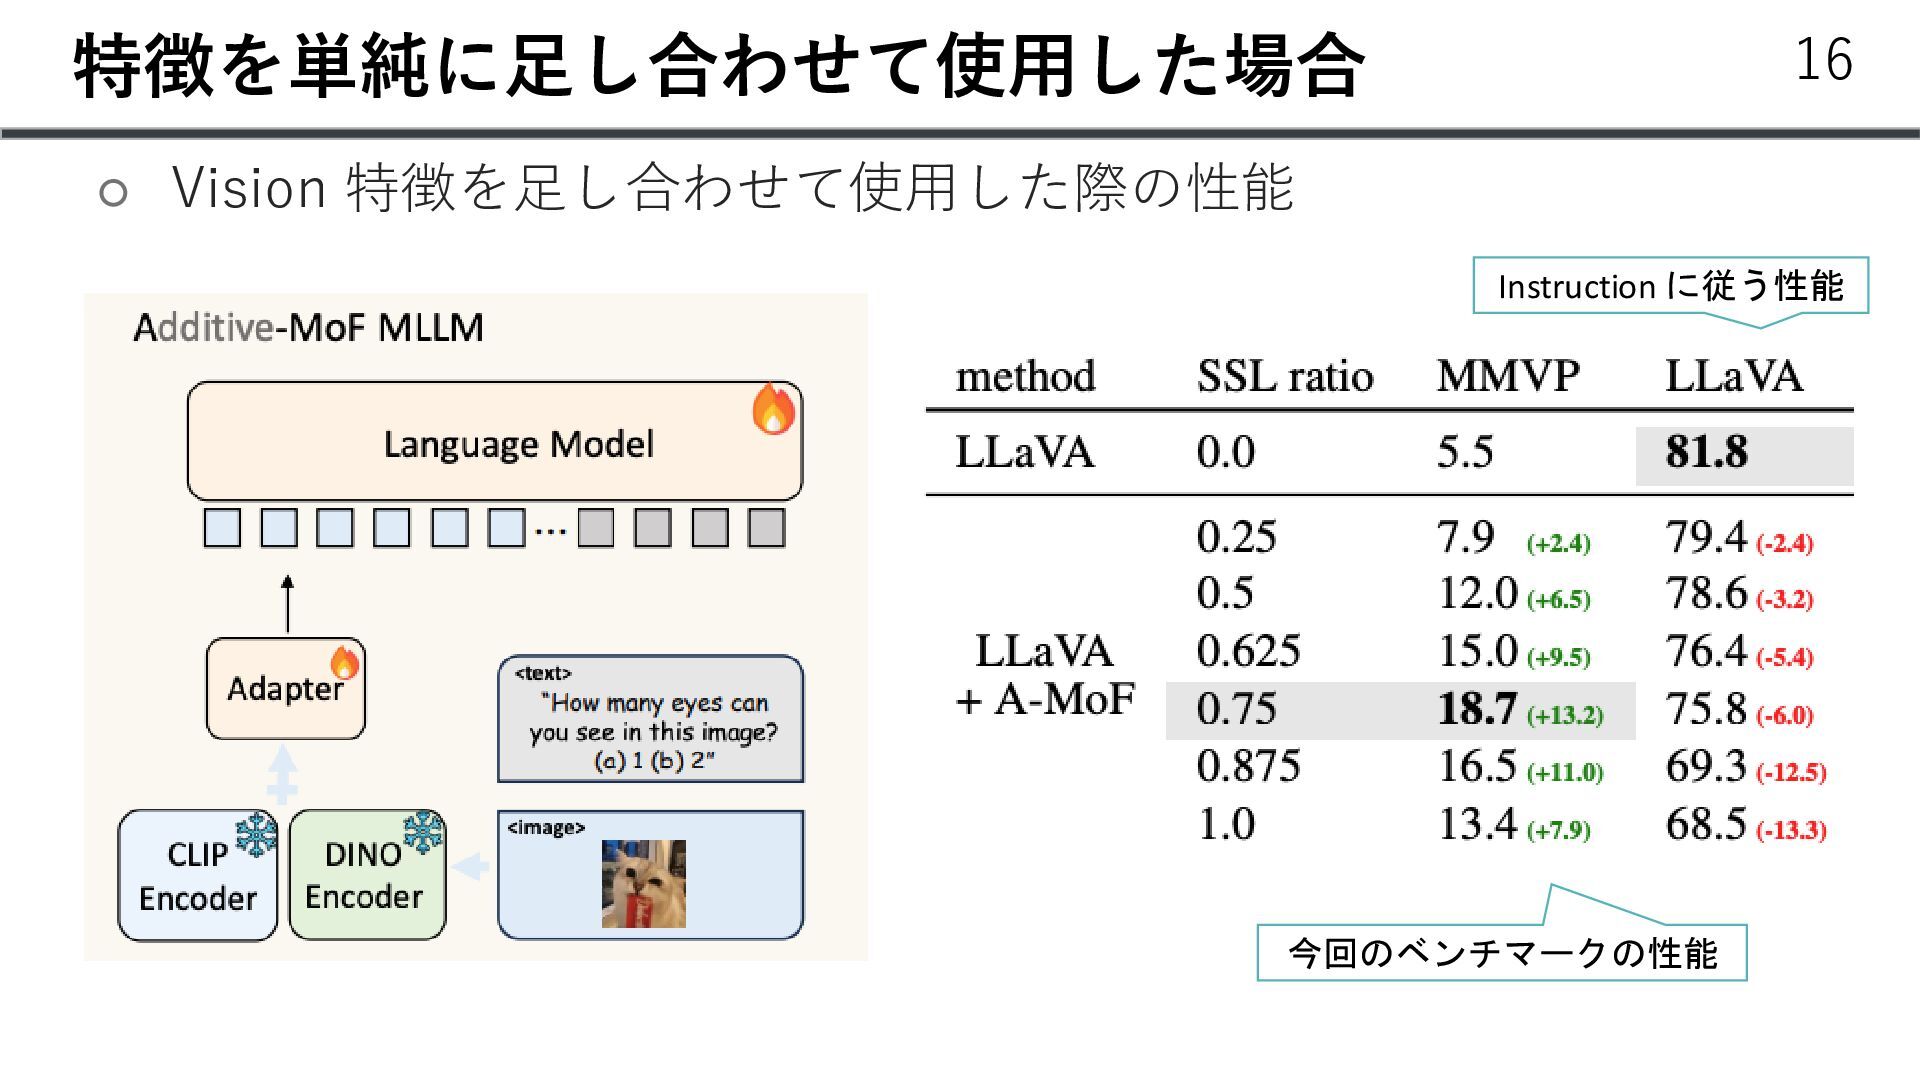
特徴を単純に足し合わせて使用した場合 ◦ Vision 特徴を足し合わせて使用した際の性能 16 今回のベンチマークの性能 Instruction に従う性能
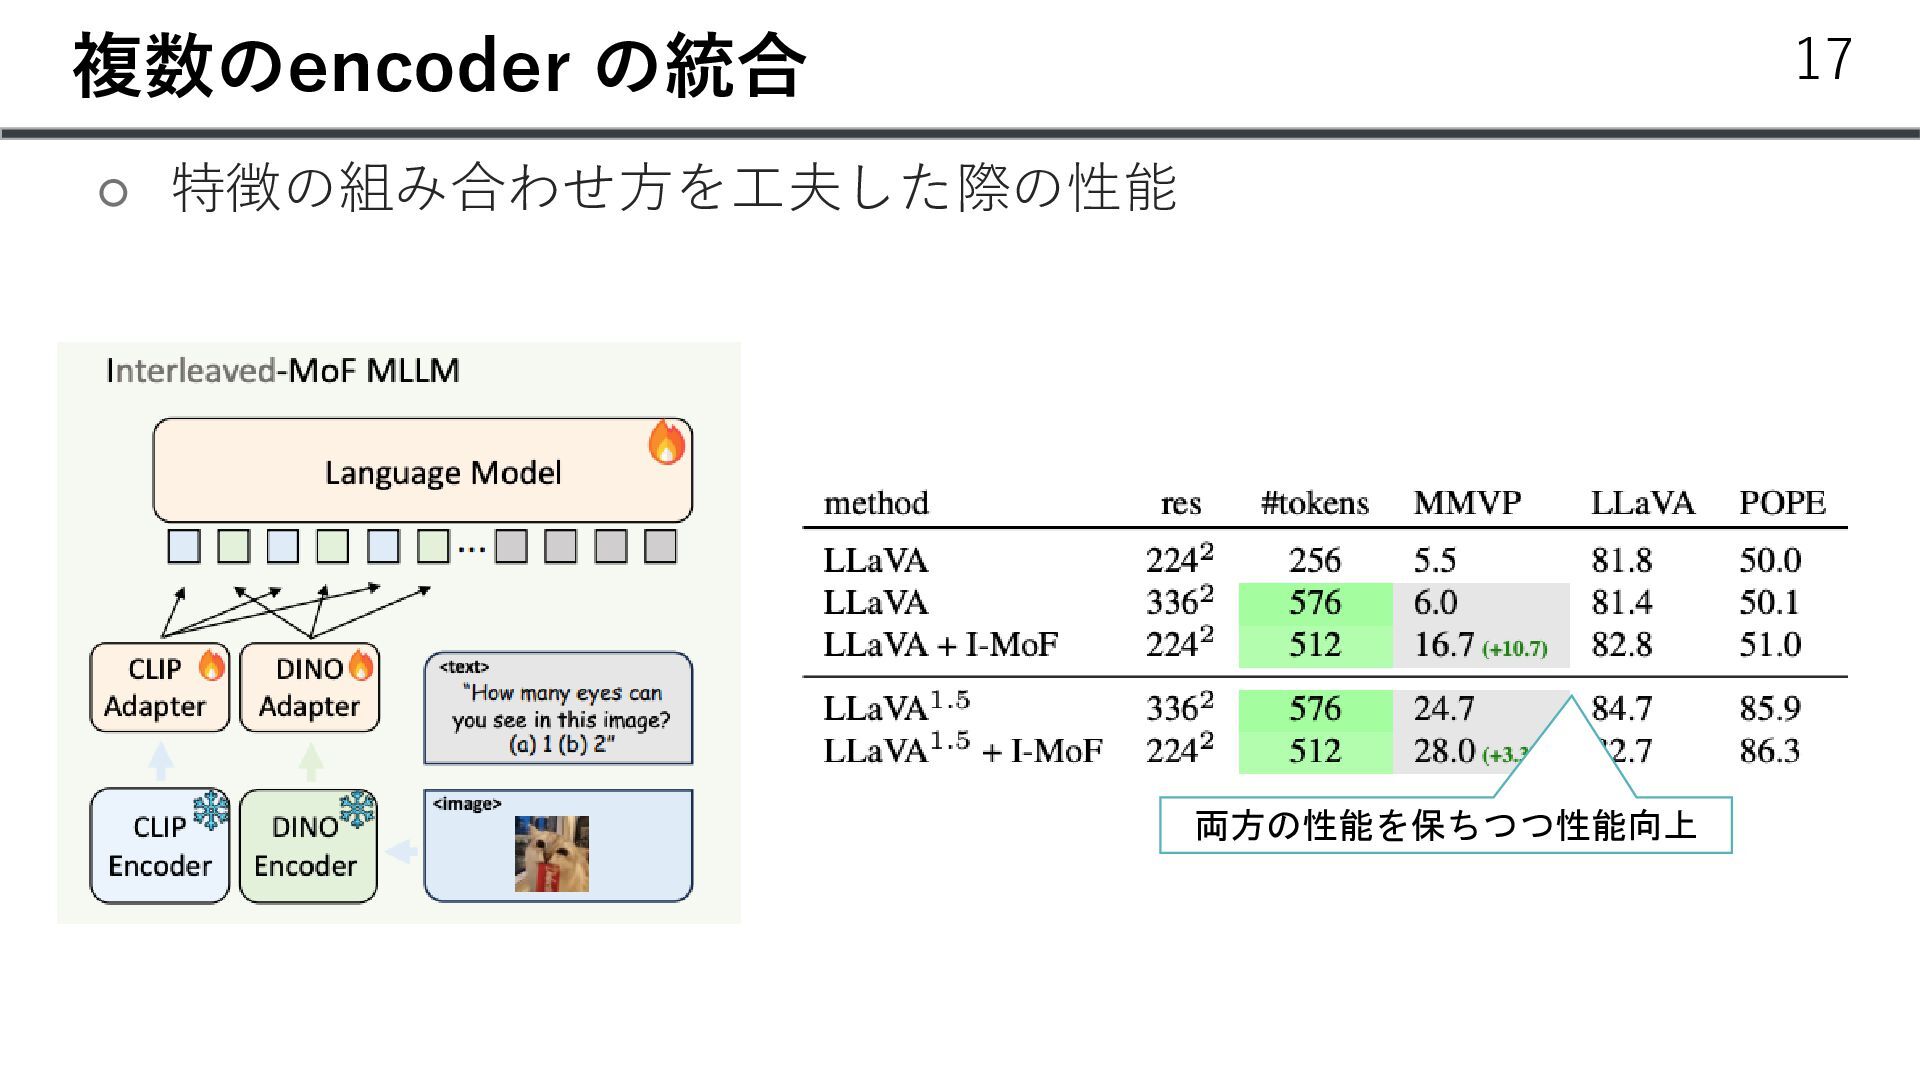
複数のencoder の統合 ◦ 特徴の組み合わせ方を工夫した際の性能 17 両方の性能を保ちつつ性能向上
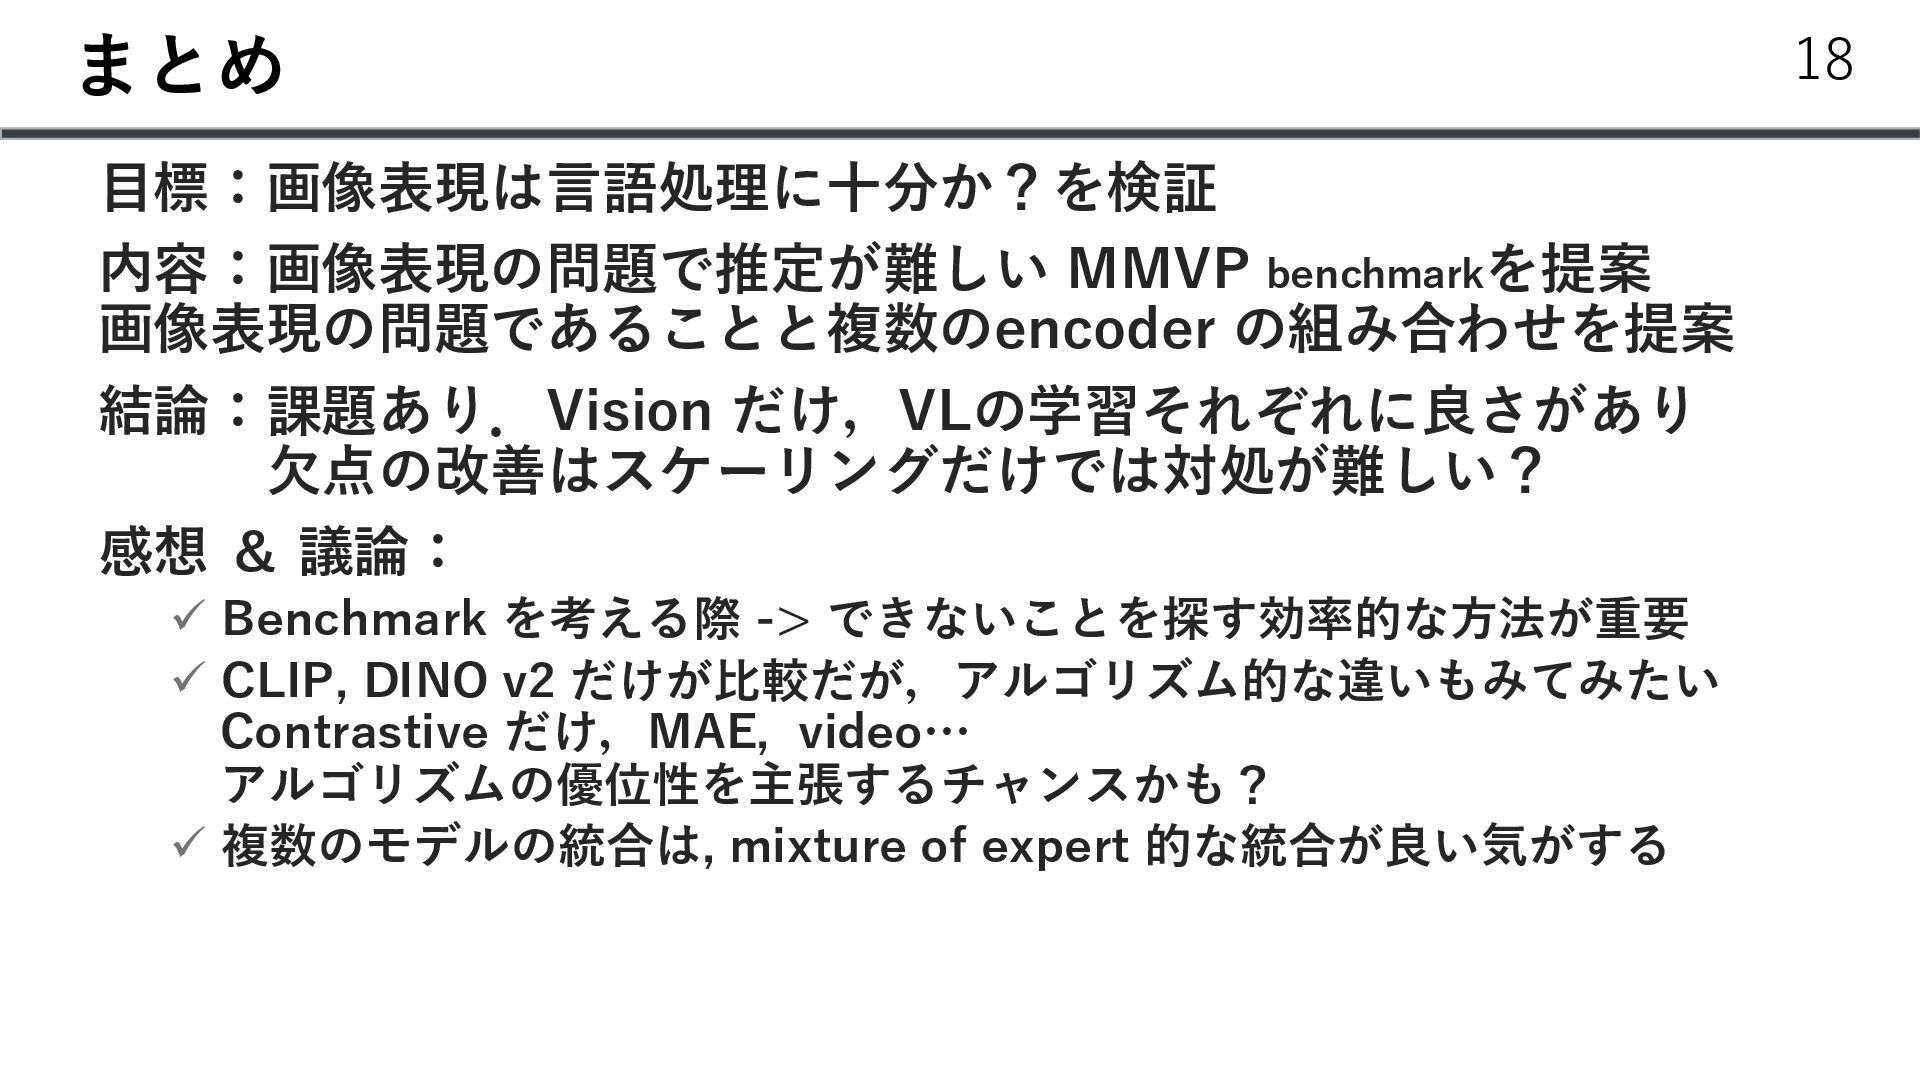
まとめ 目標:画像表現は言語処理に十分か?を検証 内容:画像表現の問題で推定が難しい MMVP benchmarkを提案 画像表現の問題であることと複数のencoder の組み合わせを提案 結論:課題あり.Vision だけ,VLの学習それぞれに良さがあり 欠点の改善はスケーリングだけでは対処が難しい?
感想 & 議論: ✓ Benchmark を考える際 -> できないことを探す効率的な方法が重要 ✓ CLIP, DINO v2 だけが比較だが,アルゴリズム的な違いもみてみたい Contrastive だけ,MAE, video… アルゴリズムの優位性を主張するチャンスかも? ✓ 複数のモデルの統合は, mixture of expert 的な統合が良い気がする 18


 naivete5656
 dk999
 institutdelelevage
 ayatokanada
 gpeyre
 casualconc
 yumulab
 sazimai
 izumiyama_lab
 sishi
 reokashiwa
 uxyall
 techseoconnect
 letsgokoyo
 eileencodes
 aleyda
 tessaabrams
 davidcarrasco
 oripsolob
 katarinadahlin
 akademiya2063
 tammyeverts
 deanohume