Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
理解してほしいVision Transformer / plz-understand-ViT
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
shun74
June 23, 2022
Programming
870
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
理解してほしいVision Transformer / plz-understand-ViT
Easy to understand explanation form NN to ViT.
shun74
June 23, 2022
More Decks by shun74
See All by shun74
深度推定モデルの自己教師あり学習/self-supervised-depth
shun74
0
580
GPUでステレオマッチング / Stereo-matching with GPU
shun74
0
1.3k
卒業研究の進め方 / How to preceed with the research
shun74
1
660
Barcode Recognition / pharmacode-decoder
shun74
0
1.2k
Vision Transformer講座 / Vision Transformer Presentation
shun74
1
860
ニューラルネットの1bit化 / 1bit-neural-network
shun74
0
1.1k
Defocus Map Estimation From a Single Image Based on Two-Parameter Defocus Model / two-parameter-defocus-model
shun74
0
440
Other Decks in Programming
See All in Programming
Coding with AI: How to trust the storyteller (AWS Community Day Adria, Ljubljana 2026)
slobodan
0
140
baseline으로 마이그레이션, 리팩토링 안전하게 맡기기
fornewid
1
900
JIS keyboard support in Omarchy
lef237
0
180
Seven New Principles of Software Engineering
yegor256
0
450
ActionController meets Protocol Buffers
sorah
1
780
Getting Started with Vibe Coding
miccheng
0
180
SODA - FACT BOOK(EN)
sodainc
1
210
[JA] Domain Modeling with Vanilla Rails: 「操作」から再考するRailsの設計論
yasaichi
4
1.8k
S3 TablesのIcebergデータに、AIエージェントからアクセスしてみた / 20261016developersio2026joetsu-accessing-iceberg-in-s3tables-via-agent
kasacchiful
PRO
0
280
TS 7.0 で baseUrl が使えなくなった今、パスエイリアスをどうするか
bicstone
2
520
Enforcing Your Architecture with Unit Tests in the AI Era (Swift Connection X)
steliosf
PRO
1
140
PumaからFalconに移行したRailsアプリケーションでの実践
falcon8823
0
350
Featured
See All Featured
AI Search: Implications for SEO and How to Move Forward - #ShenzhenSEOConference
aleyda
1
1.4k
Into the Great Unknown - MozCon
thekraken
41
2.8k
Building Applications with DynamoDB
mza
96
7.3k
Tell your own story through comics
letsgokoyo
1
1.1k
How to Align SEO within the Product Triangle To Get Buy-In & Support - #RIMC
aleyda
2
1.9k
Building Better People: How to give real-time feedback that sticks.
wjessup
371
20k
Noah Learner - AI + Me: how we built a GSC Bulk Export data pipeline
techseoconnect
PRO
0
480
My Coaching Mixtape
mlcsv
0
380
Statistics for Hackers
jakevdp
799
230k
Avoiding the “Bad Training, Faster” Trap in the Age of AI
tmiket
0
300
The Director’s Chair: Orchestrating AI for Truly Effective Learning
tmiket
1
350
B2B Lead Gen: Tactics, Traps & Triumph
marketingsoph
1
300
Transcript
理解してほしい VisionTransformer B4 佐藤 駿
はじめに • 機械学習を全く知らない人でも理解できるように解説します 目次 • 機械学習 • ニューラルネット • 畳み込みニューラルネット
(CNN) • Vision Transformer (ViT) • Attention • CNN vs ViT • ViTとCNNのいいとこどり例
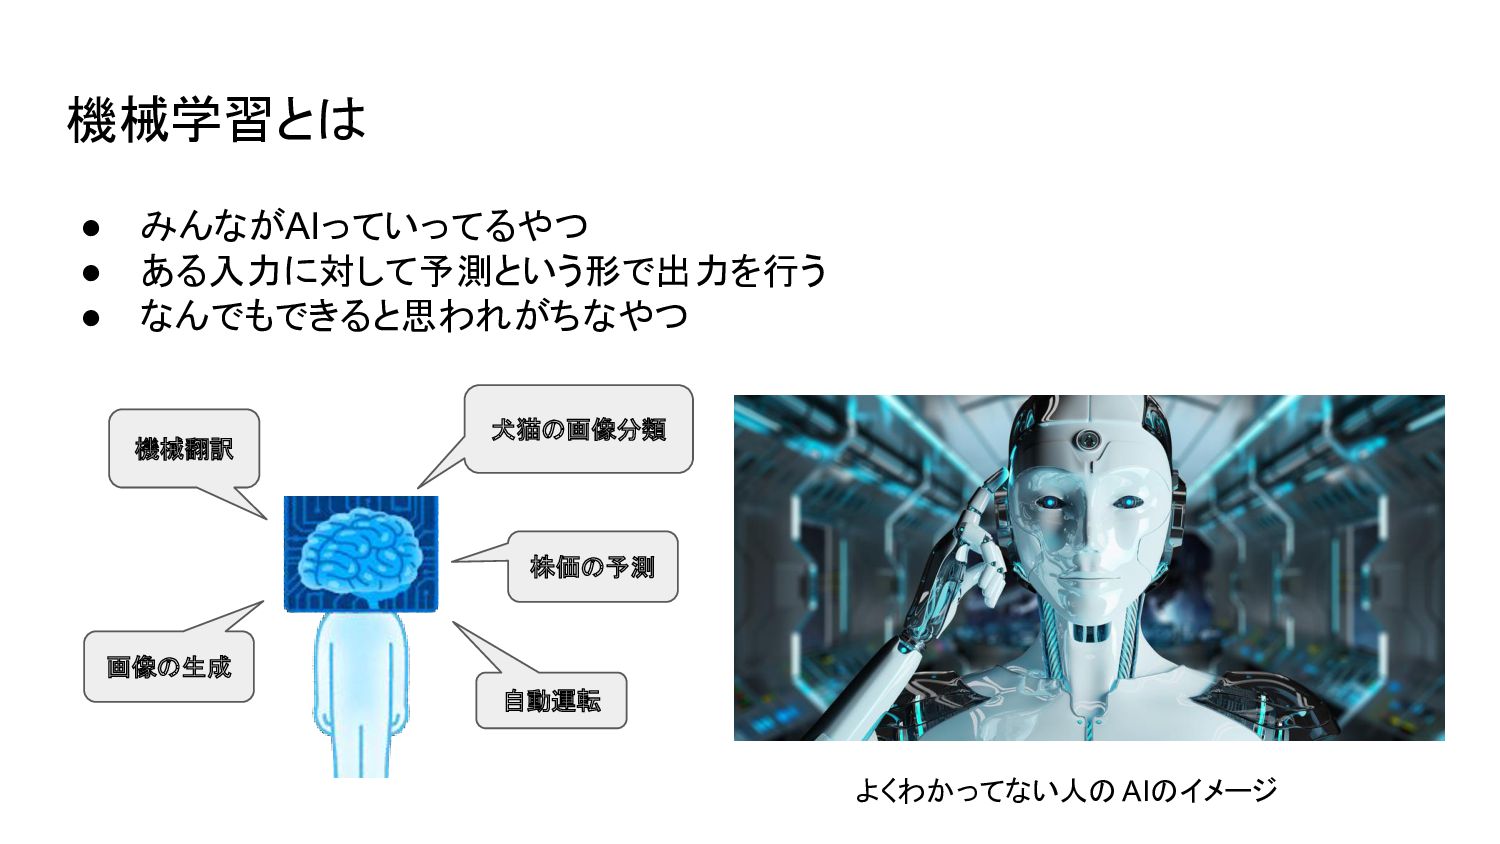
機械学習とは • みんながAIっていってるやつ • ある入力に対して予測という形で出力を行う • なんでもできると思われがちなやつ 犬猫の画像分類 株価の予測 機械翻訳
画像の生成 自動運転 よくわかってない人の AIのイメージ
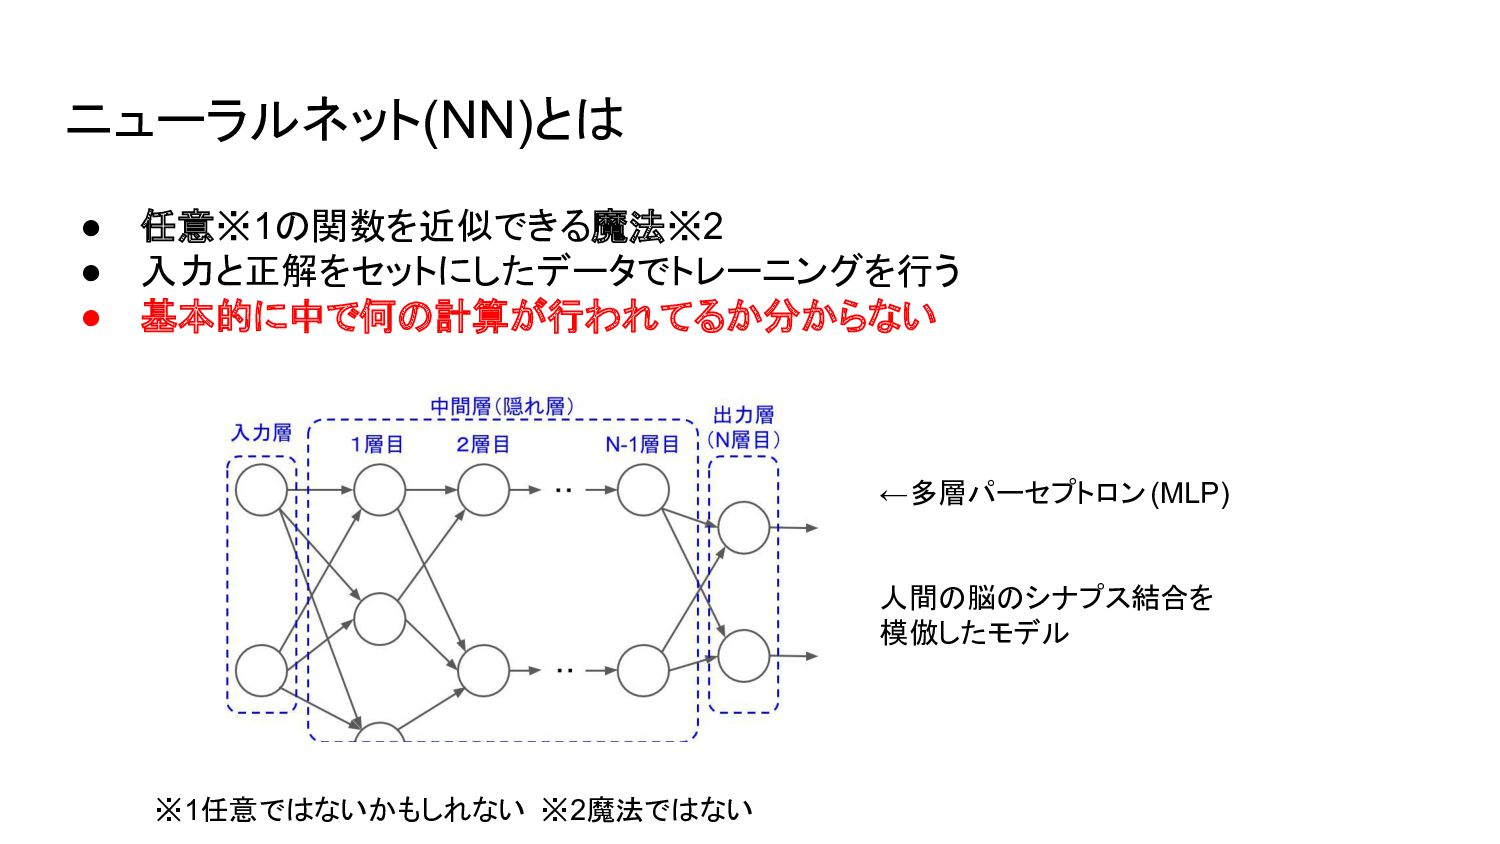
ニューラルネット(NN)とは • 任意※1の関数を近似できる魔法※2 • 入力と正解をセットにしたデータでトレーニングを行う • 基本的に中で何の計算が行われてるか分からない ※1任意ではないかもしれない ※2魔法ではない ←多層パーセプトロン(MLP)
人間の脳のシナプス結合を 模倣したモデル
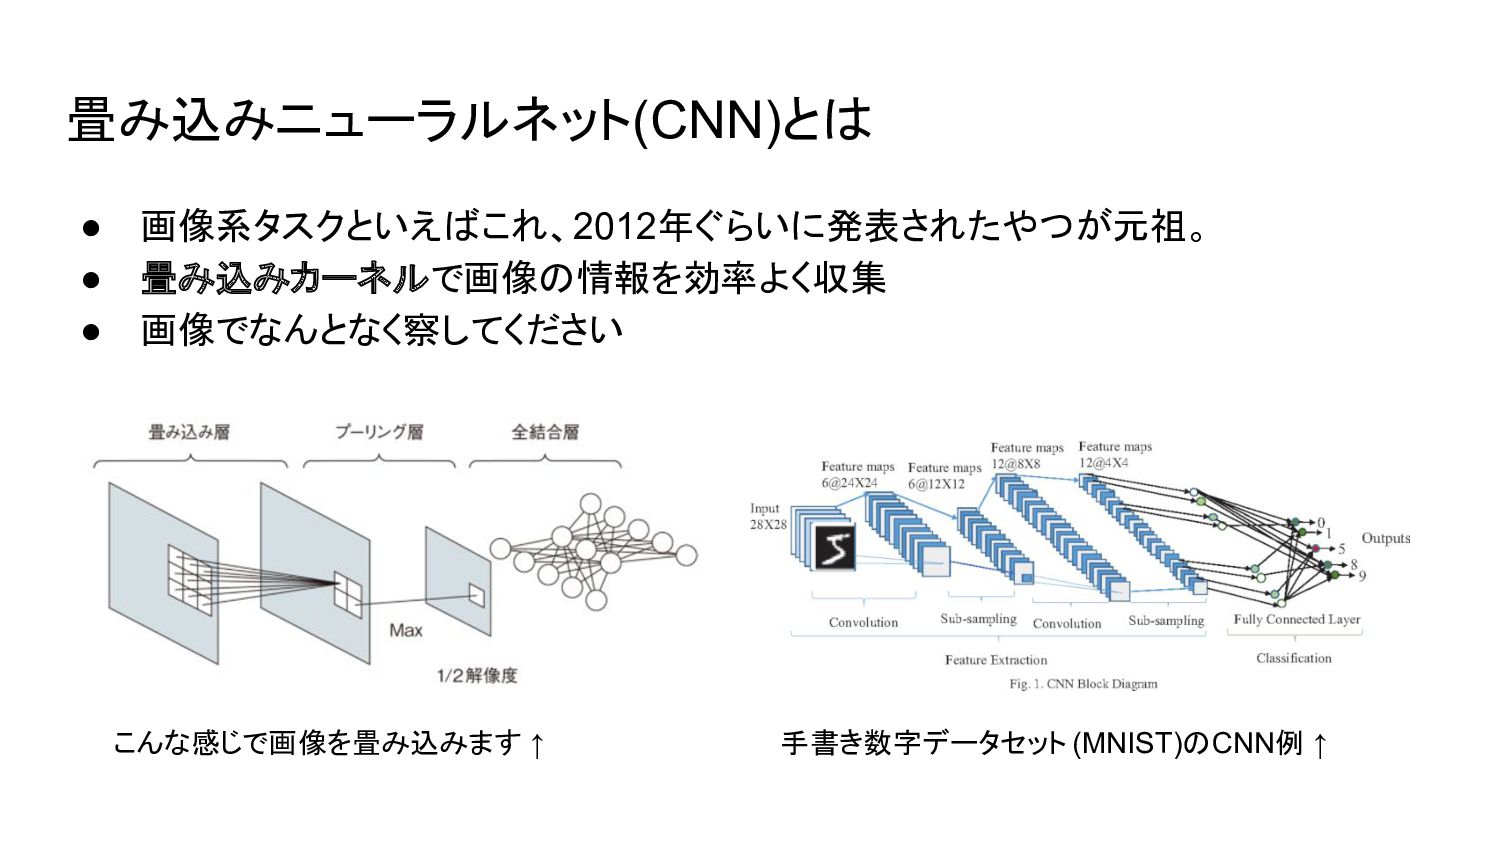
畳み込みニューラルネット(CNN)とは • 画像系タスクといえばこれ、2012年ぐらいに発表されたやつが元祖。 • 畳み込みカーネルで画像の情報を効率よく収集 • 画像でなんとなく察してください 手書き数字データセット (MNIST)のCNN例 ↑
こんな感じで画像を畳み込みます ↑
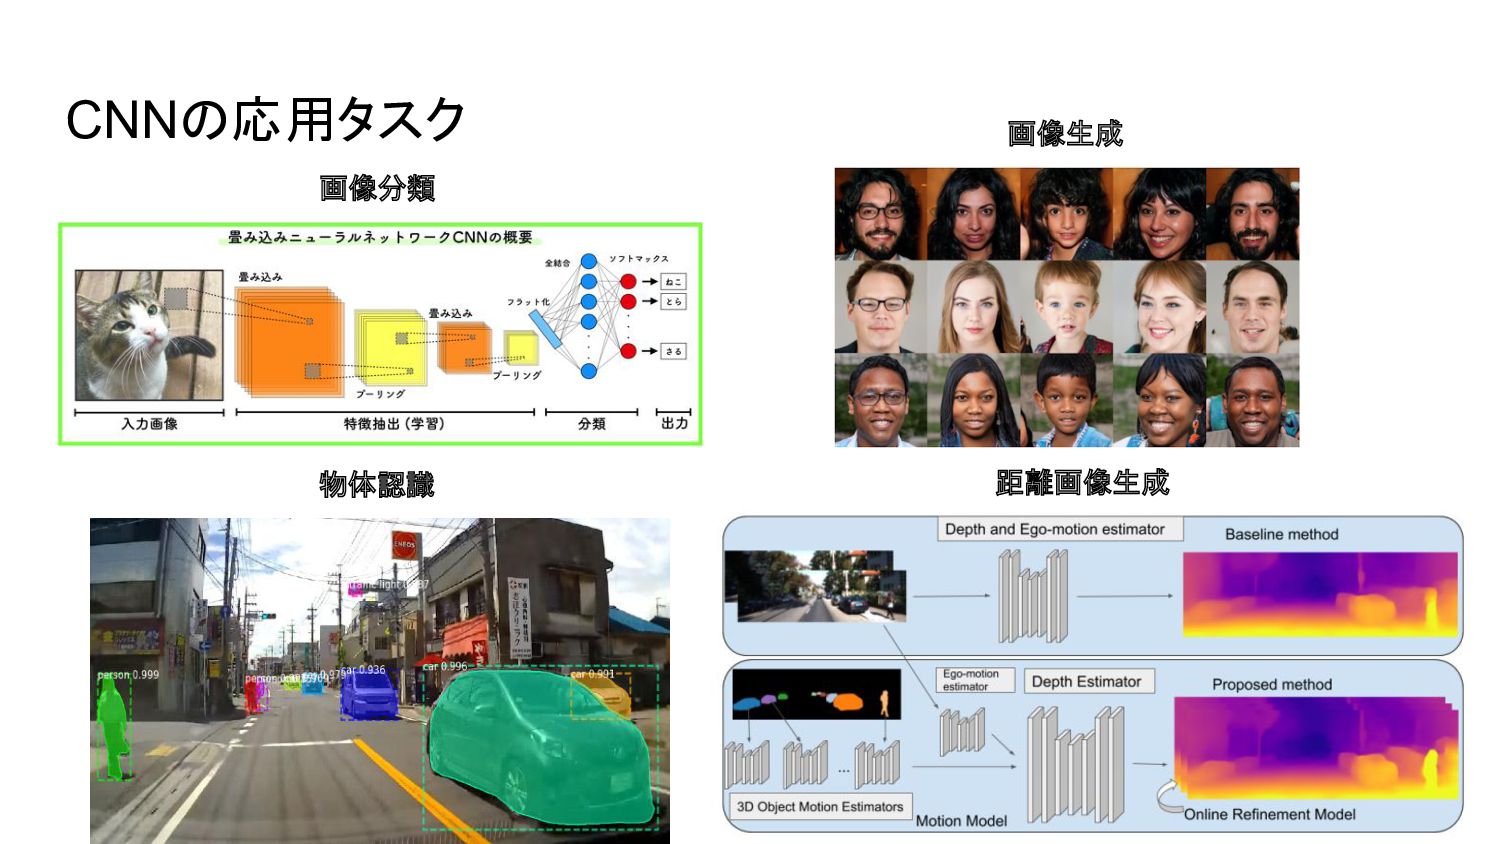
CNNの応用タスク 画像分類 画像生成 物体認識 距離画像生成
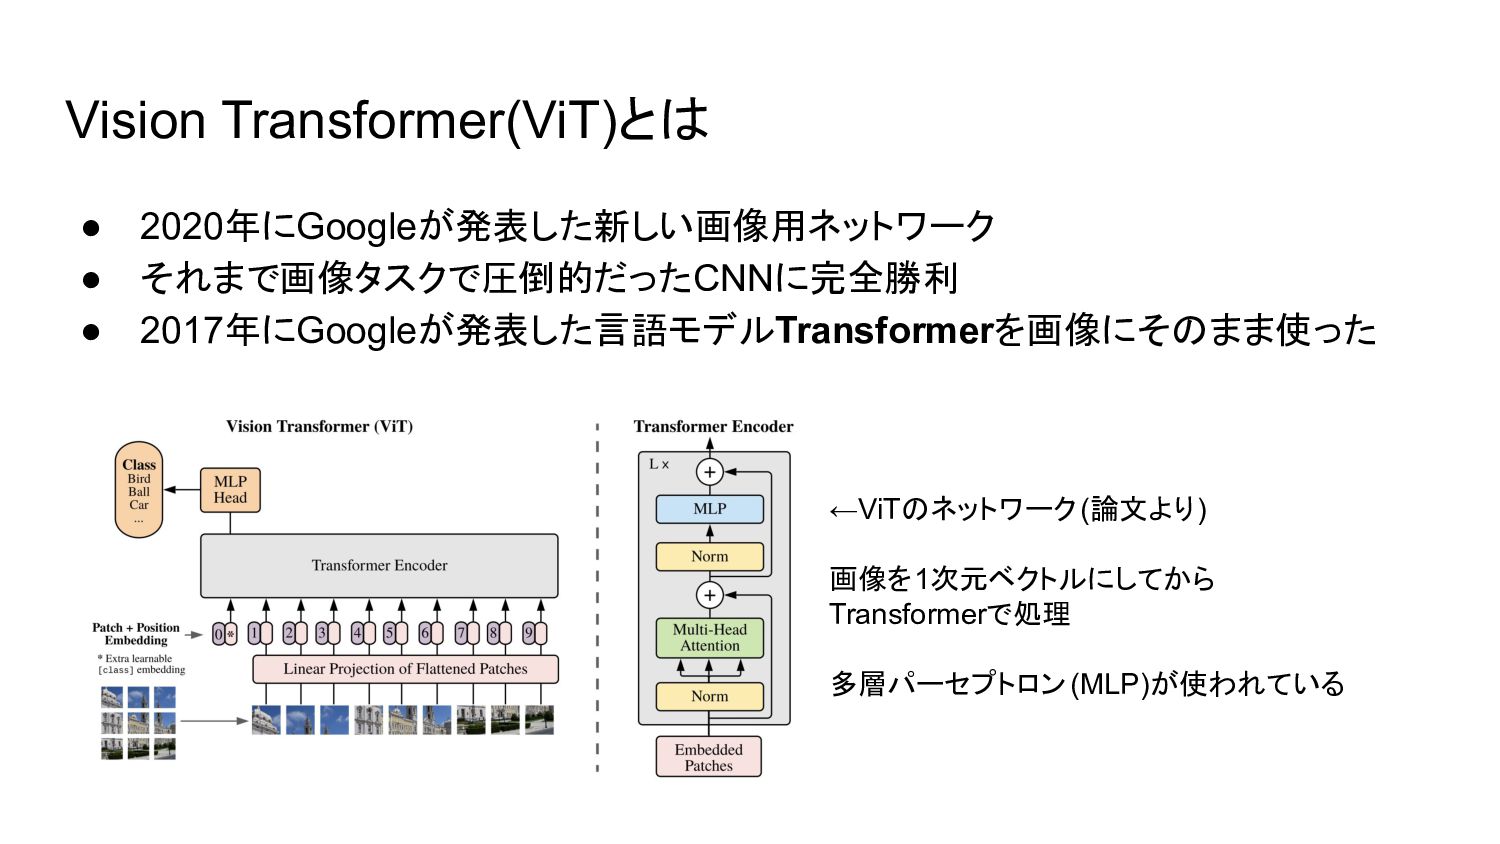
Vision Transformer(ViT)とは • 2020年にGoogleが発表した新しい画像用ネットワーク • それまで画像タスクで圧倒的だったCNNに完全勝利 • 2017年にGoogleが発表した言語モデルTransformerを画像にそのまま使った ←ViTのネットワーク(論文より) 画像を1次元ベクトルにしてから
Transformerで処理 多層パーセプトロン(MLP)が使われている
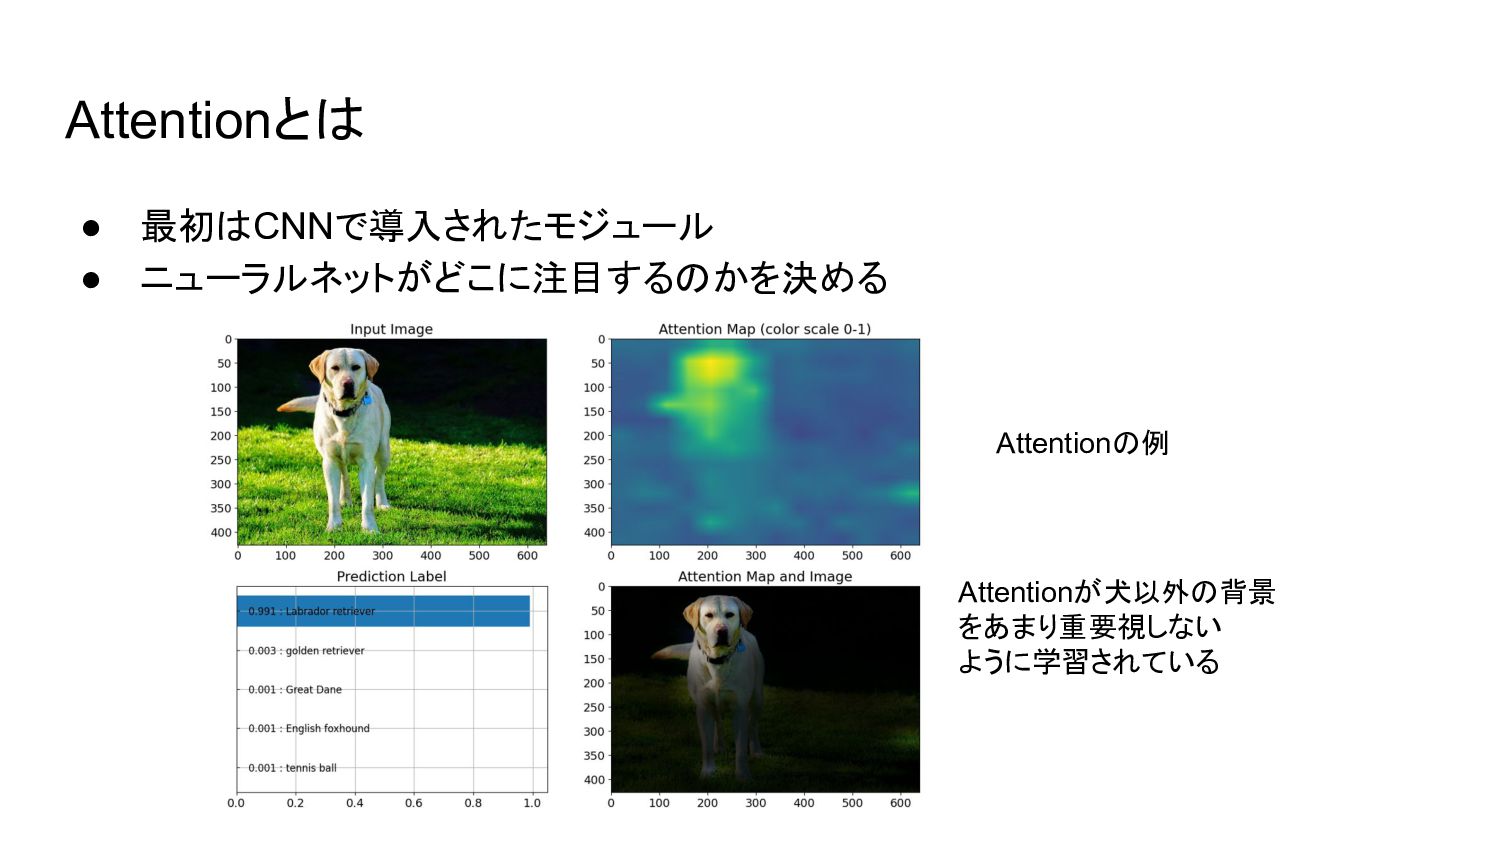
Attentionとは • 最初はCNNで導入されたモジュール • ニューラルネットがどこに注目するのかを決める Attentionの例 Attentionが犬以外の背景 をあまり重要視しない ように学習されている
Scaled Dot-Product Attentionの解説 Query, Key, Valueを用意して計算 1. Query, Keyの行列積を計算 2.
SoftMaxを使ってAttentionMapを生成 3. ValueにMaskを適用して完成 • ViTで使われているのはMulti-Head Attention • Scaled Dot-Product Attentionを複数使う • より多くのパターンを作ることで情報量UP
Vision Transformerのアーキテクチャ1 入力 画像をパッチに分割して1次元ベクトル化 (xy座標情報は捨てる) パッチごとにPosition Embeddingも追加 ViTでは16*16単位で画像をパッチ化 パッチ化した画像を平坦化して入力!
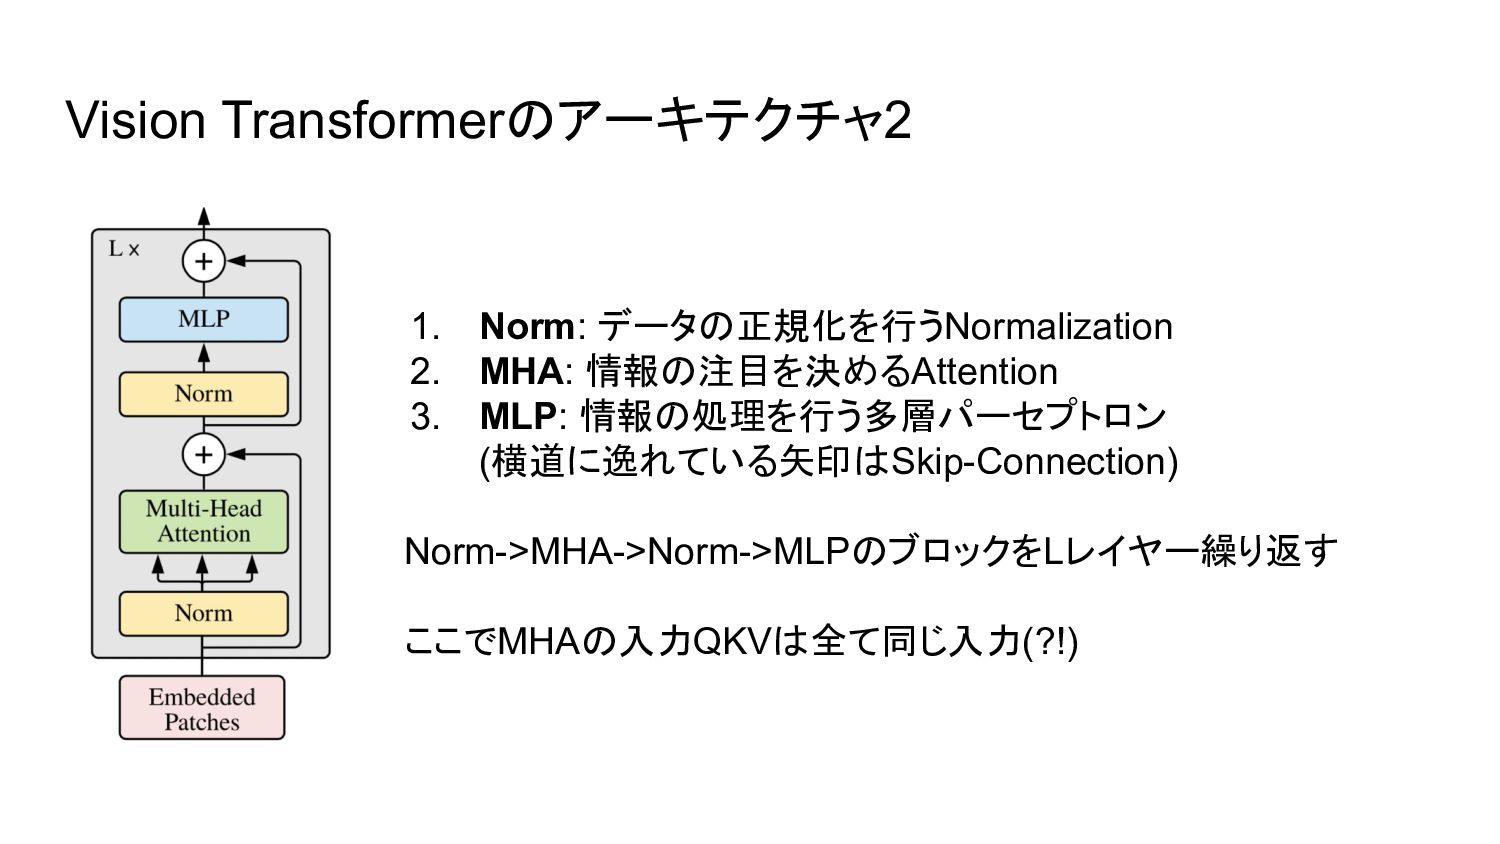
Vision Transformerのアーキテクチャ2 1. Norm: データの正規化を行うNormalization 2. MHA: 情報の注目を決めるAttention 3. MLP:
情報の処理を行う多層パーセプトロン (横道に逸れている矢印はSkip-Connection) Norm->MHA->Norm->MLPのブロックをLレイヤー繰り返す ここでMHAの入力QKVは全て同じ入力(?!)
CNN vs ViT Q. なぜViTがCNNに圧勝したのか A. タスクがちょうど良かったから ViT : Attentionで全体(Global)の特徴量をまとめる
CNN: 畳み込みで局所(Local)の特徴量を捉える • 比較が画像分類タスクだったためViTが圧勝した • 画像分類は画像の中に何が映っているか何となく分かればいい ViTとResNet(CNN)の 内部表現の類似性の比較 ViTの方が安定した表現を 獲得している (?)
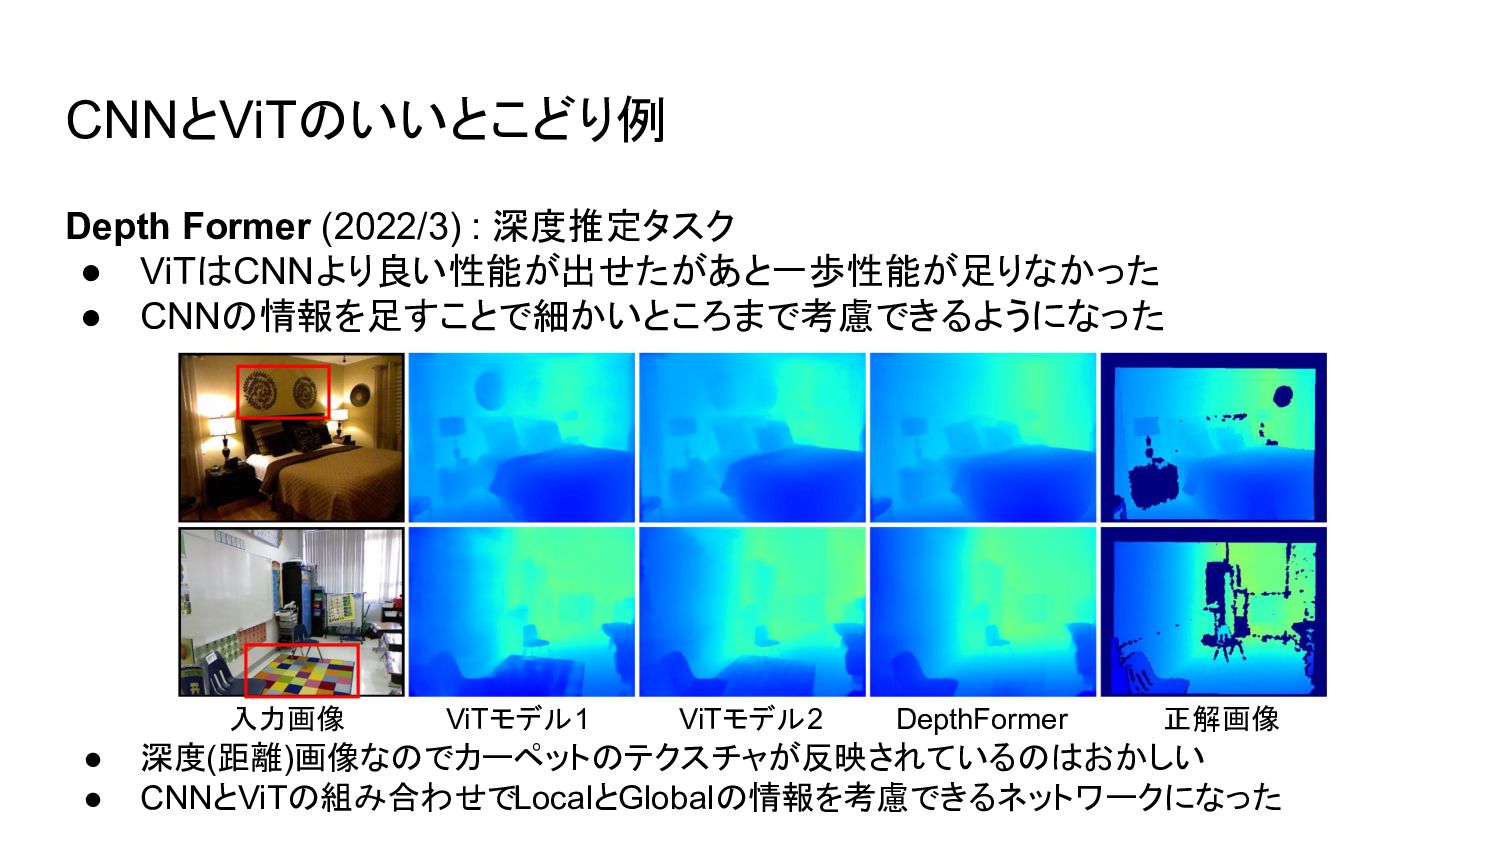
CNNとViTのいいとこどり例 Depth Former (2022/3) : 深度推定タスク • ViTはCNNより良い性能が出せたがあと一歩性能が足りなかった • CNNの情報を足すことで細かいところまで考慮できるようになった
• 深度(距離)画像なのでカーペットのテクスチャが反映されているのはおかしい • CNNとViTの組み合わせでLocalとGlobalの情報を考慮できるネットワークになった 入力画像 ViTモデル1 ViTモデル2 DepthFormer 正解画像
さいごに • 現在多くの画像タスクでBackboneとしてViTが使われている • ViT自体も様々なモデルの開発競争が行われている • ViT以外にもCNNだけのモデルやMLPのモデルも研究されている • みんなもViTを実装して最新のAIモデルを作ろう! •
画像系AIの相談があれば@shun74まで
参考 1. ニューラルネット: https://ledge.ai/neural-network/ 2. CNN: https://leadinge.co.jp/rd/2021/06/07/863/ 3. ViT: https://qiita.com/omiita/items/0049ade809c4817670d7
(最強資料) 4. ViT vs CNN: https://ai-scholar.tech/articles/transformer/transformer-vs-cnn 5. DepthFormer: https://arxiv.org/abs/2203.14211


 shun74
 slobodan
 fornewid
 lef237
 yegor256
 sorah
 miccheng
 sodainc
 yasaichi
 kasacchiful
 bicstone
 steliosf
 falcon8823
 aleyda
 thekraken
 mza
 letsgokoyo
 wjessup
 techseoconnect
 mlcsv
 jakevdp
 tmiket
 marketingsoph