Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
文献紹介201902_Effectively Crowdsourcing Radiology ...
Search
T.Tada
February 19, 2019
Technology
110
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
文献紹介201902_Effectively Crowdsourcing Radiology Report Annotations
T.Tada
February 19, 2019
More Decks by T.Tada
See All by T.Tada
文献紹介_202002_Is artificial data useful for biomedical Natural Language Processing algorithms?
tad
0
77
文献紹介_202001_A Novel System for Extractive Clinical Note Summarization using EHR Data
tad
0
200
文献紹介_201912_Publicly Available Clinical BERT Embeddings
tad
0
180
文献紹介_201911_EDA: Easy Data Augmentation Techniques for Boosting Performance on Text Classification Tasks
tad
0
230
文献紹介_201910_Do Neural NLP Models Know Numbers? Probing Numeracy in Embeddings
tad
0
110
文献紹介_201909_Sentence Mover’s Similarity_ Automatic Evaluation for Multi-Sentence Texts
tad
0
180
文献紹介_201908_Medical Word Embeddings for Spanish_ Development and Evaluation
tad
0
73
文献紹介_201907_Is Word Segmentation Necessary for Deep Learning of Chinese Representations
tad
0
130
文献紹介_201906_Predicting Annotation Difficulty to Improve Task Routing and Model Performance for Biomedical Information Extraction
tad
0
120
Other Decks in Technology
See All in Technology
Rust で関数型ドメインモデリング
takonda
0
140
Metadata - Section 1: HTML Basics
mohab1
0
120
スキマバイトという雇用形態は存在しないので、雇用期間1日のアルバイト契約を事業者とワーカーが結ぶ手続きを支えるのがタイミーなんです
akitoshiga
0
200
SAENM ~Jupyterで残すPoCの試行錯誤、未来の自分と仲間を助ける記録!~
terapyon
0
110
DevelopersIO 2026 知識の地図を描く ─ オントロジーとは何か?
ishikawa_satoru
1
1.7k
Temporal 最高!でも改めて「日付」について調べたら人類の負債すぎる件
riyaamemiya
0
150
V8のArray.prototype.flatを最大約20倍速くするまでと、巨大OSSへの大規模コミットの道のり
riyaamemiya
0
290
DGX Spark でどこまでハッキングができるのか?
kash1064
3
1.3k
Webの常識が通じないHTMLメールのダークモード
teamlab
PRO
0
120
AI導入は済んだ。次は統制を作り替える番だ_AI×開発組織 Summit 2026
techtekt
PRO
0
210
Claude Code本は、どのように執筆チームで書かれたか
oikon48
1
380
「事実」を「計測」して、「解釈」する 〜AWS Lambdaのメモリ最適解の見つけ方〜
maimyyym
0
170
Featured
See All Featured
Producing Creativity
orderedlist
PRO
348
41k
Collaborative Software Design: How to facilitate domain modelling decisions
baasie
1
340
Scaling GitHub
holman
464
140k
How to Think Like a Performance Engineer
csswizardry
28
2.9k
Understanding Cognitive Biases in Performance Measurement
bluesmoon
32
3.1k
Build your cross-platform service in a week with App Engine
jlugia
234
19k
Leveraging Curiosity to Care for An Aging Population
cassininazir
1
540
Mind Mapping
helmedeiros
1
400
[Rails World 2023 - Day 1 Closing Keynote] - The Magic of Rails
eileencodes
38
3.1k
CSS Pre-Processors: Stylus, Less & Sass
bermonpainter
360
31k
Dominate Local Search Results - an insider guide to GBP, reviews, and Local SEO
greggifford
PRO
0
370
YesSQL, Process and Tooling at Scale
rocio
174
15k
Transcript
- 文献紹介 2019/2/19 - Effectively Crowdsourcing Radiology Report Annotations 長岡技術科学大学
自然言語処理研究室 多田太郎
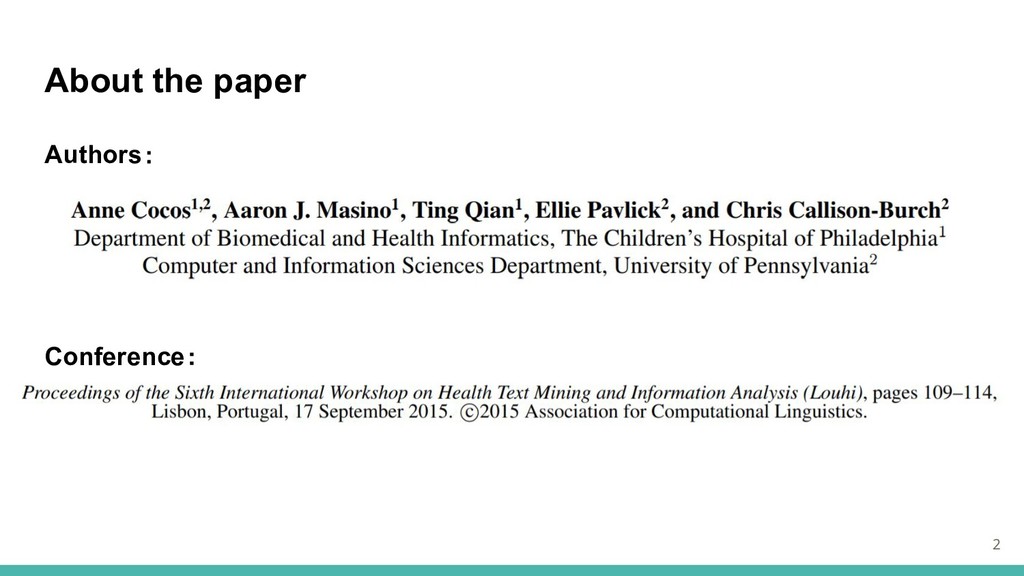
About the paper 2 Authors: Conference:
Abstract ・ラベリング作業に医療分野の知識が必要な場合、クラウドソーシングは有用か ・エキスパート注釈とクラウドソーシング注釈で訓練された同じモデルで比較 ・両手法で作成されたデータセットは同じくらい効果的であることがわかった ・クラウドソーシングによるラベルの一部を除外することで、モデルの精度が向上 3
Introduction ・多くのテキスト分類手法は、大量のラベル付きトレーニングデータが必要 →質の高いトレーニングデータを大量に収集することは、時間と費用がかかる ・アノテーションにドメイン知識を必要とする場合、クラウドソーシングはどれほど有用か ・放射線科レポートを正常または異常として分類するためのモデルに対する有用性 ・専門家とクラウドソーシングされたデータセットで分類モデルのパフォーマンスを比較 4
Methods and Data Collection ・Annotating radiology report reports ・Data collection
-Gold standard labels: expert annotations -Crowdsourced annotations -Weighting the workers’ votes ・Building a classification model 5
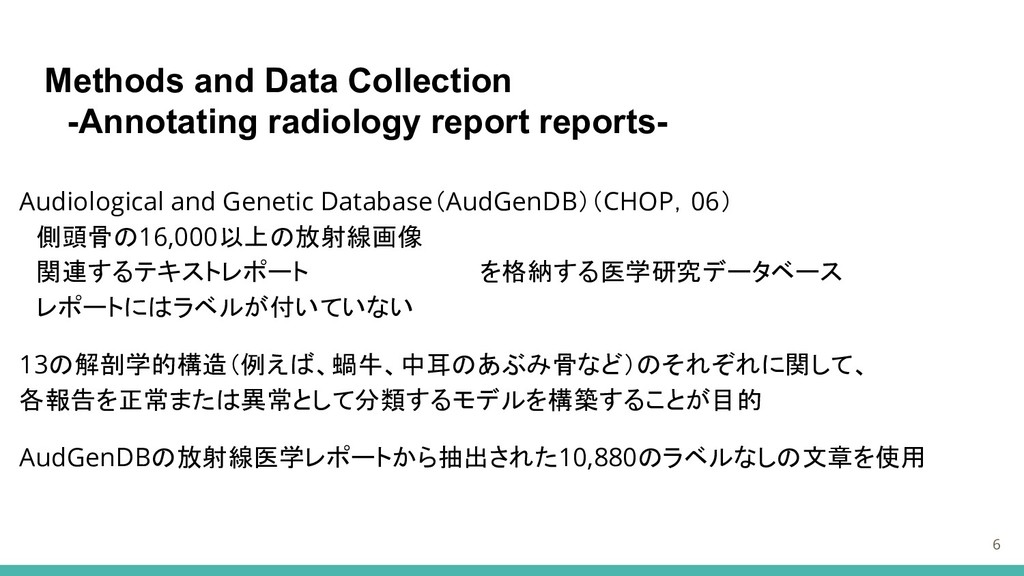
Methods and Data Collection -Annotating radiology report reports- Audiological and
Genetic Database(AudGenDB)(CHOP,06) 側頭骨の16,000以上の放射線画像 関連するテキストレポート を格納する医学研究データベース レポートにはラベルが付いていない 13の解剖学的構造(例えば、蝸牛、中耳のあぶみ骨など)のそれぞれに関して、 各報告を正常または異常として分類するモデルを構築することが目的 AudGenDBの放射線医学レポートから抽出された10,880のラベルなしの文章を使用 6
Methods and Data Collection ・Annotating radiology report reports ・Data collection
-Gold standard labels: expert annotations -Crowdsourced annotations -Weighting the workers’ votes ・Building a classification model 7
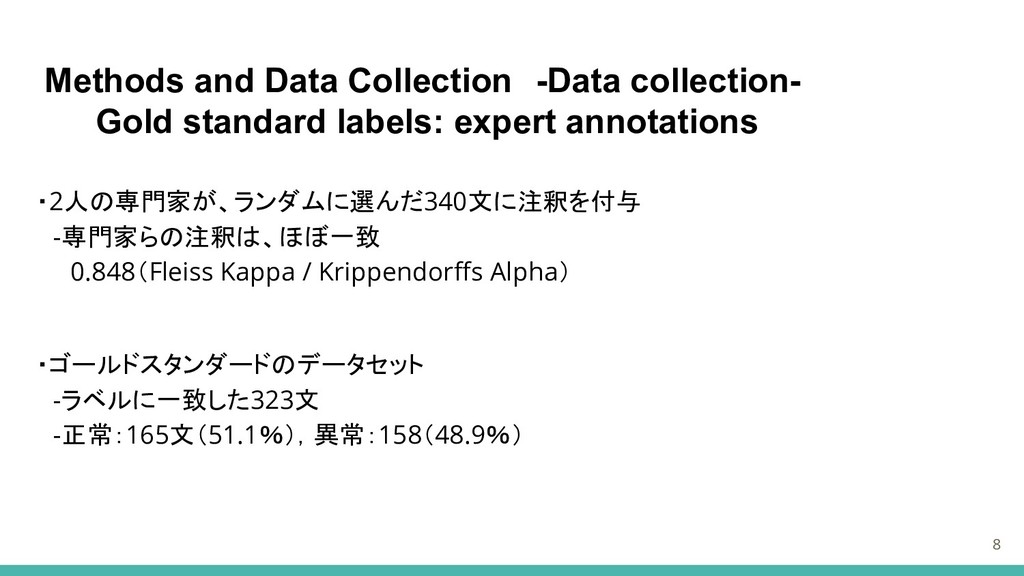
Methods and Data Collection -Data collection- Gold standard labels: expert annotations
・2人の専門家が、ランダムに選んだ340文に注釈を付与 -専門家らの注釈は、ほぼ一致 0.848(Fleiss Kappa / Krippendorffs Alpha) ・ゴールドスタンダードのデータセット -ラベルに一致した323文 -正常:165文(51.1%),異常:158(48.9%) 8
Methods and Data Collection -Data collection- Crowdsourced annotations- ・医療や放射線学の専門知識についてワーカーのスクリーニングを行わない ・以下の2点を各文に対して付与 -文が正常な観察か異常な観察か
-選択においての自信(非常に自信がある、多少自信がある、自信がない) ・各文少なくとも2人の作業者を設定 -文章ラベルが一致しなかった場合は、75%の一致率に達するまで注釈を収集し続けた -56人のユニークなワーカーにより717文を追加で収集 9
Methods and Data Collection ・以下2点をワーカーに提供 -「強調表示された文章を耳の特定の構成要素の正常または異常な観察を説明するもの として分類する」という簡単な指示 -正常および異常な文の例(ゴールドスタンダードの少なくとも1つの文を使用) 10 Methods
and Data Collection -Data collection- Crowdsourced annotations-
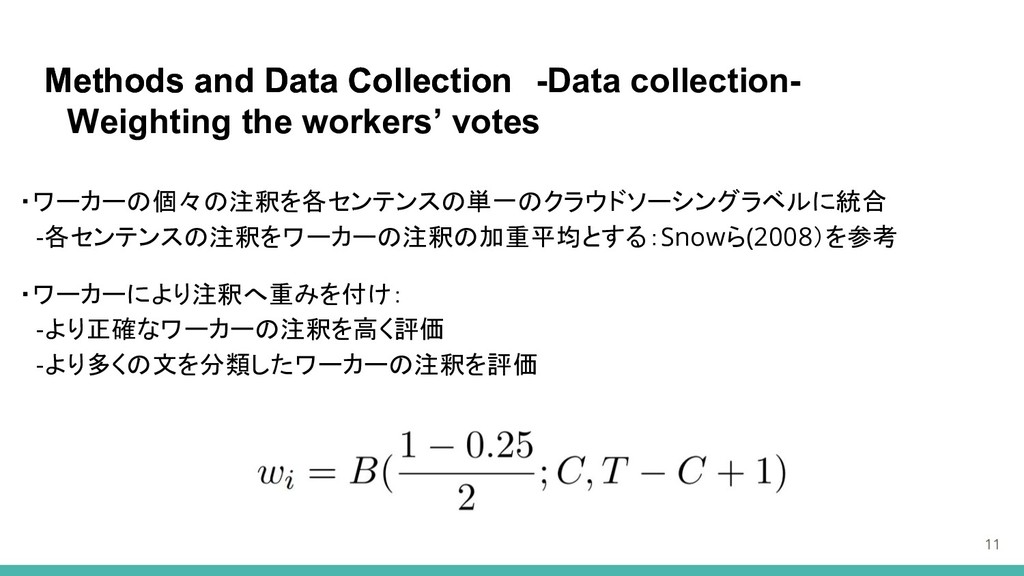
Methods and Data Collection ・ワーカーの個々の注釈を各センテンスの単一のクラウドソーシングラベルに統合 -各センテンスの注釈をワーカーの注釈の加重平均とする:Snowら(2008)を参考 ・ワーカーにより注釈へ重みを付け: -より正確なワーカーの注釈を高く評価 -より多くの文を分類したワーカーの注釈を評価 11
Methods and Data Collection -Data collection- Weighting the workers’ votes
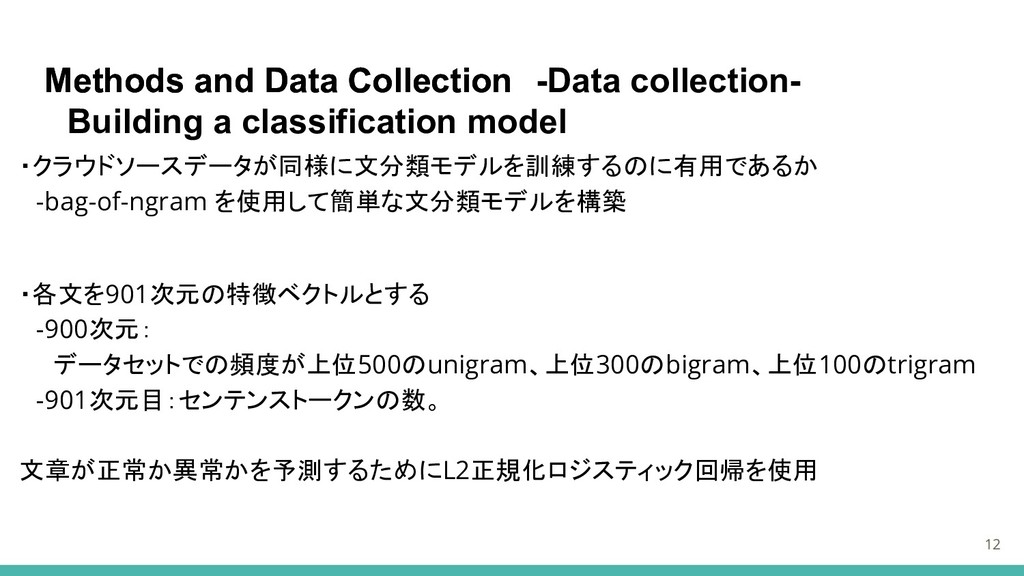
Methods and Data Collection ・クラウドソースデータが同様に文分類モデルを訓練するのに有用であるか -bag-of-ngram を使用して簡単な文分類モデルを構築 ・各文を901次元の特徴ベクトルとする -900次元: データセットでの頻度が上位500のunigram、上位300のbigram、上位100のtrigram
-901次元目:センテンストークンの数。 文章が正常か異常かを予測するためにL2正規化ロジスティック回帰を使用 12 Methods and Data Collection -Data collection- Building a classification model
Results ・Labeling performance and analysis ・Votes of confidence ・Using annotations
to train a classifier -Experts vs The Crowd -Increasing training instances -Incorporating confidence thresholds 13
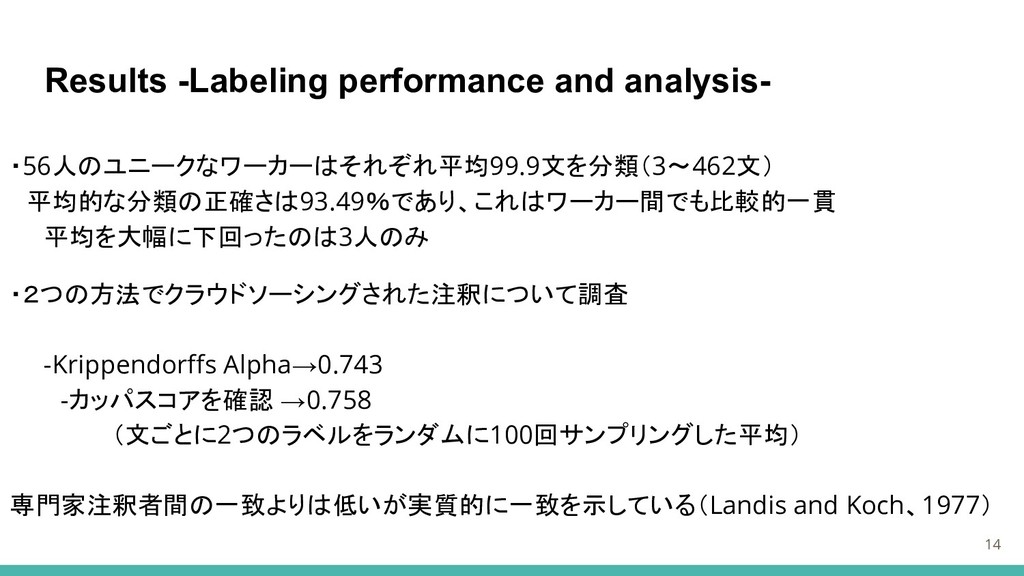
Results -Labeling performance and analysis- ・56人のユニークなワーカーはそれぞれ平均99.9文を分類(3〜462文) 平均的な分類の正確さは93.49%であり、これはワーカー間でも比較的一貫 平均を大幅に下回ったのは3人のみ ・2つの方法でクラウドソーシングされた注釈について調査 -Krippendorffs
Alpha→0.743 -カッパスコアを確認 →0.758 (文ごとに2つのラベルをランダムに100回サンプリングした平均) 専門家注釈者間の一致よりは低いが実質的に一致を示している(Landis and Koch、1977) 14
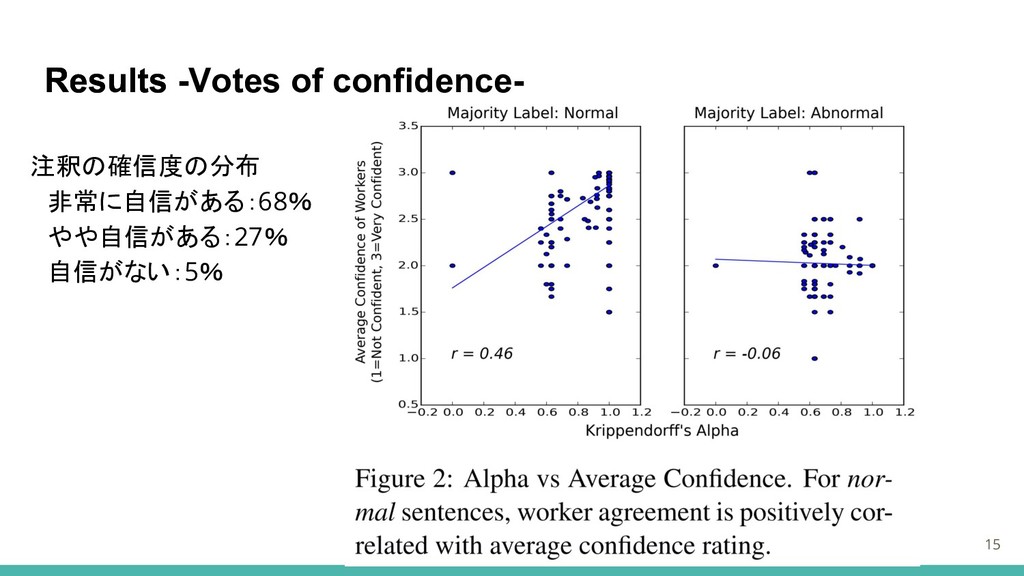
Results 15 Results -Votes of confidence- 注釈の確信度の分布 非常に自信がある:68% やや自信がある:27% 自信がない:5%
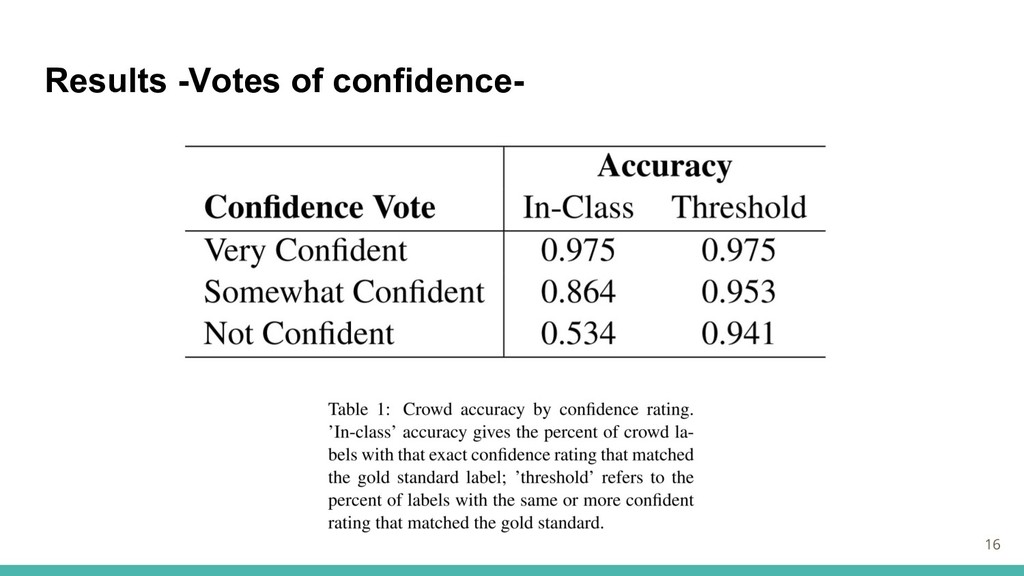
Results -Votes of confidence- 16
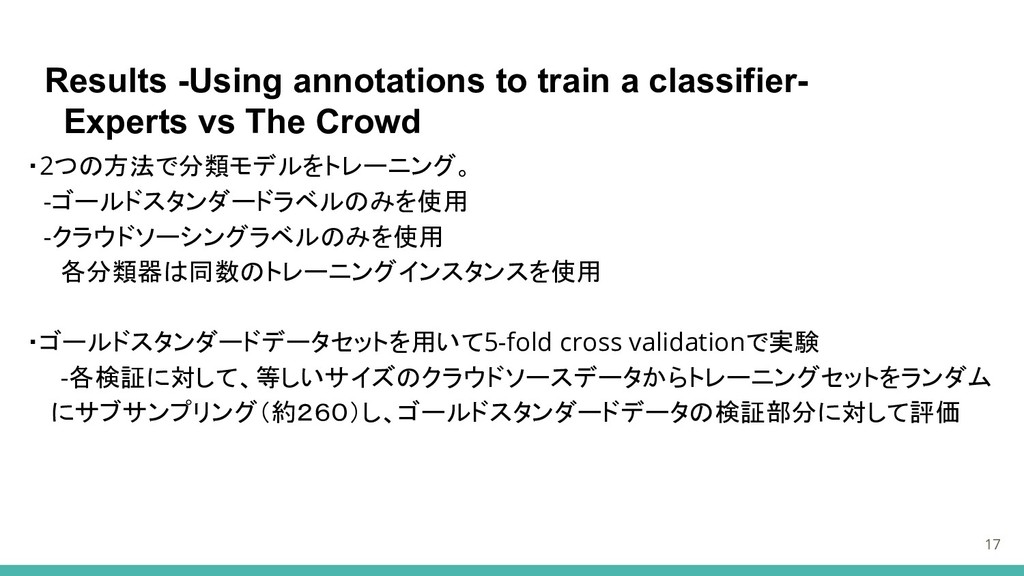
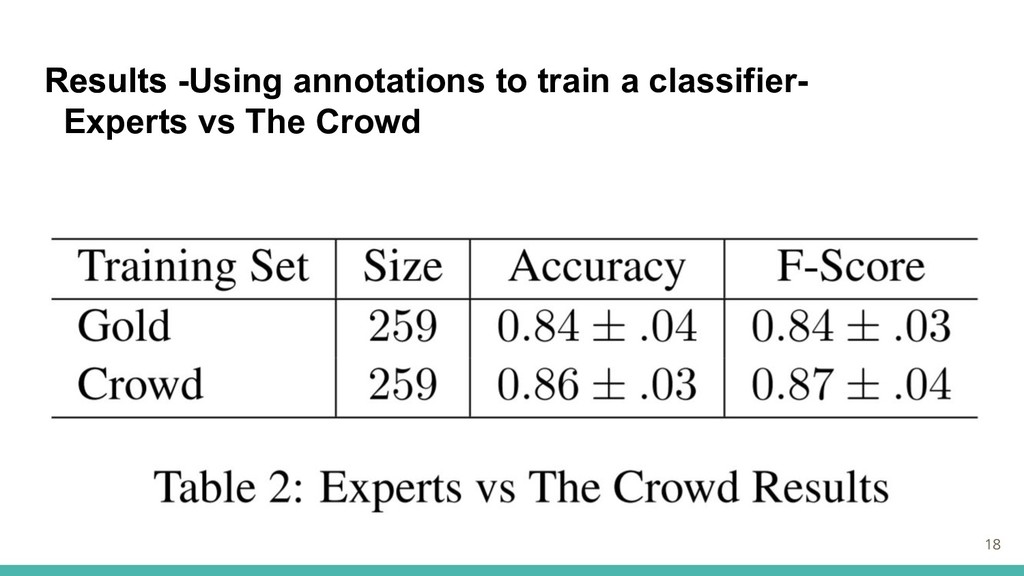
Results -Using annotations to train a classifier- Experts vs The
Crowd ・2つの方法で分類モデルをトレーニング。 -ゴールドスタンダードラベルのみを使用 -クラウドソーシングラベルのみを使用 各分類器は同数のトレーニングインスタンスを使用 ・ゴールドスタンダードデータセットを用いて5-fold cross validationで実験 -各検証に対して、等しいサイズのクラウドソースデータからトレーニングセットをランダム にサブサンプリング(約260)し、ゴールドスタンダードデータの検証部分に対して評価 17
Results 18 Results -Using annotations to train a classifier- Experts
vs The Crowd
Results -Using annotations to train a classifier- Increasing training instances
・クラウドワーカーの注釈の数を増やすことで分類モデルの精度を向上できるか ・各サイズごとに、トレーニングセットをランダムにサブサンプリング ・ゴールドスタンダードデータセット全体に対して評価 19
Results 20 Results -Using annotations to train a classifier- Increasing
training instances
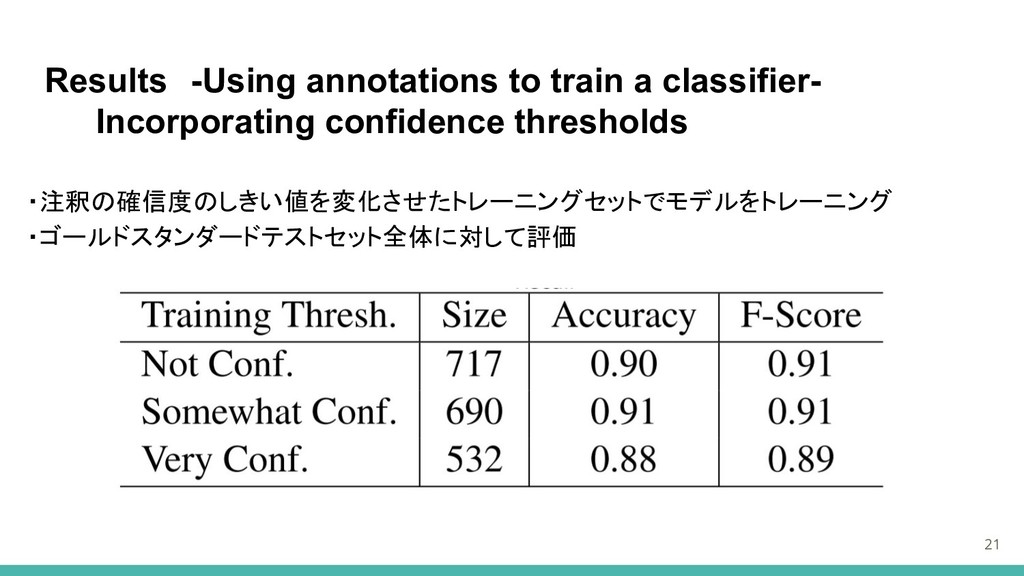
Results -Using annotations to train a classifier- Incorporating confidence thresholds
・注釈の確信度のしきい値を変化させたトレーニングセットでモデルをトレーニング ・ゴールドスタンダードテストセット全体に対して評価 21
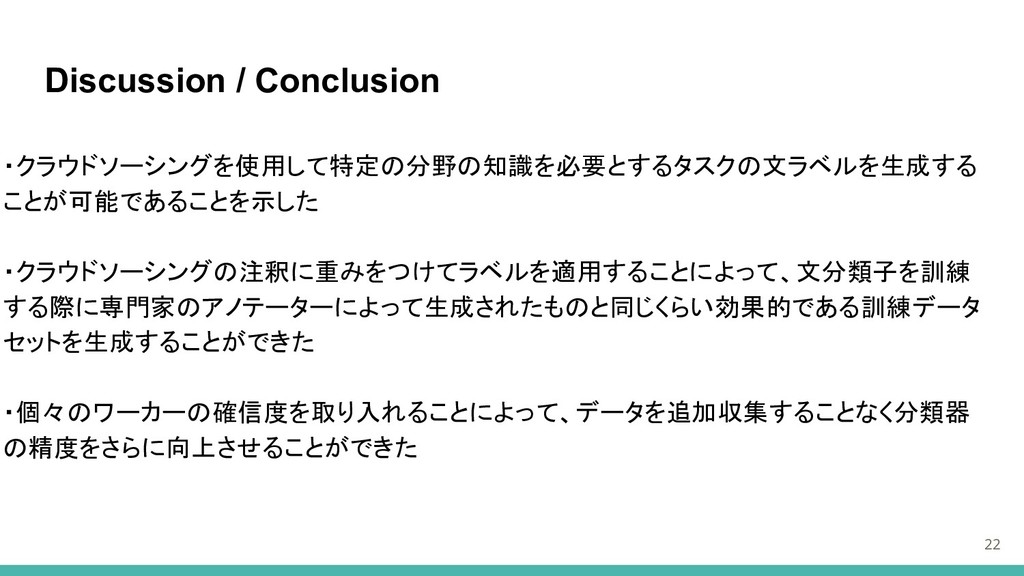
Discussion / Conclusion ・クラウドソーシングを使用して特定の分野の知識を必要とするタスクの文ラベルを生成する ことが可能であることを示した ・クラウドソーシングの注釈に重みをつけてラベルを適用することによって、文分類子を訓練 する際に専門家のアノテーターによって生成されたものと同じくらい効果的である訓練データ セットを生成することができた ・個々のワーカーの確信度を取り入れることによって、データを追加収集することなく分類器 の精度をさらに向上させることができた
22


 tad
 takonda
 mohab1
 akitoshiga
 terapyon
 ishikawa_satoru
 riyaamemiya
 kash1064
 teamlab
 techtekt
 oikon48
 maimyyym
 orderedlist
 baasie
 holman
 csswizardry
 bluesmoon
 jlugia
 cassininazir
 helmedeiros
 eileencodes
 bermonpainter
 greggifford
 rocio