Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
文献紹介_201908_Medical Word Embeddings for Spanish...
Search
T.Tada
August 28, 2019
Technology
73
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
文献紹介_201908_Medical Word Embeddings for Spanish_ Development and Evaluation
T.Tada
August 28, 2019
More Decks by T.Tada
See All by T.Tada
文献紹介_202002_Is artificial data useful for biomedical Natural Language Processing algorithms?
tad
0
77
文献紹介_202001_A Novel System for Extractive Clinical Note Summarization using EHR Data
tad
0
200
文献紹介_201912_Publicly Available Clinical BERT Embeddings
tad
0
180
文献紹介_201911_EDA: Easy Data Augmentation Techniques for Boosting Performance on Text Classification Tasks
tad
0
230
文献紹介_201910_Do Neural NLP Models Know Numbers? Probing Numeracy in Embeddings
tad
0
110
文献紹介_201909_Sentence Mover’s Similarity_ Automatic Evaluation for Multi-Sentence Texts
tad
0
180
文献紹介_201907_Is Word Segmentation Necessary for Deep Learning of Chinese Representations
tad
0
130
文献紹介_201906_Predicting Annotation Difficulty to Improve Task Routing and Model Performance for Biomedical Information Extraction
tad
0
120
文献紹介201905_Context-Aware Cross-Lingual Mapping
tad
0
120
Other Decks in Technology
See All in Technology
freeeにおけるSoftware Factory
freee
PRO
0
320
トークン化預金DCJPYの取り組みと活用ユースケース
finengine
0
230
Browser Spec: Testing Hotwire with Ruby
takahashim
1
160
Claude Code をローカルとサーバー上で利用した際の Bedrock 利用料をユーザー単位で一本化してみる
ohorig
0
110
その Valkey 使いこなしていますか?
onk
PRO
5
1.9k
AWSDirectConnectの構築の進め方を整理してみた
masa_my
1
150
Claude for Google Workspaces ポン出し/claude-for-google-workspace-slide-conversion
emiki
0
320
Tofu-Controller lightning talk @ Containerday 2026
gionn
0
190
OptunaHub: ブラックボックス最適化のためのプラットフォーム
pfn
PRO
0
150
Microsoft のサポート ライフサイクルを理解する
murachiakira
PRO
0
120
sue445's proposals 2026
sue445
0
130
顧客価値を追いかけたら、プライシングにたどり着いた
sansantech
PRO
2
580
Featured
See All Featured
Marketing Yourself as an Engineer | Alaka | Gurzu
gurzu
0
330
No one is an island. Learnings from fostering a developers community.
thoeni
21
3.9k
Pawsitive SEO: Lessons from My Dog (and Many Mistakes) on Thriving as a Consultant in the Age of AI
davidcarrasco
0
260
The State of eCommerce SEO: How to Win in Today's Products SERPs - #SEOweek
aleyda
2
12k
We Have a Design System, Now What?
morganepeng
55
8.4k
[RailsConf 2023 Opening Keynote] The Magic of Rails
eileencodes
31
10k
How To Speak Unicorn (iThemes Webinar)
marktimemedia
1
610
Responsive Adventures: Dirty Tricks From The Dark Corners of Front-End
smashingmag
254
22k
How to Grow Your eCommerce with AI & Automation
katarinadahlin
PRO
2
330
The Pragmatic Product Professional
lauravandoore
37
7.5k
Building Applications with DynamoDB
mza
96
7.2k
Let's Do A Bunch of Simple Stuff to Make Websites Faster
chriscoyier
508
140k
Transcript
- 文献紹介 2019 Aug 28 - Medical Word Embeddings for
Spanish: Development and Evaluation 長岡技術科学大学 自然言語処理研究室 多田太郎
About the paper 2 Authors: Conference: Proceedings of the 2nd
Clinical Natural Language Processing Workshop (NAACLのワークショップ)
Abstract ・医療および臨床NLPでは、単語分散表現がNERや分類など有効なリソース ・スペイン語での医療ドメインの単語埋め込みについて学習・評価 ・生物医学ドメインのスペイン語での単語埋め込みの作成と評価にほとんど注意が払わ れていない ・英語のデータ・セットをスペイン語で活用 3
Material and Methods 4 ・分散表現手法:FastText ・学習コーパス: 1. SciELOデータベース(論文の本文とアブストラクト、スペイン語の地域は不問) 2. Wikipedia(健康、薬理学、薬局、医学、生物学のカテゴリー)
Evaluation -Intrinsic- 5 ・生物医学分野で利用できる標準的なスペイン語のデータセットはない ・学習した埋め込みの評価のため、英語のデータ・セットをスペイン語に適用 使用するデータ・セット: UMNSRSの類似性(UMNSRS-sim)および関連性(UMNSRS-rel)タスク 統合医学言語システム(UMLS)のコンセプトペアで構成されるデータセット(英語) 類似性と関連性について人手で注釈が付けられている UMNSRSsim:566ペア、UMNSRS-rel:587ペアのコンセプト
MayoSRS: 類似性評価に使用 101個のUMLSペアとそれぞれの人手でつけたスコアで構成
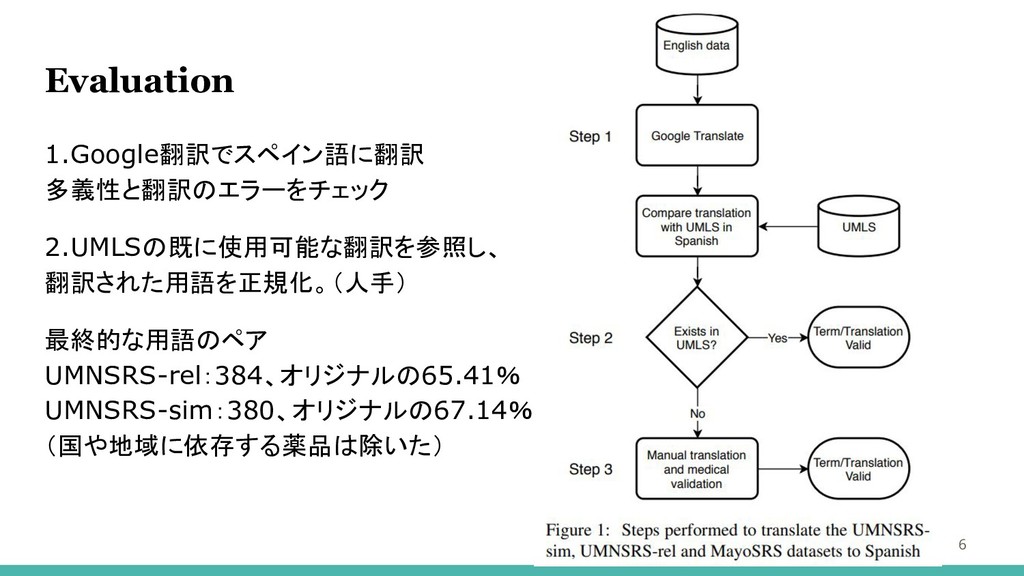
Evaluation 6 1.Google翻訳でスペイン語に翻訳 多義性と翻訳のエラーをチェック 2.UMLSの既に使用可能な翻訳を参照し、 翻訳された用語を正規化。(人手) 最終的な用語のペア UMNSRS-rel:384、オリジナルの65.41% UMNSRS-sim:380、オリジナルの67.14% (国や地域に依存する薬品は除いた)
Evaluation 7 Baseline Word Embedding: チリ大学NLPグループ(DCC Uchile)から入手可能な埋め込みを使用 学習データ:SBWC(Spanish Billion Word
Corpus) コーパスサイズ: 約1.4 億語 一般ドメイン 学習方法は本論文の学習モデルと同様
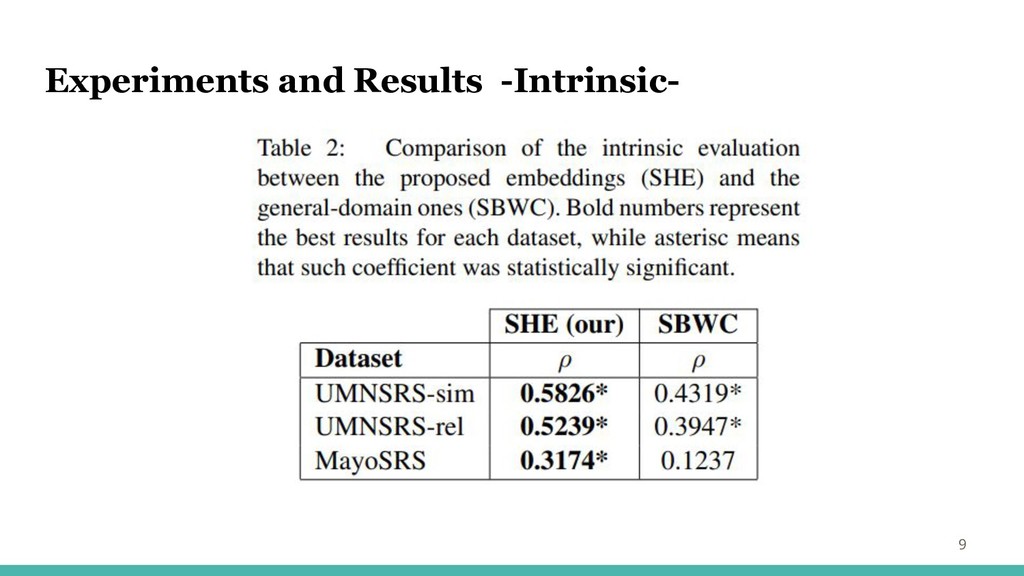
Experiments and Results -Intrinsic- 8 ・翻訳された各ペアが学習したモデルの語彙に存在するかチェック →公平な比較のため ・複数単語による用語については、個々の単語ベクトルの平均を使用 ・各翻訳済みデータセットの比較ペアの最終数:
UMNSRS-sim(322)、UMNSRSrel(252)、MayoSRS(101) ・各ペアのコサイン距離を計算、人手のアノテーションとのピアソン相関係数(ρ)
9 Experiments and Results -Intrinsic-
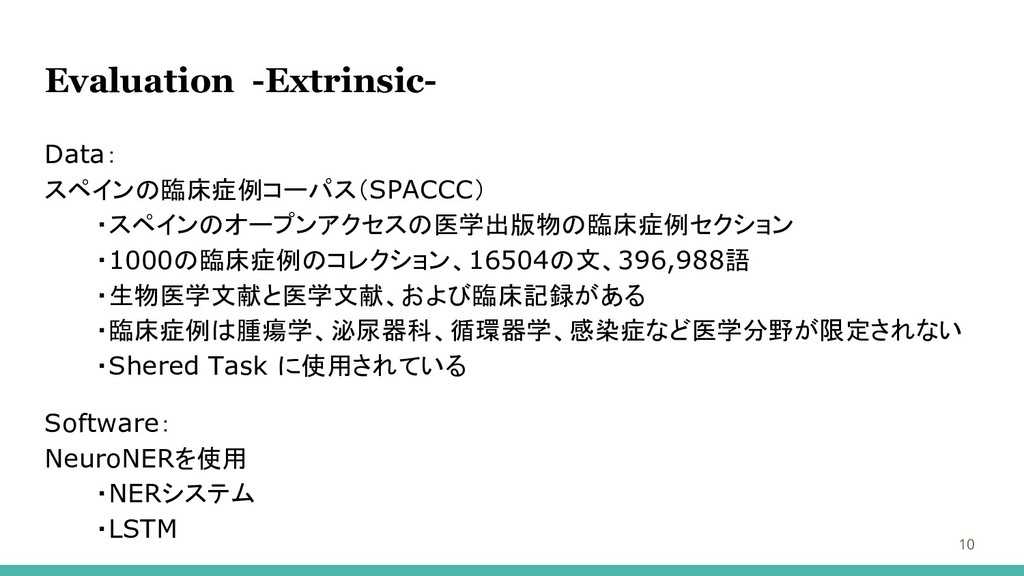
Evaluation -Extrinsic- 10 Data: スペインの臨床症例コーパス(SPACCC) ・スペインのオープンアクセスの医学出版物の臨床症例セクション ・1000の臨床症例のコレクション、16504の文、396,988語 ・生物医学文献と医学文献、および臨床記録がある ・臨床症例は腫瘍学、泌尿器科、循環器学、感染症など医学分野が限定されない ・Shered
Task に使用されている Software: NeuroNERを使用 ・NERシステム ・LSTM
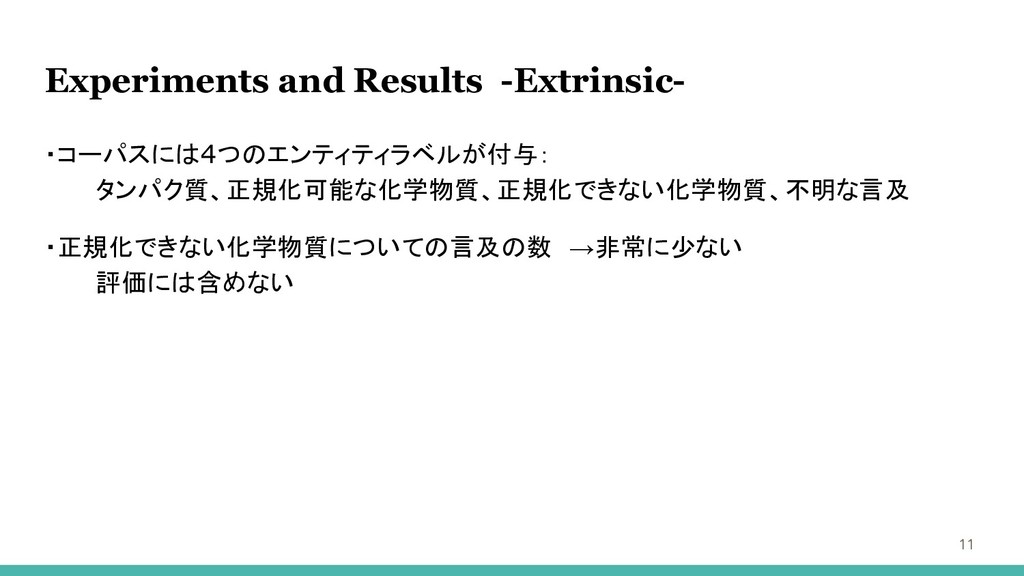
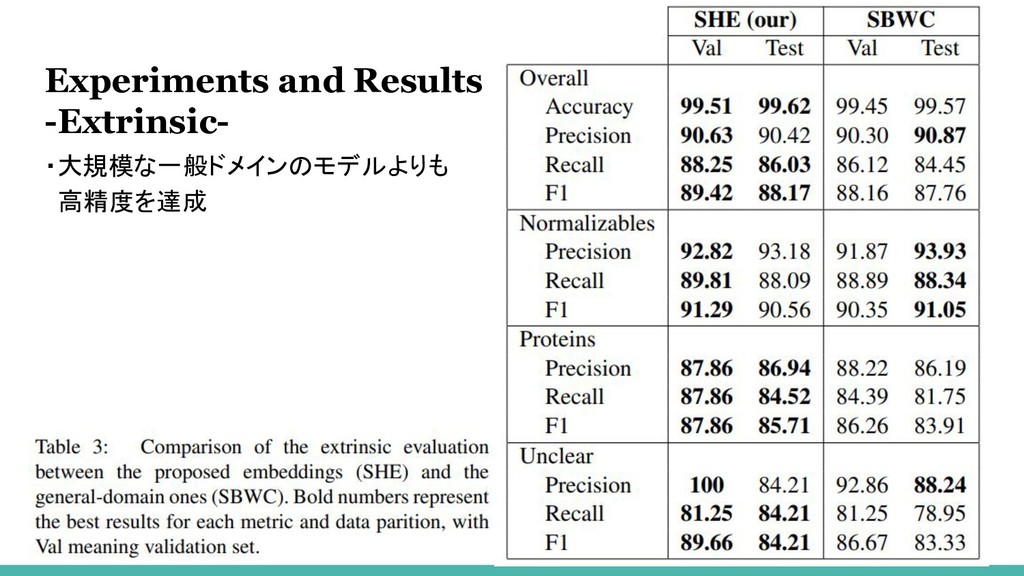
Experiments and Results -Extrinsic- 11 ・コーパスには4つのエンティティラベルが付与: タンパク質、正規化可能な化学物質、正規化できない化学物質、不明な言及 ・正規化できない化学物質についての言及の数 →非常に少ない 評価には含めない
12 ・大規模な一般ドメインのモデルよりも 高精度を達成 Experiments and Results -Extrinsic-
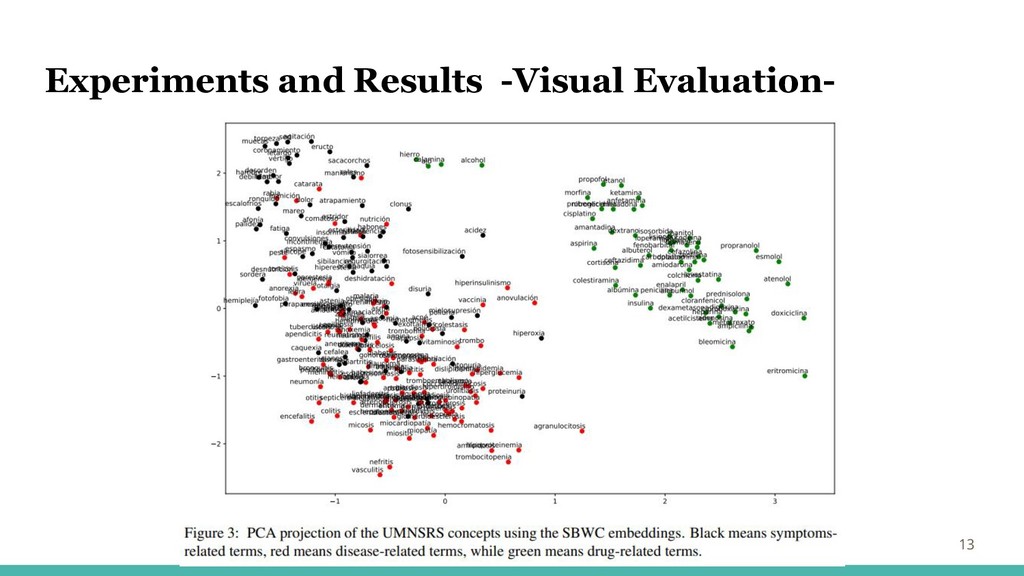
Experiments and Results -Visual Evaluation- 13
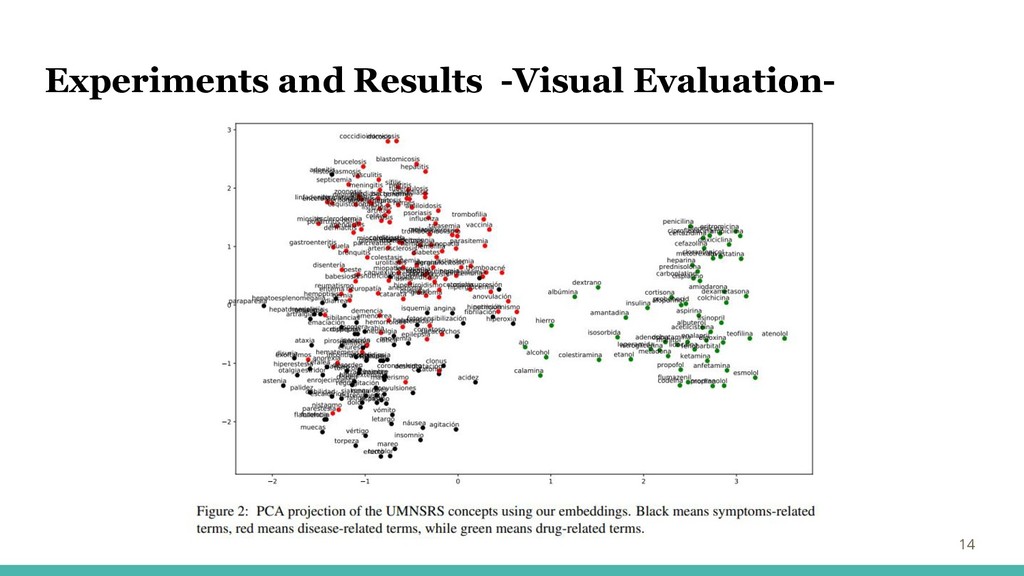
Experiments and Results -Visual Evaluation- 14
Discussion and Conclusion 15 ・スペイン語の生物医学ドメインの単語埋め込みについて学習・評価 ・本論文の埋め込みは、一般ドメインの大規模コーパスよりも優れた性能を達成 ・ドメイン内コーパスでトレーニングされたものがより明確に単語のマッピングできる ・スペイン語の医療ドメインの学習済みモデルを公開 ・英語のデータ・セットをスペイン語で活用


 tad
 freee
 finengine
 takahashim
 ohorig
 onk
 masa_my
 emiki
 gionn
 pfn
 murachiakira
 sue445
 sansantech
 gurzu
 thoeni
 davidcarrasco
 aleyda
 morganepeng
 eileencodes
 marktimemedia
 smashingmag
 katarinadahlin
 lauravandoore
 mza
 chriscoyier