Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
文献紹介_201911_EDA: Easy Data Augmentation Techniq...
Search
T.Tada
November 28, 2019
Technology
230
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
文献紹介_201911_EDA: Easy Data Augmentation Techniques for Boosting Performance on Text Classification Tasks
T.Tada
November 28, 2019
More Decks by T.Tada
See All by T.Tada
文献紹介_202002_Is artificial data useful for biomedical Natural Language Processing algorithms?
tad
0
77
文献紹介_202001_A Novel System for Extractive Clinical Note Summarization using EHR Data
tad
0
200
文献紹介_201912_Publicly Available Clinical BERT Embeddings
tad
0
180
文献紹介_201910_Do Neural NLP Models Know Numbers? Probing Numeracy in Embeddings
tad
0
110
文献紹介_201909_Sentence Mover’s Similarity_ Automatic Evaluation for Multi-Sentence Texts
tad
0
180
文献紹介_201908_Medical Word Embeddings for Spanish_ Development and Evaluation
tad
0
73
文献紹介_201907_Is Word Segmentation Necessary for Deep Learning of Chinese Representations
tad
0
130
文献紹介_201906_Predicting Annotation Difficulty to Improve Task Routing and Model Performance for Biomedical Information Extraction
tad
0
120
文献紹介201905_Context-Aware Cross-Lingual Mapping
tad
0
120
Other Decks in Technology
See All in Technology
DBについての基礎説明(MySQL編) - コロプラ 2026年度 新卒研修
colopl
0
160
AWSDirectConnectの構築の進め方を整理してみた
masa_my
1
150
AI × アーキテクト 第1・2章|生成AIの課題とアーキテクトの素養
daidaidai
1
230
Steerable Visual Representations
sansantech
PRO
0
190
Metadata - Section 2: Simple Metadata & Meta Tags
mohab1
0
120
macOS Golden Gate 時代のMac管理
tategami
0
130
Temporal 最高!でも改めて「日付」について調べたら人類の負債すぎる件
riyaamemiya
0
220
「Learning Outcome」を書きたくない私が、Learning Outcomeと折り合いをつけるまで
mhlyc
0
130
Conditional PED-ANOVA: Hyperparameter Importance in Hierarchical & Dynamic Search Spaces
pfn
PRO
0
150
Classmethod Company Deck
satoshi7
1
820
『SAR衛星データ解析入門』の ご紹介とその応用
syuchimu
0
140
[JAWS-UG彩の国埼玉#12]そろそろ準備する?re:Invent2026をやさしく解説 / reinvent2026-sainokuni
sh_fk2
1
400
Featured
See All Featured
The Art of Programming - Codeland 2020
erikaheidi
57
14k
Game over? The fight for quality and originality in the time of robots
wayneb77
1
310
Design in an AI World
tapps
1
360
Rails Girls Zürich Keynote
gr2m
96
14k
Leo the Paperboy
mayatellez
10
2.4k
Money Talks: Using Revenue to Get Sh*t Done
nikkihalliwell
0
530
The AI Revolution Will Not Be Monopolized: How open-source beats economies of scale, even for LLMs
inesmontani
PRO
3
3.8k
Practical Orchestrator
shlominoach
192
12k
Navigating the Design Leadership Dip - Product Design Week Design Leaders+ Conference 2024
apolaine
2
480
Facilitating Awesome Meetings
lara
57
7.2k
From π to Pie charts
rasagy
1
410
How to audit for AI Accessibility on your Front & Back End
davetheseo
0
610
Transcript
- 文献紹介 2019 Nov. 28 - EDA: Easy Data Augmentation
Techniques for Boosting Performance on Text Classification Tasks 長岡技術科学大学 自然言語処理研究室 多田太郎
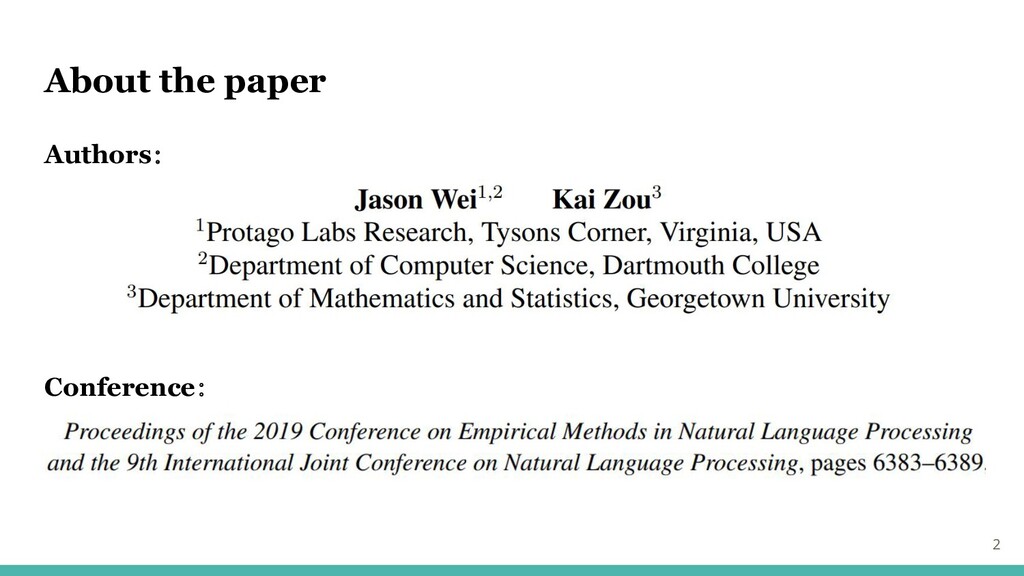
About the paper 2 Authors: Conference:
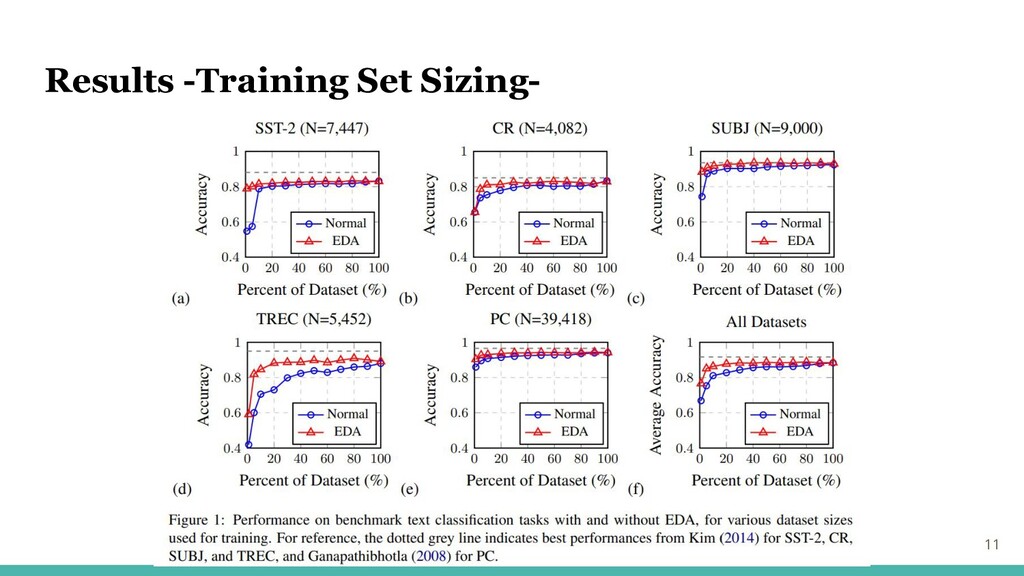
Abstract ・EDA: Easy Data Augmentation を提案 ・文に4種類の編集を行ないデータを拡張 ・ローリソース(データセットが小規模)なタスクに対して強力 ・トレーニングセット100%使用時の精度を50%のデータ+EDAで達成 3
Introduction ・テキスト分類の精度は、トレーニングデータのサイズと質に依存している ・データの拡張により、より堅牢なモデルを得られる ・折り返し翻訳、ノイズを加える、言語モデルを使った同義語置換などがある →有効だがコストが高い ・シンプルかつ言語を問わないデータ拡張を提案 4
EDA 5 トレーニングデータの特定の文に以下4つのいずれかの操作をランダムに実施 ・Synonym Replacement (SR): 文からn単語(ストップワードでない)をランダムで選択 各単語をランダムに選ばれた同義語と置き換え ・Random Insertion
(RI): 文中のランダムな単語(ストップワードでない)のランダムな同義語を取得 文のランダムな位置に挿入 この作業をn回行なう これは先行研究でやってる
EDA 6 トレーニングデータの特定の文に以下4つのいずれかの操作をランダムに実施 ・Random Swap (RS): 文からランダムに2単語を選択し入れ替え この作業をn回行なう ・Random Deletion
(RD): 確率pで文の各単語を削除(pの値は後述)
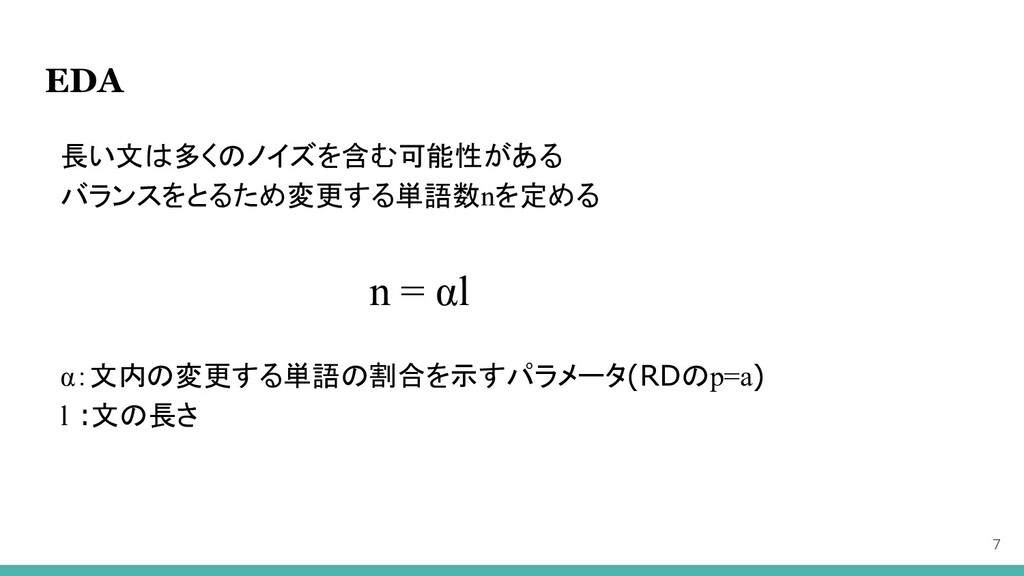
EDA 7 長い文は多くのノイズを含む可能性がある バランスをとるため変更する単語数nを定める α:文内の変更する単語の割合を示すパラメータ(RDのp=a) l :文の長さ n = αl
EDA 8
Experimental Setup 9 5つのテキスト分類のベンチマークタスクで実験 EDAは小規模なデータセットでより役立つと想定される →トレーニングデータの量を変更し実験(LSTMとCNNを使用)
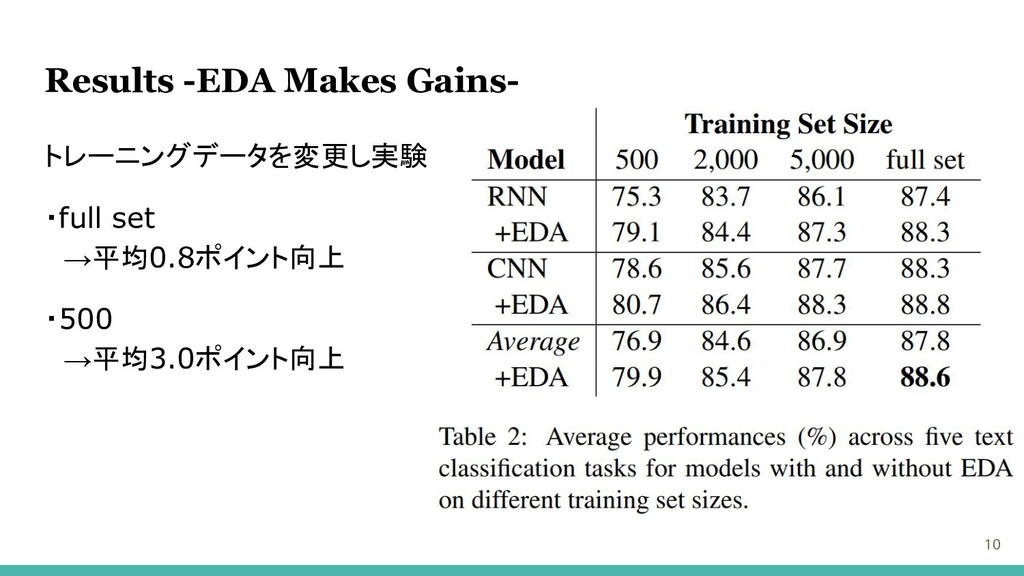
Results -EDA Makes Gains- 10 トレーニングデータを変更し実験 ・full set →平均0.8ポイント向上 ・500
→平均3.0ポイント向上
Results -Training Set Sizing- 11
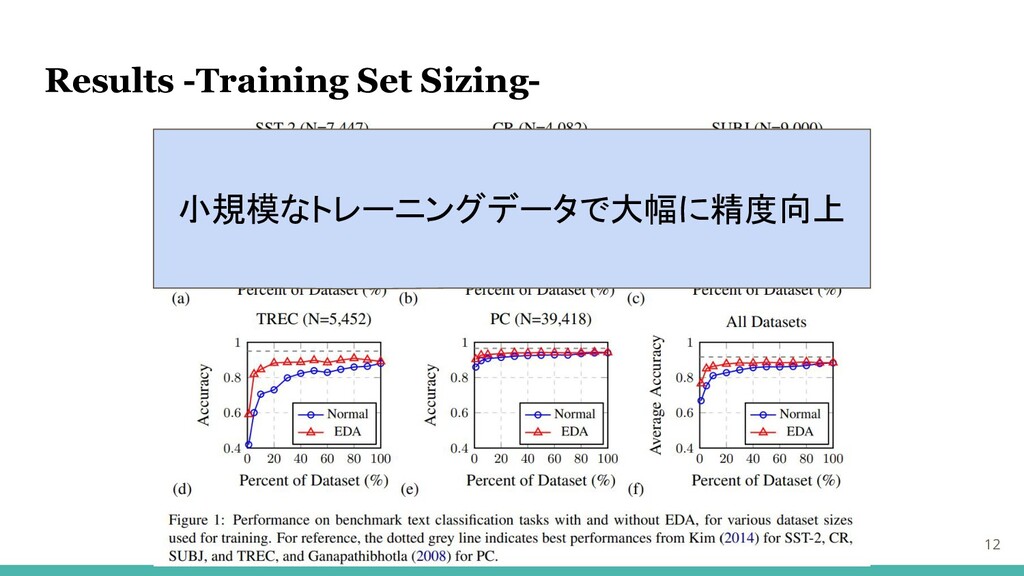
Results -Training Set Sizing- 12 小規模なトレーニングデータで大幅に精度向上
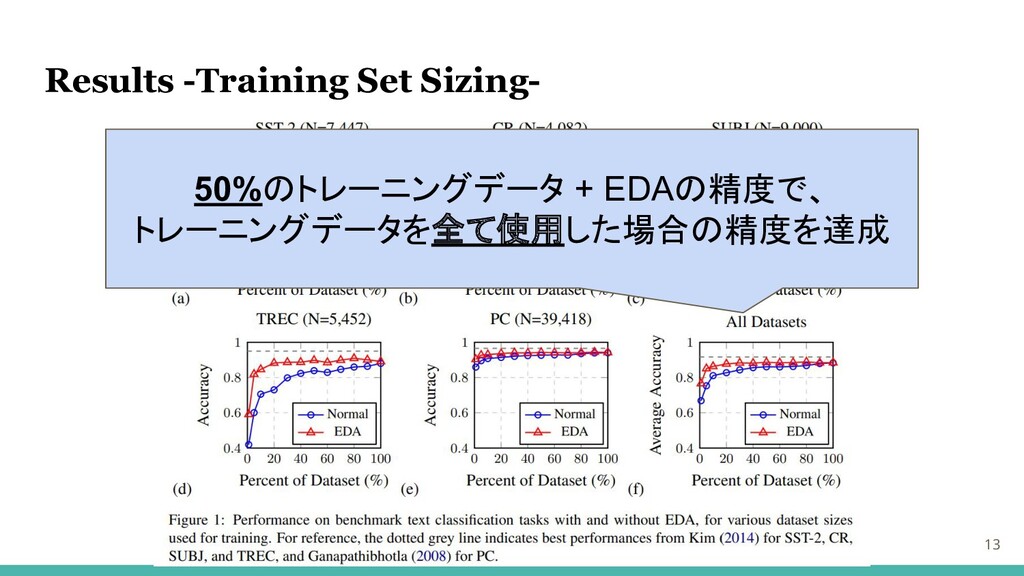
Results -Training Set Sizing- 13 50%のトレーニングデータ + EDAの精度で、 トレーニングデータを全て使用した場合の精度を達成
Results -Does EDA conserve true labels?- 14 操作をして拡張した文の分類クラスは変わらない? ・データの拡張をしない状態のPCタスク(2値)でLSTMをトレーニング ・EDAでテストデータの各文に対し、9つ拡張文を生成し実験
Results -Does EDA conserve true labels?- 15 ほとんど場合で拡張された文が元のラベルと同じ
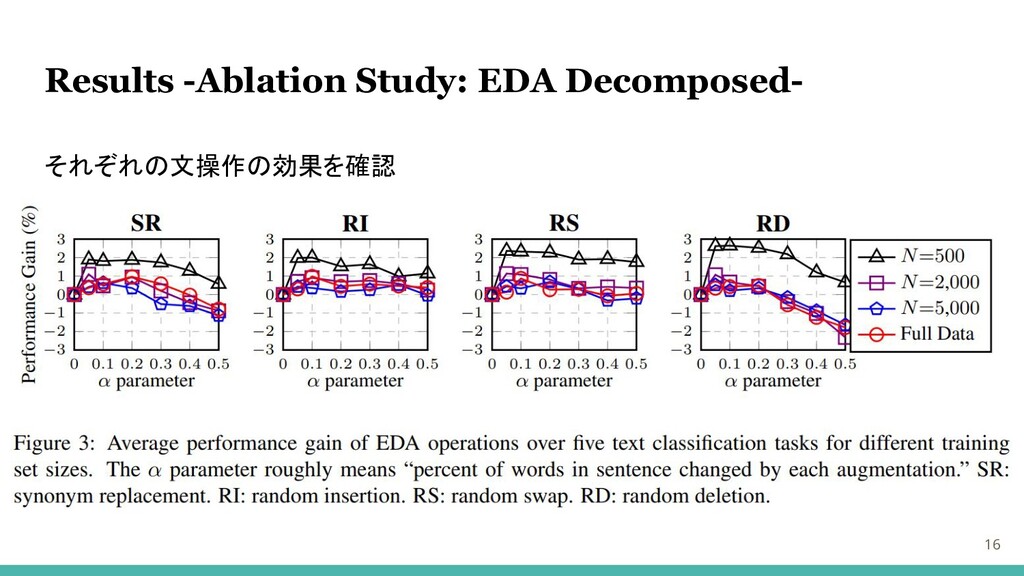
Results -Ablation Study: EDA Decomposed- 16 それぞれの文操作の効果を確認
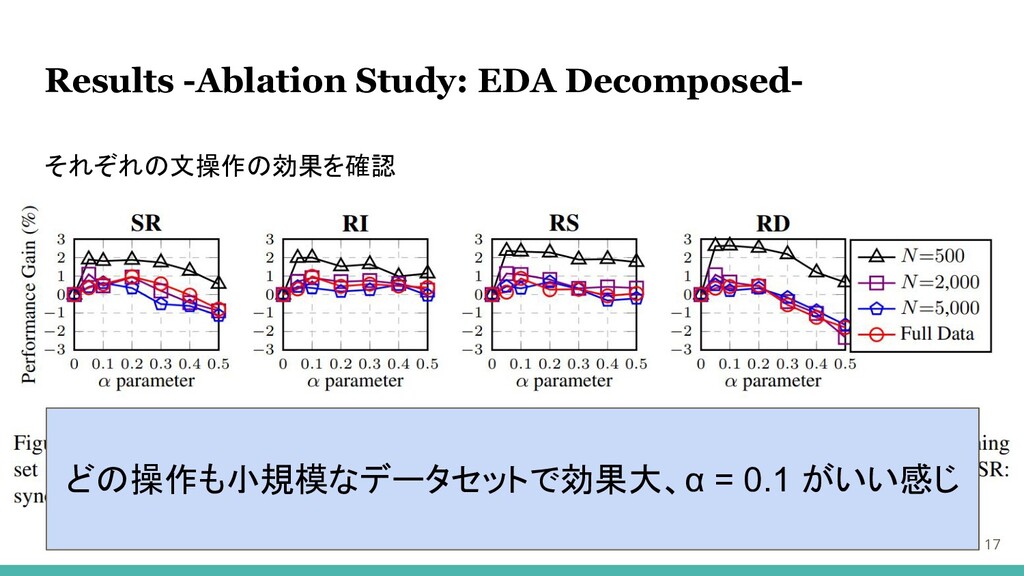
Results -Ablation Study: EDA Decomposed- 17 それぞれの文操作の効果を確認 どの操作も小規模なデータセットで効果大、α = 0.1
がいい感じ
Results -How much augmentation?- 18 どのくらい文を増やすべきか
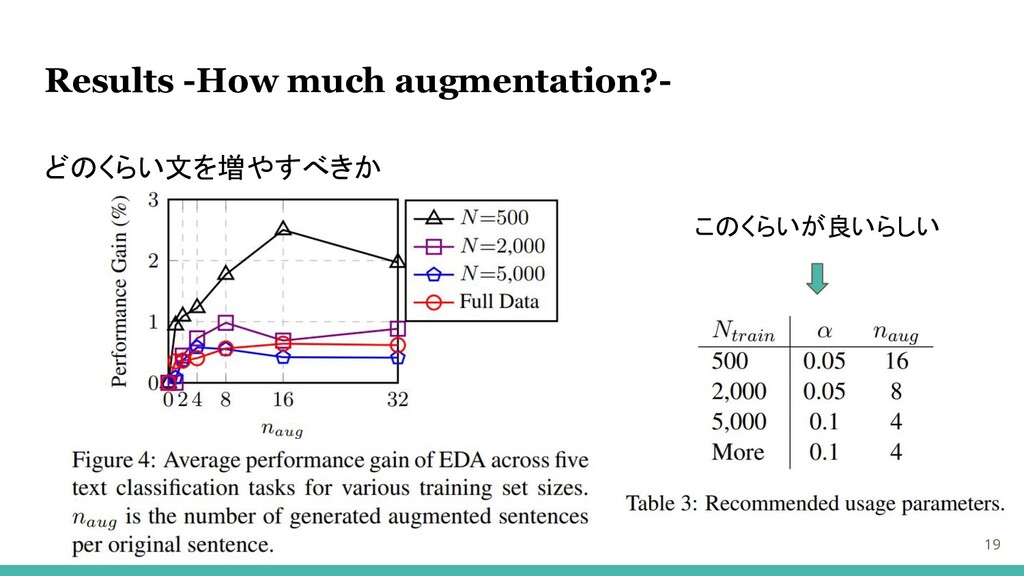
Results -How much augmentation?- 19 どのくらい文を増やすべきか このくらいが良いらしい
Comparison with Related Work 20 EDAは言語モデルも外部データも必要としない
Discussion and Limitations 21 EDAの限界 ・データの量が十分な場合に精度の向上はわずか ・pre-train モデルを使用する場合、大幅な貢献はもたらさない しかし、NNモデルを大きく複雑にしていく高コストな手法は避けたい
Conclusions 22 ・シンプルかつ低コストなデータ拡張手法を提案 ・5つの分類タスクで精度向上 ・小規模なトレーニングセットでは精度の貢献も大きく、過学習を避けられる


 tad
 colopl
 masa_my
 daidaidai
 sansantech
 mohab1
 tategami
 riyaamemiya
 mhlyc
 pfn
 satoshi7
 syuchimu
 sh_fk2
 erikaheidi
 wayneb77
 tapps
 gr2m
 mayatellez
 nikkihalliwell
 inesmontani
 shlominoach
 apolaine
 lara
 rasagy
 davetheseo