Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
文献紹介_202001_A Novel System for Extractive Clini...
Search
T.Tada
January 20, 2020
Technology
200
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
文献紹介_202001_A Novel System for Extractive Clinical Note Summarization using EHR Data
T.Tada
January 20, 2020
More Decks by T.Tada
See All by T.Tada
文献紹介_202002_Is artificial data useful for biomedical Natural Language Processing algorithms?
tad
0
77
文献紹介_201912_Publicly Available Clinical BERT Embeddings
tad
0
180
文献紹介_201911_EDA: Easy Data Augmentation Techniques for Boosting Performance on Text Classification Tasks
tad
0
230
文献紹介_201910_Do Neural NLP Models Know Numbers? Probing Numeracy in Embeddings
tad
0
110
文献紹介_201909_Sentence Mover’s Similarity_ Automatic Evaluation for Multi-Sentence Texts
tad
0
180
文献紹介_201908_Medical Word Embeddings for Spanish_ Development and Evaluation
tad
0
73
文献紹介_201907_Is Word Segmentation Necessary for Deep Learning of Chinese Representations
tad
0
130
文献紹介_201906_Predicting Annotation Difficulty to Improve Task Routing and Model Performance for Biomedical Information Extraction
tad
0
120
文献紹介201905_Context-Aware Cross-Lingual Mapping
tad
0
110
Other Decks in Technology
See All in Technology
スキルを作る、その前に!複数人で使われるスキルを 作るためのプロセス
junkifurukawa
2
370
Snapshot Testing in Practice: Predictable and Reliable SwiftUI Views
fespinoza
0
160
Loop Engineering これくらいでいい
mikanichinose
0
130
ブラウザとサーバーから考えるAI時代のフロントエンド監視
shogo4131
2
600
V8のArray.prototype.flatを最大約20倍速くするまでと、巨大OSSへの大規模コミットの道のり
riyaamemiya
0
110
Cognition AI Japan - ウェビナー2_テストQA_運用監視
cogakira
0
110
freeeらしさをAIとともに作る / Creating the freee Experience with AI
ymrl
0
220
20260930_Gemma4_Hands-on
tsho
0
240
メルペイ 会計システム概要と歴史
mewuto
0
200
1万名の社員が使う認証基盤で どう信頼性を担保するか?
kairim0
0
220
オンラインゲームのシステム全体像 - コロプラ 2026年度 新卒研修
colopl
0
1k
AI時代のPRレビューにどう向き合うか?
kairim0
1
110
Featured
See All Featured
GraphQLとの向き合い方2022年版
quramy
50
15k
Amusing Abliteration
ianozsvald
1
330
Exploring the relationship between traditional SERPs and Gen AI search
raygrieselhuber
PRO
4
4.3k
Put a Button on it: Removing Barriers to Going Fast.
kastner
60
4.6k
DevOps and Value Stream Thinking: Enabling flow, efficiency and business value
helenjbeal
2
400
A Tale of Four Properties
chriscoyier
163
24k
Leading Effective Engineering Teams in the AI Era
addyosmani
9
2.7k
How to Build an AI Search Optimization Roadmap - Criteria and Steps to Take #SEOIRL
aleyda
1
2.2k
Improving Core Web Vitals using Speculation Rules API
sergeychernyshev
21
1.7k
The Art of Programming - Codeland 2020
erikaheidi
57
14k
Distributed Sagas: A Protocol for Coordinating Microservices
caitiem20
333
23k
Applied NLP in the Age of Generative AI
inesmontani
PRO
4
2.5k
Transcript
- 文献紹介 2020 Jan. 20 - A Novel System for
Extractive Clinical Note Summarization using EHR Data 長岡技術科学大学 自然言語処理研究室 多田太郎
About the paper 2 Authors: Conference: Proceedings of the
2nd Clinical NLP 2019
・電子健康記録(EHR)内の患者のケアと管理に関する情報は埋もれている ▷医師が通常のワークフロー中にレビューすることは難しい ・臨床記録に関する疾患固有の抽出型要約タスクに取り組む ▷主に医師や看護師による記録に焦点を当てる ・EHR固有の特徴量を追加することでシステム全体のパフォーマンスが向上 3 Abstract
・EHRは、患者の健康情報の長期的な記録 ・構造化された(バイタルなど)情報 ・構造化されていない(退院サマリなど)情報 で構成される ・EHRへの移行により、意図せず記録が増大 ▷テンプレートやコピーペーストなどにより、不必要または冗長なデータが ・EHR内の重要な情報はユーザー(医師など)によって異なる 4 Introduction
・最終的な目標は医師が作成した要約に近い要約の出力 ・患者の高血圧または糖尿病に関する重要な情報に焦点を当て要約 ▷抽出型要約に取り組む ・言語資源が少ない 5 Introduction
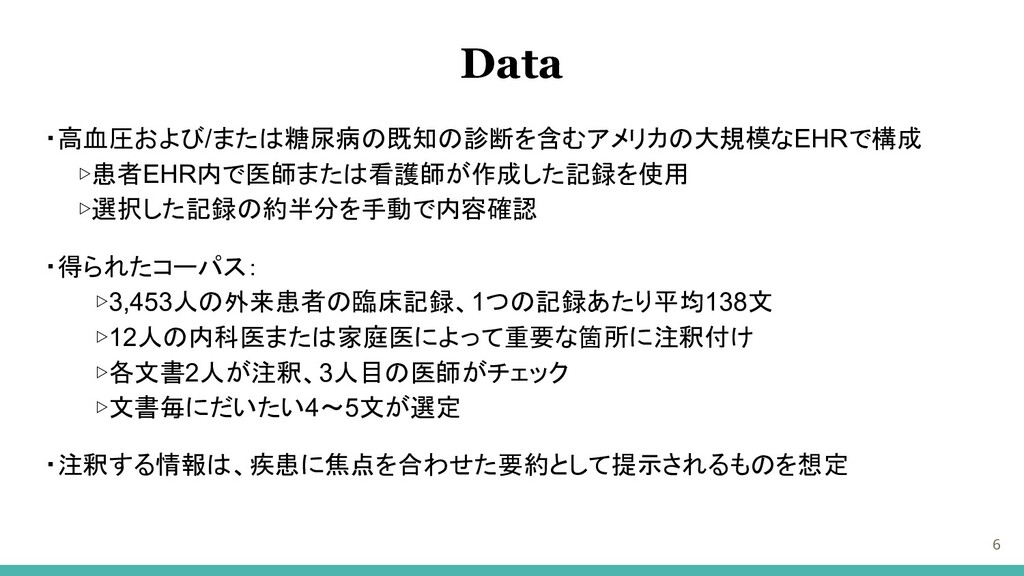
・高血圧および/または糖尿病の既知の診断を含むアメリカの大規模なEHRで構成 ▷患者EHR内で医師または看護師が作成した記録を使用 ▷選択した記録の約半分を手動で内容確認 ・得られたコーパス: ▷3,453人の外来患者の臨床記録、1つの記録あたり平均138文 ▷12人の内科医または家庭医によって重要な箇所に注釈付け ▷各文書2人が注釈、3人目の医師がチェック ▷文書毎にだいたい4〜5文が選定 ・注釈する情報は、疾患に焦点を合わせた要約として提示されるものを想定 6
Data
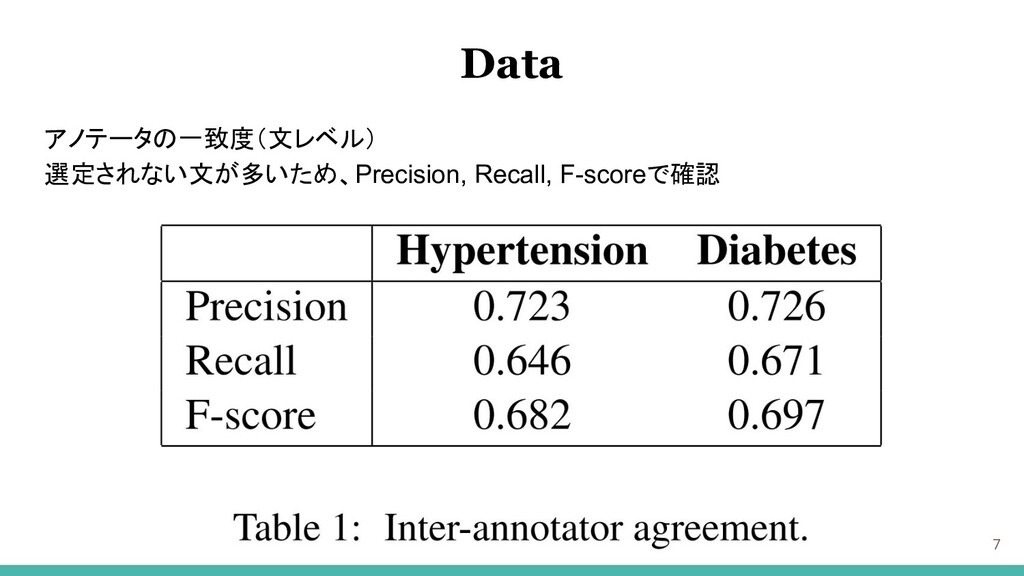
アノテータの一致度(文レベル) 選定されない文が多いため、Precision, Recall, F-scoreで確認 7 Data
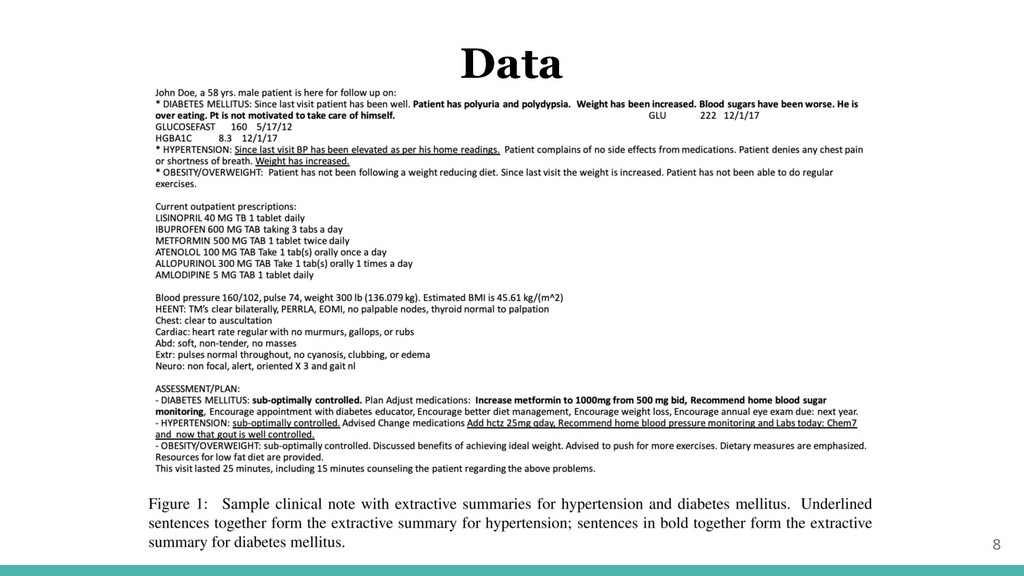
8 Data
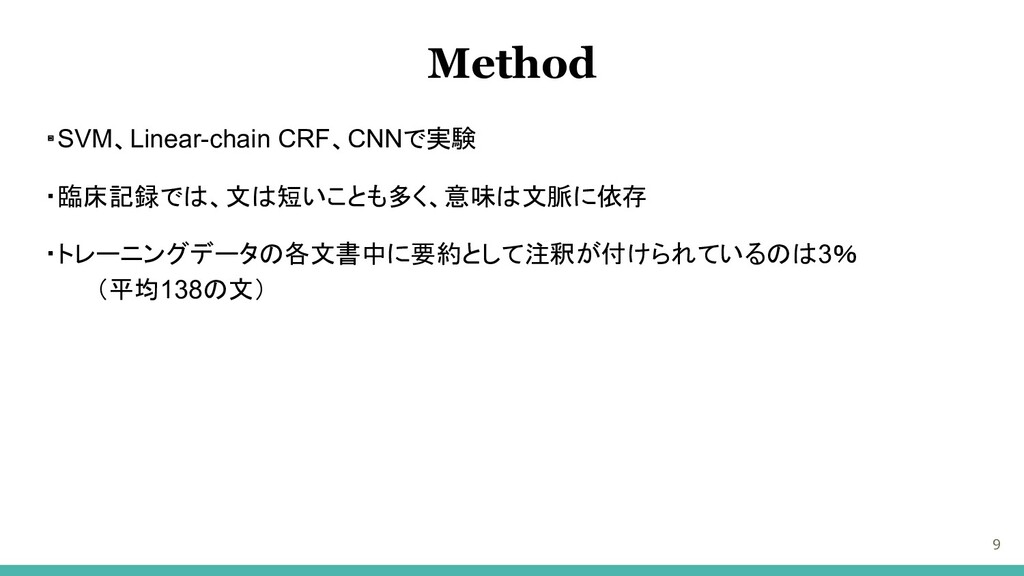
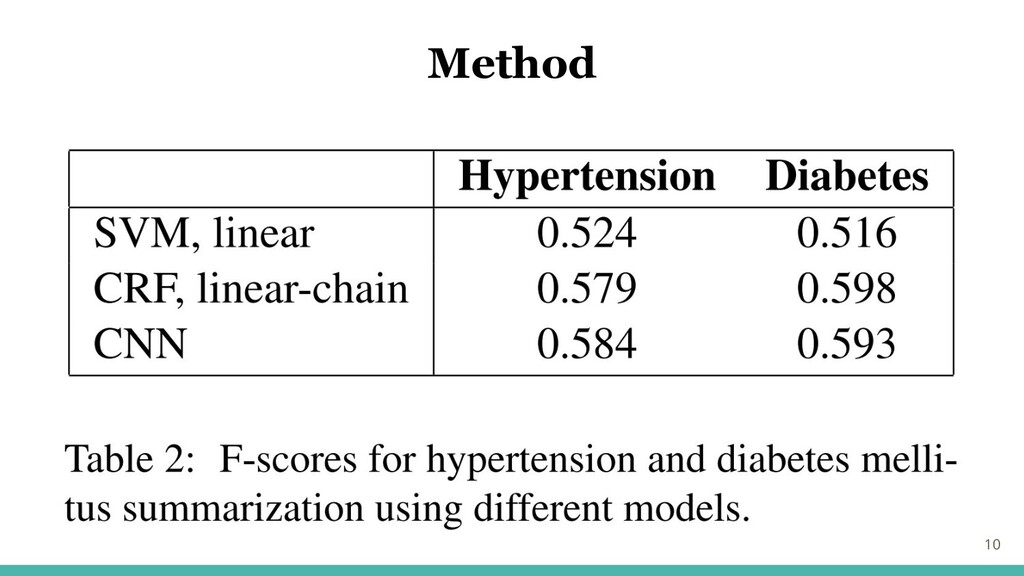
・SVM、Linear-chain CRF、CNNで実験 ・臨床記録では、文は短いことも多く、意味は文脈に依存 ・トレーニングデータの各文書中に要約として注釈が付けられているのは3% (平均138の文) 9 Method
10 Method
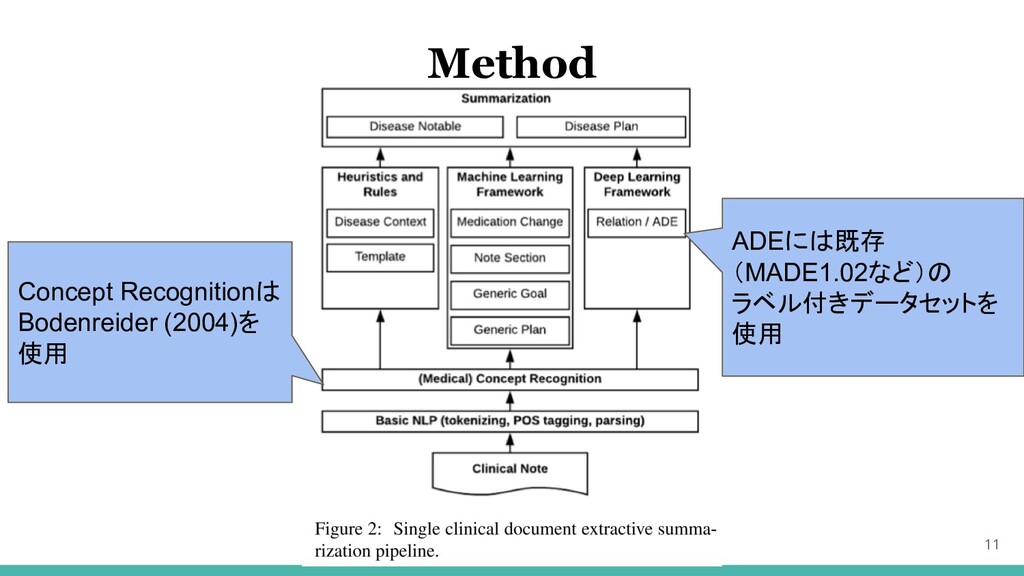
11 Method Concept Recognitionは Bodenreider (2004)を 使用 ADEには既存 (MADE1.02など)の ラベル付きデータセットを
使用
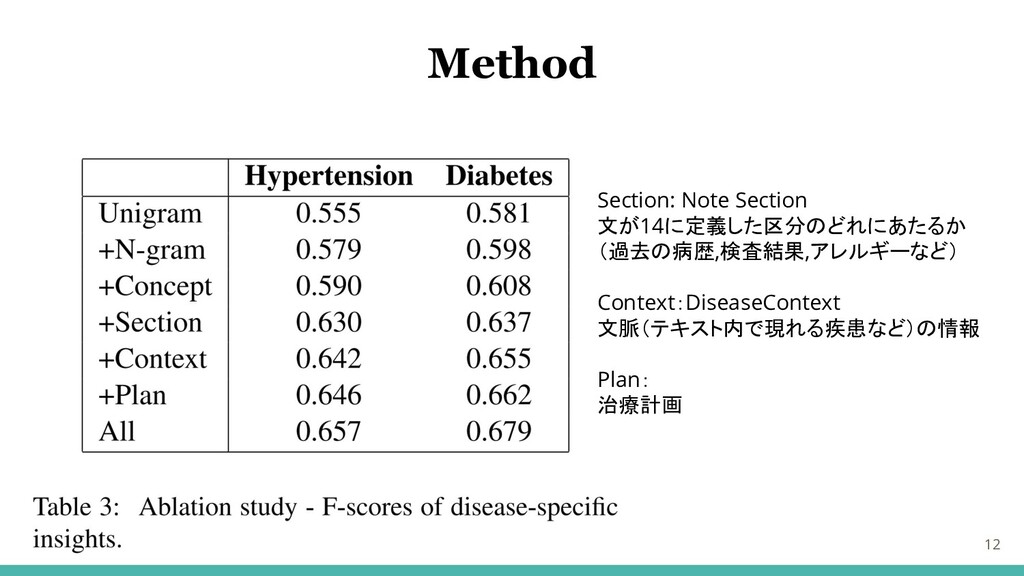
12 Section: Note Section 文が14に定義した区分のどれにあたるか (過去の病歴,検査結果,アレルギーなど) Context:DiseaseContext 文脈(テキスト内で現れる疾患など)の情報 Plan: 治療計画
Method
1.Reasons for Annotator Differences 2.Addressing Issues of Data Scarcity 3.Limitations
in Evaluation 13 Discussion
1.Reasons for Annotator Differences ・参照要約には主観的な要素が残る ・医師2人の注釈でも、何を要約に必要な情報とするかが別れる ・これは、タスクの固有の性質であり、システムで使用する一貫した参照文が必要 ▷3人目の医師の重要性を示している 14 Discussion
2.Addressing Issues of Data Scarcity ・薬物に関する事象(ADE)には既存(MADE1.02など)のラベル付きデータセットを使用 ・既存のデータ・セットも活用することが重要 15 Discussion
3.Limitations in Evaluation ・今回は臨床要約に含めるべきかどうかの微妙な違いを完全には把握していない ・例:薬物に関連する事象(ADE) ▷患者の安全性に大きな影響を与える、重要な情報 ▷患者のケアを管理する際に必要となる、まれなイベント ▷文の重要性は文書の外の知識に依存 ▷他のドメインからの一般的な要約アルゴリズムがすぐに機能しない理由のひとつ 16
Discussion
・臨床記録からの抽出型要約のための自動化システムを提案 ・臨床記録を対象としたパイプラインについて説明 ・豊富なラベル付きデータセットが利用可能になるまでは有用 17 Conclusion


 tad
 junkifurukawa
 fespinoza
 mikanichinose
 shogo4131
 riyaamemiya
 cogakira
 ymrl
 tsho
 mewuto
 kairim0
 colopl
 quramy
 ianozsvald
 raygrieselhuber
 kastner
 helenjbeal
 chriscoyier
 addyosmani
 aleyda
 sergeychernyshev
 erikaheidi
 caitiem20
 inesmontani