Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
[ACL 2026 Demo] Fast-MIA: Efficient and Scalabl...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Shotaro Ishihara
May 12, 2026
Research
160
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
[ACL 2026 Demo] Fast-MIA: Efficient and Scalable Membership Inference for LLMs
https://aclanthology.org/2026.acl-demo.9/
https://github.com/Nikkei/fast-mia
Shotaro Ishihara
May 12, 2026
Transcript
9 slides
Hiromu Takahashi and Shotaro Ishihara ACL 2026 System Demonstrations Fast-MIA:
Efficient and Scalable Membership Inference for LLMs
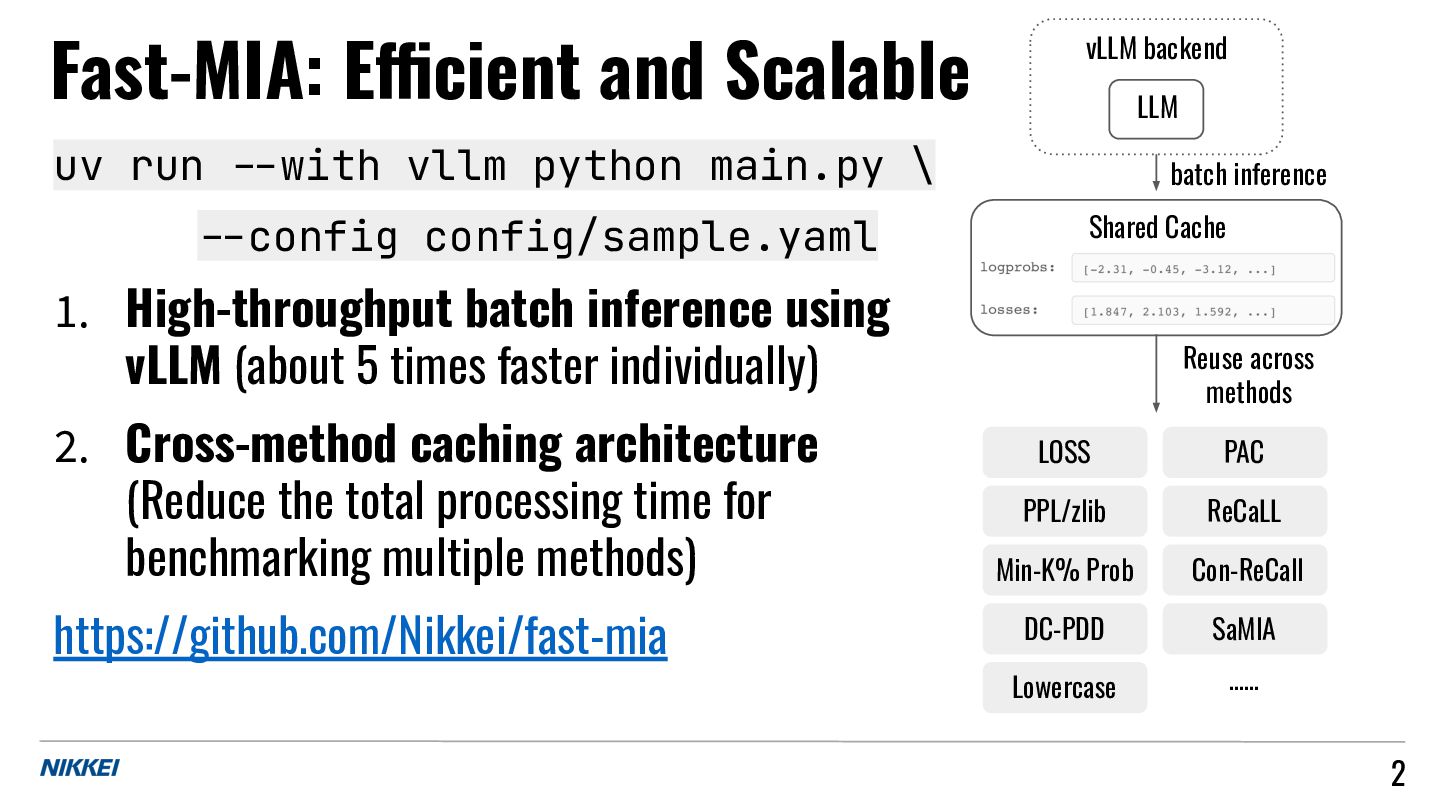
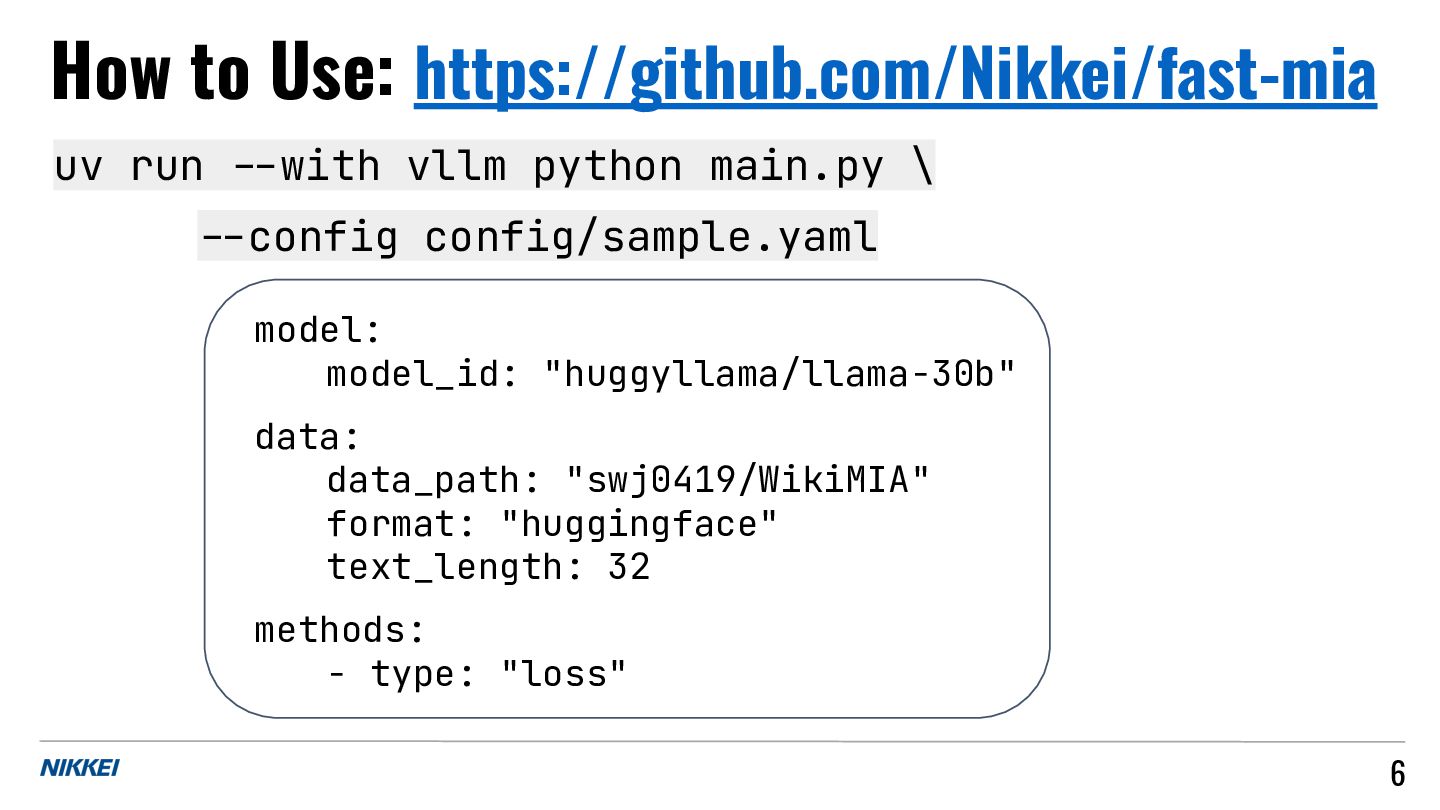
uv run --with vllm python main.py \ --config config/sample.yaml 1.
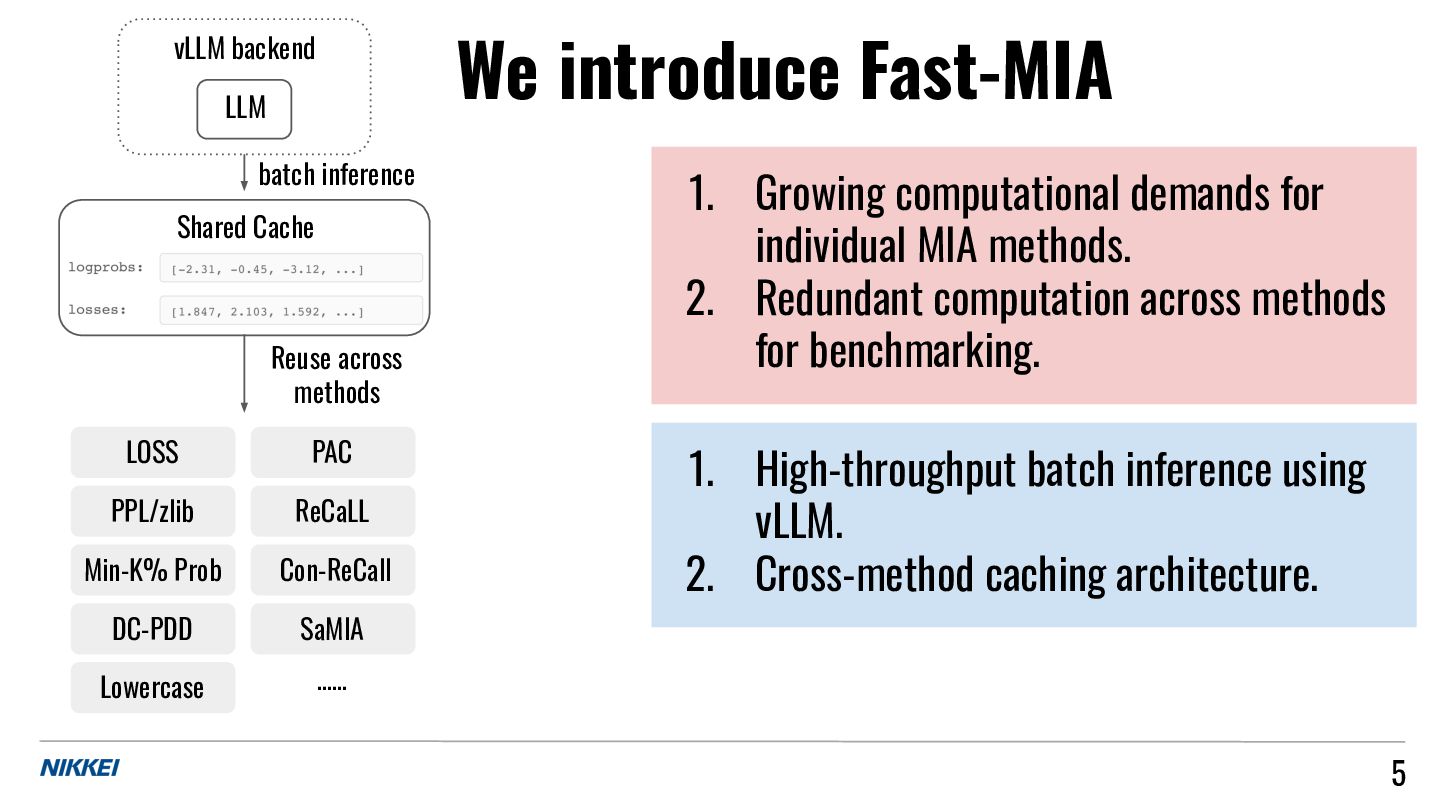
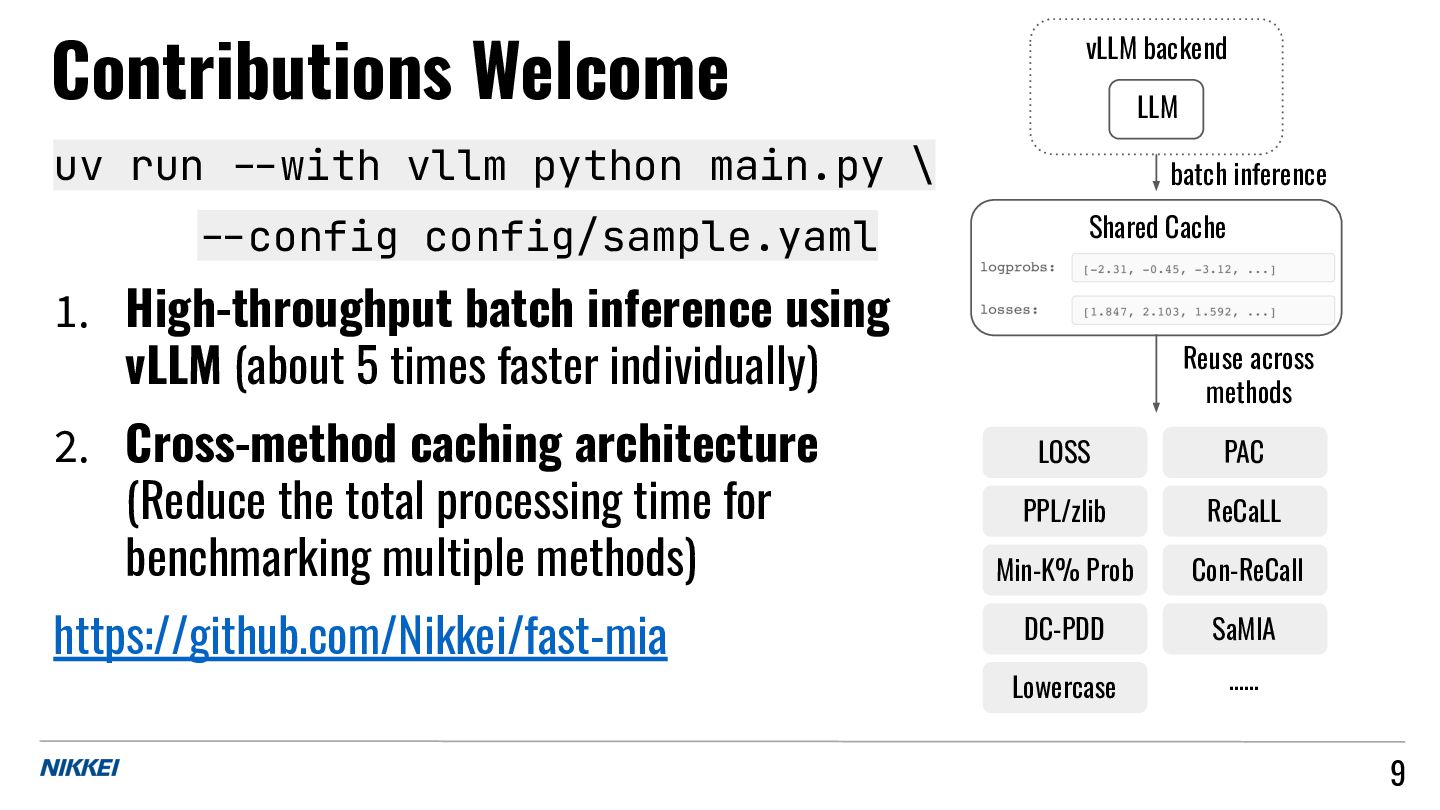
High-throughput batch inference using vLLM (about 5 times faster individually) 2. Cross-method caching architecture (Reduce the total processing time for benchmarking multiple methods) https://github.com/Nikkei/fast-mia Fast-MIA: Efficient and Scalable 2 LLM LOSS vLLM backend batch inference Shared Cache Reuse across methods PPL/zlib Min-K% Prob DC-PDD Lowercase PAC ReCaLL Con-ReCall SaMIA ……
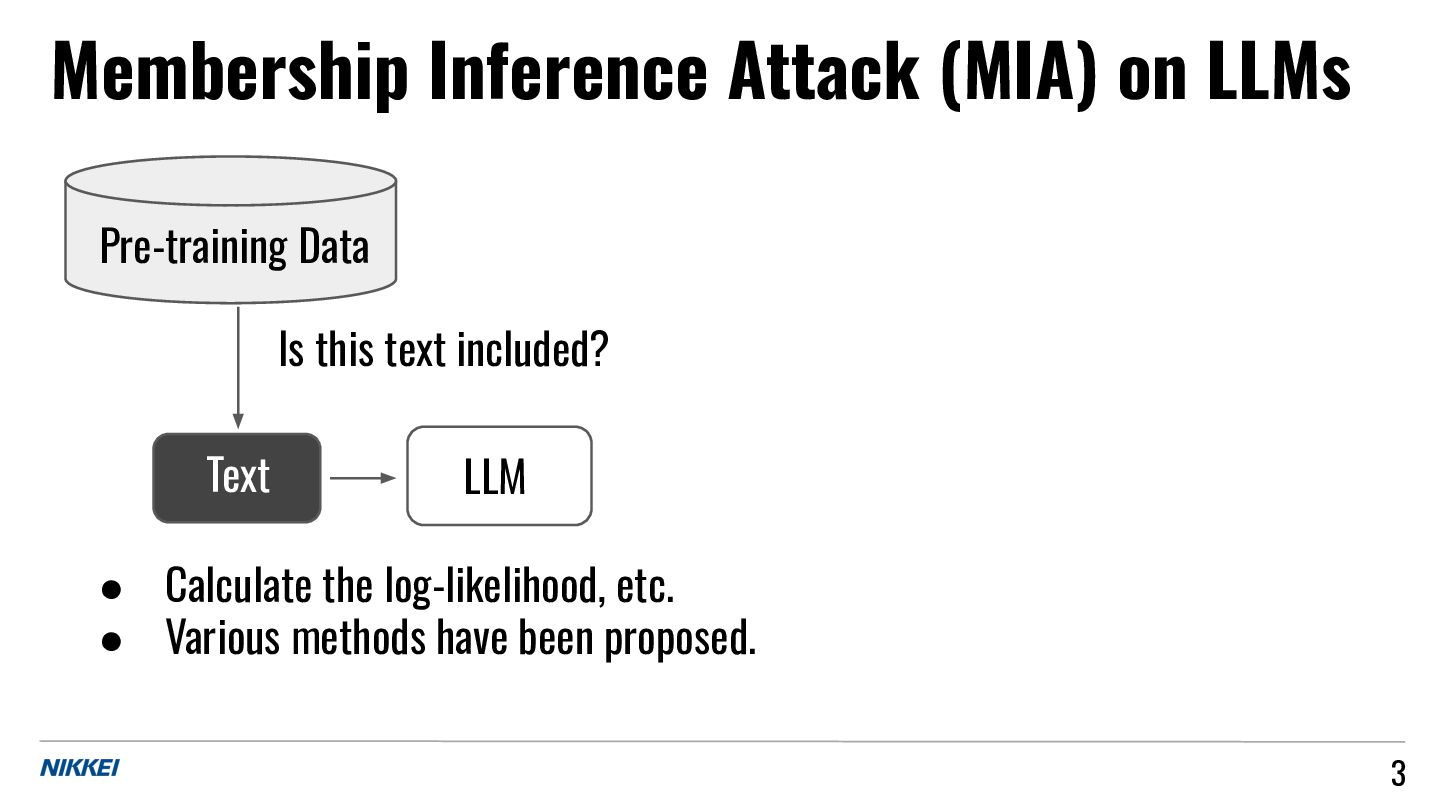
Membership Inference Attack (MIA) on LLMs 3 LLM Is this
text included? Text Pre-training Data • Calculate the log-likelihood, etc. • Various methods have been proposed.
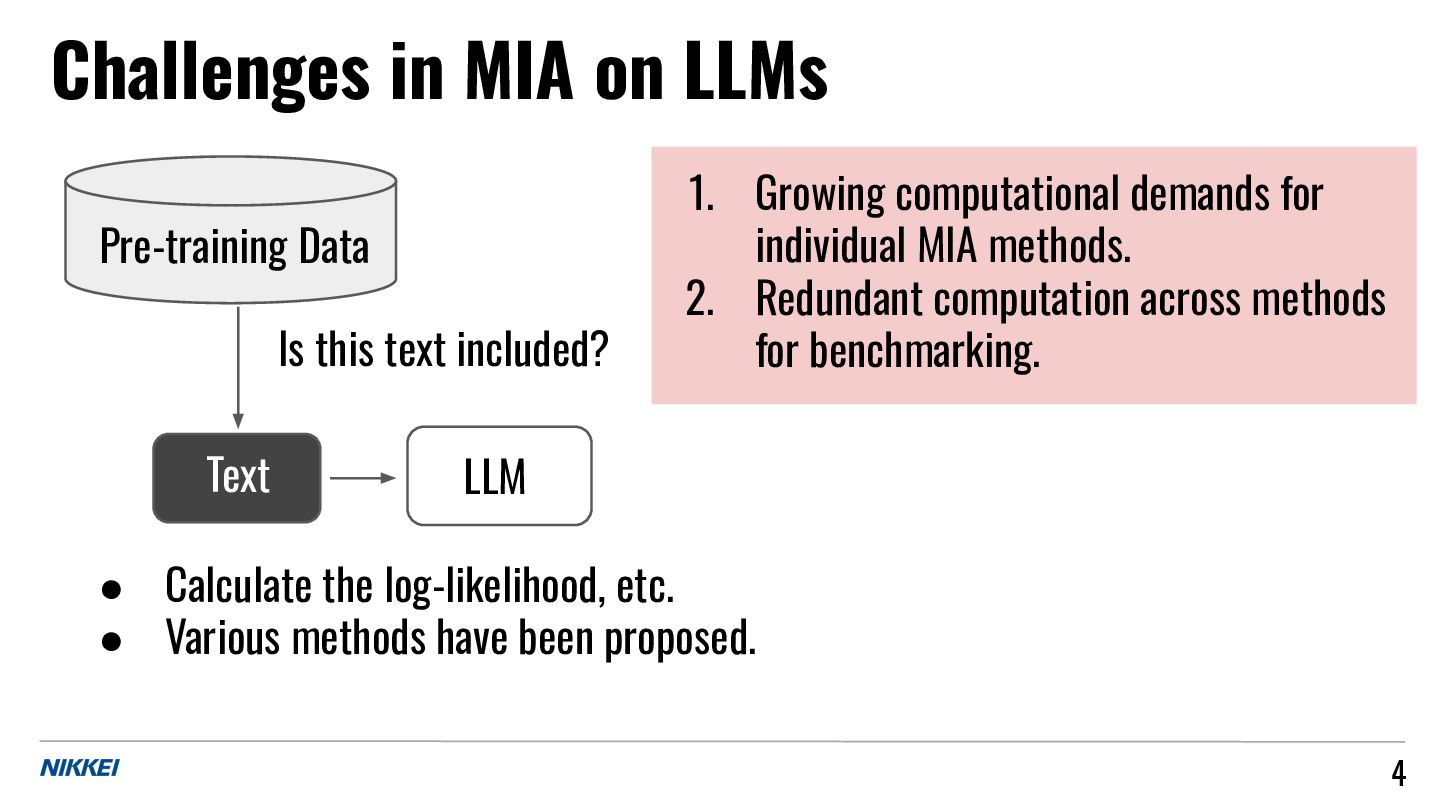
Challenges in MIA on LLMs 4 LLM Is this text
included? Text Pre-training Data • Calculate the log-likelihood, etc. • Various methods have been proposed. 1. Growing computational demands for individual MIA methods. 2. Redundant computation across methods for benchmarking.
We introduce Fast-MIA 5 1. Growing computational demands for individual
MIA methods. 2. Redundant computation across methods for benchmarking. LLM LOSS vLLM backend batch inference Shared Cache Reuse across methods PPL/zlib Min-K% Prob DC-PDD Lowercase PAC ReCaLL Con-ReCall SaMIA …… 1. High-throughput batch inference using vLLM. 2. Cross-method caching architecture.
uv run --with vllm python main.py \ --config config/sample.yaml How
to Use: https://github.com/Nikkei/fast-mia 6 model: model_id: "huggyllama/llama-30b" data: data_path: "swj0419/WikiMIA" format: "huggingface" text_length: 32 methods: - type: "loss"
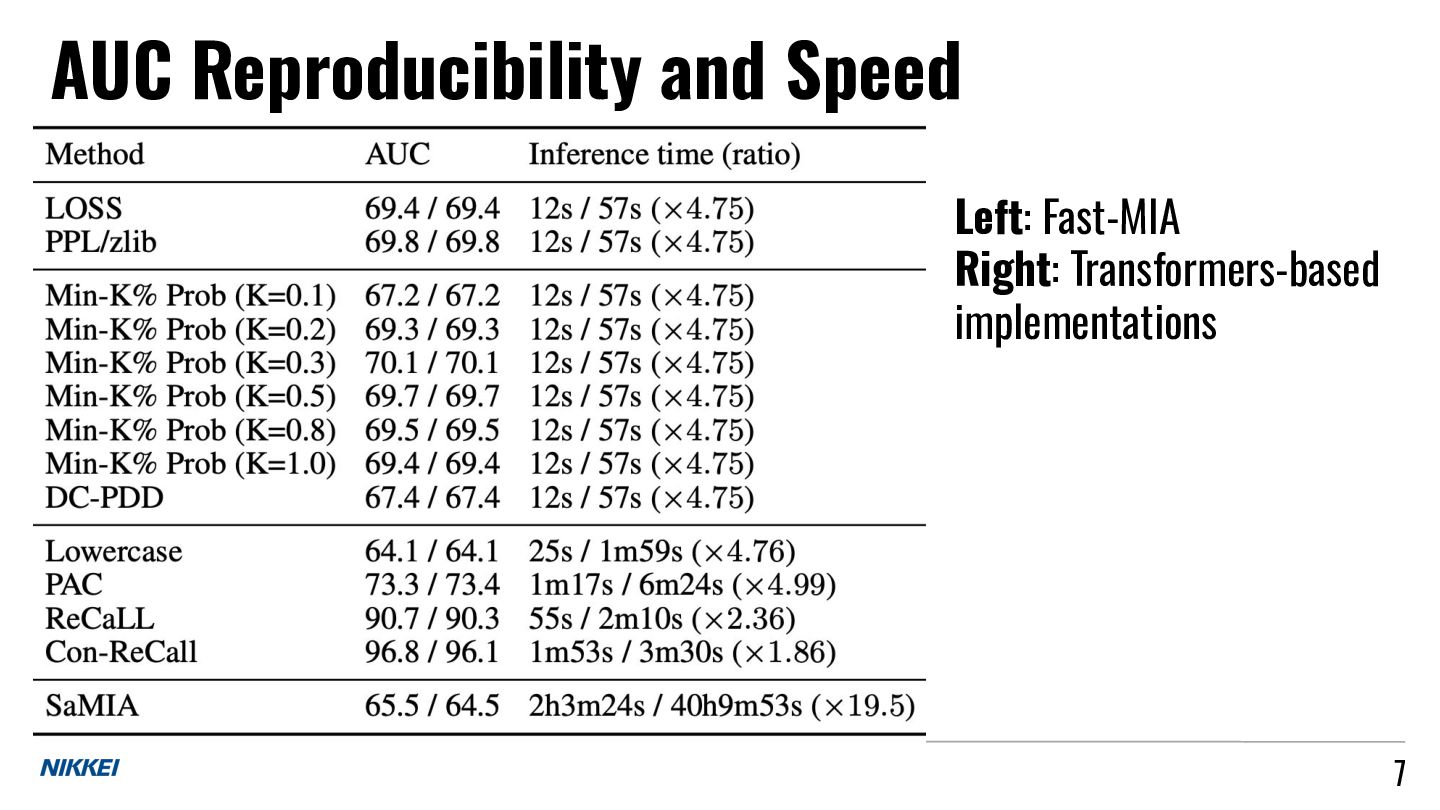
AUC Reproducibility and Speed 7 Left: Fast-MIA Right: Transformers-based implementations
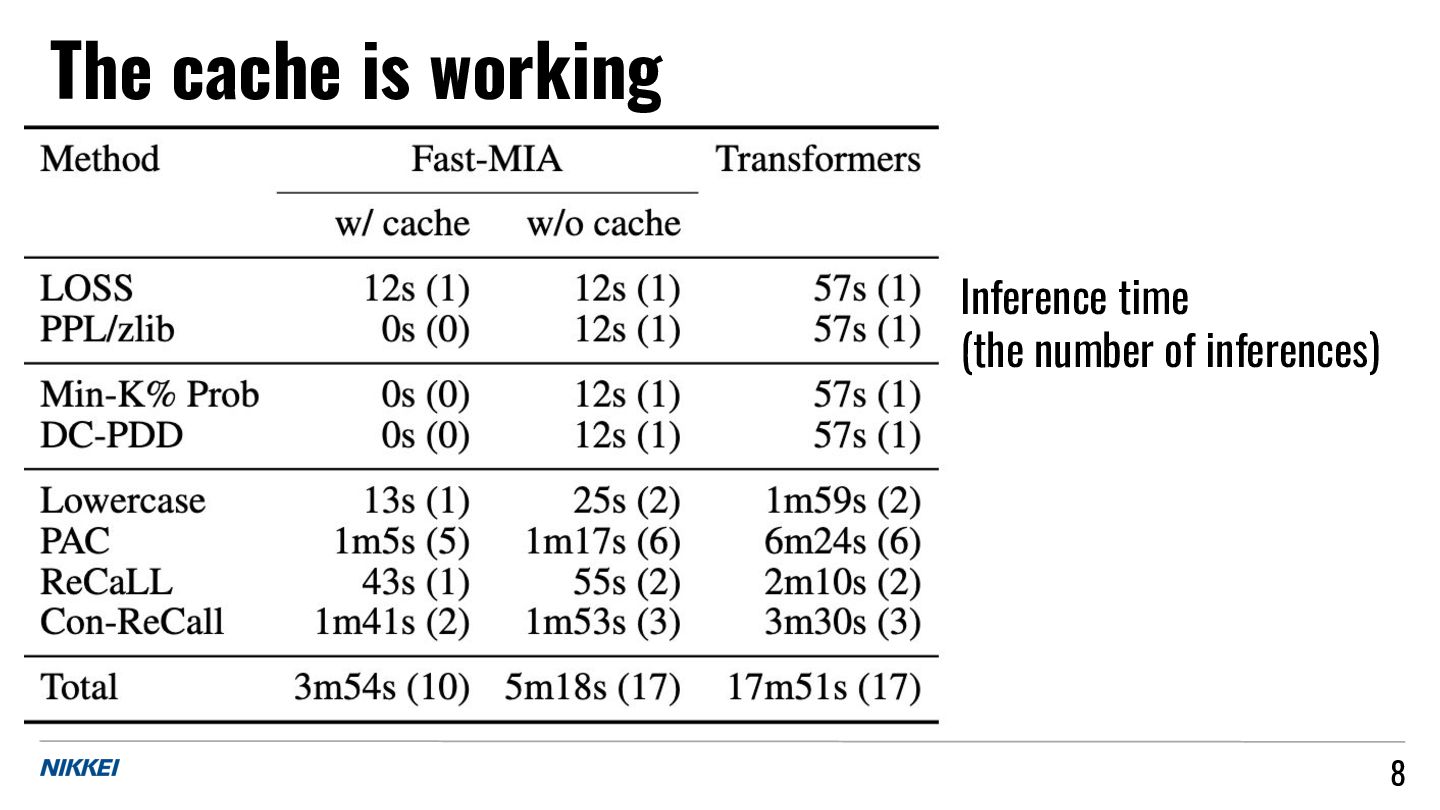
Inference time (the number of inferences) The cache is working
8
uv run --with vllm python main.py \ --config config/sample.yaml 1.
High-throughput batch inference using vLLM (about 5 times faster individually) 2. Cross-method caching architecture (Reduce the total processing time for benchmarking multiple methods) https://github.com/Nikkei/fast-mia Contributions Welcome 9 LLM LOSS vLLM backend batch inference Shared Cache Reuse across methods PPL/zlib Min-K% Prob DC-PDD Lowercase PAC ReCaLL Con-ReCall SaMIA ……
More Decks by Shotaro Ishihara
See All by Shotaro Ishihara
Agent 時代の Kaggle 展望 / kaggle-in-the-agentic-era
upura
1
1.5k
大規模言語モデルは誰を覚えているか / Who Do Large Language Models Memorize?
upura
0
230
Fast-MIA: Efficient and Scalable Membership Inference for LLMs
upura
0
110
JAPAN AI CUP Prediction Tutorial
upura
2
1.4k
情報技術の社会実装に向けた応用と課題:ニュースメディアの事例から / appmech-jsce 2025
upura
0
480
日本語新聞記事を用いた大規模言語モデルの暗記定量化 / LLMC2025
upura
0
850
Quantifying Memorization in Continual Pre-training with Japanese General or Industry-Specific Corpora
upura
1
160
JOAI2025講評 / joai2025-review
upura
0
1.9k
AI エージェントを活用した研究再現性の自動定量評価 / scisci2025
upura
1
320
Other Decks in Research
See All in Research
全国町字単位空き家率推定データver1.0データ仕様
microbaseinc
0
330
La longévité des troupeaux laitiers: état des lieux et perspectives
institutdelelevage
PRO
0
140
J-STAGEの現況と全文XML登載必須化について
xspa2012
0
410
The Conductor Pattern -Multi-Granularity Feedback for Creative Agents-
shibuiwilliam
2
120
視覚若手の会LENSって何??
mickey_0226
0
410
Evaluating LLM Reliability Across Facts, Evidence, and Cultures
yukiar
0
240
Des solutions pour pâturer davantage en hiver
institutdelelevage
PRO
0
120
OWASP AISVS - C7
shiell
2
860
超効率化への挑戦:1bit LLMの現状と展望
yumaichikawa
0
1k
論文紹介: Understanding Epistemic Language with a Language-augmented Bayesian Theory of Mind
hisaokatsumi
0
210
Vers un système bovin allaitant multiperformant :leviers actionnés et trajectoire de réduction de l'empreinte carbone à travers 4 années d'expérimentation à FERM'INOV
institutdelelevage
PRO
0
150
ros2-perf-multihost: Automated Coordination Framework for Objective Architecture Evaluation in Distributed Systems
takasehideki
0
180
Featured
See All Featured
Visualization
eitanlees
153
17k
Dealing with People You Can't Stand - Big Design 2015
cassininazir
367
27k
技術選定の審美眼(2025年版) / Understanding the Spiral of Technologies 2025 edition
twada
PRO
121
130k
How to audit for AI Accessibility on your Front & Back End
davetheseo
0
640
Paper Plane
katiecoart
PRO
6
55k
Getting science done with accelerated Python computing platforms
jacobtomlinson
2
570
VelocityConf: Rendering Performance Case Studies
addyosmani
331
25k
Why Your Marketing Sucks and What You Can Do About It - Sophie Logan
marketingsoph
0
470
世界の人気アプリ100個を分析して見えたペイウォール設計の心得
akihiro_kokubo
PRO
74
43k
コードの90%をAIが書く世界で何が待っているのか / What awaits us in a world where 90% of the code is written by AI
rkaga
63
48k
SEO in 2025: How to Prepare for the Future of Search
ipullrank
3
3.9k
Connecting the Dots Between Site Speed, User Experience & Your Business [WebExpo 2025]
tammyeverts
11
1.1k


 upura
 microbaseinc
 institutdelelevage
 xspa2012
 shibuiwilliam
 mickey_0226
 yukiar
 shiell
 yumaichikawa
 hisaokatsumi
 takasehideki
 eitanlees
 cassininazir
 twada
 davetheseo
 katiecoart
 jacobtomlinson
 addyosmani
 marketingsoph
 akihiro_kokubo
 rkaga
 ipullrank
 tammyeverts