Share
Embed
THE EFFECTS OF SYNTACTIC FEATURES IN AUTOMATIC PREDICTION OF MORPHOLOGY
Wolfgang Seeker and Jonas Kuhn Institute for Natural Language
Processing
University of Stuttgart
Proceedings of the 2013 Conference on Empirical Methods in Natural
Language Processing (EMNLP), pages 333–344,
Seattle, Washington, USA, 18-21 October 2013
Yemane
October 15, 2015
Transcript
17 slides
-
THE EFFECTS OF SYNTACTIC FEATURES IN AUTOMATIC PREDICTION OF MORPHOLOGY
OCTOBER 14, 2015 Authors Wolfgang Seeker and Jonas Kuhn Institute for Natural Language Processing University of Stuttgart Conference Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing (EMNLP), pages 333–344, Seattle, Washington, USA, 18-21 October 2013 1 -
Introduction Aim • analyze the effect of syntactic features when
used in automatic morphology prediction Approach • examine the effect of syntactic information when it is integrated into the feature model of a morphological tagger Result • taking into account syntactic context of words improved morphology prediction 2 -
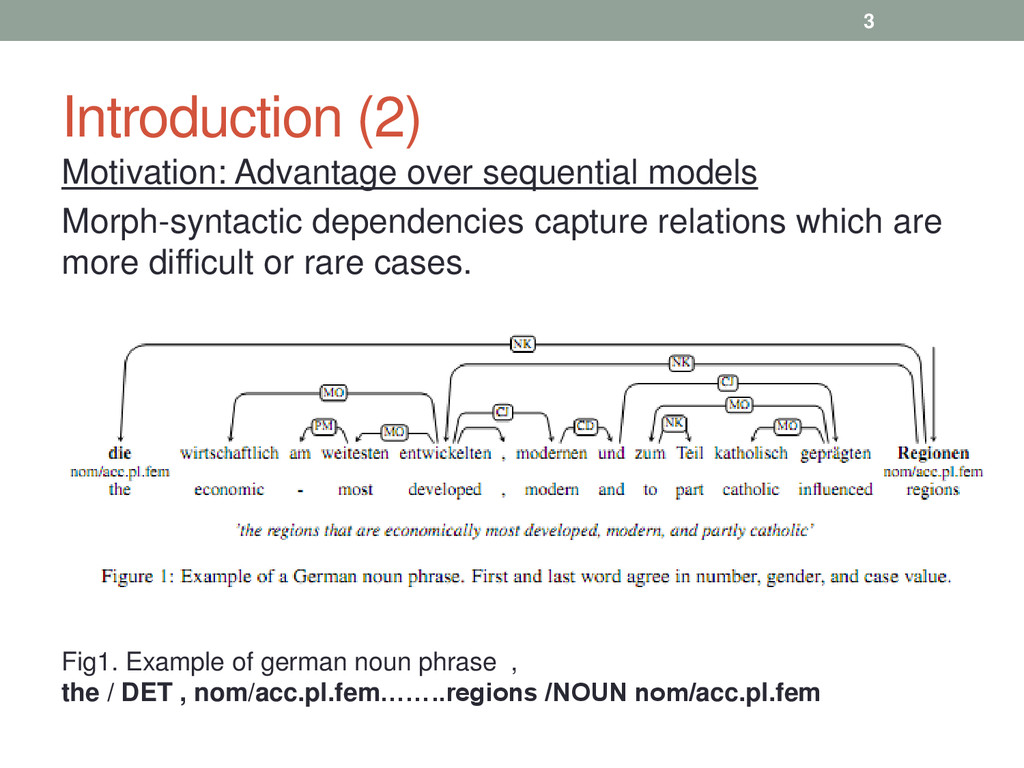
Introduction (2) Motivation: Advantage over sequential models Morph-syntactic dependencies capture
relations which are more difficult or rare cases. Fig1. Example of german noun phrase , the / DET , nom/acc.pl.fem……..regions /NOUN nom/acc.pl.fem 3 -
Languages and Data Sets Languages • Czech, German, Hungarian, and
Spanish • Czech, Hungarian – very rich morphology • German, Spanish – show verbal and nominal morphology Dataset Czech and Spanish CoNLL 2009 Shared Task data German, TiGer treebank Hungarian, Szeged Dependency Treebank 4 -
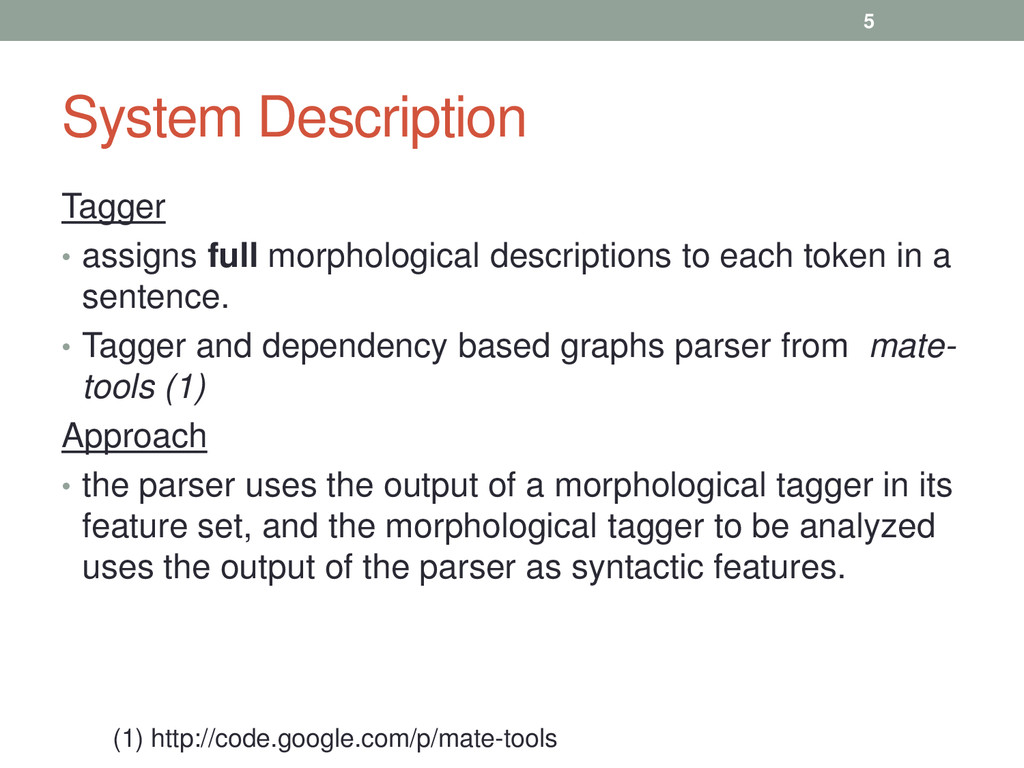
System Description Tagger • assigns full morphological descriptions to each
token in a sentence. • Tagger and dependency based graphs parser from mate- tools (1) Approach • the parser uses the output of a morphological tagger in its feature set, and the morphological tagger to be analyzed uses the output of the parser as syntactic features. (1) http://code.google.com/p/mate-tools 5 -
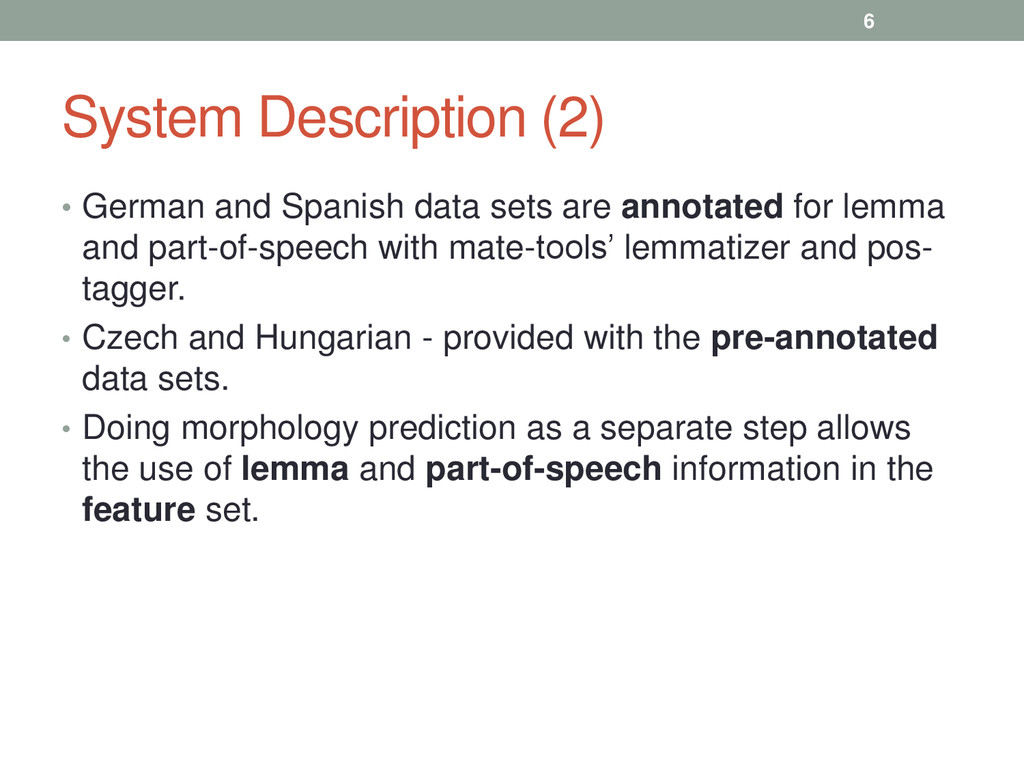
System Description (2) • German and Spanish data sets are
annotated for lemma and part-of-speech with mate-tools’ lemmatizer and pos- tagger. • Czech and Hungarian - provided with the pre-annotated data sets. • Doing morphology prediction as a separate step allows the use of lemma and part-of-speech information in the feature set. 6 -
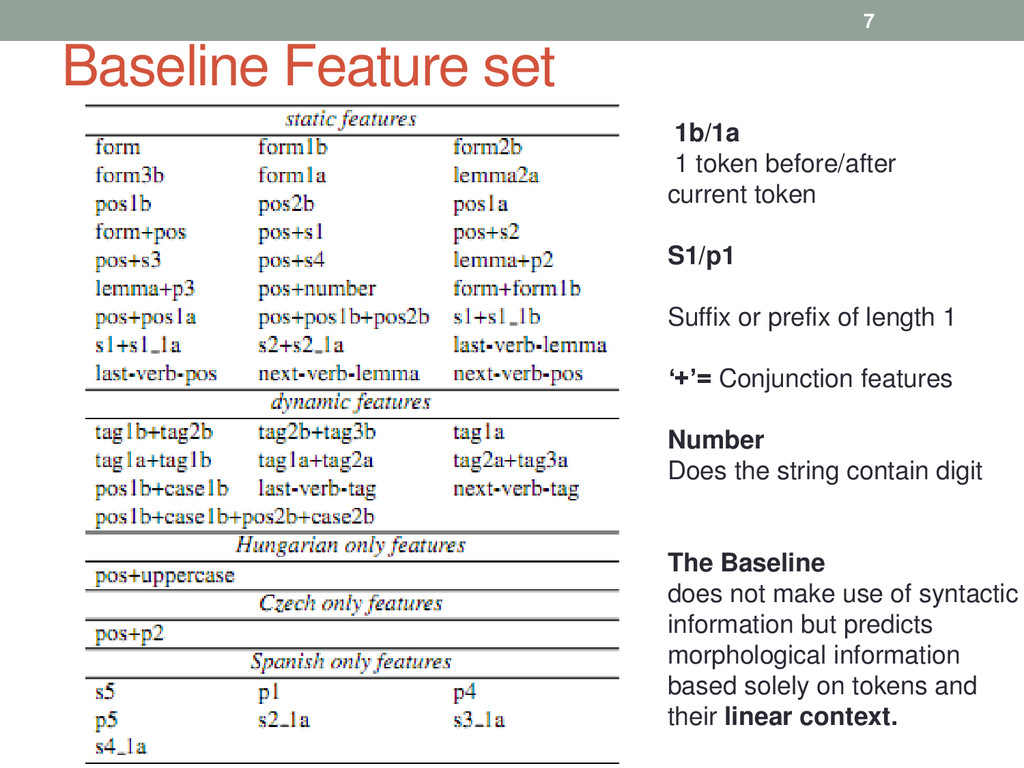
Baseline Feature set 1b/1a 1 token before/after current token S1/p1
Suffix or prefix of length 1 ‘+’= Conjunction features Number Does the string contain digit The Baseline does not make use of syntactic information but predicts morphological information based solely on tokens and their linear context. 7 -
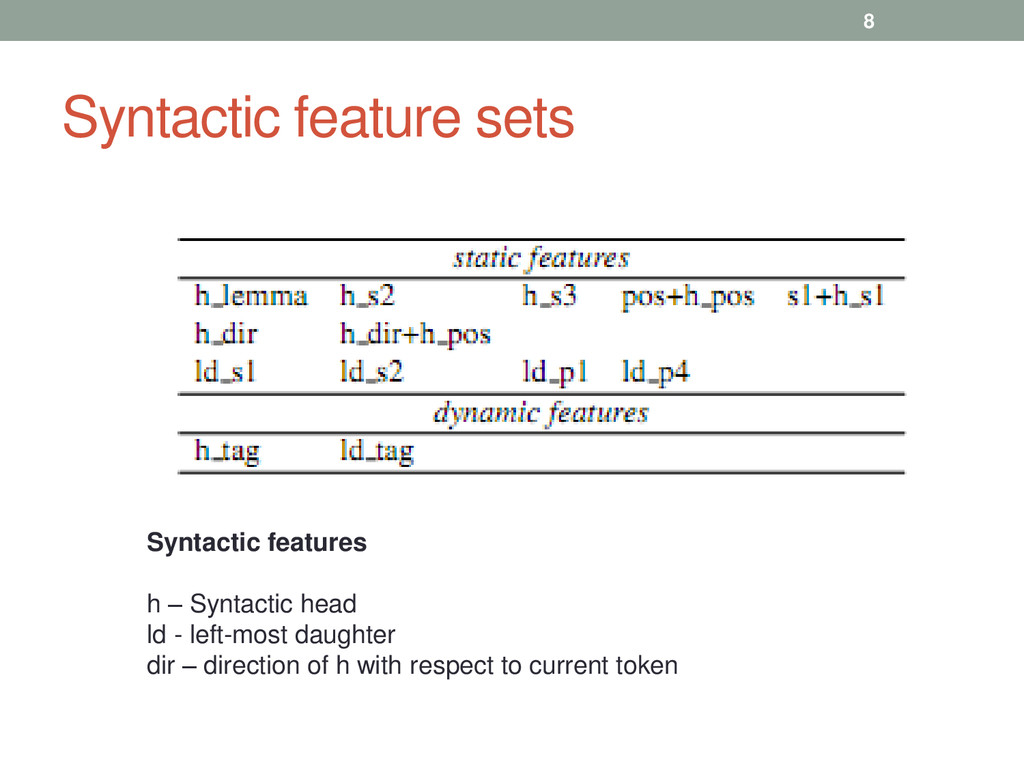
Syntactic feature sets Syntactic features h – Syntactic head ld
- left-most daughter dir – direction of h with respect to current token 8 -
Process • All data sets are annotated with predicted morphology
from baseline system + syntactic information from a dependency parser (the parser uses the morphological information from the baseline system in its feature set ) 9 -
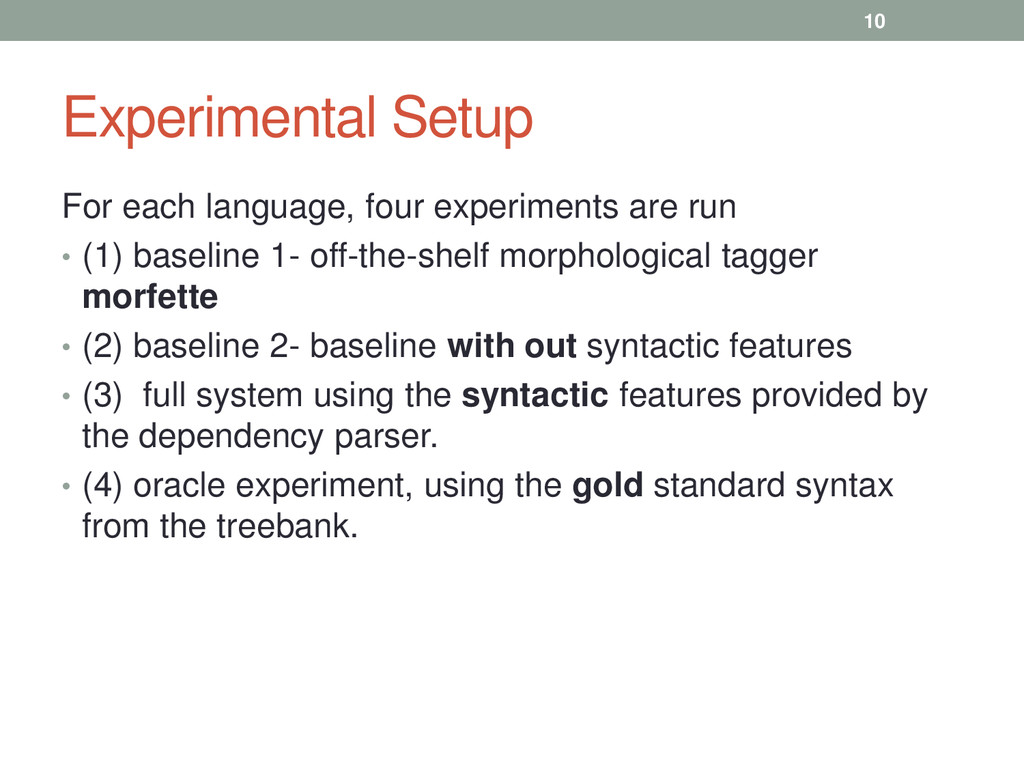
Experimental Setup For each language, four experiments are run •
(1) baseline 1- off-the-shelf morphological tagger morfette • (2) baseline 2- baseline with out syntactic features • (3) full system using the syntactic features provided by the dependency parser. • (4) oracle experiment, using the gold standard syntax from the treebank. 10 -
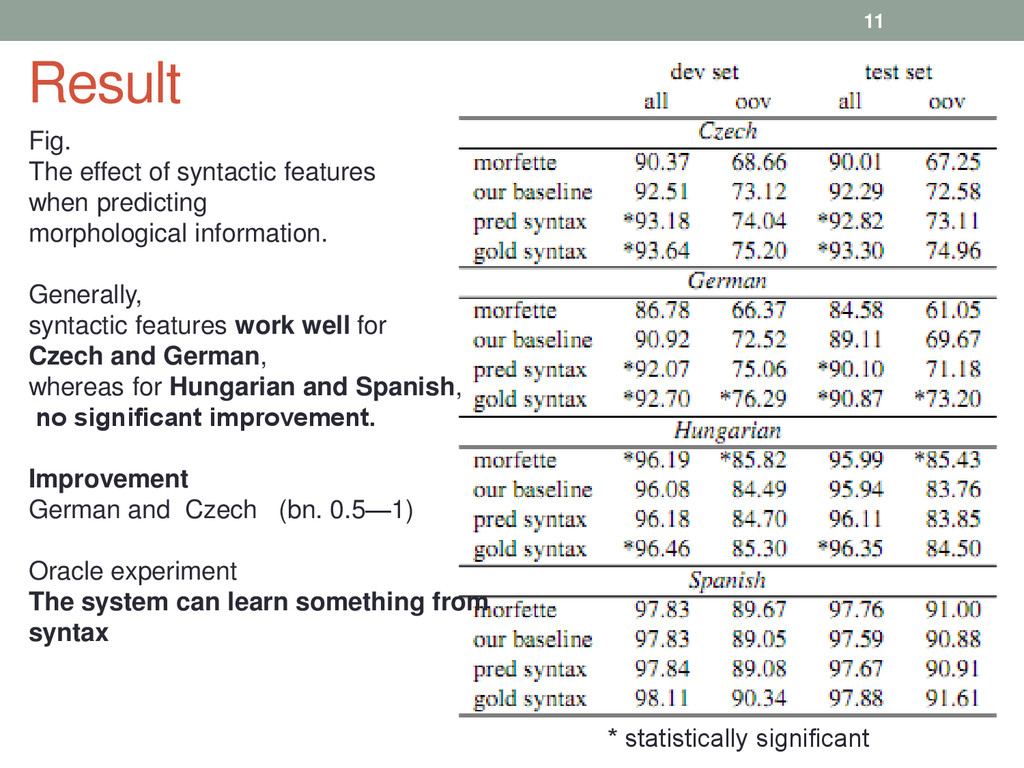
Fig. The effect of syntactic features when predicting morphological information.
Generally, syntactic features work well for Czech and German, whereas for Hungarian and Spanish, no significant improvement. Improvement German and Czech (bn. 0.5—1) Oracle experiment The system can learn something from syntax * statistically significant Result 11 -
Syntax Vs Lexicon • Lexicons encode important knowledge that is
difficult to pick up in a purely statistical system, e.g the gender of nouns • The System was extended to include information from morphological dictionaries 12 -
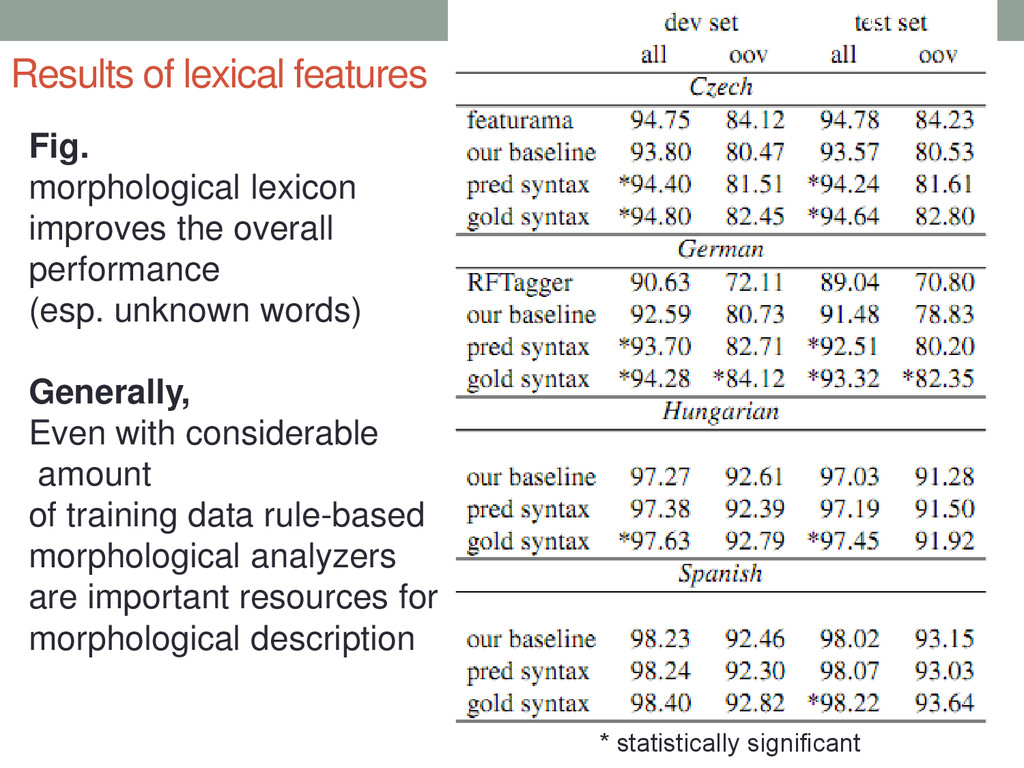
* statistically significant Fig. morphological lexicon improves the overall performance
(esp. unknown words) Generally, Even with considerable amount of training data rule-based morphological analyzers are important resources for morphological description Results of lexical features 13 -
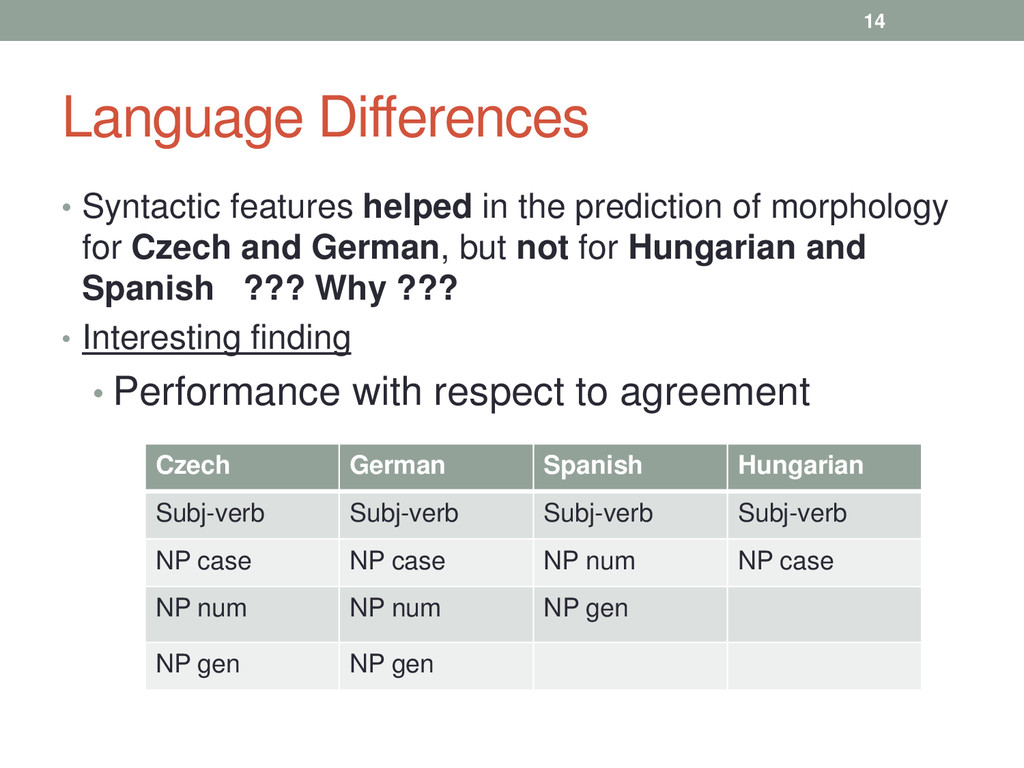
Language Differences • Syntactic features helped in the prediction of
morphology for Czech and German, but not for Hungarian and Spanish ??? Why ??? • Interesting finding • Performance with respect to agreement Czech German Spanish Hungarian Subj-verb Subj-verb Subj-verb Subj-verb NP case NP case NP num NP case NP num NP num NP gen NP gen NP gen 14 -
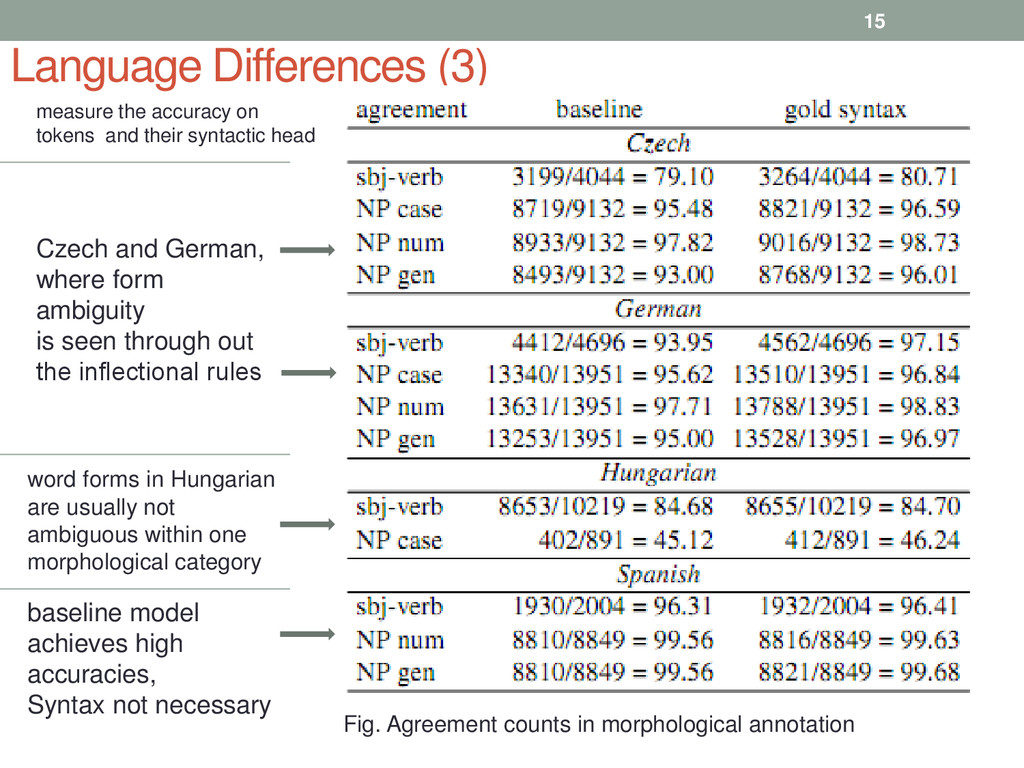
Language Differences (3) baseline model achieves high accuracies, Syntax not
necessary word forms in Hungarian are usually not ambiguous within one morphological category Czech and German, where form ambiguity is seen through out the inflectional rules 15 Fig. Agreement counts in morphological annotation measure the accuracy on tokens and their syntactic head -
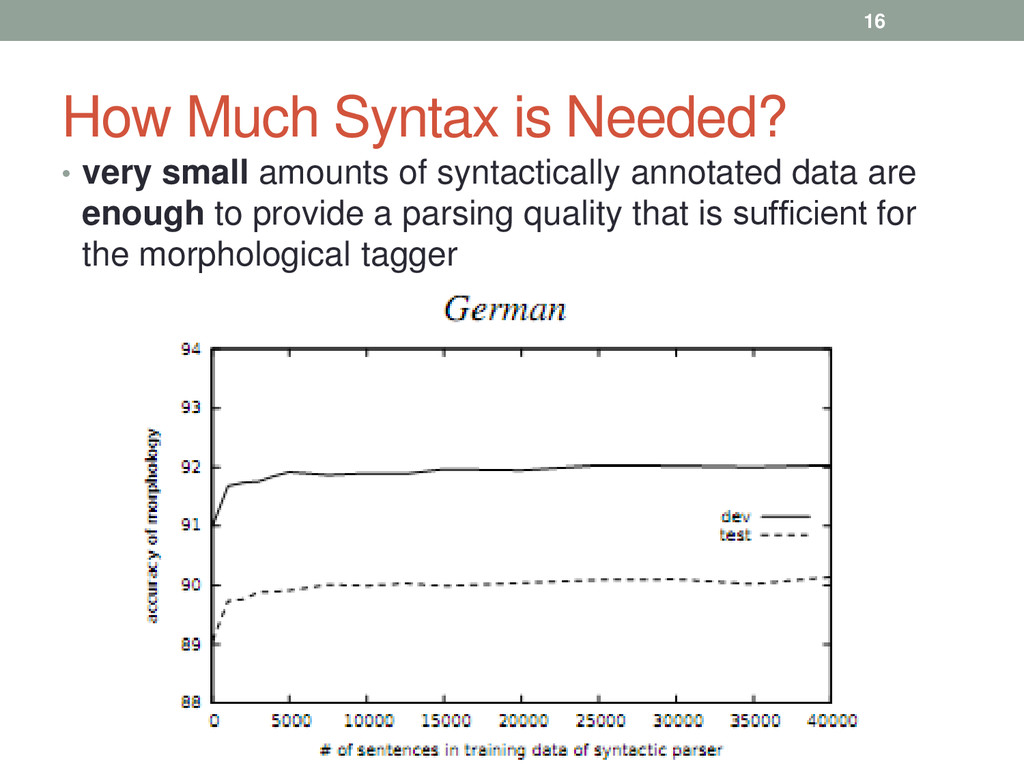
How Much Syntax is Needed? • very small amounts of
syntactically annotated data are enough to provide a parsing quality that is sufficient for the morphological tagger 16 -
Conclusion • Syntactic information for predicting morphological information is helpful
particularly for languages which show morph-syntactic agreement. • Small amounts of training data maybe sufficient to train a statistical parser that will be used by the morphological tagger. • Specific features of a language can help in explaining the behavior of automatic tools. 17