Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
tidymodelsによるtidyな機械学習 / Japan.R 2019
Search
森下光之助
December 07, 2019
Programming
6.2k
4
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
tidymodelsによるtidyな機械学習 / Japan.R 2019
2019年12月7日に行われたJapan.R 2019での発表資料です
https://japanr.connpass.com/event/154070/
森下光之助
December 07, 2019
More Decks by 森下光之助
See All by 森下光之助
『ビジネス課題を解決する技術』を出版しました / CA DATA Night #7
dropout009
1
110
baseballrによるMLBデータの抽出と階層ベイズモデルによる打率の推定 / TokyoR118
dropout009
2
1k
tidymodelsによるtidyな生存時間解析 / Japan.R2024
dropout009
2
1.5k
データ不足に数理モデルで立ち向かう / Japan.R 2023
dropout009
12
6.4k
回帰分析ではlm()ではなくestimatr::lm_robust()を使おう / TokyoR100
dropout009
67
11k
Counterfactual Explanationsで機械学習モデルを解釈する / TokyoR99
dropout009
3
3.3k
『機械学習を解釈する技術』の紹介 / Devsumi2022
dropout009
4
4.2k
シンプルな数理モデルでビジネス課題を解決する / Japan.R 2021
dropout009
2
7.2k
テレビCMのユニークリーチを最適化する / PyData.Tokyo24
dropout009
0
1.9k
Other Decks in Programming
See All in Programming
パスワード再設定メールのURLについて知っておこう
uyuki234
0
150
コードレビューのボトルネックを"する側"と"される側"の両面から解消する
yub0n
2
1.6k
Androidだけじゃない、DroidKaigiで広がった私の技術スタック
akkeylab
0
130
自サークルのIdPからログアウトできるようになるまで
taiseiue
1
130
ジョジョの世界をXRで再現する
mofurune
0
160
[2026-09-26]空論ジェネリックプロセス~テスト資産とAIで紡ぐ、再現可能なパフォーマンスチューニングの話~
tosite
0
270
Apple Intelligence を用いた個人情報誤送信防止、及びユーザーリクエスト体験の改善について
yukiny
0
330
ソニーのクラウド共通基盤の変遷と AI時代の開発スタイルに合わせた進化 / The Journey of Sony’s Common Cloud Platform and Its Evolution for AI-Native Development
kenjiyoneyama
0
250
Findy - エンジニア向け会社紹介/Findy Company Deck
findyinc
6
400k
パズルゲームの作り方 / how to make puzzle games
kaityo256
PRO
2
290
JAWS-UG 東京支部が始める、JAWS-UG支部コラボ / JAWS-UG lunchtime LT Collaboration
y0hgi
0
260
[Rails World 2026] Durable orchestration on Rails: from continuation to workflow
palkan
1
740
Featured
See All Featured
Navigating Weather and Climate Data
rabernat
0
550
The Anti-SEO Checklist Checklist. Pubcon Cyber Week
ryanjones
0
270
How to Talk to Developers About Accessibility
jct
2
570
XXLCSS - How to scale CSS and keep your sanity
sugarenia
250
1.3M
[Rails World 2023 - Day 1 Closing Keynote] - The Magic of Rails
eileencodes
38
3.1k
Stop Working from a Prison Cell
hatefulcrawdad
274
21k
Typedesign – Prime Four
hannesfritz
42
3.2k
Ruling the World: When Life Gets Gamed
codingconduct
0
400
Responsive Adventures: Dirty Tricks From The Dark Corners of Front-End
smashingmag
254
22k
ReactJS: Keep Simple. Everything can be a component!
pedronauck
666
130k
Designing Dashboards & Data Visualisations in Web Apps
destraynor
232
55k
HTML-Aware ERB: The Path to Reactive Rendering @ RubyCon 2026, Rimini, Italy
marcoroth
5
810
Transcript
tidymodelsによる tidyな機械学習 2019/12/7 Japan.R 2019 森下光之助(@dropout009)
tidymodels︓tidyなやり⽅で機械学習が⾏えるパッケージ群 ü rsample︓Train/Test、Cross Validationなどのデータ分割 ü recipe︓データの前処理、特徴量エンジニアリング ü parsnip︓モデル構築と学習 ü tune︓ハイパーパラメータのチューニング
ü yardstic :モデルの精度評価
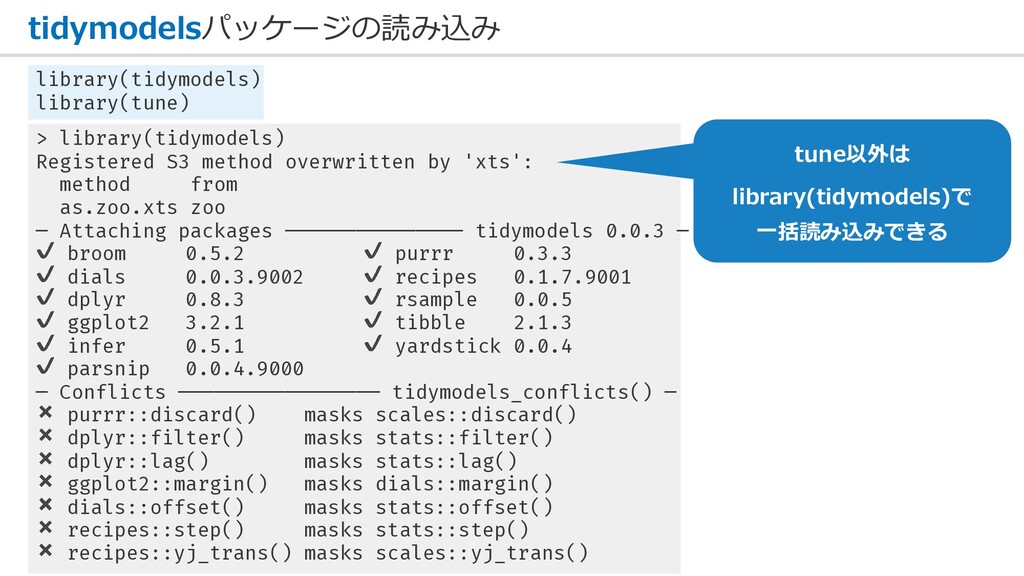
tidymodelsパッケージの読み込み library(tidymodels) library(tune) > library(tidymodels) Registered S3 method overwritten by
'xts': method from as.zoo.xts zoo ─ Attaching packages ─────────────── tidymodels 0.0.3 ─ ✔ broom 0.5.2 ✔ purrr 0.3.3 ✔ dials 0.0.3.9002 ✔ recipes 0.1.7.9001 ✔ dplyr 0.8.3 ✔ rsample 0.0.5 ✔ ggplot2 3.2.1 ✔ tibble 2.1.3 ✔ infer 0.5.1 ✔ yardstick 0.0.4 ✔ parsnip 0.0.4.9000 ─ Conflicts ───────────────── tidymodels_conflicts() ─ ✖ purrr::discard() masks scales::discard() ✖ dplyr::filter() masks stats::filter() ✖ dplyr::lag() masks stats::lag() ✖ ggplot2::margin() masks dials::margin() ✖ dials::offset() masks stats::offset() ✖ recipes::step() masks stats::step() ✖ recipes::yj_trans() masks scales::yj_trans() tune以外は library(tidymodels)で ⼀括読み込みできる
今回はサンプルデータとしてAmesHousingを使⽤ df = AmesHousing::make_ames() > df %>% + select(Sale_Price, everything())
# A tibble: 2,930 x 81 Sale_Price MS_SubClass MS_Zoning Lot_Frontage Lot_Area Street Alley <int> <fct> <fct> <dbl> <int> <fct> <fct> 1 215000 One_Story_… Resident… 141 31770 Pave No_A… 2 105000 One_Story_… Resident… 80 11622 Pave No_A… 3 172000 One_Story_… Resident… 81 14267 Pave No_A… 4 244000 One_Story_… Resident… 93 11160 Pave No_A… 5 189900 Two_Story_… Resident… 74 13830 Pave No_A… 6 195500 Two_Story_… Resident… 78 9978 Pave No_A… 7 213500 One_Story_… Resident… 41 4920 Pave No_A… 8 191500 One_Story_… Resident… 43 5005 Pave No_A… 9 236500 One_Story_… Resident… 39 5389 Pave No_A… 10 189000 Two_Story_… Resident… 60 7500 Pave No_A… # … with 2,920 more rows, and 74 more variables: Sale Priceを予測したい
rsampleでデータを分割 split = initial_split(df, prop = 0.8) df_train = training(split)
df_test = testing(split) df_cv = vfold_cv(df_train, v = 5) > df_cv # 5-fold cross-validation # A tibble: 5 x 2 splits id <named list> <chr> 1 <split [1.9K/469]> Fold1 2 <split [1.9K/469]> Fold2 3 <split [1.9K/469]> Fold3 4 <split [1.9K/469]> Fold4 5 <split [1.9K/469]> Fold5 Train/Testの分割 Trainをさらに CVとして5分割
recipeでデータの前処理 rec = recipe(Sale_Price ~ ., data = df_train) %>%
step_log(Sale_Price) > rec Data Recipe Inputs: role #variables outcome 1 predictor 80 Operations: Log transformation on Sale_Price recipeで前処理⾏う 今回はターゲットの対数をとった
parsnipでモデルを作成 model = rand_forest(mode = "regression", trees = 500, min_n
= tune(), mtry = tune()) %>% set_engine(engine = "ranger", num.threads = parallel::detectCores(), seed = 42) > model Random Forest Model Specification (regression) Main Arguments: mtry = tune() trees = 500 min_n = tune() Engine-Specific Arguments: num.threads = parallel::detectCores() seed = 42 Computational engine: ranger parsnipでモデルを指定する 今回はRF 探索したいハイパーパラメータ はtune()としておく どのRFパッケージを使うかは set_engine()で指定 パッケージ固有のパラメータ もここで指定
tuneで探索するハイパーパラメータとその範囲を指定 params = list(min_n = min_n(range = c(1, 20)), mtry
= mtry(range(5, 20))) %>% parameters() > params Collection of 2 parameters for tuning id parameter type object class min_n min_n nparam[+] mtry mtry nparam[+] 探索したいハイパーパラメータと その範囲をリストに
tuneでハイパーパラメータを探索 df_tuned = tune_bayes( rec, model = model, resamples =
df_cv, param_info = params, initial = 5, iter = 50, metrics = metric_set(rsq), control = control_bayes(no_improve = 10, verbose = TRUE)) > df_tuned # 5-fold cross-validation # A tibble: 90 x 5 splits id .metrics .notes .iter * <list> <chr> <list> <list> <dbl> 1 <split [1.8K/440]> Fold1 <tibble [4 × 5]> <tibble [0 × 1]> 0 2 <split [1.8K/440]> Fold2 <tibble [5 × 5]> <tibble [0 × 1]> 0 3 <split [1.8K/440]> Fold3 <tibble [5 × 5]> <tibble [0 × 1]> 0 4 <split [1.8K/439]> Fold4 <tibble [5 × 5]> <tibble [0 × 1]> 0 5 <split [1.8K/439]> Fold5 <tibble [5 × 5]> <tibble [0 × 1]> 0 # … with 80 more rows ハイパーパラメータの探索 今回はベイズ最適化で探す
ハイパーパラメータの探索結果を確認(tune) df_best_result = df_tuned %>% show_best(metric = "rsq", n_top =
3, maximize = TRUE) > df_best_result # A tibble: 3 x 8 mtry min_n .iter .metric .estimator mean n std_err <int> <int> <dbl> <chr> <chr> <dbl> <int> <dbl> 1 14 1 4 rsq standard 0.896 5 0.00356 2 20 1 10 rsq standard 0.896 5 0.00324 3 20 4 0 rsq standard 0.896 5 0.00325 特に精度の良かった ハイパーパラメータを確認 mtry=14, min_n=1 で最⾼の精度
最も精度の良かったハイパーパラメータをモデルにセット(parsnip) df_best_param = df_tuned %>% select_best(metric = "rsq", maximize =
TRUE) model_best = model %>% update(df_best_param) > model_best Random Forest Model Specification (regression) Main Arguments: mtry = 14 trees = 500 min_n = 1 Engine-Specific Arguments: num.threads = parallel::detectCores() seed = 42 Computational engine: ranger 特に精度の良かった ハイパーパラメータを モデルにセット
全Trainデータで再学習し、Testデータで予測(recipe, parsnip) preped_rec = rec %>% prep() df_train_baked = preped_rec
%>% juice() df_test_baked = preped_rec %>% bake(df_test) fitted_model = model_best %>% fit(Sale_Price ~ ., data = df_train_baked) df_pred = df_test_baked %>% bind_cols(fitted_model %>% predict(new_data = df_test_baked)) レシピをTrainに適⽤ レシピをTestに適⽤ Trainで学習 Testで予測
yardsticでTestデータでの精度を確認 df_eval = df_pred %>% metrics(Sale_Price, .pred) > df_eval #
A tibble: 3 x 3 .metric .estimator .estimate <chr> <chr> <dbl> 1 rmse standard 0.120 2 rsq standard 0.903 3 mae standard 0.0816 Testデータでの予測精度を計算 モデルの予測値と実際のSale Price
まとめ︓tidymodels使うとtidyなやり⽅で機械学習が⾏える ü rsample︓Train/Test、Cross Validationなどのデータ分割 ü recipe︓データの前処理、特徴量エンジニアリング ü parsnip︓モデル構築と学習 ü tune︓ハイパーパラメータのチューニング
ü yardstic :モデルの精度評価
参考⽂献 • tidymodelsによるモデル構築と運⽤ / tidymodels https://speakerdeck.com/s_uryu/tidymodels • tidymodelsによるtidyな機械学習(その1︓データ分割と前処理から学習と性能評価まで) https://dropout009.hatenablog.com/entry/2019/01/06/124932 •
tidymodelsによるtidyな機械学習(その3︓ハイパーパラメータのチューニング) https://dropout009.hatenablog.com/entry/2019/11/10/125650 • General Resampling Infrastructure • rsample https://tidymodels.github.io/rsample/ • Preprocessing Tools to Create Design Matrices • recipes https://tidymodels.github.io/recipes/ • A Common API to Modeling and Analysis Functions • parsnip https://tidymodels.github.io/parsnip/ • Tidy Characterizations of Model Performance • yardstick https://tidymodels.github.io/yardstick/ • Tidy Tuning Tools • tune https://tidymodels.github.io/tune/index.html


 dropout009
 uyuki234
 yub0n
 akkeylab
 taiseiue
 mofurune
 tosite
 yukiny
 kenjiyoneyama
 findyinc
 kaityo256
 y0hgi
 palkan
 rabernat
 ryanjones
 jct
 sugarenia
 eileencodes
 hatefulcrawdad
 hannesfritz
 codingconduct
 smashingmag
 pedronauck
 destraynor
 marcoroth