Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Reinforcement Learning Based Text Style Transfe...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
ryoma yoshimura
July 25, 2019
Research
140
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Reinforcement Learning Based Text Style Transfer without Parallel Training Corpus
研究室のNAACL論文読み会での発表資料です。
ryoma yoshimura
July 25, 2019
More Decks by ryoma yoshimura
See All by ryoma yoshimura
TransQuest: Translation Quality Estimation with Cross-lingual Transformers
kokeman
0
290
Automatic Machine Translation Evaluation in Many Languages via Zero-Shot Paraphrasing
kokeman
0
66
BLEURT: Learning Robust Metrics for Text Generation
kokeman
0
280
Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks
kokeman
1
880
Courteously Yours: Inducing courteous behavior in Customer Care responses using Reinforced Pointer Generator Network
kokeman
0
180
Beyond BLEU: Training Neural Machine Translation with Semantic Similarity
kokeman
0
180
タスクとデータセット紹介 GLUE, SuperGLUE
kokeman
0
1.1k
Reliability and Learnability of Human Bandit Feedback for Sequence-to-Sequence Reinforcement Learning
kokeman
0
90
Multi-Reference Training with Pseudo-References for Neural Translation and Text Generation
kokeman
0
250
Other Decks in Research
See All in Research
超効率化への挑戦:1bit LLMの現状と展望
yumaichikawa
0
780
大規模言語モデルは誰を覚えているか / Who Do Large Language Models Memorize?
upura
0
200
適応的スパムフィルタのための軽量な類似メッセージカウンタ / jsai2026-adaptive-spam-filter
monochromegane
0
5.7k
Visual SLAM未来予測 / Future Prediction in Visual SLAM
koide3
1
1.1k
[最先端NLP勉強会2026] Checklists Are Better Than Reward Models For Aligning Language Models
nzw0301
1
320
秋葉原ウォーカブル基礎調査報告書
izumiyama_lab
1
140
TESSERA: Temporal Embeddings of Surface Spectra for Earth Representation and Analysis
satai
2
100
完全自律LLMエージェントでDIVER OSINT CTF 2026に挑戦してみた
analokmaus
0
720
長時間動画QAにおけるマルチエージェント推論 ・SVAgent: Storyline-Guided Long Video Understanding via Cross-Modal Multi-Agent Collaboration
murakawatakuya
1
210
実例から見るLLMのマンガ理解:実務VQAタスクによる長期的文脈と視覚情報の定性評価
kzmssk
0
160
最先端NLP 2026 論文紹介: Wait, Wait, Wait... Why Do Reasoning Models Loop? / SNLP Paper Review: Wait, Wait, Wait... Why Do Reasoning Models Loop?
tkng
0
250
Language and AI
ayaniwa
0
310
Featured
See All Featured
Designing for Performance
lara
611
70k
Balancing Empowerment & Direction
lara
6
1.3k
Templates, Plugins, & Blocks: Oh My! Creating the theme that thinks of everything
marktimemedia
31
2.9k
The Illustrated Guide to Node.js - THAT Conference 2024
reverentgeek
1
550
Leadership Guide Workshop - DevTernity 2021
reverentgeek
1
380
Efficient Content Optimization with Google Search Console & Apps Script
katarinadahlin
PRO
1
890
Sharpening the Axe: The Primacy of Toolmaking
bcantrill
46
3k
Easily Structure & Communicate Ideas using Wireframe
afnizarnur
194
17k
Utilizing Notion as your number one productivity tool
mfonobong
4
610
Mind Mapping
helmedeiros
1
390
AI Search: Implications for SEO and How to Move Forward - #ShenzhenSEOConference
aleyda
1
1.4k
Into the Great Unknown - MozCon
thekraken
41
2.7k
Transcript
Reinforcement Learning Based Text Style Transfer without Parallel Training Corpus
Hongyu Gong, Suma Bhat, Lingfei Wu, JinJun Xiong, Wen-mei Hwu NAACL2019読み会 紹介者: 吉村
Abstract • パラレルコーパスをつかわないテキストスタイル変換 • スタイル、意味、流暢性の評価器を報酬として強化学習 • positive-negative, informal-formal の変換タスクで SOTA
• 人手評価でも効果的であることがわかった
Introduction • パラレルコーパスでのスタイル変換は成功しているがパラレル コーパスはいつでも利用できるわけではない • 従来手法 ◦ 意味をエンコードしてスタイル情報と組み合わせてスタイ ル変換する ◦
パラメータで微分可能な損失関数に制限されている ◦ 意味とスタイルのみを学習、評価している ▪ 流暢性などの他の重要な側面は見ていない • 提案手法 ◦ パラレルコーパスを使わないスタイル変換を行う RL を用 いた学習システムを提案する ◦ 報酬にスタイルの強さ、意味の保持、流暢性を使用
Contributions • テキストスタイル変換のための RL フレームワークを提案複数 の評価指標を報酬にして学習を行う • パラレルコーパスがない問題に対処している • 意味の保持と変換の強さで
SOTA
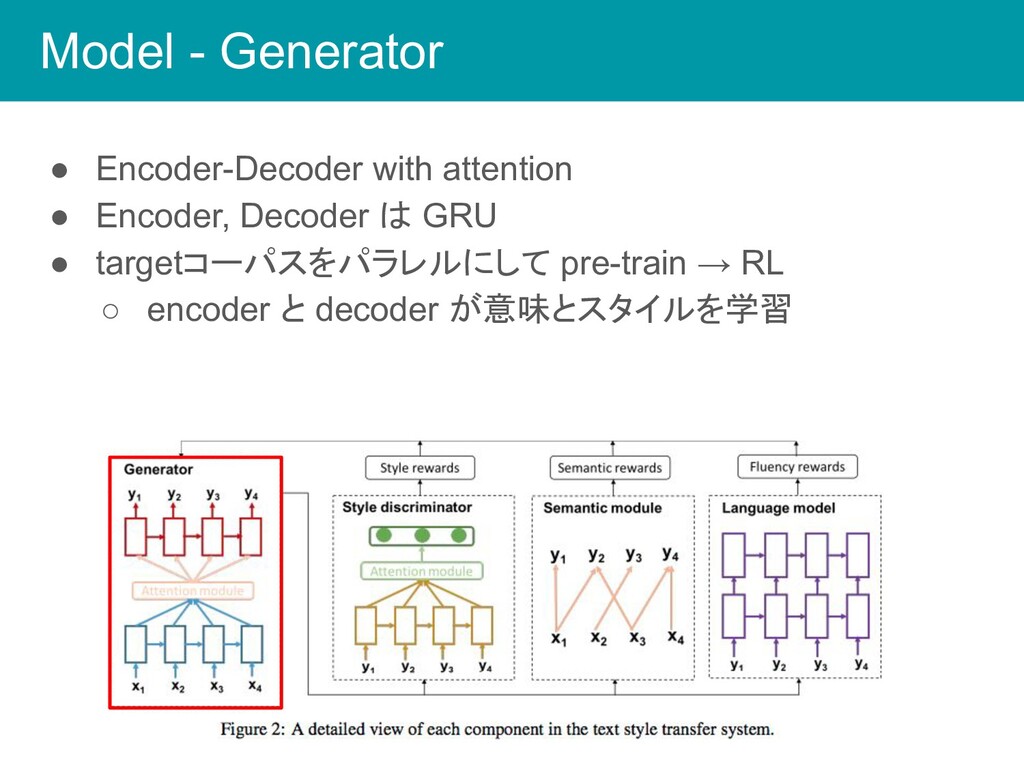
Model - Generator • Encoder-Decoder with attention • Encoder, Decoder
は GRU • targetコーパスをパラレルにして pre-train → RL ◦ encoder と decoder が意味とスタイルを学習
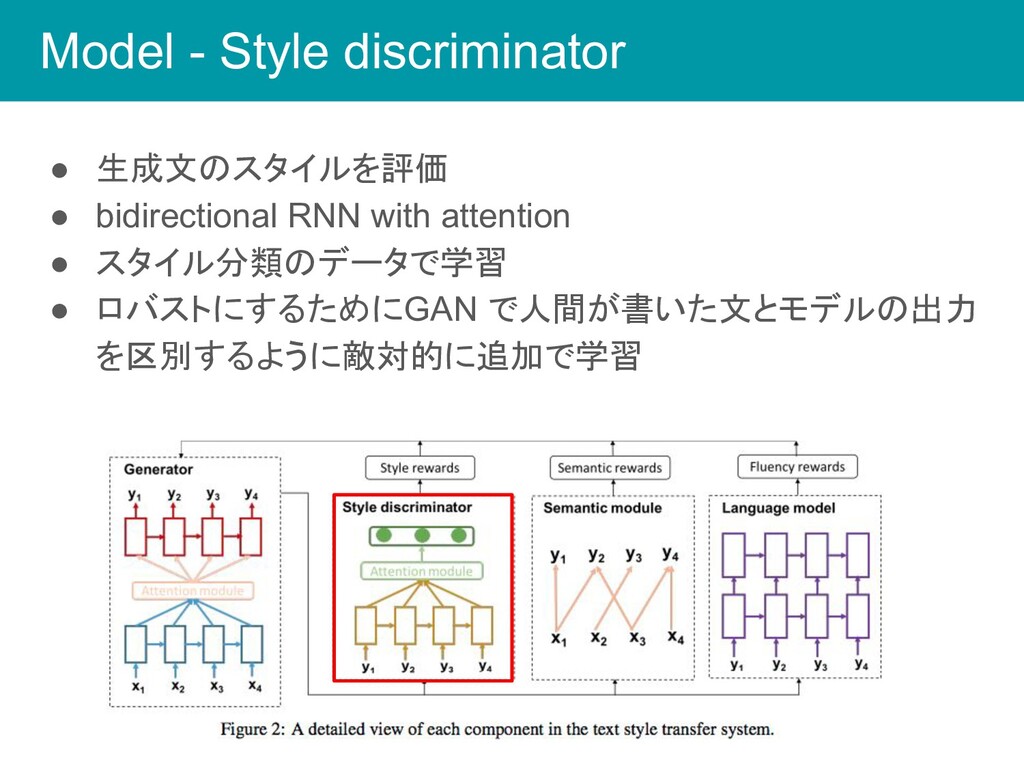
Model - Style discriminator • 生成文のスタイルを評価 • bidirectional RNN with
attention • スタイル分類のデータで学習 • ロバストにするためにGAN で人間が書いた文とモデルの出力 を区別するように敵対的に追加で学習
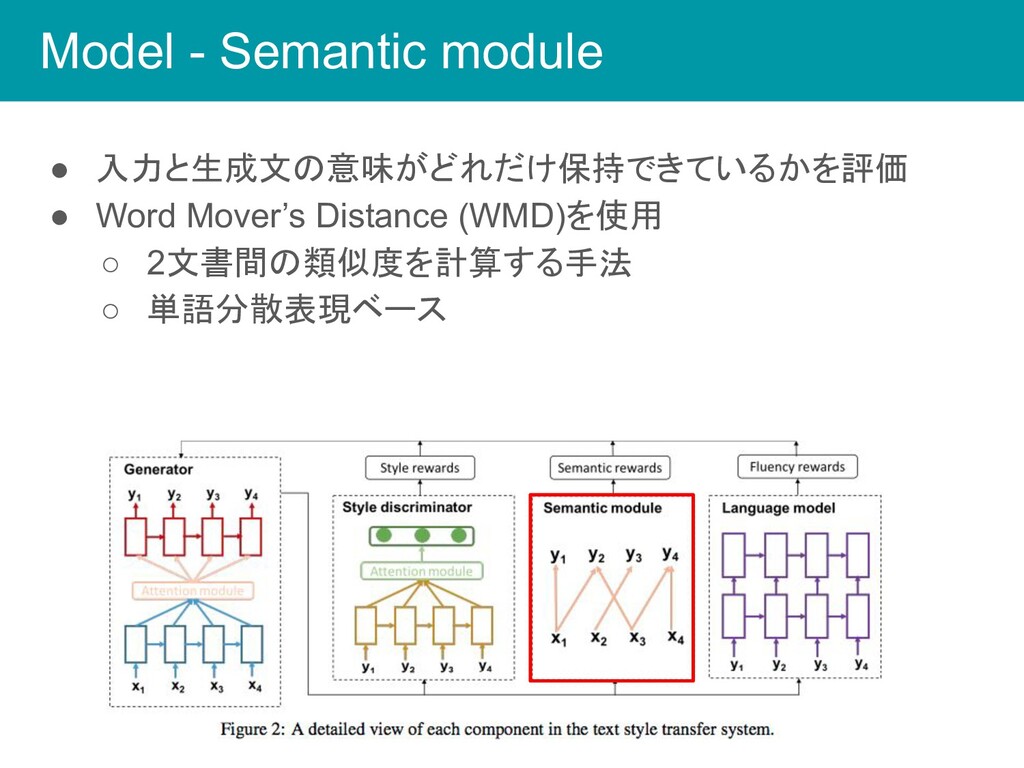
Model - Semantic module • 入力と生成文の意味がどれだけ保持できているかを評価 • Word Mover’s Distance
(WMD)を使用 ◦ 2文書間の類似度を計算する手法 ◦ 単語分散表現ベース
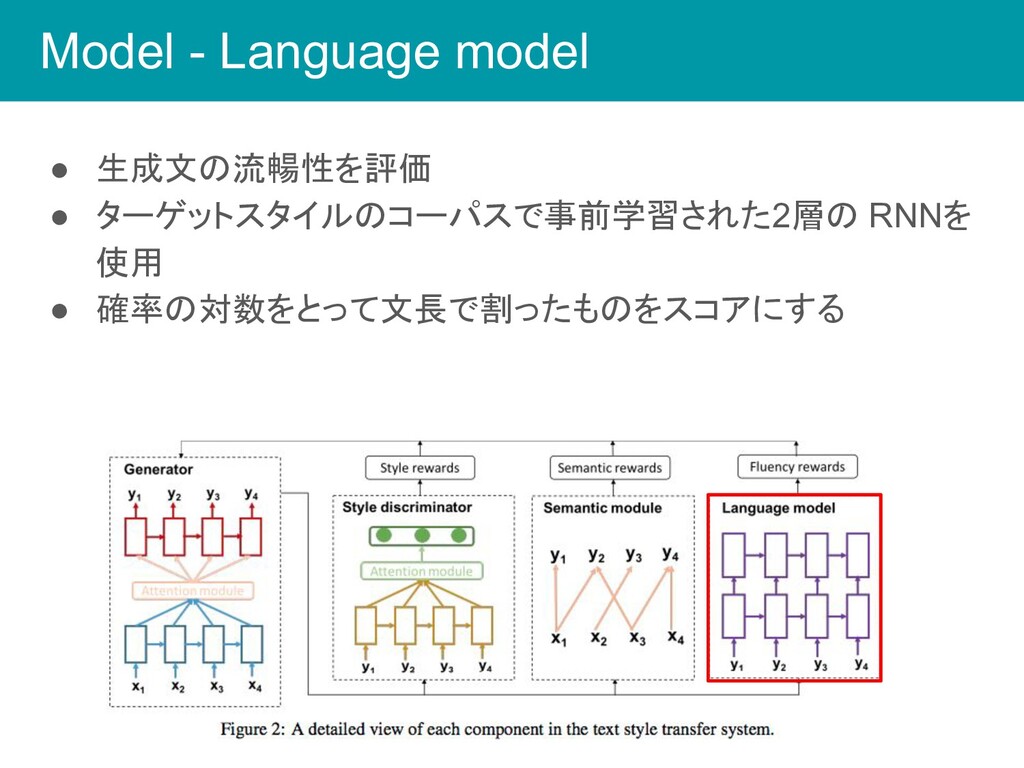
Model - Language model • 生成文の流暢性を評価 • ターゲットスタイルのコーパスで事前学習された2層の RNNを 使用
• 確率の対数をとって文長で割ったものをスコアにする
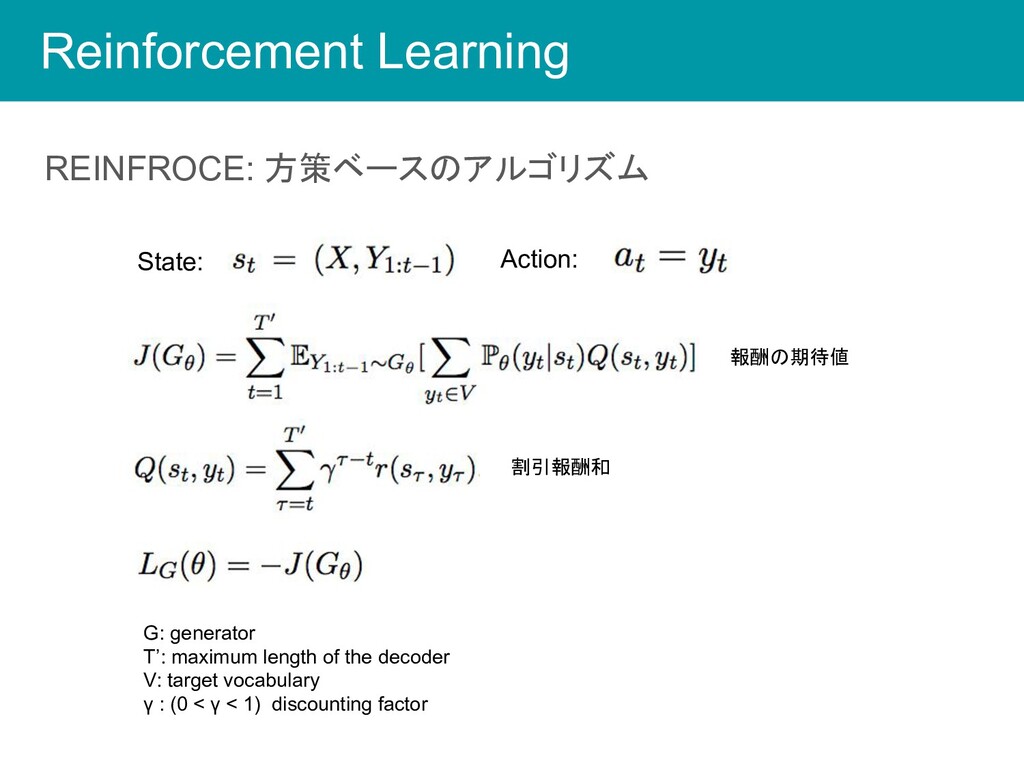
• 与えられた環境における価値を最大化するようにエージェント を学習 • 方策 π : p(a|s) ◦ 状態
s でどう行動するかを定めた確率分布 • 方策ベースと価値ベース ◦ 価値ベース: 価値関数 Q(s, a) を学習 ◦ 方策ベース: 方策を学習し、累積報酬和を最大化 Reinforcement Learning reward Enviroment Agent action state
Reinforcement Learning REINFROCE: 方策ベースのアルゴリズム G: generator T’: maximum length
of the decoder V: target vocabulary γ : (0 < γ < 1) discounting factor 割引報酬和 報酬の期待値 State: Action:
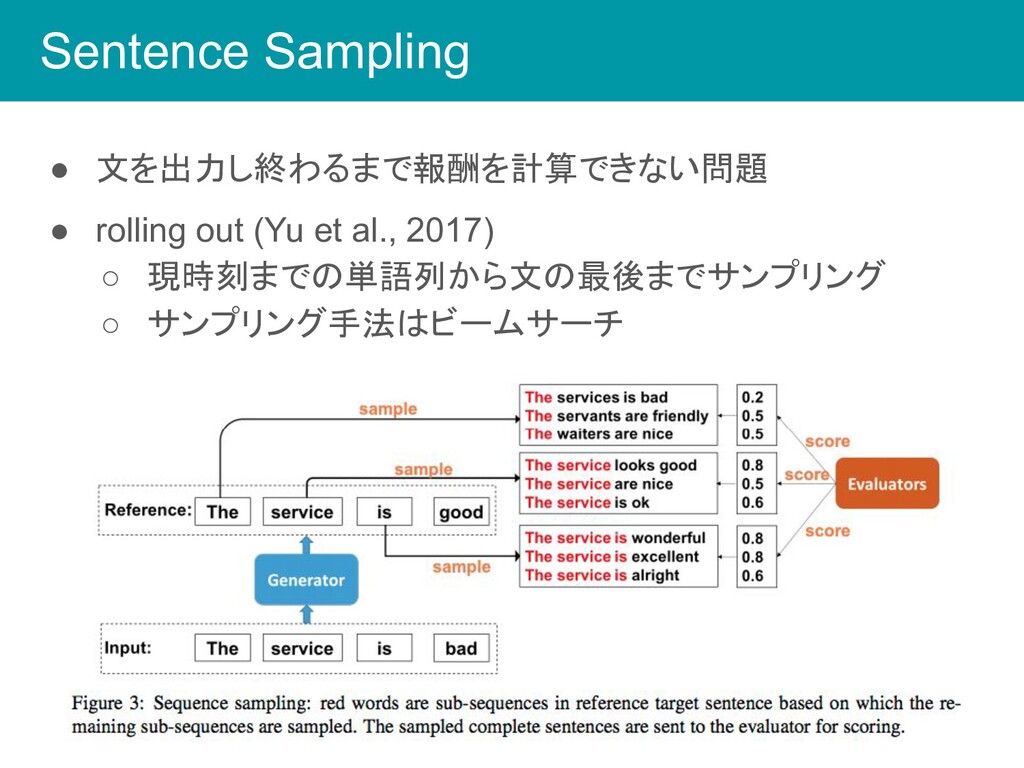
Sentence Sampling • 文を出力し終わるまで報酬を計算できない問題 • rolling out (Yu et al.,
2017) ◦ 現時刻までの単語列から文の最後までサンプリング ◦ サンプリング手法はビームサーチ •
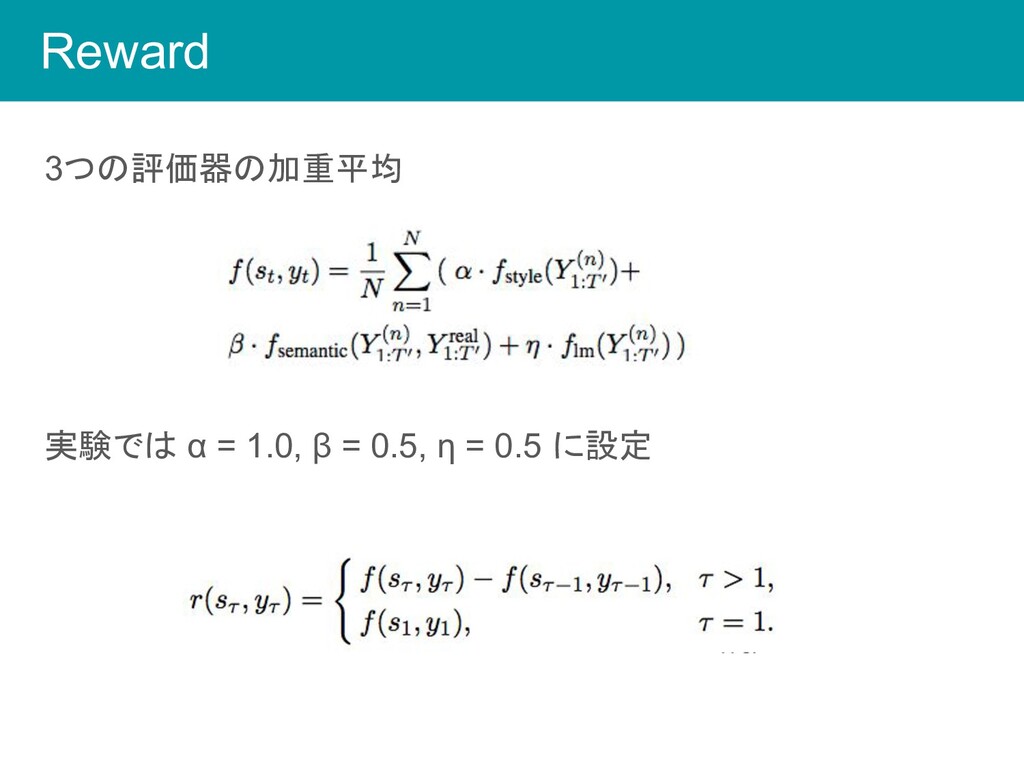
Reward 3つの評価器の加重平均 実験では α = 1.0, β = 0.5, η
= 0.5 に設定
Experiment • タスク ◦ positive - negative sentiment (ST) ◦
formal - informal (FT) • データセット ◦ ST: Yelp website (restaurant reviews) ◦ FT: Grammarly’s Yahoo Answer Fomalyty Corpus ▪ family, relationships のデータを使用
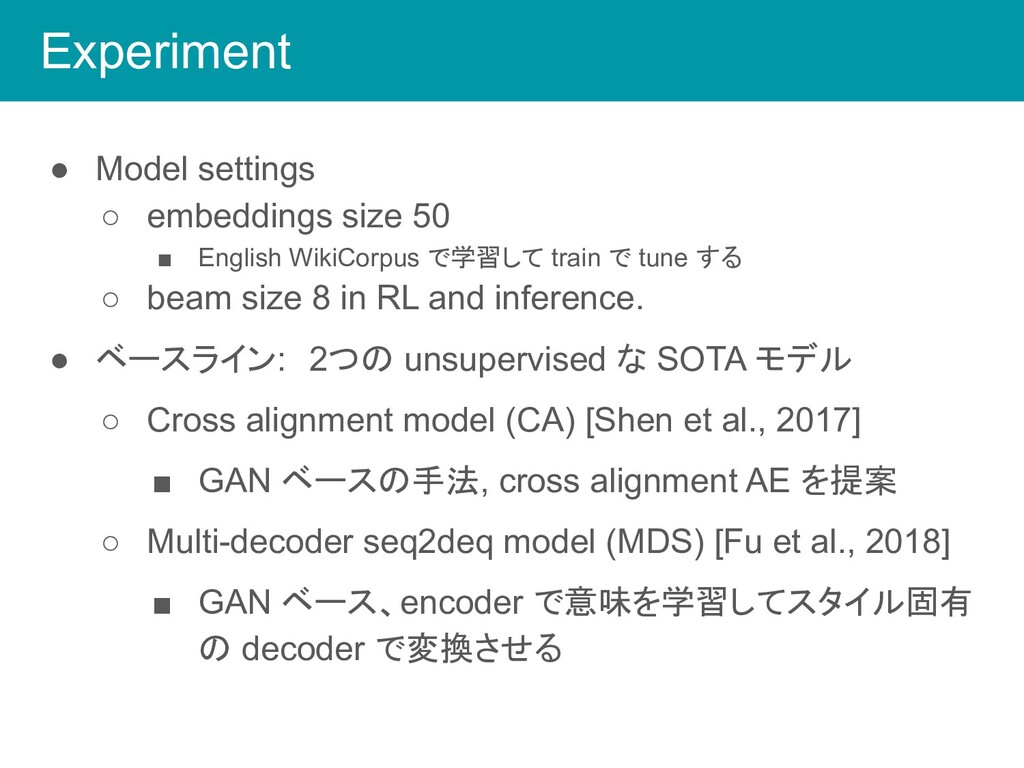
Experiment • Model settings ◦ embeddings size 50 ▪ English
WikiCorpus で学習して train で tune する ◦ beam size 8 in RL and inference. • ベースライン: 2つの unsupervised な SOTA モデル ◦ Cross alignment model (CA) [Shen et al., 2017] ▪ GAN ベースの手法, cross alignment AE を提案 ◦ Multi-decoder seq2deq model (MDS) [Fu et al., 2018] ▪ GAN ベース、encoder で意味を学習してスタイル固有 の decoder で変換させる
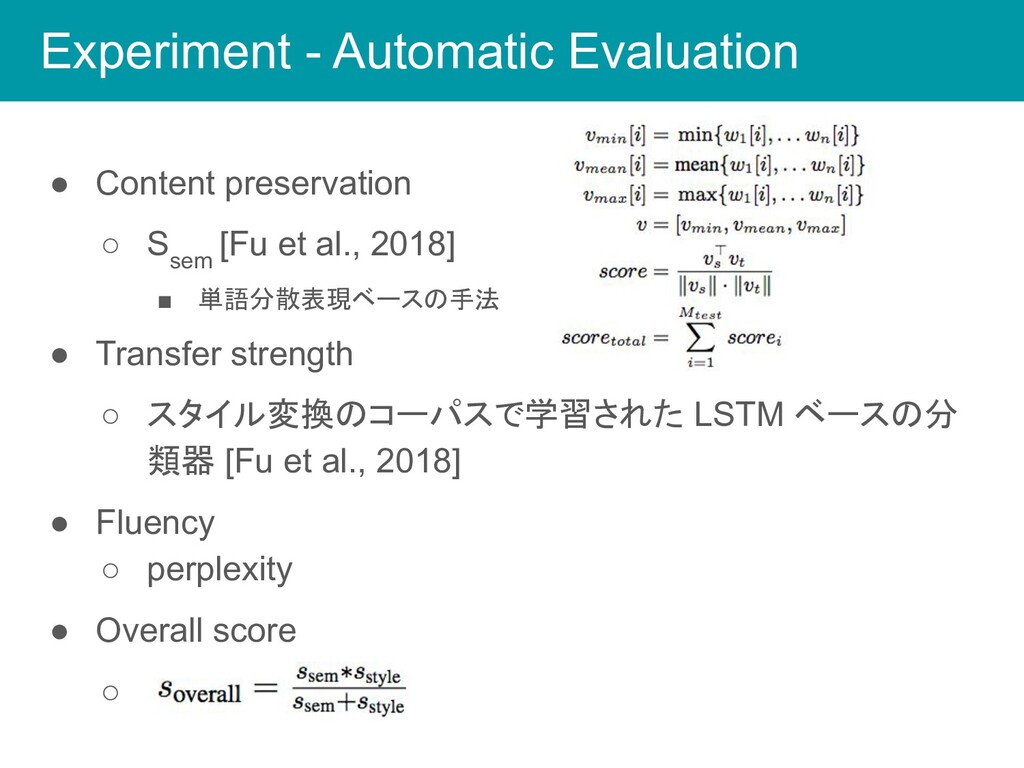
Experiment - Automatic Evaluation • Content preservation ◦ S sem
[Fu et al., 2018] ▪ 単語分散表現ベースの手法 • Transfer strength ◦ スタイル変換のコーパスで学習された LSTM ベースの分 類器 [Fu et al., 2018] • Fluency ◦ perplexity • Overall score ◦
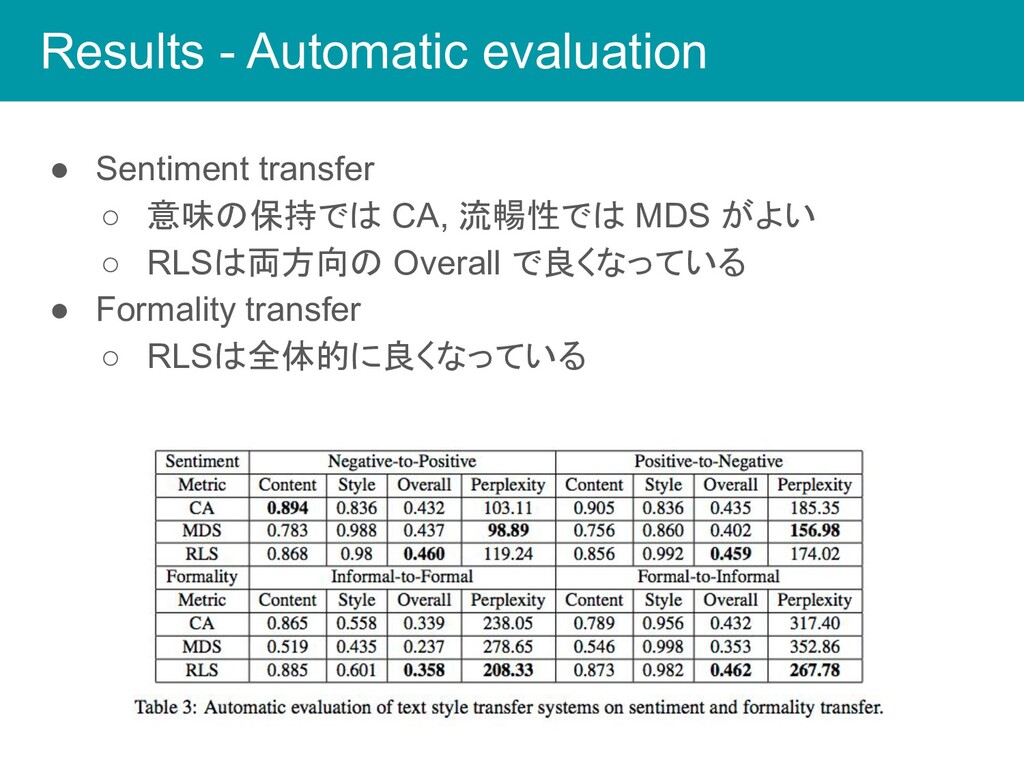
Results - Automatic evaluation • Sentiment transfer ◦ 意味の保持では CA,
流暢性では MDS がよい ◦ RLSは両方向の Overall で良くなっている • Formality transfer ◦ RLSは全体的に良くなっている
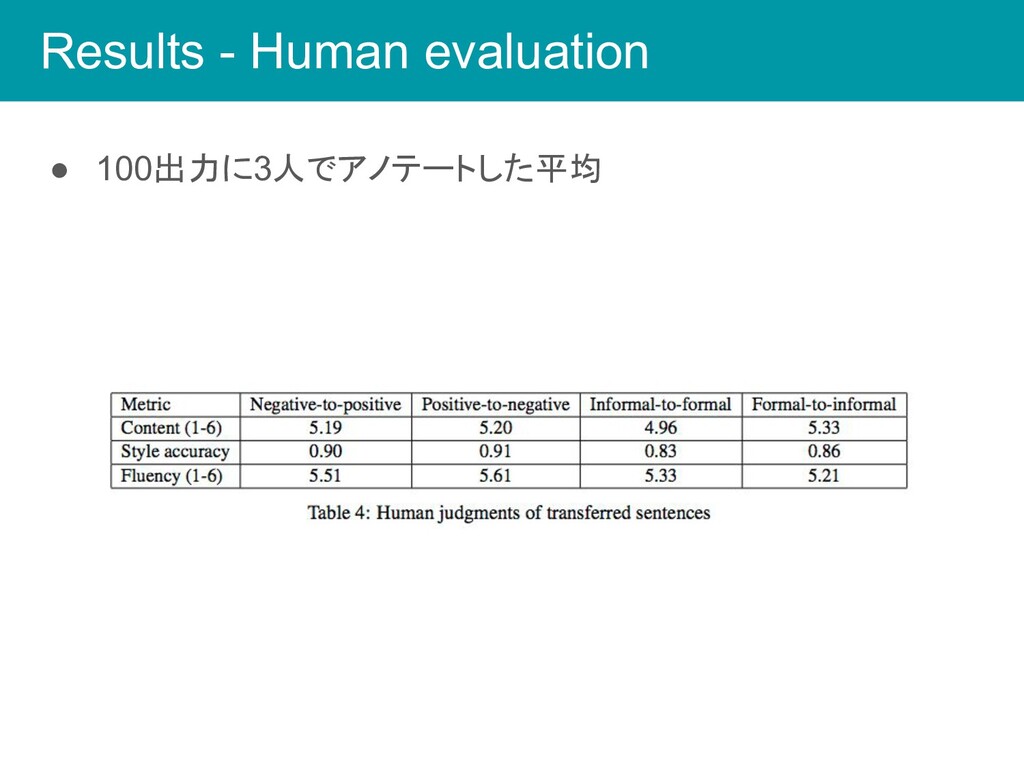
Results - Human evaluation • 100出力に3人でアノテートした平均
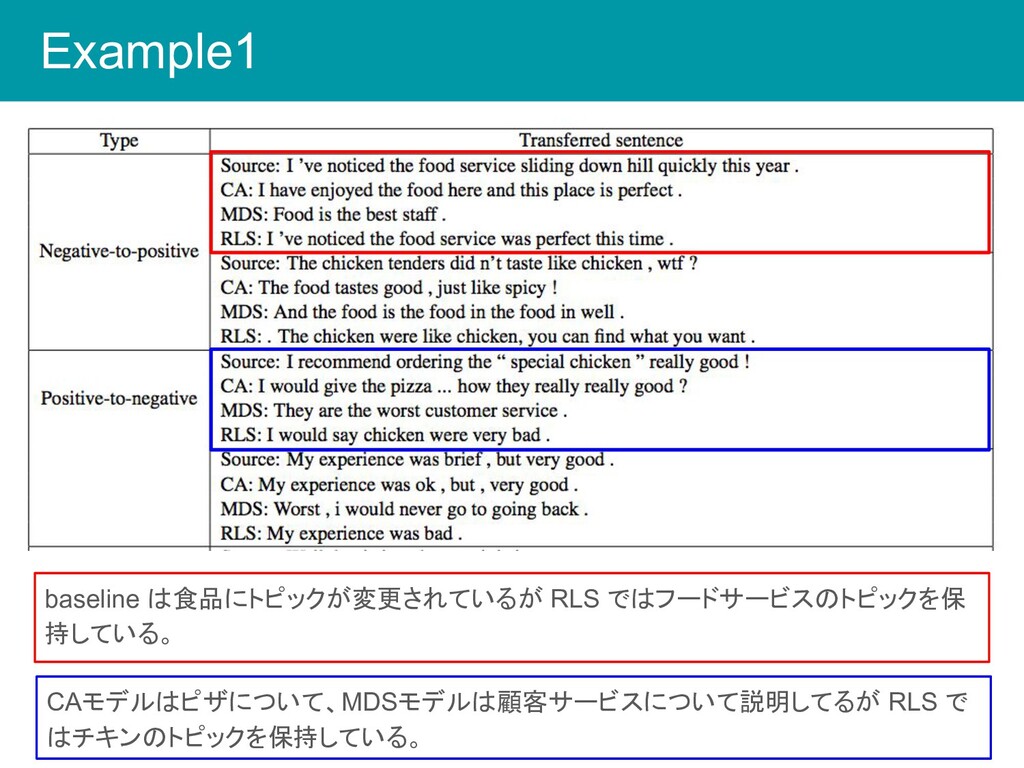
Example1 baseline は食品にトピックが変更されているが RLS ではフードサービスのトピックを保 持している。 CAモデルはピザについて、MDSモデルは顧客サービスについて説明してるが RLS で はチキンのトピックを保持している。
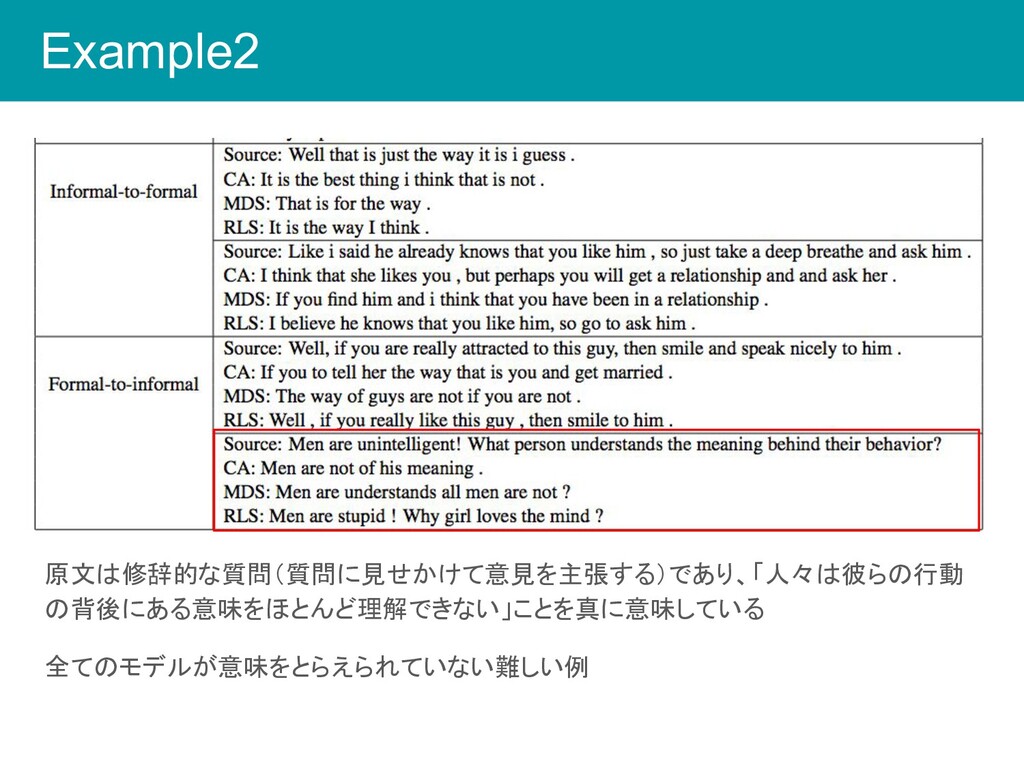
Example2 原文は修辞的な質問(質問に見せかけて意見を主張する)であり、「人々は彼らの行動 の背後にある意味をほとんど理解できない」ことを真に意味している 全てのモデルが意味をとらえられていない難しい例
Conclusions • スタイル、意味、流暢性の評価基準を組み込んだ強化学習 ベースのテキストスタイル変換システムを提案 • 2つの異なるスタイル変換タスクで自動評価および人手評価で その有用性を実証した


 kokeman
 yumaichikawa
 upura
 monochromegane
 koide3
 nzw0301
 izumiyama_lab
 satai
 analokmaus
 murakawatakuya
 kzmssk
 tkng
 ayaniwa
 lara
 marktimemedia
 reverentgeek
 katarinadahlin
 bcantrill
 afnizarnur
 mfonobong
 helmedeiros
 aleyda
 thekraken