Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Multi-Reference Training with Pseudo-References...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
ryoma yoshimura
January 23, 2019
Research
250
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Multi-Reference Training with Pseudo-References for Neural Translation and Text Generation
研究室のEMNLP読み会の発表資料です。
ryoma yoshimura
January 23, 2019
More Decks by ryoma yoshimura
See All by ryoma yoshimura
TransQuest: Translation Quality Estimation with Cross-lingual Transformers
kokeman
0
300
Automatic Machine Translation Evaluation in Many Languages via Zero-Shot Paraphrasing
kokeman
0
68
BLEURT: Learning Robust Metrics for Text Generation
kokeman
0
290
Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks
kokeman
1
900
Courteously Yours: Inducing courteous behavior in Customer Care responses using Reinforced Pointer Generator Network
kokeman
0
190
Beyond BLEU: Training Neural Machine Translation with Semantic Similarity
kokeman
0
180
Reinforcement Learning Based Text Style Transfer without Parallel Training Corpus
kokeman
0
140
タスクとデータセット紹介 GLUE, SuperGLUE
kokeman
0
1.1k
Reliability and Learnability of Human Bandit Feedback for Sequence-to-Sequence Reinforcement Learning
kokeman
0
93
Other Decks in Research
See All in Research
Physical AIでモデリングはどう変わるか/How Physical AI Will Change Modeling
stktu
0
340
AI対話に何を挟むか ― 高回転対話・デジタル摘録・手書き記録による創造体験の違い|日本創造学会2026
ishiirikie
0
200
オンライン凸最適化の基礎とゲーム理論への応用 (IBIS 2026 チュートリアル)
taira_tsuchiya
2
1.4k
超効率化への挑戦:1bit LLMの現状と展望
yumaichikawa
0
980
ふとした出会いで生まれたSkillが、 社内利用1位になるまで
mikimhk
22
25k
OWASP AISVS - C7
shiell
2
860
就労支援の現場での生成AI活用
enochan
0
200
HackSick vol.7 LT資料【LLMアーキテクチャ入門・事前学習時の躓き所解説】 スパースなAttention・状態空間モデル
rikkabotan7
0
240
Kaggle|AI Agent Security — しくじり先生、俺みたいになるな
pomcho555
1
140
The Conductor Pattern -Multi-Granularity Feedback for Creative Agents-
shibuiwilliam
2
120
CDCL を用いた MILP の厳密解法
imai448
0
330
Pesée et pointage par imagerie 3D : PHENO3D entre en phase de test terrains
institutdelelevage
PRO
0
110
Featured
See All Featured
Music & Morning Musume
bryan
48
7.5k
B2B Lead Gen: Tactics, Traps & Triumph
marketingsoph
1
300
<Decoding/> the Language of Devs - We Love SEO 2024
nikkihalliwell
1
380
Facilitating Awesome Meetings
lara
57
7.2k
Save Time (by Creating Custom Rails Generators)
garrettdimon
PRO
33
5.7k
Balancing Empowerment & Direction
lara
6
1.4k
A better future with KSS
kneath
240
18k
My Coaching Mixtape
mlcsv
0
380
Lightning talk: Run Django tests with GitHub Actions
sabderemane
0
320
The untapped power of vector embeddings
frankvandijk
2
2k
A Guide to Academic Writing Using Generative AI - A Workshop
ks91
PRO
1
560
How Software Deployment tools have changed in the past 20 years
geshan
3
35k
Transcript
Multi-Reference Training with Pseudo-References for Neural Translation and Text Generation
Renji Zheng, Mingbo Ma, Liang Huang EMNLP2018 研究室EMNLP読み会 紹介者 吉村
概要 • 複数のリファレンスでモデルを学習 ◦ テキスト生成の正解は1つではないので複数あったほうがいい ◦ 複数のリファレンスがあるデータセットを使用 • 複数のリファレンスから lattice
を作ってさらに多くの擬似リファ レンスを作成 ◦ 4~5個のリファレンスでは潜在的なリファレンスをカバーできない
Main Contributions • 機械翻訳と画像キャプションにおいてマルチリファレンスでの 学習法を3つ調査 • 複数の参照訳を lattice にするための新しいネットワークベー スの複数の系列アラインメントモデルを提案
• 擬似リファレンスでを用いた学習でMTでBLEUが+1.5、画像 キャプションでBLEUが+3.1、CIDErで+11.7
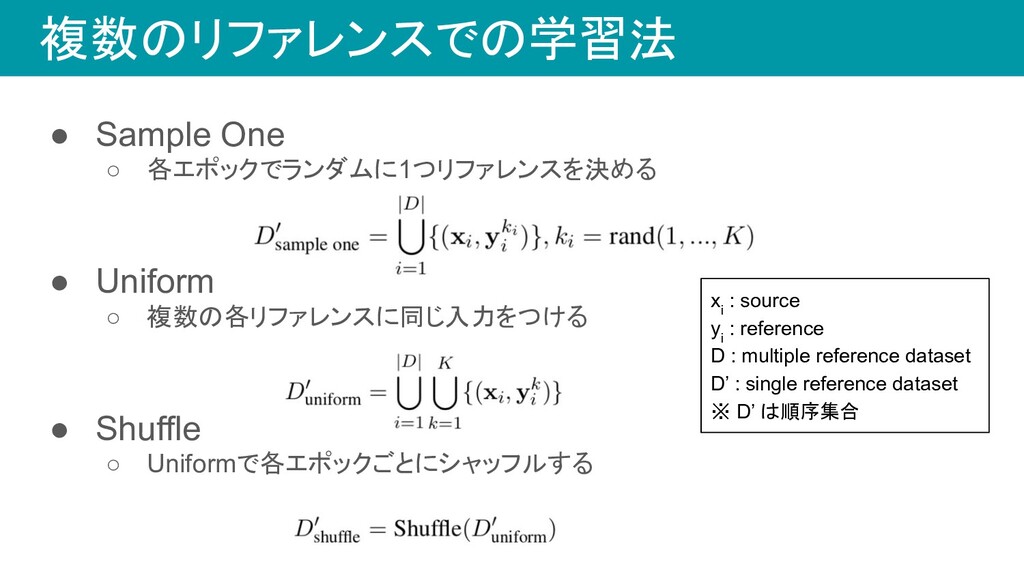
複数のリファレンスでの学習法 • 学習データを変えるだけでモデルは変更しなくていい • 複数のリファレンスがあるデータセットをシングルリファレンス のデータセットに変換 • 作り方はSample One、Uniform、Shuffleの3つ
複数のリファレンスでの学習法 • Sample One ◦ 各エポックでランダムに1つリファレンスを決める • Uniform ◦ 複数の各リファレンスに同じ入力をつける
• Shuffle ◦ Uniformで各エポックごとにシャッフルする x i : source y i : reference D : multiple reference dataset D’ : single reference dataset ※ D’ は順序集合
擬似リファレンスの作り方 • 複数のリファレンスから lattice を構築してそれをたどることで 擬似リファレンスを生成 ◦ 似た単語をマージする ◦ 元のリファレンスとBLEUを測って高いものを採用
• Hard alignと Soft align がある
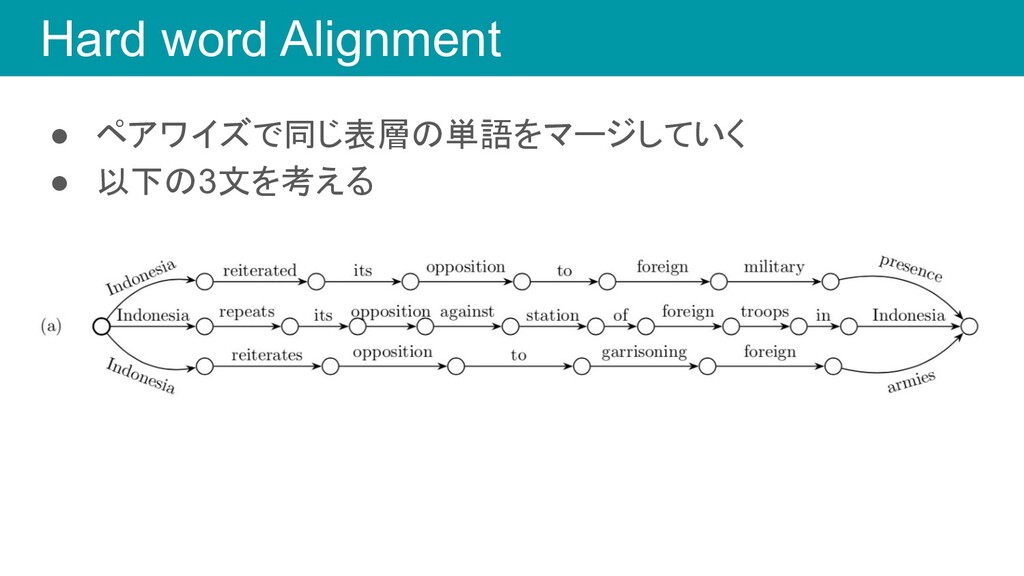
Hard word Alignment • ペアワイズで同じ表層の単語をマージしていく • 以下の3文を考える
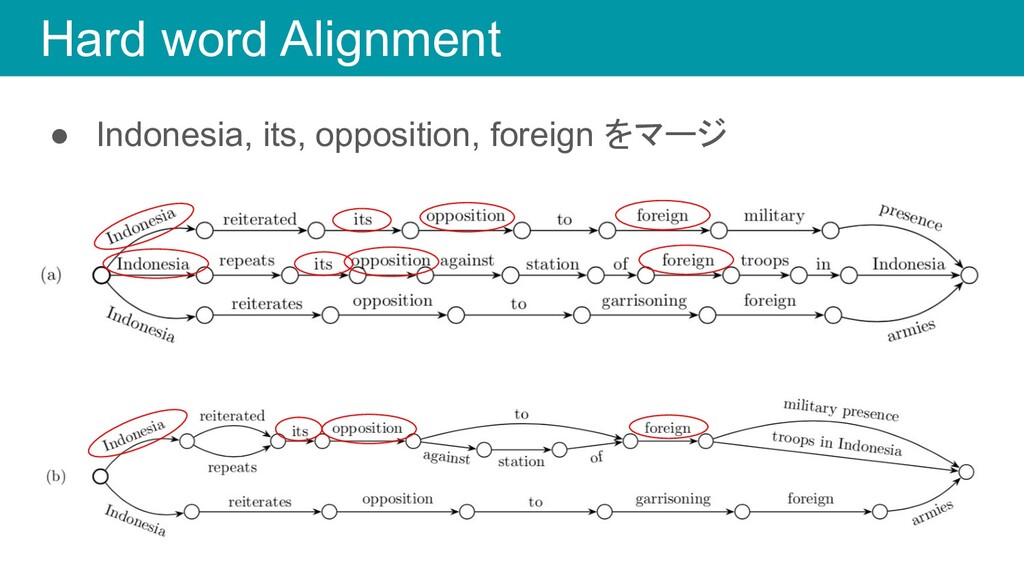
Hard word Alignment • Indonesia, its, opposition, foreign をマージ
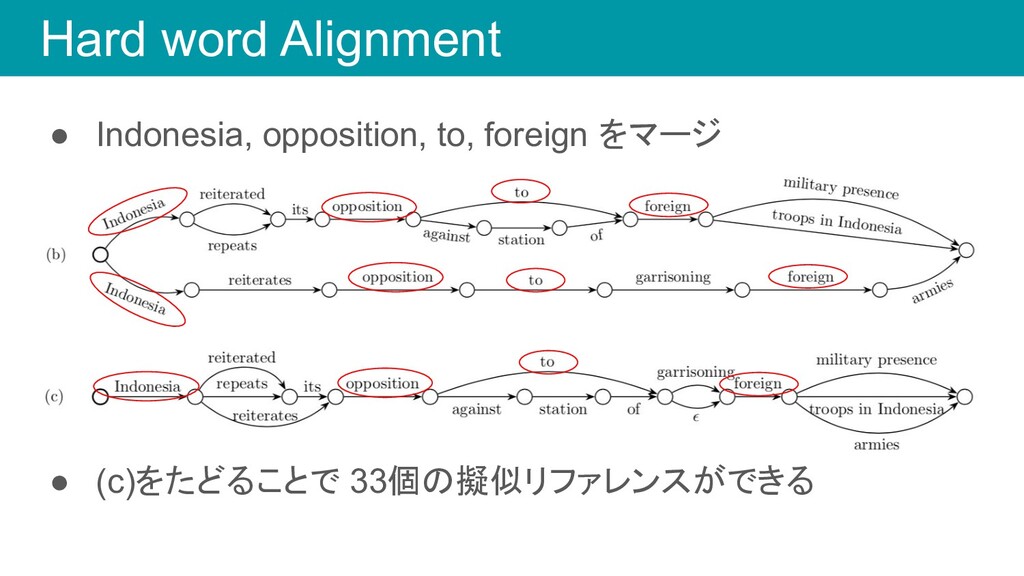
Hard word Alignment • Indonesia, opposition, to, foreign をマージ •
(c)をたどることで 33個の擬似リファレンスができる
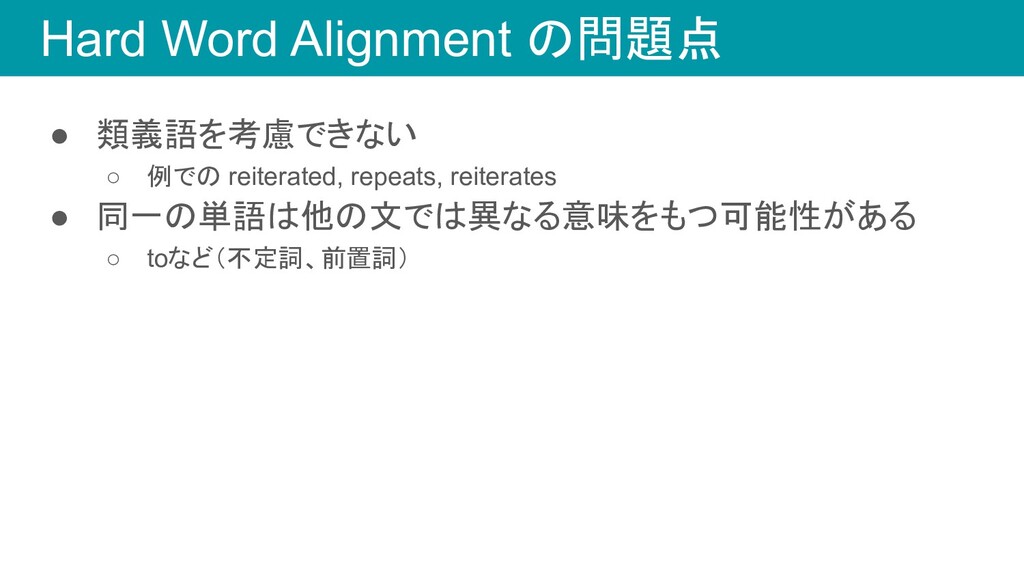
Hard Word Alignment の問題点 • 類義語を考慮できない ◦ 例での reiterated, repeats,
reiterates • 同一の単語は他の文では異なる意味をもつ可能性がある ◦ toなど(不定詞、前置詞)
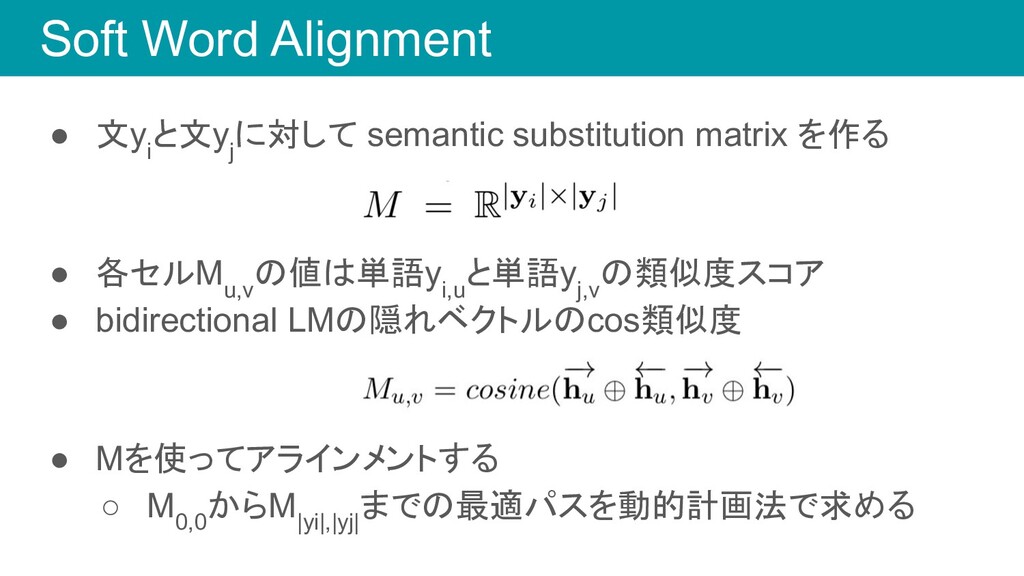
Soft Word Alignment • 文y i と文y j に対して semantic
substitution matrix を作る • 各セルM u,v の値は単語y i,u と単語y j,v の類似度スコア • bidirectional LMの隠れベクトルのcos類似度 • Mを使ってアラインメントする ◦ M 0,0 からM |yi|,|yj| までの最適パスを動的計画法で求める
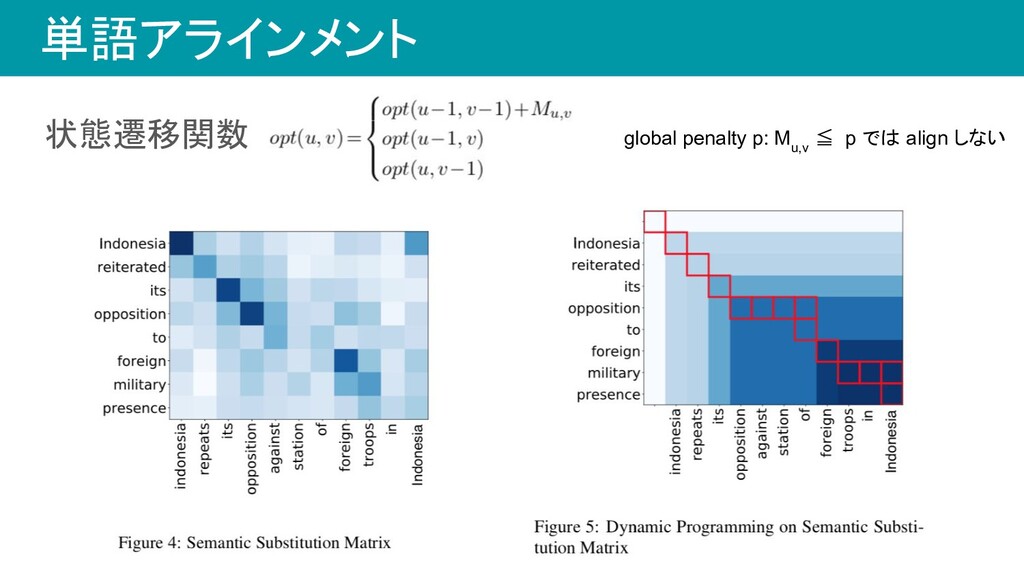
単語アラインメント 状態遷移関数 global penalty p: M u,v ≦ p では
align しない
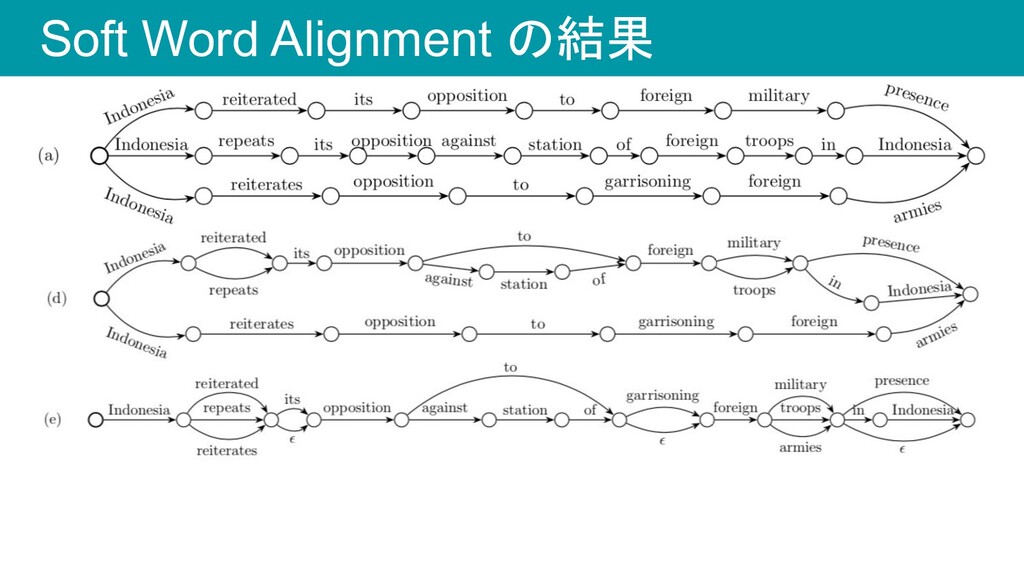
Soft Word Alignment の結果
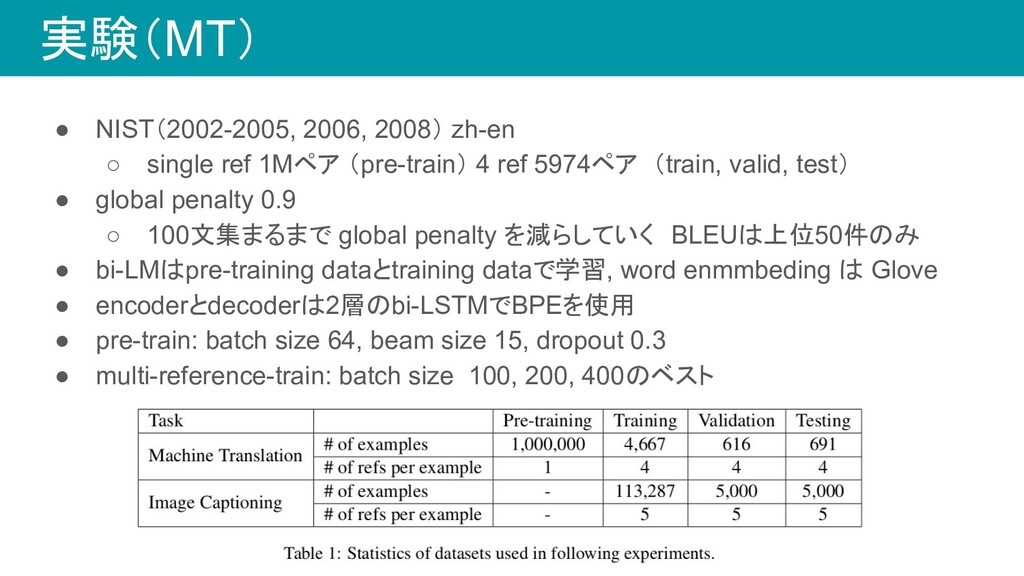
実験(MT) • NIST(2002-2005, 2006, 2008) zh-en ◦ single ref 1Mペア
(pre-train) 4 ref 5974ペア (train, valid, test) • global penalty 0.9 ◦ 100文集まるまで global penalty を減らしていく BLEUは上位50件のみ • bi-LMはpre-training dataとtraining dataで学習, word enmmbeding は Glove • encoderとdecoderは2層のbi-LSTMでBPEを使用 • pre-train: batch size 64, beam size 15, dropout 0.3 • multi-reference-train: batch size 100, 200, 400のベスト
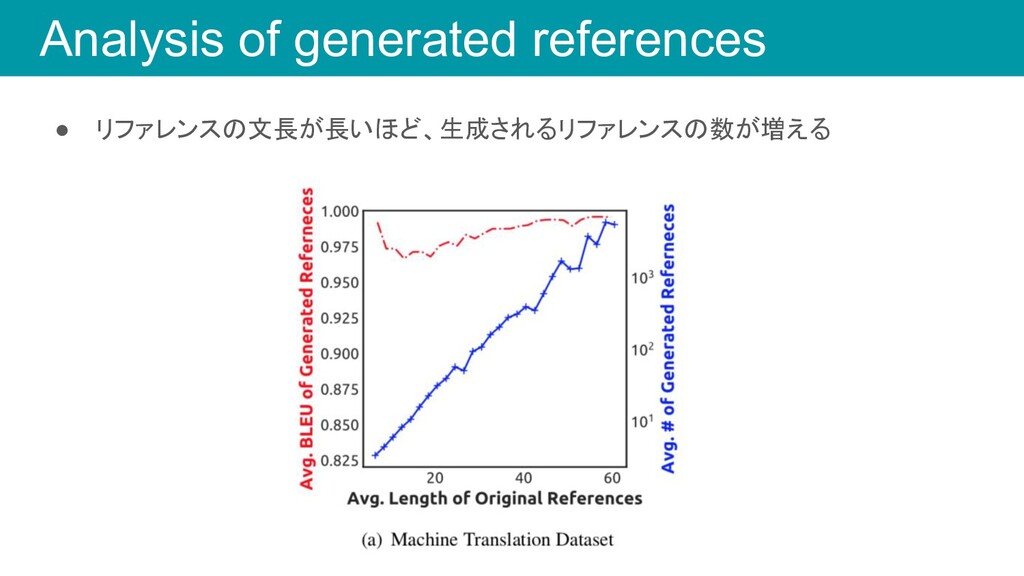
Analysis of generated references • リファレンスの文長が長いほど、生成されるリファレンスの数が増える
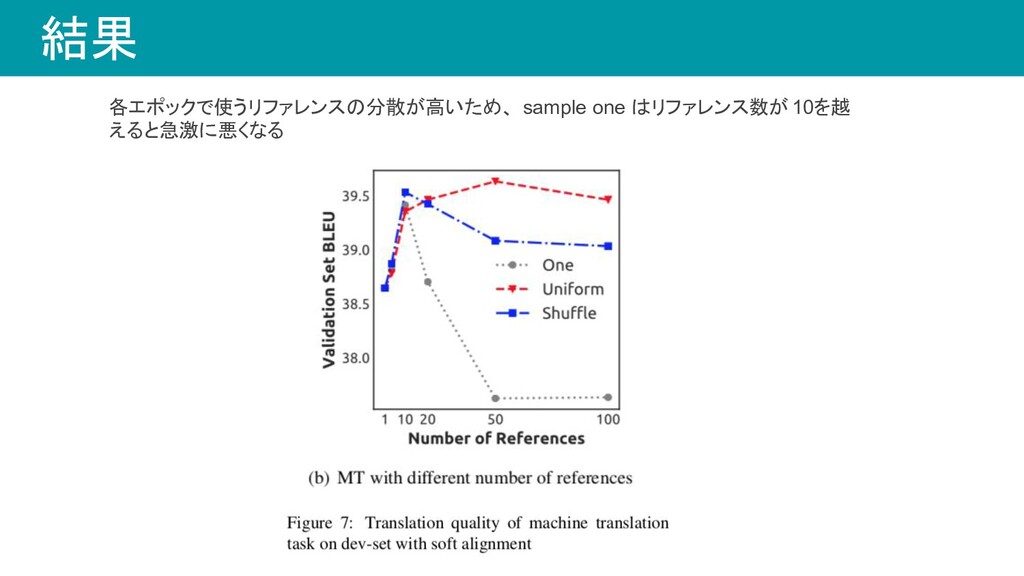
結果
結果 各エポックで使うリファレンスの分散が高いため、 sample one はリファレンス数が10を越 えると急激に悪くなる
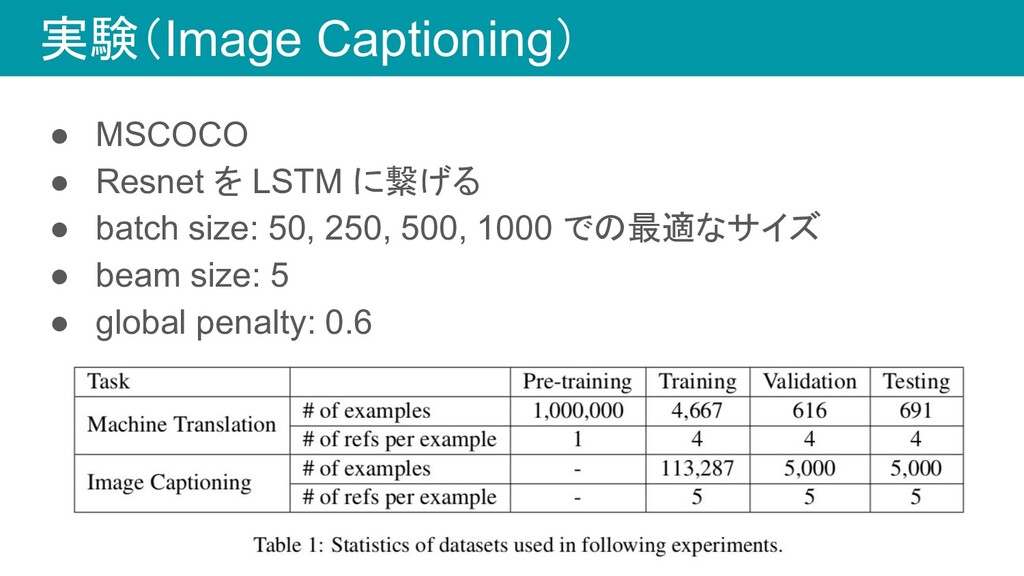
実験(Image Captioning) • MSCOCO • Resnet を LSTM に繋げる •
batch size: 50, 250, 500, 1000 での最適なサイズ • beam size: 5 • global penalty: 0.6
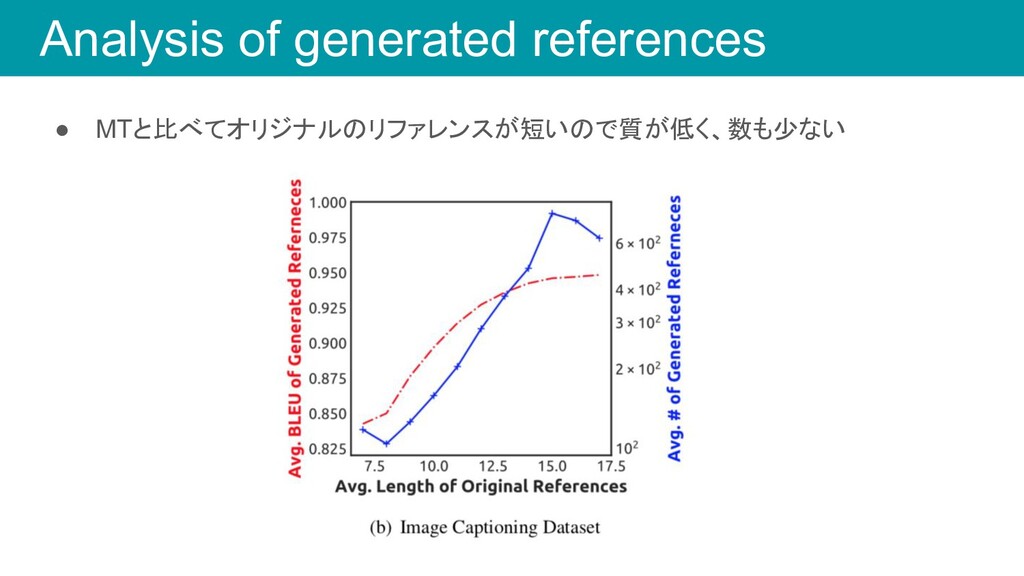
Analysis of generated references • MTと比べてオリジナルのリファレンスが短いので質が低く、数も少ない
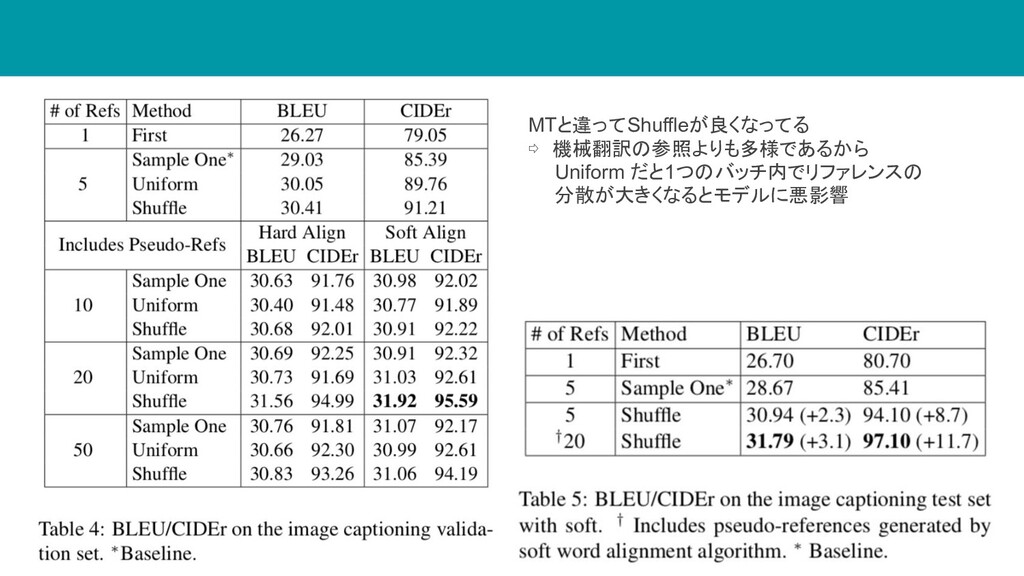
MTと違ってShuffleが良くなってる ⇨ 機械翻訳の参照よりも多様であるから Uniform だと1つのバッチ内でリファレンスの 分散が大きくなるとモデルに悪影響
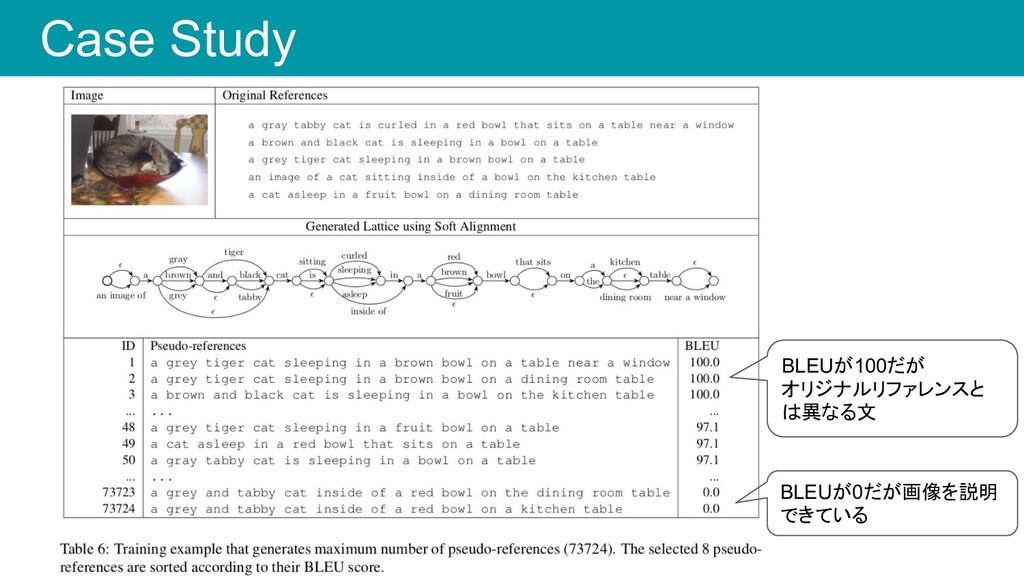
Case Study BLEUが100だが オリジナルリファレンスと は異なる文 BLEUが0だが画像を説明 できている
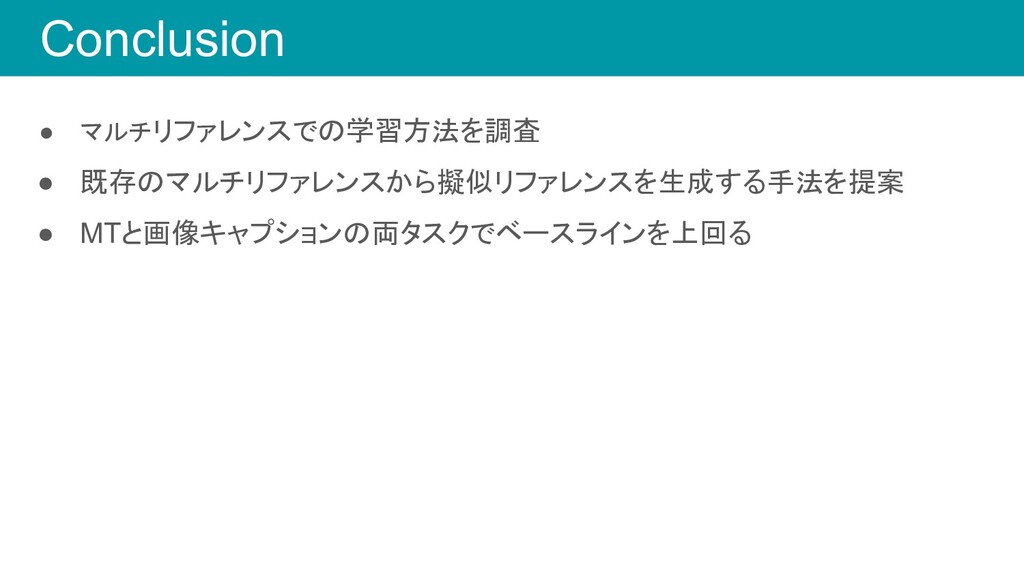
Conclusion • マルチリファレンスでの学習方法を調査 • 既存のマルチリファレンスから擬似リファレンスを生成する手法を提案 • MTと画像キャプションの両タスクでベースラインを上回る


 kokeman
 stktu
 ishiirikie
 taira_tsuchiya
 yumaichikawa
 mikimhk
 shiell
 enochan
 rikkabotan7
 pomcho555
 shibuiwilliam
 imai448
 institutdelelevage
 bryan
 marketingsoph
 nikkihalliwell
 lara
 garrettdimon
 kneath
 mlcsv
 sabderemane
 frankvandijk
 ks91
 geshan