Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Liu et al., 2021. Pay Attention to MLPs. arXiv
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
tosho
May 27, 2021
Research
210
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Liu et al., 2021. Pay Attention to MLPs. arXiv
https://arxiv.org/abs/2105.08050
tosho
May 27, 2021
More Decks by tosho
See All by tosho
LayerXにおけるセキュリティ管理の現在地と次の一手
tosho
0
640
Experts, Errors, and Context: A Large-Scale Study of Human Evaluation for Machine Translation
tosho
0
340
Good for Misconceived Reasons: An Empirical Revisiting on the Need for Visual Context in Multimodal Machine Translation
tosho
0
400
Shaham and Levy, 2021. Neural Machine Translation without Embeddings. NAACL2021
tosho
0
140
Huang et al. 2020 Unsupervised Multimodal Neural Machine Translation with Pseudo Visual Pivoting
tosho
0
510
Ive, Madhyastha, Specia_2019_EMNLP_Deep Copycat Networks for Text-to-Text Generation
tosho
0
190
Tan, Bansal_2019_EMNLP_LXMERT Learning Cross-Modality Encoder Representations from Transformers
tosho
0
300
Tsai et al._2019_ACL_Multimodal Transformer for Unaligned Multimodal Language Sequences
tosho
0
480
Zhou et al. 2019. Density Matching for Bilingual Word Embedding. NAACL
tosho
3
350
Other Decks in Research
See All in Research
最先端NLP勉強会2026 論文紹介:Reasoning with Sampling: Your Base Model is Smarter Than You Think (ICLR 2026 paper)
kogoro
4
720
SAM3を用いたコマ・吹き出しの 領域検出と分割構造からの読み順推定
kzmssk
0
190
CDCL を用いた MILP の厳密解法
imai448
0
310
Karkada さんの論文 × 2 の紹介: (1) Closed-Form Training Dynamics Reveal Learned Features and Linear Structure in Word2Vec-like Models, (2) Symmetry in language statistics shapes the geometry of model representations
eumesy
PRO
1
860
生成AIなんでも展示会vol6 LT登壇資料 NexteraBERT
rikkabotan7
0
190
La génomique au service de la fromageabilité du lait grâce aux spectres MIR
institutdelelevage
PRO
0
180
視覚若手の会LENSって何??
mickey_0226
0
360
某助成金プロジェクト採択に向けて企業研究所のアウトリーチ専任者がやったこと
afroscript
0
200
論文紹介: Understanding Epistemic Language with a Language-augmented Bayesian Theory of Mind
hisaokatsumi
0
200
湯村研究室の紹介2026 / yumulab2026
yumulab
0
140
Volatilité des marchés et sécheresse historique, l’élevage bovin viande sous contraintes en 2026
institutdelelevage
PRO
0
130
SLAMはどこまで解決されたのか?
tomonom
0
1.5k
Featured
See All Featured
I Don’t Have Time: Getting Over the Fear to Launch Your Podcast
jcasabona
35
2.9k
Accessibility Awareness
sabderemane
1
250
Building a Modern Day E-commerce SEO Strategy
aleyda
45
9.3k
Utilizing Notion as your number one productivity tool
mfonobong
4
620
Performance Is Good for Brains [We Love Speed 2024]
tammyeverts
12
1.9k
Cheating the UX When There Is Nothing More to Optimize - PixelPioneers
stephaniewalter
287
14k
Getting science done with accelerated Python computing platforms
jacobtomlinson
2
540
How People are Using Generative and Agentic AI to Supercharge Their Products, Projects, Services and Value Streams Today
helenjbeal
2
360
We Analyzed 250 Million AI Search Results: Here's What I Found
joshbly
2
2k
AI: The stuff that nobody shows you
jnunemaker
PRO
10
1.2k
GraphQLとの向き合い方2022年版
quramy
50
15k
SEO for Brand Visibility & Recognition
aleyda
0
4.8k
Transcript
Pay Attention to MLPs Hanxiao Liu, Zihang Dai, David R.
So, Quoc V. Le 紹介者:平澤 寅庄 東京都立大学大学院 小町研究室 D1 2021年5月27日 @論文読み会
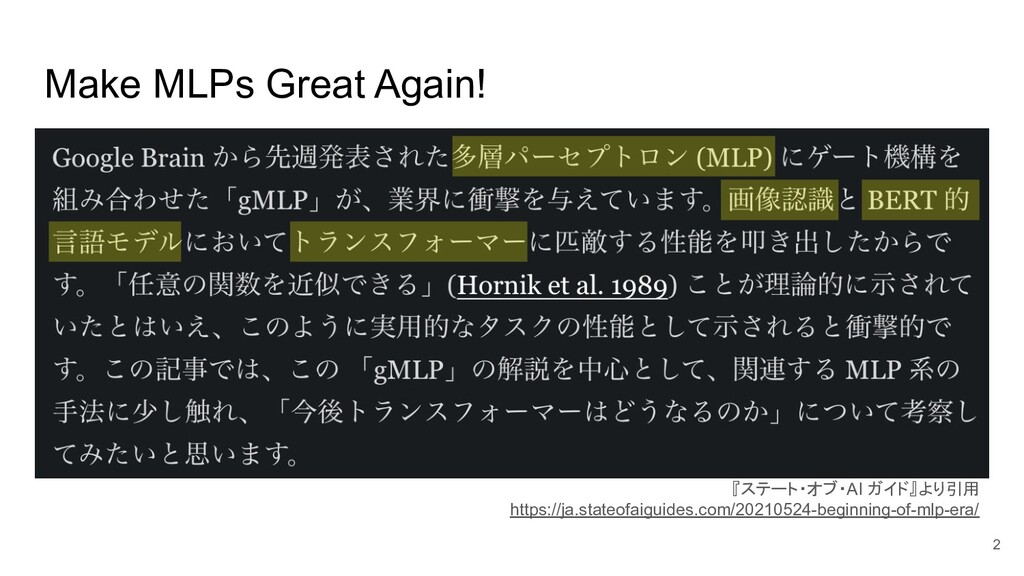
Make MLPs Great Again! 『ステート・オブ・AI ガイド』より引用 https://ja.stateofaiguides.com/20210524-beginning-of-mlp-era/ 2
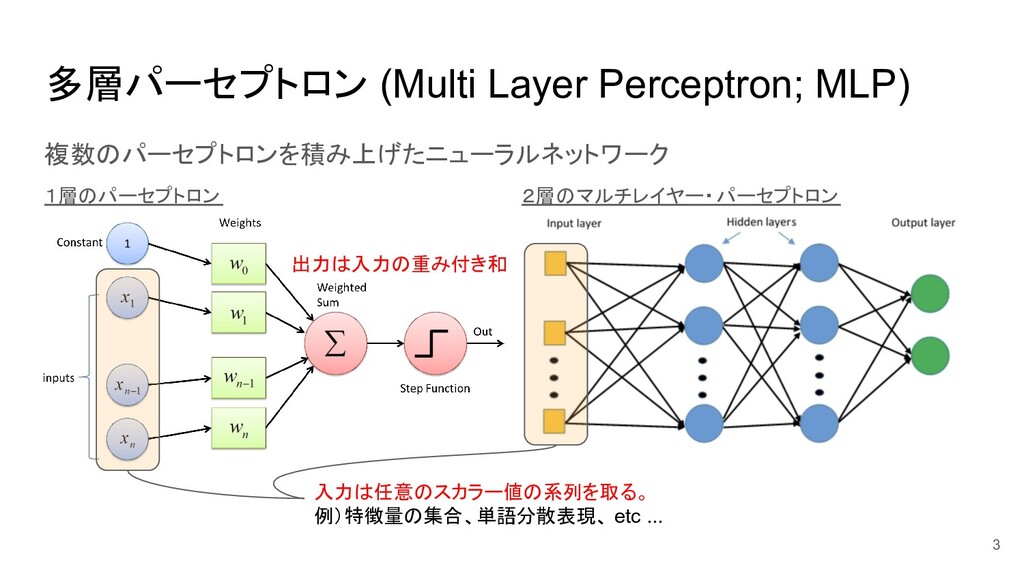
多層パーセプトロン (Multi Layer Perceptron; MLP) 複数のパーセプトロンを積み上げたニューラルネットワーク 1層のパーセプトロン 2層のマルチレイヤー・パーセプトロン 入力は任意のスカラー値の系列を取る。 例)特徴量の集合、単語分散表現、
etc ... 出力は入力の重み付き和 3
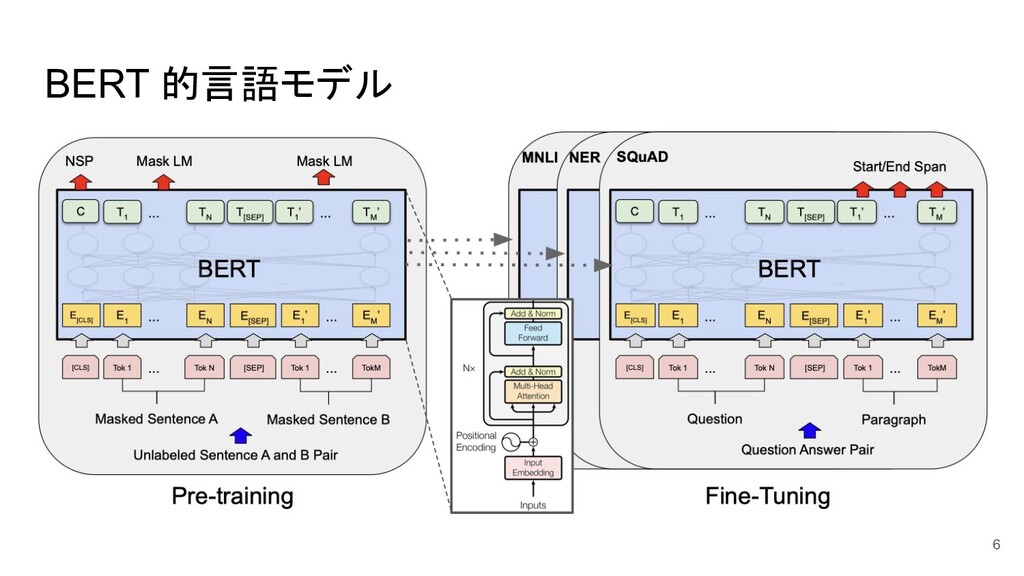
トランスフォーマー(Transformer) Vaswani et al., 2017 が提案した Encoder-Decoder 系列変換モデル • Multi-Head
Attention を導入することで、 全トークンの状態を並列で計算すること ができるようになった ◦ 各位置の状態は入力されるベクトル列の 重み付き和(重み=Attention)で計算する ◦ それまで主流だった RNN(再帰ニューラル ネットワーク)は順番にトークンごとの 状態を計算する必要があった • Positional Encoding でトークンの位置情報を組み込む • BERT的言語モデルは Encoder 側のみを使う Encoder Decoder 重みを計算 4
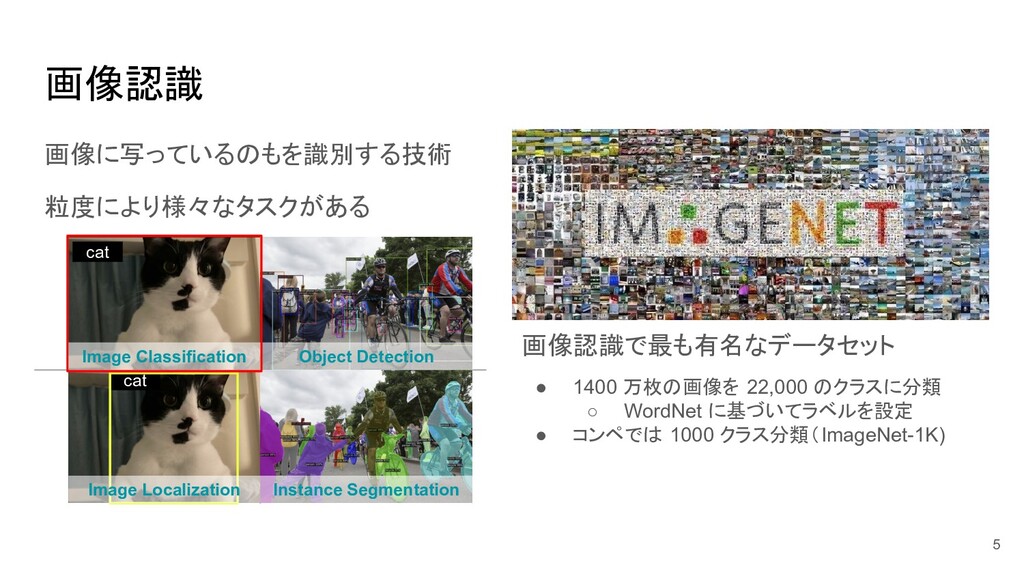
画像認識 画像に写っているのもを識別する技術 粒度により様々なタスクがある cat Image Localization Object Detection Instance Segmentation
画像認識で最も有名なデータセット • 1400 万枚の画像を 22,000 のクラスに分類 ◦ WordNet に基づいてラベルを設定 • コンペでは 1000 クラス分類(ImageNet-1K) cat Image Classification 5
BERT 的言語モデル 6
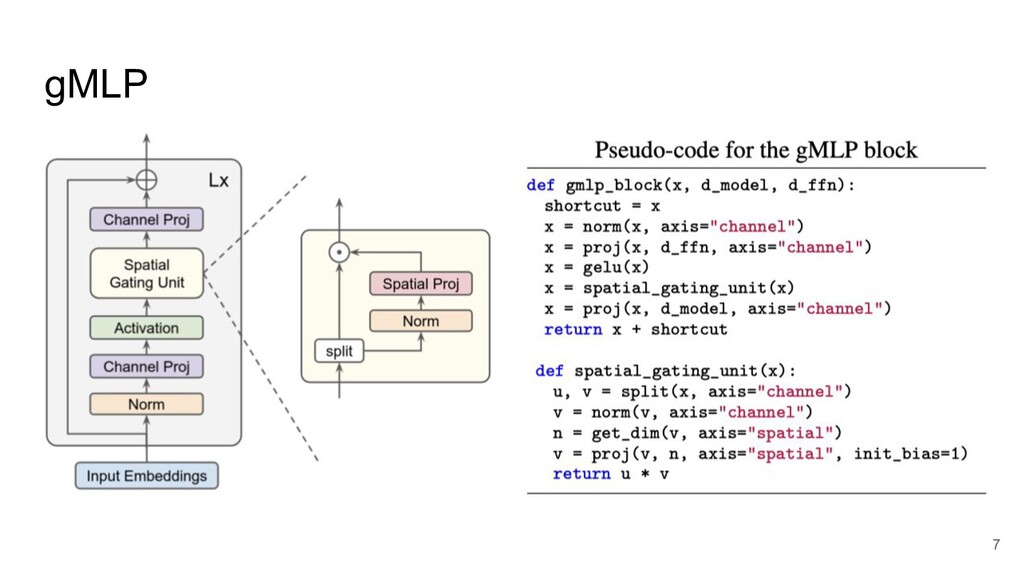
gMLP 7
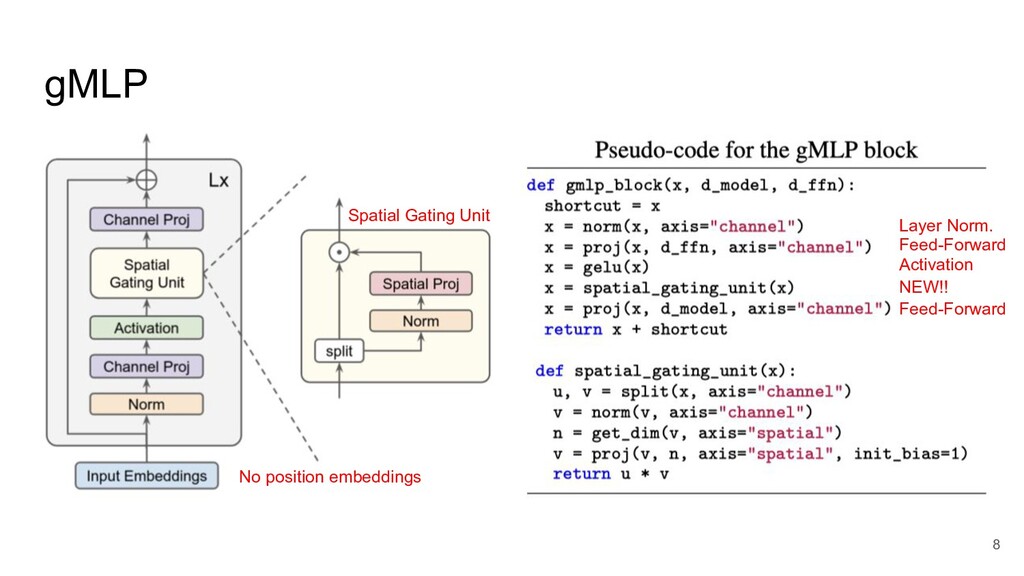
gMLP Layer Norm. Feed-Forward Activation NEW!! Feed-Forward Spatial Gating Unit
No position embeddings 8
Spatial Gating Unit トークン間インタラクションを担うモジュール 入力を分割 {する|しない} パーセプトロン(系列方向) 要素積 x1 x2
x3 x4 u1 u2 u3 u4 v1 v2 v3 v4 v1 v2 v3 v4 s1 s2 s3 s4 ⊙ W Gate 9
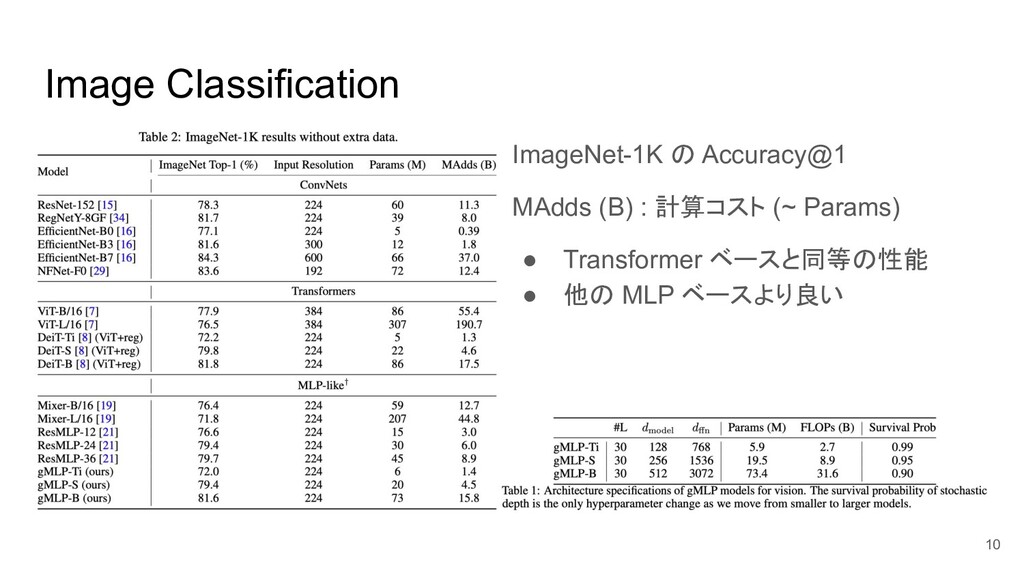
Image Classification ImageNet-1K の Accuracy@1 MAdds (B) : 計算コスト (~
Params) • Transformer ベースと同等の性能 • 他の MLP ベースより良い 10
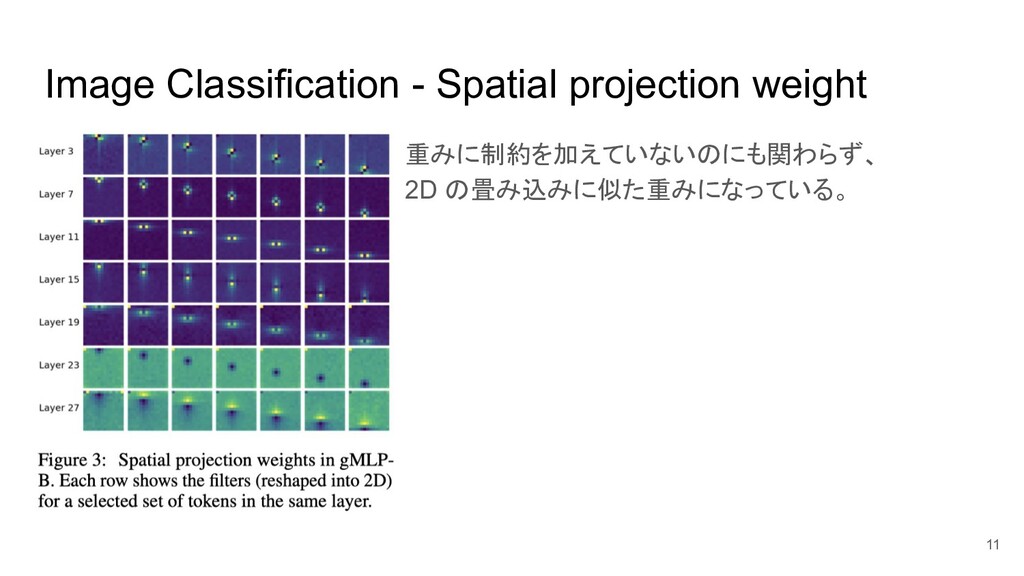
Image Classification - Spatial projection weight 重みに制約を加えていないのにも関わらず、 2D の畳み込みに似た重みになっている。 11
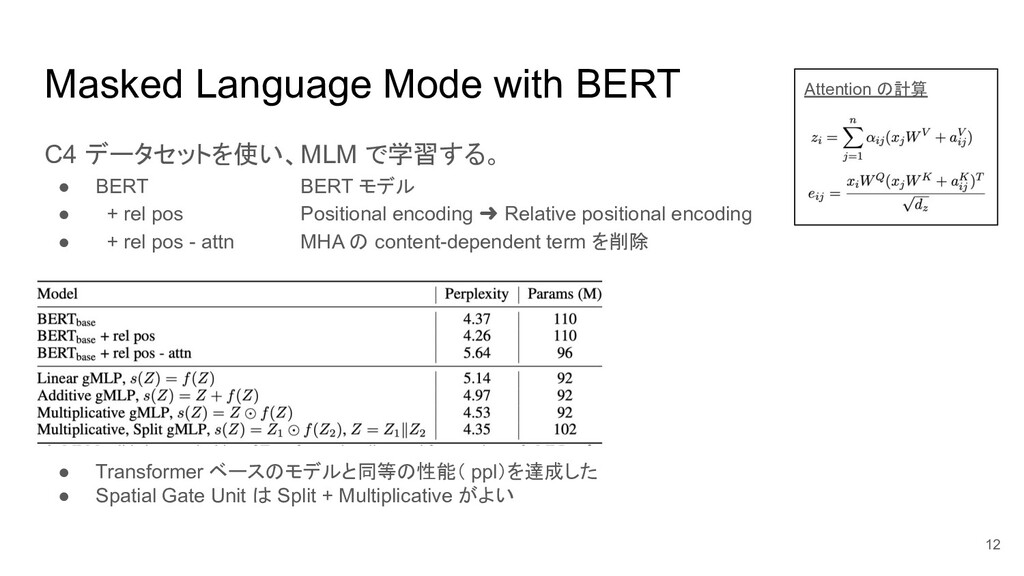
Masked Language Mode with BERT C4 データセットを使い、MLM で学習する。 • BERT
BERT モデル • + rel pos Positional encoding ➜ Relative positional encoding • + rel pos - attn MHA の content-dependent term を削除 Attention の計算 • Transformer ベースのモデルと同等の性能( ppl)を達成した • Spatial Gate Unit は Split + Multiplicative がよい 12
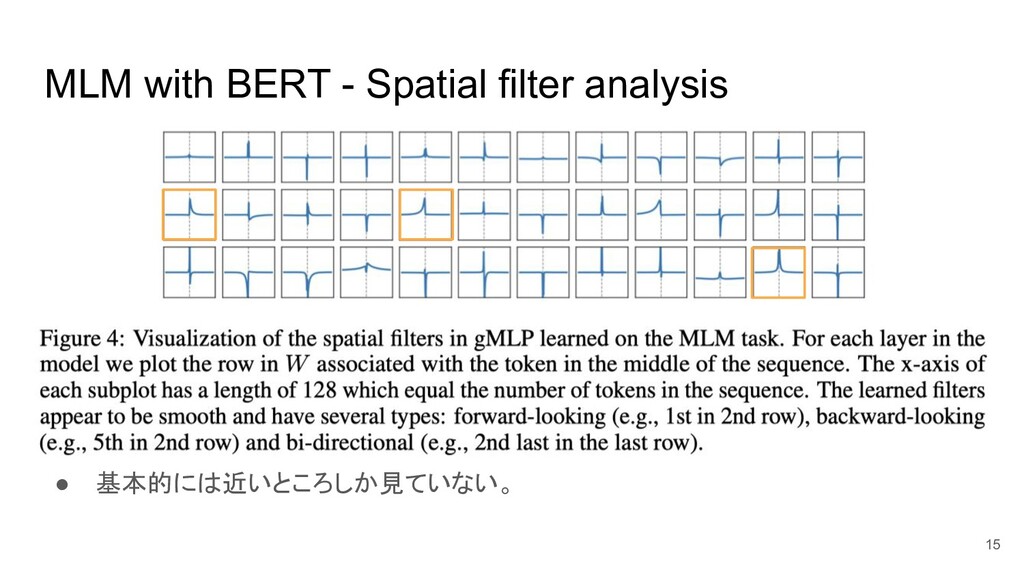
MLM with BERT - Spatial filter analysis 13
MLM with BERT - Spatial filter analysis • 基本的には近いところしか見ていない。 v1
v2 v3 v4 Gate を計算するときにどの要素を 見ているかを表している。 14
MLM with BERT - Spatial filter analysis • 基本的には近いところしか見ていない。 15
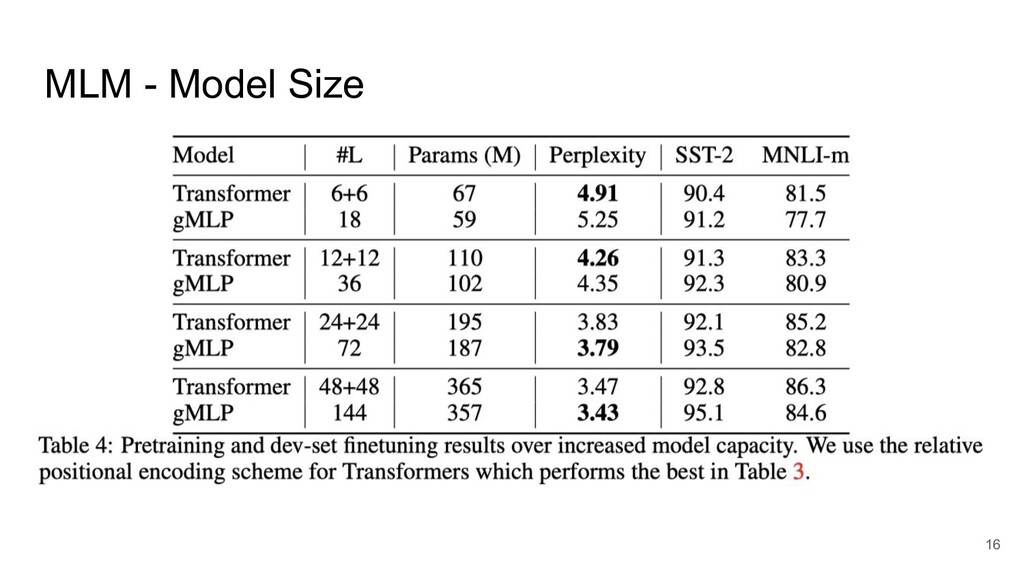
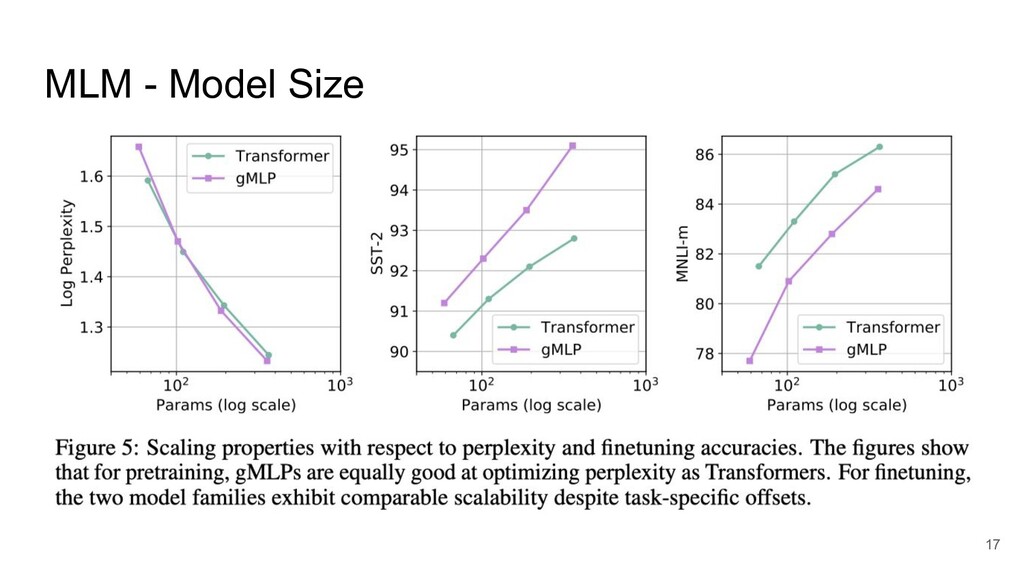
MLM - Model Size 16
MLM - Model Size 17
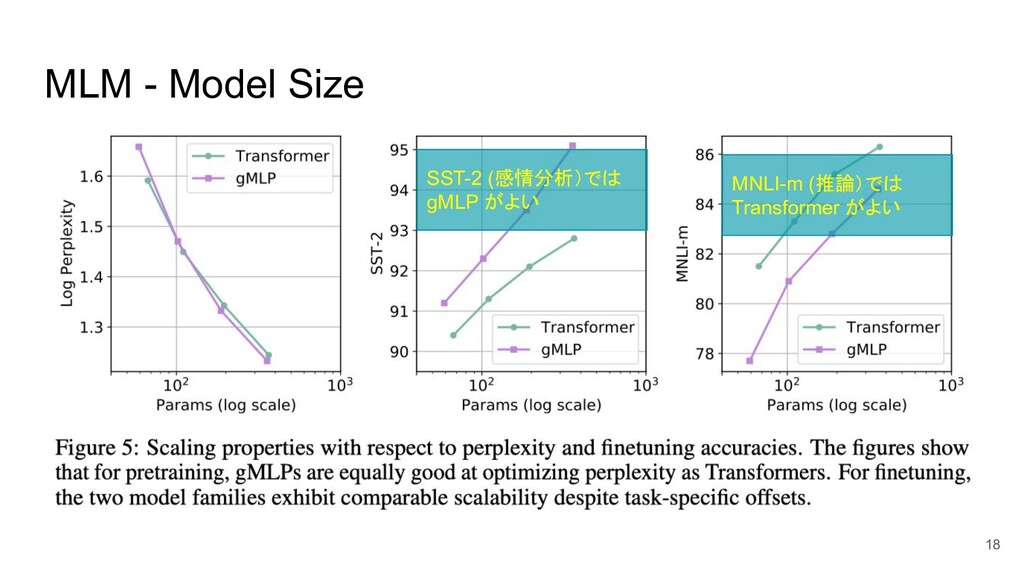
MLM - Model Size SST-2 (感情分析)では gMLP がよい MNLI-m (推論)では
Transformer がよい 18
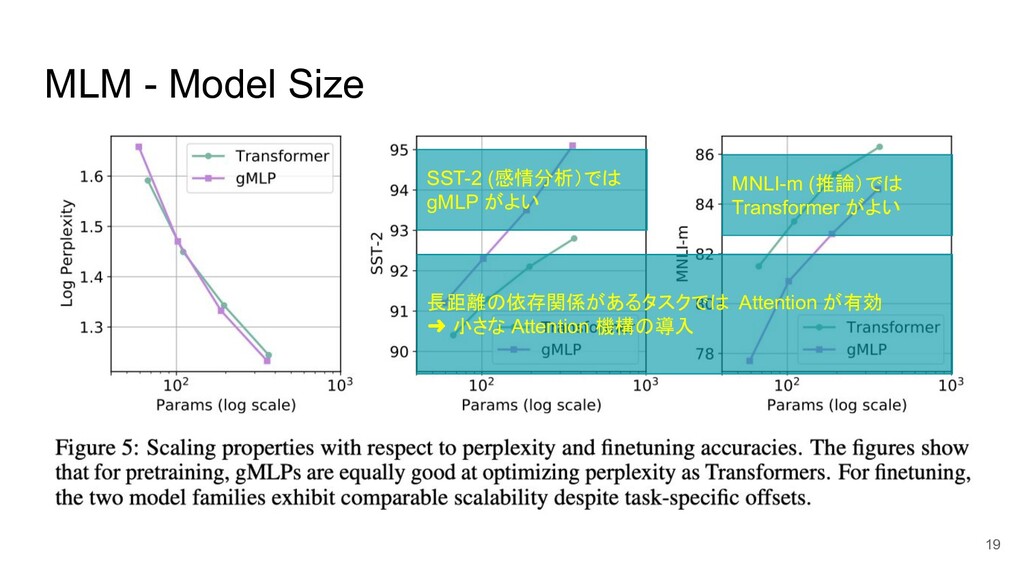
MLM - Model Size SST-2 (感情分析)では gMLP がよい MNLI-m (推論)では
Transformer がよい 長距離の依存関係があるタスクでは Attention が有効 ➜ 小さな Attention 機構の導入 19
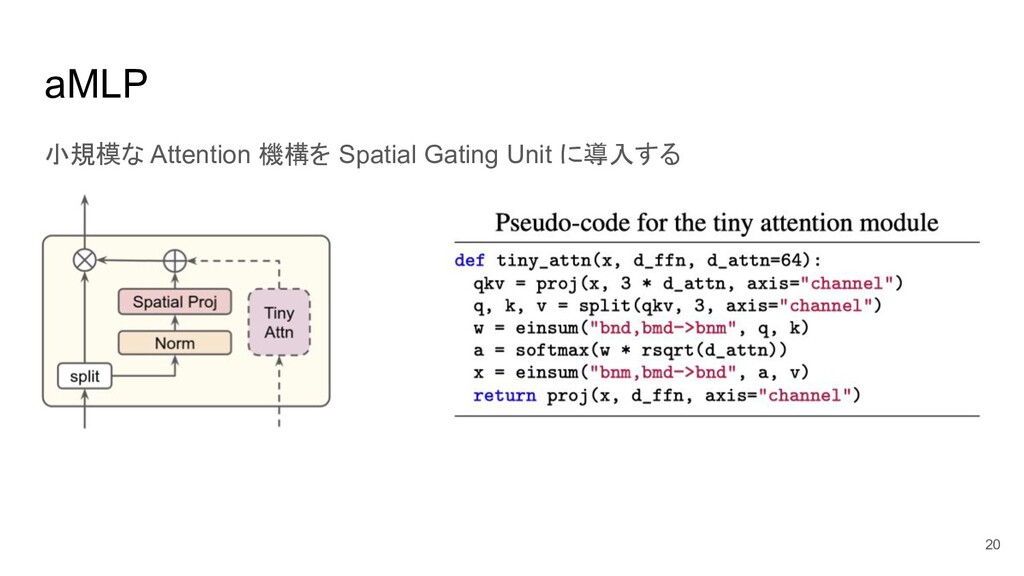
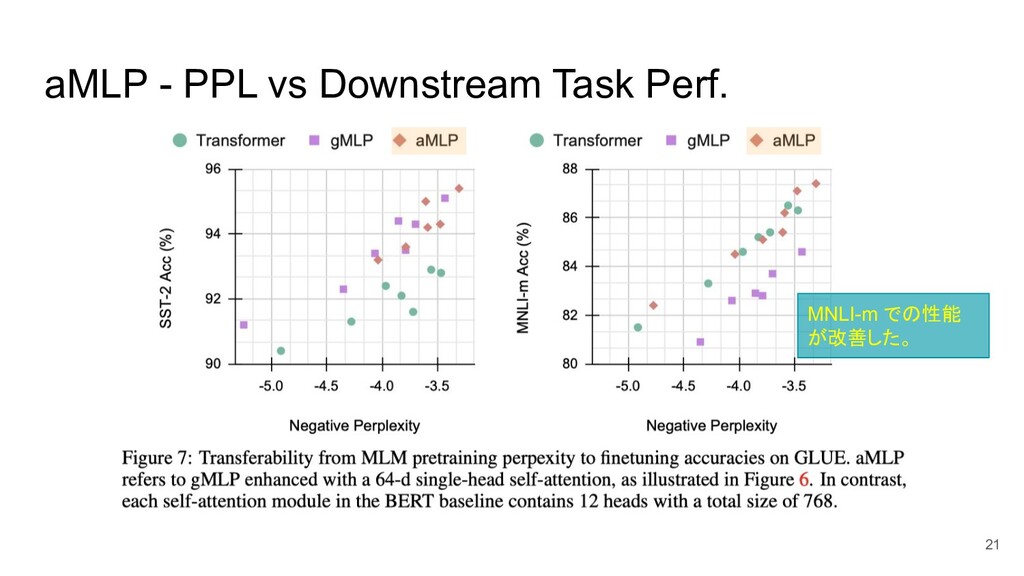
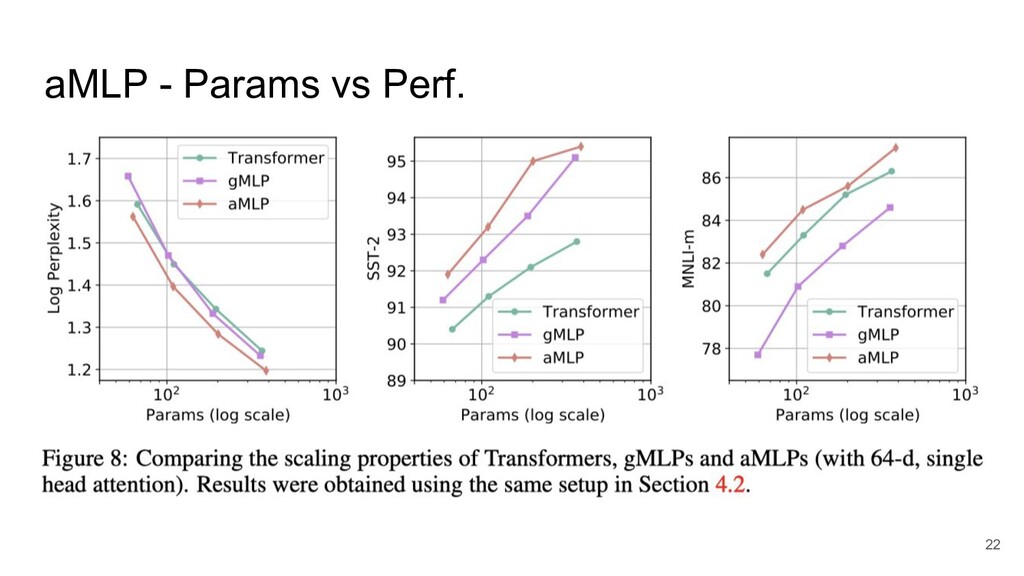
aMLP 小規模な Attention 機構を Spatial Gating Unit に導入する 20
aMLP - PPL vs Downstream Task Perf. MNLI-m での性能 が改善した。
21
aMLP - Params vs Perf. 22
MLM - Main results 23
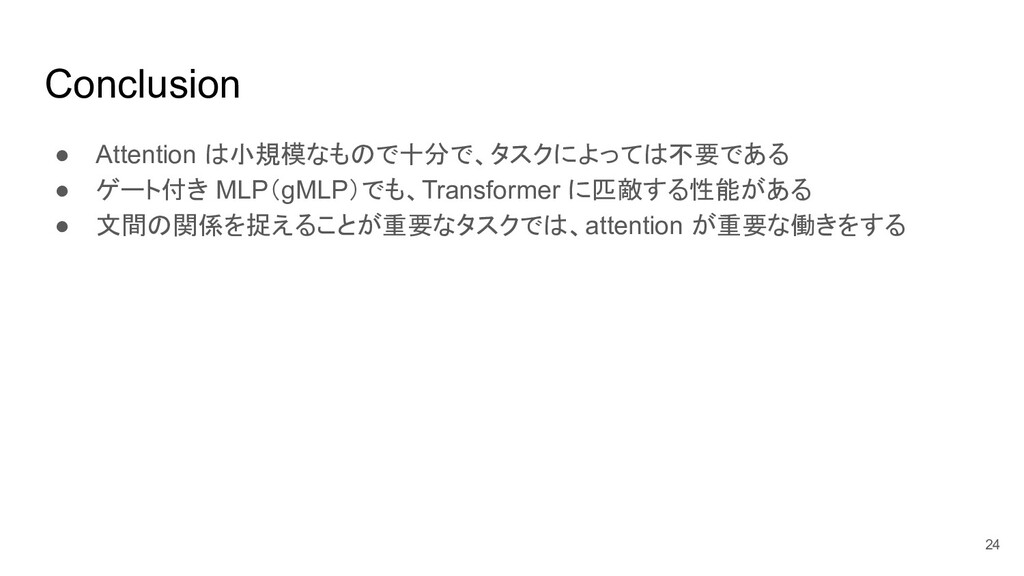
Conclusion • Attention は小規模なもので十分で、タスクによっては不要である • ゲート付き MLP(gMLP)でも、Transformer に匹敵する性能がある • 文間の関係を捉えることが重要なタスクでは、attention
が重要な働きをする 24

 Your Podcast. Everywhere. Effortlessly.


 tosho
 kogoro
 kzmssk
 imai448
 eumesy
 rikkabotan7
 institutdelelevage
 mickey_0226
 afroscript
 hisaokatsumi
 yumulab
 tomonom
 jcasabona
 sabderemane
 aleyda
 mfonobong
 tammyeverts
 stephaniewalter
 jacobtomlinson
 helenjbeal
 joshbly
 jnunemaker
 quramy