Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
ACL読み会2020_Jointly Masked Sequence-to-Sequence ...
Search
maskcott
August 07, 2020
Research
32
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
ACL読み会2020_Jointly Masked Sequence-to-Sequence Model for Non-Autoregressive Neural Machine Translation
maskcott
August 07, 2020
More Decks by maskcott
See All by maskcott
論文紹介2022後期(EMNLP2022)_Towards Opening the Black Box of Neural Machine Translation: Source and Target Interpretations of the Transformer
maskcott
0
93
論文紹介2022後期(ACL2022)_DEEP: DEnoising Entity Pre-training for Neural Machine Translation
maskcott
0
51
PACLIC2022_Japanese Named Entity Recognition from Automatic Speech Recognition Using Pre-trained Models
maskcott
0
62
WAT2022_TMU NMT System with Automatic Post-Editing by Multi-Source Levenshtein Transformer for the Restricted Translation Task of WAT 2022
maskcott
0
64
論文紹介2022前期_Redistributing Low Frequency Words: Making the Most of Monolingual Data in Non-Autoregressive Translation
maskcott
0
75
論文紹介2021後期_Analyzing the Source and Target Contributions to Predictions in Neural Machine Translation
maskcott
0
95
WAT2021_Machine Translation with Pre-specified Target-side Words Using a Semi-autoregressive Model
maskcott
0
68
NAACL/EACL読み会2021_NEUROLOGIC DECDING: (Un)supervised Neural Text Generation with Predicate Logic Constraints
maskcott
0
58
論文紹介2021前期_Bilingual Dictionary Based Neural Machine Translation without Using Parallel Sentences
maskcott
0
66
Other Decks in Research
See All in Research
学術バーQ AI研究最前線:自己教師あり学習による画像モデルの事前学習
naok615
0
170
HackSick vol.7 LT資料【LLMアーキテクチャ入門・事前学習時の躓き所解説】 スパースなAttention・状態空間モデル
rikkabotan7
0
220
XDPerf: A High-Performance Traffic Generator Built with WASM and eBPF
takehaya
1
340
CVPR2026論文紹介_VLMにとって良いvision encoderとは何か?Rethinking Model Selection in VLM Through the Lens of Gromov-Wasserstein Distance
kobayashi31
1
270
Santé et fertilité des sols : ce que nous disent les pratiques dans les systèmes de polyculture-élevage
institutdelelevage
PRO
0
120
視覚若手の会LENSって何??
mickey_0226
0
360
Prithvi-EO-2.0
satai
3
100
J-STAGEの現況と全文XML登載必須化について
xspa2012
0
340
就労支援の現場での生成AI活用
enochan
0
150
[最先端NLP勉強会2026] Agentic Rubrics as Contextual Verifiers for SWE Agents
rfujii
1
390
【ローカルAIに向き合う展示会vol.2】液体時間定数型モジュールを用いた オリジナルの双方向エンコーダーモデルNexteraBERT 推論速度向上検討並びにダウンストリーム評価
rikkabotan7
0
230
Vector Map as Language: Toward Unified Remote Sensing Vector Mapping
satai
3
320
Featured
See All Featured
Lightning talk: Run Django tests with GitHub Actions
sabderemane
0
300
Being A Developer After 40
akosma
92
590k
Navigating Team Friction
lara
192
16k
Why Your Marketing Sucks and What You Can Do About It - Sophie Logan
marketingsoph
0
430
SERP Conf. Vienna - Web Accessibility: Optimizing for Inclusivity and SEO
sarafernandez
2
1.6k
Stewardship and Sustainability of Urban and Community Forests
pwiseman
0
550
XXLCSS - How to scale CSS and keep your sanity
sugarenia
250
1.3M
Into the Great Unknown - MozCon
thekraken
41
2.8k
HU Berlin: Industrial-Strength Natural Language Processing with spaCy and Prodigy
inesmontani
PRO
0
750
Let's Do A Bunch of Simple Stuff to Make Websites Faster
chriscoyier
508
140k
How GitHub (no longer) Works
holman
316
150k
The Language of Interfaces
destraynor
162
27k
Transcript
1
Abstract ・様々な自然言語処理のタスクで注目を集めているmasked languageモデルをseq2seqモデルに適用し た ”jointly masked seq2seq” モデルを提案しNATに適用した ・具体的にはトレーニング時にエンコーダーへの入力をマスキングし、デコーダーではn-gramのロス関数 で連続的にマスキングすることで学習するもの
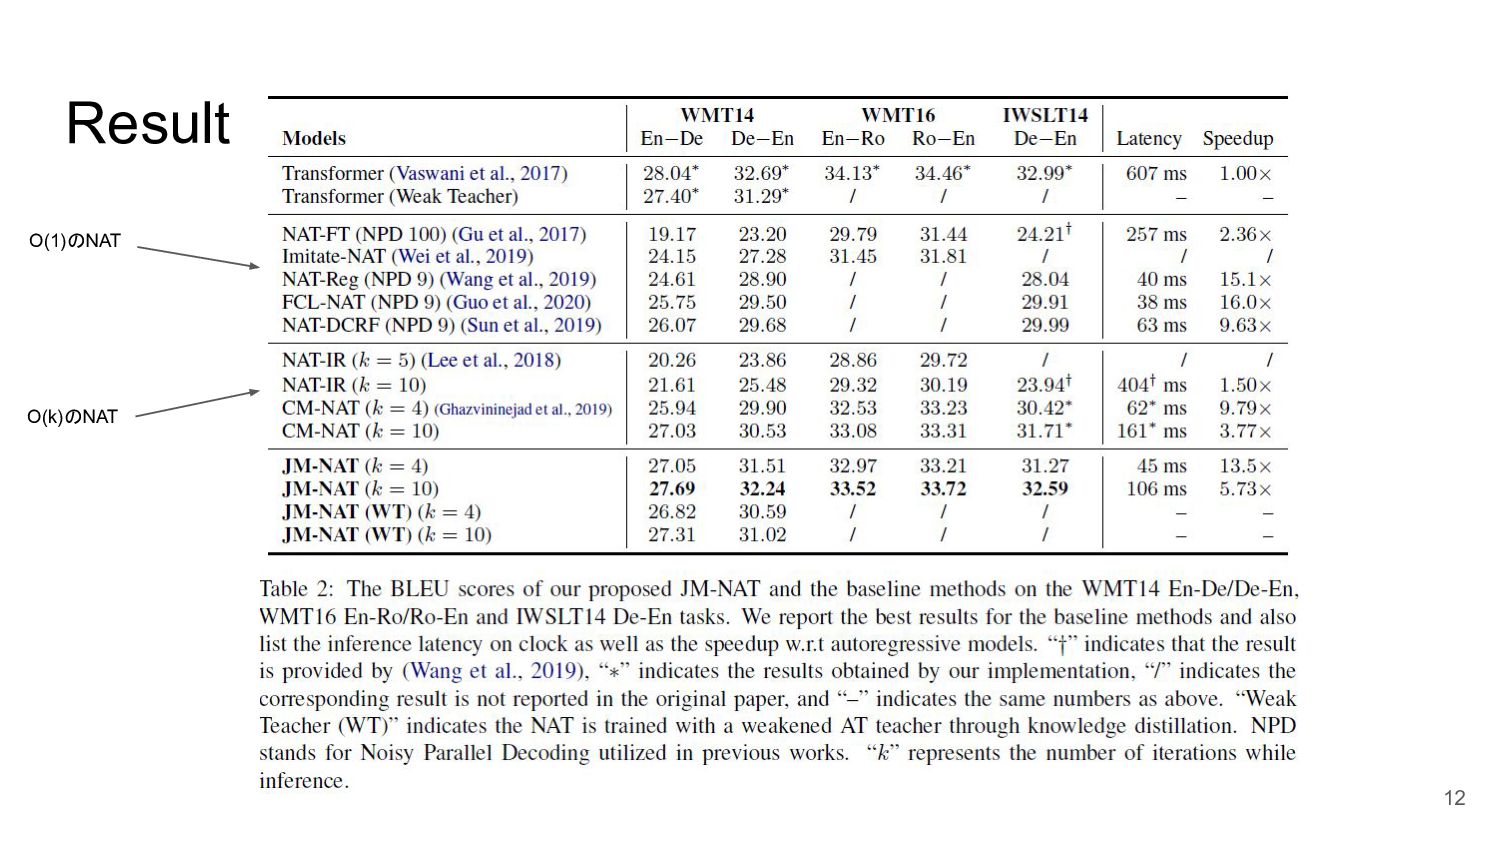
・ WMT14 en-de/de-en で 27.69/32.24 のBLEUスコアを達成し、自己回帰モデルの5倍の速度を実現 2
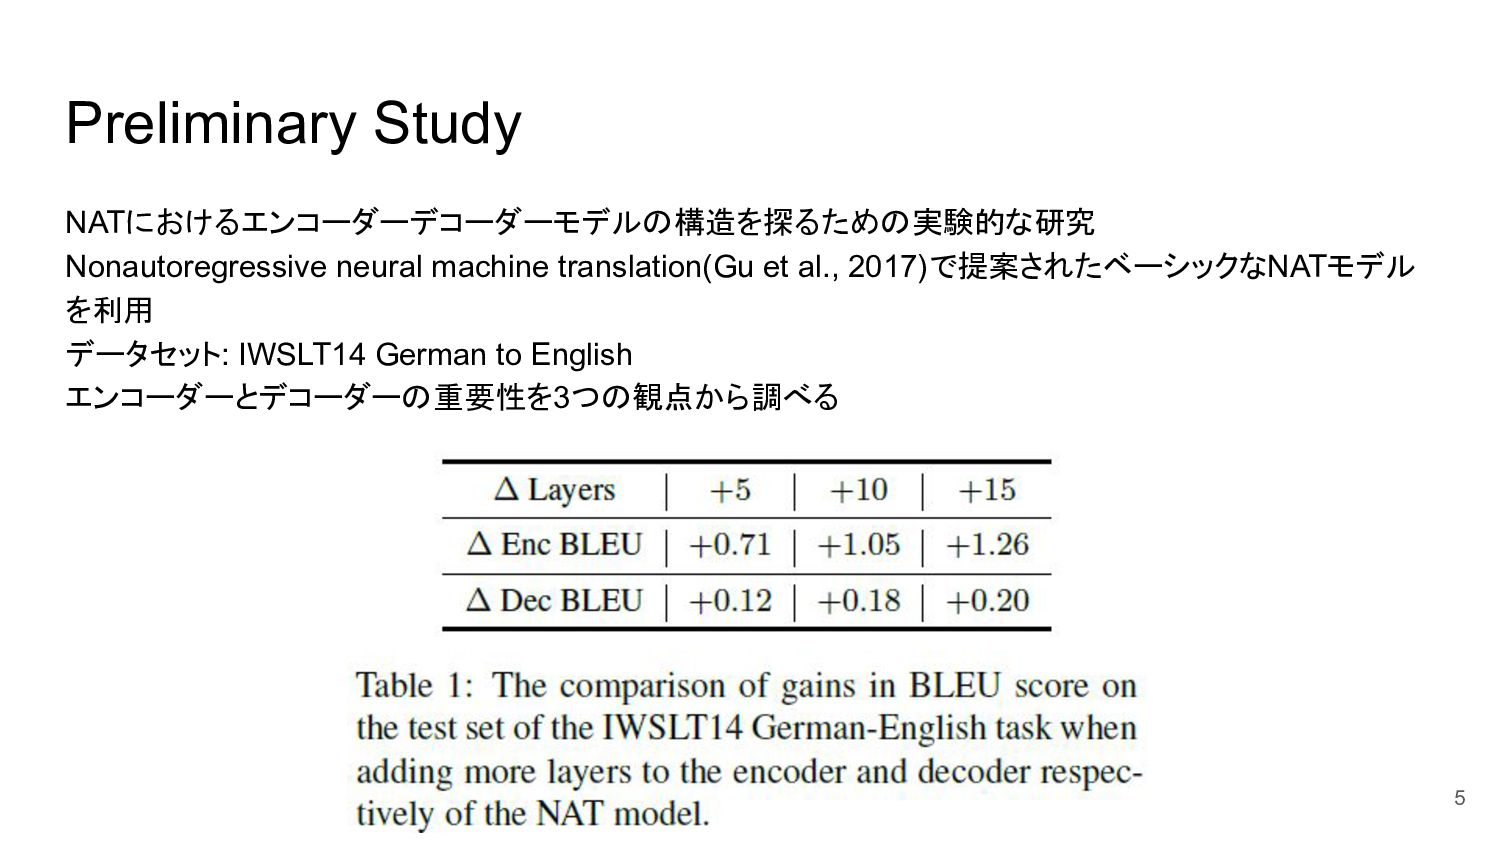
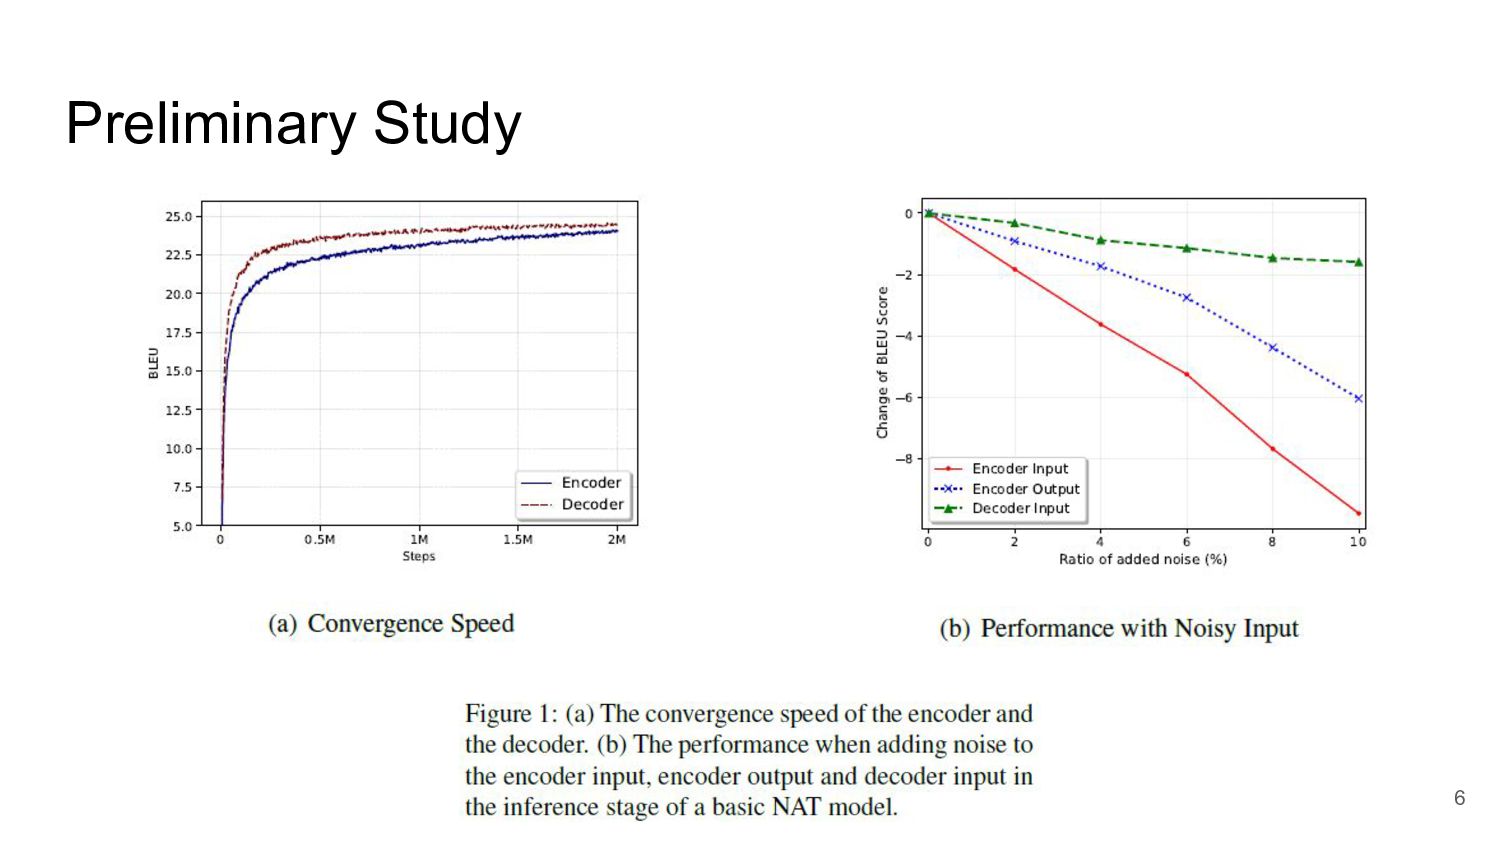
Introduction ・NATモデルの精度が落ちる理由として次の二つが先行研究で主に挙げられている 1.ソース側の情報が適切にエンコードされていないこと 2.デコーダーがタスクをうまく処理できず、繰り返しや長文における性能が低下したりする →NATモデルのエンコーダーとデコーダーの機能を実験的に研究するとエンコーダーの方がデコーダーよ りも翻訳結果に影響を与えることが判明 ・BERTに倣ってエンコーダ―でマスキングを行うことでエンコーダーを徹底的に学習させる ・デコーダーの入力に対して連続的なマスキングを行う手法とn-gramロス関数の実装を提案 ・二つの方法を統合してjointly masked
seq2seqモデルを実装 3
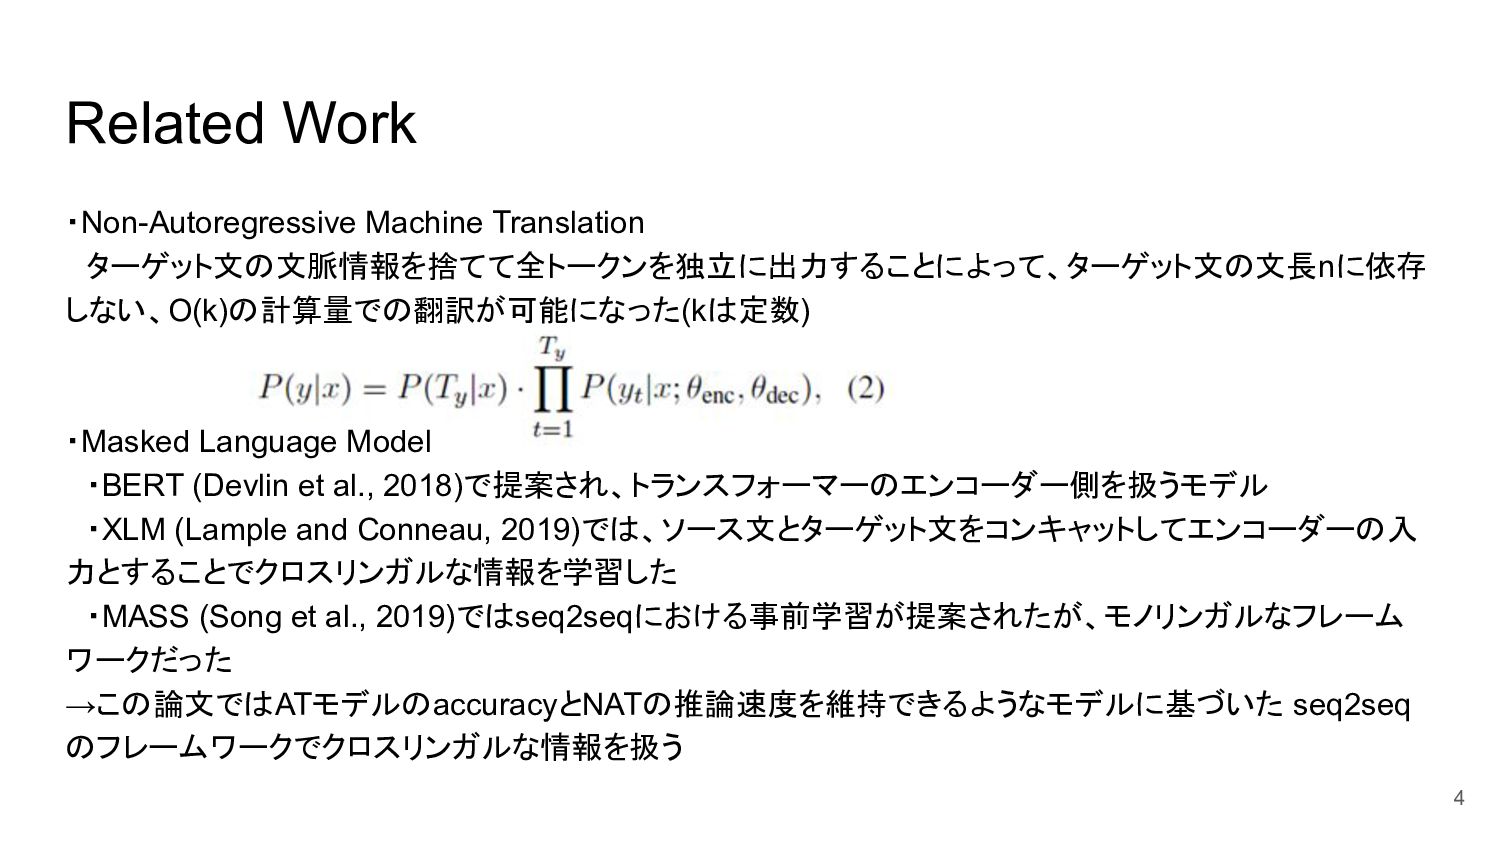
Related Work ・Non-Autoregressive Machine Translation ターゲット文の文脈情報を捨てて全トークンを独立に出力することによって、ターゲット文の文長nに依存 しない、O(k)の計算量での翻訳が可能になった(kは定数) ・Masked Language Model
・BERT (Devlin et al., 2018)で提案され、トランスフォーマーのエンコーダー側を扱うモデル ・XLM (Lample and Conneau, 2019)では、ソース文とターゲット文をコンキャットしてエンコーダーの入 力とすることでクロスリンガルな情報を学習した ・MASS (Song et al., 2019)ではseq2seqにおける事前学習が提案されたが、モノリンガルなフレーム ワークだった →この論文ではATモデルのaccuracyとNATの推論速度を維持できるようなモデルに基づいた seq2seq のフレームワークでクロスリンガルな情報を扱う 4
Preliminary Study NATにおけるエンコーダーデコーダーモデルの構造を探るための実験的な研究 Nonautoregressive neural machine translation(Gu et al., 2017)で提案されたベーシックなNATモデル
を利用 データセット: IWSLT14 German to English エンコーダーとデコーダーの重要性を3つの観点から調べる 5
Preliminary Study 6
Methodology 問題設定 ・ソース文とターゲット文 ロス関数 エンコーダーマスキング 個の単語をランダムに選択して とする のうち80%を[mask], 10%をvocabからランダムに別の単語に置き換える 置き換えた後の文を とする
ロス関数 7
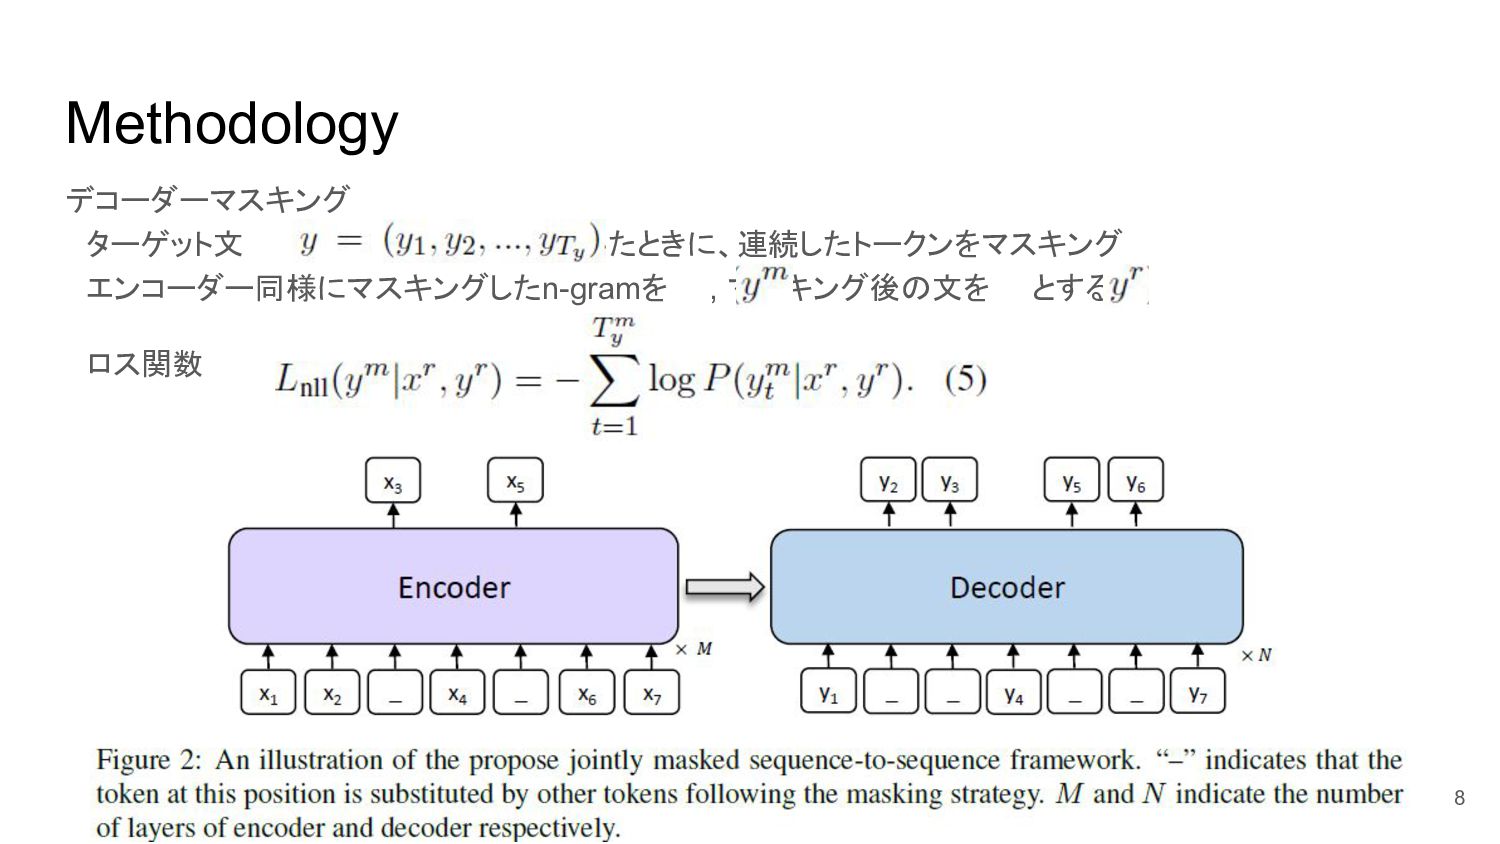
Methodology デコーダーマスキング ターゲット文 が与えられたときに、連続したトークンをマスキング エンコーダー同様にマスキングしたn-gramを , マスキング後の文を とする ロス関数 8
Methodology 連続的なn-gramベースのロス関数(Ma et al., 2018; Shao et al., 2018, 2019)も利用(デコーダー)
与えられるn-gram 9
Methodology 目的関数 デコード方法 エンコーダーの入力に特殊なトークンを加えて、そのトークンに相当する隠れベクトルから文長を予測する (Ghazvininejad et al., 2019) この文長に関するロスも上式に加えて計算 文長が決まったらターゲット文を[mask]で初期化してデコーダーに入力
出力のうち確率の低かった単語を選び、隣接する単語とともにマスクをしてデコーダーに入力を繰り返す (選ぶ単語の数は線形関数的に減衰させる) 事前に決めたイテレーション数回すか結果が変わらなくなったら終了 10
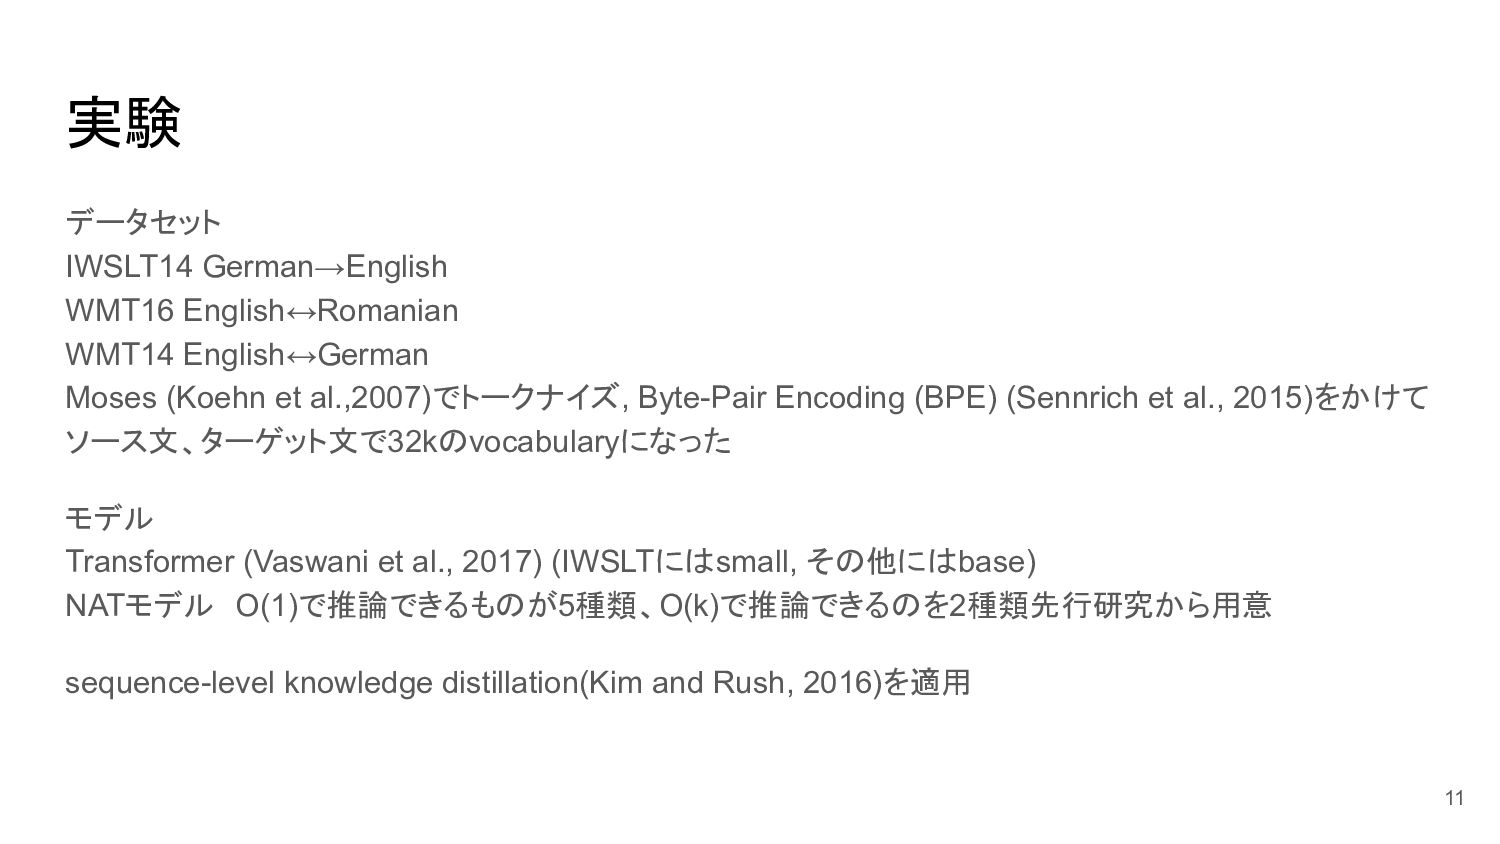
実験 データセット IWSLT14 German→English WMT16 English↔Romanian WMT14 English↔German Moses (Koehn
et al.,2007)でトークナイズ, Byte-Pair Encoding (BPE) (Sennrich et al., 2015)をかけて ソース文、ターゲット文で32kのvocabularyになった モデル Transformer (Vaswani et al., 2017) (IWSLTにはsmall, その他にはbase) NATモデル O(1)で推論できるものが5種類、O(k)で推論できるのを2種類先行研究から用意 sequence-level knowledge distillation(Kim and Rush, 2016)を適用 11
Result 12 O(1)のNAT O(k)のNAT
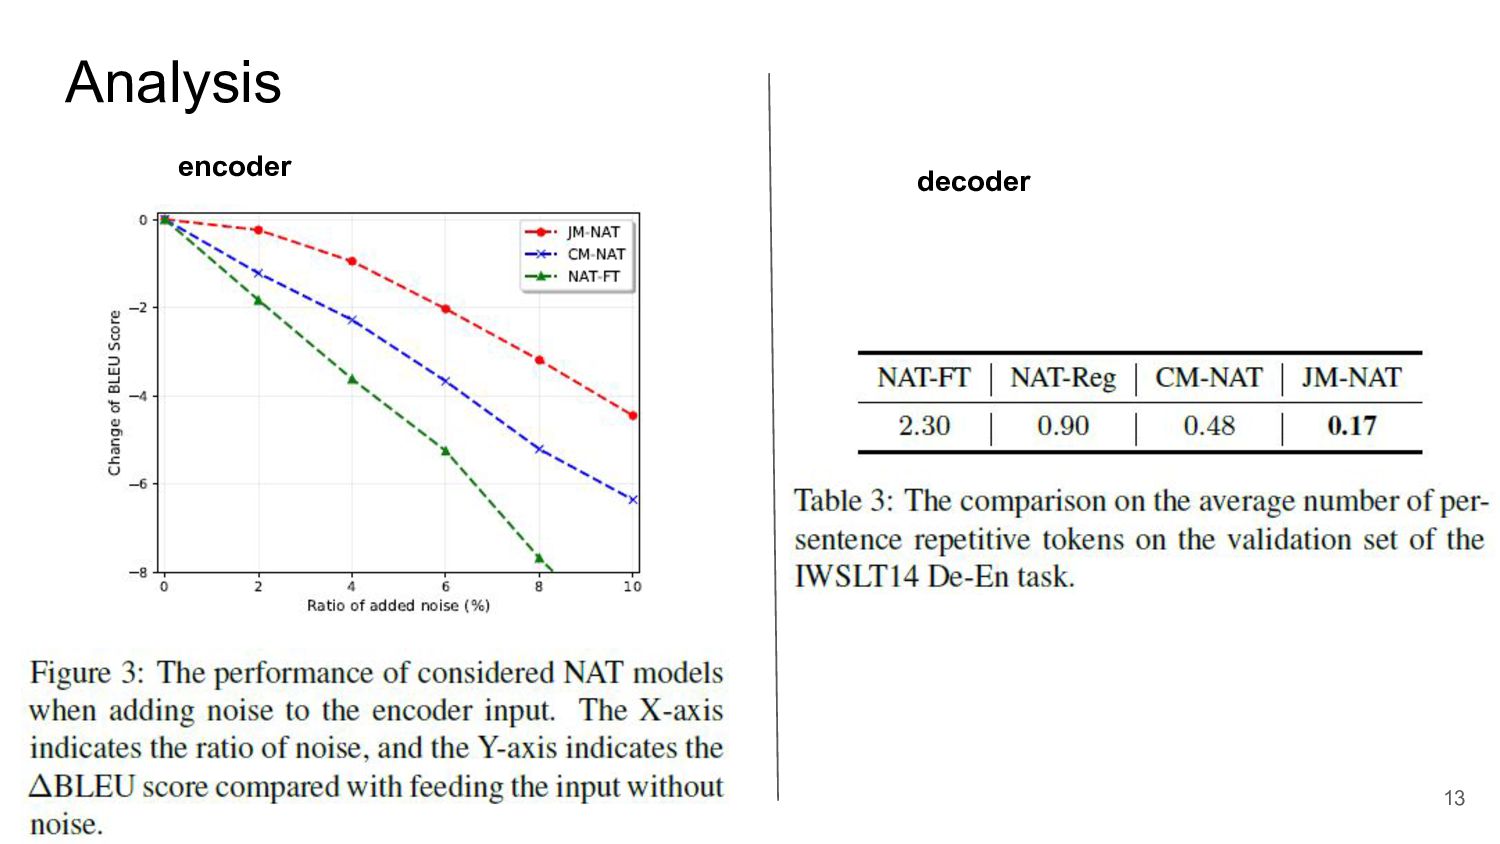
Analysis 13 encoder decoder
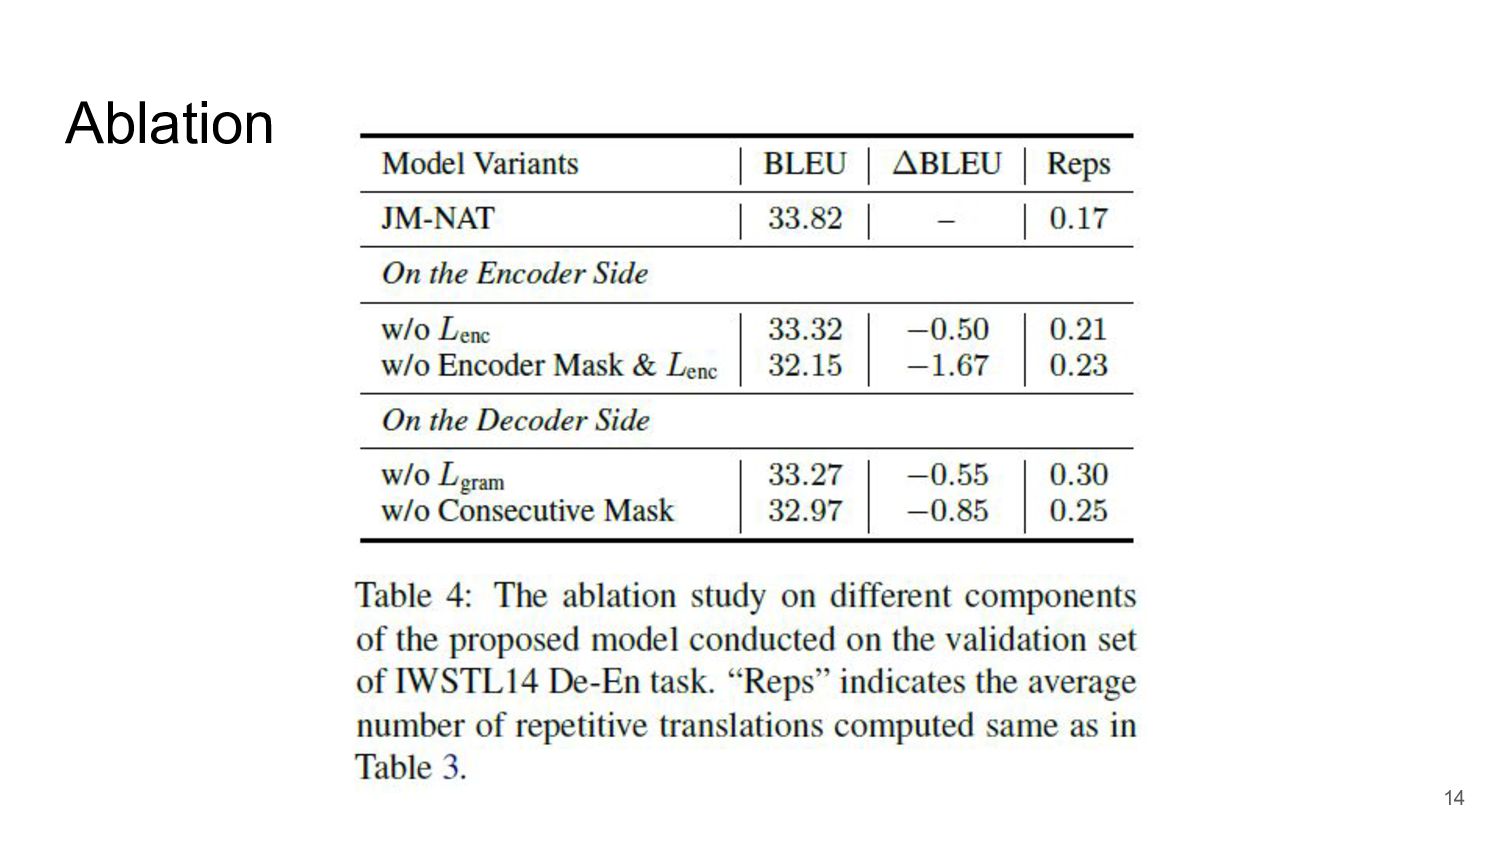
Ablation 14
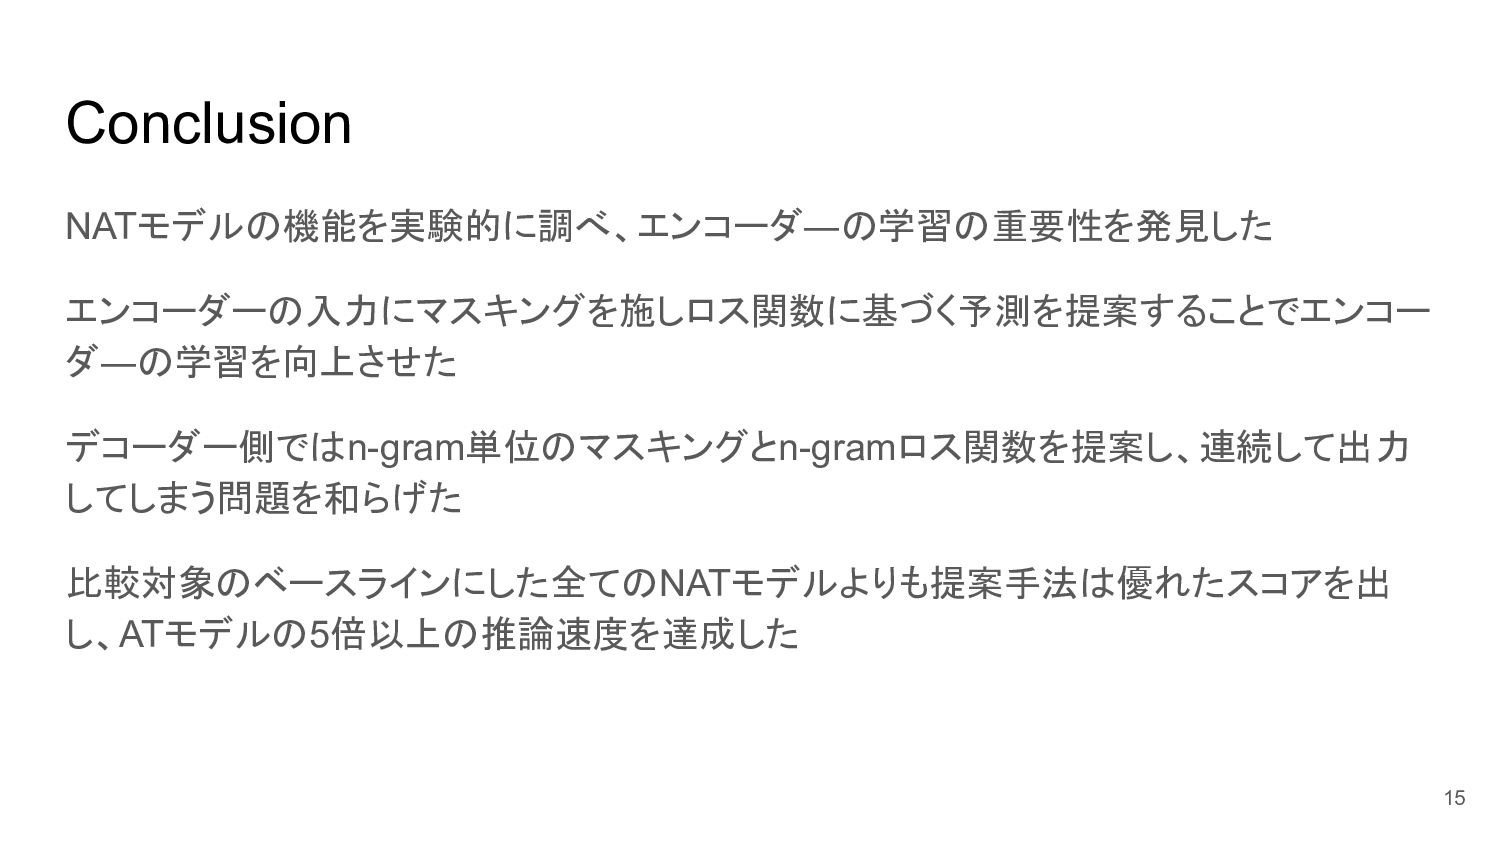
Conclusion NATモデルの機能を実験的に調べ、エンコーダ―の学習の重要性を発見した エンコーダーの入力にマスキングを施しロス関数に基づく予測を提案することでエンコー ダ―の学習を向上させた デコーダー側ではn-gram単位のマスキングとn-gramロス関数を提案し、連続して出力 してしまう問題を和らげた 比較対象のベースラインにした全てのNATモデルよりも提案手法は優れたスコアを出 し、ATモデルの5倍以上の推論速度を達成した 15


 maskcott
 naok615
 rikkabotan7
 takehaya
 kobayashi31
 institutdelelevage
 mickey_0226
 satai
 xspa2012
 enochan
 rfujii
 sabderemane
 akosma
 lara
 marketingsoph
 sarafernandez
 pwiseman
 sugarenia
 thekraken
 inesmontani
 chriscoyier
 holman
 destraynor