Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
文献紹介20181211_On Learning Better Word Embeddings...
Search
Sponsored
·
SiteGround - Reliable hosting with speed, security, and support you can count on.
→
T.Tada
December 11, 2018
Technology
120
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
文献紹介20181211_On Learning Better Word Embeddings from Chinese Clinical Records: Study on Combining In-Domain and Out-Domain Data
T.Tada
December 11, 2018
More Decks by T.Tada
See All by T.Tada
文献紹介_202002_Is artificial data useful for biomedical Natural Language Processing algorithms?
tad
0
81
文献紹介_202001_A Novel System for Extractive Clinical Note Summarization using EHR Data
tad
0
200
文献紹介_201912_Publicly Available Clinical BERT Embeddings
tad
0
180
文献紹介_201911_EDA: Easy Data Augmentation Techniques for Boosting Performance on Text Classification Tasks
tad
0
230
文献紹介_201910_Do Neural NLP Models Know Numbers? Probing Numeracy in Embeddings
tad
0
110
文献紹介_201909_Sentence Mover’s Similarity_ Automatic Evaluation for Multi-Sentence Texts
tad
0
180
文献紹介_201908_Medical Word Embeddings for Spanish_ Development and Evaluation
tad
0
78
文献紹介_201907_Is Word Segmentation Necessary for Deep Learning of Chinese Representations
tad
0
130
文献紹介_201906_Predicting Annotation Difficulty to Improve Task Routing and Model Performance for Biomedical Information Extraction
tad
0
120
Other Decks in Technology
See All in Technology
AIエージェントの監視、思考を見るか行動を見るか / Monitoring AI Agents: Thoughts or Actions
yusukeshimizu
2
180
Cloudflareの向き先
chimame
1
190
AIコーディングはじめました
miso
0
170
Gifu WordPress Meetup #200 に向けて、私たちには何ができるだろうか?/ 2026-11-07 Gifu WordPress Meetup
torounit
0
250
これからのデータエンジニアの役割について考える / Rethinking the Role of Data Engineers in the AI Era
okiyuki99
0
240
長い仕事を任せる (Workflows、クラウドセッション、Kiro Web) | 目指せ Kiro マスター 10
inariku
PRO
3
170
Kiro Crew の Bot (続く役目を任せる窓口) | 目指せ Kiro マスター 12
inariku
PRO
2
360
Content Mapper APIの応用例~CSS Modules、言語ファイル~
uhyo
2
640
属人化したISMS運用をGitHubとAIで仕組み化した1年間の記録
sioncojp
4
2k
田んぼの見回りをIoTで減らしたい!水位監視から電池駆動カメラまでの試行錯誤
itosoft
1
120
81天的 AI Agent 軟體開發團隊治理實務分享
regionbbs
0
150
bpf_arenaとstruct_opsを使うのが難しかった話
masu_mi
0
230
Featured
See All Featured
Avoiding the “Bad Training, Faster” Trap in the Age of AI
tmiket
1
300
The World Runs on Bad Software
bkeepers
PRO
72
12k
How STYLIGHT went responsive
nonsquared
100
6.4k
Navigating the moral maze — ethical principles for Al-driven product design
skipperchong
2
680
ラッコキーワード サービス紹介資料
rakko
5
5.8M
エンジニアに許された特別な時間の終わり
watany
109
250k
The Impact of AI in SEO - AI Overviews June 2024 Edition
aleyda
6
1.3k
How to Get Subject Matter Experts Bought In and Actively Contributing to SEO & PR Initiatives.
livdayseo
0
240
Learning to Love Humans: Emotional Interface Design
aarron
275
41k
Data-driven link building: lessons from a $708K investment (BrightonSEO talk)
szymonslowik
1
1.4k
Design of three-dimensional binary manipulators for pick-and-place task avoiding obstacles (IECON2024)
konakalab
0
660
Building Adaptive Systems
keathley
44
3.3k
Transcript
- 文献紹介 2018/12/11 - On Learning Better Word Embeddings from
Chinese Clinical Records: Study on Combining In-Domain and Out-Domain Data 長岡技術科学大学 自然言語処理研究室 多田太郎
About the thesis 2
Introduction ・単語エンベディングはバイオメディカル分野において多くの有望な結果を得ている. ・中国の臨床記録を用いた分野においては大きく遅れがある. ・中国の臨床記録から埋め込みを学習することに焦点を当てる. 3
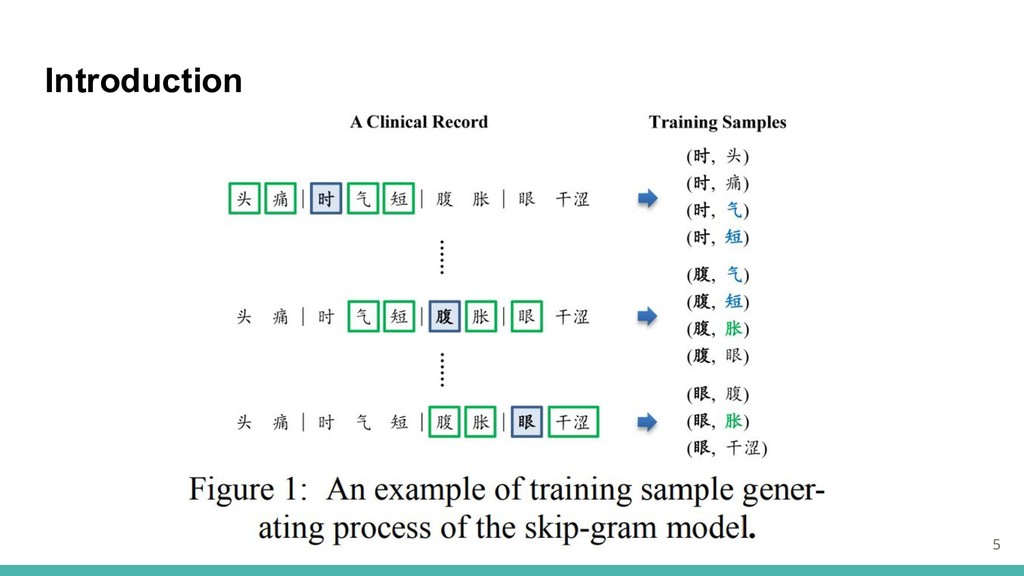
Introduction 貢献: ・より良い学習をするためのドメイン内およびドメイン外のデータ結合方法の提案 ・追加の標準的な医学用語データセットを用いて単語エンベディングを評価する方法を提案 ・良い訓練サンプルの選択,適切な量の外部ドメインデータを収集することで質の向上を確 認 Skip-gramを用いて学習していく 4
Introduction 5
Skip-Gram Model for Learning Embeddings from Chinese Clinical Records -
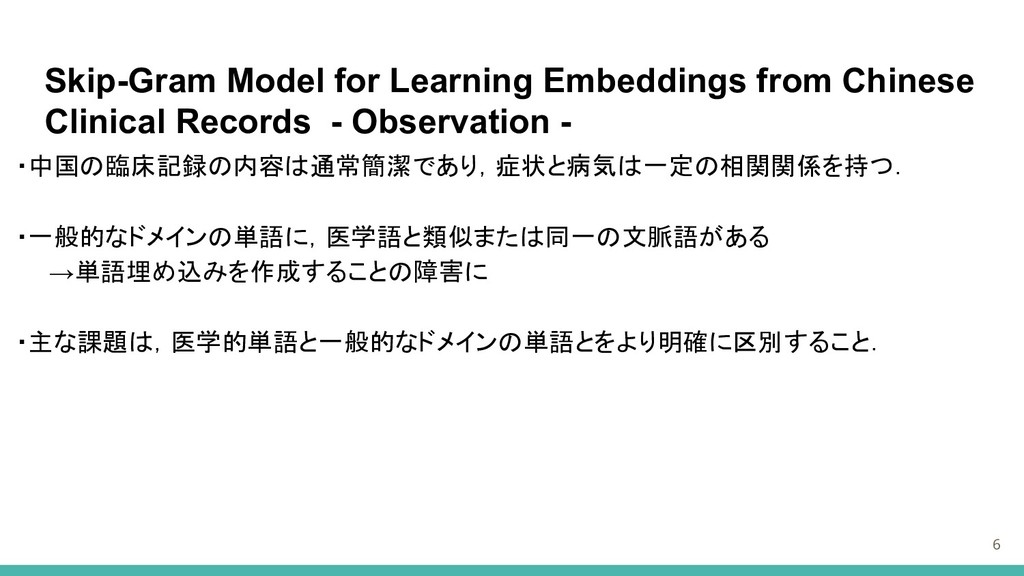
Observation - ・中国の臨床記録の内容は通常簡潔であり,症状と病気は一定の相関関係を持つ. ・一般的なドメインの単語に,医学語と類似または同一の文脈語がある →単語埋め込みを作成することの障害に ・主な課題は,医学的単語と一般的なドメインの単語とをより明確に区別すること. 6
Skip-Gram Model for Learning Embeddings from Chinese Clinical Records -
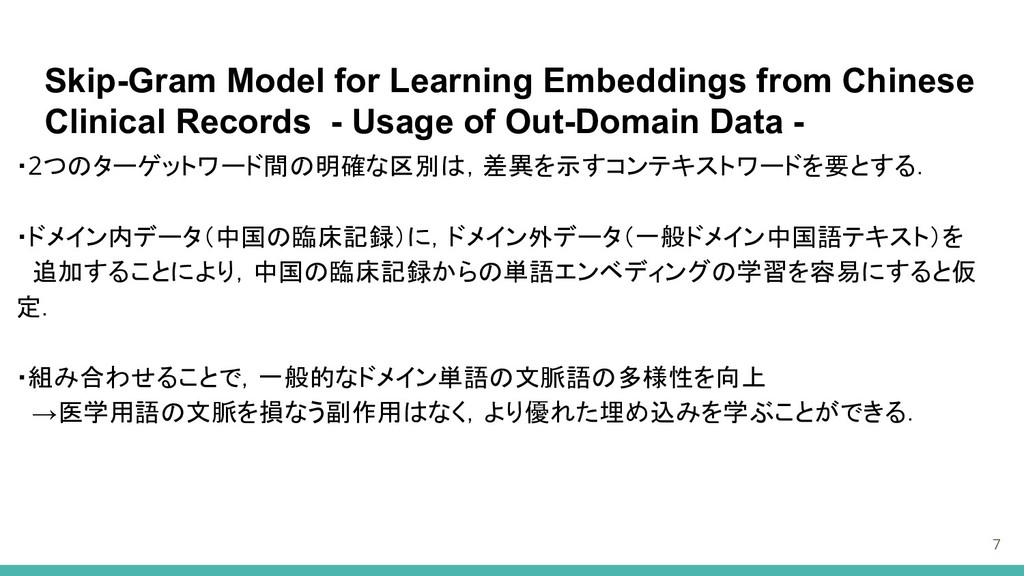
Usage of Out-Domain Data - ・2つのターゲットワード間の明確な区別は,差異を示すコンテキストワードを要とする. ・ドメイン内データ(中国の臨床記録)に,ドメイン外データ(一般ドメイン中国語テキスト)を 追加することにより,中国の臨床記録からの単語エンベディングの学習を容易にすると仮 定. ・組み合わせることで,一般的なドメイン単語の文脈語の多様性を向上 →医学用語の文脈を損なう副作用はなく,より優れた埋め込みを学ぶことができる. 7
Skip-Gram Model for Learning Embeddings from Chinese Clinical Records -Learning
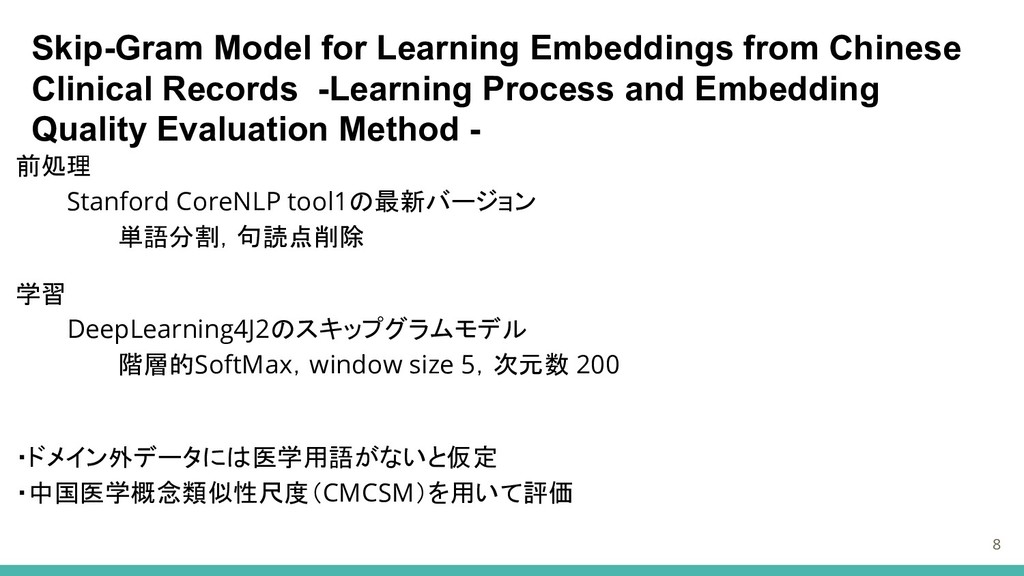
Process and Embedding Quality Evaluation Method - 前処理 Stanford CoreNLP tool1の最新バージョン 単語分割,句読点削除 学習 DeepLearning4J2のスキップグラムモデル 階層的SoftMax,window size 5,次元数 200 ・ドメイン外データには医学用語がないと仮定 ・中国医学概念類似性尺度(CMCSM)を用いて評価 8
Learning Process and Embedding Quality Evaluation Method 9
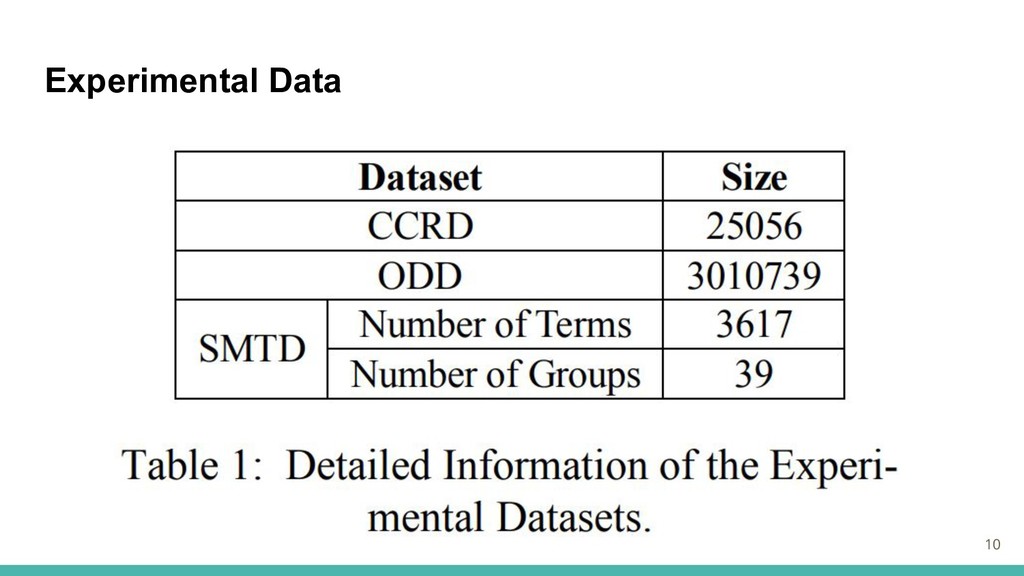
Experimental Data 10
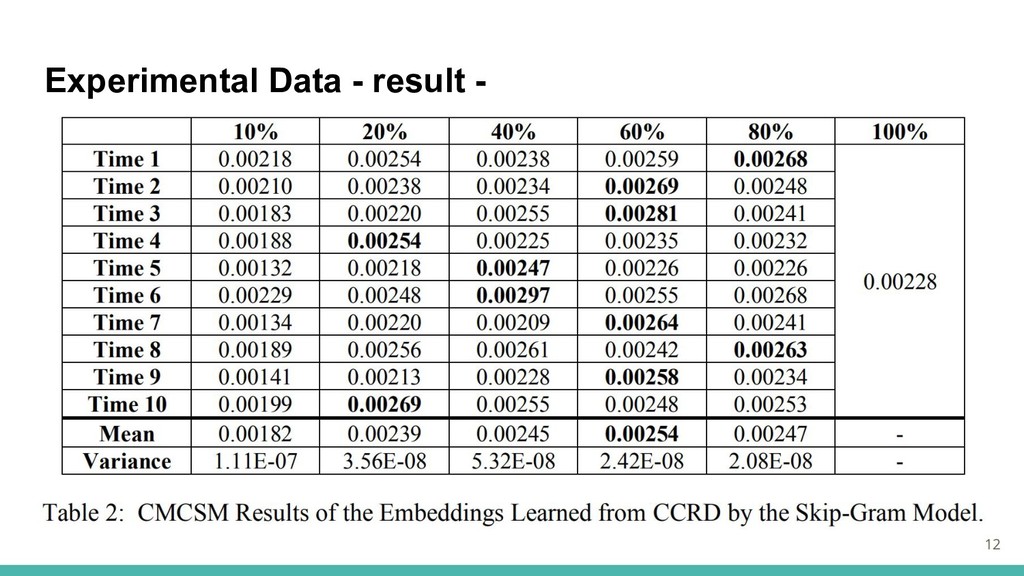
Experimental Data ・スキップグラムモデルを適用してCCRDを学習し,CMCSMで評価. ・異なるサイズのデータセットの効果を評価. CCRDから5つのサブデータセットをサンプリング(80%,60%,40%,20%,10%) ・ドメイン内のデータのみを使用する場合,以下の必要がある. 可能な限り多くのトレーニングデータを収集 有益なサンプルを選択する 11
Experimental Data - result - 12
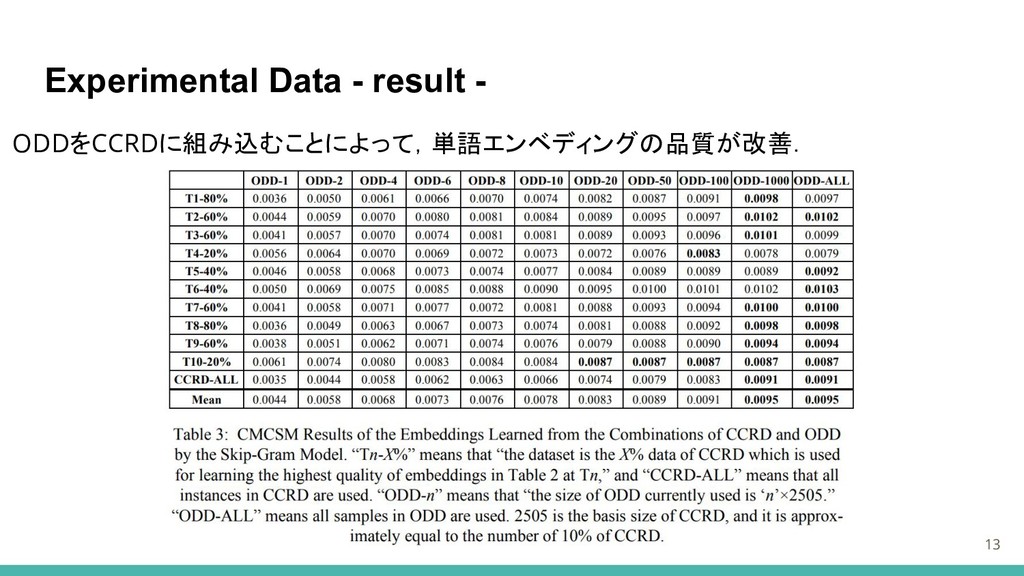
Experimental Data - result - 13 ODDをCCRDに組み込むことによって,単語エンベディングの品質が改善.
Discussion / Conclusions ・良好な単語ベクトルを学習する方法に関する既存の研究の大部分は,同じ領域内のデータ に基づいている(Chiu et al. 2016, Lai et
al. 2016) →さらなる探求は多くの面で継続される必要がある. ・ドメイン外データを用いて,中国の臨床記録からのより良い単語ベクトルを学習方法を提示. ・ 適切な量のドメイン外データを収集し,良好なトレーニングサンプルを選択することで単語ベ クトルの質の向上を確認. 14

 SiteGround - Reliable hosting with speed, security, and support you can count on.


 tad
 yusukeshimizu
 chimame
 miso
 torounit
 okiyuki99
 inariku
 uhyo
 sioncojp
 itosoft
 regionbbs
 masu_mi
 tmiket
 bkeepers
 nonsquared
 skipperchong
 rakko
 watany
 aleyda
 livdayseo
 aarron
 szymonslowik
 konakalab
 keathley