Share
Embed

Transcript
75 slides
-
FIND MEANING IN COMPLEXITY Elizabeth Tseng, Senior Bioinformatics Scientist Iso-SeqTM
Bioinformatics Analysis of the Human MCF-7 Transcriptome Sequenced with PacBio® Long Reads Pacific Biosciences, the Pacific Biosciences logo, PacBio, SMRT, SMRTbell, and Iso-Seq are trademarks of Pacific Biosciences in the United States and/or other countries. All other trademarks are the sole property of their respective owners. © Copyright 2014 by Pacific Biosciences of California, Inc. All rights reserved. -
Outline • Motivation – Why use the PacBio® system for
transcriptome sequencing? • Iso-Seq™ Library Preparation Protocol – Library workflow – Size selection • Iso-Seq Bioinformatics #1: Quality Control • Human MCF-7 Transcriptome • Rat Heart and Lung Transcriptome • Iso-Seq Bioinformatics #2: Isoform-level Clustering -
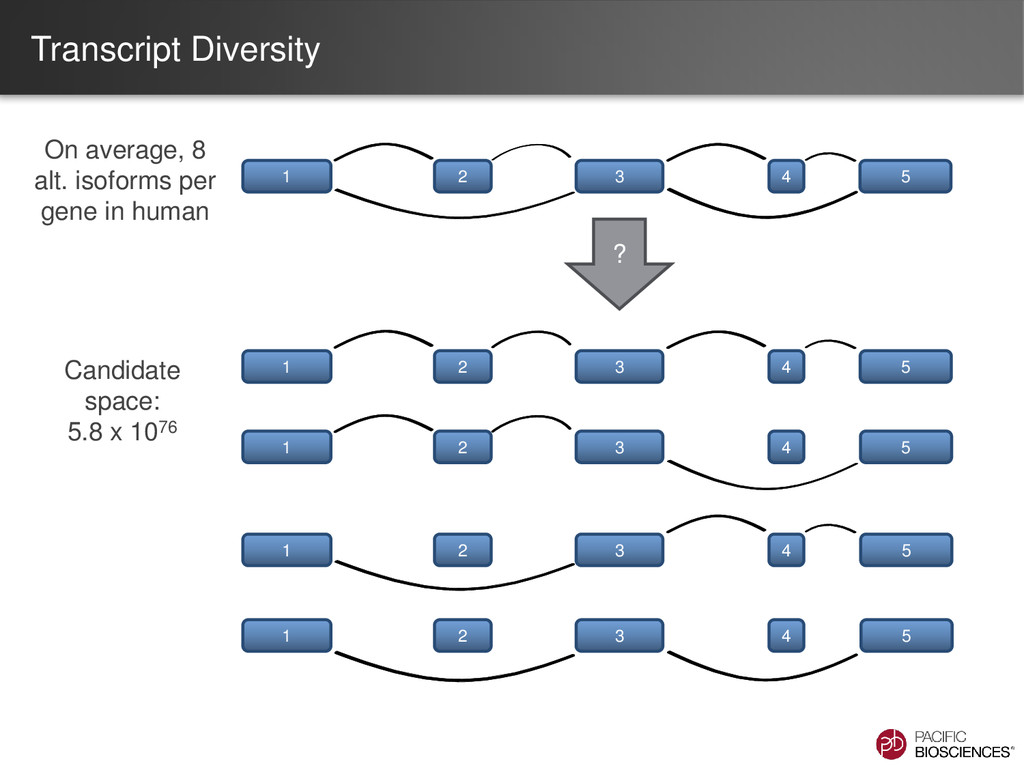
Transcript Diversity On average, 8 alt. isoforms per gene in
human Candidate space: 5.8 x 1076 1 2 3 4 5 1 2 3 4 5 1 2 3 4 5 1 2 3 4 5 1 2 3 4 5 ? -
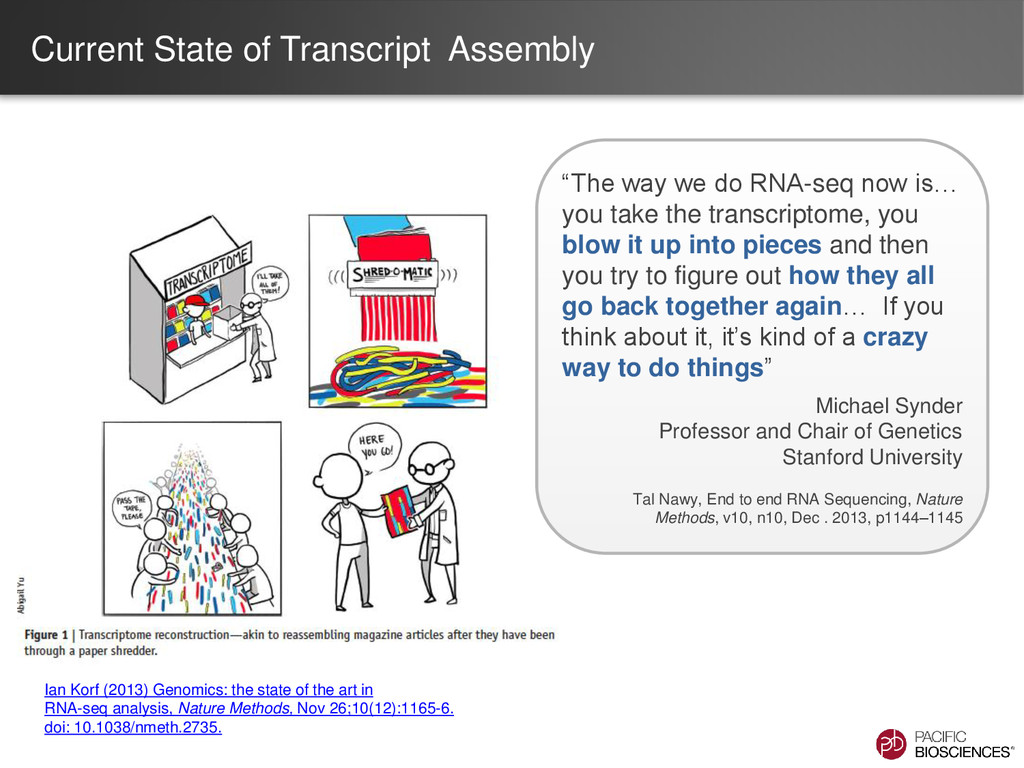
Current State of Transcript Assembly “The way we do RNA-seq
now is… you take the transcriptome, you blow it up into pieces and then you try to figure out how they all go back together again… If you think about it, it’s kind of a crazy way to do things” Michael Synder Professor and Chair of Genetics Stanford University Tal Nawy, End to end RNA Sequencing, Nature Methods, v10, n10, Dec . 2013, p1144–1145 Ian Korf (2013) Genomics: the state of the art in RNA-seq analysis, Nature Methods, Nov 26;10(12):1165-6. doi: 10.1038/nmeth.2735. -
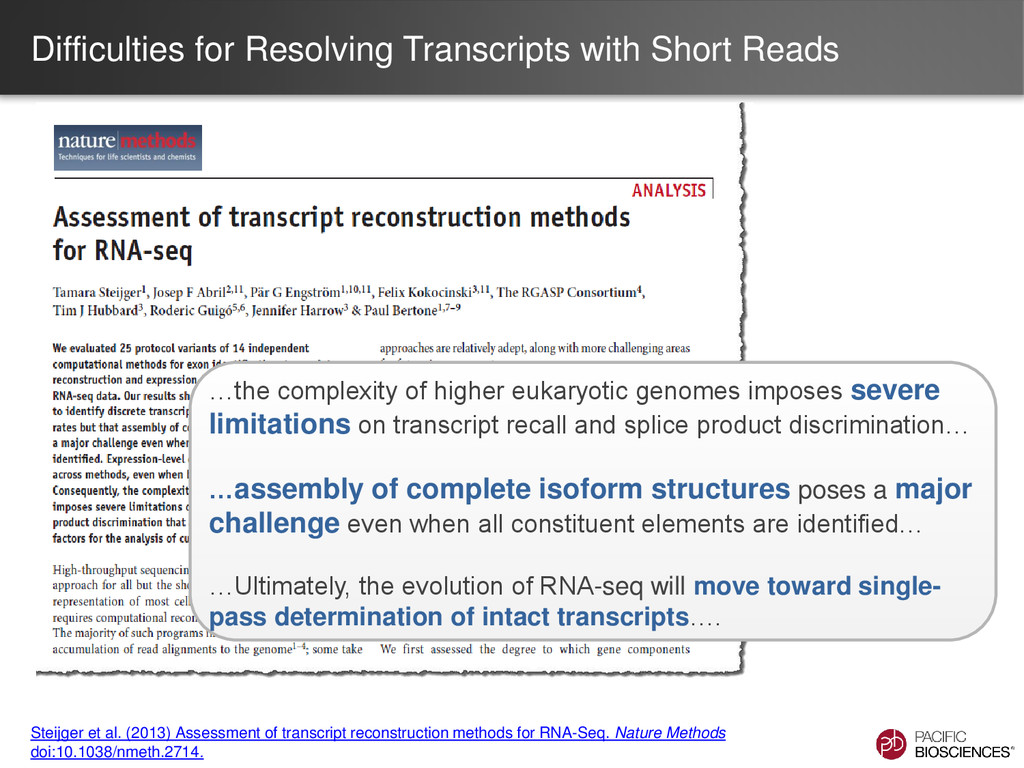
Difficulties for Resolving Transcripts with Short Reads Steijger et al.
(2013) Assessment of transcript reconstruction methods for RNA-Seq. Nature Methods doi:10.1038/nmeth.2714. …the complexity of higher eukaryotic genomes imposes severe limitations on transcript recall and splice product discrimination… …assembly of complete isoform structures poses a major challenge even when all constituent elements are identified… …Ultimately, the evolution of RNA-seq will move toward single- pass determination of intact transcripts…. -
Iso-Seq™ Method: PacBio® Sequencing for Isoform Analysis • Single-molecule observation
– one read = one transcript • Sequence transcript in full length – most transcripts 1 – 5 kb – PacBio’s avg. read length ~ 5 kb – no assembly required • No systematic bias – GC-rich, AT-rich, tandem repeats -
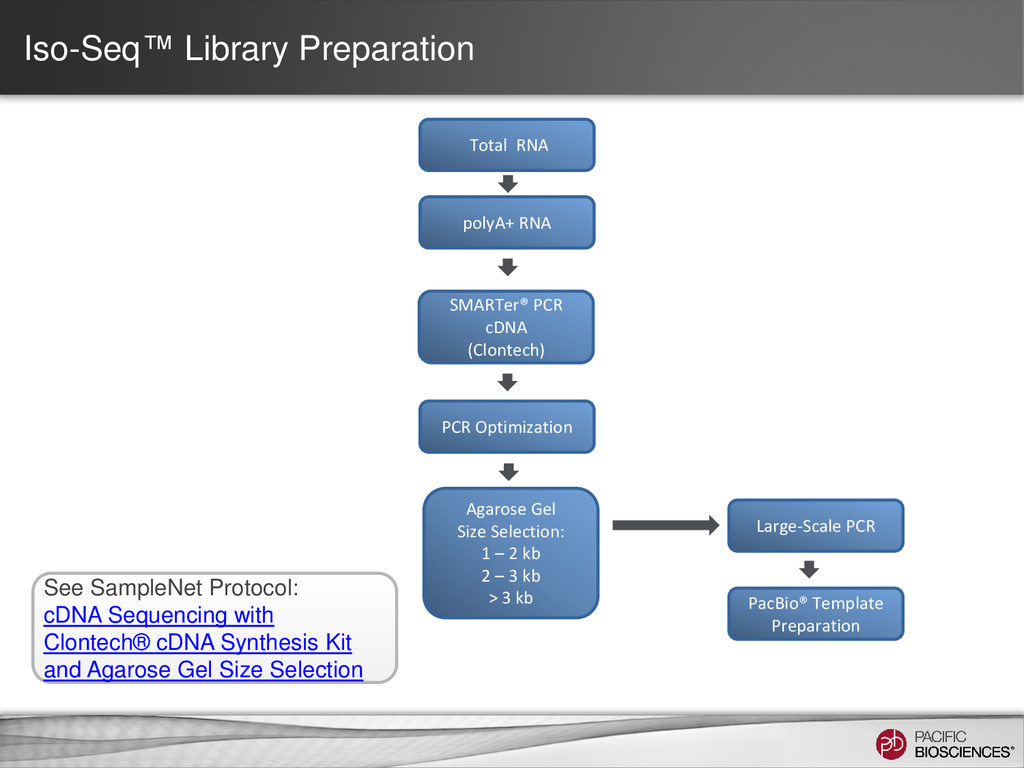
Iso-Seq™ Library Preparation See SampleNet Protocol: cDNA Sequencing with Clontech®
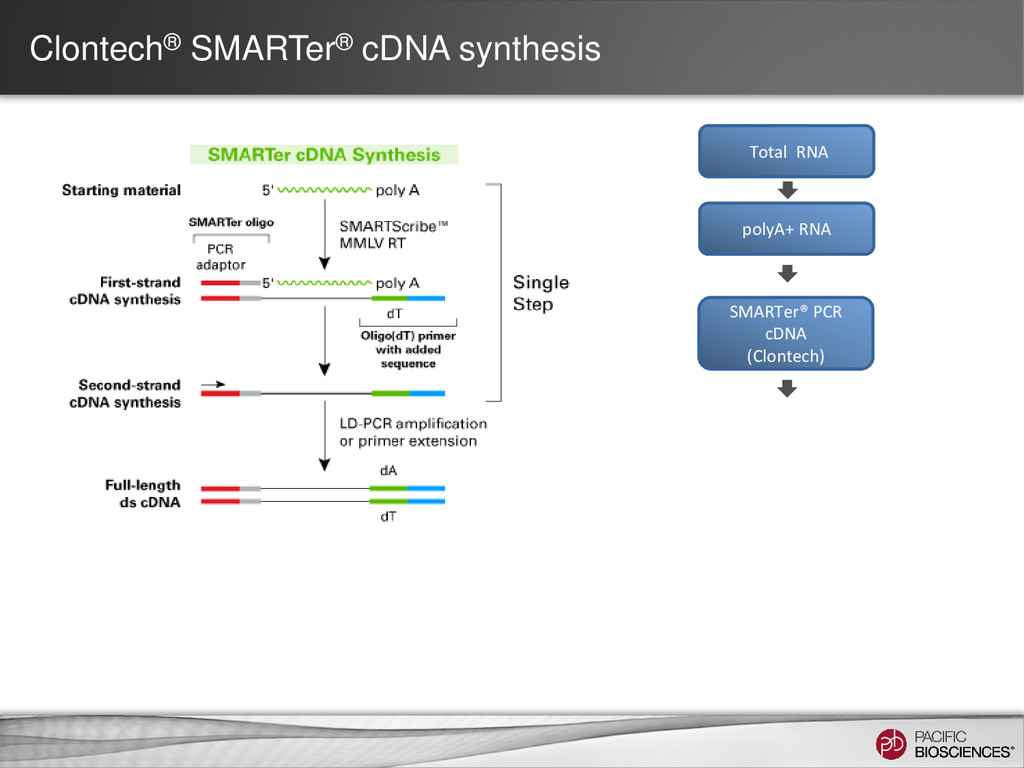
cDNA Synthesis Kit and Agarose Gel Size Selection polyA+ RNA PCR Optimization Agarose Gel Size Selection: 1 – 2 kb 2 – 3 kb > 3 kb Large-Scale PCR SMARTer® PCR cDNA (Clontech) PacBio® Template Preparation Total RNA -
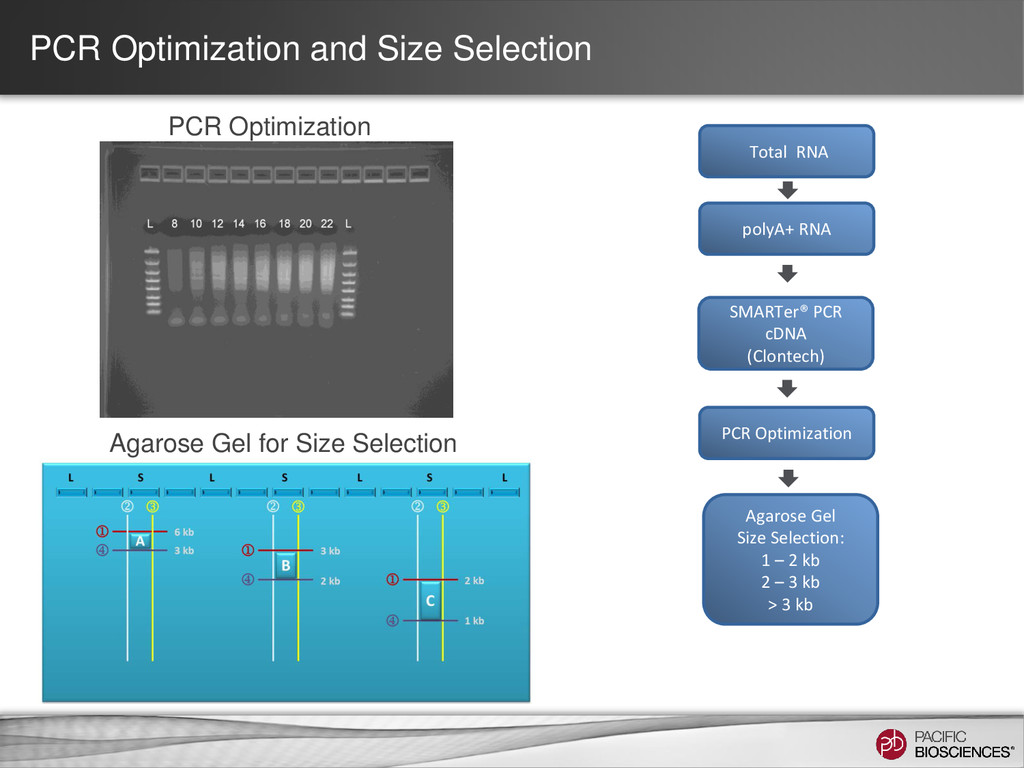
PCR Optimization and Size Selection PCR Optimization Agarose Gel for
Size Selection polyA+ RNA PCR Optimization Agarose Gel Size Selection: 1 – 2 kb 2 – 3 kb > 3 kb SMARTer® PCR cDNA (Clontech) Total RNA -
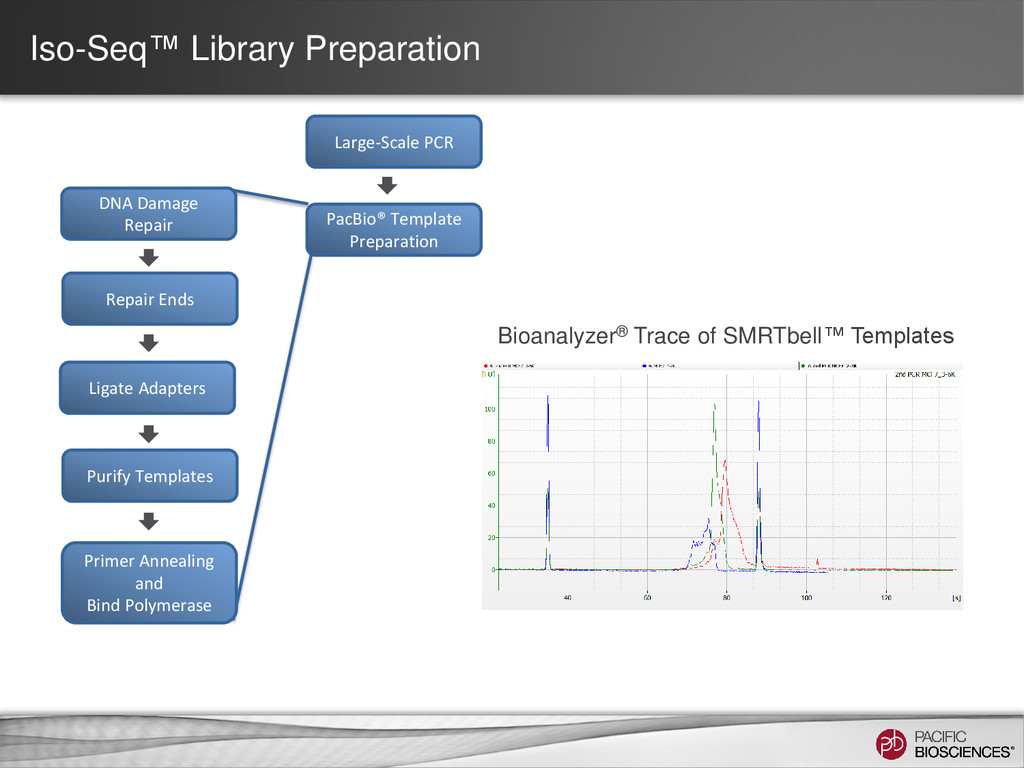
Iso-Seq™ Library Preparation Bioanalyzer® Trace of SMRTbell™ Templates Large-Scale PCR
PacBio® Template Preparation DNA Damage Repair Repair Ends Ligate Adapters Purify Templates Primer Annealing and Bind Polymerase -
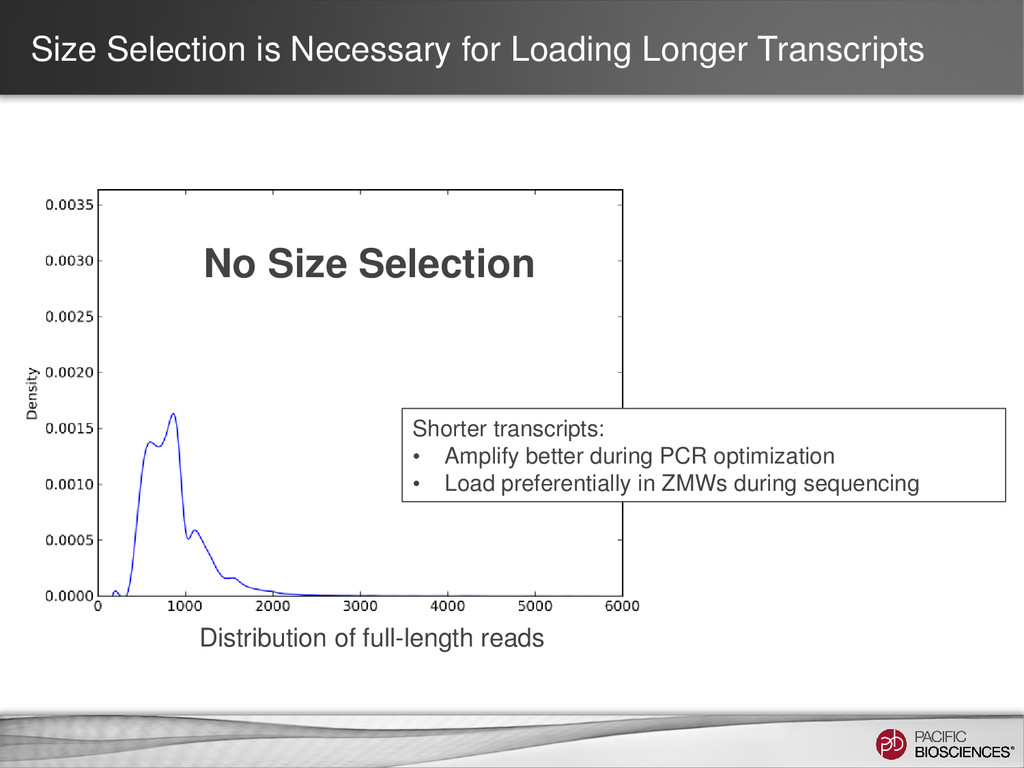
Distribution of full-length reads No Size Selection Size Selection is
Necessary for Loading Longer Transcripts Shorter transcripts: • Amplify better during PCR optimization • Load preferentially in ZMWs during sequencing -
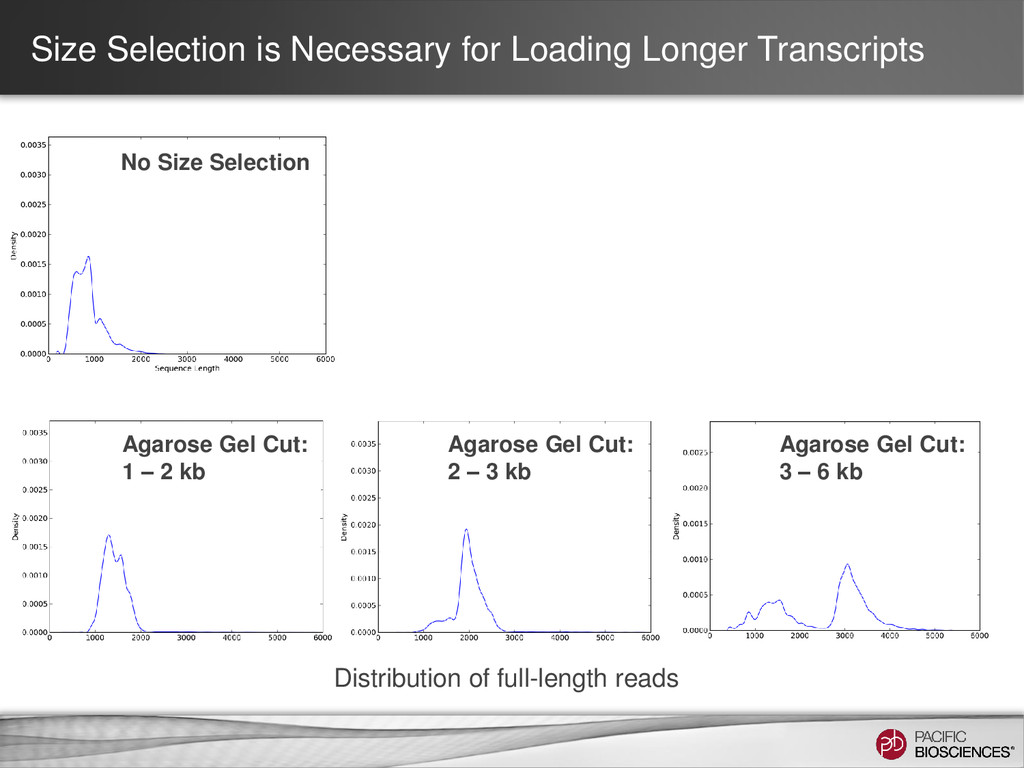
Size Selection is Necessary for Loading Longer Transcripts Distribution of
full-length reads No Size Selection Agarose Gel Cut: 1 – 2 kb Agarose Gel Cut: 2 – 3 kb Agarose Gel Cut: 3 – 6 kb -
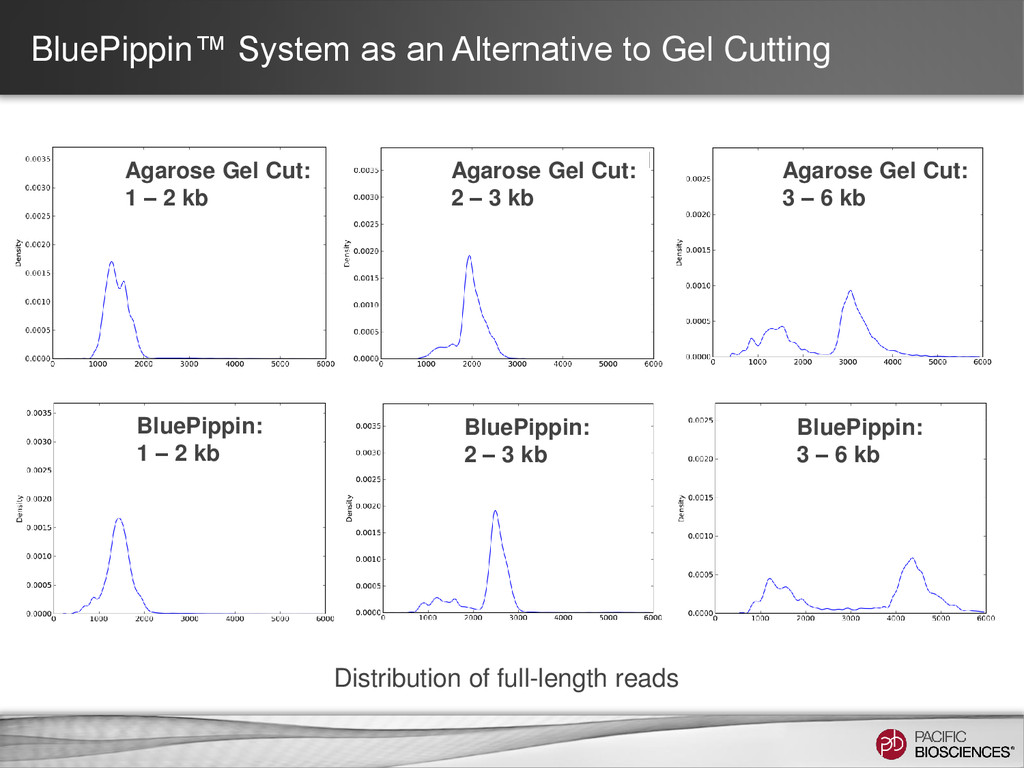
BluePippin™ System as an Alternative to Gel Cutting Agarose Gel
Cut: 1 – 2 kb Agarose Gel Cut: 2 – 3 kb Agarose Gel Cut: 3 – 6 kb Distribution of full-length reads BluePippin: 1 – 2 kb BluePippin: 2 – 3 kb BluePippin: 3 – 6 kb -
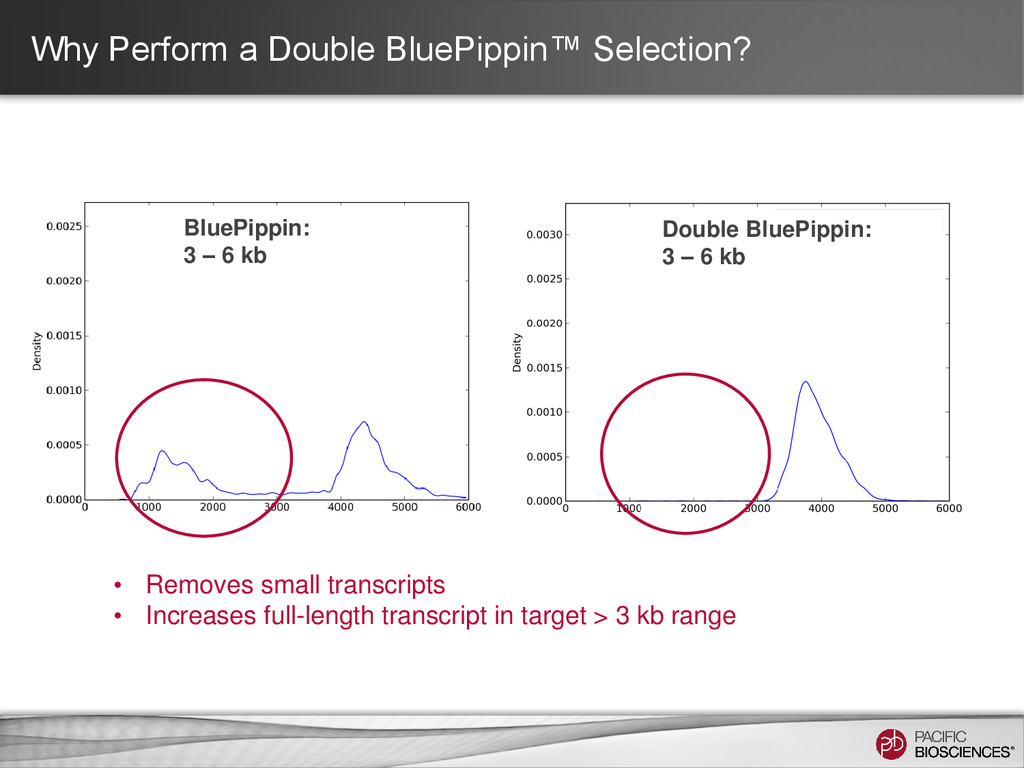
Why Perform a Double BluePippin™ Selection? • Removes small transcripts
• Increases full-length transcript in target > 3 kb range BluePippin: 3 – 6 kb Double BluePippin: 3 – 6 kb -
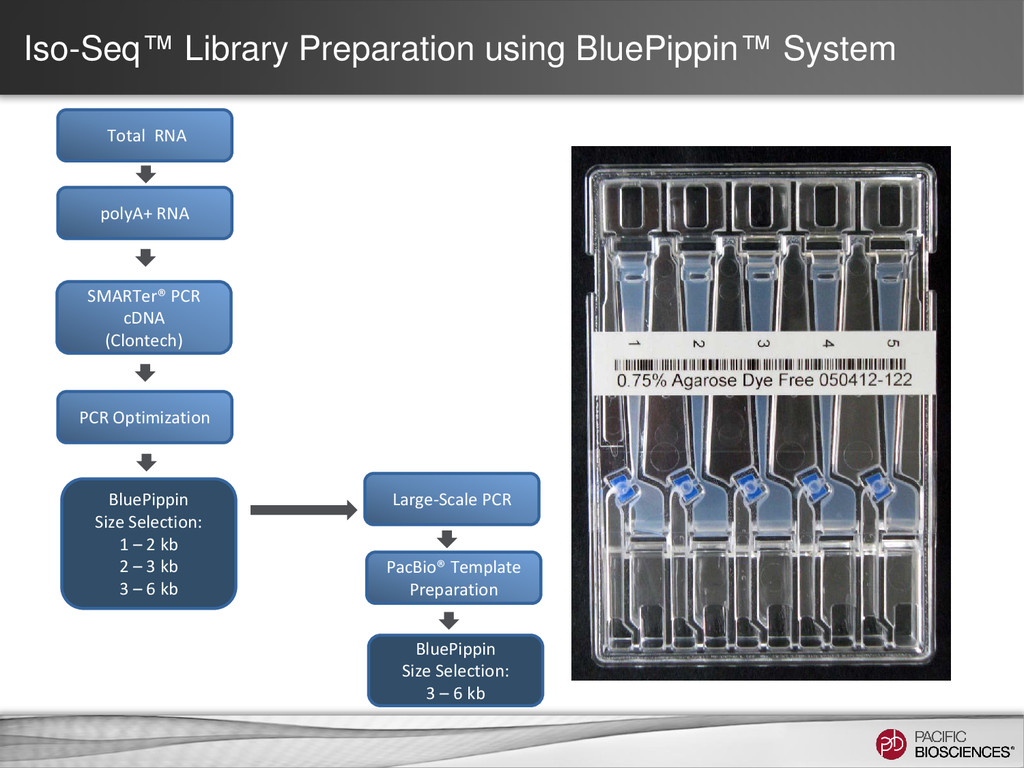
Iso-Seq™ Library Preparation using BluePippin™ System polyA+ RNA PCR Optimization
BluePippin Size Selection: 1 – 2 kb 2 – 3 kb 3 – 6 kb Large-Scale PCR SMARTer® PCR cDNA (Clontech) PacBio® Template Preparation Total RNA BluePippin Size Selection: 3 – 6 kb -
Goal of Quality Control • Identify full-length reads • Validate
size selection • Detect and remove artificial chimeras -
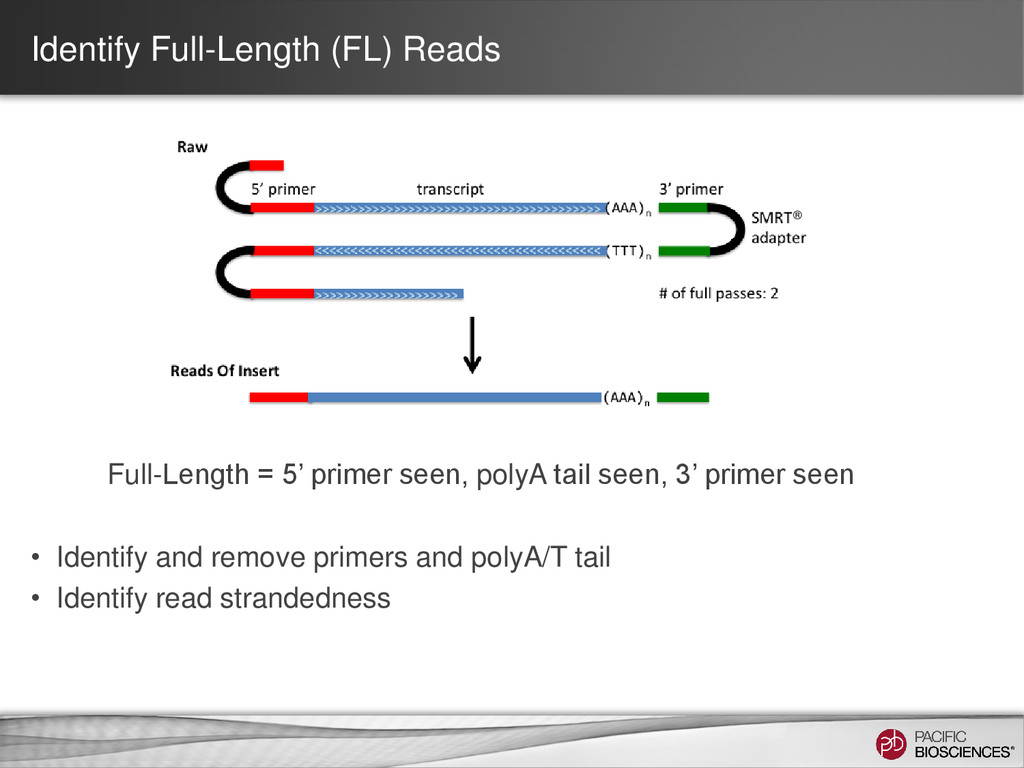
Identify Full-Length (FL) Reads Full-Length = 5’ primer seen, polyA
tail seen, 3’ primer seen • Identify and remove primers and polyA/T tail • Identify read strandedness ® -
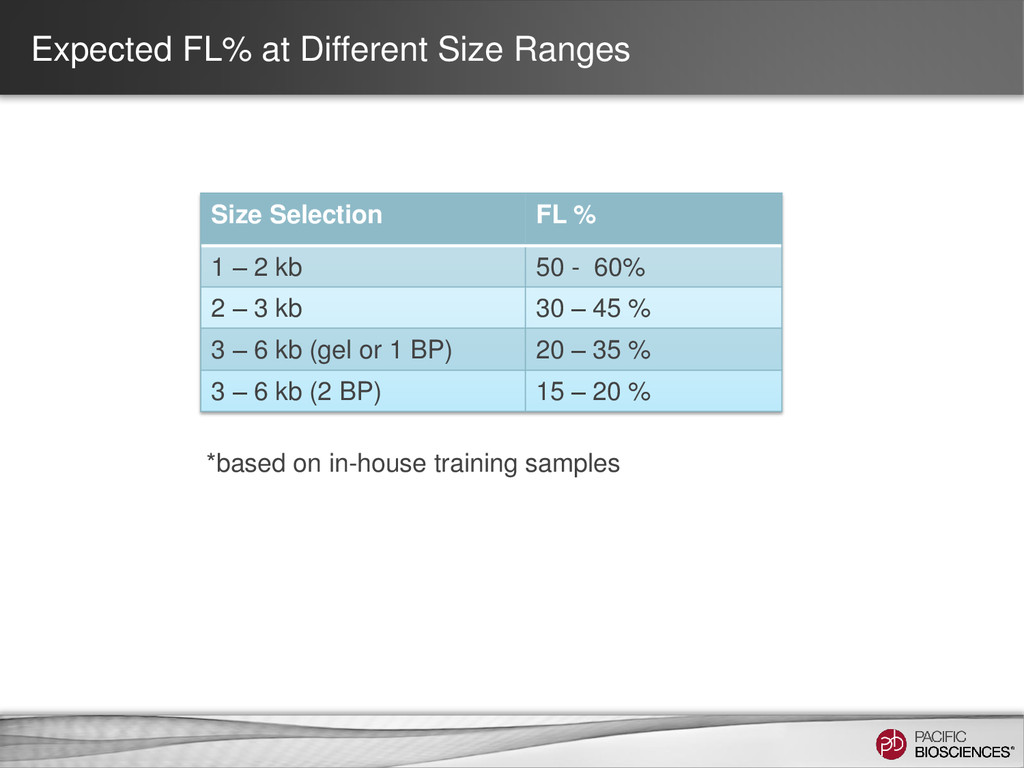
Expected FL% at Different Size Ranges Size Selection FL %
1 – 2 kb 50 - 60% 2 – 3 kb 30 – 45 % 3 – 6 kb (gel or 1 BP) 20 – 35 % 3 – 6 kb (2 BP) 15 – 20 % *based on in-house training samples -
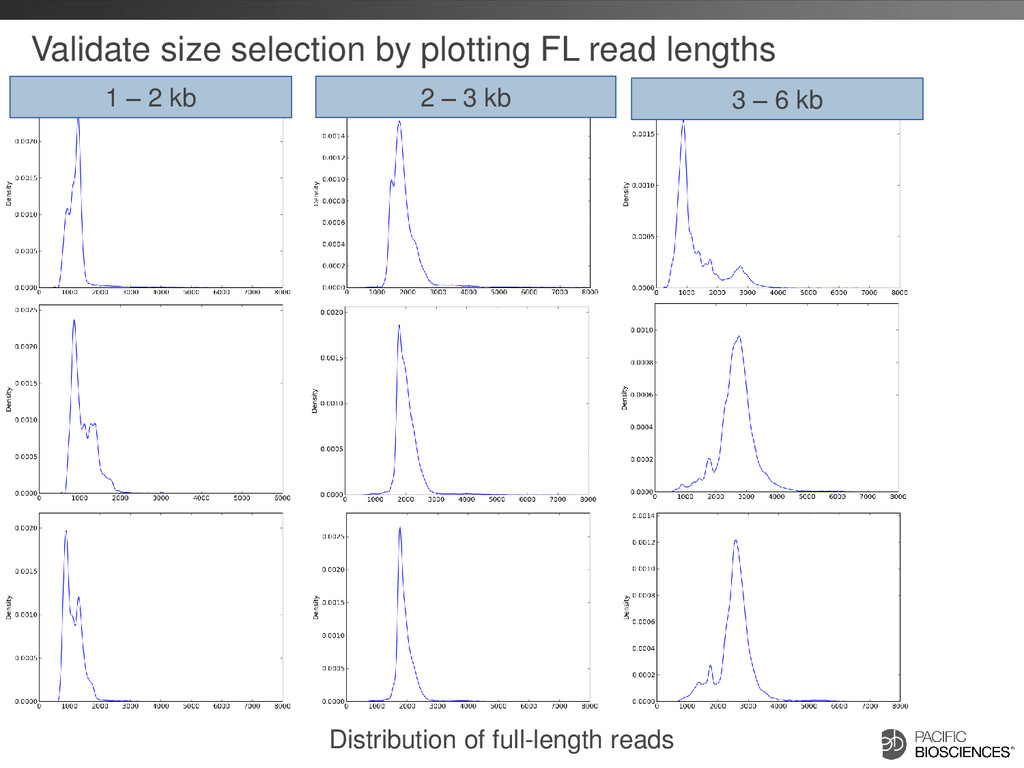
Validate size selection by plotting FL read lengths 1 –
2 kb 2 – 3 kb 3 – 6 kb Distribution of full-length reads -
Artificial Chimeras (1) Cause Outcome Detection Low SMRT® adaptor concentration
Primer-ligated cDNA form concatemers High incidence of artificial chimera (identifiable cDNA primer in the middle) MCF=7 Clontech 1 – 2 kb Trainee Artificial chimeras A 2415 (3.9%) B 79 (0.5%) C 304 (0.2%) D 235 (0.2%) (AAA)n Artificial Concatemer 5’ primer Transcript 1 Transcript 2 3’ primer 3’ primer 5’ primer -
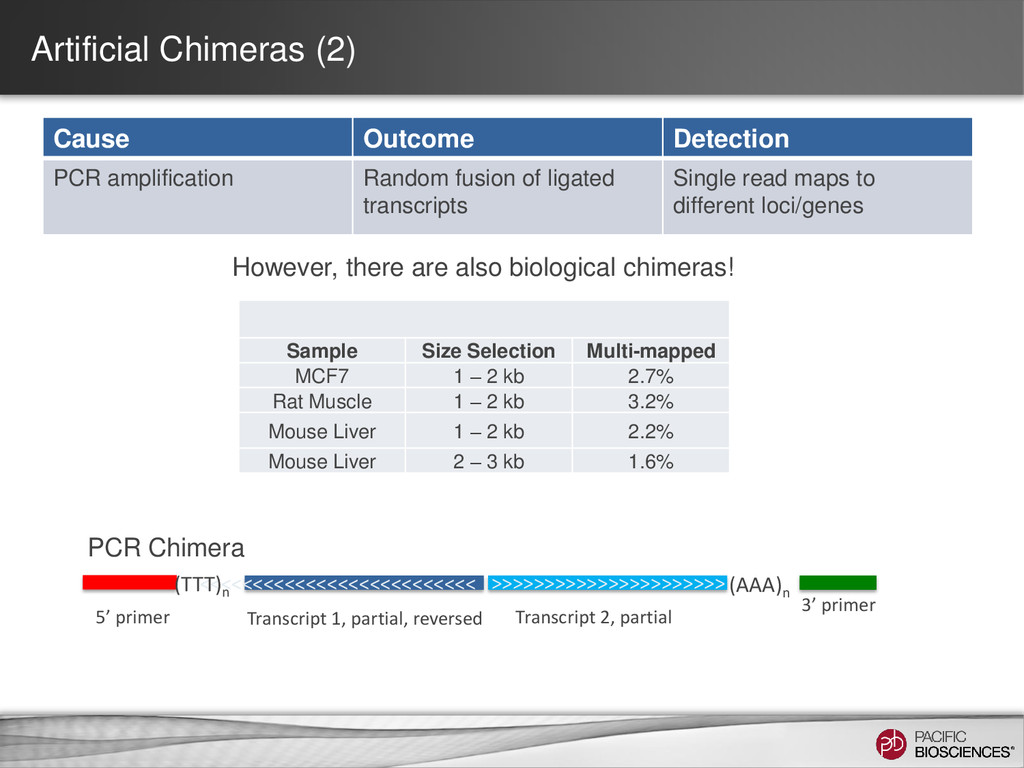
Artificial Chimeras (2) Cause Outcome Detection PCR amplification Random fusion
of ligated transcripts Single read maps to different loci/genes <<<<<<<<<<<<<<<<<<<<<<<<<< Transcript 1, partial, reversed Transcript 2, partial 5’ primer 3’ primer (TTT)n (AAA)n >>>>>>>>>>>>>>>>>>>>>> Sample Size Selection Multi-mapped MCF7 1 – 2 kb 2.7% Rat Muscle 1 – 2 kb 3.2% Mouse Liver 1 – 2 kb 2.2% Mouse Liver 2 – 3 kb 1.6% However, there are also biological chimeras! PCR Chimera -
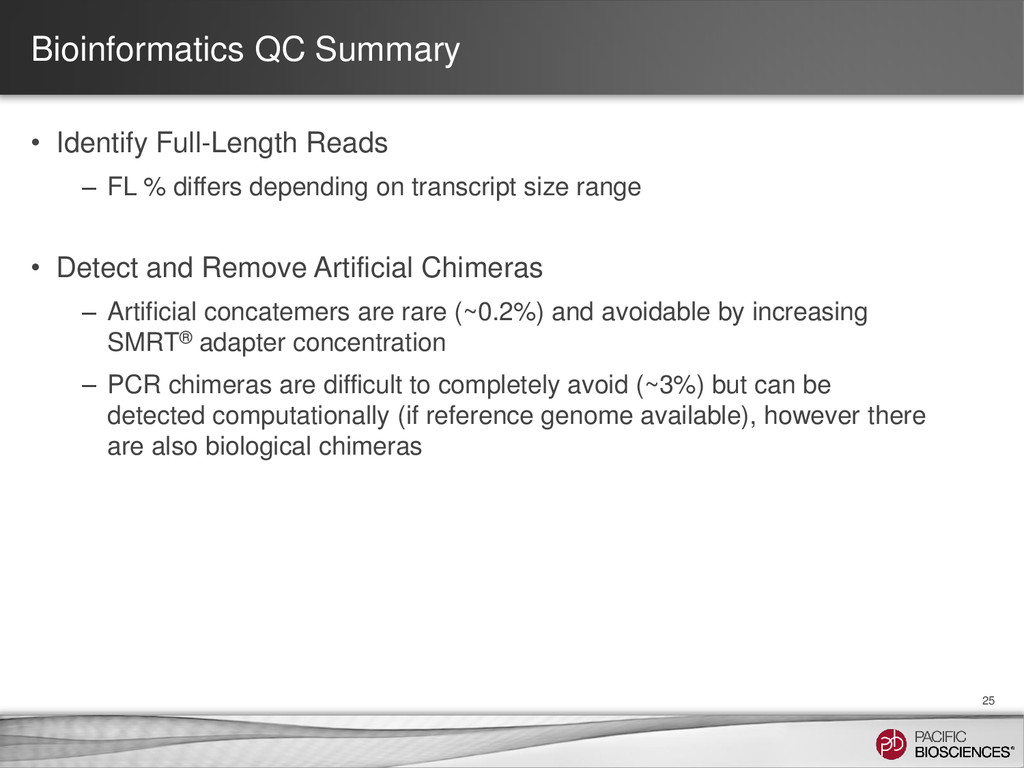
Bioinformatics QC Summary • Identify Full-Length Reads – FL %
differs depending on transcript size range • Detect and Remove Artificial Chimeras – Artificial concatemers are rare (~0.2%) and avoidable by increasing SMRT® adapter concentration – PCR chimeras are difficult to completely avoid (~3%) but can be detected computationally (if reference genome available), however there are also biological chimeras 25 -
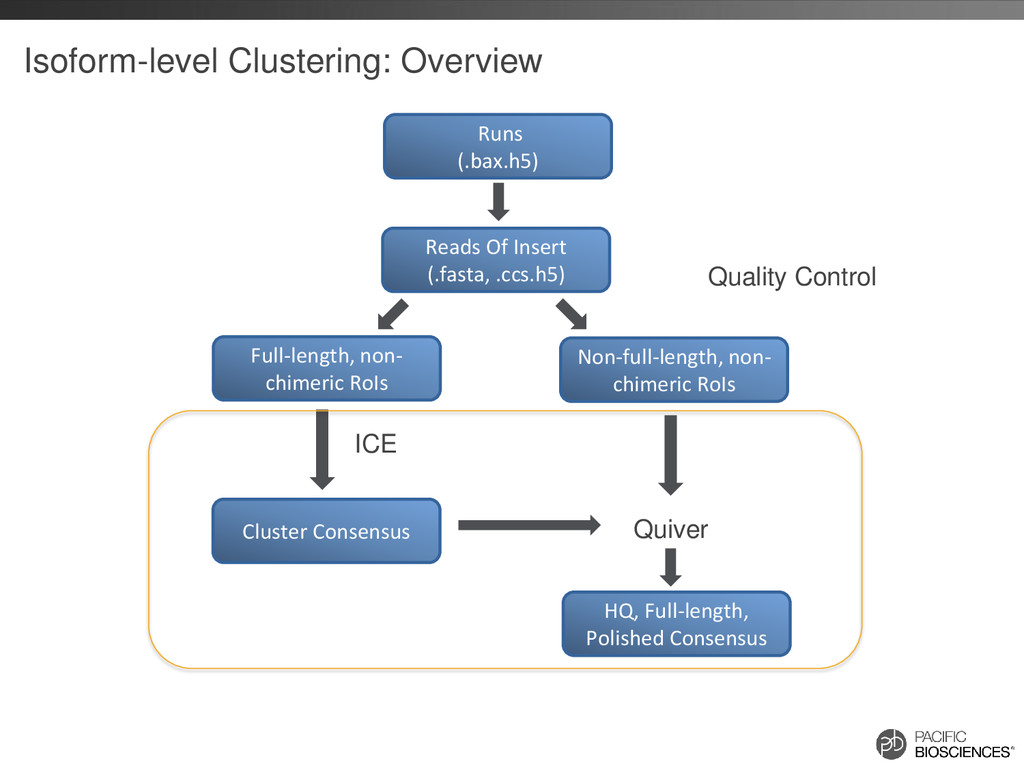
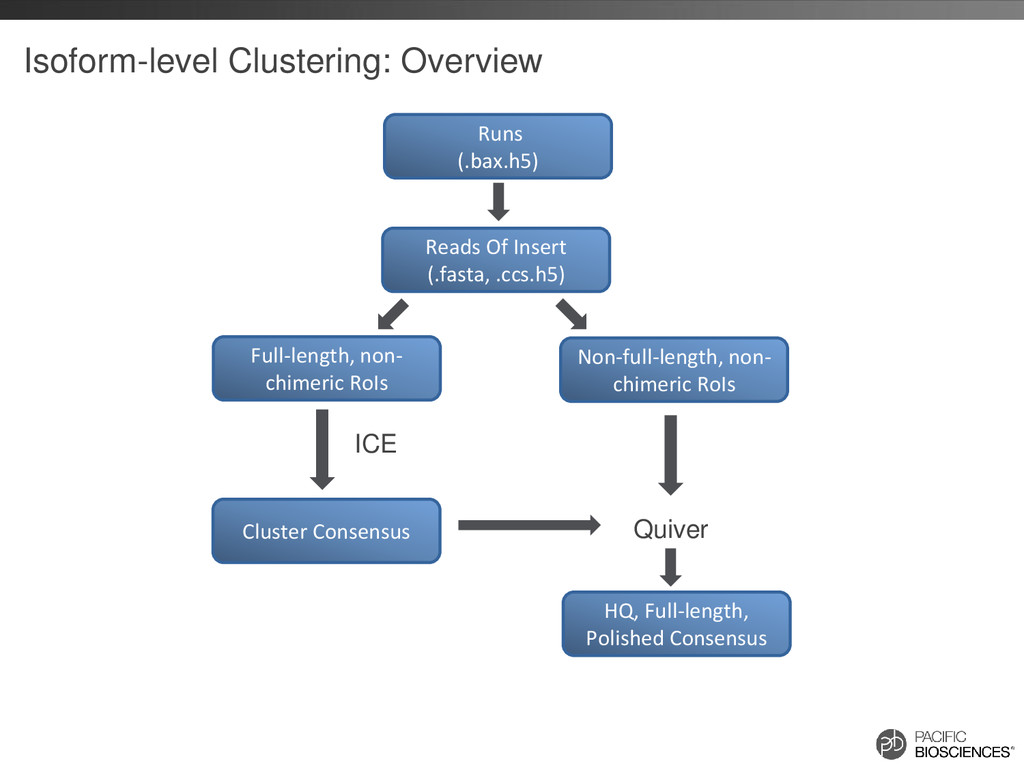
Runs (.bax.h5) Reads Of Insert (.fasta, .ccs.h5) Full-length, non- chimeric
RoIs Non-full-length, non- chimeric RoIs Cluster Consensus HQ, Full-length, Polished Consensus Quiver ICE Isoform-level Clustering: Overview Quality Control -
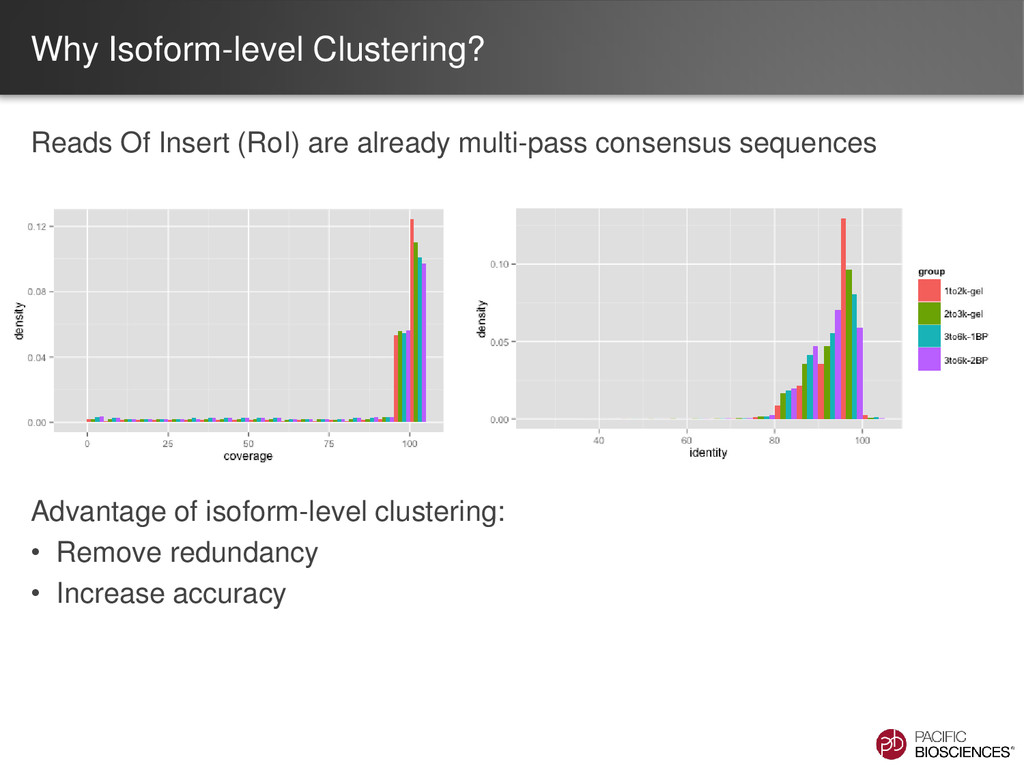
Why Isoform-level Clustering? Reads Of Insert (RoI) are already multi-pass
consensus sequences Advantage of isoform-level clustering: • Remove redundancy • Increase accuracy -
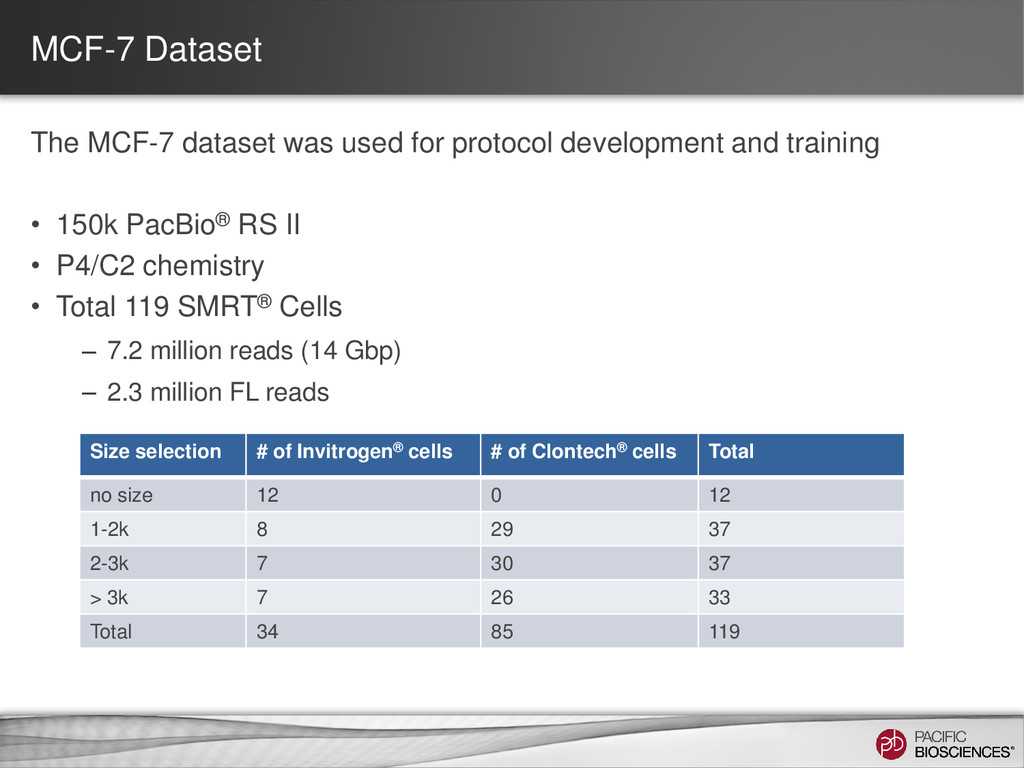
MCF-7 Dataset The MCF-7 dataset was used for protocol development
and training • 150k PacBio® RS II • P4/C2 chemistry • Total 119 SMRT® Cells – 7.2 million reads (14 Gbp) – 2.3 million FL reads Size selection # of Invitrogen® cells # of Clontech® cells Total no size 12 0 12 1-2k 8 29 37 2-3k 7 30 37 > 3k 7 26 33 Total 34 85 119 -
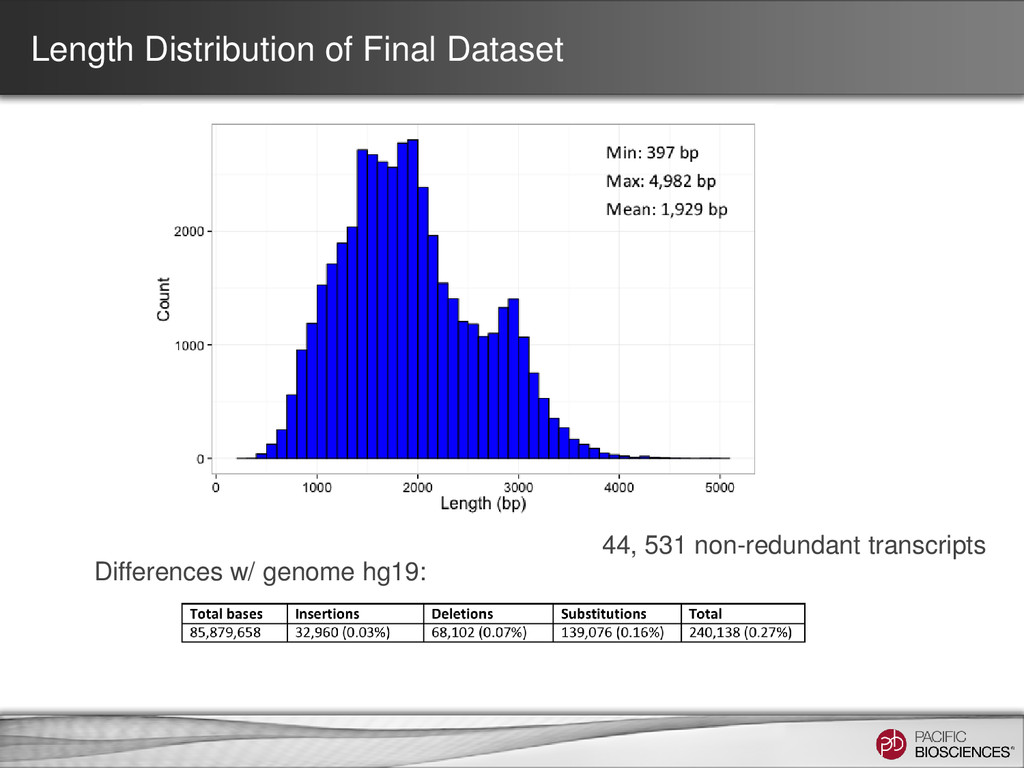
Length Distribution of Final Dataset Differences w/ genome hg19: 44,
531 non-redundant transcripts -
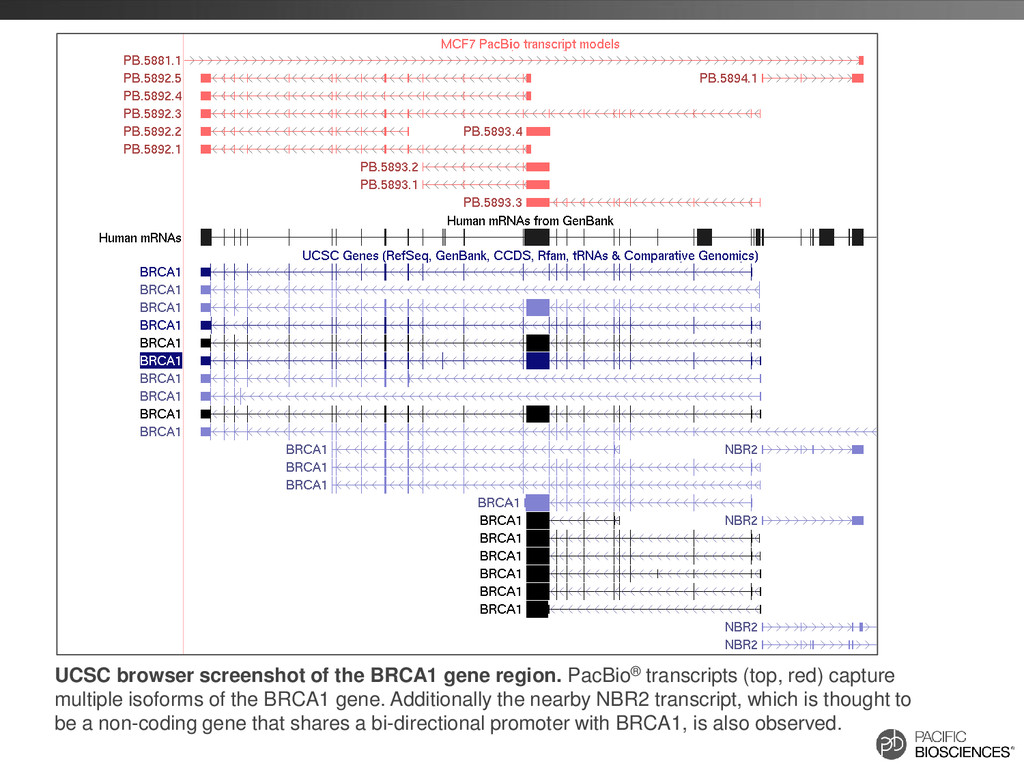
UCSC browser screenshot of the BRCA1 gene region. PacBio® transcripts
(top, red) capture multiple isoforms of the BRCA1 gene. Additionally the nearby NBR2 transcript, which is thought to be a non-coding gene that shares a bi-directional promoter with BRCA1, is also observed. -
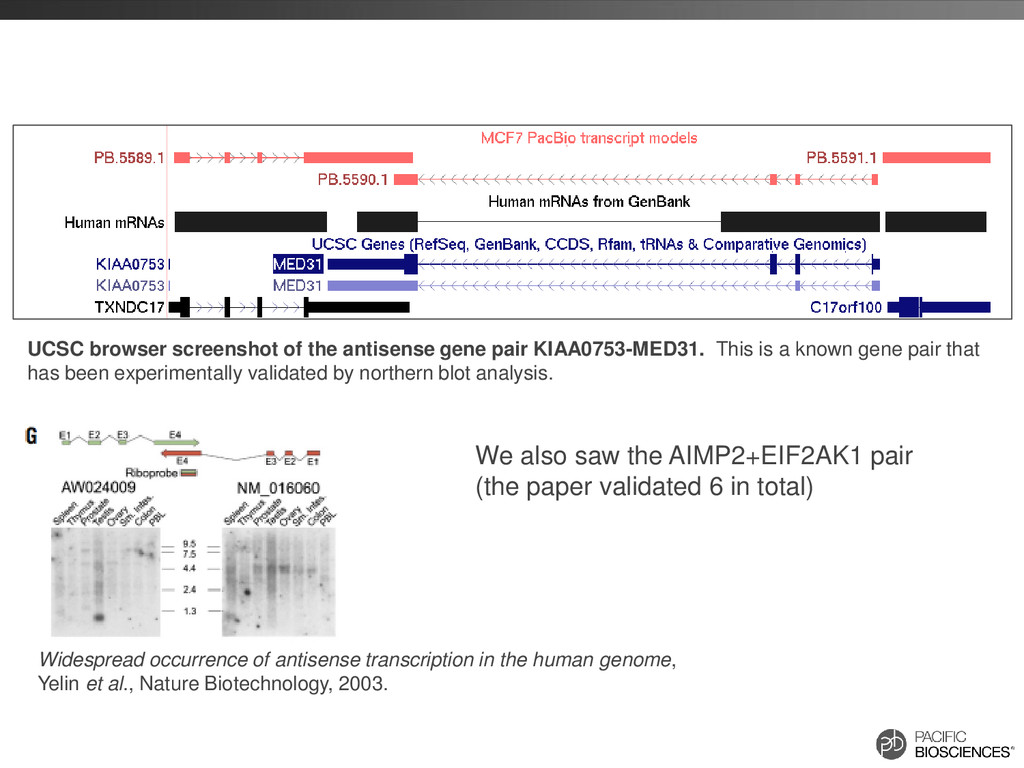
UCSC browser screenshot of the antisense gene pair KIAA0753-MED31. This
is a known gene pair that has been experimentally validated by northern blot analysis. Widespread occurrence of antisense transcription in the human genome, Yelin et al., Nature Biotechnology, 2003. We also saw the AIMP2+EIF2AK1 pair (the paper validated 6 in total) -
Candidate Cancer Fusion Genes • Fusion genes map to two
distinct coding loci • Use genomic aligners (GMAP) to find fusion candidates • However, PCR chimeras can form during library preparation and are hard to distinguish from true cancer fusion genes • Current solution: create several “filtering steps” – require a minimum number of full-length, raw-read support – require that each mapped locus encodes a different gene • Post-filtering: 93 fusion candidates -
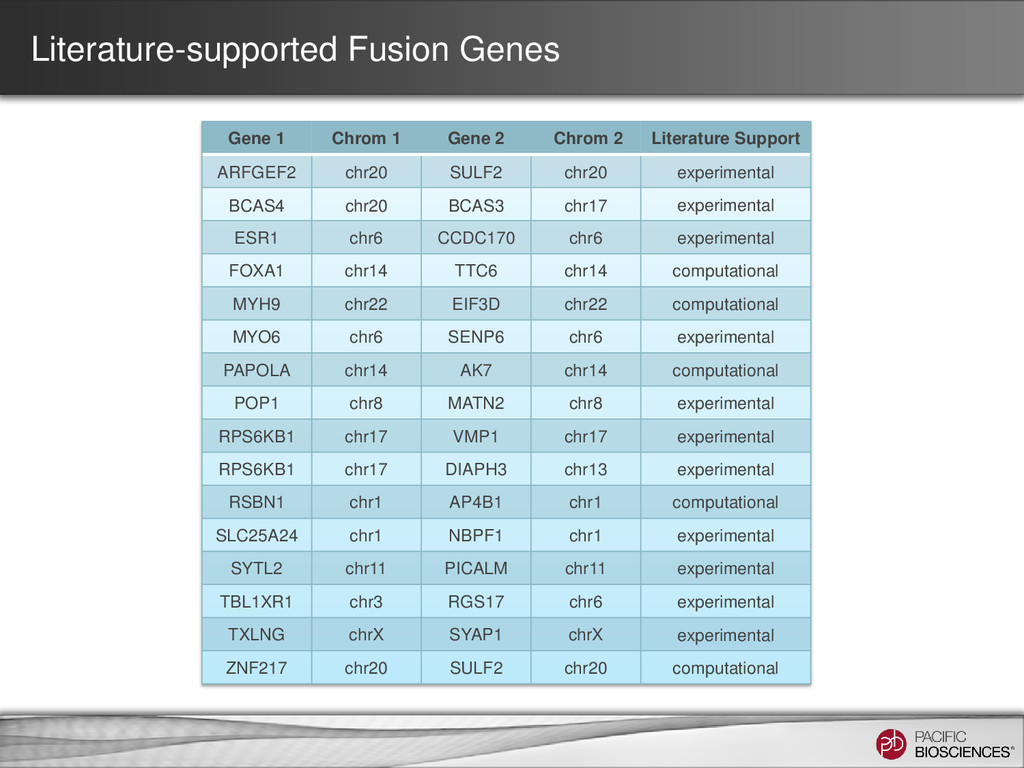
Literature-supported Fusion Genes Gene 1 Chrom 1 Gene 2 Chrom
2 Literature Support ARFGEF2 chr20 SULF2 chr20 experimental BCAS4 chr20 BCAS3 chr17 experimental ESR1 chr6 CCDC170 chr6 experimental FOXA1 chr14 TTC6 chr14 computational MYH9 chr22 EIF3D chr22 computational MYO6 chr6 SENP6 chr6 experimental PAPOLA chr14 AK7 chr14 computational POP1 chr8 MATN2 chr8 experimental RPS6KB1 chr17 VMP1 chr17 experimental RPS6KB1 chr17 DIAPH3 chr13 experimental RSBN1 chr1 AP4B1 chr1 computational SLC25A24 chr1 NBPF1 chr1 experimental SYTL2 chr11 PICALM chr11 experimental TBL1XR1 chr3 RGS17 chr6 experimental TXLNG chrX SYAP1 chrX experimental ZNF217 chr20 SULF2 chr20 computational -
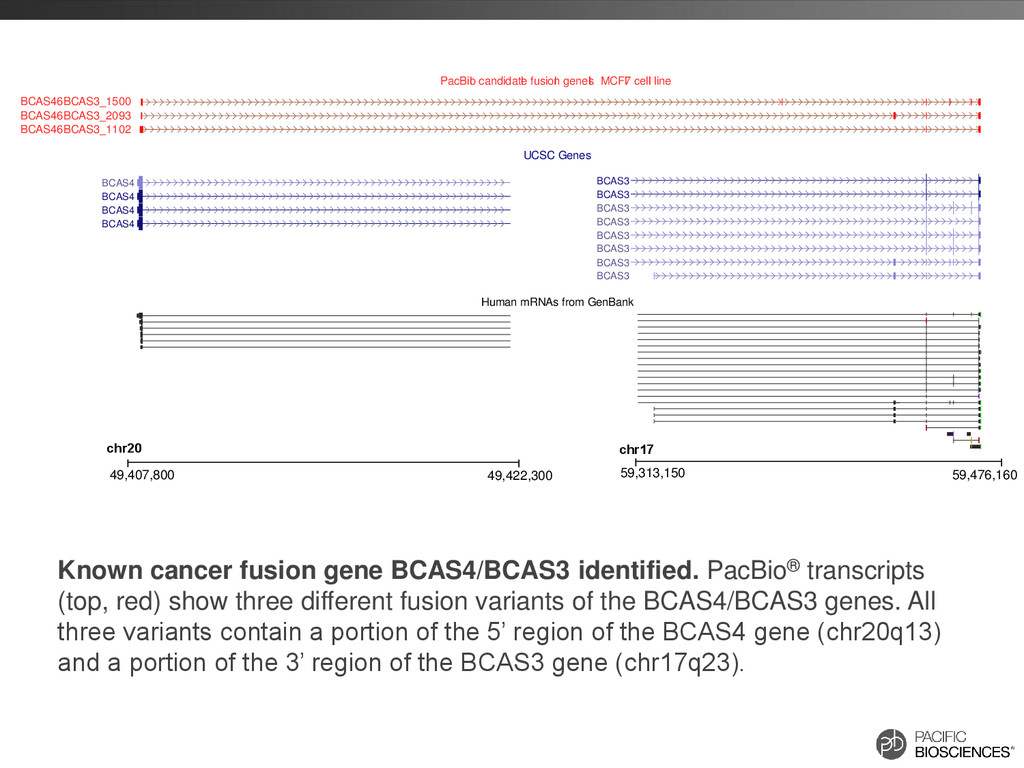
BCAS3 BCAS3 BCAS3 BCAS3 BCAS3 BCAS3 BCAS3 BCAS3 BCAS4 BCAS4
BCAS4 BCAS4 BCAS46BCAS3_1500 BCAS46BCAS3_2093 BCAS46BCAS3_1102 PacBio l candidate l fusion l genes l l l - l l l MCF7 l cell l line UCSC Genes Human mRNAs from GenBank chr20 49,407,800 49,422,300 chr17 59,313,150 59,476,160 Known cancer fusion gene BCAS4/BCAS3 identified. PacBio® transcripts (top, red) show three different fusion variants of the BCAS4/BCAS3 genes. All three variants contain a portion of the 5’ region of the BCAS4 gene (chr20q13) and a portion of the 3’ region of the BCAS3 gene (chr17q23). -
Rat Heart and Lung Transcriptome Sample Number of cells at
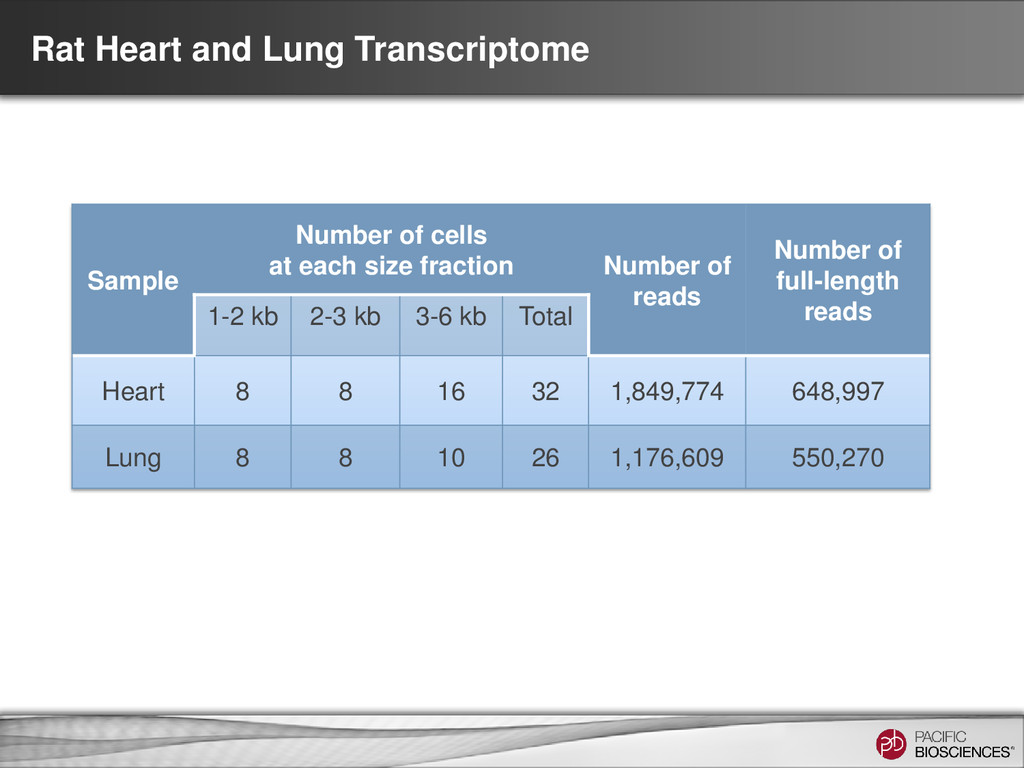
each size fraction Number of reads Number of full-length reads 1-2 kb 2-3 kb 3-6 kb Total Heart 8 8 16 32 1,849,774 648,997 Lung 8 8 10 26 1,176,609 550,270 -
Consensus Transcript Length & Accuracy 41 0 2000 4000 6000
8000 0 2000 4000 6000 Consensus transcript length Count group Heart Lung min: 138 bp max: 7,952 bp median: 1,563 bp Sample Number of transcripts Aligned transcript coverage Base differences against reference genome 95-99% 100% Sub Ins Del Total Heart 15,930 3,769 (24%) 11,728 (73%) 89,728 (0.26%) 48,289 (0.14%) 53,599 (0.16%) 191,616 (0.57%) Lung 14,455 2,685 (19%) 10,762 (75%) 99,123 (0.39%) 33,783 (0.13%) 48,271 (0.19%) 181,177 (0.73%) -
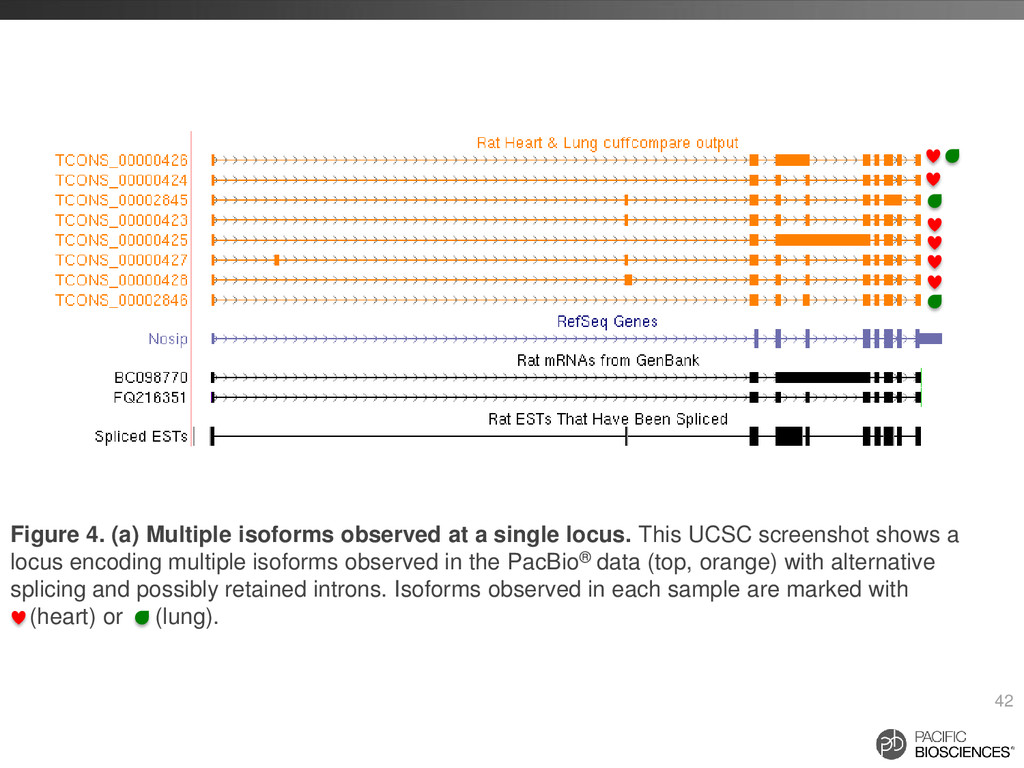
42 Figure 4. (a) Multiple isoforms observed at a single
locus. This UCSC screenshot shows a locus encoding multiple isoforms observed in the PacBio® data (top, orange) with alternative splicing and possibly retained introns. Isoforms observed in each sample are marked with (heart) or (lung). -
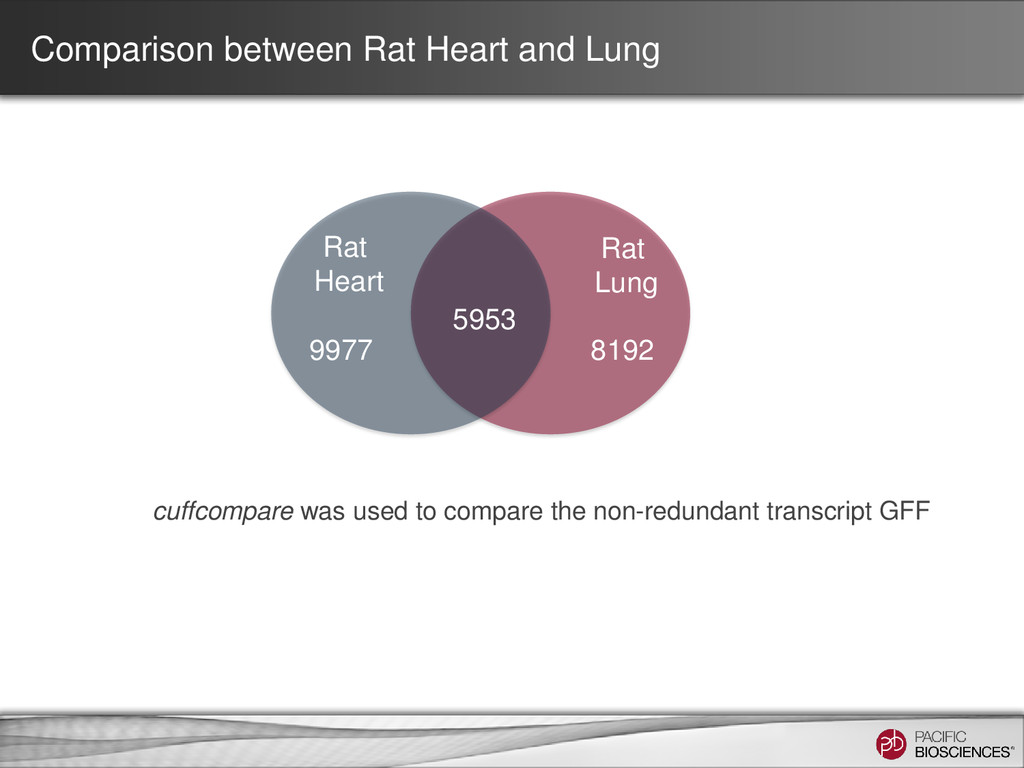
5953 8192 9977 Rat Heart Rat Lung Comparison between Rat
Heart and Lung cuffcompare was used to compare the non-redundant transcript GFF -
Goal for Iso-Seq™ Protocol 45 Understand transcriptome complexity using accurate,
unassembled, full-length long reads -
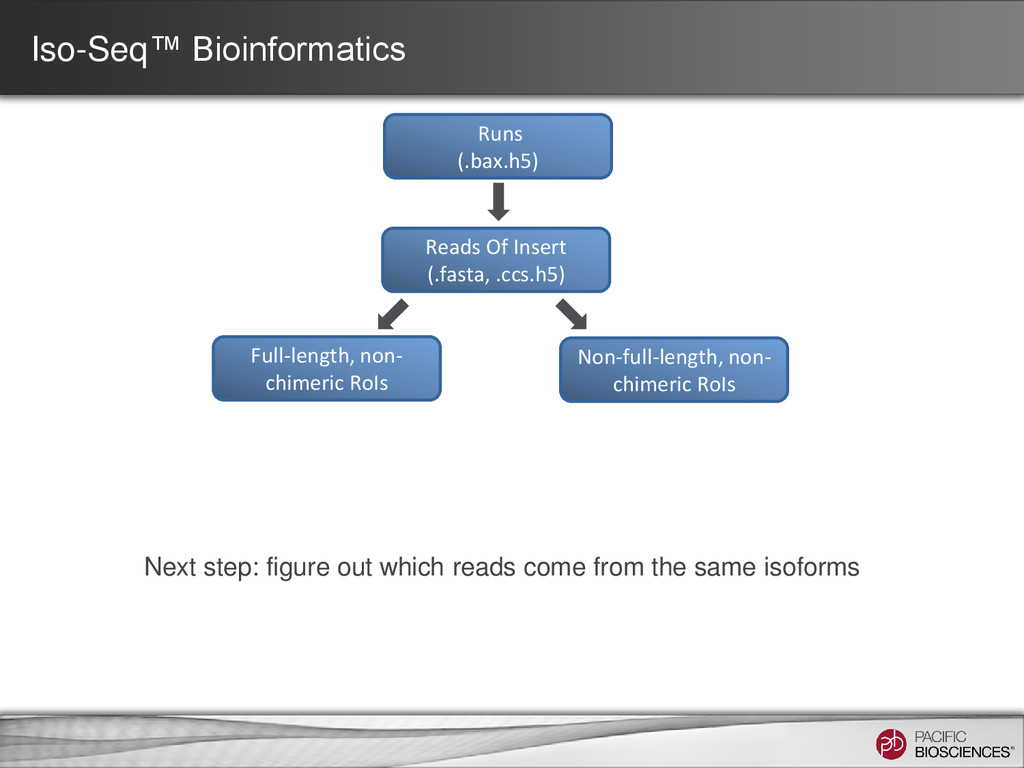
Runs (.bax.h5) Reads Of Insert (.fasta, .ccs.h5) Full-length, non- chimeric
RoIs Non-full-length, non- chimeric RoIs Iso-Seq™ Bioinformatics Next step: figure out which reads come from the same isoforms -
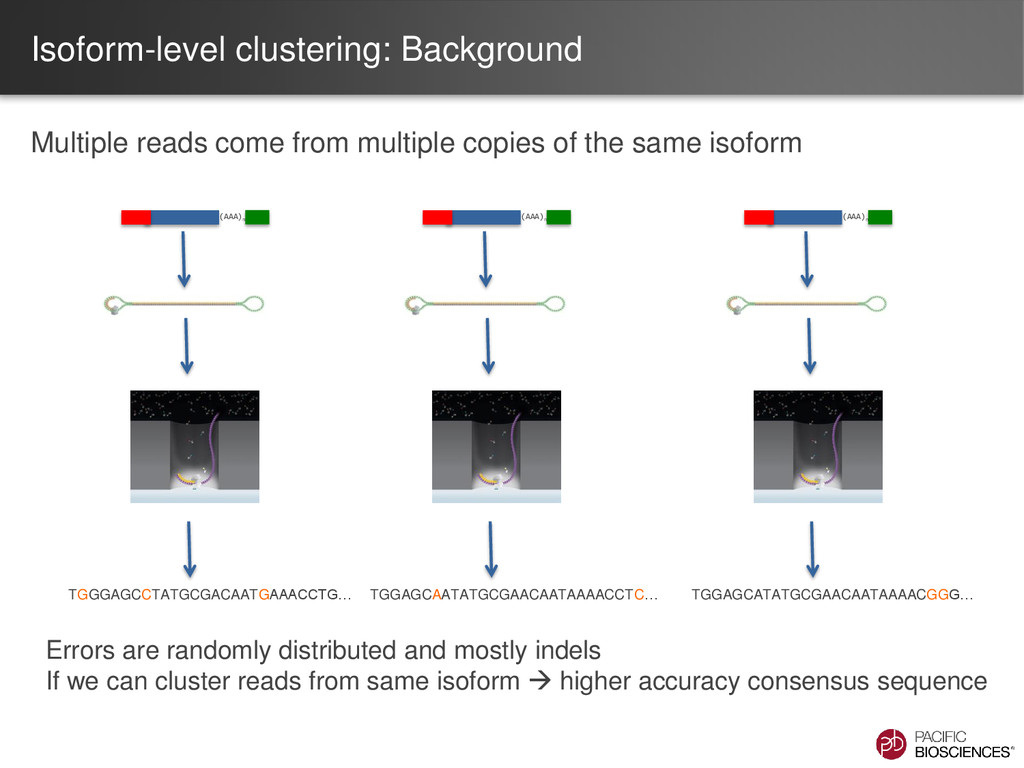
Isoform-level clustering: Background Multiple reads come from multiple copies of
the same isoform (AAA)n TGGGAGCCTATGCGACAATGAAACCTG… (AAA)n TGGAGCAATATGCGAACAATAAAACCTC… (AAA)n TGGAGCATATGCGAACAATAAAACGGG… Errors are randomly distributed and mostly indels If we can cluster reads from same isoform higher accuracy consensus sequence -
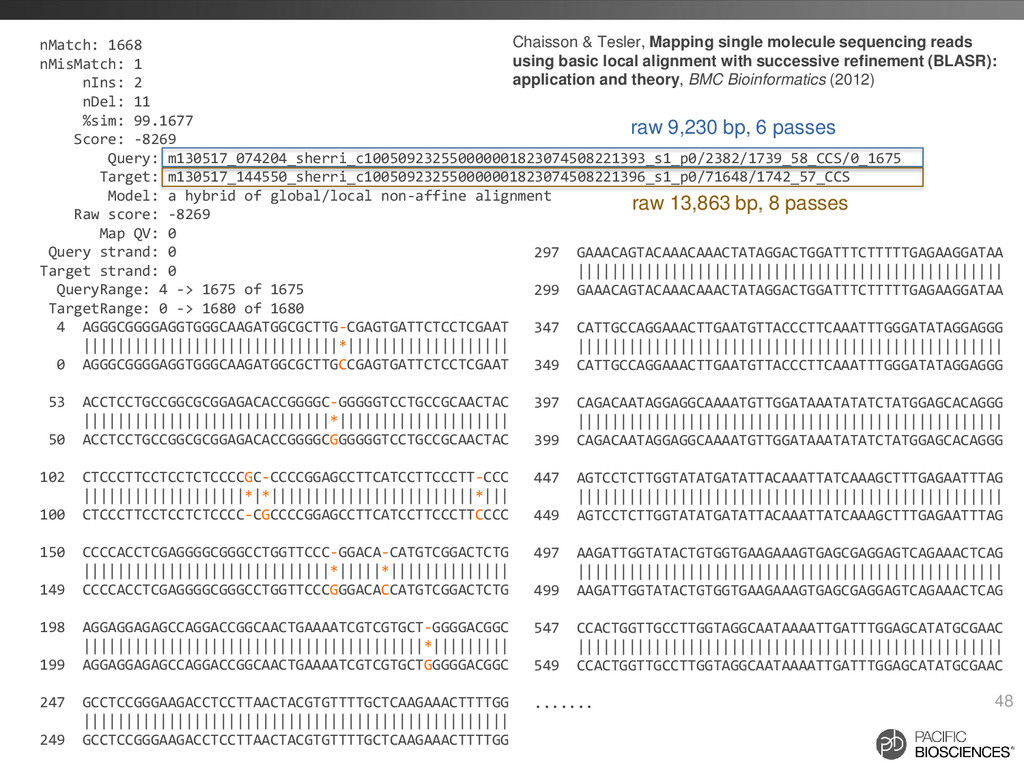
48 nMatch: 1668 nMisMatch: 1 nIns: 2 nDel: 11 %sim:
99.1677 Score: -8269 Query: m130517_074204_sherri_c100509232550000001823074508221393_s1_p0/2382/1739_58_CCS/0_1675 Target: m130517_144550_sherri_c100509232550000001823074508221396_s1_p0/71648/1742_57_CCS Model: a hybrid of global/local non-affine alignment Raw score: -8269 Map QV: 0 Query strand: 0 Target strand: 0 QueryRange: 4 -> 1675 of 1675 TargetRange: 0 -> 1680 of 1680 4 AGGGCGGGGAGGTGGGCAAGATGGCGCTTG-CGAGTGATTCTCCTCGAAT ||||||||||||||||||||||||||||||*||||||||||||||||||| 0 AGGGCGGGGAGGTGGGCAAGATGGCGCTTGCCGAGTGATTCTCCTCGAAT 53 ACCTCCTGCCGGCGCGGAGACACCGGGGC-GGGGGTCCTGCCGCAACTAC |||||||||||||||||||||||||||||*|||||||||||||||||||| 50 ACCTCCTGCCGGCGCGGAGACACCGGGGCGGGGGGTCCTGCCGCAACTAC 102 CTCCCTTCCTCCTCTCCCCGC-CCCCGGAGCCTTCATCCTTCCCTT-CCC |||||||||||||||||||*|*||||||||||||||||||||||||*||| 100 CTCCCTTCCTCCTCTCCCC-CGCCCCGGAGCCTTCATCCTTCCCTTCCCC 150 CCCCACCTCGAGGGGCGGGCCTGGTTCCC-GGACA-CATGTCGGACTCTG |||||||||||||||||||||||||||||*|||||*|||||||||||||| 149 CCCCACCTCGAGGGGCGGGCCTGGTTCCCGGGACACCATGTCGGACTCTG 198 AGGAGGAGAGCCAGGACCGGCAACTGAAAATCGTCGTGCT-GGGGACGGC ||||||||||||||||||||||||||||||||||||||||*||||||||| 199 AGGAGGAGAGCCAGGACCGGCAACTGAAAATCGTCGTGCTGGGGGACGGC 247 GCCTCCGGGAAGACCTCCTTAACTACGTGTTTTGCTCAAGAAACTTTTGG |||||||||||||||||||||||||||||||||||||||||||||||||| 249 GCCTCCGGGAAGACCTCCTTAACTACGTGTTTTGCTCAAGAAACTTTTGG 297 GAAACAGTACAAACAAACTATAGGACTGGATTTCTTTTTGAGAAGGATAA |||||||||||||||||||||||||||||||||||||||||||||||||| 299 GAAACAGTACAAACAAACTATAGGACTGGATTTCTTTTTGAGAAGGATAA 347 CATTGCCAGGAAACTTGAATGTTACCCTTCAAATTTGGGATATAGGAGGG |||||||||||||||||||||||||||||||||||||||||||||||||| 349 CATTGCCAGGAAACTTGAATGTTACCCTTCAAATTTGGGATATAGGAGGG 397 CAGACAATAGGAGGCAAAATGTTGGATAAATATATCTATGGAGCACAGGG |||||||||||||||||||||||||||||||||||||||||||||||||| 399 CAGACAATAGGAGGCAAAATGTTGGATAAATATATCTATGGAGCACAGGG 447 AGTCCTCTTGGTATATGATATTACAAATTATCAAAGCTTTGAGAATTTAG |||||||||||||||||||||||||||||||||||||||||||||||||| 449 AGTCCTCTTGGTATATGATATTACAAATTATCAAAGCTTTGAGAATTTAG 497 AAGATTGGTATACTGTGGTGAAGAAAGTGAGCGAGGAGTCAGAAACTCAG |||||||||||||||||||||||||||||||||||||||||||||||||| 499 AAGATTGGTATACTGTGGTGAAGAAAGTGAGCGAGGAGTCAGAAACTCAG 547 CCACTGGTTGCCTTGGTAGGCAATAAAATTGATTTGGAGCATATGCGAAC |||||||||||||||||||||||||||||||||||||||||||||||||| 549 CCACTGGTTGCCTTGGTAGGCAATAAAATTGATTTGGAGCATATGCGAAC ....... raw 9,230 bp, 6 passes raw 13,863 bp, 8 passes Chaisson & Tesler, Mapping single molecule sequencing reads using basic local alignment with successive refinement (BLASR): application and theory, BMC Bioinformatics (2012) -
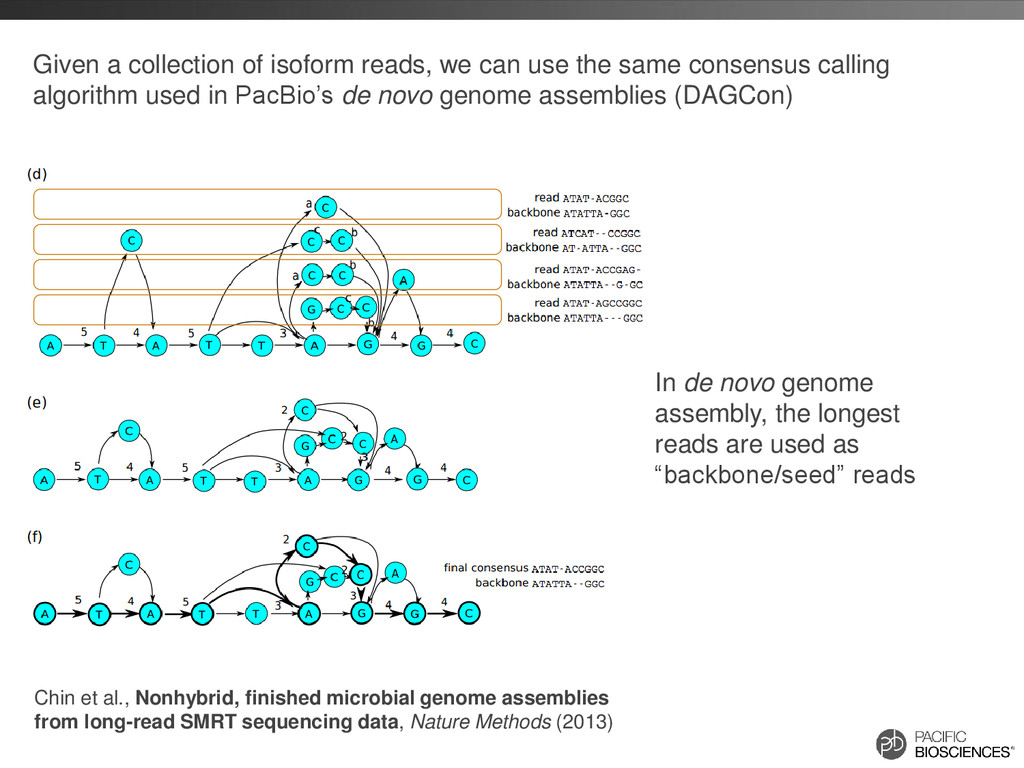
Given a collection of isoform reads, we can use the
same consensus calling algorithm used in PacBio’s de novo genome assemblies (DAGCon) Chin et al., Nonhybrid, finished microbial genome assemblies from long-read SMRT sequencing data, Nature Methods (2013) In de novo genome assembly, the longest reads are used as “backbone/seed” reads -
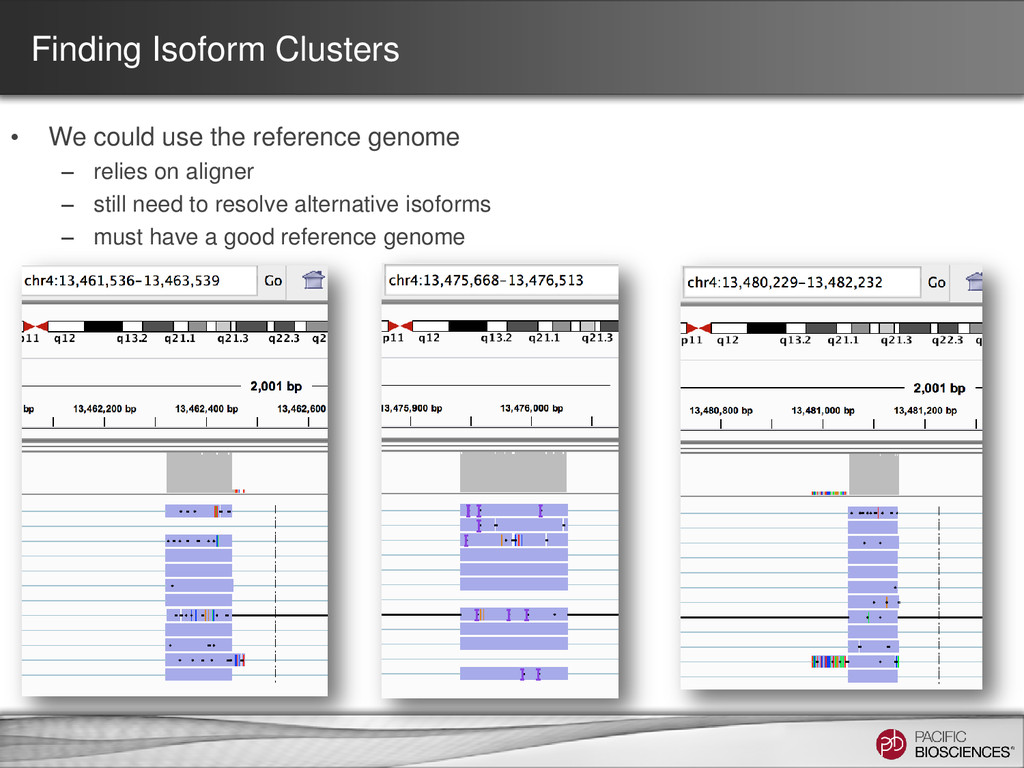
Finding Isoform Clusters • We could use the reference genome
– relies on aligner – still need to resolve alternative isoforms – must have a good reference genome -
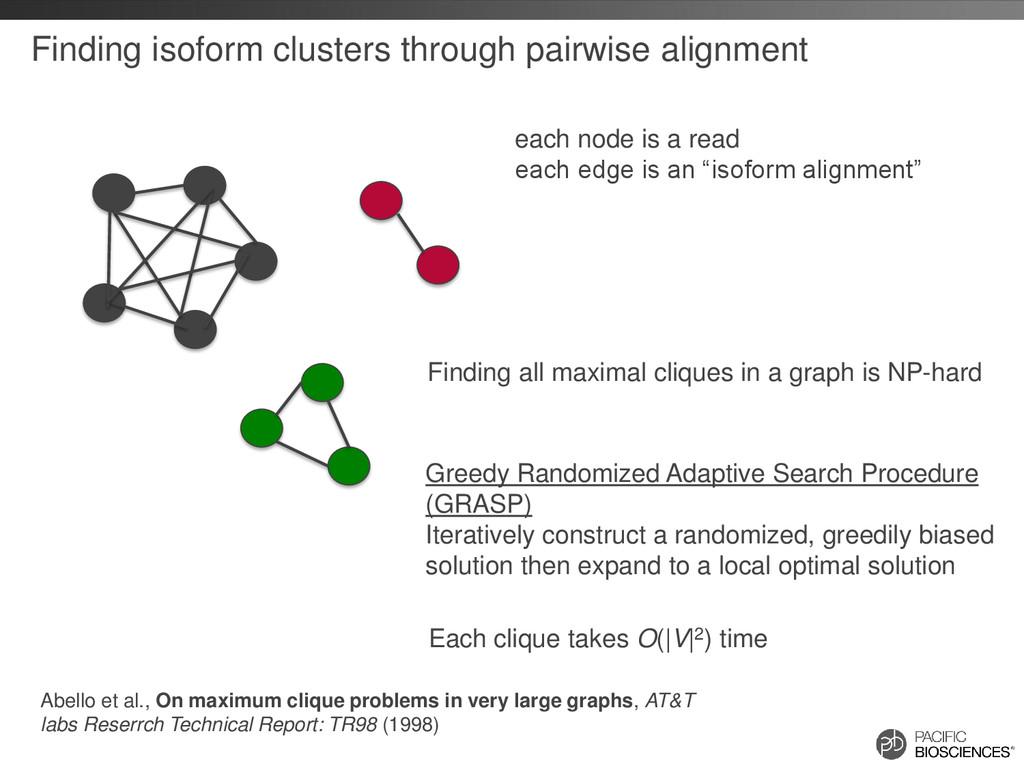
Finding isoform clusters through pairwise alignment each node is a
read each edge is an “isoform alignment” Finding all maximal cliques in a graph is NP-hard Abello et al., On maximum clique problems in very large graphs, AT&T labs Reserrch Technical Report: TR98 (1998) Greedy Randomized Adaptive Search Procedure (GRASP) Iteratively construct a randomized, greedily biased solution then expand to a local optimal solution Each clique takes O(|V|2) time -
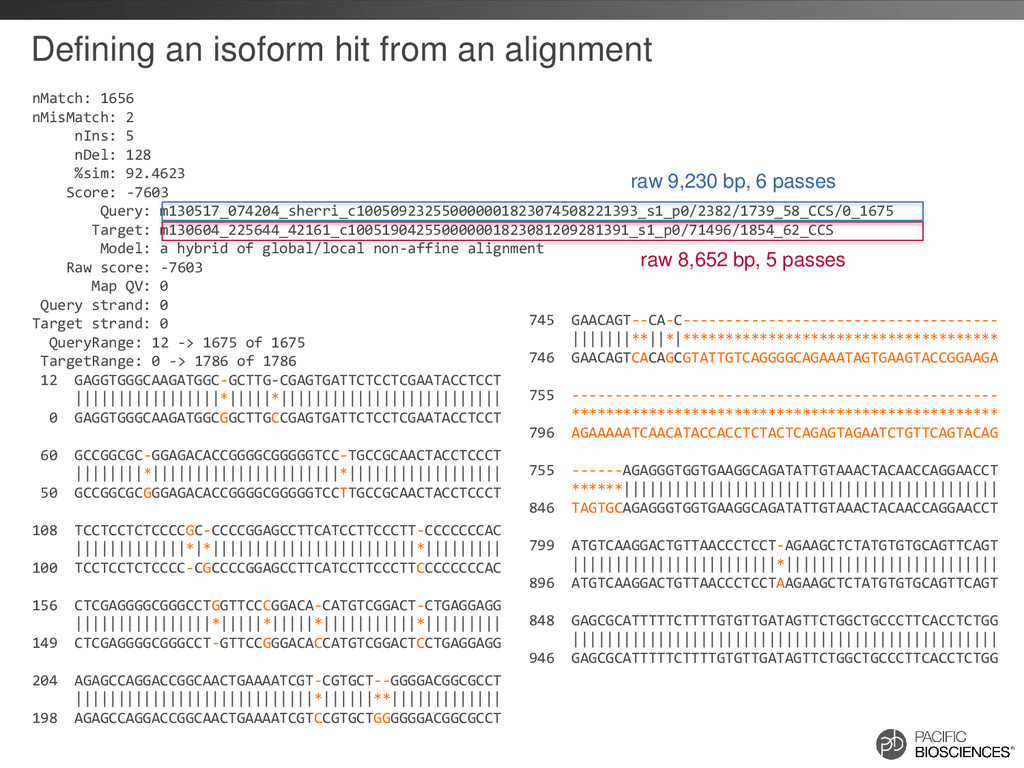
Defining an isoform hit from an alignment nMatch: 1656 nMisMatch:
2 nIns: 5 nDel: 128 %sim: 92.4623 Score: -7603 Query: m130517_074204_sherri_c100509232550000001823074508221393_s1_p0/2382/1739_58_CCS/0_1675 Target: m130604_225644_42161_c100519042550000001823081209281391_s1_p0/71496/1854_62_CCS Model: a hybrid of global/local non-affine alignment Raw score: -7603 Map QV: 0 Query strand: 0 Target strand: 0 QueryRange: 12 -> 1675 of 1675 TargetRange: 0 -> 1786 of 1786 12 GAGGTGGGCAAGATGGC-GCTTG-CGAGTGATTCTCCTCGAATACCTCCT |||||||||||||||||*|||||*|||||||||||||||||||||||||| 0 GAGGTGGGCAAGATGGCGGCTTGCCGAGTGATTCTCCTCGAATACCTCCT 60 GCCGGCGC-GGAGACACCGGGGCGGGGGTCC-TGCCGCAACTACCTCCCT ||||||||*||||||||||||||||||||||*|||||||||||||||||| 50 GCCGGCGCGGGAGACACCGGGGCGGGGGTCCTTGCCGCAACTACCTCCCT 108 TCCTCCTCTCCCCGC-CCCCGGAGCCTTCATCCTTCCCTT-CCCCCCCAC |||||||||||||*|*||||||||||||||||||||||||*||||||||| 100 TCCTCCTCTCCCC-CGCCCCGGAGCCTTCATCCTTCCCTTCCCCCCCCAC 156 CTCGAGGGGCGGGCCTGGTTCCCGGACA-CATGTCGGACT-CTGAGGAGG ||||||||||||||||*|||||*|||||*|||||||||||*||||||||| 149 CTCGAGGGGCGGGCCT-GTTCCGGGACACCATGTCGGACTCCTGAGGAGG 204 AGAGCCAGGACCGGCAACTGAAAATCGT-CGTGCT--GGGGACGGCGCCT ||||||||||||||||||||||||||||*||||||**||||||||||||| 198 AGAGCCAGGACCGGCAACTGAAAATCGTCCGTGCTGGGGGGACGGCGCCT 745 GAACAGT--CA-C------------------------------------- |||||||**||*|************************************* 746 GAACAGTCACAGCGTATTGTCAGGGGCAGAAATAGTGAAGTACCGGAAGA 755 -------------------------------------------------- ************************************************** 796 AGAAAAATCAACATACCACCTCTACTCAGAGTAGAATCTGTTCAGTACAG 755 ------AGAGGGTGGTGAAGGCAGATATTGTAAACTACAACCAGGAACCT ******|||||||||||||||||||||||||||||||||||||||||||| 846 TAGTGCAGAGGGTGGTGAAGGCAGATATTGTAAACTACAACCAGGAACCT 799 ATGTCAAGGACTGTTAACCCTCCT-AGAAGCTCTATGTGTGCAGTTCAGT ||||||||||||||||||||||||*||||||||||||||||||||||||| 896 ATGTCAAGGACTGTTAACCCTCCTAAGAAGCTCTATGTGTGCAGTTCAGT 848 GAGCGCATTTTTCTTTTGTGTTGATAGTTCTGGCTGCCCTTCACCTCTGG |||||||||||||||||||||||||||||||||||||||||||||||||| 946 GAGCGCATTTTTCTTTTGTGTTGATAGTTCTGGCTGCCCTTCACCTCTGG raw 9,230 bp, 6 passes raw 8,652 bp, 5 passes -
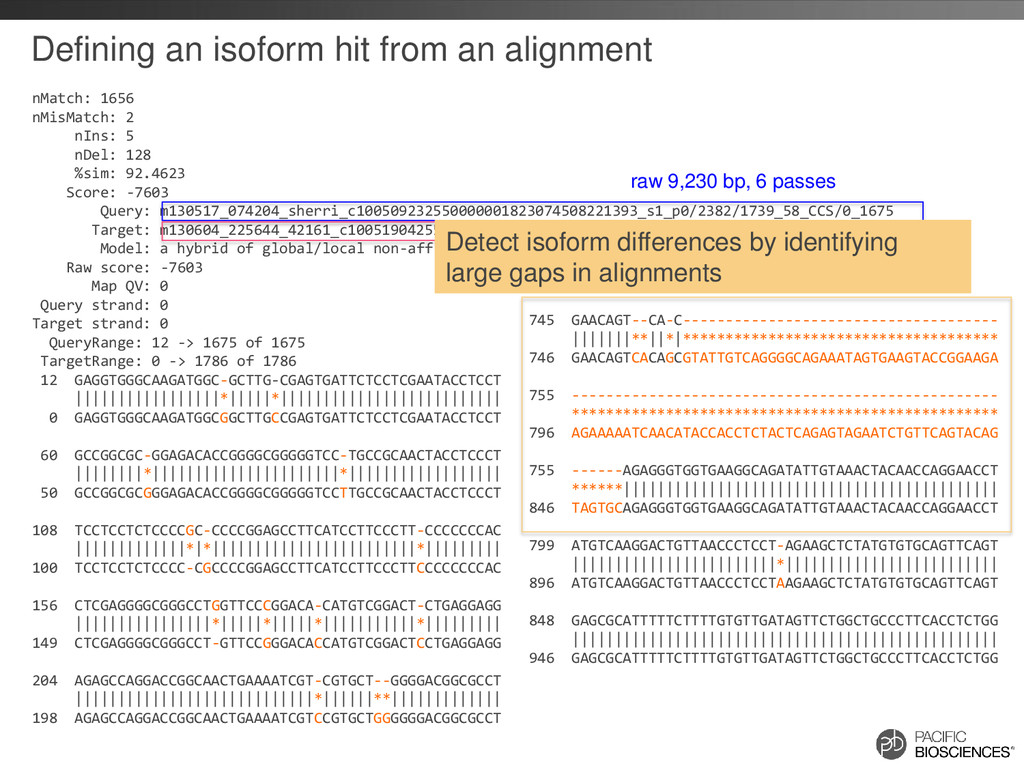
Defining an isoform hit from an alignment nMatch: 1656 nMisMatch:
2 nIns: 5 nDel: 128 %sim: 92.4623 Score: -7603 Query: m130517_074204_sherri_c100509232550000001823074508221393_s1_p0/2382/1739_58_CCS/0_1675 Target: m130604_225644_42161_c100519042550000001823081209281391_s1_p0/71496/1854_62_CCS Model: a hybrid of global/local non-affine alignment Raw score: -7603 Map QV: 0 Query strand: 0 Target strand: 0 QueryRange: 12 -> 1675 of 1675 TargetRange: 0 -> 1786 of 1786 12 GAGGTGGGCAAGATGGC-GCTTG-CGAGTGATTCTCCTCGAATACCTCCT |||||||||||||||||*|||||*|||||||||||||||||||||||||| 0 GAGGTGGGCAAGATGGCGGCTTGCCGAGTGATTCTCCTCGAATACCTCCT 60 GCCGGCGC-GGAGACACCGGGGCGGGGGTCC-TGCCGCAACTACCTCCCT ||||||||*||||||||||||||||||||||*|||||||||||||||||| 50 GCCGGCGCGGGAGACACCGGGGCGGGGGTCCTTGCCGCAACTACCTCCCT 108 TCCTCCTCTCCCCGC-CCCCGGAGCCTTCATCCTTCCCTT-CCCCCCCAC |||||||||||||*|*||||||||||||||||||||||||*||||||||| 100 TCCTCCTCTCCCC-CGCCCCGGAGCCTTCATCCTTCCCTTCCCCCCCCAC 156 CTCGAGGGGCGGGCCTGGTTCCCGGACA-CATGTCGGACT-CTGAGGAGG ||||||||||||||||*|||||*|||||*|||||||||||*||||||||| 149 CTCGAGGGGCGGGCCT-GTTCCGGGACACCATGTCGGACTCCTGAGGAGG 204 AGAGCCAGGACCGGCAACTGAAAATCGT-CGTGCT--GGGGACGGCGCCT ||||||||||||||||||||||||||||*||||||**||||||||||||| 198 AGAGCCAGGACCGGCAACTGAAAATCGTCCGTGCTGGGGGGACGGCGCCT 745 GAACAGT--CA-C------------------------------------- |||||||**||*|************************************* 746 GAACAGTCACAGCGTATTGTCAGGGGCAGAAATAGTGAAGTACCGGAAGA 755 -------------------------------------------------- ************************************************** 796 AGAAAAATCAACATACCACCTCTACTCAGAGTAGAATCTGTTCAGTACAG 755 ------AGAGGGTGGTGAAGGCAGATATTGTAAACTACAACCAGGAACCT ******|||||||||||||||||||||||||||||||||||||||||||| 846 TAGTGCAGAGGGTGGTGAAGGCAGATATTGTAAACTACAACCAGGAACCT 799 ATGTCAAGGACTGTTAACCCTCCT-AGAAGCTCTATGTGTGCAGTTCAGT ||||||||||||||||||||||||*||||||||||||||||||||||||| 896 ATGTCAAGGACTGTTAACCCTCCTAAGAAGCTCTATGTGTGCAGTTCAGT 848 GAGCGCATTTTTCTTTTGTGTTGATAGTTCTGGCTGCCCTTCACCTCTGG |||||||||||||||||||||||||||||||||||||||||||||||||| 946 GAGCGCATTTTTCTTTTGTGTTGATAGTTCTGGCTGCCCTTCACCTCTGG raw 9,230 bp, 6 passes raw 8,652 bp, 5 passes Detect isoform differences by identifying large gaps in alignments -
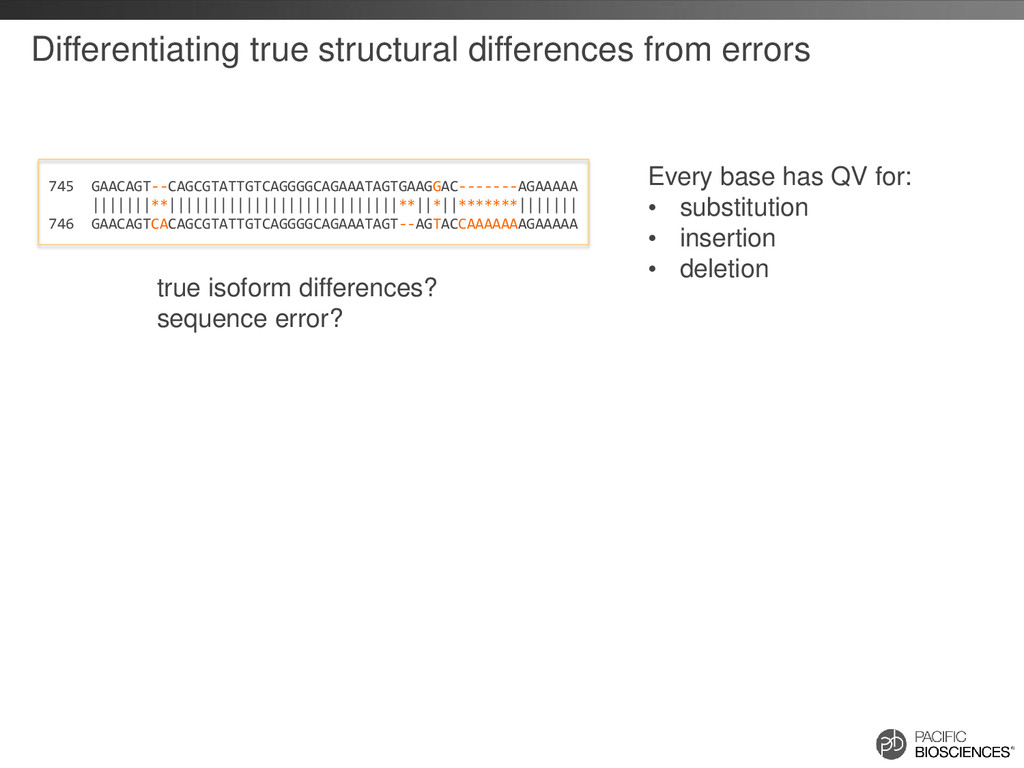
Differentiating true structural differences from errors 745 GAACAGT--CAGCGTATTGTCAGGGGCAGAAATAGTGAAGGAC-------AGAAAAA |||||||**|||||||||||||||||||||||||||**||*||*******||||||| 746
GAACAGTCACAGCGTATTGTCAGGGGCAGAAATAGT--AGTACCAAAAAAAGAAAAA true isoform differences? sequence error? Every base has QV for: • substitution • insertion • deletion -
Differentiating true structural differences from errors S + + I
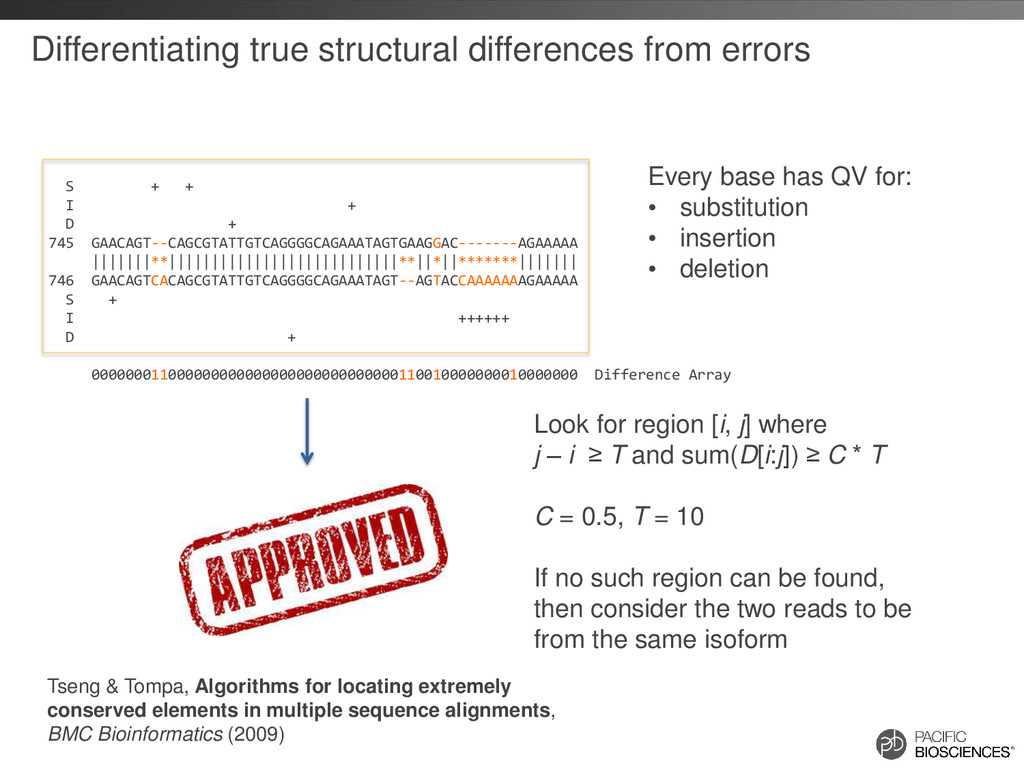
+ D + 745 GAACAGT--CAGCGTATTGTCAGGGGCAGAAATAGTGAAGGAC-------AGAAAAA |||||||**|||||||||||||||||||||||||||**||*||*******||||||| 746 GAACAGTCACAGCGTATTGTCAGGGGCAGAAATAGT--AGTACCAAAAAAAGAAAAA S + I ++++++ D + 000000011000000000000000000000000000110010000000010000000 Difference Array Every base has QV for: • substitution • insertion • deletion Look for region [i, j] where j – i ≥ T and sum(D[i:j]) ≥ C * T C = 0.5, T = 10 If no such region can be found, then consider the two reads to be from the same isoform Tseng & Tompa, Algorithms for locating extremely conserved elements in multiple sequence alignments, BMC Bioinformatics (2009) -
Differentiating true structural differences from errors S + + I
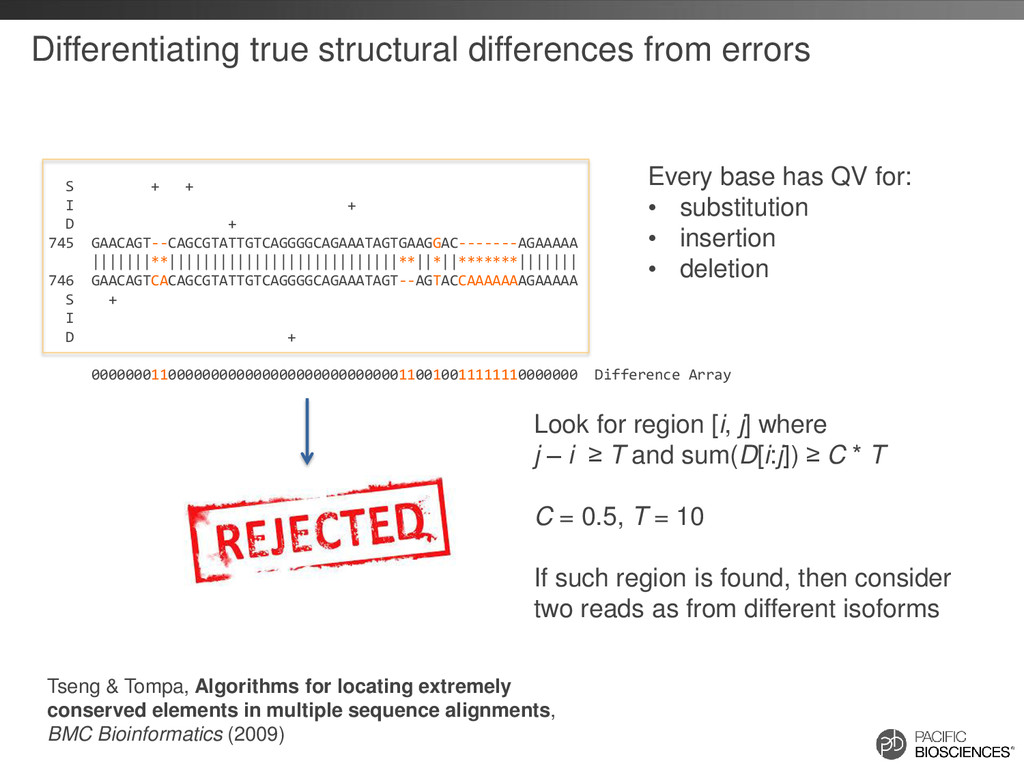
+ D + 745 GAACAGT--CAGCGTATTGTCAGGGGCAGAAATAGTGAAGGAC-------AGAAAAA |||||||**|||||||||||||||||||||||||||**||*||*******||||||| 746 GAACAGTCACAGCGTATTGTCAGGGGCAGAAATAGT--AGTACCAAAAAAAGAAAAA S + I D + 000000011000000000000000000000000000110010011111110000000 Difference Array Every base has QV for: • substitution • insertion • deletion Look for region [i, j] where j – i ≥ T and sum(D[i:j]) ≥ C * T C = 0.5, T = 10 If such region is found, then consider two reads as from different isoforms Tseng & Tompa, Algorithms for locating extremely conserved elements in multiple sequence alignments, BMC Bioinformatics (2009) -
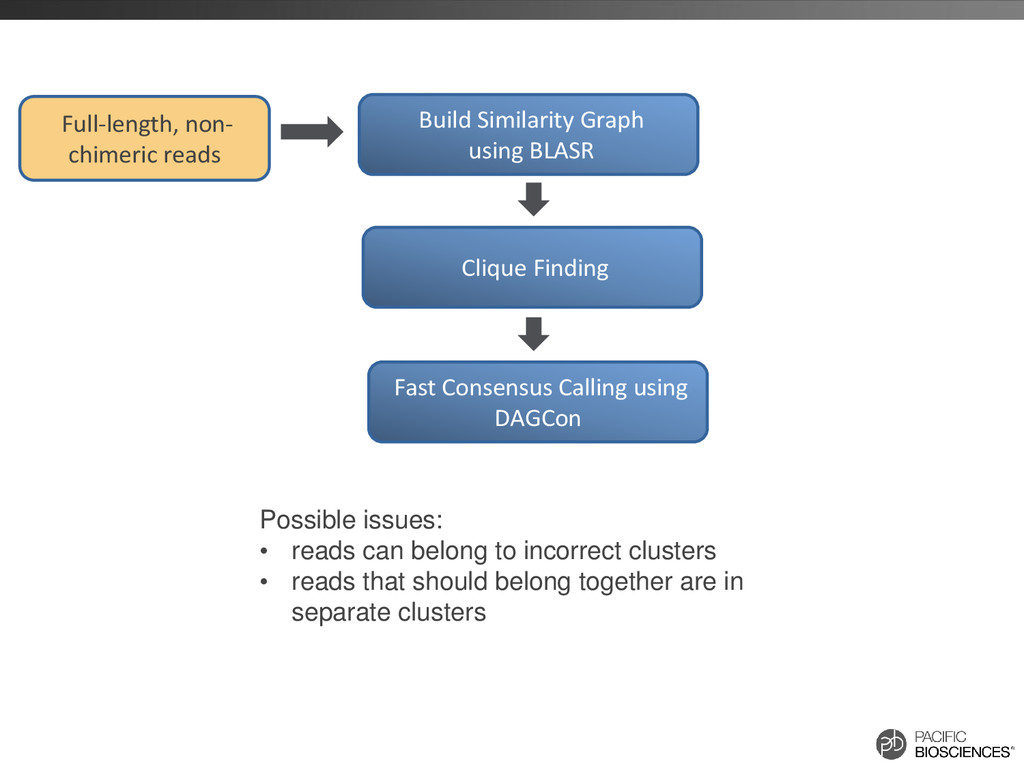
Possible issues: • reads can belong to incorrect clusters •
reads that should belong together are in separate clusters Build Similarity Graph using BLASR Clique Finding Fast Consensus Calling using DAGCon Full-length, non- chimeric reads -
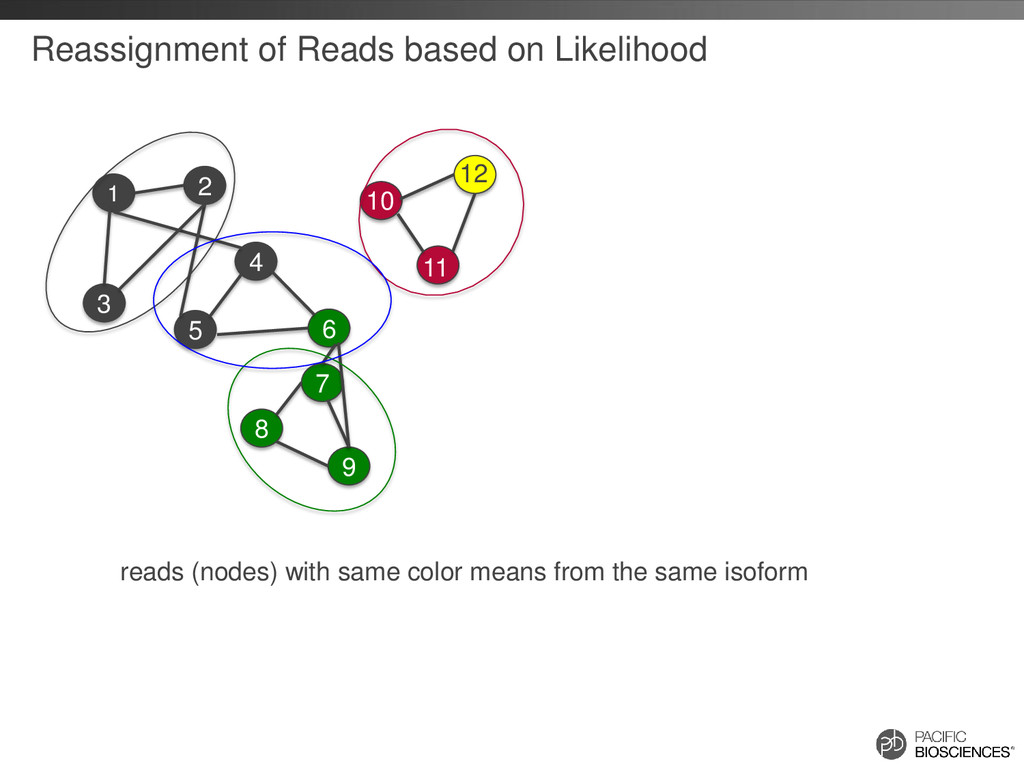
Reassignment of Reads based on Likelihood 1 4 3 2
5 7 8 9 6 10 11 12 reads (nodes) with same color means from the same isoform -
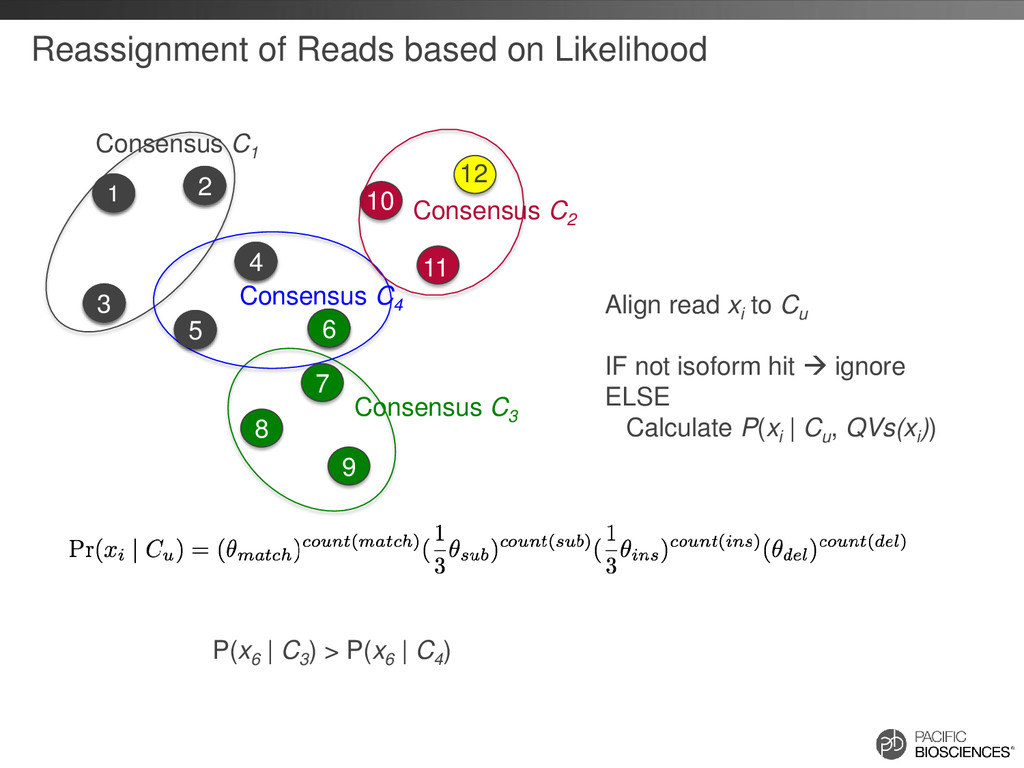
Reassignment of Reads based on Likelihood Consensus C1 Consensus C2
Consensus C3 Consensus C4 Align read xi to Cu IF not isoform hit ignore ELSE Calculate P(xi | Cu , QVs(xi )) 1 4 3 2 5 6 10 11 12 7 8 9 P(x6 | C3 ) > P(x6 | C4 ) -
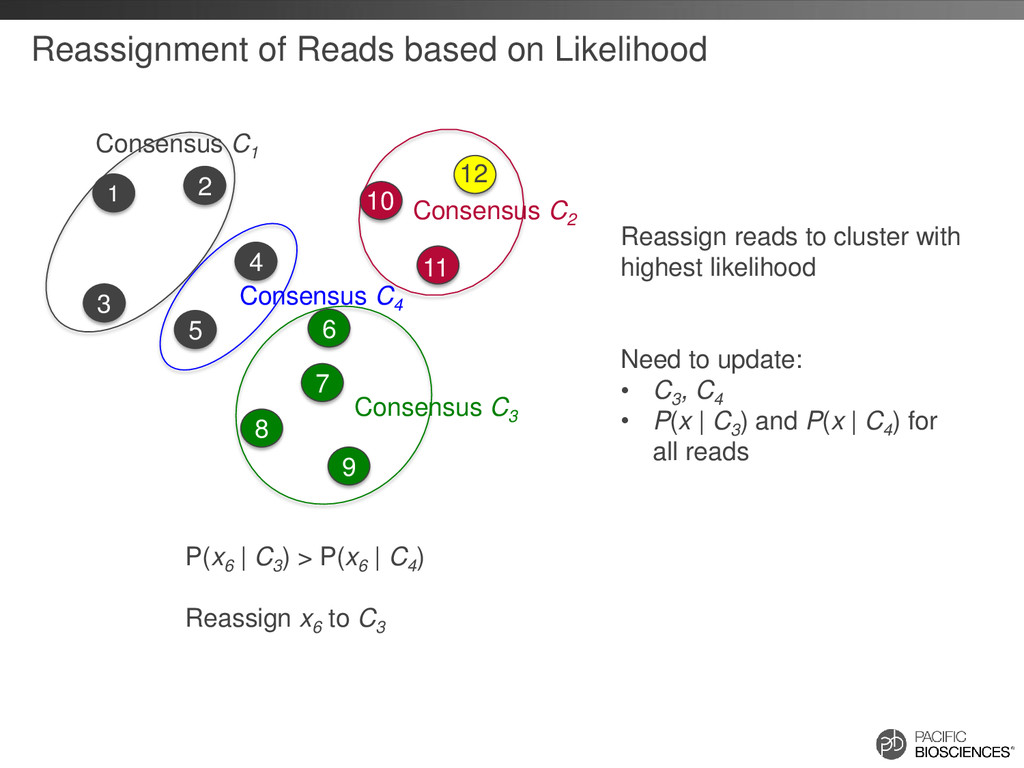
Reassignment of Reads based on Likelihood Consensus C1 Consensus C3
Consensus C4 Reassign reads to cluster with highest likelihood Need to update: • C3 , C4 • P(x | C3 ) and P(x | C4 ) for all reads Consensus C2 1 4 3 2 5 6 7 8 9 10 11 12 P(x6 | C3 ) > P(x6 | C4 ) Reassign x6 to C3 -
Merge Highly Identical Clusters Consensus C3 Consensus C2 1 4
3 2 5 6 7 8 9 10 11 12 C1 and C4 are isoform hits and ≥ 99.5% identical Merge C1 and C4 C5 Need to update: • C5 • P(x | C5 ) for all reads Consensus C5 -
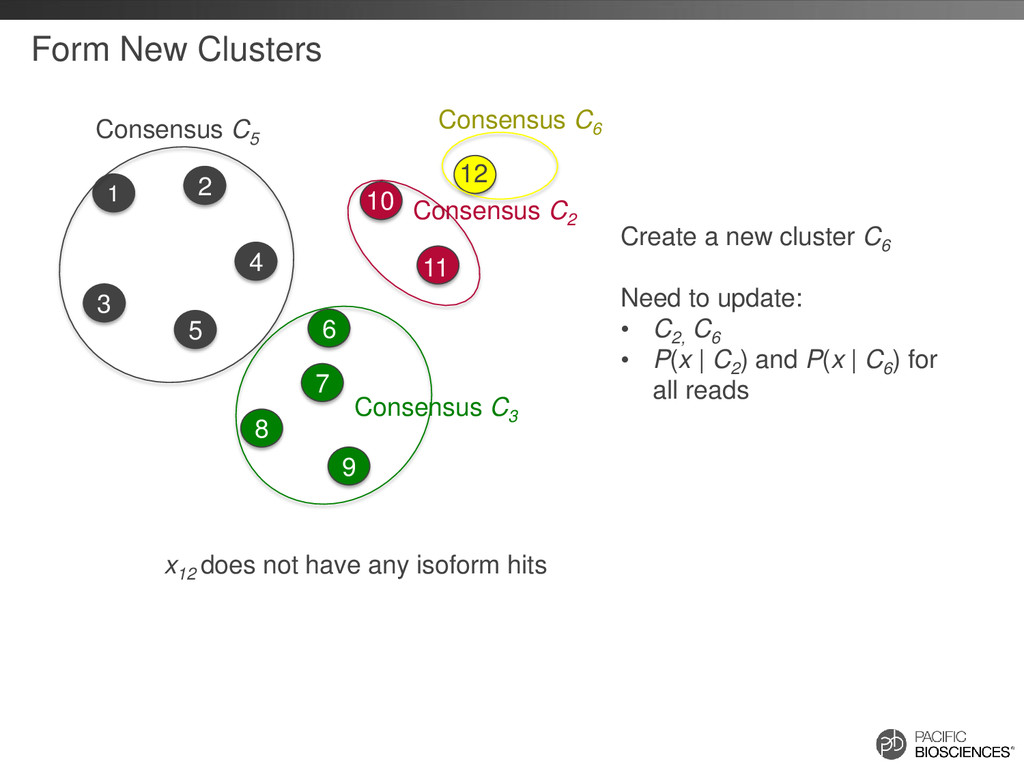
Form New Clusters Consensus C3 Consensus C2 1 4 3
2 5 6 7 8 9 10 11 12 x12 does not have any isoform hits Consensus C5 Create a new cluster C6 Need to update: • C2, C6 • P(x | C2 ) and P(x | C6 ) for all reads Consensus C6 -
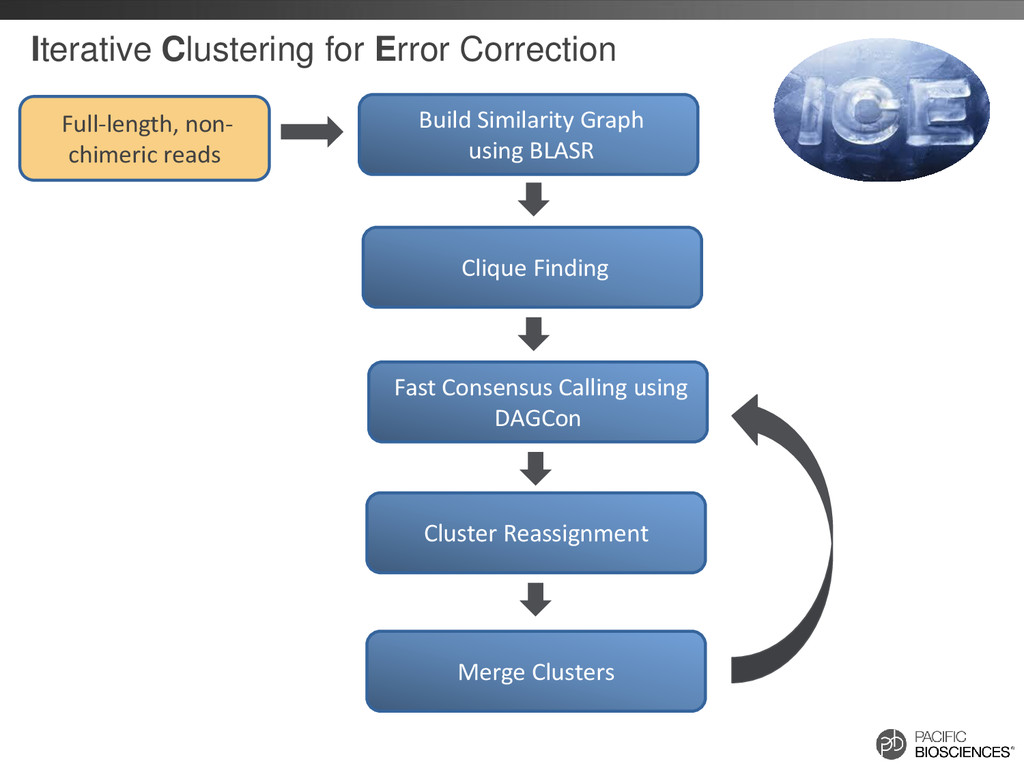
Iterative Clustering for Error Correction Build Similarity Graph using BLASR
Clique Finding Fast Consensus Calling using DAGCon Full-length, non- chimeric reads Cluster Reassignment Merge Clusters -
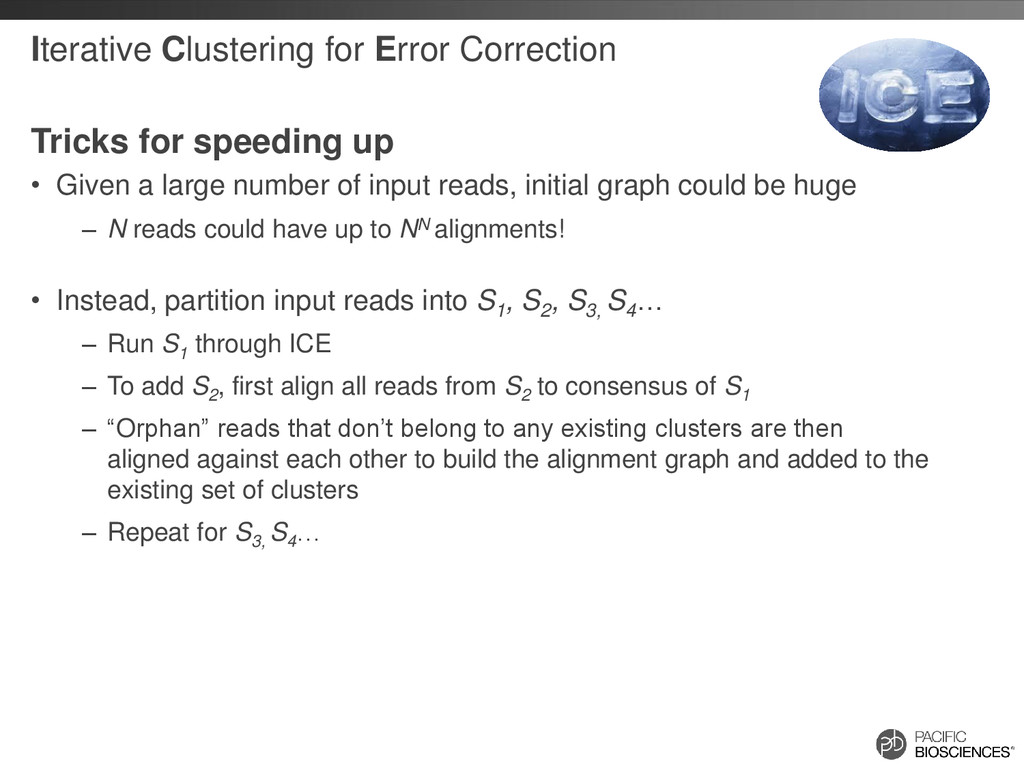
Iterative Clustering for Error Correction Tricks for speeding up •
Given a large number of input reads, initial graph could be huge – N reads could have up to NN alignments! • Instead, partition input reads into S1 , S2 , S3, S4 … – Run S1 through ICE – To add S2 , first align all reads from S2 to consensus of S1 – “Orphan” reads that don’t belong to any existing clusters are then aligned against each other to build the alignment graph and added to the existing set of clusters – Repeat for S3, S4 … -
Quiver for Final Consensus Polishing • Recruit non-full-length reads –
Same “isoform hit” criteria – But does not require each read to be fully aligned – Each non-FL read can belong to multiple clusters Chin et al., Nonhybrid, finished microbial genome assemblies from long-read SMRT sequencing data, Nature Methods (2013) -
Runs (.bax.h5) Reads Of Insert (.fasta, .ccs.h5) Full-length, non- chimeric
RoIs Non-full-length, non- chimeric RoIs Cluster Consensus HQ, Full-length, Polished Consensus Quiver ICE Isoform-level Clustering: Overview -
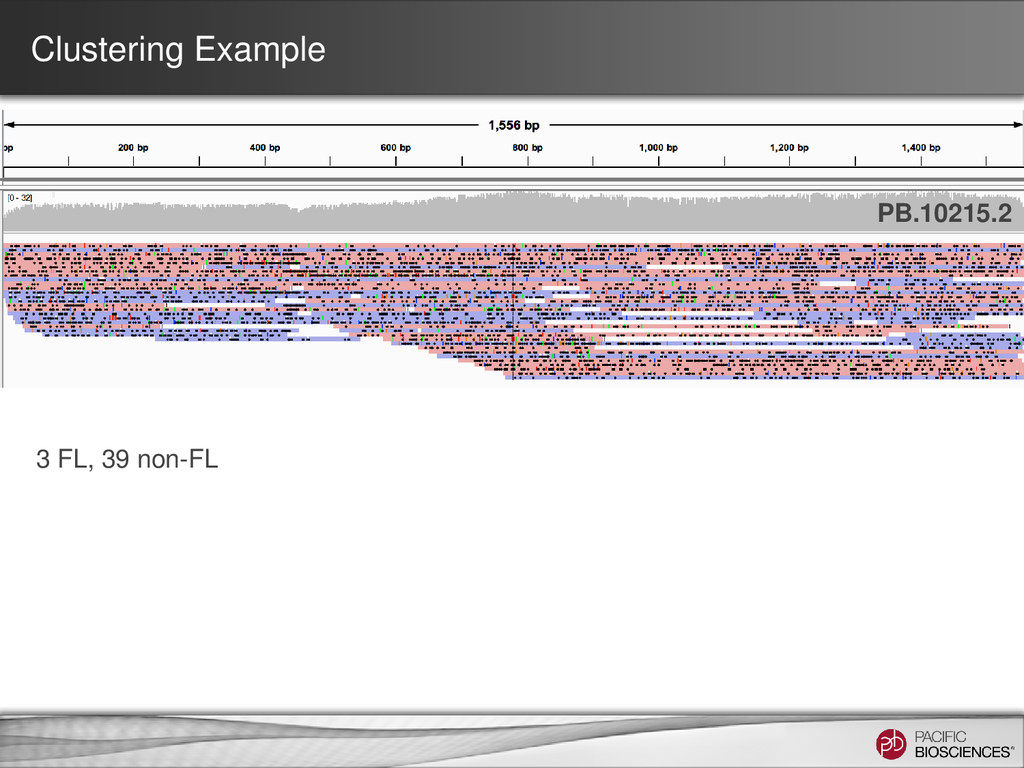
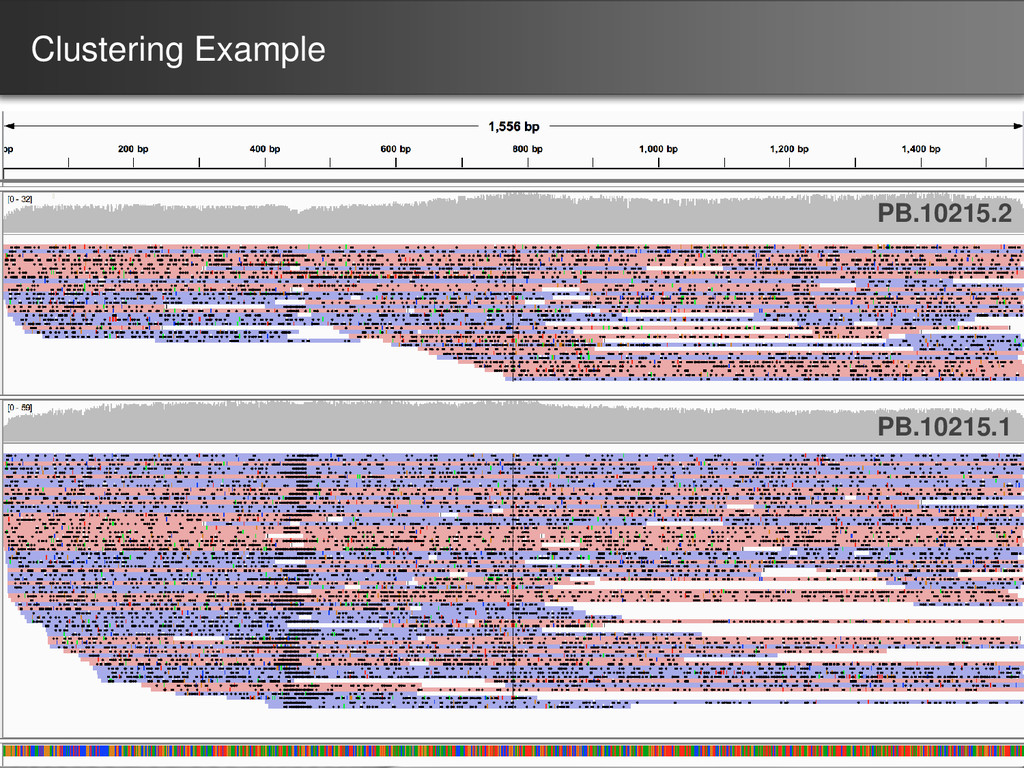
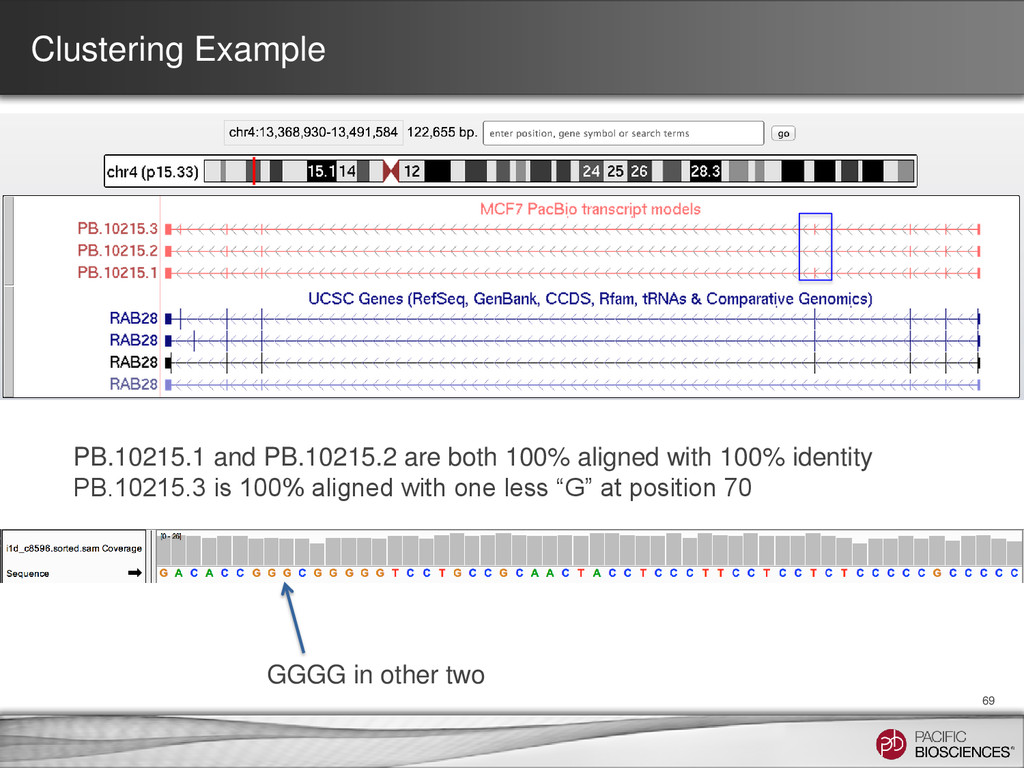
Clustering Example 69 PB.10215.1 and PB.10215.2 are both 100% aligned
with 100% identity PB.10215.3 is 100% aligned with one less “G” at position 70 GGGG in other two -
Collapsing Redundant Transcripts • Both MCF-7 and rat transcriptome datasets
were further processed for collapsing redundant transcripts • Consensus transcripts were mapped back to the genome – If exon structure identical but only differ on the 5’ start site, collapse 70 -
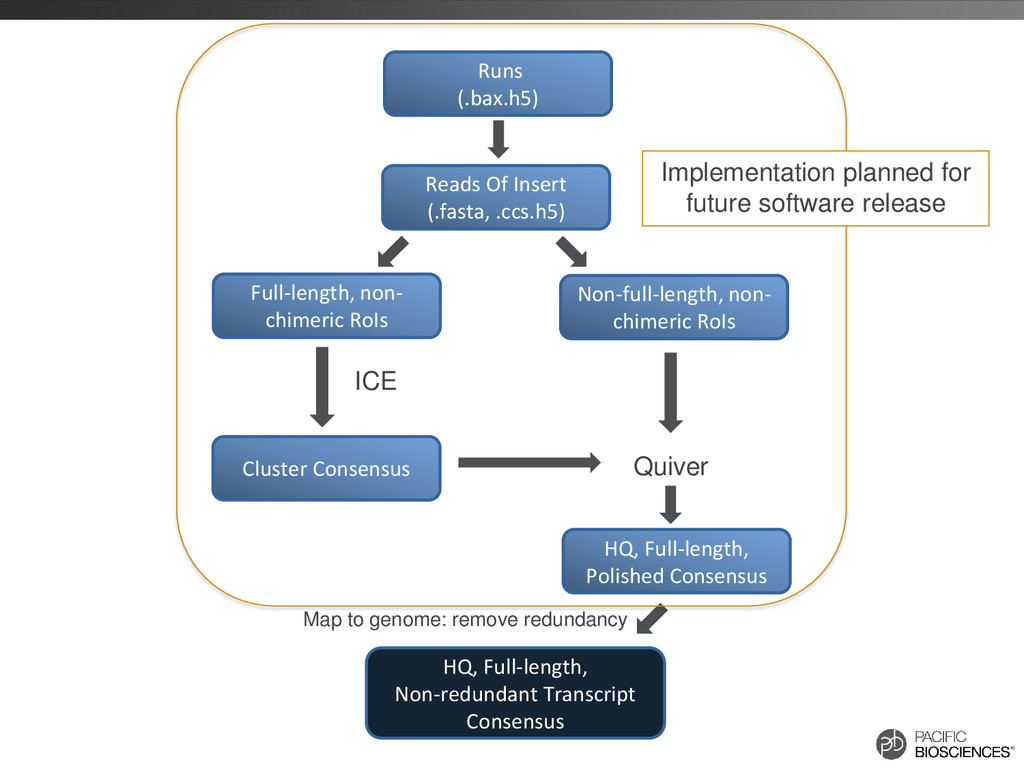
Runs (.bax.h5) Reads Of Insert (.fasta, .ccs.h5) Full-length, non- chimeric
RoIs Non-full-length, non- chimeric RoIs Cluster Consensus HQ, Full-length, Polished Consensus HQ, Full-length, Non-redundant Transcript Consensus Quiver ICE Map to genome: remove redundancy Implementation planned for future software release -
• Construct cDNA libraries enriched in full-length transcripts • Size
selection using agarose gel or BluePippin™ system • Sequence transcripts up to 6 kb in full-length • Single-molecule observation of each transcript • Identify putatively full-length transcripts • Detect artificial chimeras • Isoform-level clustering to generate high-quality transcript consensus sequences • Novel transcripts • Alternative splicing • Alternative polyadenylation • Retained introns • Fusion genes • Anti-sense transcription Full-length cDNA Sequencing Bioinformatics Analysis Biological Applications Summary of Iso-Seq™ Method -
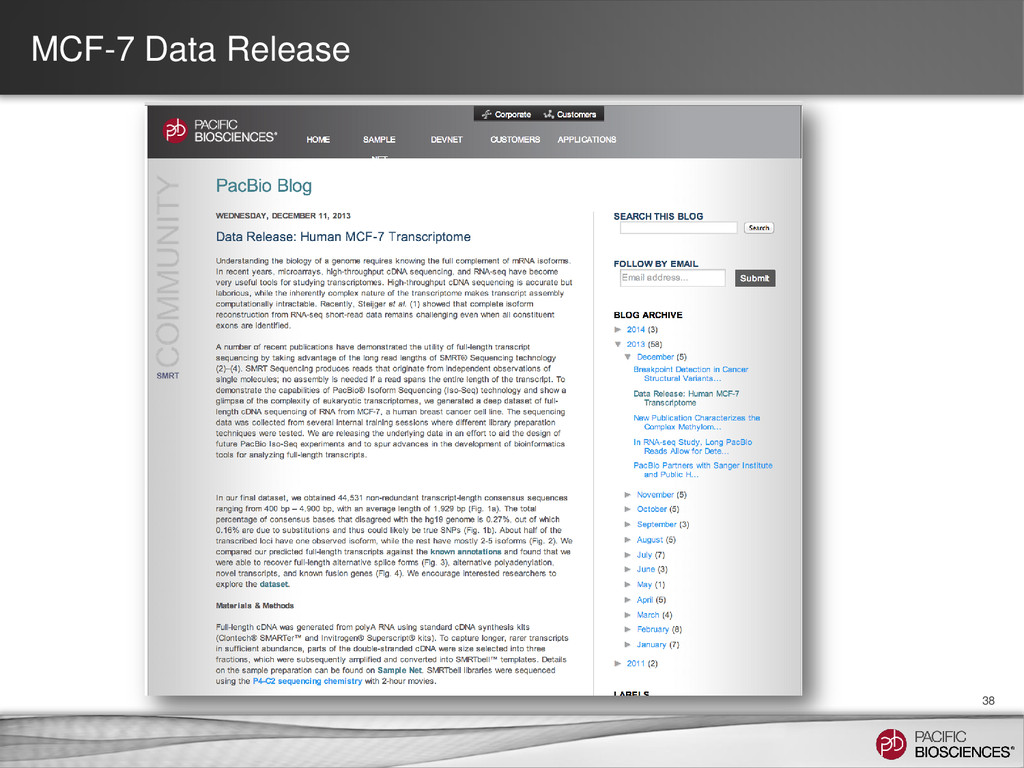
References • MCF-7 Blog Release • MCF-7 Dataset • DevNet
(GitHub) Code Repository and Tutorial Wiki • Iso-Seq™ Library Preparation Protocol Recent Customer Publications: • Sharon et al., A single-molecule long-read survey of the human transcriptome, Nature Biotech. (2013) • Au et al., Characterization of the human ESC transcriptome by hybrid sequencing, PNAS (2013) • Zhang et al., PacBio sequencing of gene families-a case study with wheat gluten genes, Gene (2013) Contact your FAS to learn more! -
Pacific Biosciences, the Pacific Biosciences logo, PacBio, SMRT, SMRTbell, and
Iso-Seq are trademarks of Pacific Biosciences in the United States and/or other countries. All other trademarks are the sole property of their respective owners. 75
 pacbio
 arfon
 tsoh
 tagtag
 trycycle
 mickey_0226
 nozakijcom
 mickey_kubo
 mariiabarkan12
 ykiyota
 tammyeverts
 aleyda
 szymonslowik
 leimatthew05
 zakiyama
 reverentgeek
 wjessup
 jonoalderson
 coloredviolet
 chrisshort
 sergeychernyshev