Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
BB_twtr at SemEval-2017 Task 4: Twitter Sentime...
Search
Yuto Kamiwaki
May 29, 2018
Research
270
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
BB_twtr at SemEval-2017 Task 4: Twitter Sentiment Analysis with CNNs and LSTMs
2018/05/30文献紹介の発表内容
Yuto Kamiwaki
May 29, 2018
More Decks by Yuto Kamiwaki
See All by Yuto Kamiwaki
Emo2Vec: Learning Generalized Emotion Representation by Multi-task Training
yuto_kamiwaki
0
120
Modeling Naive Psychology of Characters in Simple Commonsense Stories
yuto_kamiwaki
1
220
Using millions of emoji occurrences to learn any-domain representations for detecting sentiment, emotion and sarcasm
yuto_kamiwaki
0
130
Epita at SemEval-2018 Task 1: Sentiment Analysis Using Transfer Learning Approach
yuto_kamiwaki
0
150
Tensor Fusion Network for Multimodal Sentiment Analysis
yuto_kamiwaki
0
290
Sentiment Analysis: It’s Complicated!
yuto_kamiwaki
0
96
ADAPT at IJCNLP-2017 Task 4: A Multinomial Naive Bayes Classification Approach for Customer Feedback Analysis task
yuto_kamiwaki
0
180
EmoWordNet: Automatic Expansion of Emotion Lexicon Using English WordNet
yuto_kamiwaki
0
120
ATTENTION-BASED LSTM FOR PSYCHOLOGICAL STRESS DETECTION FROM SPOKEN LANGUAGE USING DISTANT SUPERVISION
yuto_kamiwaki
0
170
Other Decks in Research
See All in Research
適応的スパムフィルタのための軽量な類似メッセージカウンタ / jsai2026-adaptive-spam-filter
monochromegane
0
5.7k
進化?迷走?CasualConc ファミリーアプリの現在地 @ 英語コーパス学会 2026
casualconc
0
120
VRID: View-Invariant Representation through Dual-Axis Transformation for Cross-iew Pose Estimation
satai
3
110
生成AIなんでも展示会vol6 LT登壇資料 NexteraBERT
rikkabotan7
0
160
NLP colloquium: AI Safety Survey
kanekomasahiro
2
1.1k
敵対生成プロンプト同時探索による内省型プロンプト最適化
kinoue_smarthr
0
430
MIRU2026 チュートリアル講演2:三次元データ処理の動向
nnchiba
6
5k
実例から見るLLMのマンガ理解:実務VQAタスクによる長期的文脈と視覚情報の定性評価
kzmssk
0
160
JICA QUEST 共創×革新プログラム Impact Report(海ノ向こうコーヒー)
ontheslope
0
720
The story of RefactoringMiner. Slow research, long-term impact
tsantalis
0
180
論文読み会 SNLP2026 Tau2-Bench: Evaluating Conversational Agents in a Dual-Control Environment
s_mizuki_nlp
0
280
Claude Code × autoresearch 実践
mathbullet
0
290
Featured
See All Featured
Put a Button on it: Removing Barriers to Going Fast.
kastner
60
4.6k
Mind Mapping
helmedeiros
1
380
Mobile First: as difficult as doing things right
swwweet
225
10k
Optimising Largest Contentful Paint
csswizardry
37
4k
End of SEO as We Know It (SMX Advanced Version)
ipullrank
3
4.4k
Groundhog Day: Seeking Process in Gaming for Health
codingconduct
0
380
Are puppies a ranking factor?
jonoalderson
2
4k
The Psychology of Web Performance [Beyond Tellerrand 2023]
tammyeverts
49
3.6k
For a Future-Friendly Web
brad_frost
183
10k
A brief & incomplete history of UX Design for the World Wide Web: 1989–2019
jct
2
510
Site-Speed That Sticks
csswizardry
13
1.5k
Speed Design
sergeychernyshev
33
2.1k
Transcript
BB_twtr at SemEval-2017 Task 4: Twitter Sentiment Analysis with CNNs
and LSTMs 長岡技術科学大学 自然言語処理研究室 上脇優人 Mathieu Cliche Bloomberg SemEval-2017 pp573-580 5月文献紹介 ※sentiment=感情としています
Abstract •内容は,SoTAを達成したTwitterの感情分類 器(CNNとLSTM)について. •最終的なCNNとLSTMは,再度fine tuneした SemEval-2017 Twitter datasetでトレー ニングした. •パフォーマンスを向上させるためにいくつかの
CNNとLSTMを一緒に使う. •この手法は,40のチームの中で5つの英語のサ ブタスクで1位であった. 2
Introduction •Tweetの極性を決定するタスクは,タスクの 理解がしやすく,簡単な方法で良い結果を得る ことが可能. •SemEval-2017のコンペは,5つのサブタス ク. • (タスクの種類については,Rosenthal et al.,2017を参照)
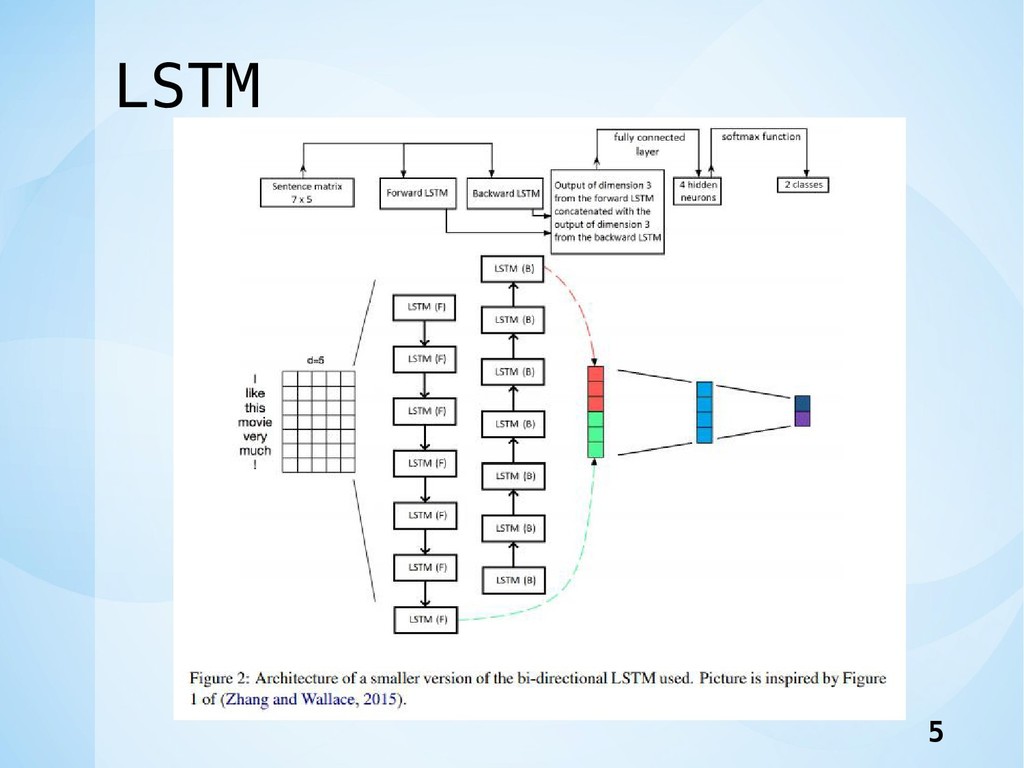
•深層学習の手法は,いくつかのNLPタスクで従 来の手法を大幅に凌駕していて感情分析も例外 でない. •感情分析においても有用な深層学習のCNNと LSTMを用いて(組み合わせたりして)感情分 類器を構築する. 3
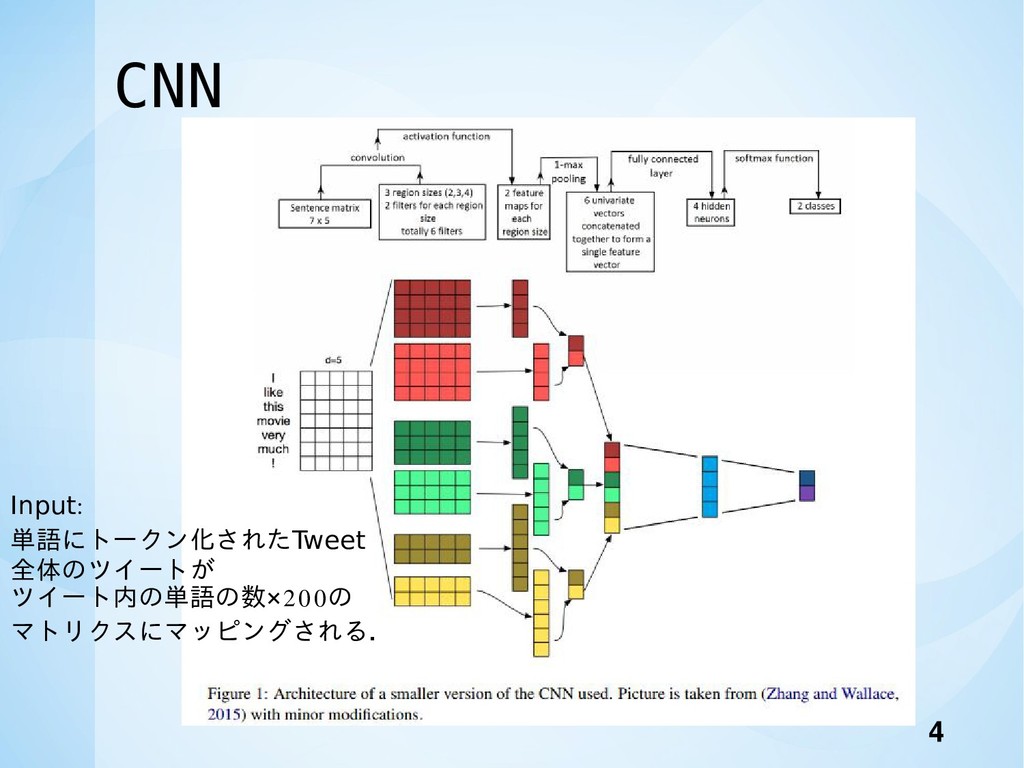
CNN 4 Input: 単語にトークン化されたTweet 全体のツイートが ツイート内の単語の数×200の マトリクスにマッピングされる.
LSTM 5
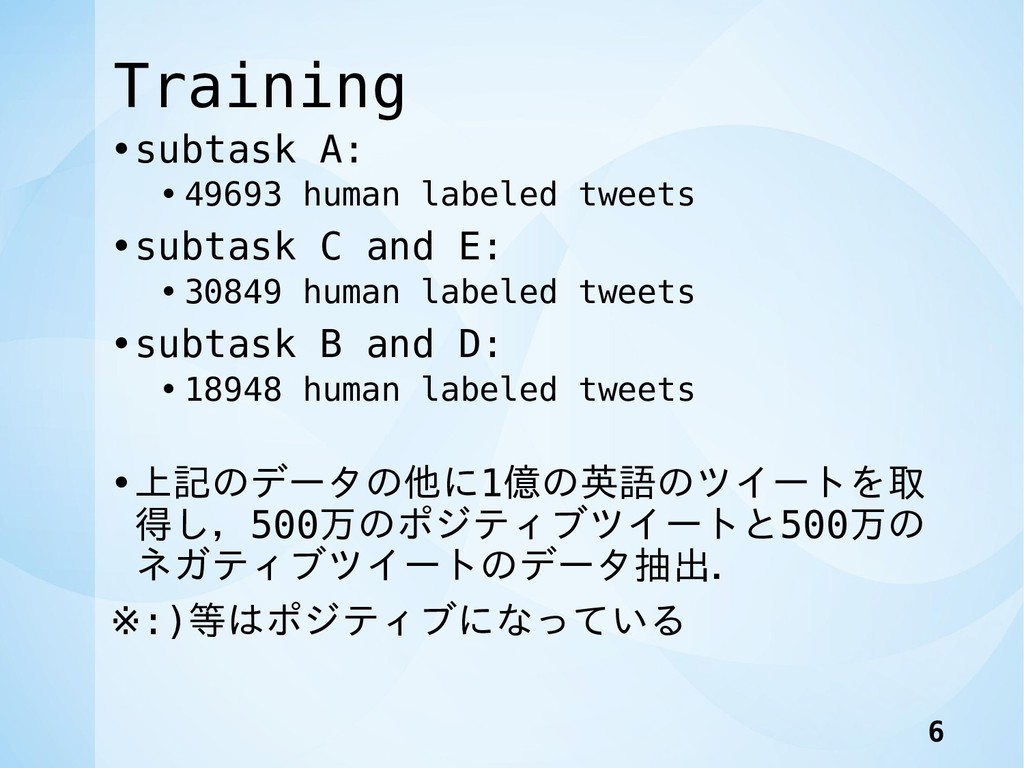
Training •subtask A: • 49693 human labeled tweets •subtask C
and E: • 30849 human labeled tweets •subtask B and D: • 18948 human labeled tweets •上記のデータの他に1億の英語のツイートを取 得し,500万のポジティブツイートと500万の ネガティブツイートのデータ抽出. ※:)等はポジティブになっている 6
Unsupervised training •取得した1億のラベルなしデータを使用. •学習に使用したモデルは,下記3種類のアルゴ リズム. • Word2vec • FastText •
GloVe •全てのアルゴリズムにおいて論文著者が提供す るコードをデフォルトで使用. 7
Distant training •極性情報を追加するためにDistant training. •Distant trainingには、CNNを使用し,初 期値は教師なしフェーズで学習した embeddingを使用. •次に,抽出した500万のポジティブツイートと 500万のネガティブツイートのデータを用いて
CNNをtrainingしてノイズを分類. 8
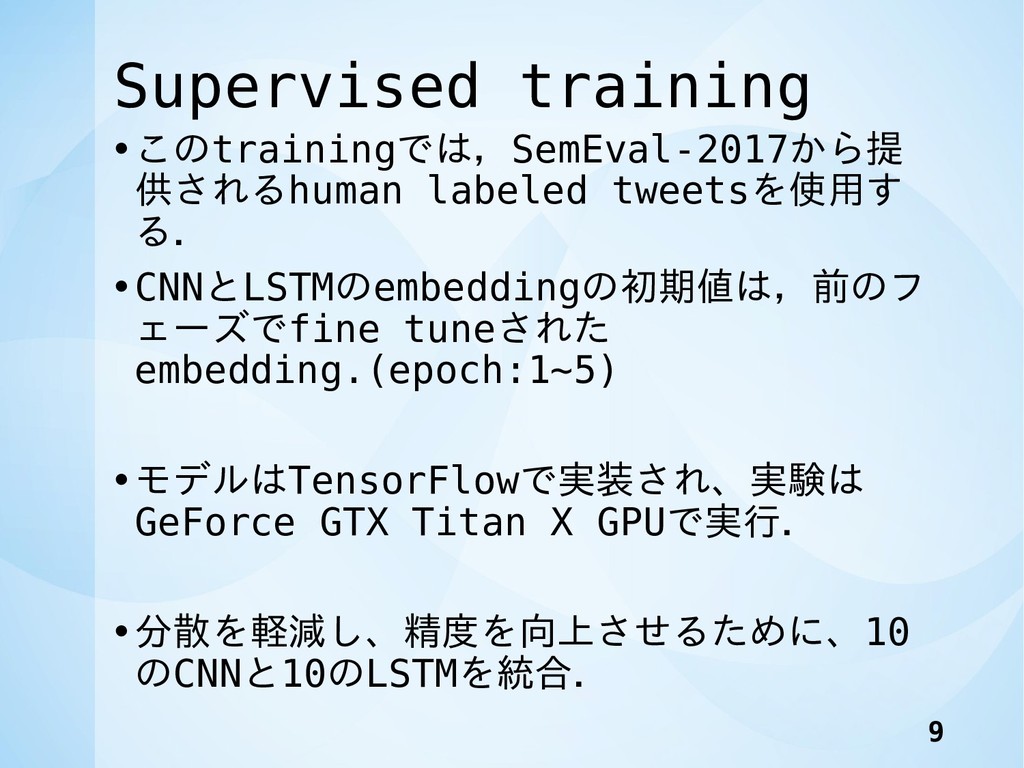
Supervised training •このtrainingでは,SemEval-2017から提 供されるhuman labeled tweetsを使用す る. •CNNとLSTMのembeddingの初期値は,前のフ ェーズでfine tuneされた
embedding.(epoch:1~5) •モデルはTensorFlowで実装され、実験は GeForce GTX Titan X GPUで実行. •分散を軽減し、精度を向上させるために、10 のCNNと10のLSTMを統合. 9
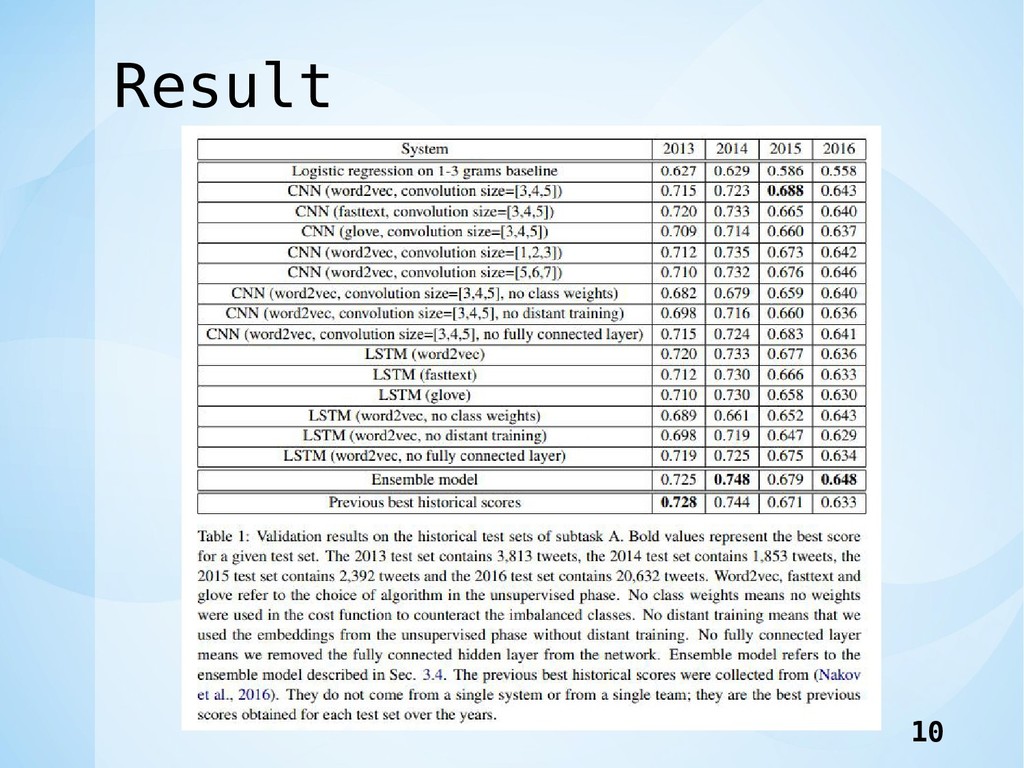
Result 10
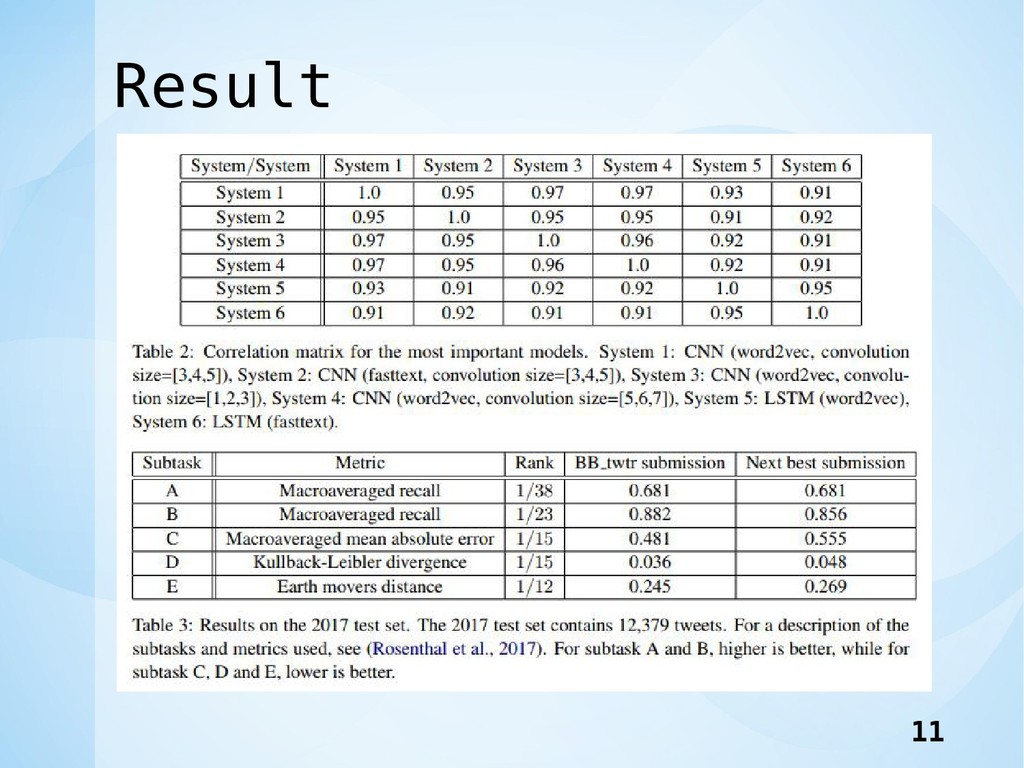
Result 11
Conclusion •SemEval-2017 Twitter sentiment analysis competitionのpaper. •Tweetの分類器を現代のtraining法に加えて 深層学習のモデルで実験した. •最後のモデルは,10のCNNと10のLSTMを用い た.(異なるハイパーパラメータ・トレーニン
グ). •参加したタスク全てで1位だった. 12
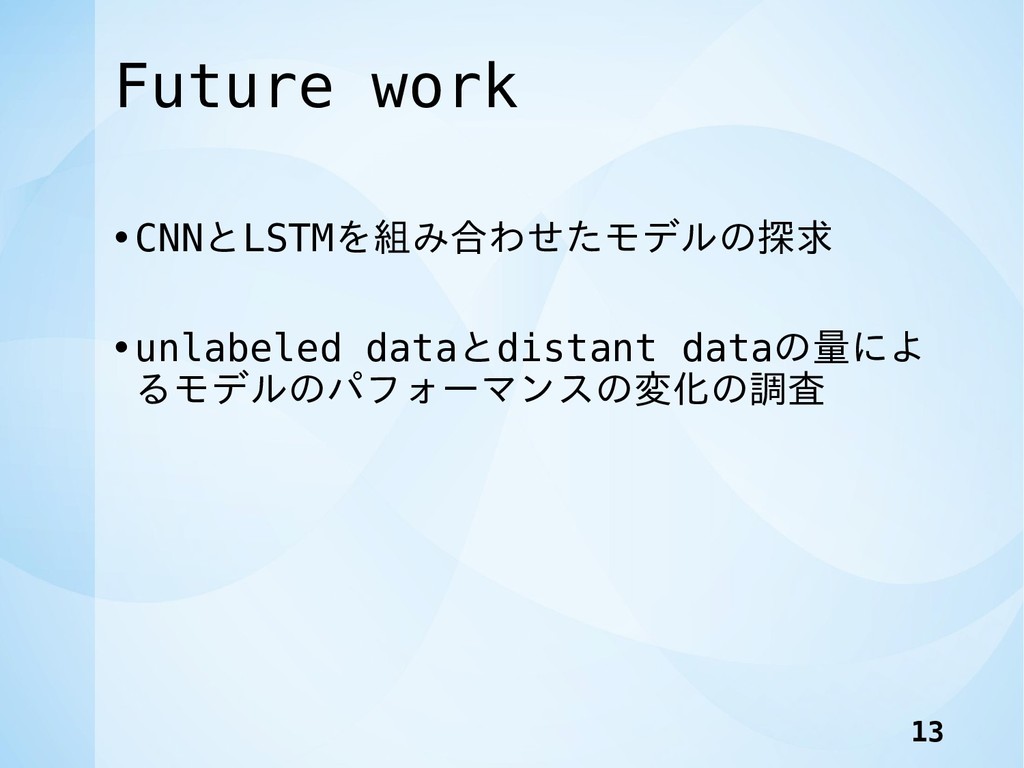
Future work •CNNとLSTMを組み合わせたモデルの探求 •unlabeled dataとdistant dataの量によ るモデルのパフォーマンスの変化の調査 13


 yuto_kamiwaki
 monochromegane
 casualconc
 satai
 rikkabotan7
 kanekomasahiro
 kinoue_smarthr
 nnchiba
 kzmssk
 ontheslope
 tsantalis
 s_mizuki_nlp
 mathbullet
 kastner
 helmedeiros
 swwweet
 csswizardry
 ipullrank
 codingconduct
 jonoalderson
 tammyeverts
 brad_frost
 jct
 sergeychernyshev